TL;DR
Agentic context engineering lets AI agents improve without retraining by turning task outcomes into reviewed playbook lessons, so pick it over fine-tuning when mistakes repeat. A Generator runs the task, a Reflector works out what went right or wrong, and a Curator merges small itemized updates into the playbook. The model weights never change, so a bad lesson can be rolled back like a config file. In the ACE research paper, accepted at ICLR 2026, the method beat strong baselines by 10.6% on agent benchmarks and 8.6% on finance tasks. Choose fine-tuning instead when the model lacks a skill entirely, and keep a short static prompt when the task is simple and stable. In production, run every update through human approval, versioning and audit, because a self-updating playbook can learn the wrong thing as easily as the right one.
Key Takeaways
- Agentic context engineering (ACE) improves an AI agent by editing the context it reads, not the model it runs on.
- The context grows into a playbook of small, itemized strategies instead of one prompt that gets rewritten each time.
- Three roles do the work: a Generator runs tasks, a Reflector extracts lessons, and a Curator merges them as delta updates.
- The ACE paper reports gains of 10.6% on agent benchmarks and 8.6% on finance tasks, with 86.9% lower adaptation latency on average.
- It fits workflows with repeated failure patterns, a usable feedback signal, a review owner and an evaluation set.
- Because it updates itself, the playbook is a production asset that needs approval gates, version history, rollback and an audit trail.
On-Demand Webinar
Model Context Protocol (MCP): The Key to Building Context-Aware AI Agents
Watch Kanerika’s on-demand session on how MCP gives agents structured access to tools and data, the context layer a learning playbook builds on.
Watch the Webinar →The Agent That Makes the Same Mistake Every Monday
Picture an accounts payable agent that processes supplier invoices around the clock. Every Monday, one packaging supplier sends a credit memo with a negative line that points back to an open invoice. The agent flags it as a duplicate charge and routes it to a person.
An analyst fixes it in two minutes. She also notes in the ticket that this supplier always nets credits against an earlier invoice. The next Monday, the agent makes the exact same mistake, because nothing it learned was kept.
That gap is the whole problem. The model is capable, the tools work, and the correction exists in a ticket. What is missing, then, is a way for the lesson to travel from the ticket back into the agent’s working context.
Retraining the model for one supplier quirk would be slow and expensive, and it would also hide the fix inside weights nobody can read. Agentic context engineering takes the other route instead. This guide explains how that route works, where it pays off, and how to keep it under control in an enterprise.
What Is Agentic Context Engineering?
Agentic context engineering is a way to make an AI agent better at its job by improving what it reads, not what it is. To do that, the agent keeps a structured playbook of lessons. After each task, the outcome is studied, and useful lessons are written back into that playbook for the next run.
The term comes from a research paper, “Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models” (arXiv 2510.04618). Researchers from Stanford University, SambaNova Systems and UC Berkeley, led by Qizheng Zhang and Changran Hu, posted the first version on October 6, 2025. The latest version is dated March 29, 2026, and the paper was also accepted at ICLR 2026.
Definition: Agentic context engineering (ACE) treats an agent’s context as an evolving playbook of strategies learned from execution feedback. The agent improves over time, while the model weights stay fixed.
In the usual taxonomy of agents, this behavior belongs to learning agents, which change their future actions based on past results. What makes ACE different is where the learning lives: in plain, readable text that a team can inspect, edit and roll back.
An Evolving Playbook, Not a Longer Prompt
A prompt is usually one block of instructions that someone rewrites by hand. An ACE playbook, on the other hand, is a list of separate entries, each with its own id, scope and history. As a result, new lessons are added as entries, and weak ones are corrected or retired one at a time.
The difference matters, above all, once the agent has run thousands of tasks. A rewritten prompt tends to lose old detail each time it is condensed. A playbook keeps each lesson in its own slot, so a fix for one supplier does not quietly erase a fix for another.
The static side of context, such as how to select, compress and isolate information for a single call, is a separate discipline. Our guide to context engineering covers that layer. This article stays on the learning loop that sits on top of it.
Two Meanings of the Term
Vendors and blogs use the phrase in two ways, and the gap between them changes what you are buying. First, there is the specific ACE framework from the paper. Second, there is a loose label for any technique that manages what an agent sees.
| Meaning | What it refers to | How to tell in a vendor pitch |
|---|---|---|
| ACE research framework | A Generator, Reflector and Curator loop that updates an itemized playbook from execution feedback | The vendor can show the playbook, its update history and how a lesson gets approved or removed |
| General agent context management | Retrieval, memory, summarization and prompt templates for agents | Nothing in the system changes based on whether past tasks succeeded or failed |
Still, a simple test cuts through the marketing. Ask what happens to the agent’s context after a task fails. If the answer is “nothing until an engineer edits the prompt,” the product is context management, not ACE.
Why Deployed AI Agents Stop Improving
A deployed agent usually improves only when a person changes it. The prompt is written once, tested and frozen, while the business around it keeps moving. New suppliers, new policies and new edge cases arrive, and the agent meets each one as if for the first time.
That pattern is one of the quiet reasons why AI agents fail in production. Accuracy at launch looks fine, then a long tail of small, repeated errors builds up. Each error is cheap to fix by hand, yet the fixes never reach the agent.
Teams that try to automate prompt updates often hit two failure modes, which the ACE paper names directly. Teams that do not automate at all hit a third.
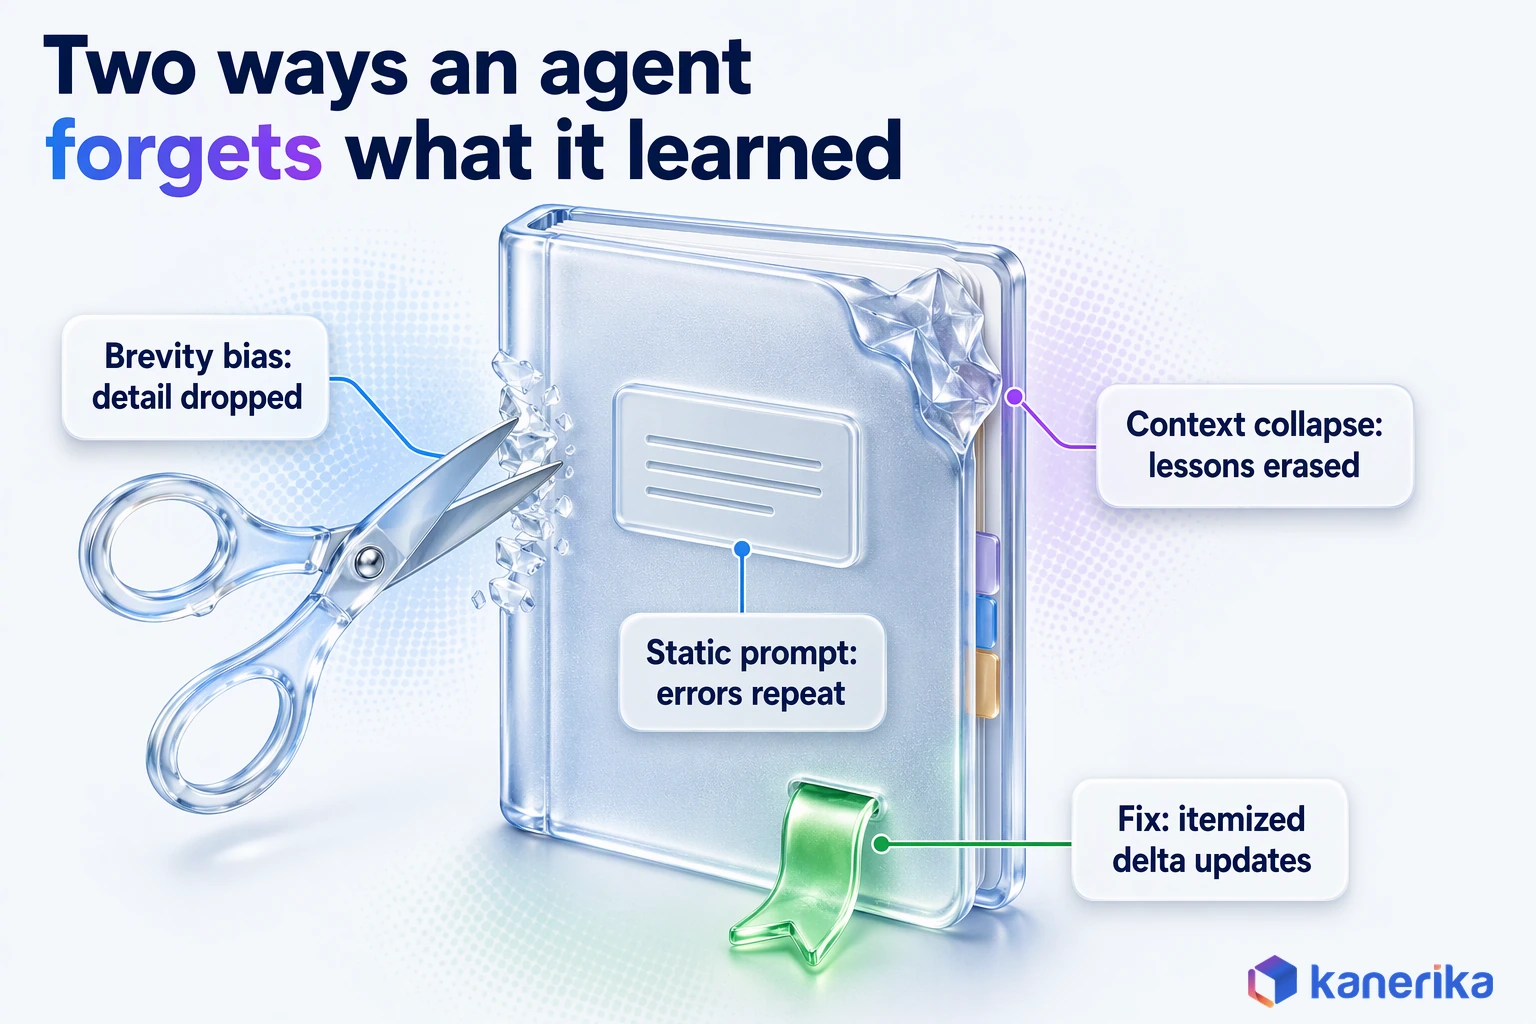
- Brevity bias. Prompt optimizers favor short, general instructions. In doing so they drop the domain detail, such as a specific supplier rule, that made the agent accurate in the first place.
- Context collapse. When a model rewrites the whole context at every step, it tends to compress it. Over many rounds, hard-won lessons get summarized into vague advice and then vanish.
- Static prompts. With no update loop at all, every correction stays in tickets and chat threads. The agent therefore repeats the same mistake until someone ships a new prompt.
In short, all three share one root cause. The agent has no durable, structured place to keep what it has learned, and no safe process for adding to it.
How the Generator, Reflector and Curator Loop Works
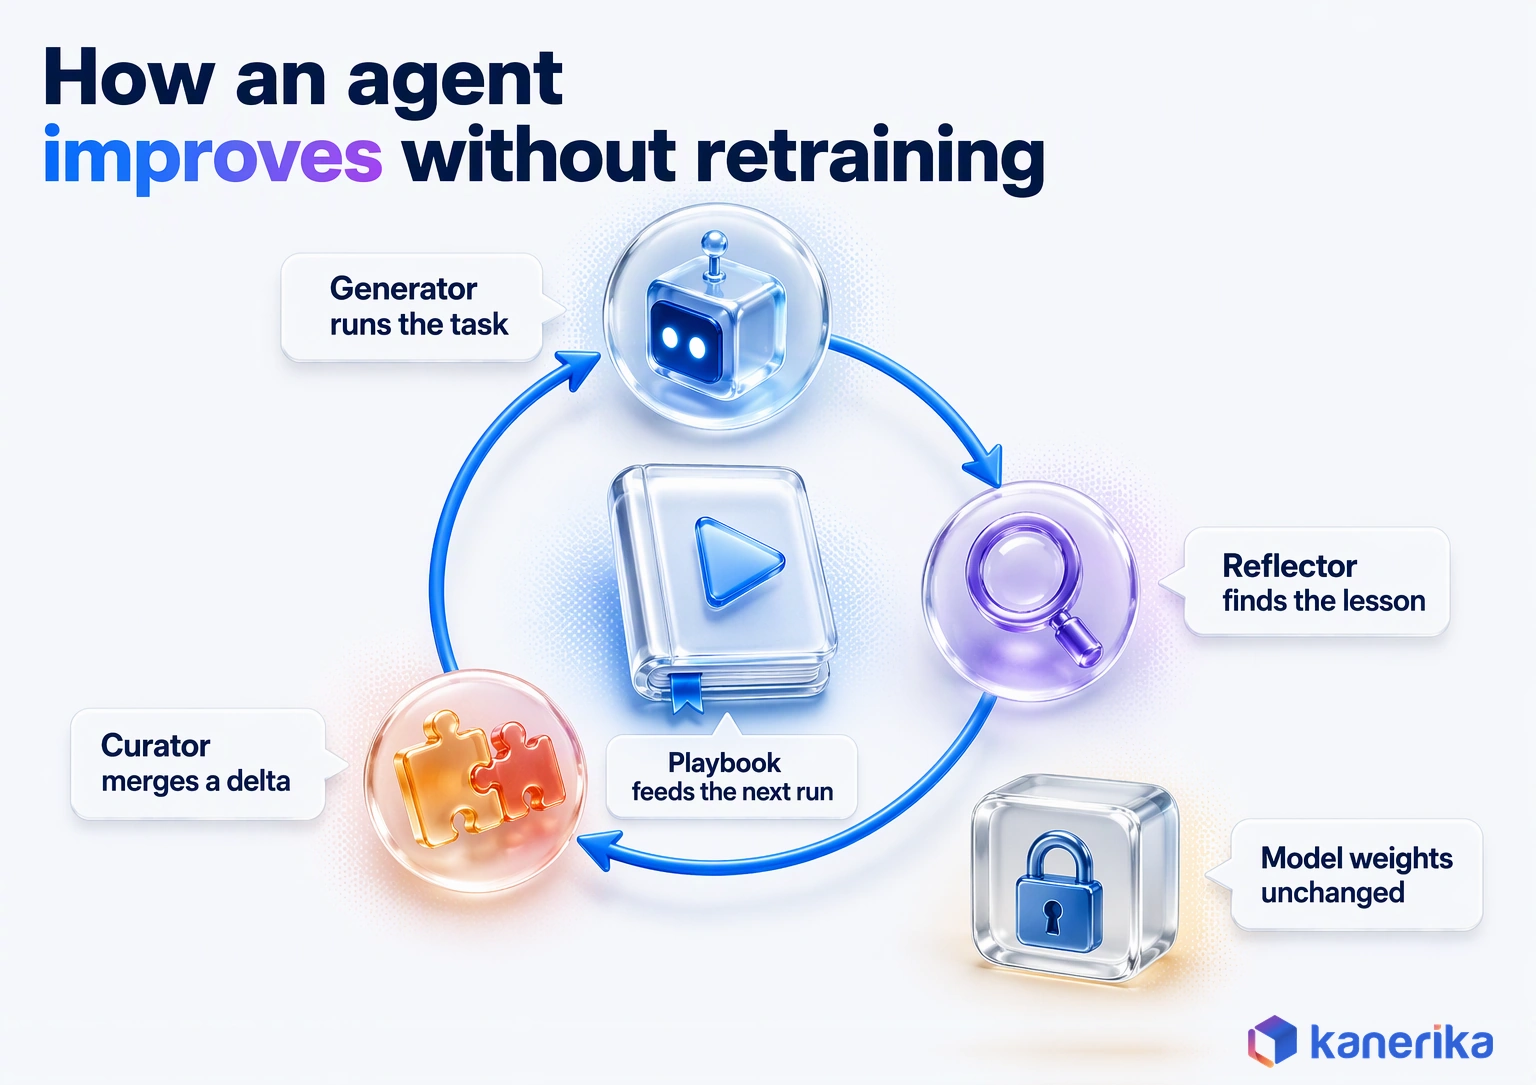
At the core of ACE sits a loop with three roles, each with one clear job. The split exists so that no single model call has to run the task, judge it and rewrite the rules at once.
The Generator does the actual work, such as answering a question or calling tools to complete a task. While it works, it can mark which playbook entries helped and which ones misled it. That trace then goes to the next role, along with the outcome.
The Reflector reads the trace and asks what went right, what went wrong and why. Next, it turns those answers into concrete lessons. The paper lets the Reflector refine its insights over several passes before handing them on, because the quality of the lesson depends on this step. In effect, the Reflector is an LLM acting as a judge of the agent’s own run, so the same reliability checks apply to it.
Lastly, the Curator decides what changes in the playbook. It converts lessons into small delta entries and merges them into the existing context. Entries are added, updated or marked as harmful, while the rest of the playbook stays untouched.
The paper ran all three roles on a single model, DeepSeek-V3.1 in non-thinking mode. The loop therefore needs three distinct jobs, each with its own instructions, rather than three different models. That keeps it simpler than a full multi-agent AI system, where separate agents hand work to each other.
Generator, Reflector, Curator: Who Does What
Each role has a clear input and output, and each one fails in a recognizable way when it is weak. The table below works as a checklist when you design or review an ACE pipeline.
| Role | Input | Output | What goes wrong if it is weak |
|---|---|---|---|
| Generator | New task plus the current playbook | Task result, reasoning trace, entries marked helpful or misleading | Ignores the playbook, so lessons never affect behavior |
| Reflector | Trace, outcome and any feedback signal | Specific lessons about causes and fixes | Produces generic advice or blames the wrong step |
| Curator | Lessons plus the existing playbook | Small delta entries merged into the playbook | Duplicates entries, bloats the context or overwrites good rules |
Incremental Delta Updates and Grow-and-Refine
Delta updates are what keep the playbook from collapsing. Instead of asking a model to rewrite the whole context, the Curator emits only the change, for example one new entry or one corrected rule. That change is merged by ordinary code instead of another model call.
Because the merge is plain logic, it cannot accidentally summarize away older entries. It also makes updates cheap, since only a small piece of text is produced per task. Because each delta is small and self-contained, several can be merged in parallel, which lets the loop learn from a batch of tasks at once.
Grow-and-refine handles the opposite risk of endless growth. New entries are appended freely, and each entry keeps counters of how often it helped or hurt. Then the playbook is cleaned, either after every update or only when it grows past the context limit. Near-duplicates are found through semantic similarity and merged, and low-value entries are also pruned.
The same grow-and-refine idea is showing up outside research. Nous Research’s open-source Hermes Agent, for instance, turns finished tasks into reusable skills. Kanerika’s podcast looks at why it is trending in “Hermes Agent: Why Is It Trending?”
Worked Example: One Invoice Exception Through a Full Learning Cycle
A concrete run makes the loop easier to judge than any diagram. Here is the Monday credit memo from the opening, followed through one complete cycle in a governed enterprise setup. The example is illustrative, but every step maps to a real control you would build.
- Failure. First, the Generator processes the packaging supplier’s credit memo. It reads the negative line as a duplicate charge and routes the document to the exception queue.
- Trace. The system records the task, the playbook entries the agent consulted, its reasoning and the final outcome. The analyst’s correction, “credit nets against open invoice,” is attached as the feedback signal.
- Reflection. Next, the Reflector compares the agent’s reasoning with the correction. It concludes that the agent never checked whether the negative line referenced an open invoice number.
- Candidate lesson. The Curator drafts one delta entry. It says that a negative line referencing an open invoice is a credit to be matched, not a duplicate.
- Scope and counterexample check. The entry is scoped to credit memos in the packaging category. It is then replayed against held-out past documents to confirm it does not misclassify real duplicates.
- Approval. After that, an accounts payable lead reviews the entry, the evidence traces and the replay result. She approves it, and it enters the playbook as a new version.
- Monitor. Finally, over the following weeks, the entry’s helpful and harmful counters are tracked. If harmful marks start to rise, the entry is sent back for review or rolled back.
What the Cycle Left Out
Notice what never happened in that cycle. Nobody retrained a model, opened a data science ticket or waited for a release train. The fix moved from a ticket into the agent in a form a finance lead could read and approve.
Teams that build agents as graphs can map this cycle almost one to one. Running LangGraph with MCP, for instance, the Generator, Reflector and Curator become separate nodes, with the approval step as an interrupt before the playbook write.
Checklist
Agentic AI Readiness Checklist
Use Kanerika’s agentic AI checklist to confirm owners, data access, feedback signals and human oversight before an agent starts learning from its own work.
Get the Checklist →What a Playbook Entry Looks Like
A playbook entry needs enough structure to be searched, scoped, audited and removed. The fields below are a practical minimum for enterprise use. In the research version, each entry has an id plus helpful and harmful counters, so governance adds the rest.
| Field | Purpose |
|---|---|
| id | Stable reference used in traces, reviews and rollbacks |
| scope | Where the rule applies, such as a supplier category or document type |
| rule | The lesson in plain language the agent can act on |
| evidence | Trace ids that produced or confirmed the lesson |
| helpful / harmful | Counters updated each time the entry is used |
| owner | The person accountable for approving and reviewing it |
| status | Candidate, approved, suspended or retired |
| expiry | A date or event that forces a fresh review |
Here is how the Monday credit memo lesson could look once approved. The format is only illustrative, so any store that keeps these fields and their history will do.
id: INV-047
scope:
  document_type: credit_memo
  supplier_category: packaging
rule: >
  A negative line that cites an open invoice number is a credit.
  Match it to that invoice before flagging any duplicate.
evidence: [trace-a91f, trace-b207, trace-c3d4]
counters: {helpful: 0, harmful: 0}
owner: ap-operations-lead
status: approved
version: 14
expiry: review on next supplier contract change
Every field also earns its place in an audit. Suppose an auditor asks why the agent treated a document a certain way. The trace then points to INV-047, and INV-047 points to its evidence and approver.
What the ACE Research Shows, and Its Limits
The research results are strong enough to take seriously and narrow enough to read carefully. The authors tested ACE on agent tasks and on financial reasoning, against strong existing methods, and reported both accuracy and cost.
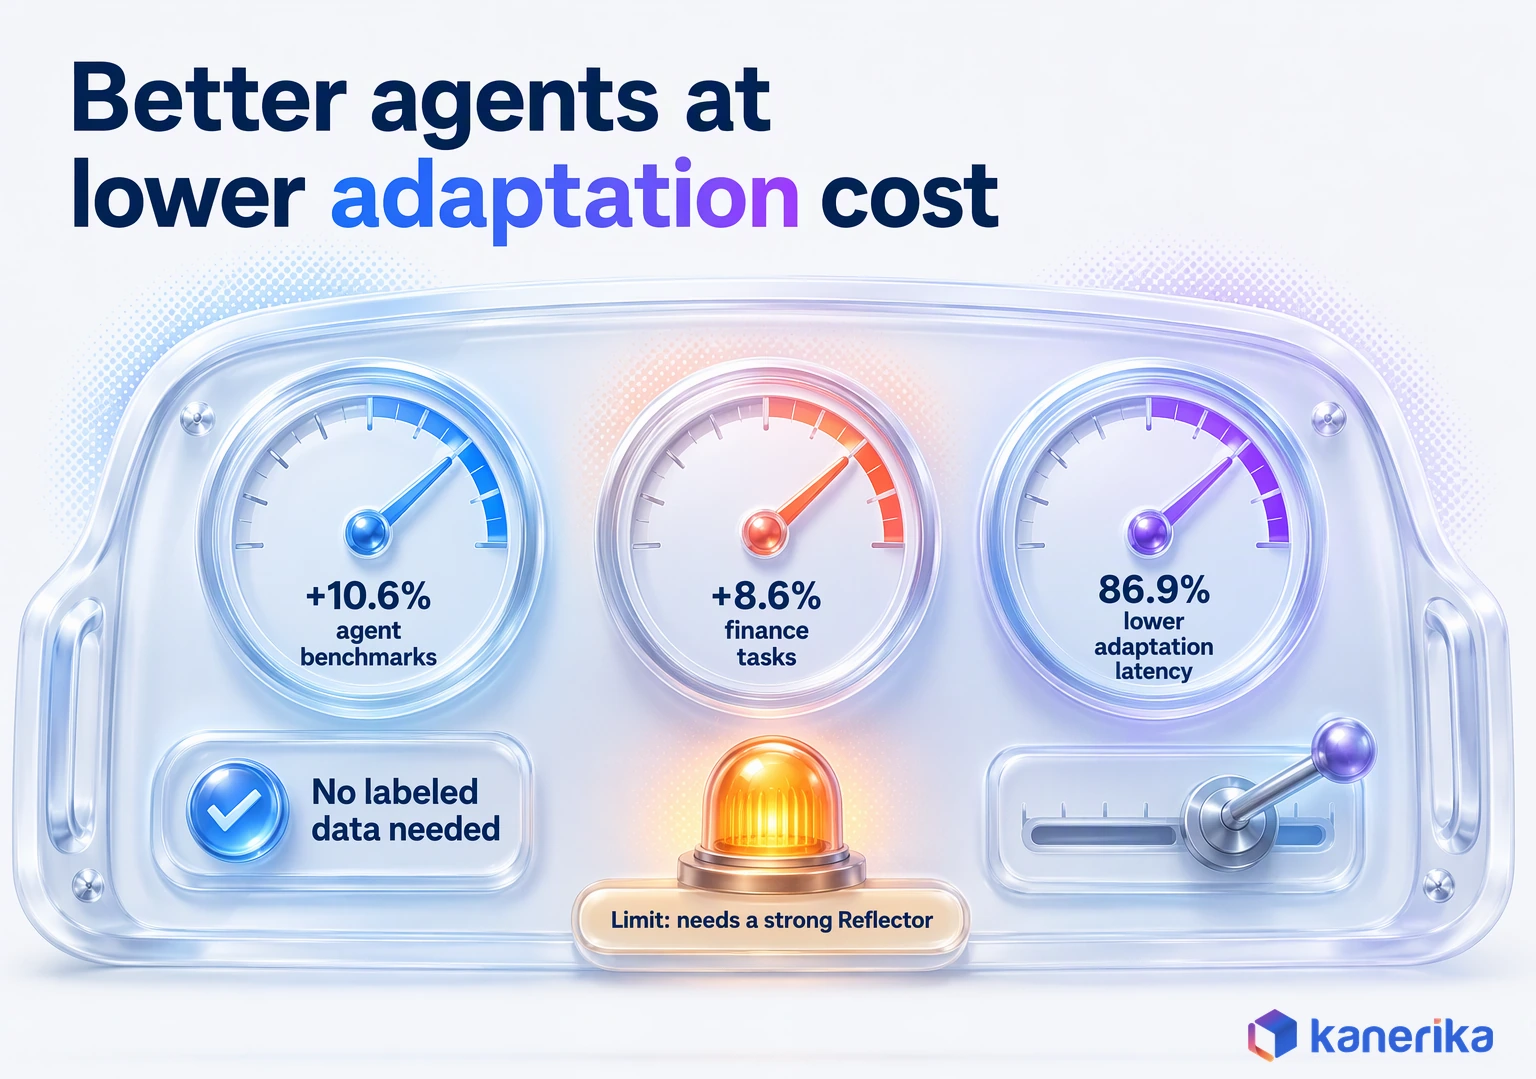
On the agent side, the main benchmark was AppWorld, where an agent completes multi-step tasks through app APIs. On the finance side, they used the FiNER and Formula benchmarks. The headline numbers, taken from the full paper, are below.
| Result | Reported figure |
|---|---|
| Agent benchmarks vs strong baselines | +10.6% |
| Finance benchmarks vs strong baselines | +8.6% |
| AppWorld gain without ground-truth labels | Up to 17.1% |
| Average adaptation latency | 86.9% lower |
| Offline AppWorld vs GEPA | 82.3% lower latency, 75.1% fewer rollouts |
| Online FiNER vs Dynamic Cheatsheet | 91.5% lower latency, 83.6% lower token cost |
Two findings stand out for enterprise teams. First, ACE learned from natural execution feedback, such as whether code ran or a task succeeded, without labeled training data. Second, it matched the top-ranked production agent on the AppWorld leaderboard, IBM-CUGA running GPT-4.1, on average. It also beat that agent on the harder test-challenge split while using the open-source DeepSeek-V3.1.
The authors are also clear about the limits. ACE depends on a reasonably strong Reflector, since a weak one produces noisy or misleading lessons. Some tasks, such as HotPotQA question answering, also benefit more from short, concise instructions than from a long, detailed playbook.
Benchmarks are not your workflow, either. The paper’s cost figures describe adaptation on research tasks. They are useful context for sizing, but they are not a promise about savings in an enterprise process with its own data, reviewers and volumes.
Anyone who wants to test the method directly can start from the authors’ open-source reference code, released under the Apache-2.0 license.
Agentic Context Engineering vs Prompt Optimization, RAG, Agent Memory and Fine-Tuning
ACE sits beside several techniques that also make agents better, and buyers often treat them as rivals. They are better read, however, as tools for different problems. The useful question is what each one changes, and what that costs when it is wrong.
Prompt optimization, for instance, tunes a single instruction block against a test set. It helps with tone, format and general task framing, yet it is prone to the brevity bias described above. The basics of that trade-off are covered in our comparison of context engineering vs prompt engineering.
Retrieval-augmented generation brings facts from documents into the context at query time. It answers what a policy says, not what the team learned the last time a case went wrong. Our guide to agentic RAG covers the retrieval loop in depth.
Agent memory, meanwhile, stores conversation history or user facts. An ACE playbook, by contrast, is closer to curated procedural knowledge. It holds strategies and rules with evidence and counters, rather than a log of what was said.
Talk to Kanerika
Choosing Between ACE, RAG and Fine-Tuning?
Talk to Kanerika about which technique fits your agent’s failure patterns, and what a governed first pilot would involve.
Schedule a Demo →What Each Technique Changes, Side by Side
The table compares the five options on what they change, what they fix and when each one is the better pick.
| Technique | What changes | What it fixes | Cost to change | Choose it when |
|---|---|---|---|---|
| Agentic context engineering | Itemized playbook entries | Repeated, fixable reasoning or policy mistakes | Low per update, plus review time | The same failure types recur and outcomes are observable |
| Prompt optimization | One instruction block | General framing, format and tone | Low, but each rewrite risks lost detail | The task is simple and stable |
| RAG | Retrieved documents per query | Missing or outdated facts | Medium, for indexing and upkeep | Answers depend on a changing document base |
| Agent memory | Stored history and user facts | Lost conversation or user context | Low to medium | Continuity across sessions matters |
| Fine-tuning | Model weights | Missing skills, style or domain fluency | High, with retraining to undo | The model cannot do the task even with good context |
In practice these layers stack. For example, a mature agent may use RAG for facts, memory for continuity and an ACE playbook for procedure. Fine-tuning stays the last resort, used when context alone cannot close the gap.
Offline, Online or Hybrid Adaptation: Which to Choose
An ACE loop can learn before deployment, during deployment or in a mix of both. The paper tested the first two modes, and the third is how most regulated enterprises will want to run it.
Offline adaptation builds the playbook on a training set before release, much like tuning a system prompt. Online adaptation updates the playbook while the agent serves real tasks, so it learns from live traffic. Hybrid adaptation lets the online loop propose candidates, but only approved entries reach the production playbook in scheduled releases.
| Mode | How it learns | Main risk | Our pick for |
|---|---|---|---|
| Offline | On a fixed training set before release | Misses new patterns after launch | A first pilot, or a workflow that rarely changes |
| Online | During live use, after each task or batch | Bad lessons reach users before anyone reviews them | Low-risk internal tasks with fast, clear feedback |
| Hybrid | Online candidates, offline-approved releases | Slower learning, plus reviewer workload | Finance, compliance and customer-facing work |
For that reason, our default for an enterprise starting out is hybrid. It keeps the learning signal from live work while a named owner decides what the agent is allowed to learn. Online mode can come later, for narrow tasks where a wrong lesson costs little and is caught fast.
Where Agentic Context Engineering Pays Off: Use Cases
The method fits best where an agent sees many similar tasks and the right answer depends on rules that are learned over time. Four patterns show up again and again in enterprise work.
Invoice and Document Exceptions
Accounts payable automation, claims intake and order processing all live on exceptions. Each supplier, insurer or customer also has quirks that no generic prompt covers. A playbook lets the agent absorb those quirks one approved entry at a time, as in the worked example above.
Kanerika Service
Agentic AI Services
Kanerika designs, builds and runs AI agents with evaluation sets, approval queues, versioning and audit trails, so learning agents reach production under control.
Explore Agentic AI ServicesCompliance Review
Policy checks often hinge on precedent: how a reviewer ruled on a similar case last month. Suppose, for instance, a reviewer rules that any marketing claim citing a third-party survey must show the survey date. The agent records that ruling as a scoped entry, with the decision as its evidence, and applies it to the next such claim. That evidence field also gives auditors the trail they ask for.
Support Triage
Ticket routing improves when the agent learns which symptoms point to which team. For example, imagine tickets that mention an “SSO loop” bouncing from Billing to Identity three times in one week. Each bounce is therefore a feedback signal. The Reflector then proposes a routing entry that sends those tickets straight to Identity, and the support lead approves it. Over time, routing rules accumulate in a form support leads can read. The same loop can sit on top of the AI agents for customer support compared in our buyer’s guide.
Financial Reasoning
The paper’s finance results came from FiNER, which labels financial entities in filings, and Formula, which tests numerical reasoning. Both reward domain-specific detail, exactly what brevity bias tends to remove. Teams doing financial document analysis should therefore treat those benchmarks as a signal worth testing on their own data, not as a guaranteed result.
A Five-Gate Decision Framework: When ACE Fits and When It Does Not
ACE is not the right answer for every agent, and building it where it does not fit wastes reviewer time. Five questions settle the decision. If any one of them gets a clear “no,” fix that first or choose another method.
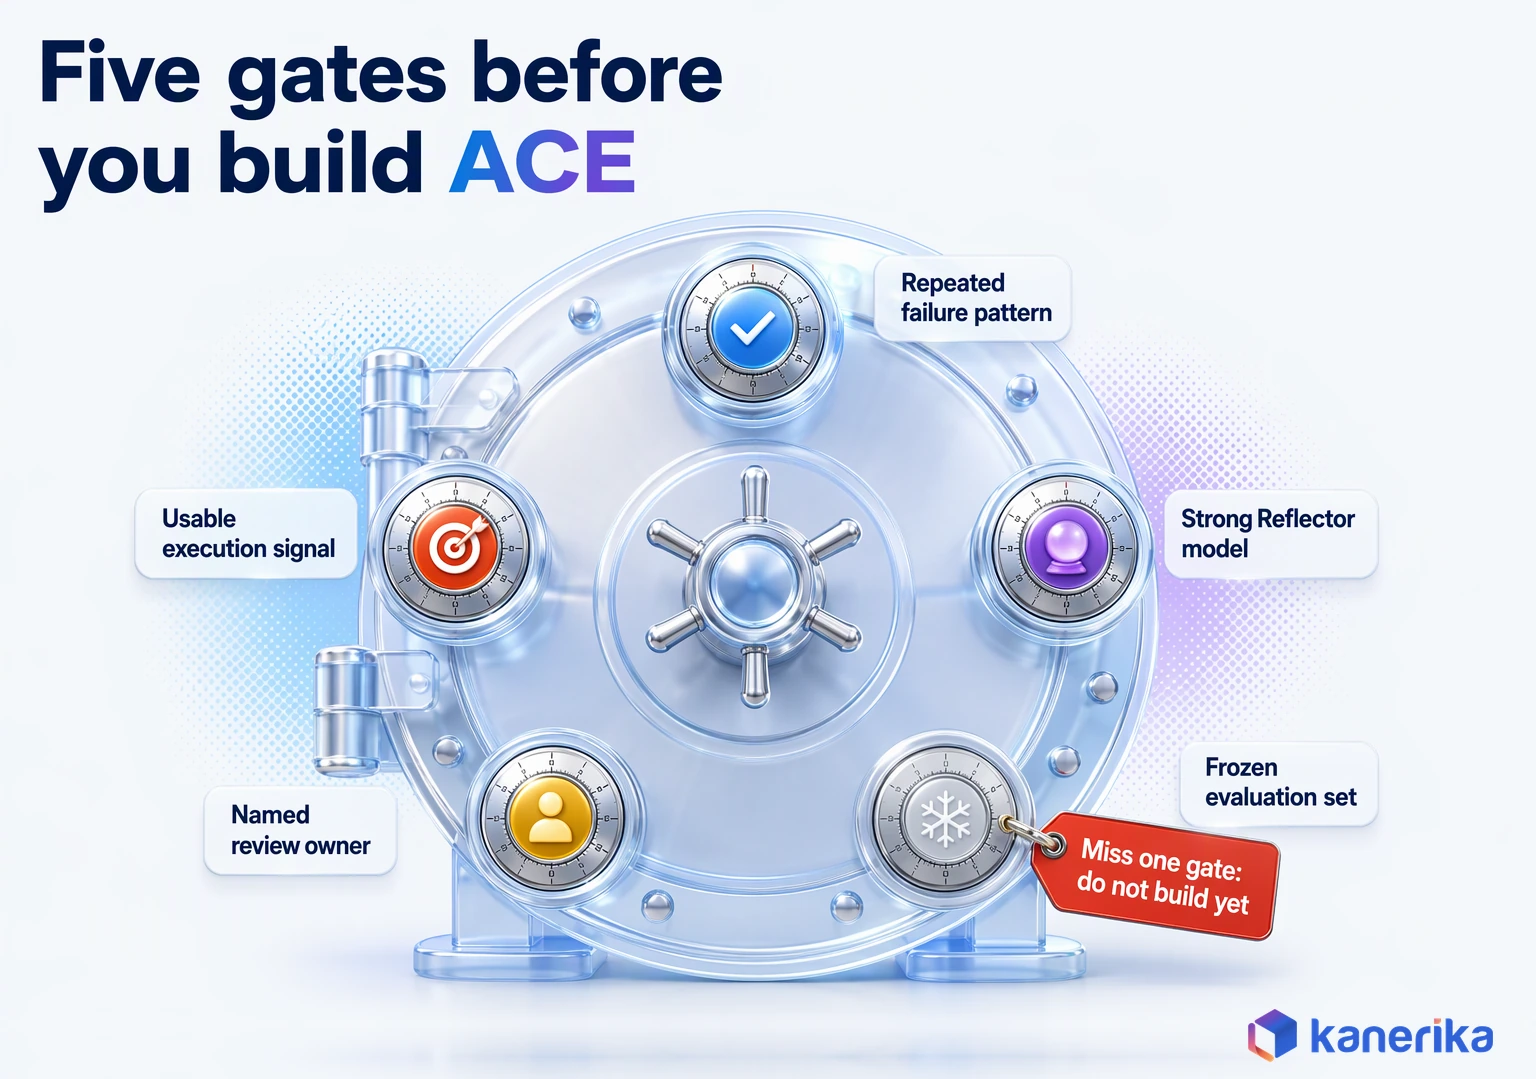
- Is there a repeated failure pattern? The agent must fail in recognizable, recurring ways. Random, one-off errors, on the other hand, give the Reflector nothing reusable to learn.
- Is there a usable execution signal? You need some way to know whether a task went well, such as a correction, a test result or a downstream reversal.
- Is the Reflector model strong enough? The paper’s own limitation applies here. A reasoning-capable model must be able to diagnose failures, or the playbook fills with noise.
- Is there a review owner? Someone in the business must approve, reject and retire entries. Without an owner, the playbook drifts with no one accountable. Our guide to human-in-the-loop AI agents covers which actions need that kind of sign-off.
- Is there an evaluation set? A frozen set of past tasks lets you prove that a new entry helps and does not break anything else.
Equally useful is knowing when not to use it. Skip ACE when the task is simple and a short prompt already works, as the HotPotQA finding suggests. Avoid it when the model lacks a basic skill, because no playbook will teach that, and parameter-efficient fine-tuning or a stronger model is the fix. And leave it out when no one can review the updates.
Choose Components by Capability, Not by Vendor Label
Many agentic AI tools advertise self-improvement, and the label alone tells you little. Instead, judge a stack by whether it provides four capabilities.
- A playbook store that keeps entries as separate records with scope, evidence and status.
- Versioning so every playbook state can be named, compared and restored, as part of wider AI agent lifecycle management.
- An evaluation harness that replays held-out tasks with and without a candidate entry, the same discipline used in agentic AI testing before release.
- An approval queue where owners see each candidate with its evidence before it goes live.
Take the credit-memo lesson from the worked example. INV-047 lives in the store as one record with its scope and evidence, and version 14 is the playbook state it entered. Replays against held-out documents tested it, and the approval queue is where the accounts payable lead saw it first.
These four capabilities sit around the agent rather than inside it. Check each one separately, whichever of the code-first AI agent frameworks you pick to run the three roles.
The playbook also sits beside the agent’s connections to tools and other agents. If your architecture uses MCP and A2A protocols, treat the playbook as one more governed resource, read under the same access controls as any other tool or data source.
AI Assessment
How Ready Is Your Team for Self-Improving Agents?
Score your AI maturity across data, governance and operations, and see which gaps to close before you add a learning loop to an agent.
Start Your AI Assessment →How to Measure Improvement, Cost and Operating Effort
A self-improving agent should be able to prove it is improving. The measurement plan has to be able to show the opposite too, or it is not measurement. That means a baseline, a hold-out set and a way to switch the playbook off.
Start by freezing an evaluation set of past tasks with known good outcomes, and keep it out of the learning loop. Then run an ablation: the same agent with the playbook on and with it off. If the gap does not show up on tasks the playbook never saw, the agent has memorized rather than learned. Our LLM evaluation framework guide covers the metrics and release gates for that set.
Cost and effort also belong in the same scorecard. A playbook that raises accuracy while doubling reviewer workload may not be worth it. Track these measures from the first pilot.
| Measure | What it tells you | Warning sign |
|---|---|---|
| Task success on the hold-out set | Whether learning generalizes | Gains appear only on training tasks |
| Playbook-off ablation gap | How much the playbook itself contributes | Gap near zero after many entries |
| Repeat-error rate | Whether known failures stop recurring | The same exception types keep returning |
| Cost per successful task | Model and tool spend per good outcome | Rising as the context grows |
| Reviewer minutes per approved entry | Human effort the loop consumes | Review backlog grows week over week |
| Playbook size and growth | Whether refine steps keep it lean | Steady growth with many near-duplicates |
The paper’s latency and token savings are a reasonable reference point for adaptation cost. Even so, your own numbers will depend on task volume, model pricing and how many candidates reviewers must read.
Governing a Self-Updating Playbook: Poisoning, Rollback and Audit
A system that learns from feedback can be taught the wrong thing on purpose. Governance for a learning agent therefore starts from that fact. Every path that writes to the playbook is a path an attacker or a careless input can use.
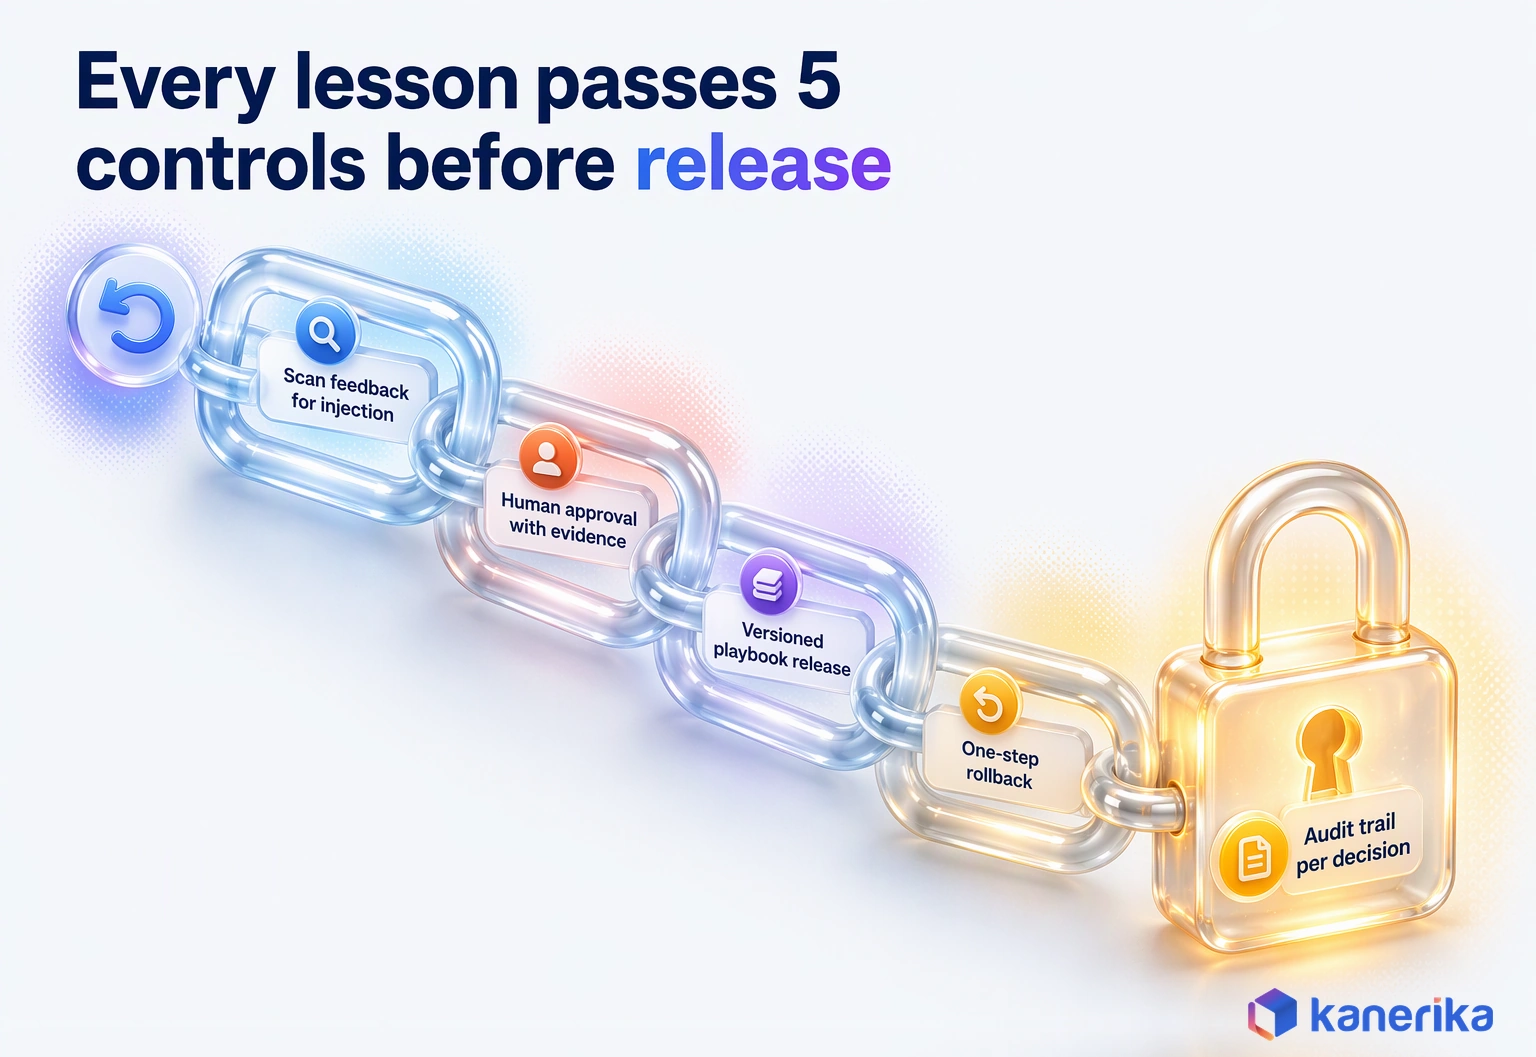
The OWASP Top 10 for LLM Applications 2025 names the main risks. Prompt injection (LLM01) can arrive through feedback text, such as a ticket comment written to look like an instruction. Data and model poisoning (LLM04) also covers lessons that slowly bias the agent. Sensitive information disclosure (LLM02) applies when a learned rule captures a customer name or account number.
Excessive agency (LLM06) is the fourth concern. A playbook entry should never grant the agent new permissions or tools; it can only guide how existing ones are used. That boundary belongs in the Curator’s instructions and in code, alongside the AI agent guardrails that limit what each tool call may do.
Controls That Map to OWASP and NIST
Each risk above has a matching control, and most of them are ordinary engineering practice applied to a new kind of asset.
| Risk | Control |
|---|---|
| Injection through feedback (LLM01) | Treat feedback as data, scan it, and never copy it into a rule verbatim |
| Poisoned lessons (LLM04) | Human approval, counterexample replay and harmful-count alerts |
| Sensitive data in rules (LLM02) | Redaction before storage and a deletion path that reaches every playbook version |
| Excessive agency (LLM06) | Entries guide behavior only; permissions stay in code and access policy |
| Bad release | Versioned playbook with one-step rollback to the last good state |
| Unexplained decisions | Audit trail linking each decision to entry ids, evidence and approver |
These controls also map well to the NIST AI Risk Management Framework. Its Generative AI Profile, NIST AI 600-1, was released on July 26, 2024. The profile calls for documented provenance, monitoring and incident response, all of which an entry-level audit trail supports. Our NIST AI RMF playbook guide shows how to apply the framework without turning it into a checklist.
Deletion, in particular, deserves special care. If a customer asks for their data to be removed, the request must reach every playbook version and backup that might hold it. For the wider program around policies, roles and reviews, see our guide to agentic AI governance.
Agents rarely go wrong in one dramatic step. Instead, they drift through a series of small, unreviewed changes, which is exactly what an ungoverned learning loop produces.
How Kanerika Delivers Self-Improving Agents in Stages
Kanerika builds enterprise agents so that learning is earned, measured and reversible. The work runs in five stages, and each stage closes only when its exit check is met.
The order is deliberate. On the expert-network project described below, sourced context alone produced the measured gains, with no learning loop at all. That is why stages 1 to 3 come before any Reflector is switched on.
The Five Stages and What Each One Checks
Each stage below pairs our standard step with what the expert-network project showed about it in practice.
- Workflow diagnosis and failure-pattern mining. We study tickets, corrections and logs to find the errors that repeat, and confirm that an execution signal exists. On the expert-network project, the manual process spanned three disconnected systems, and mismatch tickets were the clearest failure signal.
- Evaluation set and baseline. We freeze a hold-out set of real tasks and measure the current agent before any learning starts. Pick measures the business already tracks; that case page reports its results as mapping accuracy and mismatch tickets.
- Playbook schema, store and versioning. We define entry fields, scopes and owners, and set up a store where every state can be compared and restored. Structure comes first for a reason: the expert-network agent matched people by semantic search across three named dimensions, skills, domains and expertise levels.
- Reflector and Curator with a human approval queue. Candidate lessons reach business owners with evidence and replay results before anything changes. The expert-network dashboard followed the same principle, showing each recommendation with its context and source links, which removed manual triage.
- Governed production. Approved entries ship in versioned releases, with rollback, drift monitoring through AI observability tools and an audit trail from day one. Compliance sits inside the loop too, as on that project, where checking compliance data during validation meant fewer compliance issues and fewer escalations.
Through our agentic AI services, these stages follow the same delivery model as any production agent we build. Security, access control and monitoring are built in from the start.
Case Study: 80% Fewer Mismatch Tickets with a Context-Aware AI Agent
A self-improving agent needs a solid context foundation before any learning loop is added. This Kanerika project did not add a learning loop; it shows what a solid context foundation delivers before one is added.
The client is a global leader in facilitating knowledge-sharing between industry experts and decision-makers, with a network of over one million subject-matter experts. Poor search led to inaccurate expert recommendations. Manual validation across disconnected tools raised effort and error rates, and frequent rework also delayed survey delivery.
Kanerika built a context-aware AI agent that read each survey request and matched experts by semantic search. It then validated every shortlist automatically against past participation, survey history and compliance data. Results appeared on one unified dashboard, and the internal time this freed up went to high-impact work instead of rework.
The case study page reports a 40% increase in mapping accuracy, an 80% decrease in mismatch tickets and 22% bandwidth savings. That kind of structured, sourced context is what an ACE loop builds on. A playbook can only refine decisions the agent can already see and explain.
Case Study
80% Fewer Mismatch Tickets with Context-Aware AI
A global expert network used a context-aware AI agent to cut mismatch tickets by 80%, raise mapping accuracy by 40% and free 22% of team bandwidth.
Read the Case Study →So, How Do AI Agents Improve Without Retraining?
AI agents improve without retraining when their context learns instead of their weights. Agentic context engineering does this with a loop. First the Generator acts, then the Reflector diagnoses, and finally the Curator writes small, itemized lessons into the playbook. Because those lessons are plain text with ids, evidence and owners, they can be reviewed, measured and rolled back.
The research shows real gains, and the limits are just as real: a strong Reflector, a usable feedback signal and a review owner are prerequisites. So start with one workflow that repeats the same mistakes, measure it against a frozen baseline and run updates through approval. That is how an AI agent gets better every week while the model underneath stays exactly the same.
Frequently Asked Questions
What is agentic context engineering?
Agentic context engineering is a method for improving AI agents by evolving the context they read instead of retraining the model. The agent keeps a playbook of itemized lessons drawn from execution feedback. A Generator runs tasks, a Reflector extracts lessons and a Curator merges them, so the agent gets better while the model weights stay fixed.
How is agentic context engineering different from prompt engineering?
Prompt engineering writes and tunes one block of instructions, usually by hand, and each rewrite can drop useful detail. Agentic context engineering keeps separate playbook entries that are added, corrected or retired based on how real tasks turned out. The context changes from feedback in small steps, and each entry keeps its own evidence and history.
Does agentic context engineering change model weights?
No. The model stays exactly as it is, and only the playbook text the agent reads is updated. That makes changes faster and cheaper than fine-tuning and easier to inspect, since every lesson is readable. It also means a bad lesson can be rolled back by restoring an earlier playbook version instead of retraining anything.
When should an enterprise use agentic context engineering?
Use it when an agent fails in recurring patterns, outcomes are observable, a capable model can act as Reflector, a business owner will review updates and an evaluation set exists. Avoid it for simple, stable tasks where a short prompt works, or when the model lacks a basic skill, which calls for fine-tuning or a stronger model.
How do you prevent context poisoning in a self-improving agent?
Treat all feedback as untrusted data and scan it for injected instructions. Route every candidate entry through human approval with its evidence and a replay against held-out tasks. Track harmful counts and alert on spikes. Keep the playbook versioned so any bad release can be rolled back in one step, and log which entries shaped each decision.
How do you measure whether an AI agent is improving?
Compare the agent against a frozen baseline on a hold-out set the playbook never learned from. Run an ablation with the playbook switched off to isolate its effect. Track repeat-error rate, cost per successful task, reviewer minutes per approved entry and playbook growth, so accuracy gains are weighed against the effort they consume.
Why is agentic context engineering important for AI agents?
Deployed agents usually stop improving once their prompt is frozen, so corrections stay in tickets and the same errors repeat. Agentic context engineering gives those corrections a durable home the agent reads on every task. It also avoids brevity bias and context collapse, two failure modes that erase domain detail when prompts are rewritten automatically.
What are the core components of agentic context engineering?
There are three roles and one artifact. The Generator performs tasks and marks which playbook entries helped. The Reflector studies traces and outcomes to find lessons. The Curator turns lessons into small delta entries merged by ordinary code. The playbook itself holds those entries with ids, scope, evidence and counters of helpful and harmful use.
How does agentic context engineering make AI agents self-improving?
Each completed task produces a trace and an outcome signal, such as a correction or a test result. The Reflector explains what went right or wrong, and the Curator records the lesson as a scoped playbook entry. On later tasks the agent reads that entry, so a mistake fixed once stops recurring without any change to model weights.
What role does memory play in agentic context engineering?
Agent memory usually stores conversation history or facts about users, which keeps continuity across sessions. An ACE playbook is a different kind of memory, closer to procedural knowledge. It holds rules and strategies learned from outcomes, each with evidence and an owner. Many production agents use both, plus retrieval for documents, as separate layers.
What challenges can agentic context engineering solve?
It targets repeated, fixable mistakes that a capable model keeps making because nothing it learned was kept. It also counters brevity bias, where prompt optimizers drop domain detail, and context collapse, where repeated rewrites shrink hard-won lessons into vague advice. Exception handling, compliance precedent and ticket routing are typical problems it helps with in enterprises.
How do enterprises implement agentic context engineering?
Start with one workflow that has recurring failures and a clear feedback signal. Freeze an evaluation set and measure a baseline. Define a playbook schema with scope, evidence, owner and status, then add a Reflector and Curator that send candidates to a human approval queue. Release approved entries in versions with rollback and monitoring.
Is agentic context engineering the same as context engineering?
No. Context engineering is the broader practice of choosing, compressing and arranging what a model sees on each call. Agentic context engineering, from the ACE research paper, adds a learning loop on top, where execution feedback updates an itemized playbook over time. Some vendors use the terms loosely, so ask whether outcomes change the context.
How is agentic context engineering different from RAG?
Retrieval-augmented generation pulls facts from documents into the context at query time, which helps when answers depend on changing content. Agentic context engineering stores lessons learned from the agent’s own successes and failures. RAG answers what a policy says, while an ACE playbook records how to handle a case that went wrong before.