TL;DR
AI data management uses machine learning to find, check, match and classify data, and the platform to pick depends on your biggest gap. Choose Ataccama ONE when data quality is the problem, and Informatica IDMC when integration and master data come first. Pick Collibra for governance and stewardship, Alation for search and discovery, and Microsoft Purview if your estate runs on Microsoft and Fabric. Let AI automate low-risk work such as profiling and anomaly alerts, and keep people approving merges, access rules and deletions. Gartner reported in February 2025 that 63% of organizations lack, or are unsure they have, the right data management practices for AI. Start with one data domain, measure discovery time and error rates, then scale what the pilot proves.
Key Takeaways
- AI data management uses machine learning to profile, check, match, classify and monitor data, so people stop doing that work row by row.
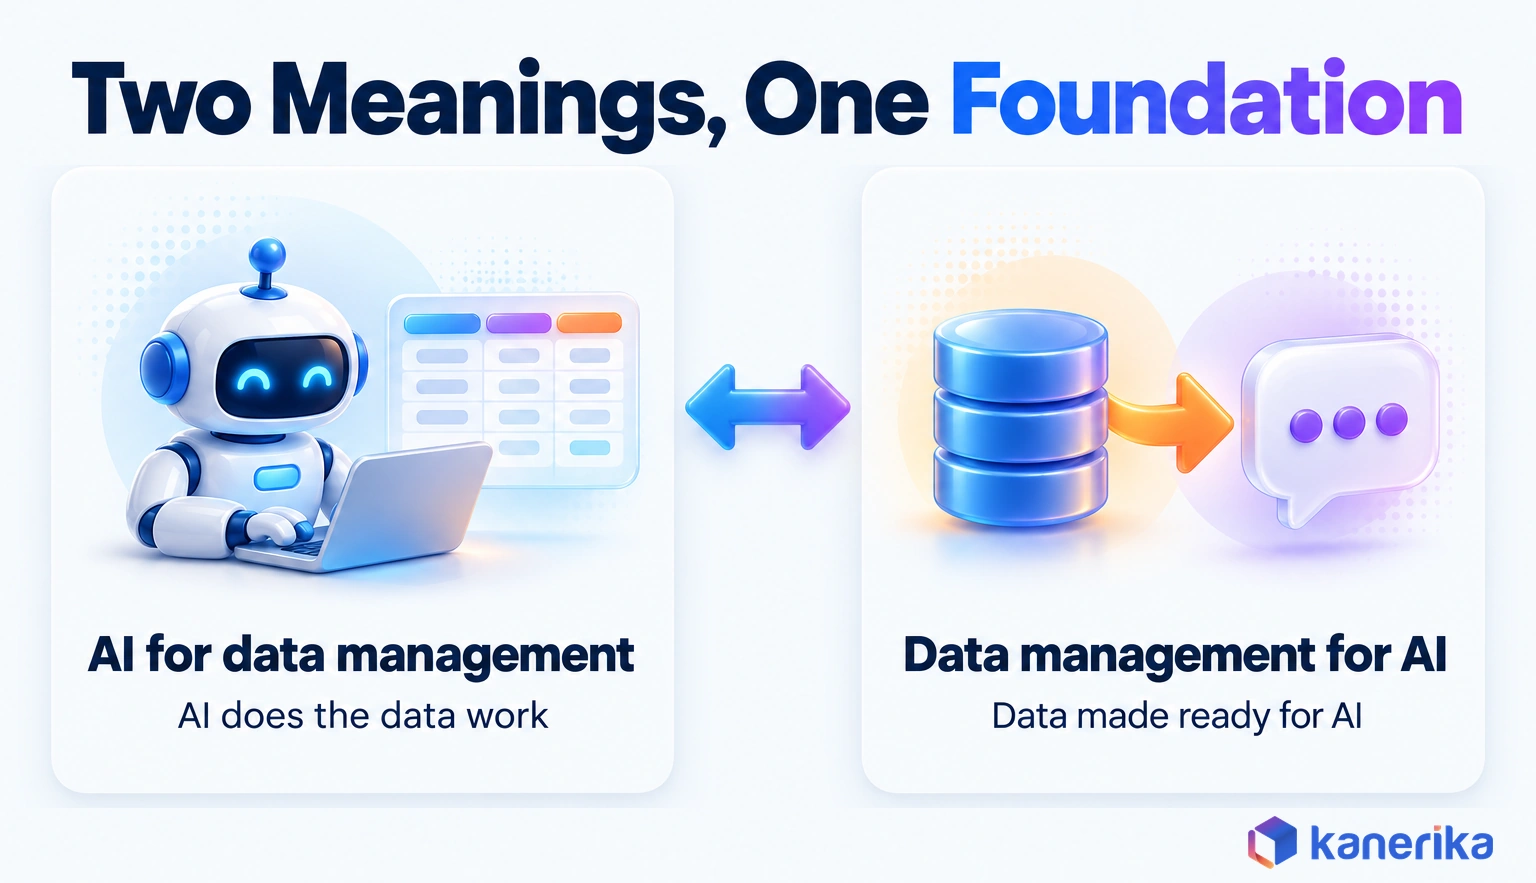
- The term also has two meanings: AI that does data management work, and data management that makes data ready for AI.
- Ataccama ONE, Informatica IDMC, Collibra, Alation and Microsoft Purview each lead for a different job, so match the platform to your biggest gap.
- Let AI automate low-risk checks and recommend mappings and tags, while people approve merges, access changes and deletions.
- Prove value in one data domain with measured discovery time, error rates and steward hours before you scale.
- Budget for five cost lines, including steward time, because only Microsoft publishes list prices among these five platforms.
Watch on YouTube
State of Enterprise AI 2026: Data Foundations, Maturity Stages & ROI
Kanerika walks through the data foundations, maturity stages and ROI questions behind enterprise AI. Watch it alongside this guide to see why data readiness shapes what AI can deliver.
When One Bad Record Reaches Every Dashboard and Every AI Answer
Picture a mid-size insurer that stores the same customer twice. The policy system holds “J. Alvarez” at one address, and the claims system holds “Jose Alvarez” at another.
Nobody notices at first. The quarterly retention forecast counts him as two people, one active and one lapsed. Then the new AI service assistant reads the same data. So when a call center rep asks about him, it says he has no open claim.
Neither system is broken, and every pipeline job reports success. The fault is a matching problem, and it now surfaces in two places at once.
That is also why data management and AI now sit in the same conversation. Gartner reported in February 2025 that 63% of organizations either do not have or are unsure if they have the right data management practices for AI. The same release predicts that through 2026, organizations will abandon 60% of AI projects unsupported by AI-ready data.
This guide explains what the practice involves, where it works across the data lifecycle and what it should never do alone. It then compares five platforms, gives you a way to choose between them, and closes with costs, risks and a rollout plan.
What Is AI Data Management?
AI data management is the use of machine learning and generative AI to automate the routine work of finding, cleaning, matching, classifying and governing data. It turns manual stewardship tasks into suggestions, checks and alerts that people review, so trusted data reaches reports and AI systems faster.
The idea is easy to grasp once you see the work it replaces. Before, a data steward wrote a rule for every bad postal code and scanned new tables by hand for personal data. The same steward also compared customer lists in spreadsheets. AI models now take the first pass on each of those jobs, while the steward handles the edge cases.
The phrase also carries a second meaning, which causes confusion in vendor pitches and search results alike.
AI for Data Management vs Data Management for AI
AI for data management means AI doing the work. So a model might suggest a quality rule, flag a tax ID column, or propose that two supplier records describe the same company.
Data management for AI runs the other way. Here the goal is making data fit for AI to consume. That includes training sets, the documents behind a retrieval system and the tables an AI agent queries. That work covers ownership, quality thresholds, lineage, access rules and freshness.
Real programs usually need both, because the same weak spots hurt in both directions. A catalog that AI helped build is also what tells an AI agent which table is the approved source. This guide covers the first meaning in depth, then gives the second its own section on unstructured data, RAG and agents.
Traditional vs AI-Assisted Data Management
The quickest way to see the difference is task by task. In each row below the traditional method still works, but it scales with headcount, while the AI-assisted method scales with data volume.
| Task | Traditional approach | AI-assisted approach | Who still decides |
|---|
| Discovery | Interviews and manual scans of each new source | Automated scans profile tables and suggest what each one holds | Data owner confirms |
| Quality rules | Engineers hand-code checks column by column | Models propose rules from observed patterns and adapt thresholds | Steward approves each rule |
| Matching | Exact-match keys and spreadsheet reviews | Fuzzy, probabilistic matching scores likely duplicates | Steward approves merges |
| Classification | Manual tagging of sensitive fields | Pattern and content recognition suggests tags such as PII | Privacy lead confirms |
| Lineage | Diagrams drawn from interviews | Lineage harvested from metadata and query logs | Owner validates key flows |
| Monitoring | Scheduled reports reviewed after the fact | Anomaly detection alerts when values or volumes drift | On-call owner triages |
The last column matters most. AI changes who does the first pass, while accountability stays with a named person.
A sensible starting point is data profiling, since every AI feature in the table depends on an accurate picture of what the data holds today. Until that picture exists, a model has nothing reliable to learn from.
Where AI Works Across the Data Lifecycle
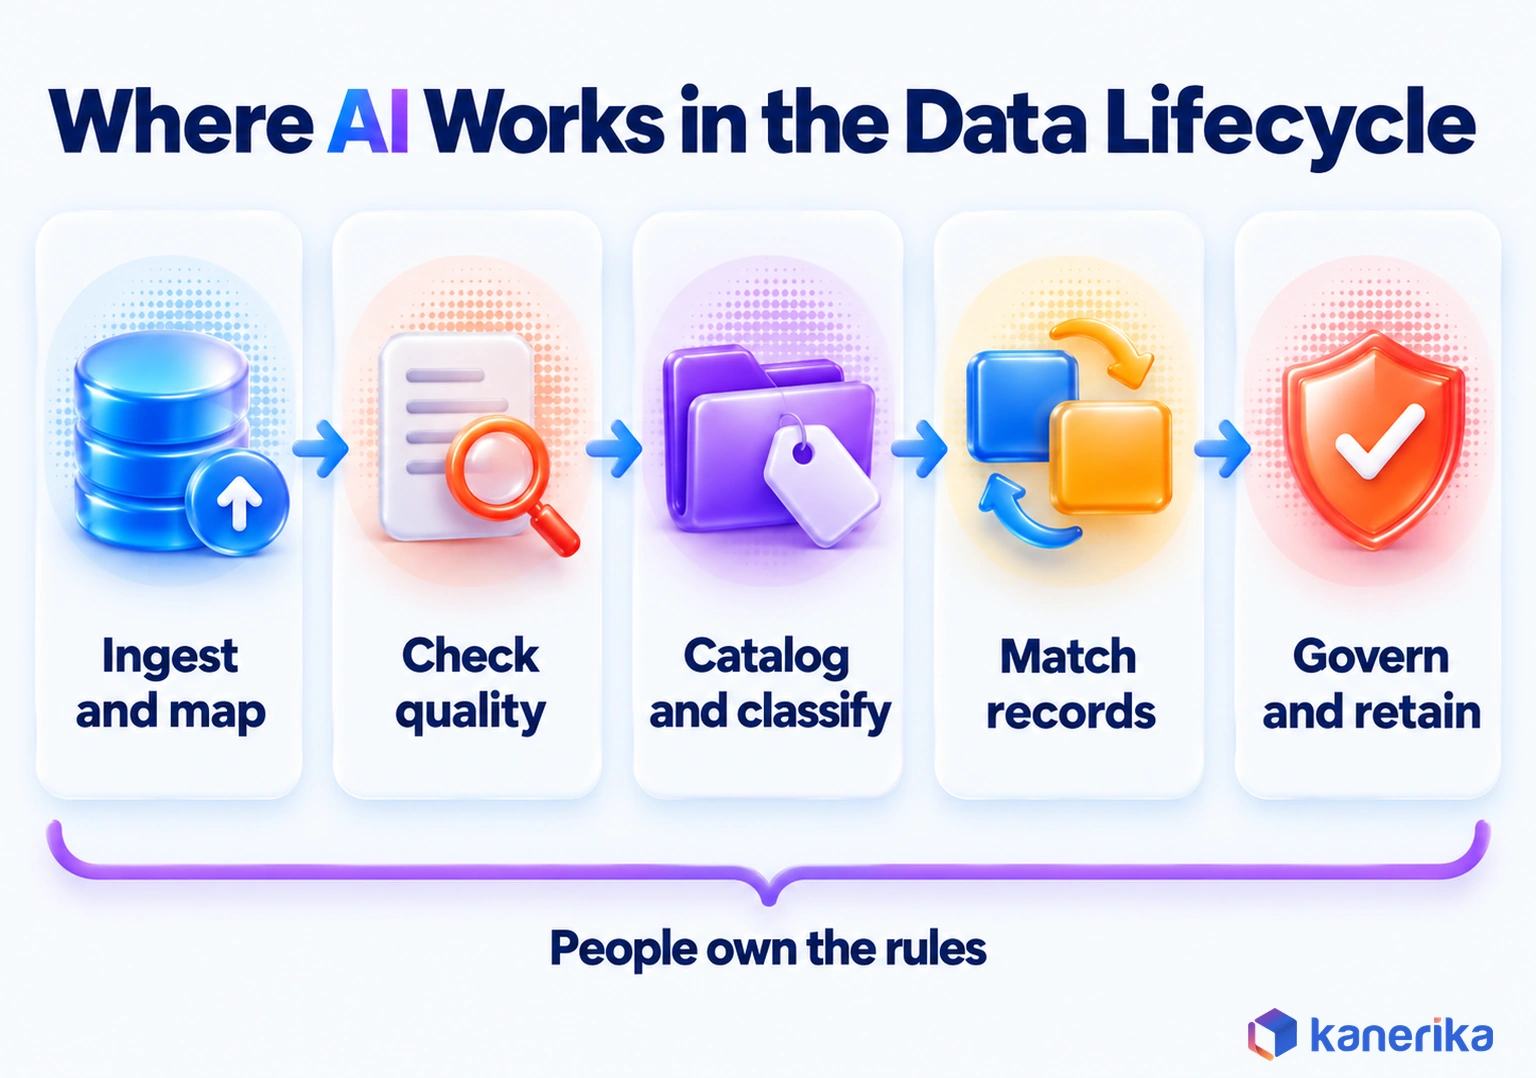
AI is most useful where data work is repetitive, high-volume and pattern-based. That covers almost every stage of the data lifecycle, from the moment a new source arrives until the day old records are archived.
The value differs by stage, so it helps to walk through them in order. Each stage below explains what AI does, what it saves and where a person still has to sign off.
Ingestion and Integration
New sources rarely arrive with clean, documented schemas. AI-assisted integration tools compare incoming fields with known ones and suggest mappings. For example, a tool may propose that “cust_no” in a new CRM export matches “customer_id” in the warehouse.
That suggestion saves hours per source, but a wrong mapping silently corrupts every table downstream. So the right pattern is suggest, then review, then lock the mapping under version control.
Teams building the flows themselves can follow the patterns in our guides to AI data pipelines and automated data integration. Both also cover validation at load time, which catches what a mapping review misses.
Data Quality and Anomaly Detection
Classic quality checks catch only what someone thought to write a rule for. Anomaly detection instead learns what normal looks like for each table, such as daily row counts, null rates and value ranges. It then alerts when a load drifts outside that range.
Picture an order table that usually grows by 40,000 rows a day and suddenly grows by 4,000. No rule says “flag a 90% drop,” but a model trained on the table’s history spots it within one load. This is the core of data observability, and it pairs well with automated cleaning for known, low-risk fixes such as standardizing date formats.
Quality also has two sides that teams often blur. Our explainer on data integrity vs data quality separates them, which helps when you decide which checks a model should own.
Metadata, Cataloging and Classification
A catalog is only useful while it is current, and manual cataloging never keeps up with new tables. So AI scans sources, writes draft descriptions, links columns to business glossary terms and suggests sensitivity tags.
Classification is where this pays off fastest, especially for personal data. For example, a column named “field_17” may hold national ID numbers or email addresses, and a model can still recognize them. Sensitive data then gets tagged before anyone queries it.
Because cataloging and classification share the same scans, many teams buy them together. You can compare the options in our review of metadata management tools.
Master Data Matching and Deduplication
The insurer in the opening scenario had exactly this problem, since its two records never matched. Exact matching treats “Jose Alvarez” and “J. Alvarez” as two different people. Machine learning matching instead scores the pair on name, address, birth date and history, then ranks how likely they are to be the same person.
High-confidence pairs can merge automatically under strict rules, while borderline pairs go to a steward queue. That split keeps the steward’s day focused on a few dozen hard cases instead of thousands of easy ones.
Governance, Access and Lineage
Governance work is mostly about knowing who owns data, who can see it and where it flows. AI helps by harvesting data lineage from metadata, suggesting owners from usage patterns and flagging access that looks unusual for a role.
The policies themselves stay human decisions. A model can suggest that a finance analyst should not see raw salary data. Still, a data owner sets the rule, and access controls enforce it. If your team is unsure where IT policy ends and data policy begins, our guide to IT governance vs data governance draws that line.
Datasheet
Elevate Data Governance, Compliance and Security of Your Organization
Kanerika’s data governance datasheet covers how it approaches governance, compliance and security programs for enterprise data.
View the Datasheet →
Retention and Archiving
Old data costs money to store, and it creates risk once it outlives its legal purpose. AI can help by finding tables nobody has queried for many months, grouping records by retention class and proposing candidates for archiving or deletion.
Deletion, however, is the one action here that cannot be undone. So treat AI output as a proposal list that legal and the data owner approve, and keep an audit trail of every decision.
What AI Should Automate, Recommend, or Leave to People
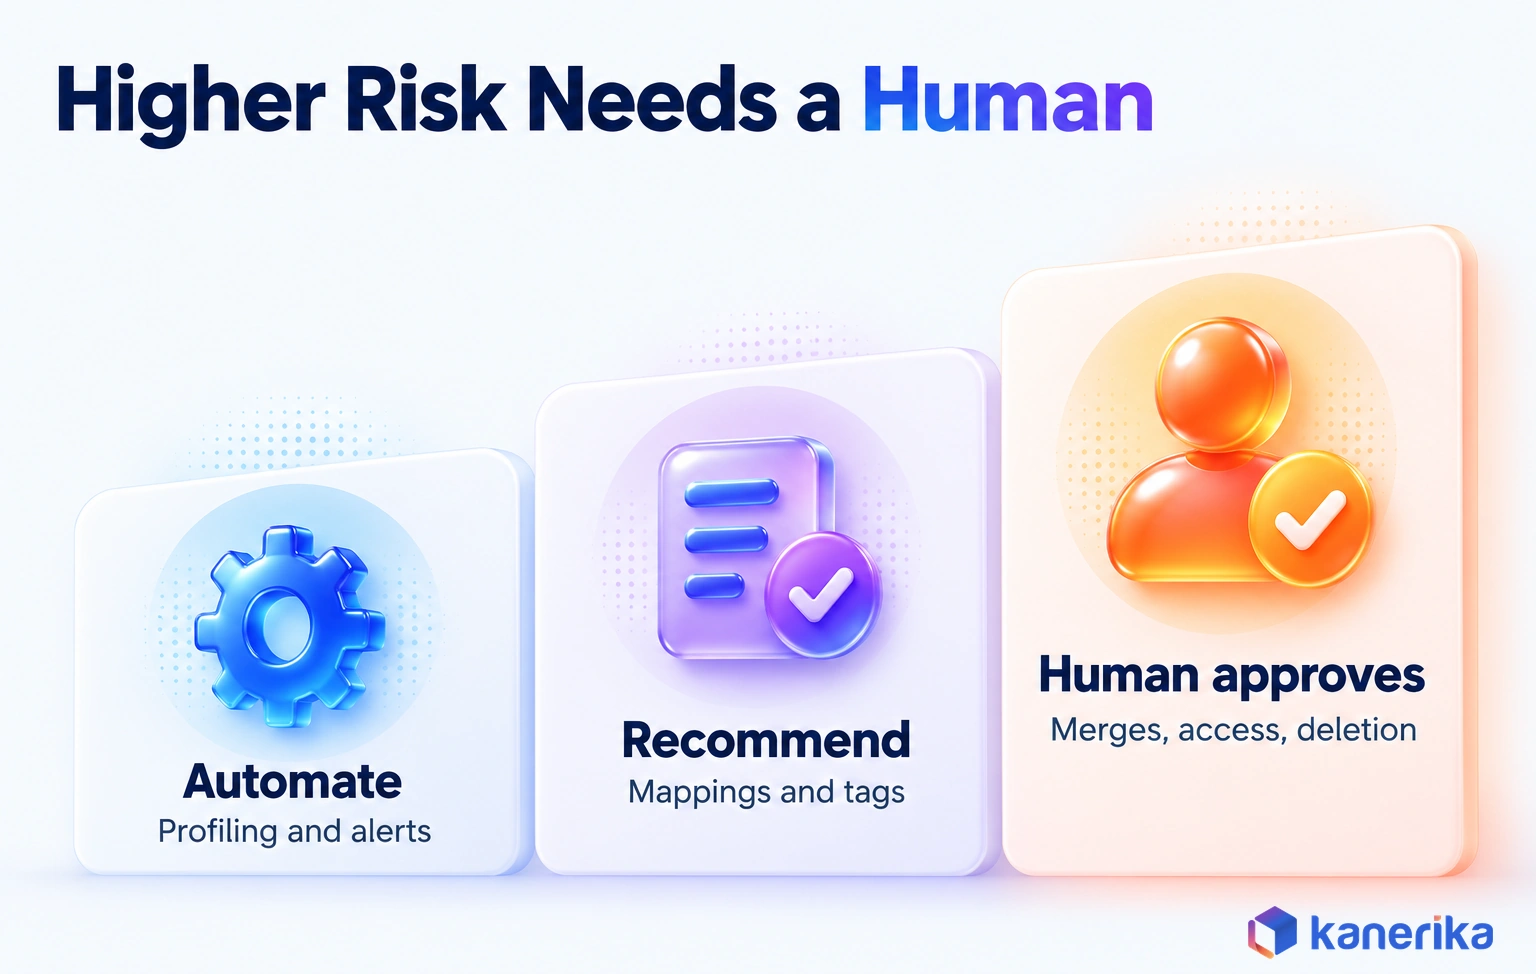
The safest way to use AI in data management is to decide in advance how much authority each task gets. In practice, a simple test works well: the more a mistake costs, and the harder it is to reverse, the more a person should approve.
That test then gives three tiers. Automate tasks where a wrong result is cheap and visible, such as profiling a new table. Let AI recommend where an error is costly but reviewable, such as a field mapping. Then keep human approval for errors that are expensive or permanent.
| Task | Automate | Recommend | Human approval |
|---|
| Profiling new tables | Yes | No | No |
| Anomaly alerts on loads | Yes | No | Owner triages the alert |
| Standardizing dates and phone numbers | Yes, with logs | No | No |
| Field mappings for new sources | No | Yes | Before production |
| Glossary terms and descriptions | No | Yes | Steward review |
| Sensitivity tags such as PII | No | Yes | Privacy lead confirms |
| Merging master records | Only above a strict match score | Yes | For borderline pairs |
| Access policy changes | No | Yes | Always |
| Deleting or archiving data | No | Yes | Always, with an audit trail |
The tiers can still change over time. When a recommendation has been right for months and every override is logged, a team can promote it to automation. A new hire earns more autonomy the same way.
Good data stewardship is what makes that promotion safe, because someone reviews the overrides and spots drift early. Unless someone runs that review, a model that was accurate in spring can quietly degrade by fall.
Top 5 AI Data Management Platforms in 2026
The five platforms below were chosen for their AI capabilities in data management, not for breadth of features. Each one leads on a different job, so read the comparison as a question of fit rather than rank.
If you need a wider list that also includes integration, warehousing and BI tools, see our roundup of data management tools. The pricing column shows each vendor’s model, not a price.
| Platform | AI engine or feature | Best for | Pricing model |
|---|
| Ataccama ONE | ONE AI Agent, automated quality checks and anomaly detection | AI-led data quality | Quote-based |
| Informatica IDMC | CLAIRE, a metadata-based AI engine | Enterprise integration and master data | Quote-based |
| Collibra | AI Governance, automated and adaptive quality rules | Governance and stewardship | Quote-based |
| Alation | Catalog within its Intelligence Operating System, built for people and AI agents | Search and discovery | Quote-based |
| Microsoft Purview | Unified Catalog with quality scores and AI-powered Copilot search | Microsoft and Fabric estates | Pay as you go, per governed asset |
1. Ataccama ONE: Best for AI-Led Data Quality
Ataccama positions ONE as an “agentic data trust platform,” and its center of gravity is data quality. The Ataccama ONE platform includes the ONE AI Agent, plus a data quality module with automated checks, monitoring, anomaly detection and remediation.
Its catalog adds automated discovery and a business glossary, so quality rules connect to the terms the business uses. Choose Ataccama when bad data is the main complaint and you want quality, cataloging and remediation in one place instead of three tools stitched together.
In practice, the AI proposes a rule, such as a postal-code format check, and a steward approves it before it runs. If moving data between many systems is your bigger problem, test its connectors against your source list first.
2. Informatica IDMC With CLAIRE: Best for Enterprise Integration and MDM
Informatica’s Intelligent Data Management Cloud (IDMC) runs on CLAIRE, a metadata-based AI engine that Informatica says powers data, applications and AI agents. Its strength is breadth, particularly integration, quality, master data and governance services on one metadata layer.
Ownership has also changed. Salesforce completed its acquisition of Informatica on November 18, 2025, so ask about roadmap and packaging, especially if you do not run Salesforce.
Choose IDMC when many sources and shared master data are the core problem. Our guide to enterprise data integration shows what that work involves at scale.
In a pilot, check the kind of suggestion this guide described earlier, such as “cust_no” mapping to “customer_id”, and track how often stewards accept it. Usage is metered in Informatica Processing Units (IPUs), so model your consumption during the pilot.
3. Collibra: Best for Governance and Stewardship, Including AI Governance
Collibra comes from the governance side, and the Collibra platform reflects that. Its AI Governance capability lets teams catalog, assess and monitor any AI use case, model or agent.
It includes data quality with automated rule creation and adaptive rules, plus privacy features for personal data. Choose Collibra when policy, ownership and stewardship workflows matter more than integration. Our comparison of data governance tools sets it against other governance-first options.
In practice, a model drafts a quality rule from observed patterns, and the steward approves it inside the workflow. Collibra assumes named owners and stewards already exist, so it fits poorly before those roles are assigned.
4. Alation: Best for Catalog Search and Discovery
Alation built its name on helping people find and trust data. Its data catalog now sits within what Alation calls its “Intelligence Operating System,” built so teams and AI agents can find data and its context.
That makes it a strong pick when discovery is the main problem. For example, analysts cannot find the right table, or they find three and do not know which one is approved. For a full side-by-side of catalog options, see our data catalog tools comparison.
Faced with three look-alike customer tables, the catalog should show which one is approved, who owns it and how often it is used. Its value depends on people curating it, so confirm who will endorse tables and maintain descriptions after launch.
5. Microsoft Purview: Best for Microsoft and Fabric Estates
Microsoft Purview’s Unified Catalog organizes data into governance domains and data products, tracks critical data elements, and applies data quality rules and scores. It also adds health controls and AI-powered Copilot search on top.
Its biggest advantage is fit. That matters most for organizations on Azure, Microsoft 365 and Fabric, because governance sits next to the sources and identities they already run.
For example, a classification scan can tag a column of national ID numbers as sensitive before anyone queries it. Confirm scan depth for the non-Microsoft sources you run before you commit.
Our Microsoft Purview guide covers setup in depth. For the Fabric side specifically, Microsoft Fabric governance shows how the two work together.
Case Study
90% Compliance Adherence for Healthcare with Purview
A top North American healthcare organization centralized its catalog and classifications in Microsoft Purview, cutting data discovery time by 57% and raising compliance adherence by 90%.
Read the Case Study →
How to Choose an AI Data Management Platform
The right platform is the one whose AI solves your biggest data problem on the systems you already run. Start from the problem and the estate, then shortlist, then test the AI features on your own data before you sign anything.
The table below maps common situations to a starting shortlist. It is a first cut, since two firms with the same stack can have very different pain points.
| Your situation | Main need | Start your shortlist with |
|---|
| Mostly Azure, Microsoft 365 and Fabric | Governance across existing Microsoft sources | Microsoft Purview |
| Many sources, duplicate customer and product records | Integration plus master data | Informatica IDMC |
| Bad data keeps reaching reports | Automated quality checks and remediation | Ataccama ONE |
| Strict regulation, many data owners, AI models in use | Policy, stewardship and AI governance | Collibra |
| Analysts cannot find or trust tables | Search, context and discovery | Alation |
A Weighted Scorecard for Your Shortlist
Once you have two or three names, score them the same way. The weighting below is a suggested starting point, so adjust it to your own priorities.
- Fit with your estate and connectors, 25%. Check that it scans and governs your actual sources without custom work.
- AI features proven on your data, 20%. Run its matching, classification and rule suggestions on a real sample.
- Approval workflow, 20%. Stewards should be able to review, override and log every AI suggestion.
- Security and privacy controls, 15%. Test sensitive-data detection, masking and access policies.
- Total cost over three years, 10%. Include compute, connectors, services and steward time.
- Usability for stewards and analysts, 10%. Ask the people who will use it daily to try it first.
Above all, score the 20% AI line only from your own proof of concept, never from the demo. Vendor demos run on tidy data, while your own sample shows how the AI handles your naming habits, gaps and edge cases.
It also helps to score your own starting point before you score vendors. A team with no named data owners will struggle on any platform, and that gap is cheaper to find before the contract than after it.
Talk to Kanerika
Not Sure Which Platform’s AI Fits Your Data?
Kanerika can review your sources, data issues and governance needs, then help you shortlist and test AI data management platforms on your own data.
Schedule a Demo →
Data Management for AI: Unstructured Data, RAG and AI Agents
The second meaning of AI data management is making data safe and useful for AI to consume. It matters more as companies move from dashboards to assistants and agents that read data directly and then act on it.
The shift changes what “managed” means. A report reads a few curated tables, whereas a retrieval-augmented generation (RAG) assistant may read thousands of PDFs, contracts and wiki pages. Much of that is unstructured data that no catalog has ever seen, so an outdated policy document in the corpus gets quoted with full confidence.
Agents raise the stakes further, because they query systems and take actions. An agent needs what a new analyst needs, such as the approved source, its owner, its freshness and the access rules.
Our guide to generative AI for data analytics also shows what this looks like for analytics teams. For assistants, RAG vs fine-tuning explains why answer quality depends on the documents behind them.
A Readiness Check Before AI Reads Your Data
Picture an HR assistant that quotes a leave policy the company replaced long ago. The old PDF has no owner, no “last reviewed” date and no classification, so retrieval treats it like a current document.
It is the insurer’s matching gap again, this time in documents. Before any AI system reads your data, check these points, which close exactly those gaps:
- Every source the AI reads has a named owner and a “last reviewed” date.
- Documents carry classifications, so the retrieval layer can exclude restricted content.
- Access rules follow the user, so an assistant never shows a person data they could not open themselves.
- Embeddings and indexes refresh whenever their sources change.
- Lineage records which documents and tables fed each answer, so errors can be traced.
- Quality checks run on each source before it is indexed, well before a wrong answer surfaces.
A structured AI readiness assessment turns this list into a scored baseline. It also shows which sources to fix first, so the effort goes where an AI system will read most.
AI Assessment
How Ready Is Your Data for AI?
Take Kanerika’s AI Maturity Assessment to score your data, governance and AI practices before you compare platforms.
Start Your AI Assessment →
What AI Data Management Costs and How to Measure ROI
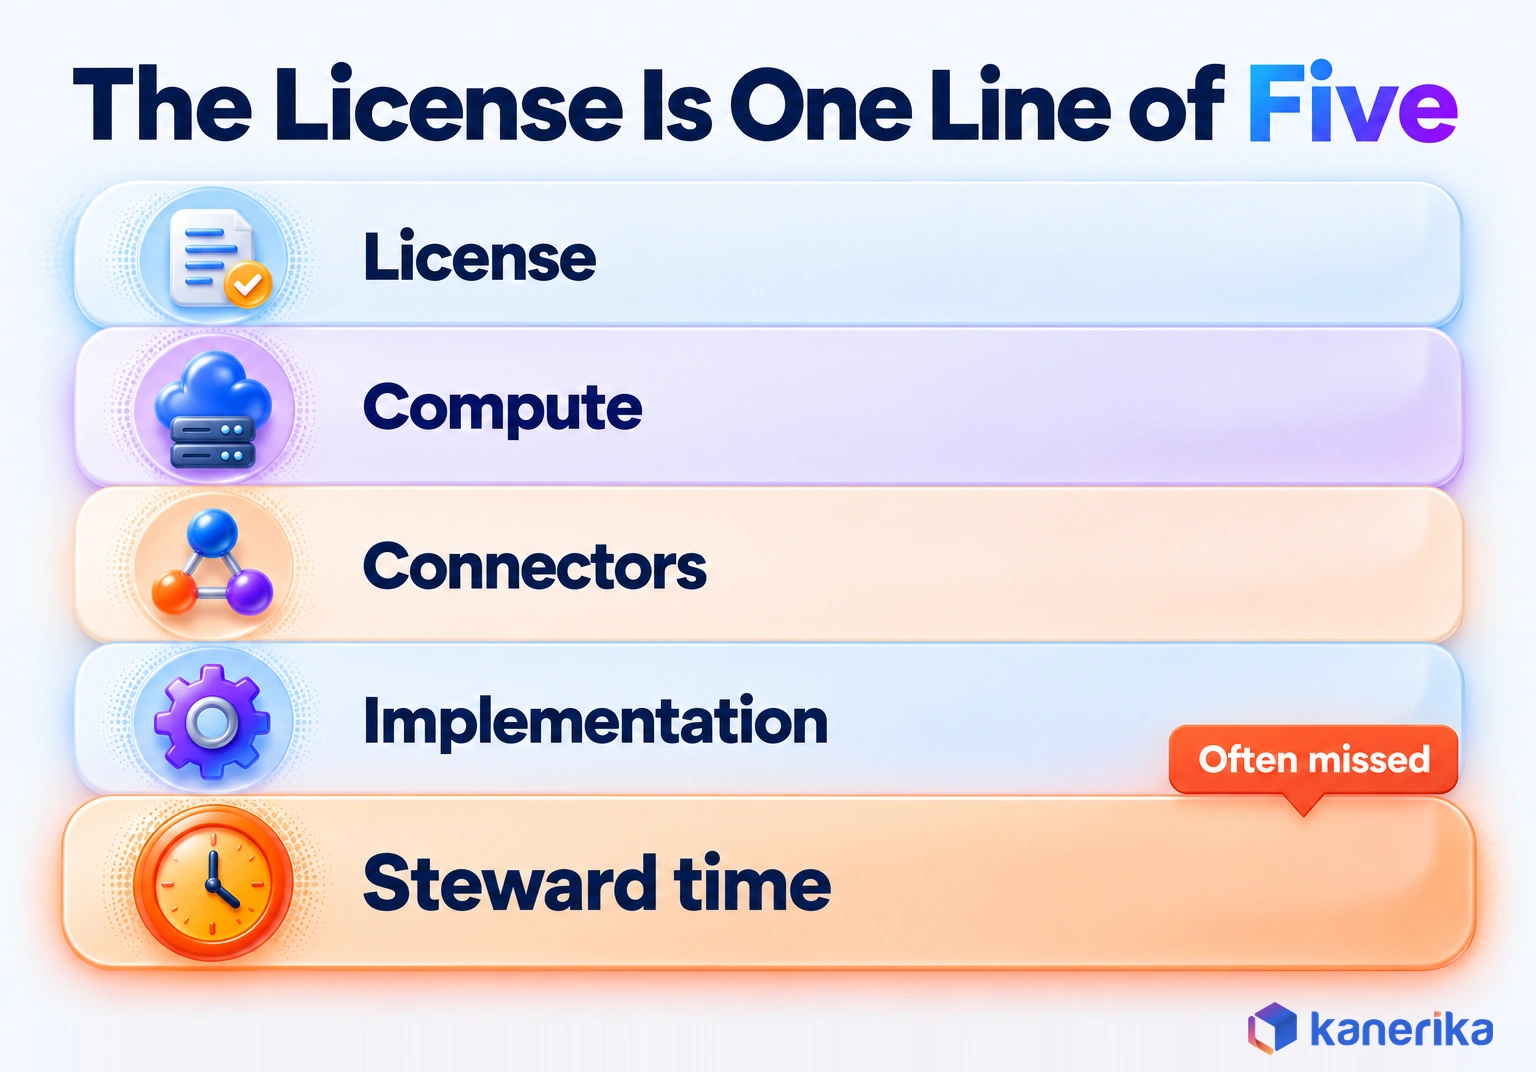
AI data management costs more than its license fee, and budgets that only count the license tend to run short. Five components make up the real total, and most of them grow with the number of sources and assets you govern.
| Cost component | What drives it | How to estimate it |
|---|
| License or subscription | Users, governed assets and modules | Vendor quote, or Microsoft’s published per-asset pricing for Purview |
| Compute | Scans, quality checks and AI features running on data | Pilot usage multiplied by the planned number of sources |
| Connectors | Number and type of source systems | Count sources and check which need paid or custom connectors |
| Implementation | Setup, integration, policy design and rule migration | Partner or internal estimate per data domain |
| Stewardship time | Reviewing AI suggestions and approving merges and tags | Hours per week per steward, by domain |
Purview is the one platform here with public pricing. Its Unified Catalog is billed per unique governed asset, and Microsoft’s own example prices 200 governed assets at $100 for 30 days without discounts.
That works out to 50 cents per asset for the period, though prices can change and enterprise agreements differ. For the full picture, see our Microsoft Purview licensing breakdown.
How to Measure ROI
ROI is easier to prove when you measure before you buy. First, pick a few measures, then record a baseline in the pilot domain and track them every month:
- Time to find and access a trusted data set.
- Data quality issues per load, and the share caught before they reach reports.
- Time to resolve a data incident, from alert to fix.
- Steward hours spent on manual matching, tagging and rule writing.
- Share of critical data elements with an owner, a definition and a quality score.
- Time to prepare evidence for an audit or a regulator request.
These measures turn into money when you multiply saved hours by loaded cost or count avoided rework. A written data quality framework also keeps the definitions stable, so a drop in issues reflects better data instead of a changed rule.
Risks, Regulation and Common Mistakes
AI makes data management faster, which also means it can spread a mistake faster. The controls below belong in place before any AI feature touches production data.
Privacy and Security Controls
AI features must read data to classify, match or profile it, so they need the same controls as any privileged user. Limit what each feature can read, mask sensitive fields in non-production copies and log every access.
Masking also keeps test and training copies useful without exposing real identities, as our guide to data masking explains. Broader rules on consent and retention live in your data privacy program, while a separate AI security review covers threats to the AI features.
Which Frameworks Apply
Two frameworks come up most often. The NIST AI Risk Management Framework, released January 26, 2023, organizes AI risk work into four core functions: govern, map, measure and manage. NIST then added a generative AI profile, NIST-AI-600-1, on July 26, 2024.
In Europe, Article 10 of the EU AI Act covers high-risk AI systems trained on data. Their training, validation and testing data sets must follow data governance and management practices, which also include examining the data for possible biases.
US state privacy laws such as California’s CCPA add their own rules on personal data, so map each AI data flow to the laws that apply to it. None of this replaces a governance program. A clear data governance framework assigns the owners and policies these rules assume, while AI governance tools handle oversight of the models and agents themselves.
Checklist
Data Governance Checklist
Use Kanerika’s Data Governance Checklist to confirm owners, policies and controls are in place before AI features touch production data.
Get the Checklist →
Common Mistakes
The same handful of mistakes shows up across programs, whichever platform a team picks. Each one is cheap to avoid early and expensive to fix later.
- Buying a platform before naming the problem. Teams end up paying for features nobody uses.
- Letting AI suggestions go live unreviewed. One wrong mapping or merge can quickly spread to every downstream table, especially in shared models.
- Skipping the baseline. Without before-and-after measures, nobody can prove the investment worked.
- Treating it as an IT project. Business owners, not IT, must own definitions and approve rules.
- Ignoring unstructured data. Documents feeding AI assistants need the same ownership and access rules as tables.
- Scaling before the pilot passes. One domain that works beats five half-governed ones.
Most of these come down to ownership, so settle who owns each domain before the kickoff.
A Five-Step Rollout Plan
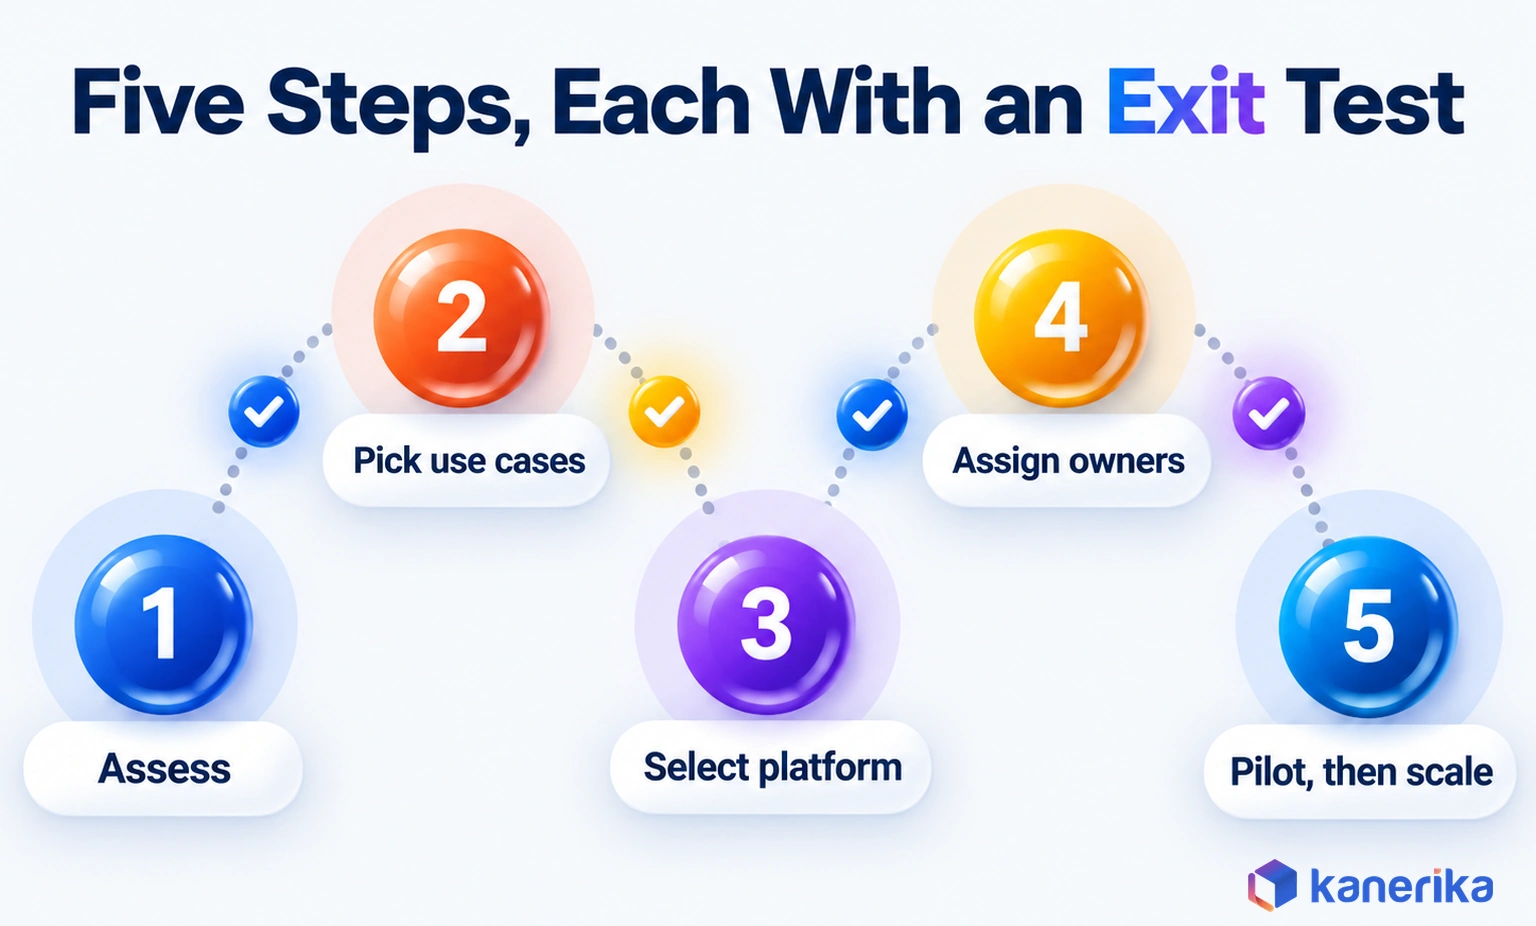
A good rollout proves value in one domain before it spreads, and each step ends with a test that says whether to move on. The plan below fits most organizations, whichever platform they pick.
- Assess your data and current practices. First, profile key sources, list critical data elements and record baseline measures. Exit test: a written baseline for discovery time, issue counts and steward hours.
- Choose use cases and KPIs. Pick one domain, such as customer or product data, and two or three measures to improve. Exit test: the business owner signs off on targets.
- Select the platform. Shortlist with the scenario table above, then run a proof of concept on your own data. Exit test: AI suggestions meet an agreed accuracy bar on your sample.
- Assign governance roles. Name owners and stewards, then set which tasks AI automates, recommends or leaves to people. Exit test: every AI action type has an approver.
- Pilot, then scale. Run the domain in production for a set period, compare it with the baseline, then add the next domain. Exit test: targets met and no unreviewed AI changes in the audit log.
Keep the first domain small enough to finish. Customer data is a common first choice, because duplicates there are visible and costly, and wins are easy to explain to the business.
Roles deserve the most care, since they outlast any tool. Our data governance best practices guide covers role design in more detail.
How Kanerika Delivers AI Data Management
Kanerika runs these programs through its data governance services, often on Microsoft Purview and Fabric. The method follows the rollout above: assess, define controls, pilot, roll out and expand, with a measured baseline at the start.
One engagement shows the pattern. A top North American healthcare organization had data spread across Azure Blob Storage, SQL databases and SaaS applications, with no consistent classification or metadata framework.
Kanerika built a centralized catalog in Microsoft Purview with metadata and classifications. The team also added a classification framework with steward roles and usage policies, along with Power BI dashboards and governance documentation. Each of those pieces maps to a section of this guide, from classification and access rules to steward roles and measured results.
The published case study reports results that track the mechanisms in this guide. Data discovery time fell 57%, the gain a central catalog with classifications is meant to deliver. Data accuracy rose 35% with named stewards in place. Compliance adherence rose 90% once classifications fed usage policies, while data accessibility improved by 70%.
Teams earlier in the journey start with the same first step. Kanerika profiles the key sources, records baseline measures and agrees approval rules with data owners before any AI feature goes live. That way the pilot has a clear baseline to prove itself against.
Kanerika Service
Data Governance Services
Kanerika designs and runs data governance and AI data management programs on Microsoft Purview and Fabric, from baseline assessment to steward roles and production rollout.
Explore Data Governance Services
The Bottom Line on AI Data Management
AI data management works by giving machine learning the first pass on repetitive data work, from mappings and quality checks to matching, classification and lineage. People still keep the decisions that are costly or permanent, and that split is what makes the speed safe.
The platform choice follows your biggest gap. Ataccama ONE fits data quality, Informatica IDMC fits integration and master data, and Collibra fits governance. Alation fits discovery, while Microsoft Purview fits Microsoft and Fabric estates.
If your customer records look like the insurer’s, start there. Profile the domain, run matching on a real sample in two shortlisted platforms, and compare steward hours against your baseline. That test shows which of the five platforms fits your data.
Frequently Asked Questions
What is AI data management?
AI data management is the use of machine learning and generative AI to automate routine data work such as discovery, quality checks, record matching, classification and lineage. People still set the rules and approve risky changes. The term also covers preparing data so AI systems, including assistants and agents, can use it safely and accurately.
How is AI used in data management?
AI scans new sources and suggests field mappings, learns normal patterns in each table and flags anomalies, and drafts catalog descriptions and sensitivity tags. It also scores likely duplicate records and harvests lineage from metadata. In each case the AI takes the first pass on repetitive work, and data owners review the results that matter.
What is the difference between AI for data management and data management for AI?
AI for data management means AI doing data work, such as suggesting quality rules, matching records or tagging sensitive fields. Data management for AI means preparing data so AI systems can use it, covering ownership, quality, lineage, access and freshness for training sets, documents and agent queries. Most programs need both, since they share the same foundations.
How much does an AI data management platform cost?
Cost depends on the platform, the number of governed assets and sources, compute, connectors, implementation and steward time. Most vendors quote prices privately. Microsoft publishes Purview pricing, and its own example prices 200 governed assets at $100 for 30 days without discounts. Budget for all five cost components, since license fees are only part of the total.
Is Microsoft Purview an AI data management tool?
Yes, especially for organizations on Microsoft platforms. Purview’s Unified Catalog organizes data into governance domains and data products, tracks critical data elements, and applies data quality rules and scores. It also includes AI-powered Copilot search. It fits best when your sources sit in Azure, Microsoft 365 and Fabric, alongside the identities your teams already use.
What is the difference between Collibra and Alation?
Collibra comes from governance, with policy and stewardship workflows, data quality with automated and adaptive rules, and AI Governance for cataloging and monitoring AI use cases, models and agents. Alation is strongest at catalog search and discovery, helping people and AI agents find data and its context. Pick Collibra for policy-heavy programs and Alation for discovery-led ones.
How do you measure ROI from AI data management?
Record a baseline before the pilot, then track a few measures every month. Useful ones include time to find trusted data, quality issues per load, time to resolve incidents, steward hours on manual work and audit preparation time. Convert saved hours into cost using loaded rates, and count avoided rework from errors caught before reports.
How long does it take to implement AI data management?
It depends on source count, data quality, the platform and how quickly owners are named. A sensible plan proves value in one domain first, such as customer data, with baseline measures and approval rules in place. Once that pilot meets its targets, later domains move faster because the roles, policies and templates already exist.
Can AI data management tools work with Microsoft Fabric?
Yes. Microsoft Purview is the most direct option for Fabric, since it governs Fabric data alongside other Microsoft sources. For other platforms, ask each vendor whether it has a Fabric connector. Then test scanning, lineage and classification on your own Fabric items during the proof of concept, before you commit to a contract or a rollout plan.
What are the best AI data management tools in 2026?
Five platforms lead for different jobs. Ataccama ONE suits AI-led data quality, Informatica IDMC with CLAIRE suits enterprise integration and master data, and Collibra suits governance and stewardship. Alation suits catalog search and discovery, and Microsoft Purview suits Microsoft and Fabric estates. Test each shortlisted tool’s AI features on a sample of your own data first.
Will AI replace data management teams?
AI is unlikely to replace data management teams. It takes over repetitive work such as profiling, rule drafting and first-pass record matching. People remain responsible for definitions, policies, approvals and fixing the issues AI flags. In practice, steward time moves from manual cleanup toward reviewing AI suggestions, improving data ownership and handling the hard edge cases.
Is AI in data management safe for sensitive information?
It can be safe when the AI features run under the same controls as any privileged user. Limit what each feature can read, mask sensitive fields in non-production copies and log every access. Keep people approving access changes and deletions, and check where any vendor AI service processes your data before you switch it on.
Can AI automatically clean data?
AI can automatically fix many low-risk issues, such as inconsistent date formats, extra spaces and standard address formats. It can also suggest fixes for harder problems, such as likely duplicates or values outside a learned range. Changes that are costly or permanent, like merging customer records, should go to a steward for approval with a logged decision.
What are the four pillars of data management?
The four pillars most often cited are data governance, data quality, data integration and data security. Governance sets ownership and policy, quality keeps data accurate and complete, integration connects sources, and security controls access. Lists vary by source. AI supports each pillar through automated classification, quality monitoring, mapping suggestions and alerts on unusual access.
What are the 6 C's of data quality?
One common version lists completeness, consistency, conformity, correctness, currency and coverage. Completeness means required fields are filled, consistency means values agree across systems, and conformity means formats follow standards. Correctness means data reflects reality, currency means it is recent enough, and coverage means it spans the scope you need. AI tools can monitor all six continuously.
Why do so many AI projects fail?
Many AI projects stall because the data behind them is not ready. Gartner predicts that through 2026, organizations will abandon 60% of AI projects unsupported by AI-ready data. Common causes include unclear ownership, poor quality, missing lineage and weak access controls. Fixing data management for one use case before scaling lowers that risk.
What is the difference between AI data management and data governance?
Data governance sets the policies, roles and standards for how data is owned, used and protected. AI data management is the practice of using AI to carry out much of that work, such as classifying data, checking quality and tracing lineage. Governance decides the rules, and AI data management helps apply them at scale across many sources.




