TL;DR
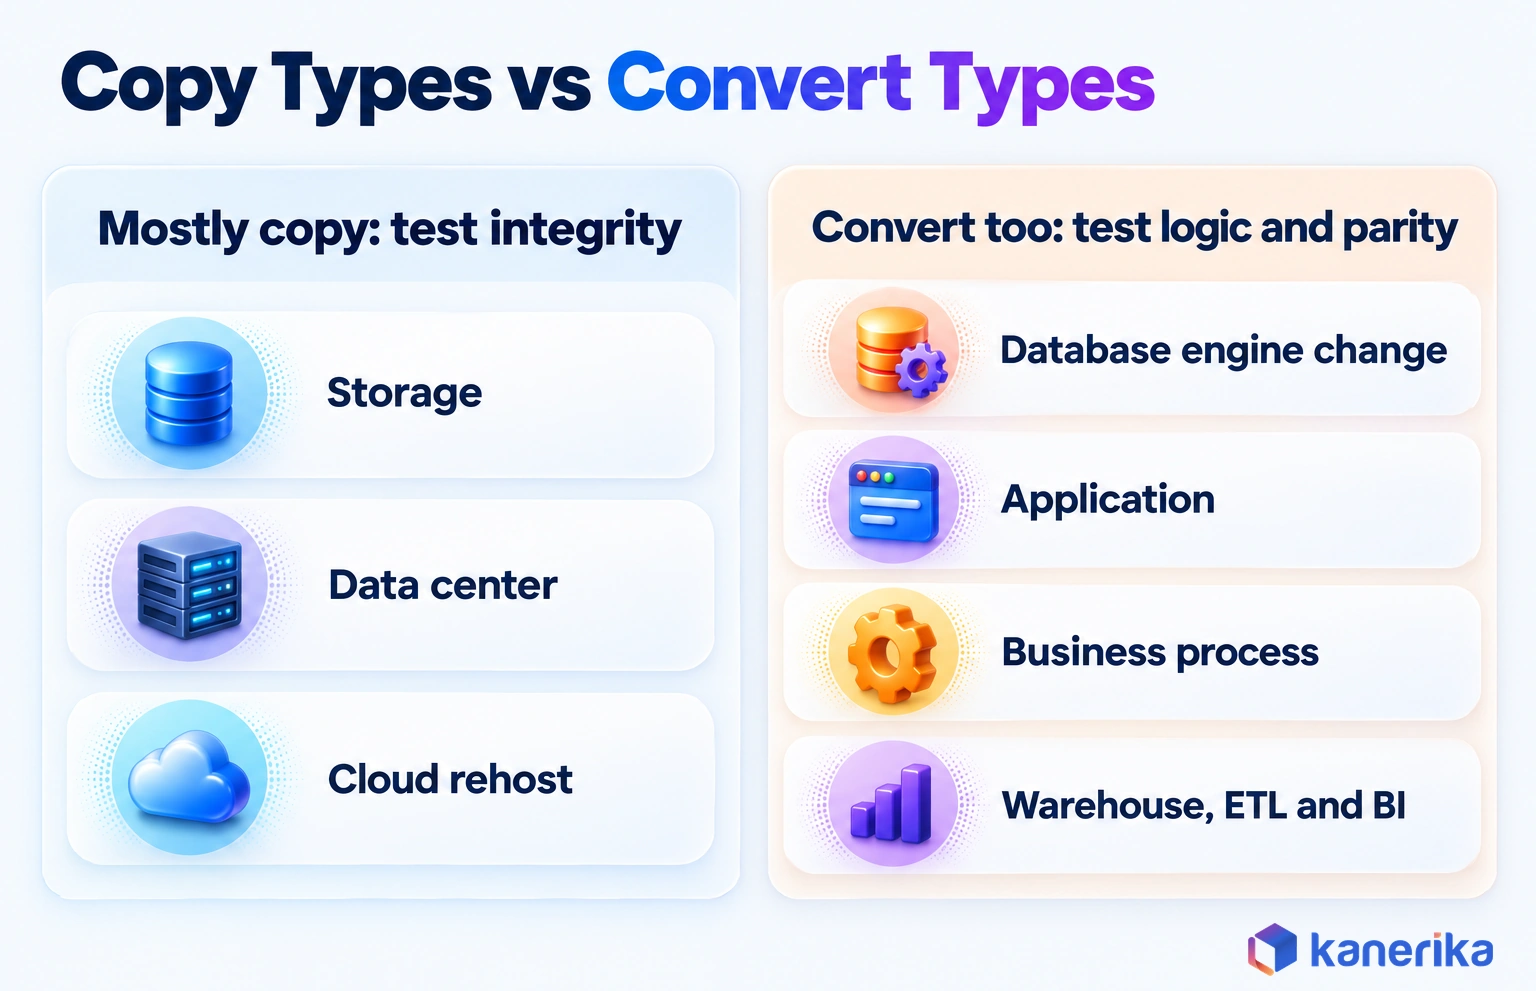
The types of data migration sort on three axes: what moves, how it moves, and how much moves between how similar systems. By what moves, there are seven types: storage, database, application, cloud, business process, data center, and analytics platform. Of the three strategies, big bang suits small, tolerant moves, hybrid suits large databases with tight outages, and trickle suits many modules with 24×7 users.
Scope and similarity add modifiers, such as full or partial and same or different database engine. One cloud project often holds four of these types, and each needs its own strategy. List every type in your project first, because that mix sets the tools, the downtime and the tests.
Key Takeaways
- A data migration is classified on three separate axes: what moves, how it moves, and how much moves between how similar systems.
- The seven object types are storage, database, application, cloud, business process, data center, and analytics platform (warehouse, ETL and BI) migration.
- Big bang moves everything in one cutover, trickle runs old and new systems side by side, and hybrid pairs a bulk load with continuous replication.
- Heterogeneous moves, such as Oracle to PostgreSQL, add schema and code conversion that homogeneous moves skip.
- Downtime tolerance, source-target similarity and dependency count decide the right mix, so plan a validation check for each type.
- Warehouse, ETL and BI moves shift data, logic and reports at once, so they need report parity tests as well as row counts.
One Ticket, Four Migrations
At first, the request looks simple: move monthly reporting to the cloud before the on-premises server reaches end of support.
Then the inventory starts. The reports read from SSAS cubes, the cubes read from a SQL Server warehouse, and dozens of SSIS packages feed that warehouse. A shared drive full of extracts sits beside it all.
So the single ticket is really four migrations. Inside the cloud move sit a database move, an analytics platform move for the packages and cubes, and a storage move.
That is why the types of data migration matter before anyone picks a tool. This guide sorts them on three axes, defines each one, and shows how to tell which ones your project contains.
What Is Data Migration and Why the Type Matters
Data migration is the work of moving data between storage systems, formats or applications, then retiring or repurposing the source. It sounds like copying, but it rarely is. Instead, the data usually lands in a new structure, under new rules, for new users.
The triggers are familiar. A database version reaches end of support, a company commits to the cloud, or two businesses merge after an acquisition. An analytics team may also outgrow a legacy warehouse, which is a common start for legacy system modernization. Each trigger points to a different type of move, even when the ticket uses the same words.
Naming the type early matters for three practical reasons. First, it decides the tooling, since a storage copy and an engine change need very different data migration tools. Second, it sets the downtime pattern. Third, it defines what testing must prove, because a file copy needs checksums while a report migration needs matching numbers.
Skipping this step is how budgets slip later. A team that scopes a lift-and-shift and then finds stored procedures to rewrite has quietly changed type mid-project.
Migration ROI Calculator
Estimate the Return on Your Migration
Before scope drifts, use Kanerika’s Migration ROI Calculator to estimate the savings and payback of the migration types your project contains.
Calculate Migration ROI →Three Ways to Classify a Data Migration
Every migration answers three plain questions. Each question is its own axis, so a project has one answer on each axis. Take an Oracle-to-PostgreSQL move within AWS, done over one weekend: it is a database migration (what), big bang (how) and heterogeneous (how similar).
- What moves (object type): storage, database, application, cloud, business process, data center, or an analytics platform.
- How it moves (strategy): big bang, trickle or hybrid.
- How much and how similar (modifiers): full or partial scope, homogeneous or heterogeneous engines, and structured or unstructured data.
This is why articles disagree on how many types of data migration exist. One list says there are four types, another says six, and a third says seven. They are usually counting different axes, or mixing two axes in one list, such as cloud migration placed next to big bang migration.
Keeping the axes apart makes planning easier. A phrase like “a heterogeneous, phased database migration to the cloud” tells a team most of what it needs to scope the work. That one phrase names the object, the strategy and the similarity, so the tooling and the test plan follow from it.
The rest of this guide takes the axes in order, starting with the object, then the strategy, then the modifiers.
Types of Data Migration by What Moves
The first axis is the object, that is, the thing that changes home. The table compares the seven object types before each one gets a closer look.
| Type | What moves | Typical trigger | Main risk | Downtime profile | Tooling category |
|---|---|---|---|---|---|
| Storage | Files, blocks and objects between arrays, NAS or object stores | Hardware refresh, capacity limits | Corruption, slow transfer | Low with background sync | Storage replication and sync tools |
| Database | Tables, schemas and procedures between engines or versions | End of support, license cost | Type and code mismatches | Minutes to hours at cutover | Database migration services, schema converters |
| Application | Data and business rules into a new ERP, CRM or app | Software replacement | Lost rules, broken mappings | Planned cutover window | ETL tools, vendor import utilities |
| Cloud | Data, apps or whole workloads to or between clouds | Cloud commitment, data center exit | Latency, security and cost surprises | Depends on the strategy | Cloud provider migration services |
| Business process | Data behind a process after a reorg or merger | Acquisition, process redesign | Conflicting master data | Phased by business unit | Master data and integration tools |
| Data center | Servers, storage and network as one estate | Lease end, site consolidation | Hidden dependencies | Waves over months | Discovery and dependency mapping tools |
| Warehouse, ETL and BI | Warehouse tables, pipelines and reports | Legacy platform retirement | Logic drift, report mismatch | Parallel run per subject area | Code conversion accelerators, BI migration tools |
Storage Migration
Storage migration moves data from one storage system to another, such as from an aging SAN to a newer array or to cloud object storage. The data itself does not change shape, so files stay files and blocks stay blocks.
Picture 200 TB of file shares moving from a NetApp filer to Azure Files with a background sync. A final delta copy at cutover then catches the last changes.
The risks are physical rather than logical. Teams watch integrity, throughput and permissions, then prove the move with checksums and file counts. A storage refresh is often the simplest type, yet it still needs a rollback plan in case the new system underperforms.
Database Migration
Database migration moves tables, indexes, views and stored procedures from one database to another. It can be a version upgrade on the same engine or a move to a new engine, such as Oracle to PostgreSQL.
The hard part, however, is mapping. Data types differ between engines, and procedural code also often needs a rewrite. That split between homogeneous and heterogeneous migration gets its own section further down.
When the main change is the format of the data rather than its home, the line between moving and reshaping blurs. The guide on data conversion vs data migration explains how to scope each part.
Application Migration
Application migration moves an application’s data into a replacement system, such as a new ERP, CRM or HR suite. The data model changes with the software, so customer, product and order records must be remapped to the new structure.
Business rules also travel. A discount rule that lived in old code may need to become configuration in the new product. If that rule is missed, invoices can be wrong from day one, even when every record arrived.
Cloud Migration
Cloud migration moves data, applications or whole workloads from on-premises systems to a cloud, or from one cloud to another. It overlaps with the other types, because a cloud move usually carries a database, storage or application migration inside it.
For applications, AWS names seven strategies in its large migration guide: retire, retain, rehost, relocate, repurchase, replatform, and refactor or re-architect. Those names describe what happens to each application, though. The data inside still needs its own strategy and its own validation.
The destination also adds its own details on top of the type. For one cloud in depth, see the guide to migrating data to Azure, which covers services, steps and cutover on that platform.
Case Study
60% Less Manual Reconciliation via Snowflake Migration
Kanerika moved a leading beverage manufacturer and distributor from legacy SSAS and hybrid systems to a unified Snowflake architecture, cutting manual reconciliation by 60% and saving $130K a year.
Read the Case Study →Business Process Migration
Business process migration moves the data that supports a process, often after a reorganization, merger or process redesign. For example, two merged companies may need one customer master, one chart of accounts and one supplier list. Ongoing enterprise data integration then keeps those shared records in sync after the move.
The technical copy is the easy part. The hard part is agreement, because each side defines a customer or a product differently. Data owners from both sides must settle those rules before the load, and data governance tools help record who decided what. Otherwise the new process inherits two versions of the truth.
Data Center Migration
Data center migration moves an entire estate, including servers, storage, network and the data on them. It usually happens when a lease ends or when a company consolidates sites.
Sequencing decides success here. Applications that talk to each other must move together, otherwise latency and broken connections appear. That is why teams start with dependency mapping and then move in waves of linked systems. Wave one might hold the ERP and its reporting database, since they query each other all day, and file servers can follow later.
Data Warehouse, ETL and BI Platform Migration
Many lists skip this type, even though it is often the most involved. An analytics platform migration moves a warehouse, the ETL jobs that feed it and the reports that read from it. For example, SSIS or Informatica pipelines may move to Data Factory in Microsoft Fabric, or SSAS models may move to a cloud warehouse.
Three things move at once. Data moves into new tables, logic moves from one pipeline tool to another, and reports must show the same numbers on the new platform. Each layer needs its own test, which is why these projects often run old and new systems in parallel.
An Informatica to Microsoft Fabric migration shows how much of the work is logic conversion rather than data copying. SSIS to Fabric migration follows the same pattern. ETL here is the tooling inside the move, a distinction that data integration vs ETL covers in detail. A clear ETL framework on the target also keeps the converted jobs consistent.
The target design also matters. Choosing a lake or lakehouse target changes how tables are laid out and which data warehouse architecture patterns still apply after the move.
Big Bang vs Trickle vs Hybrid Migration
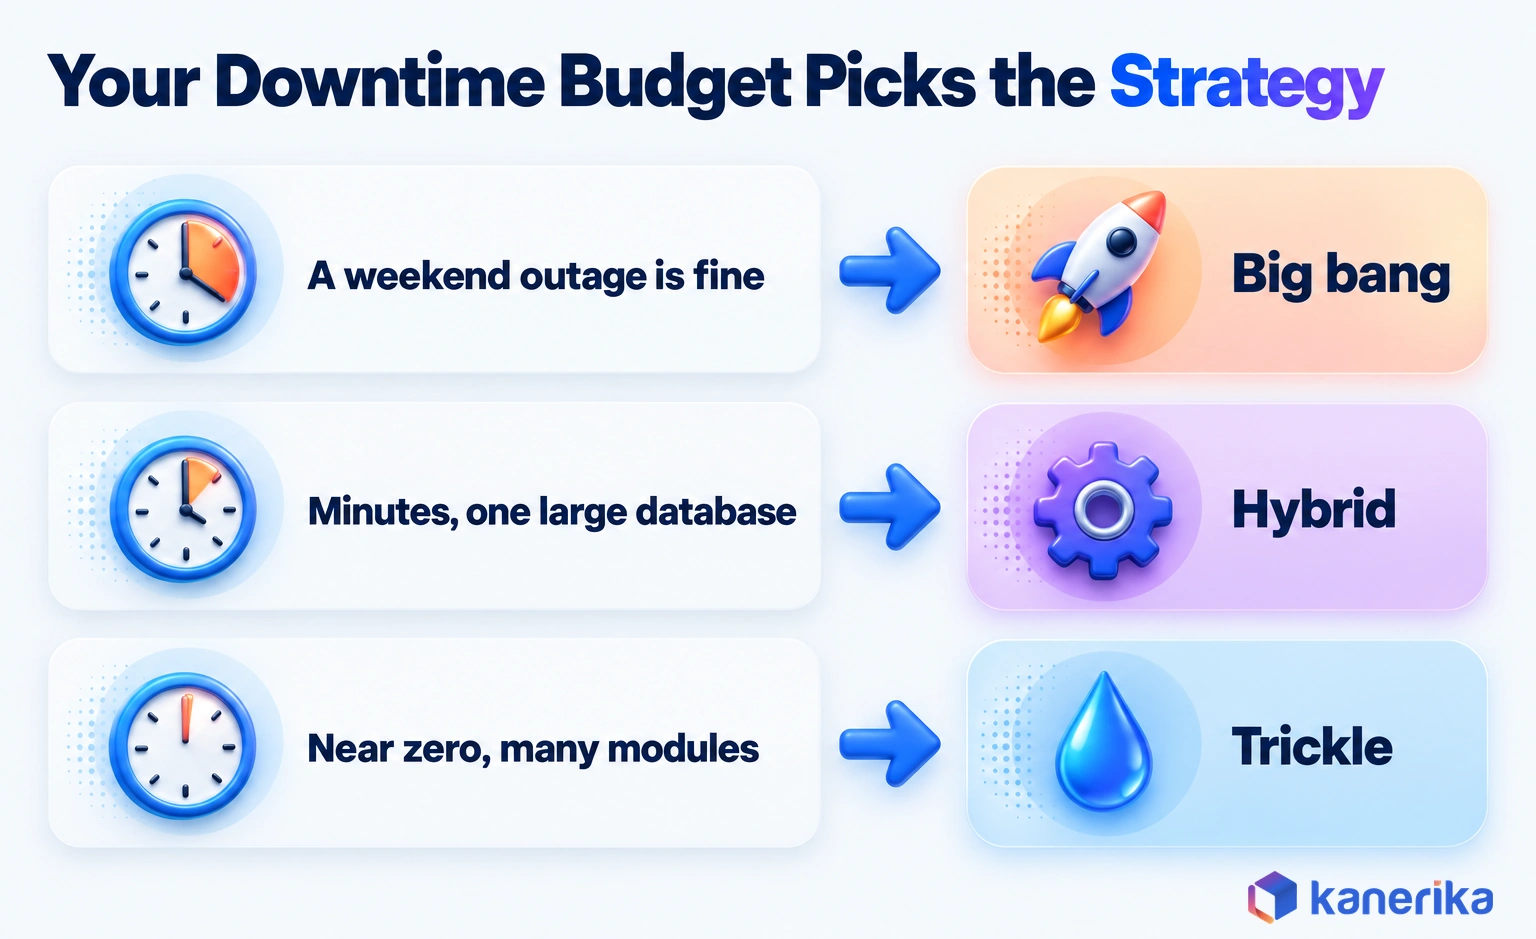
The second axis is strategy, meaning how the data gets from the old system to the new one and how long both stay live. There are three common answers, and they trade outage length against the cost of running two systems.
| Factor | Big bang | Trickle (phased) | Hybrid |
|---|---|---|---|
| Cutover | One planned window | Many small cutovers | One short final cutover |
| Downtime | Longest, often a weekend | Small per phase | Short, once sync catches up |
| Rollback | Simple: return to the source | Per phase, more complex | Possible until final cutover |
| Parallel-run cost | None or very short | Highest: both systems run for months | Moderate, during sync |
| Team load | Intense for a few days | Steady over a long period | Heavy at setup and at cutover |
| Best fit | Small data, tolerant users | Many modules, 24×7 users | Large databases, tight outage limits |
Big Bang Migration
A big bang migration moves everything in one planned window. Users stop work, the team extracts, loads and checks the data, and the new system goes live when the window closes.
It is simple to plan and also avoids a long period of dual running. The risk is concentrated, though, because a failed load means an extended outage or a rollback under pressure. Big bang therefore suits smaller datasets and teams that can accept a weekend of downtime.
Trickle or Phased Migration
A trickle migration moves data in stages while the old and new systems both run. Changes made in the source keep syncing to the target until each phase is switched over.
This keeps downtime low and lets the team learn from each phase. The price, though, is complexity. Two systems must stay consistent, sync jobs need monitoring, and users may work across both for months. As a result, the data pipelines that carry the sync become production systems in their own right.
Hybrid Migration
A hybrid migration pairs a big-bang bulk load with trickle-style replication. The team runs one bulk load of historical data, replicates ongoing changes until the target catches up, and then finishes with a short cutover.
Google calls this pattern continuous migration in its Database Migration Service overview. It defines the pattern as “a continuous flow of changes from your source to your destination that follows an initial full dump and load”. The same idea also goes by ongoing or online migration.
In AWS DMS, the strategy is a task setting. As of October 2026, the CreateReplicationTask MigrationType takes one of three values: full-load, cdc or full-load-and-cdc. The last value is the hybrid pattern, and setting EnableValidation to true in ValidationSettings makes DMS compare source and target rows as it goes.
Microsoft’s Azure Database Migration Service supports online and offline modes for moves to Azure SQL Managed Instance and SQL Server on Azure VMs. Moves to Azure SQL Database, by contrast, run offline.
Hybrid still needs a brief pause for the final switch, because connection strings, scheduled jobs and permissions must move with the data. That step is easy to get wrong, so the cutover deserves its own rehearsal.
Migration Scope, Source Similarity and Data Shape
The third axis covers modifiers that describe how much moves and how different the two ends are. They do not replace the object type or the strategy, but they often decide how much conversion work a project carries. They also explain why two projects with the same object type can differ in effort.
Full, Partial, Incremental and Pilot Migration
Scope says how much data moves in a given run.
- Full: all in-scope data moves, usually when the source will be retired.
- Partial: a subset moves, such as one region, one product line or the most recent years of history.
- Incremental: only new or changed records move after an initial load, which is how trickle and hybrid strategies stay in sync.
- Pilot: a small, representative slice moves first to test mappings, tools and timings.
A pilot is cheap insurance. It exposes mapping gaps and slow transfers while the stakes are still low. Partial scope also forces a decision about archived data, because records that nobody queries may belong in cheaper storage rather than on the new platform.
Homogeneous vs Heterogeneous Migration
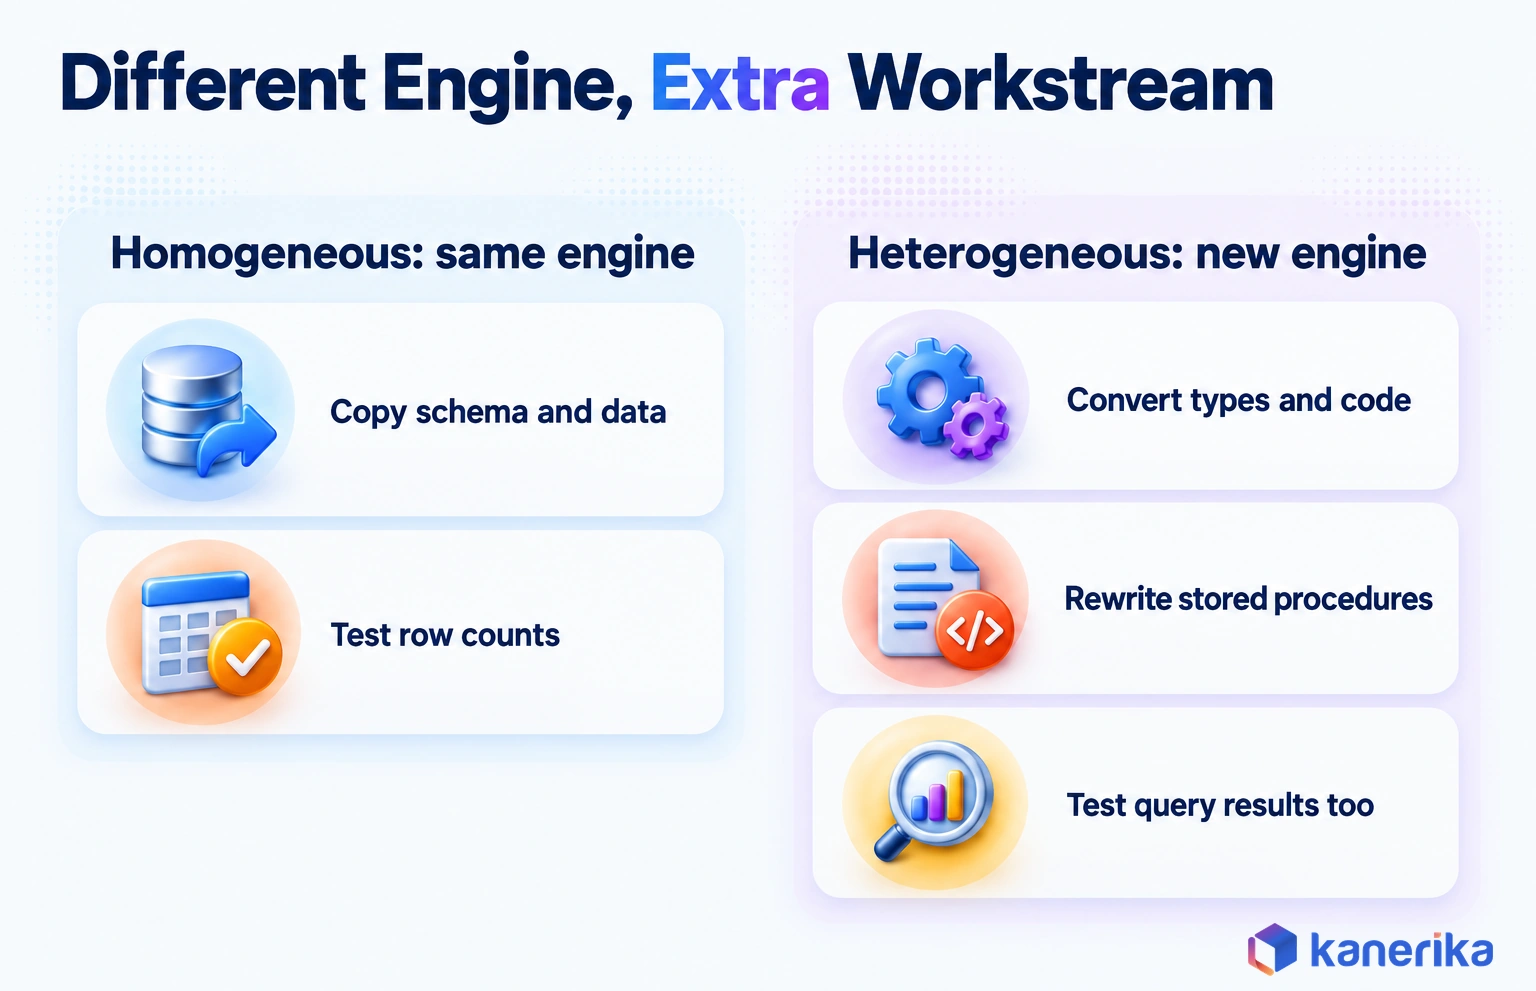
A homogeneous migration keeps the same database engine on both sides, such as MySQL to Cloud SQL for MySQL. A heterogeneous migration changes the engine, such as Oracle to Cloud SQL for PostgreSQL or SQL Server to Cloud SQL for PostgreSQL.
The difference is conversion work. Homogeneous moves can usually copy schemas and replicate data with native tools. Heterogeneous moves must also convert data types, rewrite stored procedures and prove that queries return the same results.
Even so, cloud services support both paths. Google’s service lists homogeneous moves to Cloud SQL and AlloyDB, plus heterogeneous moves such as Oracle to AlloyDB. AWS Database Migration Service states that it “supports fully heterogeneous data migrations between the supported engines.”
So similarity changes the plan more than the tool does. Two projects with the same tool can differ a lot in effort, because only one of them has code to convert.
Structured, Semi-Structured and Unstructured Data
Data shape changes both the mapping and the checks. Structured data in tables maps column by column, so row counts and field totals prove the move.
Semi-structured data, such as JSON or XML, carries nested fields that may need flattening or a new schema. Unstructured data, such as documents, images and audio, moves as files, so checksums and metadata matter more than field mapping.
Many enterprise migrations carry all three. A customer system may hold tables, JSON event logs and scanned contracts, and each one needs its own validation rule.
How to Choose the Right Type of Data Migration
Choosing a type is really choosing a combination: one or more object types, a strategy per stream, and a scope for each run. Three facts then settle most of it. They are the downtime users accept, the similarity of source and target, and the number of dependent systems.
The matrix below maps common situations to a sensible mix. Treat it as a starting point, then adjust it for your own dependencies. If the bigger question is where to land, start with choosing the target platform before you fix the migration mix.
| Situation | Object type(s) | Strategy | Scope | First test |
|---|---|---|---|---|
| End-of-support database | Database, often homogeneous | Hybrid | Full | Row counts and checksums per table |
| Cloud move with 24×7 users | Cloud, database, application | Hybrid or trickle | Pilot, then full | Replication lag and a cutover rehearsal |
| ETL and BI replatform | Warehouse, ETL and BI, heterogeneous | Trickle by subject area | Partial, one domain at a time | Report parity on a pilot domain |
| Merger or acquisition | Business process, application | Trickle by business unit | Partial | Master data match rates |
| Storage refresh | Storage | Big bang or background sync | Full | File counts and checksums |
Read the table by row, since one program can sit on several rows at once. That overlap is normal rather than a sign of poor scoping.
Six Checks Before You Commit to a Type
Before the plan is fixed, run a short pre-flight. These six checks turn the matrix into a plan the team can defend.
- Inventory: list every database, file store, pipeline and report in scope.
- Dependency map: record which systems read from or write to each one.
- Downtime budget: agree in writing how long each business process can pause.
- Similarity check: compare engines, data types and code to see how much conversion is hidden.
- Pilot: move one representative slice and time it.
- Reconciliation plan: define the counts, totals and report checks that prove success.
The full plan, execute and verify process sits in data platform migration best practices. A short version of that process closes this section. These checks stay on the choice of type, because that choice comes first and shapes every later step.
Checklist
Data Migration Checklist
Work through inventory, dependencies, cutover planning and reconciliation with a step-by-step checklist before you lock in your migration types.
Get the Checklist →Worked Example: One Project, Four Migration Types
Consider a beverage manufacturer and distributor that runs analytics on SSAS and a mix of on-premises and cloud systems. Refreshes run hourly, outages are frequent, and several licenses and replication tools overlap. The goal is near real-time reporting on one cloud warehouse.
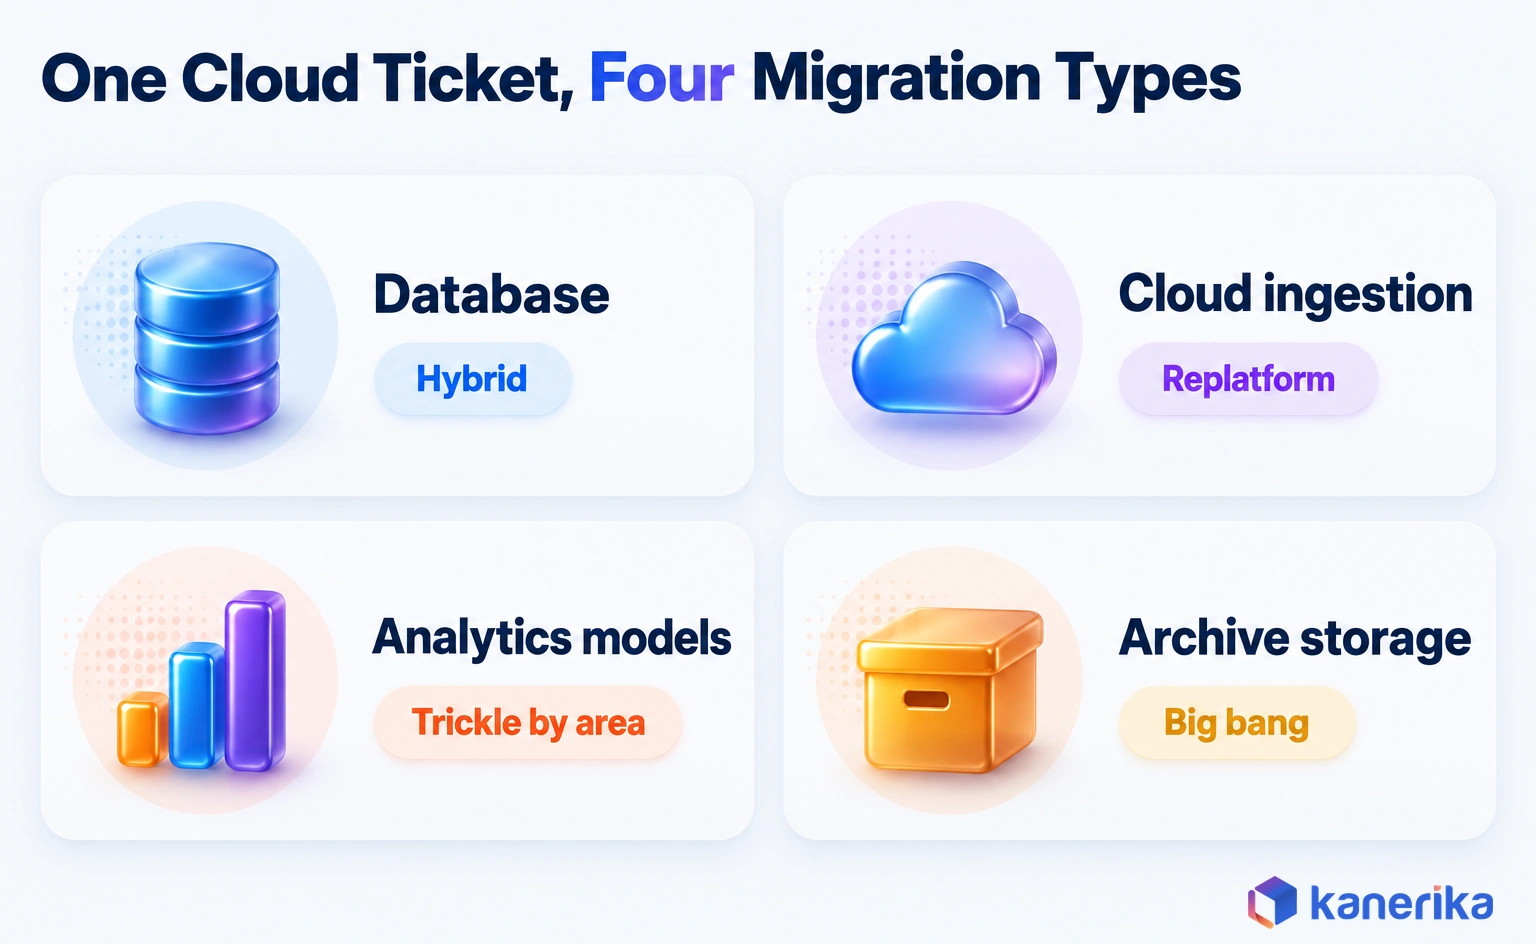
Sorting the work by axis then turns one large project into four streams.
- Database migration (heterogeneous, hybrid): source tables load in bulk into the cloud warehouse, then changes replicate until cutover.
- Cloud migration (replatform): ingestion jobs leave on-premises servers for managed, automated ingestion.
- Analytics platform migration (trickle by subject area): SSAS models are rebuilt one area at a time, with reports compared in parallel.
- Storage migration (big bang): archive files and extracts move to cloud storage in one window, since no user waits on them.
Each stream gets its own strategy because each has a different downtime budget. Finance reports cannot go dark, so the analytics stream runs in parallel, while the archive can move over a weekend. This example is modeled on a Kanerika Snowflake migration; the published results appear in the Kanerika section below.
Risks to Check by Migration Type and How to Validate
Each type fails in its own way, so validation should match the type instead of following one generic checklist. The table below pairs each risk with the type it hits hardest.
| Risk | Type most exposed | Control |
|---|---|---|
| Silent data loss | Database, storage | Row counts and checksums per table or file |
| Type and precision changes | Heterogeneous database | Column-level profiling before and after |
| Broken business rules | Application, business process | Financial control totals and sample transactions |
| Report mismatch | Warehouse, ETL and BI | Report parity on the same date range |
| Hidden dependencies | Data center, cloud | Dependency map and a cutover rehearsal |
| Failed cutover | Any big bang move | Tested rollback plan with a go or no-go point |
Tool logs make these controls concrete. When AWS DMS data validation finds a differing row, the table state shows Mismatched records. DMS logs the key and the mismatched values, typed as RECORD_DIFF or MISSING_TARGET, in the awsdms_validation_failures_v1 table on the target. Validation also needs a primary key or unique index on every table.
Run these checks during the pilot as well as at the end. For deeper methods, see the guide to data quality during migration and the practical steps in data migration testing.
After go-live, the job shifts from proving the move to watching the new system. Data observability then helps catch drift that slips past the final checks.
Data Migration Process Steps and Best Practices
Whatever the type, the process runs in the same five steps. What changes by type is the depth of each step, not the order.
- Assess: profile the source and confirm which types the project holds.
- Design: pick the target layout and a strategy per stream.
- Pilot: move one slice and fix the mappings it exposes.
- Migrate and validate: load in waves, with type-matched checks on each wave.
- Cut over and retire: switch users, monitor, then decommission the source.
Three best practices hold across every type. Keep the source read-only or replicated until sign-off, so rollback stays possible. Automate reconciliation instead of sampling by hand, and name one data owner per domain to sign off the results.
Benefits of Getting the Migration Type Right
Naming the types early pays off in cost, speed and trust. Teams retire overlapping licenses instead of paying for two stacks, a topic the guide to Microsoft licensing optimization covers for Microsoft estates. Fewer cutover surprises also mean less rework, and the Kanerika program below shows both effects in its published numbers.
How Kanerika Runs Multi-Type Migrations
Kanerika’s data migration services treat a migration as a set of typed streams, each with its own strategy, scope and test. That framing matters most on analytics platform moves, where data, logic and reports all change at once.
On ETL paths, Kanerika’s FLIP accelerator converts most of the pipeline logic automatically. Kanerika’s ETL migration consultants then review and redesign the 20-30% of logic that FLIP cannot automate, as on Informatica to Microsoft Fabric moves. Supported ETL paths include Informatica to Talend, Alteryx, Databricks or Microsoft Fabric.
FLIP deploys through Docker inside the client’s own network and analyzes only schema and structure, so production data stays untouched. For database streams, the team runs schema reconciliation and parallel-run testing before cutover.
That split shapes the plan. Automated conversion shortens the heterogeneous part of a project, while human review keeps business rules intact. The guide to migration accelerators explains how this tooling fits into a wider program.
Case Study: A Database, Cloud and Analytics Migration in One Program
The worked example above is modeled on this program.
Kanerika migrated SSAS to a unified Snowflake architecture with automated ingestion for near real-time analytics. In the terms of this guide, that was a database, cloud and analytics platform migration delivered as one program. The published case study, dated November 5, 2025, reports these results.
- 60% reduction in manual data reconciliation
- 40% faster data reporting cycles
- 3X quicker analytics delivery
- $130K annual savings from license and maintenance cost reduction
The reconciliation gain matters most for this guide, because reconciliation is the one check every migration type shares. It is also the first control in the risk table above.
Kanerika Service
Data Migration Services
Kanerika plans and runs multi-type migrations, using FLIP to automate pipeline conversion and consultants to redesign the logic it cannot automate.
Explore Migration ServicesThe Bottom Line: Which Types of Data Migration Are You Running?
Every project can be named on three axes. The object type says what moves, the strategy says how it moves, and scope and similarity say how much changes on the way.
Start with the object types, because one cloud ticket can hide four of them. Then give each stream the strategy its downtime budget allows. In general, big bang fits small, tolerant moves, hybrid fits large databases with tight outages, and trickle fits many dependent modules.
So, which types of data migration are you running? List what moves, decide how each stream moves, and that answer becomes your plan.
Frequently Asked Questions
What are the main types of data migration?
The main types of data migration by object are storage, database, application, cloud, business process, data center, and warehouse, ETL and BI platform migration. Each type then runs with a strategy, which is big bang, trickle or hybrid. Scope and similarity add modifiers such as full or partial and homogeneous or heterogeneous.
What are the 4 types of data migration?
Lists that name four types usually mean storage, database, application and cloud migration. Those four cover what many projects move. Longer lists add business process, data center, and warehouse, ETL and BI platform migration. The counts differ because sources classify on different axes, and some mix object types with strategies such as big bang.
What is the difference between data migration and data conversion?
Data migration moves data from one system, platform or location to another. Data conversion changes the format, structure, codes or units of the data so a target system can use it. A migration often includes conversion, and conversion can also happen without any move. Many replatforming projects need both jobs, planned and tested as separate workstreams.
What are the 5 Rs of migration?
The 5 Rs come from Gartner, which outlined five cloud migration strategies in 2011. AWS later built its own six strategies on that list, as an AWS enterprise strategy blog explains. AWS publishes the later lists, which name strategies such as rehost, replatform, repurchase, refactor and retire. Each application in scope gets one of them.
What are the 6 Rs of data migration?
The 6 Rs are the six application migration strategies AWS described, building on Gartner’s earlier five. They are rehost, replatform, repurchase, refactor or re-architect, retire and retain. Each one names what happens to an application in a cloud move. AWS later added relocate, which forms the 7 Rs list in its large migration guidance.
What are the 7 migration strategies?
AWS lists seven migration strategies in its large migration guide. They are retire, retain, rehost, relocate, repurchase, replatform, and refactor or re-architect. AWS notes that rehost, replatform, relocate and retire are the most common in large migrations. These strategies apply to applications, so the data inside each one still needs its own strategy.
Which migration approach keeps downtime lowest?
Hybrid and trickle approaches keep downtime lowest. Both rely on continuous replication, where an initial full load is followed by a steady flow of changes from source to target. Users keep working until a short final cutover. Some pause is still needed to switch connections and jobs, so rehearse the cutover and agree the window in advance.
What are common challenges in data migration?
Common challenges include hidden dependencies between systems, data type and code mismatches between engines, and poor source data quality. Business rules buried in old code can be lost, and reports may show different numbers after the move. Tight downtime windows and weak rollback plans add risk. A pilot run surfaces many of these problems early.
How do you validate data after a migration?
Validate data at several levels. Compare row counts and checksums per table or file, profile columns for type and precision changes, and match financial control totals. For analytics platforms, run the same reports on both systems for the same date range. Run these checks in the pilot first, then again before and after cutover.
How long does a data migration project take?
Duration depends on the types involved, the data volume, the number of dependent systems and the downtime budget. A storage refresh can finish quickly, while an analytics platform migration with many pipelines runs in phases. Heterogeneous moves take longer because code and data types need conversion. A pilot run gives the most reliable estimate for your project.
How can automation and AI help with data migration?
Automation speeds up the repetitive parts of a migration, such as schema conversion, pipeline code conversion and validation checks. On ETL paths, Kanerika’s FLIP accelerator converts most of the logic, and consultants review and redesign the 20-30% that FLIP cannot automate. People still own business rules, mapping decisions and final sign-off, which keeps results trustworthy.
What are some data migration strategies?
The three common data migration strategies are big bang, trickle and hybrid. Big bang moves everything in one planned outage window. Trickle moves data in phases while both systems run and stay in sync. Hybrid runs a bulk load first, replicates ongoing changes, and finishes with a short cutover once the target catches up.
What is the difference between big bang and trickle data migration?
Big bang migration moves all data in one cutover window, so downtime is longer, the project is short and rollback is simple. Trickle migration moves data in phases while the old and new systems run side by side. It keeps downtime low, and it costs more because two systems must run and stay synchronized.
What is the difference between homogeneous and heterogeneous migration?
A homogeneous migration keeps the same database engine on both sides, such as MySQL to Cloud SQL for MySQL. A heterogeneous migration changes the engine, such as Oracle to PostgreSQL. Heterogeneous moves add schema conversion, data type mapping and code rewrites, so they need more testing. AWS and Google migration services support both kinds of move.
What is the most common type of migration?
No reliable public figure ranks migration types by frequency. In practice, database and cloud migrations sit at the core of many enterprise projects, because a new engine or a cloud platform drives much of the work. They often arrive together with application, storage or analytics platform migrations inside the same program of work.
Can a data migration involve more than one type?
Yes. Many enterprise projects combine several types. A move of reporting to the cloud can include a database migration, an ETL migration, a BI migration and a storage migration at once. Each part should get its own strategy and validation plan, because each has a different downtime budget and a different way of failing.
How do I choose the right type of data migration for my organization?
Start by listing what moves, then check three facts. These are the downtime your users accept, how similar the source and target engines are, and how many systems depend on the data. Low tolerance for downtime points to hybrid or trickle. Different engines add conversion work. Many dependencies call for phased waves and a pilot run first.
What is the difference between cloud migration and data warehouse migration?
Cloud migration moves data, applications or workloads from on-premises systems to a cloud, or between clouds. Data warehouse migration moves an analytics platform, including warehouse tables, the ETL jobs that feed them and the reports on top. A warehouse migration is also a cloud migration when the new warehouse runs in the cloud, which is common.
Is ETL the same as data migration?
ETL is a technique, and data migration is a project. ETL extracts, transforms and loads data, and teams often use it inside a migration to reshape records for the target. Ongoing ETL also runs long after a migration ends, feeding warehouses every day. Moving ETL jobs to a new tool is a migration type of its own.