TL;DR
A legacy systems to Databricks migration works best as a phased move in waves, not a single big-bang cutover. Warehouses such as Oracle or Teradata need automated SQL conversion, then engineers to finish the stored procedures. With ETL tools such as Informatica or SSIS, convert sound pipelines and rebuild the ones that were already fragile. Low-change systems of record can stay put, queried in place through Lakehouse Federation until a move pays off. Set up Unity Catalog before the first wave, so permissions and lineage never become a cleanup project. Prove each wave with financial totals in a parallel run, then switch the legacy platform off on a fixed date.
Key Takeaways
- Plan the move in waves, starting with high-value, low-complexity workloads, instead of one big-bang cutover.
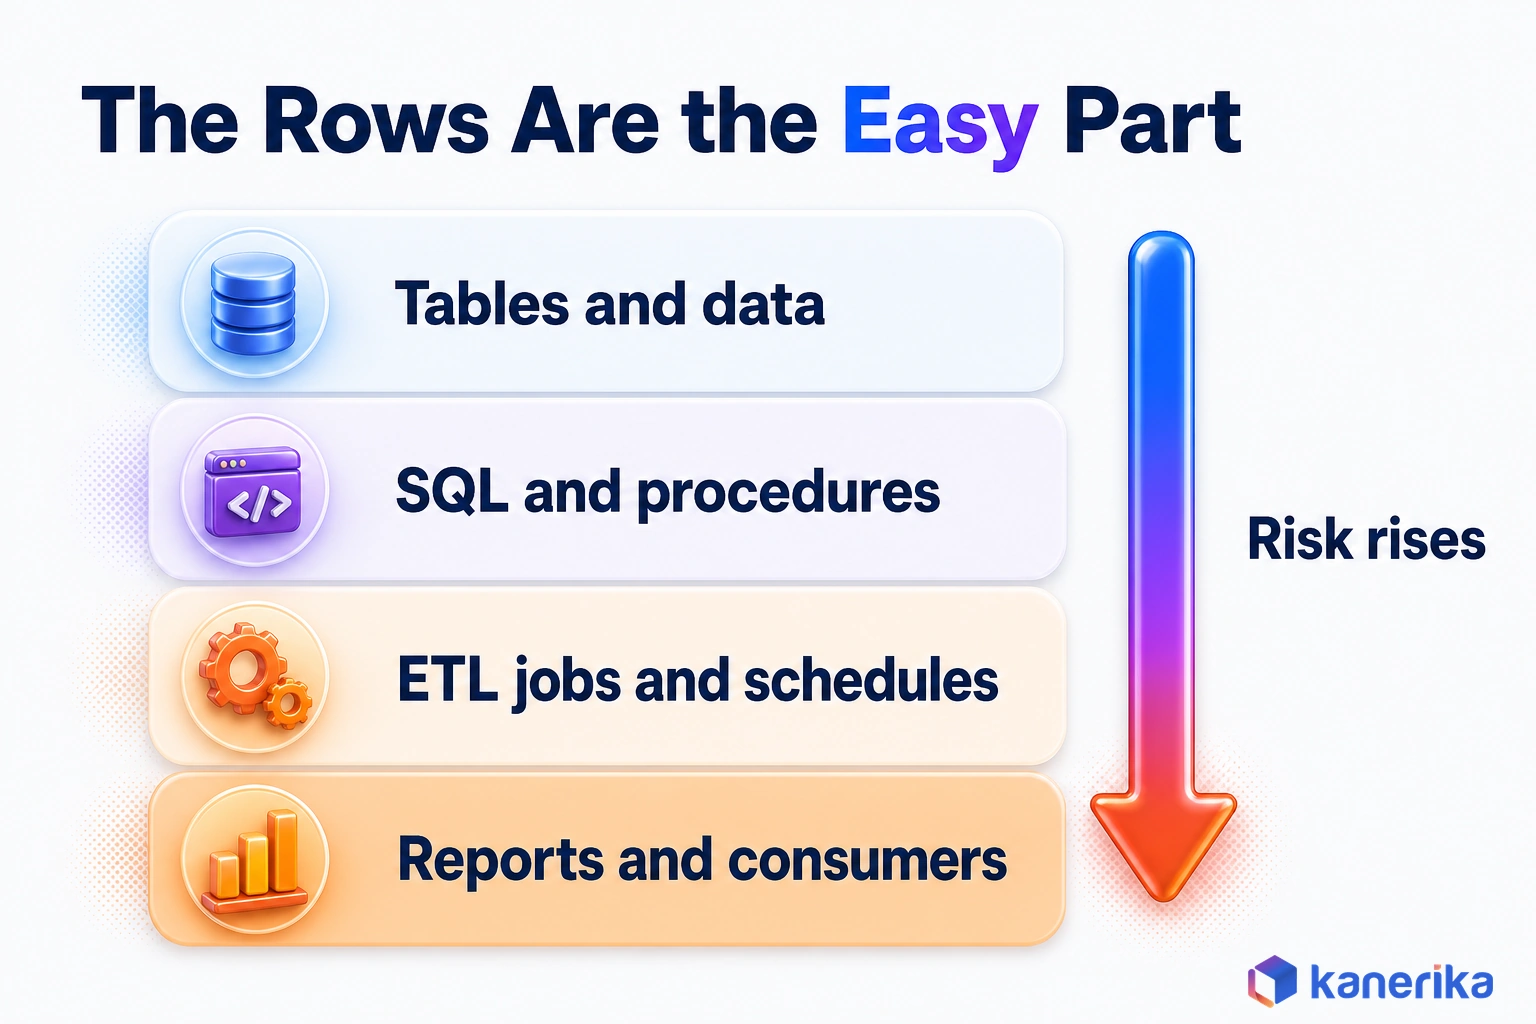
- Copying rows is the easy part, while stored procedures, ETL logic, schedules and report consumers carry most of the risk.
- Free tools such as Databricks Lakebridge profile and convert common warehouse SQL, while partner accelerators cover gaps such as Informatica.
- Lakehouse Federation lets low-change systems stay where they are while Databricks queries them in place.
- Set up Unity Catalog groups and grants before the first wave, so access and lineage move with the data.
- Validate with financial totals and report comparisons during a parallel run, then retire the legacy platform on a fixed date.
The Numbers Matched. The Month-End Report Did Not.
Picture the first Monday after a warehouse cutover at a mid-sized distributor. At this point, the migration team has proof that every table arrived. Row counts match to the last record, and the nightly jobs finished early on the new platform.
Then finance opens the month-end margin report. Gross margin is off by only a fraction of a percent, but that is enough to stop the close.
Nobody lost any data. A stored procedure in the old warehouse rounded each invoice line before it added up the totals. The converted job added everything first and rounded once at the end, so the same rows produced a different answer.
That gap between moving data and moving meaning is what this guide is about.
Why a Legacy Systems to Databricks Migration Is More Than a Data Copy
A legacy systems to Databricks migration replaces an older data platform with the Databricks lakehouse. It moves far more than tables, because the old platform also holds business rules, schedules, security roles and the reports people trust.
That is also why copying data is usually the shortest phase. The longer work sits in translating logic written for another engine, then proving that the new numbers match the old ones. Teams that plan only for the copy tend to discover the rest during cutover week, when every surprise costs the most.
This guide follows the order a real program runs in. It starts with scope and the reasons to move, then covers source-specific paths and strategy. After that come assessment, target design, code conversion, validation, cost and the mistakes that cause rework.
What a Legacy-to-Databricks Migration Actually Moves
Scope is easiest to see one asset type at a time, starting with a single warehouse. Take a finance warehouse running on Oracle, where the tables become Delta tables through mostly mechanical work.
Its PL/SQL packages must be rewritten as SQL or Python, and its scheduler entries become Databricks jobs. The database roles turn into Unity Catalog groups and grants. Each of those is a separate workstream with its own owner and its own test plan.
Asset-by-Asset Scope
| Asset | On the legacy platform | What changes on Databricks |
|---|
| Data | Tables, files and history | Lands as Delta tables in cloud storage, usually through bronze, silver and gold layers |
| Schemas and data types | DDL and vendor-specific types | Mapped to Databricks SQL types, with checks on precision and date handling |
| SQL and stored procedures | Views, PL/SQL, T-SQL, Teradata BTEQ scripts | Converted to Databricks SQL or Python; procedural logic needs engineer review |
| ETL jobs | Informatica, SSIS or DataStage mappings | Rebuilt as notebooks, SQL or declarative pipelines |
| Schedules and dependencies | Enterprise schedulers, cron, agent jobs | Recreated as Databricks jobs with explicit task dependencies |
| BI reports | Power BI, Tableau or Cognos on the old source | Pointed at Databricks SQL warehouses and tested again |
| Security roles | Database roles and grants | Mapped to Unity Catalog groups, grants, row filters and column masks |
| Downstream consumers | Extracts, APIs and partner feeds | Moved one by one, each with an owner who signs off |
The table also shows where the risk sits. Data and schemas are well understood, so tools handle most of them. The bottom half, from stored procedures down to consumers, is where business meaning lives, so it deserves most of the testing budget.
Our comparison of data lake vs data warehouse lays out the two patterns a lakehouse brings together, which helps when the design is open.
Migrate, Rebuild, Retire or Retain
Each object in the inventory gets one of four outcomes before any wave is planned, and each outcome has a plain test.
| Outcome | Test | Typical example |
|---|
| Migrate | The logic is sound and still used; it only needs a new engine | A monthly revenue model with stable rules |
| Rebuild | Still needed, but the job is fragile, slow or undocumented | A sprawling procedure nobody dares to touch |
| Retire | No queries or report views in the usage logs for months | Extracts built for a campaign that ended long ago |
| Retain | Changes rarely, gains little from moving, or sits close to an operational system | A system of record queried a few times a week |
Retiring is the cheapest outcome, so it pays to look for it first. In practice, usage logs on a legacy platform often reveal a long tail of tables and reports that nobody has opened in a year. Every one of them dropped from scope is one less thing to convert, test and explain.
Kanerika Service
Databricks Consulting and Implementation
Kanerika’s Databricks team plans the inventory, target design and migration waves for legacy estates, then takes the first workloads into governed production.
Explore Databricks Services
Signs It Is Time to Leave the Legacy Platform
The decision to move usually comes from a deadline or a blocker rather than a strategy deck. A license renewal, a hardware refresh or a stalled AI project forces the question of whether to keep investing in the old stack.
These are the signals that show up most often:
- A support or license renewal is due. A multi-year renewal on an appliance or proprietary engine locks in cost for another cycle, so the time to decide is before signing.
- Batch windows are being missed. Nightly loads run into business hours, but adding hardware no longer buys enough headroom.
- AI and machine learning work depends on copies. Data scientists export extracts to train models, which breaks lineage and doubles storage.
- Hardware or software reaches end of life. Once the vendor stops patching, the security team starts asking for an exit plan.
- Skills are getting scarce. Few engineers want to maintain old ETL tools or proprietary SQL dialects, and the ones who do are expensive.
- Two platforms are already running. A newer platform exists, but the old one never switches off. The business pays twice for storage, licenses and support, and teams argue over which numbers are right.
What Moving Solves
Moving solves several of these at once. Storage and compute scale separately on Databricks, so a heavy month-end run no longer needs year-round capacity. Data engineering, BI and machine learning also share one governed copy of the data. Teams that plan to train models on the new platform can follow our guide to MLflow on Databricks once the data has landed.
The vendor’s scale matters too, since this is a platform choice for a decade or more. In its August 13, 2026 announcement, Databricks reported a revenue run-rate above $7 billion and growth of more than 80% year over year. The same release says more than 20,000 organizations use the platform, including 70% of the Fortune 500.
Case Study
60% Faster Error Resolution with Cloud App Migration
A global spend-management provider consolidated a legacy platform into its cloud-native one. Kanerika migrated the data and services, cutting infrastructure cost 32% and error resolution time 60%.
Read the Case Study →
When Not to Move Everything
A full move is not always the right answer. Some systems change rarely, feed only a few reports and sit close to an operational application. Moving them adds cost and risk without much return.
For those, Lakehouse Federation lets Databricks query sources such as Oracle, Teradata, SQL Server and Synapse without migrating the data. Analysts get one SQL interface while the source stays where it is. A federated source can still be copied into Unity Catalog managed tables later, once a renewal or new workload justifies the move.
The trade-off shows up at query time. Federated queries lean on the source system’s capacity, so heavy daily workloads usually belong on Databricks itself. Our guide to Databricks Lakehouse Federation covers the feature in more depth.
Source-by-Source Migration Paths
Every legacy source brings its own conversion problem, so the right path depends on where you start. A Teradata warehouse, for example, is mostly a SQL dialect problem. A Hadoop cluster is mostly a jobs and file-format problem, while an Informatica estate is a mapping-logic problem.
The table below summarizes the four most common starting points. The sections after it then explain each one in detail.
| Source | What moves | Main conversion work | Landing route on Databricks |
|---|
| Data warehouses (Oracle, Teradata, Netezza, SQL Server, Synapse) | Tables, views, stored procedures, scheduled loads | Dialect SQL and procedural code | Bulk export to cloud storage, CDC connectors where supported, automated SQL conversion |
| Hadoop and Hive | Hive tables, HDFS files, Pig, Sqoop and Oozie jobs | Re-expressing jobs as Spark SQL or PySpark | Hive tables rewritten as Delta; jobs rebuilt as Databricks jobs |
| ETL tools (Informatica, SSIS, DataStage, Talend) | Mappings, workflows and parameters | Translating tool logic into code | Converted pipelines in notebooks or declarative pipelines |
| Mainframe and DB2 feeds | Extract files, copybook layouts, batch schedules | Parsing fixed-width and packed fields | Files landed in cloud storage and picked up by Auto Loader |
Data Warehouses: Oracle, Teradata, Netezza, SQL Server, Synapse
Warehouse migrations are mostly about SQL. The tables generally move cleanly through bulk export to cloud storage. Views and stored procedures, on the other hand, need translation from PL/SQL, BTEQ, T-SQL or Netezza SQL into Databricks SQL.
Databricks has a free tool for this work. As of October 2026, the Lakebridge documentation shows Oracle, Teradata, SQL Server, Snowflake and Synapse covered by all four of its components. Those are the profiler, the analyzer, the converter and the reconcile step. Netezza and DB2 also appear on its list of sources.
For changes that keep arriving during a phased move, Lakeflow Connect adds managed, serverless connectors governed by Unity Catalog. Its CDC database connectors, as of October 2026, include SQL Server, MySQL and PostgreSQL. SQL Server sources add wrinkles of their own, such as linked servers and agent jobs. Our SQL Server data migration guide covers those in depth.
Hadoop and Hive
Hadoop migrations usually retire a cluster that costs more to run than it returns. Hive tables are rewritten as Delta tables, which adds ACID transactions and time travel on top of the same open file formats. Delta Lake is an independent open-source project under the Linux Foundation, so the table format is not tied to one vendor.
The jobs take more effort than the tables. Pig scripts, Sqoop imports and Oozie workflows have no direct twin on Databricks. Each one is re-expressed as Spark SQL, PySpark or a Databricks job. Lakebridge’s analyzer can scan Hive, Pig, Sqoop and Oozie code to size the work. It lists no converter for them as of October 2026, so plan these jobs as engineer rewrites.
ETL Tools: Informatica, SSIS, DataStage, Talend
ETL tool migrations carry the most hidden logic. A single Informatica mapping can hold lookups, filters, joins and expressions that nobody has documented since the tool was installed. SSIS packages also add script tasks and package variables on top.
The usual target on Databricks is ELT. Raw data lands first, then SQL or PySpark transforms it inside the lakehouse, and our comparison of ETL vs ELT explains the difference in detail. Lakebridge can convert SSIS and DataStage and can assess Talend, but as of October 2026 Informatica is not on its list. Partner accelerators fill that gap, and our guide to ETL migration also walks through the general approach.
Kanerika Service
Informatica to Databricks Migration with FLIP
FLIP converts Informatica workflows into Databricks pipelines, cutting manual effort by up to 83% while the live environment keeps running.
Explore the Migration Service
Mainframe and DB2 Feeds
Mainframe sources rarely move in one step, especially when other systems still depend on them. The common pattern keeps the mainframe running, extracts its data to files on a schedule and lands those files in cloud storage. Copybook layouts and packed decimal fields need parsing before the data is usable.
On the Databricks side, Auto Loader incrementally processes new files as they arrive in cloud storage, through the cloudFiles source. A minimal ingestion job for a daily DB2 extract looks like this:
# Land a daily DB2 extract into the bronze layer with Auto Loader
df = (spark.readStream
      .format("cloudFiles")
      .option("cloudFiles.format", "csv")
      .option("cloudFiles.schemaLocation", "/Volumes/main/raw/checkpoints/db2_orders_schema")
      .option("header", "true")
      .load("/Volumes/main/raw/landing/db2_orders/"))

(df.writeStream
   .option("checkpointLocation", "/Volumes/main/raw/checkpoints/db2_orders")
   .trigger(availableNow=True)
   .toTable("main.bronze.db2_orders"))
The checkpoint lets each run pick up only new files, so the same extract is never loaded twice. Once the bronze table exists, the parsing and cleanup rules move into silver, where they can be tested on their own.
Schema drift is the error pattern to plan for. Auto Loader infers every CSV column as a string unless cloudFiles.inferColumnTypes is set to true. Under the default schema evolution mode, addNewColumns, a new column in the extract stops the stream with an UnknownFieldException.
Auto Loader adds that column to the schema first, so restarting the stream resumes the load. Values that do not match the schema land in the _rescued_data column rather than being dropped. Our Databricks Auto Loader guide covers ingestion setup beyond this example.
Choosing a Migration Strategy
A migration strategy decides how much of the old design survives the move. A clean SQL Server reporting mart with a hard renewal date suits a lift-and-shift. In the same estate, a decade of undocumented Teradata procedures calls for a redesign instead.
| Strategy | When it fits | Main risk | Effort |
|---|
| Lift-and-shift | Clean, well-documented SQL and a hard deadline | Carries old inefficiencies and bad jobs onto the new platform | Low |
| Replatform and refactor | Sound logic that needs a new engine plus tuning | Conversion errors in procedural code | Medium |
| Redesign | Fragile pipelines, or a move to streaming or a new data model | Largest scope, though the cleanest result | High |
| Phased hybrid | Large estates with many sources and owners | Two platforms run at once for a while | Medium to high, spread across waves |
Large programs often end up with the phased hybrid. Early waves lift and refactor simple workloads in order to build confidence and skills. Later waves redesign the pipelines that were already causing trouble, because rebuilding a broken job on a new platform only moves the breakage.
ETL-First or BI-First?
Within a phased plan, teams still have to choose what moves first. There are two common orders, and each suits a different situation.
ETL-first moves the pipelines and data before touching reports. Picture an insurer whose nightly claims load keeps missing its window. Moving ingestion and transformation first fixes the pain that started the program. Reports keep reading from the old warehouse until the new tables are proven.
BI-first rebuilds the reporting layer on Databricks early, often on top of federated or replicated data. A retailer whose executives want a new sales dashboard before the holiday season might choose this path. It shows value quickly, though the pipelines behind those reports still have to move later.
A simple rule helps when teams disagree. If the pain is in loads and freshness, go ETL-first. If the pain is in slow or inconsistent reporting, go BI-first and let the old pipelines feed it for a while.
Assessment: Inventory, Dependencies and Wave Planning
Assessment turns a vague estate into a ranked list of work. Estimates are won or lost in this phase, because everything later depends on knowing what exists and how it connects.
Databricks describes its own migration method in five phases: discovery, assessment, strategy and design, a production pilot, and execution. The steps below fit inside the first three of those phases, before any code moves.
- Build the inventory. List every table, view, procedure, ETL job, schedule, report and consumer. Profiling tools such as the Lakebridge profiler and analyzer can scan supported sources and size the code base.
- Map dependencies. Trace which jobs feed which tables, and which reports read them. A wave that moves a table without its upstream job will break on day one.
- Profile usage. Pull query and login history to see what people actually use. This is where most retire candidates show up.
- Score complexity and value. Rate each workload on conversion difficulty and business value, using simple 1-to-5 scales.
- Plan the waves. Group related workloads so each wave can be tested and cut over on its own.
The two scores from step four do most of the planning work. Plotted on two axes, they sort the estate into four groups, and each group has an obvious place in the plan.
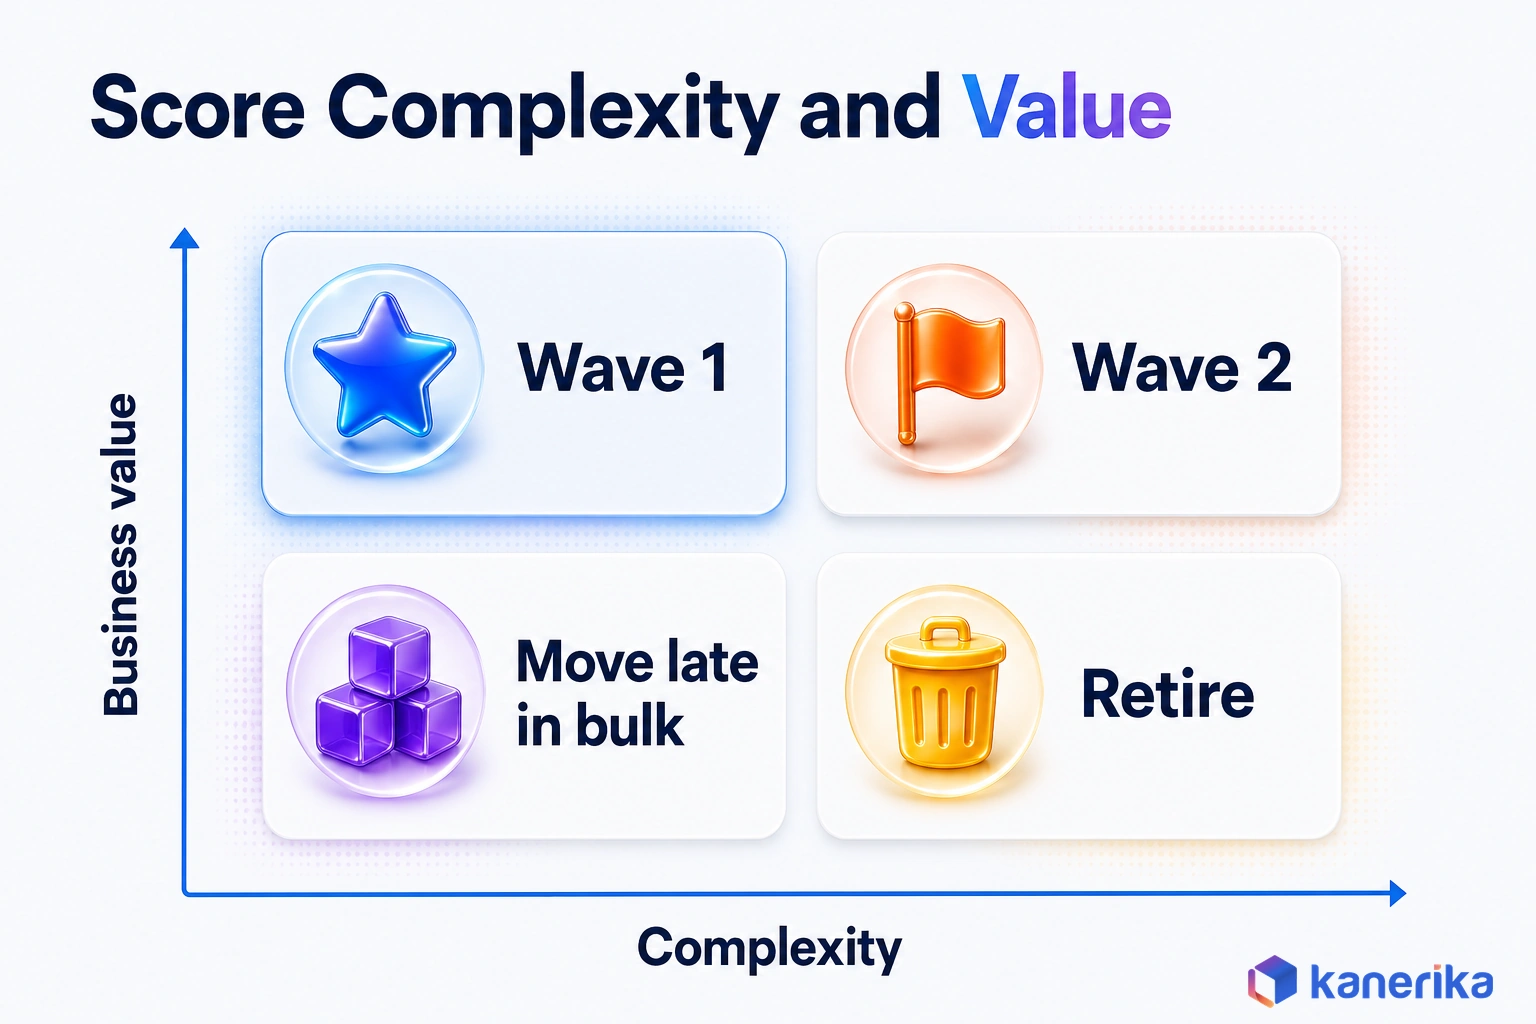
High-value, low-complexity workloads go in the first wave, since they prove the approach quickly. High-value, high-complexity work follows once the team has learned the conversion patterns. Low-value, high-complexity items are the strongest retire candidates, and the low-low group can move in bulk late in the program. The generic phase-by-phase steps behind this are also in our data migration checklist.
Target Architecture: Medallion Layers, Unity Catalog and Ingestion
The target architecture is the shape the data takes once it lands on Databricks. Getting it right before the first wave avoids rework, since every later wave plugs into the same layers and permissions.
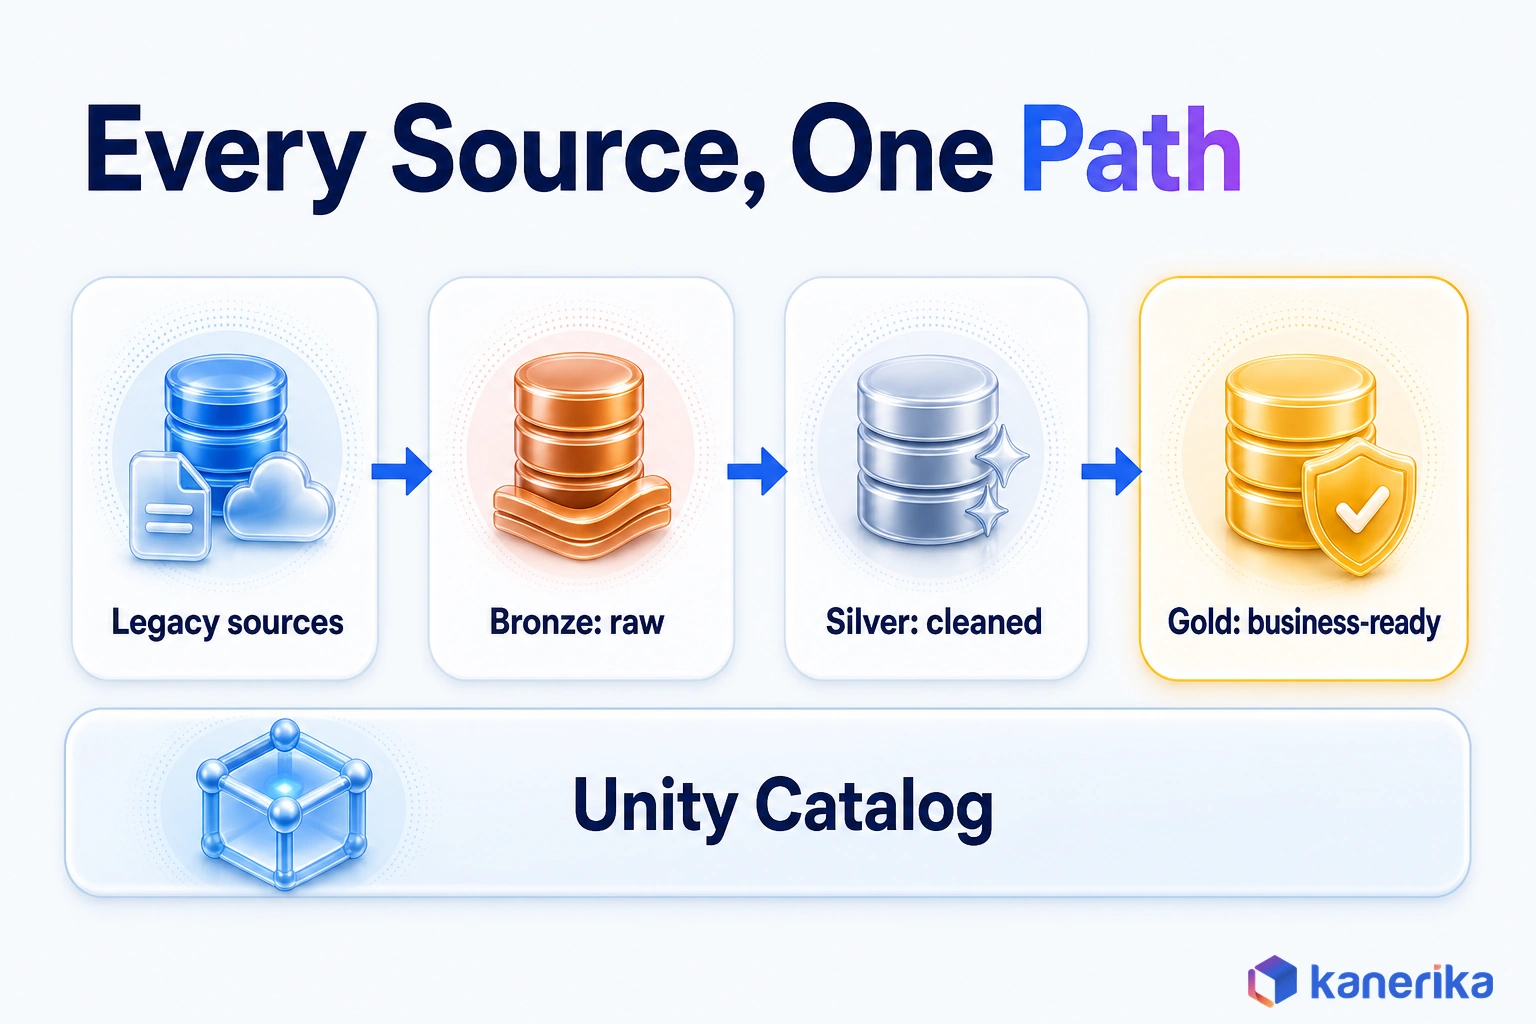
The usual pattern is the medallion design. Raw data lands in a bronze layer exactly as the source sent it. Silver then holds cleaned and conformed tables, while gold holds the business-ready tables that reports and models read. Legacy staging, core and mart schemas map onto those three layers quite naturally, which keeps the move familiar for the people who maintain them.
Each ingestion and governance tool has a clear job in that design:
| Tool | Job in the migration |
|---|
| Auto Loader | Picks up extract files from cloud storage incrementally into bronze |
| Lakeflow Connect | Managed, serverless connectors, including CDC for supported databases |
| Lakehouse Federation | Queries sources in place during the transition, or for systems you retain |
| Unity Catalog | One place for grants, lineage and audit across every layer |
Security deserves its own design pass. Legacy database roles rarely map one-to-one onto Unity Catalog. Map them to groups first, then grant those groups access at the catalog, schema or table level. A role like FINANCE_READ, for instance, becomes a finance readers group with SELECT on the gold finance schema.
Row filters and column masks then replace the secure views that older platforms used to hide sensitive fields. Our guide to Databricks security controls covers the options one control at a time.
The workspace and network setup underneath all of this is a separate project. A solid Databricks deployment plan covers workspaces, networking and environments. Our overview of Databricks lakehouse architecture shows how the layers fit together.
Converting SQL, Stored Procedures and ETL Code
Code conversion is where automation helps the most, and also where it stops short. Tools can translate much of a dialect’s SQL. Logic that encodes business rules, however, still needs an engineer who knows what the code was meant to do.
Databricks introduced Lakebridge on June 12, 2025, as a free migration tool built on BladeBridge technology. Databricks says it can automate up to 80% of migration tasks and make projects up to twice as fast. Those are vendor figures, so treat them as a ceiling for well-supported sources rather than a plan.
Where Automation Stops and Engineers Take Over
Partner accelerators cover other ground. Kanerika’s FLIP targets Informatica pipelines, which Lakebridge does not list, and our guide to migrating Informatica to Databricks covers that path. Either way, the split of work looks much the same:
| Area | What automation handles well | What still needs engineers |
|---|
| Dialect SQL | Functions, data types, joins and most query syntax | Edge cases in date math, nulls and implicit casts |
| Stored procedures | Simple control flow and DML statements | Cursors, dynamic SQL, error handling and temp-table logic |
| User-defined functions | Direct translations of scalar functions | Functions that call external libraries or vendor packages |
| Orchestration | Rebuilding job steps and dependencies | Retry rules, business calendars and cross-system triggers |
| Performance | A baseline conversion that runs correctly | Partitioning, clustering and file sizing for real volumes |
The month-end rounding problem from the opening sits squarely in the right-hand column. A converter can translate ROUND and SUM perfectly and still change the order in which they run. Only a test that compares business totals catches it, which is why conversion and validation work best as one workstream.
Watch on YouTube
Alteryx to Databricks Migration with FLIP: Up to 80% Automation (Demo)
Kanerika demonstrates an Alteryx to Databricks migration with the FLIP accelerator, from the source workflow to the converted Databricks output.
Conversion also gets faster with a shared pattern library. Suppose a wave 1 engineer rewrites a cursor loop as one set-based MERGE. Written down once, that pattern serves every wave-2 procedure with the same shape, so later waves are sized on known effort.
Validation, Parallel Run and Cutover
The distributor’s margin report passed every row count, which is exactly why row counts are only the first check. Validation has to prove that the new platform gives the same answers as the old one. The costliest errors leave the row count intact and change the numbers.
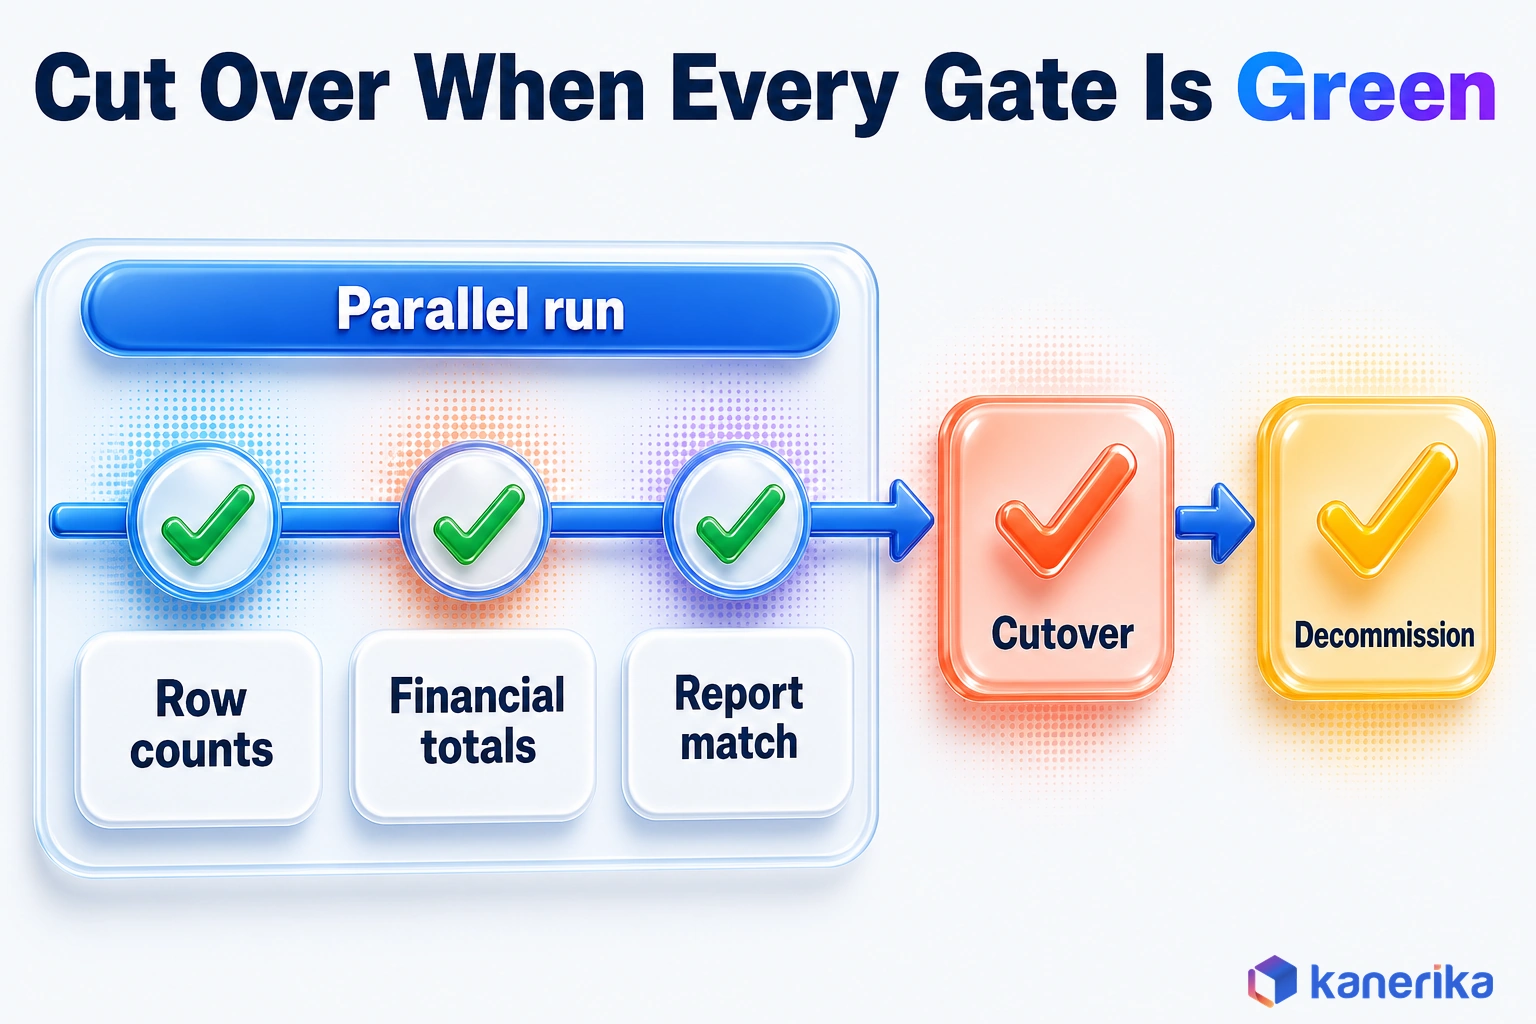
A practical sequence moves from cheap checks to expensive ones:
- Row counts per table and partition, to catch missing or duplicated loads.
- Aggregate and financial totals, such as revenue by month or balance by account, compared to the cent.
- Report-level comparison, running the same report on both platforms and comparing the output.
- Parallel run, operating both platforms on live data for an agreed period.
- Exit criteria sign-off, where data owners confirm that each check passed.
- Rollback plan, kept ready until the sign-off is complete.
- Decommission, switching off the legacy jobs on a fixed date.
Aggregate checks are also simple to write. A query like this one lists every month where the legacy total and the Databricks total disagree:
-- Months where legacy and Databricks margin totals disagree
SELECT l.fiscal_month,
       l.gross_margin            AS legacy_total,
       d.gross_margin            AS databricks_total,
       l.gross_margin - d.gross_margin AS difference
FROM   legacy_snapshot.finance.monthly_margin AS l
JOIN   main.gold.monthly_margin AS d
  ON   l.fiscal_month = d.fiscal_month
WHERE  l.gross_margin <> d.gross_margin
ORDER  BY l.fiscal_month;
An empty result for every month in the comparison window is the evidence finance needs. Lakebridge’s reconcile component also automates this kind of source-to-target comparison for supported sources. Our guides to data migration testing and data reconciliation cover the techniques in more depth.
Exit Criteria and Cutover
The Databricks migration method also calls for parallel testing and reconciliation during user acceptance testing. Agree the exit criteria before the parallel run starts, so nobody moves the goalposts under deadline pressure.
| Check | Exit criterion | Owner |
|---|
| Row counts | Full match per table, or every gap explained | Data engineering |
| Financial totals | No unexplained differences at the agreed precision | Finance data owner |
| Report comparison | Key reports match on both platforms | Report owners |
| Performance | Critical jobs finish inside their batch window | Platform team |
| Access | Every user group tested against Unity Catalog grants | Security |
| Rollback | Restore path tested once before cutover | Migration lead |
Cutover itself should then be boring. When every criterion is green, consumers switch to Databricks and the legacy jobs stop writing. The old platform then stays read-only for a short safety period before it is shut down.
What Drives Migration Cost and Timeline
Two estates with the same terabytes can differ widely in effort if one is mostly stored procedures and the other is simple tables. Cost and timeline depend on a handful of measurable drivers, and data size is only one of them.
| Driver | Why it matters |
|---|
| Object count | More tables, jobs and reports mean more conversion and testing |
| Share of procedural code | Procedures and scripts need engineer time that tools cannot replace |
| Number of sources | Each source adds its own connector, dialect and owner |
| Data volume | Drives transfer time, storage cost and the length of backfills |
| Dual-run period | Two platforms cost money for as long as both are live |
| Compliance scope | Regulated data adds review, masking and audit work |
On the platform side, Databricks pricing is pay-as-you-go with no up-front cost and per-second billing. Usage is measured in Databricks Units (DBUs), a normalized unit of processing, and committed-use contracts can lower the rate. That model rewards the cleanup work described earlier, because retired tables and tuned jobs stop consuming DBUs straight away.
Even so, the dual-run period is the line item teams forget most often. Budget for both platforms during the parallel run, and put the decommission date in the plan from the start. A migration that never switches off the old system keeps paying for it indefinitely.
Migration ROI Calculator
Estimate the Payback of Your Migration
Enter your current platform costs and effort to see what a move off your legacy stack could return before you commit to a plan.
Calculate Migration ROI →
Common Migration Mistakes and How to Avoid Them
Picture a fragile nightly job that the team copied over unchanged, now failing on Databricks for the same reasons it failed on the old warehouse. Mistakes like that repeat from one program to the next, which makes them avoidable. Each of the seven below has a straightforward fix.
- Lifting and shifting bad jobs. A slow, fragile pipeline stays slow and fragile on Databricks. Fix: mark such jobs for rebuild during assessment.
- Adding governance after cutover. Permissions bolted on later leave gaps and audit findings. Fix: set up Unity Catalog groups and grants before the first wave.
- Validating only row counts. Counts match while totals drift, as in the rounding example. Fix: compare financial totals and report outputs.
- No budget for the dual run. The parallel period gets cut short in order to save money. Fix: plan and fund both platforms until the exit criteria pass.
- Big-bang cutover. Everything switches at once, so one failure blocks everything. Fix: cut over in waves that can each roll back.
- Ignoring report consumers. Extracts and spreadsheets that read the old system break silently once the source moves. Fix: list every consumer and give each one an owner.
- No decommission date. The old platform lingers and still costs money. Fix: put the shutdown date in the plan and track it.
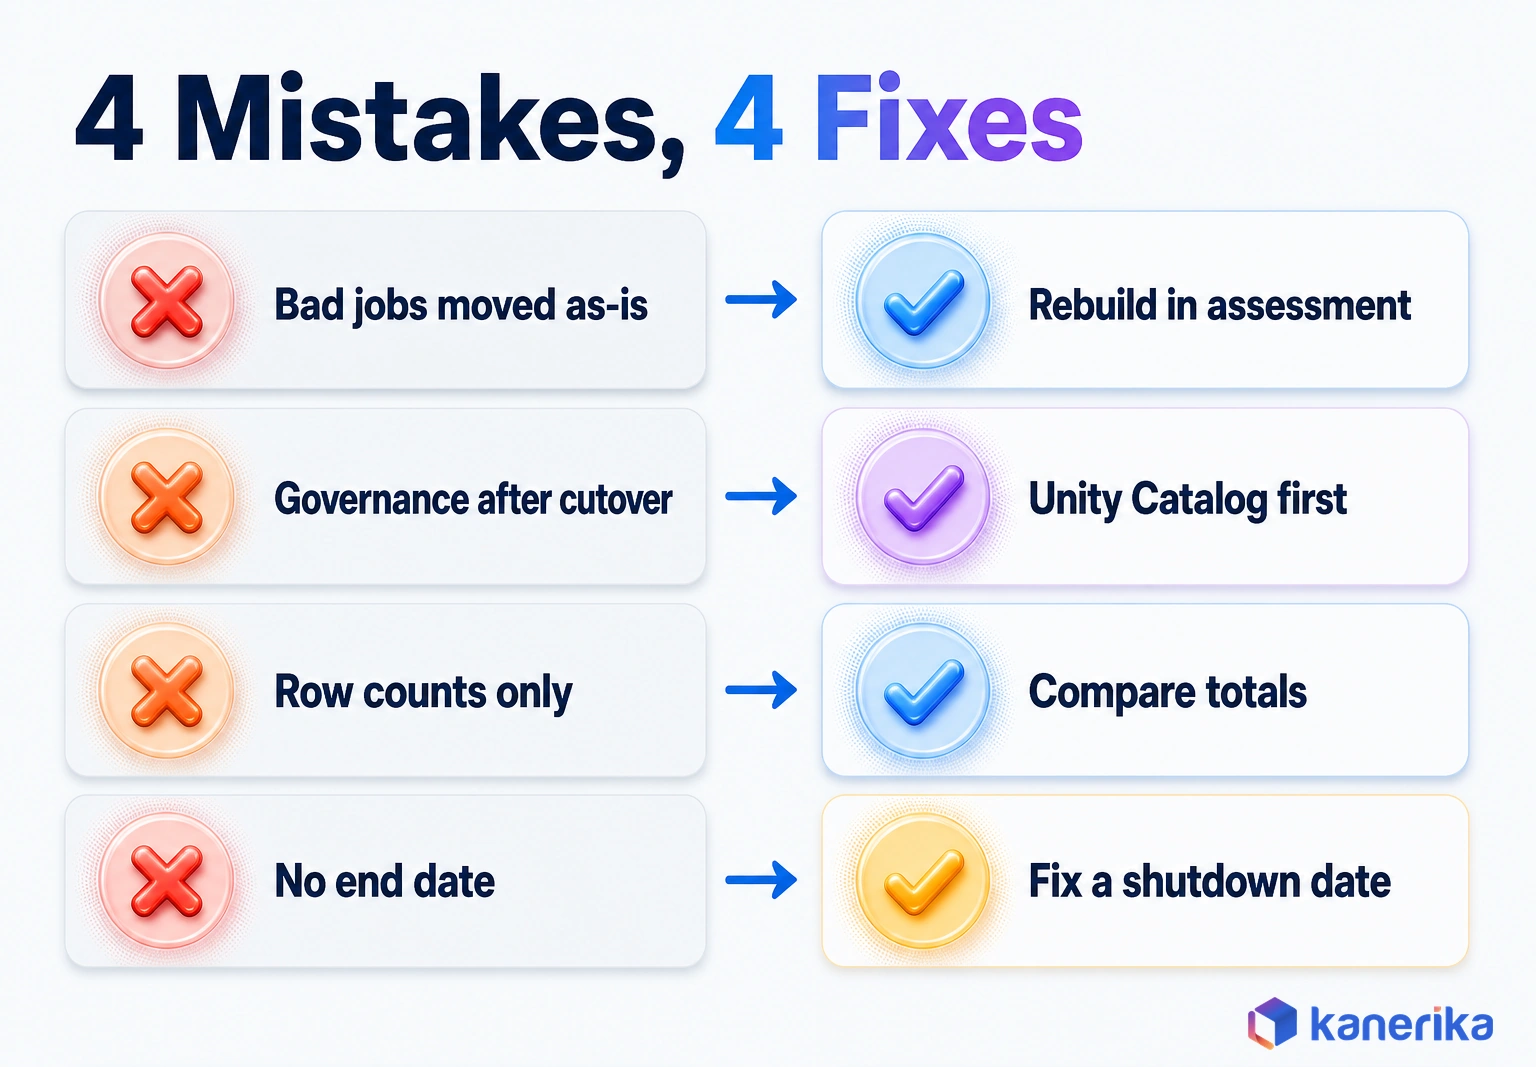
Four of these belong on the wall of any migration team room: rebuild bad jobs, set up governance before the first wave, check totals and not just counts, and fix a shutdown date. Each is cheap to prevent and expensive to fix late.
A broader list of what can go wrong, from data loss to scope creep, is in our guide to risks in data migration. Many of those risks shrink once the plan includes waves, real validation and a firm end date.
How Kanerika Runs a Legacy Systems to Databricks Migration
Kanerika runs legacy migrations as a sequence of short, testable stages rather than one long project. The approach follows the same order as this guide:
- Assess. Inventory, dependency mapping, usage profiling and wave planning.
- Design. Medallion layers, Unity Catalog groups and the landing zone.
- Convert. FLIP automates the conversion of Informatica pipelines, cutting manual effort by up to 83% while the live environment keeps running.
- Migrate in waves. Each wave runs in parallel with the legacy system until its exit criteria pass.
- Optimize and hand over. Apply Databricks cost optimization and performance tuning, then train the in-house team to run the platform.
FLIP is available on Azure Marketplace and is eligible for Microsoft Azure Consumption Commitment (MACC) spend. The Informatica to Databricks migration page has the details.
The same discipline applies to any legacy platform consolidation. A global spend-management and logistics-audit provider was running a legacy platform alongside a newer cloud-native one. Kanerika moved the remaining data and services onto the modern platform and sunset the legacy system. Infrastructure cost fell 32%, application performance improved 46%, and error resolution became 60% faster.
To scope a move of your own, explore our Databricks consulting services.
Talk to Kanerika
Plan Your Legacy to Databricks Migration
Bring your platform inventory. Kanerika will walk through wave order, conversion approach and the validation plan for your estate in one working session.
Schedule a Demo →
Bottom Line: Move the Meaning, Not Just the Data
A move to Databricks succeeds when the new platform gives the business the same answers it trusted, on a faster foundation. Copying tables is the easy part.
Three steps can start before any code moves. Pull usage logs to find the retire candidates, then score complexity against value to pick wave 1. Write the decommission date and the dual-run budget into the plan as well.
Follow that order, and a legacy systems to Databricks migration ends the way it should, with the month-end report matching on the first run.
Frequently Asked Questions
How do you migrate legacy systems to Databricks?
Start with an inventory of tables, code, jobs, reports and consumers, then score each workload on complexity and value. Design the target with medallion layers and Unity Catalog before the first wave. Convert SQL and ETL with automated tools plus engineer review, run each wave in parallel with the old system, and retire it once exit criteria pass.
Why should companies move from legacy systems to Databricks?
Legacy platforms tie storage to compute, lock teams into proprietary dialects and force data scientists to work from copies. Databricks scales storage and compute separately, bills by usage and lets engineering, BI and machine learning share one governed copy of the data. The trigger is usually a license renewal, missed batch windows or a stalled AI project.
What is Databricks Lakebridge?
Lakebridge is a free migration tool from Databricks, announced in June 2025 and built on BladeBridge technology. It includes a profiler, an analyzer, SQL converters and a reconcile component for comparing source and target data. Databricks says it can automate up to 80% of migration tasks. It covers sources such as Oracle, Teradata, SQL Server, Snowflake and Synapse.
How do you validate data after migrating to Databricks?
Move from cheap checks to expensive ones. Compare row counts per table, then aggregate and financial totals such as revenue by month, then the output of key reports on both platforms. Run both systems in parallel on live data, and agree exit criteria with data owners before cutover so the sign-off is objective.
How do you reduce downtime during a Databricks migration?
Move in waves and keep the legacy system running until each wave passes its checks. Use change data capture or incremental file loads to keep Databricks current during the parallel run, and Lakehouse Federation to query sources in place. Switch consumers over only when exit criteria pass, with a tested rollback path ready.
What challenges do companies face during this migration?
The biggest challenges are hidden business logic in stored procedures and ETL tools, undocumented dependencies, report consumers nobody listed and validation that stops at row counts. Skills gaps and the cost of running two platforms add pressure. Most of these shrink with a proper assessment, governance set up before cutover and a fixed decommission date.
How do you calculate the ROI of a Databricks migration?
Compare the full cost of the legacy platform, including licenses, hardware, support and staff time, with projected Databricks usage plus migration effort and the dual-run period. Then add measurable gains such as faster loads, retired tools and new analytics or AI work. Use your own baseline figures, because vendor averages rarely match a specific estate.
Which legacy databases and platforms can be migrated to Databricks?
Common sources include Oracle, Teradata, Netezza, SQL Server, Synapse and DB2 warehouses, Hadoop and Hive clusters, and ETL tools such as Informatica, SSIS, DataStage and Talend. Mainframe data usually moves through scheduled file extracts. Databricks Lakebridge documents its supported sources, and partner accelerators cover tools it does not list, such as Informatica.
How long does a legacy systems to Databricks migration take?
Timelines depend on object count, the share of stored procedures and scripts, the number of sources, data volume and the length of the parallel run. A single well-documented warehouse moves far faster than an estate with many sources and undocumented ETL. A complexity and value assessment gives a defensible schedule, organized as waves rather than one date.
How much does a Databricks migration cost?
Cost has two parts, the migration effort and the running platform. Effort grows with object count, procedural code, sources, compliance scope and the dual-run period. Databricks itself is pay-as-you-go with per-second billing, measured in Databricks Units, and committed-use contracts can lower the rate. Retiring unused tables before the move cuts both parts.
What is the difference between a data warehouse and a Databricks lakehouse?
A traditional data warehouse stores structured data in a proprietary engine built mainly for SQL reporting. A Databricks lakehouse keeps data in open Delta tables on cloud storage and serves SQL analytics, data engineering and machine learning from that one copy. It adds warehouse features such as ACID transactions, plus central governance through Unity Catalog.
How do you migrate ETL pipelines to Databricks?
Inventory every mapping, workflow and schedule, then decide which pipelines to convert, rebuild or retire. Sound pipelines can be converted with tools such as Lakebridge or a partner accelerator, while fragile ones are better rebuilt. Most teams shift to ELT, landing raw data first and transforming it with SQL or PySpark inside the lakehouse.
What happens to SSIS packages during a Databricks migration?
SSIS packages are translated into Databricks code, usually notebooks, SQL or declarative pipelines, and their schedules become Databricks jobs. Lakebridge lists SSIS among its supported sources, which helps with assessment and conversion. Script tasks, package variables and connection managers still need engineer review, and each converted package should be validated against the original output.
How do you migrate Oracle or Teradata to Databricks?
Export tables to cloud storage and load them as Delta tables, then convert PL/SQL or BTEQ code into Databricks SQL or Python. Lakebridge covers both sources with profiling, analysis, conversion and reconciliation. Lakehouse Federation can query the old system during the transition, so reports keep working while each wave is validated and cut over.
How do you migrate Hadoop to Databricks?
Rewrite Hive tables as Delta tables, which adds ACID transactions and time travel, and copy HDFS files to cloud storage. Pig scripts, Sqoop imports and Oozie workflows are re-expressed as Spark SQL, PySpark or Databricks jobs. Validate each job’s output against the cluster before switching it off, then decommission the hardware on a set date.














