TL;DR
Build your ETL framework on the data platform you already run. Then add one shared layer that every pipeline uses. That layer handles settings, logs, data checks and recovery in one place. Make every load safe to rerun, so a retry never doubles your data. Watch most for unsafe retries, renamed source columns and unchecked loads. Test on two workloads first, then measure onboarding speed, recovery time and data freshness.
Key Takeaways
- A framework gives every pipeline the same configuration, modules, run state, quality checks and monitoring, so no job reinvents them.
- Metadata-driven designs win when many sources look alike, while explicit code wins for complex business logic.
- Build in eight steps, and spend the most time on standards and restart logic because they are hardest to change later.
- Restarts stay safe only when loads are idempotent, watermarks are stored and retries back off.
- Extending your current platform usually beats building from scratch, and a bought tool also leaves the rules to you.
- Measure success once a month by onboarding time, recovery time, freshness and rows quarantined.
The 2 a.m. Retry That Doubled Revenue
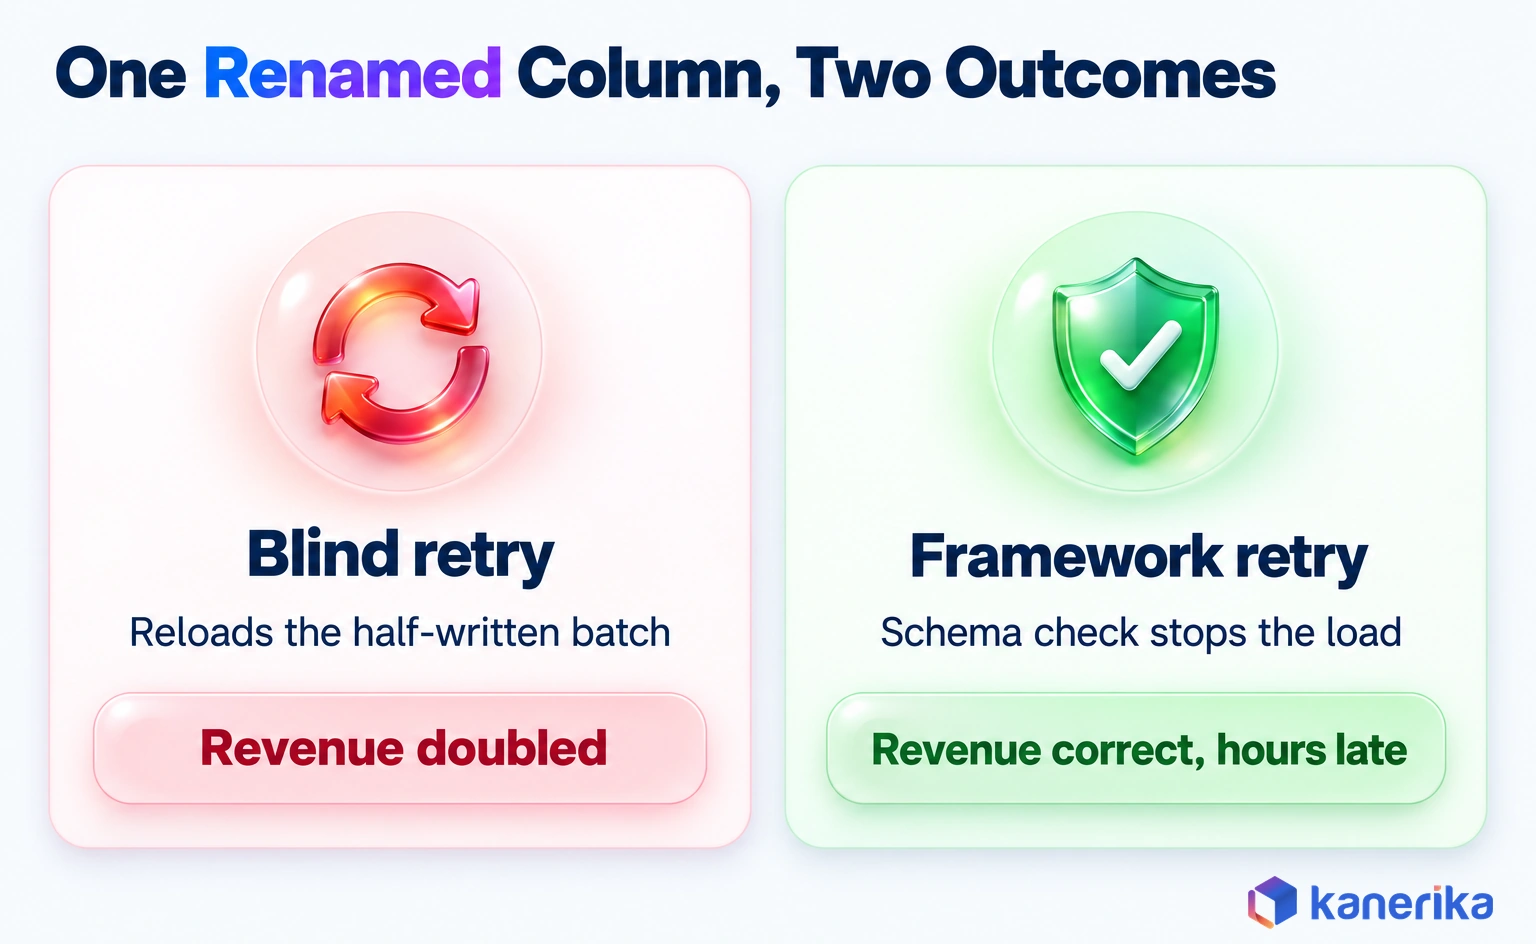
Picture a nightly sales load at a retail distributor. At 1:40 a.m., a source team renames a column from cust_id to customer_id, so the load fails halfway through. The scheduler then retries at 2 a.m., exactly as designed.
That retry starts from the top, even though half the batch was already written. The second run therefore writes those rows again. By 8 a.m., finance is looking at a dashboard that shows double the real revenue for one region.
No one in that story was careless. The real cause was that the distributor’s sixty nightly jobs each handled failure in their own way. An ETL framework answers one question: what should every pipeline share so this never happens again?
What Is an ETL Framework?
An ETL framework is the reusable layer of standards, configuration and shared code that every extract, transform and load job runs on. It also decides how sources are registered, how loads are checked and logged, and how a failed run recovers. Each pipeline then describes only what is unique to it.
For example, consider a team running 60 nightly jobs written by different people over five years. Each job has its own retry code, its own log format and its own idea of a successful run. When an auditor asks which jobs check row counts, nobody can answer without reading 60 scripts.
With a shared layer in place, retry logic, logging and row-count checks are written once. A new source then becomes a configuration entry plus whatever transformation it really needs. The sixty-first job also inherits everything else on day one.
ETL Framework vs ETL Pipeline vs ETL Tool
These three terms often get used as if they meant the same thing, so planning meetings get confusing. A pipeline is one flow of data from a source to a target (see how data pipelines work). A tool is the software that runs and schedules pipelines.
The framework sits above both. It holds the rules and shared modules that make every pipeline behave the same way, whichever tool runs it. It is also narrower than data integration as a whole, as our comparison of data integration vs ETL explains.
| Aspect | Pipeline | Tool | Framework |
|---|---|---|---|
| What it is | One flow that moves data from a source to a target | Software that runs and schedules flows | Shared standards, configuration and modules for all flows |
| Scope | One source and one target, such as a sales feed | Many pipelines, but only on one product | Every pipeline in the estate, whatever tool runs it |
| Owner | The engineer who built it | The vendor, plus a platform admin | A data platform or engineering lead |
| Lifespan | Until the source or report changes | Until the contract or platform changes | Longer than any single tool or pipeline |
| Example | Nightly load of point-of-sale data into the warehouse | Fabric Data Factory, Airflow or Informatica | Config store, run log, quality gates and restart logic |
Why You Still Need One When ELT and Managed Tools Exist
Modern platforms run jobs very well, especially at scale. Fabric Data Factory, Databricks and Snowflake, for example, all schedule, scale and retry work with little setup. Still, they leave the rules to you. How is a source named, where does run state live, which checks block a load, and who gets paged?
Those rules matter more as AI work grows, because models are only as good as the data they read. Gartner predicts that through 2026, organizations will abandon 60% of AI projects unsupported by AI-ready data. A shared control layer is where readiness becomes routine, since every load passes the same checks before anything downstream reads it.
It also gives your enterprise data integration architecture one place to enforce standards across teams.
Core Components of an ETL Framework
Every working framework has the same six parts, whatever platform it runs on. Think of them as services a pipeline calls so it does not have to write them itself. The sections below describe each part, and the table after them shows what breaks when one is missing.
Checklist
Data Engineering Checklist
Check your pipelines, standards, quality controls and monitoring against a step-by-step data engineering checklist before you design a shared ETL framework.
Get the Checklist →Metadata and Configuration Store
The configuration store is the framework’s memory. For each source, it records the connection reference, target table, column mappings, load type, schedule and owner. Pipelines read their instructions from it, so changing a schedule or adding a column becomes a data change instead of a code release.
A small table in your warehouse can do this job, and so can a set of YAML files in Git. The format matters less than having one place everyone trusts.
Reusable Extract and Load Modules
Extract modules handle the three ways data leaves a source, which is the ingestion half of the work (see data ingestion vs data integration). A full extract copies everything, so it suits small reference tables. An incremental extract uses a watermark, such as a last-modified timestamp, to pull only new or changed rows.
Change data capture (CDC) goes one step further. It reads the source’s change log, so it also catches deletes that a timestamp would miss.
Load modules then decide how data lands in the target. Four publish patterns cover nearly every case:
- Append for event and log data that never changes once it is written.
- Merge or upsert on a business key when records update in place.
- Drop and reload for small tables, since a full refresh is cheap.
- Blue/green swap, which loads a shadow table and switches readers once checks pass.
Set the pattern in configuration so every team loads data the same way.
Transformation Layer
Transformations hold the business rules: how revenue is calculated, how customers are matched and which orders count as returns. These rules can live in SQL, dbt models, Spark notebooks or a tool’s visual designer.
The framework’s job is to keep them versioned in Git and tested before release. It also keeps them apart from extract and load code, so a rule change never touches a connector.
Orchestration and Run State
Orchestration decides what runs, in what order and after which dependencies, and our roundup of data orchestration tools compares the main options. Run state records what actually happened. Each run gets an ID, start and end times, row counts, a status and the watermark it reached.
That record is also what makes recovery possible. When a job fails at step four of six, the framework restarts from the last checkpoint and uses the stored watermark. Otherwise, the only safe option is to start over and hope the target can absorb duplicates.
Data Quality Gates and Quarantine
Quality gates stop bad data before it reaches a report. A data contract, for instance, states what a source promises: columns, types, keys and allowed nulls. Row-count reconciliation then compares what left the source with what landed in the target.
Rows that fail a rule go to a reject or quarantine table with the reason attached, so the good rows still load. Your wider data quality framework sets the rules, while the ETL layer enforces them on every run.
Observability, Lineage and Security
Observability means you hear about a failure before your users do. Structured logs, alerts on failed or late runs, and freshness dashboards cover the basics. Data lineage also records which source fed which table, so an impact question becomes a quick lookup.
Security also belongs in the framework. Service accounts get least-privilege access, credentials come from a secrets vault, sensitive columns are masked, and every run leaves an audit trail.
| Component | What it is responsible for | What breaks without it |
|---|---|---|
| Configuration store | Sources, mappings, load type, schedule and owner | Every change needs a code release, so changes slow down |
| Extract and load modules | Full, incremental and CDC reads and the publish patterns | Each job reinvents loading, so bugs multiply |
| Transformation layer | Versioned, tested business rules | Reports disagree because their rules differ |
| Orchestration and run state | Order, dependencies, run IDs and watermarks | Failed runs restart from zero instead of a checkpoint |
| Quality gates and quarantine | Contracts, reconciliation and reject tables | Bad rows reach dashboards before anyone notices |
| Observability and security | Logs, alerts, lineage, vault and masking | Users find failures before the data team does |
Metadata-Driven vs Hard-Coded ETL Frameworks
The biggest design choice in an ETL framework is how much of each pipeline lives in configuration and how much lives in code. A metadata-driven design describes each source as data, then one generic pipeline reads that description at run time. A hard-coded design gives each source its own explicit job.
Metadata-driven designs win when you have many similar sources. For example, forty SaaS tables that all land as daily incremental loads become one pipeline and forty configuration rows.
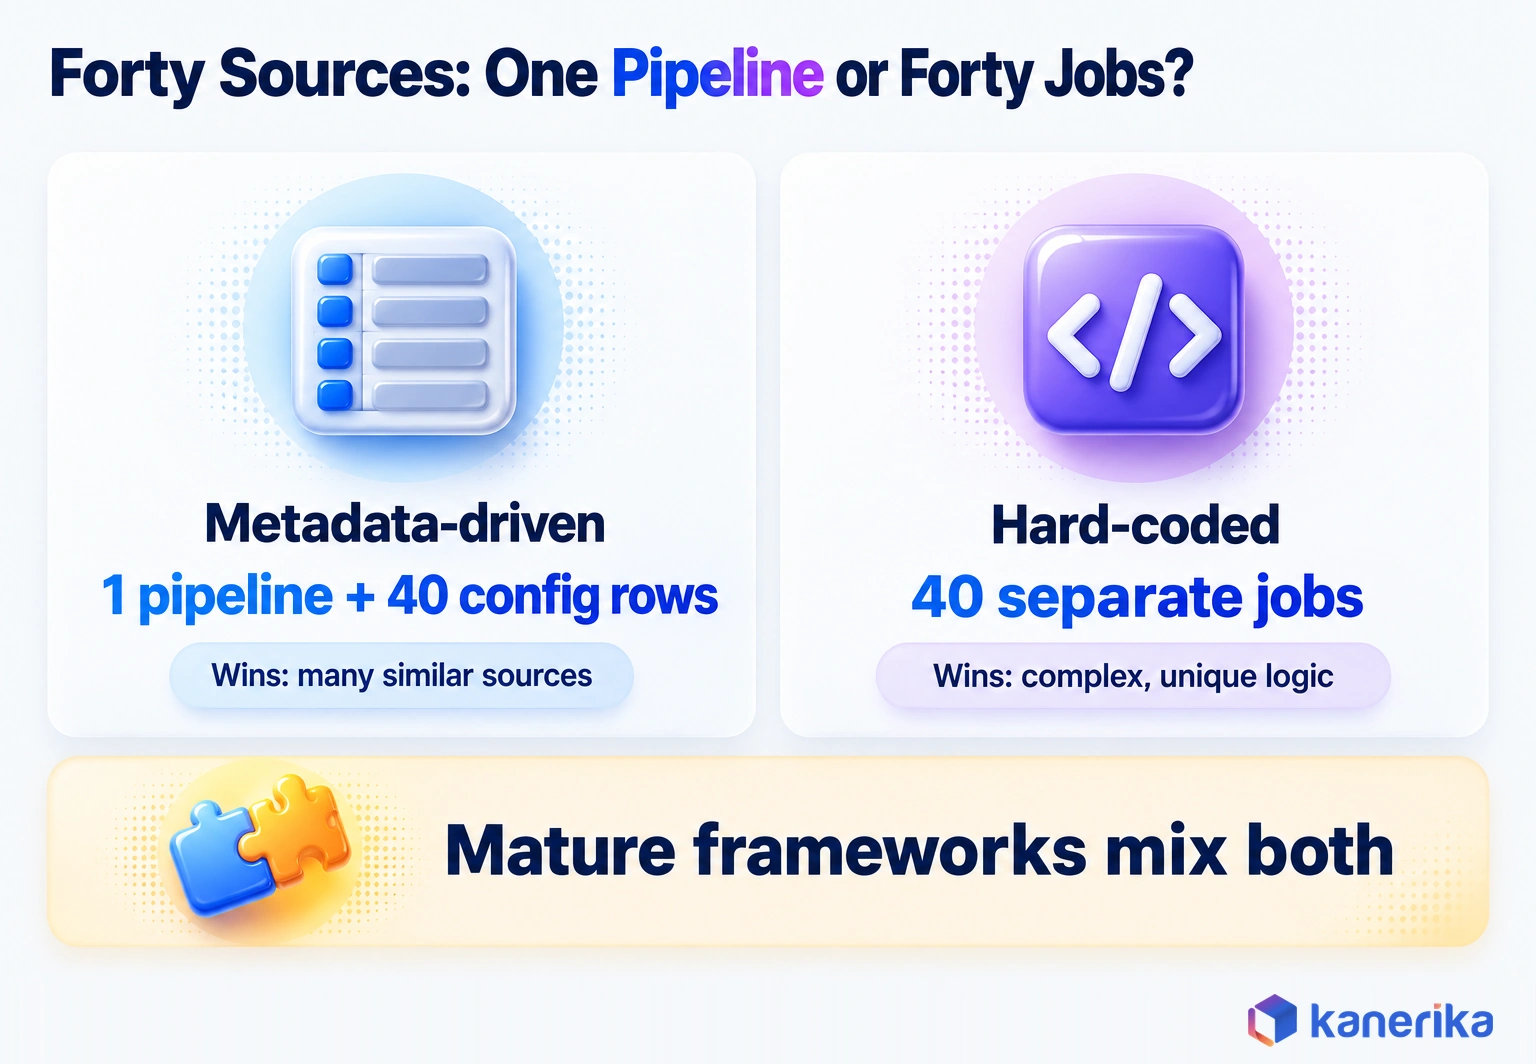
Hard-coded jobs win when logic is complex and unique. Think of a pricing calculation with a dozen exceptions: no configuration schema could express it cleanly. Mature frameworks mix both: configuration handles extract, load, scheduling and checks, while complex transformations stay as reviewed code.
| Factor | Metadata-driven | Hard-coded |
|---|---|---|
| Best fit | Many sources with a similar shape | Few sources, especially with complex, unique logic |
| Adding a source | Add a configuration row, then test it | Write and test a new job |
| Change control | Data change, still reviewed like code | Code release through CI/CD |
| Debugging | Harder, because one generic job has many inputs | Easier, because the logic is explicit |
| Main risk | One bad config row can break many loads at once | Copied logic drifts apart over time |
Here is what one configuration entry might look like for an incremental orders load. Each field maps to a component described earlier.
source: erp_sales
object: dbo.orders
target: bronze.orders
load_type: incremental
watermark_column: modified_at
publish_mode: merge
business_key: [order_id]
schedule: "0 2 * * *"
quality:
  reconcile_counts: true
  on_reject: quarantine.orders_rejects
owner: sales-data-team
Notice that nothing in the entry says how to retry or where to write logs. The framework supplies both, so every source gets them without extra code. The target name, bronze.orders, follows the raw layer of a medallion architecture.
Designing an ETL Framework for Scale and Modularity
Scale in a framework comes from small, swappable parts, not from one bigger job. Each module does one task, such as extracting, checking or loading, and reads its settings from configuration. A slow or broken module can then be fixed or replaced without touching the others.
The usual runtime pattern is a parent pipeline that reads the configuration table and loops over its rows. In Azure Data Factory, a ForEach activity runs these iterations in parallel, with a batchCount that defaults to 20 and caps at 50. Fabric pipelines expose the same Sequential and Batch count settings.
The same loop accepts at most 100,000 items, so very large estates split the work into a parent and a child pipeline. Keep the batch count within what each source can handle, too. Microsoft’s documentation warns that parallel iterations writing to the exact same file will most likely cause an error.
How to Build an ETL Framework in 8 Steps
Building an ETL framework is mostly a sequence of decisions, so each step should leave behind an artifact the team can review. The eight steps below run in order, although steps four to six often overlap.
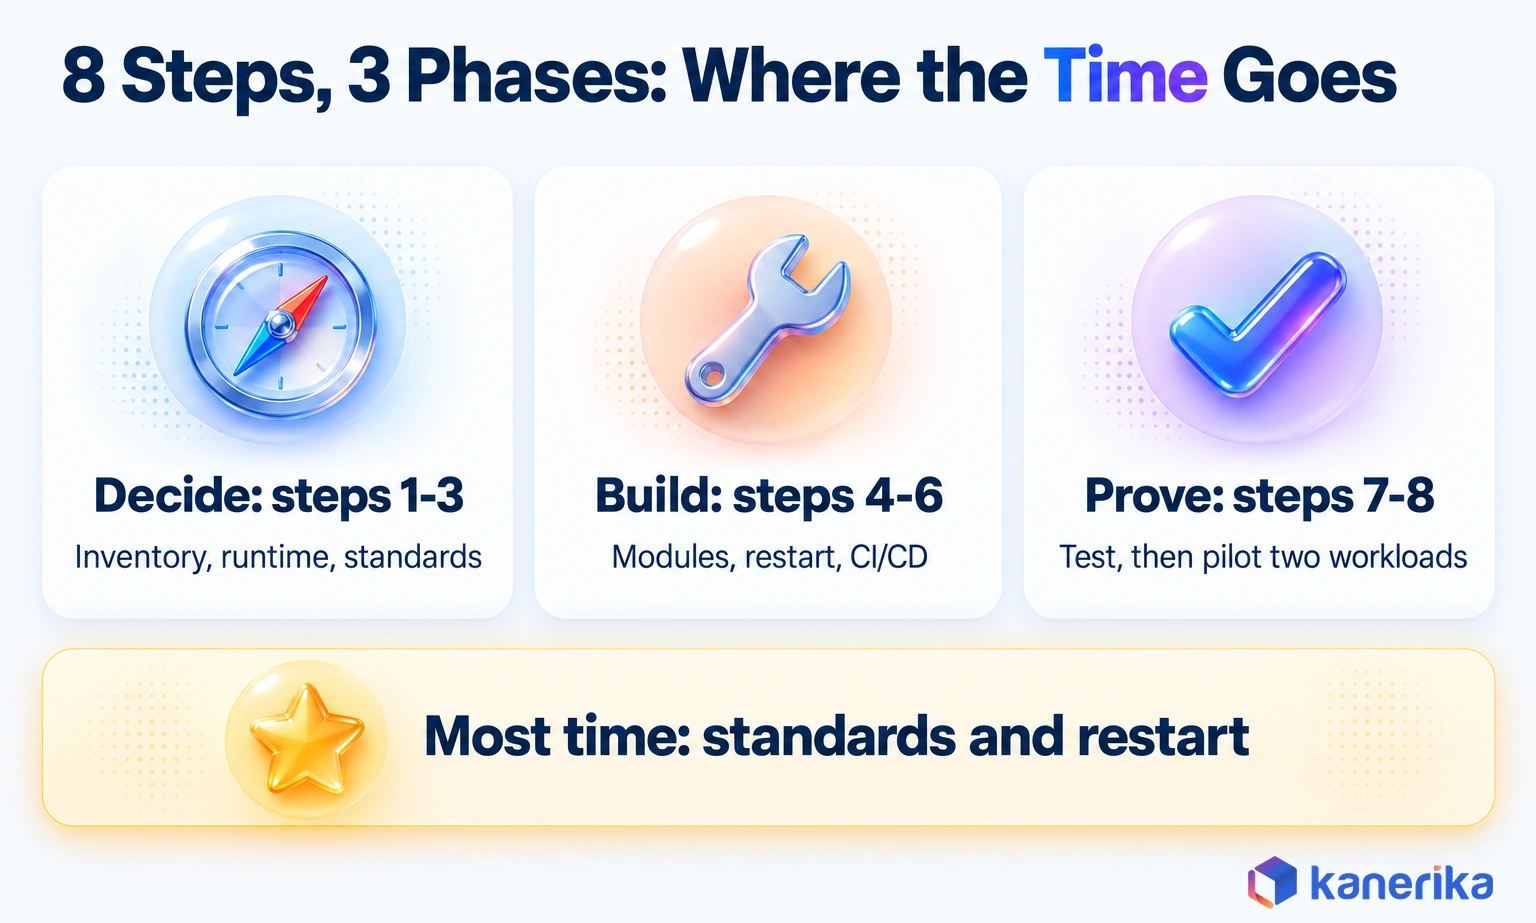
Budget the most time for steps three and five. Standards and recovery logic are the hardest parts to change once dozens of pipelines depend on them.
Step 1: Inventory Existing Jobs and SLAs
List every pipeline you run today, with its source, target, schedule, owner and failure history. Note the SLA each one serves, such as a finance close or a morning sales report. Then group the jobs by pattern: full loads, incremental loads, CDC feeds and file drops.
The artifact is an inventory sheet that shows which patterns cover the most jobs, so you know what to build first.
Step 2: Choose the Runtime and Extend Your Platform
Build on the platform your team already runs and knows, because skills and support carry over. For example, a Fabric shop extends Data Factory pipelines and notebooks. A Databricks shop builds on Lakeflow pipelines, while a Snowflake shop pairs dynamic tables with its existing orchestrator (see our Snowflake architecture guide). The artifact is a one-page decision record that names the runtime, the orchestrator and the reasons.
Step 3: Define Standards and the Metadata Model
Write down naming rules for layers, tables and columns, plus the fields every configuration entry must carry. Then agree on run-log columns and on what counts as a failed, partial or successful run.
This step feels slow, but every later module depends on it. The artifact is a standards document and an empty configuration schema.
Step 4: Build Reusable Extract, Transform and Load Modules
Write one module per pattern: a full extract, an incremental extract with a watermark, a CDC reader, and one loader per publish mode. Each module then takes its settings from the configuration store and writes to the run log. Keep transformations separate so they can be versioned on their own. The artifact is a small library that a new pipeline calls instead of copying code.
Step 5: Add Validation, Quarantine and Restart
Add schema checks before each load, reconciliation after it and a quarantine table for rejected rows. Make every load idempotent, which means running it twice gives the same result as running it once.
Store checkpoints so a failed run resumes from its last good watermark. The artifact is a tested restart path for each publish mode.
Step 6: Add Orchestration, Logging, Alerting and CI/CD
Wire the modules into your orchestrator with dependencies, timeouts and retry policies. Also send structured logs and alerts to the channel your on-call team already watches. Keep configuration and code in Git, then promote changes through development, test and production.
Timeouts matter more than they look. Without one, a hung extract can hold its slot for hours and block the 6 a.m. finance chain behind it. The artifact is a pipeline that deploys the framework itself, so no one edits production by hand.
Step 7: Test Units, Reconciliation, Performance and Recovery
Unit-test each module with small fixtures, then reconcile row counts and key totals on real data. After that, run one load at production volume to find the slow steps.
Then break things on purpose. Kill a job mid-load, rename a source column and expire a credential, then confirm the framework recovers each time. If you want to automate these checks, compare ETL testing tools before writing your own. The artifact is a test suite that runs whenever code changes.
Step 8: Pilot on Two Workloads, Then Onboard the Rest
Pick two pilots that differ: one simple, high-volume incremental load and one awkward source with late files or schema changes. Run them on the framework for a few weeks while the old jobs keep running, then compare the results.
Fix what the pilots expose, then move the remaining jobs in waves grouped by pattern. Wave planning works the same way for most types of data migration, so reuse that playbook if you have one. The artifact is an onboarding guide so short that a new engineer can add a source alone.
Error Handling and Restart: What to Watch For Most
Error handling is where a framework earns its keep, because failures are routine in data work. Sources change, files arrive late, credentials expire and targets go down for maintenance. The goal is a framework that fails safely: it stops, records what happened and resumes without damage.
Four habits make that possible. First, idempotent loads mean the 2 a.m. retry could have run twice and still written each row once. Second, replay from the stored watermark lets a restart resume where the last good run ended, not at row one.
Third, retries use exponential backoff, so a source that is briefly down gets breathing room instead of a flood of reconnects at 2 a.m. Fourth, bad rows are set aside instead of loaded, so a broken record never reaches the finance dashboard. Rows that fail validation go to quarantine, while records that cannot be processed go to a dead-letter table for a person to review.
Replaying the 2 a.m. Failure on a Framework
Now replay the 2 a.m. story once these habits are in place. The schema check catches the renamed column before a single row is written, so the load stops cleanly. The retry hits the same check and stops again instead of reloading.
An alert then reaches the data owner, who maps the new column name in configuration. The next run merges the batch on its business key, so finance sees the right revenue a few hours late.
| Failure | How the framework detects it | Automatic action | Human action |
|---|---|---|---|
| Schema drift | Contract check before load | Stop the load so the target stays untouched | Update the mapping or approve the new column |
| Late file | Freshness check against the SLA window | Wait, retry, then alert at the deadline | Chase the source team |
| Duplicate batch | Batch ID or file hash already in the run log | Skip the batch and log it | None, unless the source resent it on purpose |
| Partial load | Row counts differ between source and target | Roll back, then rerun from the checkpoint | Review the cause when it repeats |
| Credential expiry | Authentication error on connect | Retry with backoff, then alert | Rotate the secret in the vault |
| Target outage | Connection or timeout errors | Pause the queue until the target recovers | Confirm recovery, then check the backlog |
ETL vs ELT and Batch vs Streaming Inside a Framework
Where the transformation runs changes from pattern to pattern, while the control layer stays the same. In ETL, data is transformed before it lands in the warehouse (our data warehouse architecture guide shows where each layer sits). In ELT, raw data lands first and the warehouse or lakehouse engine transforms it.
Our guide to ETL vs ELT covers the differences in depth. Here the point is simpler, since both need configuration, run state, quality gates and restart logic.
Microsoft’s Fabric Data Factory shows the mix well, since it supports both ETL and ELT. Copy job handles bulk, incremental and CDC replication, and Dataflow Gen2 handles transformations, while pipelines run on schedule or event triggers.
Streaming shortens the timing and keeps the duties. A streaming job still needs a checkpoint, a schema contract and a place for bad events.
Zero-ETL and Mirroring Still Need Rules
Zero-ETL features and database mirroring deserve a separate word. They replicate source tables into the analytics platform with little or no pipeline code, so setup is quick. Fabric Mirroring, for example, keeps a near real-time replica in OneLake. That is replication, and the copy still needs quality rules, lineage and an owner before anyone builds reports on it.
| Pattern | Where the transform runs | What the framework still owns |
|---|---|---|
| Batch ETL | Integration engine, before load | Configuration, run state, quality gates and restart |
| Batch ELT | Warehouse or lakehouse, once data lands | The same duties and versioned models |
| Streaming | Stream processor, event by event | Checkpoints, schema contracts and dead-letter handling |
| CDC replication | Source change log, then applied to the target | Watermarks, delete handling and reconciliation |
| Zero-ETL or mirroring | Platform-managed replica | Quality rules, lineage and ownership, since the copy is raw |
Build, Extend or Buy: Choosing Your ETL Framework Approach
Every data team ends up with a framework of some kind, whether it designs one or not. The real choice, then, is how much of it you write yourself.
There are three practical choices: build, extend or buy. Extending means adding a thin layer to your current platform, and buying means a managed ingestion tool. To build, you either write the framework from scratch or adopt an open-source orchestrator and add conventions.
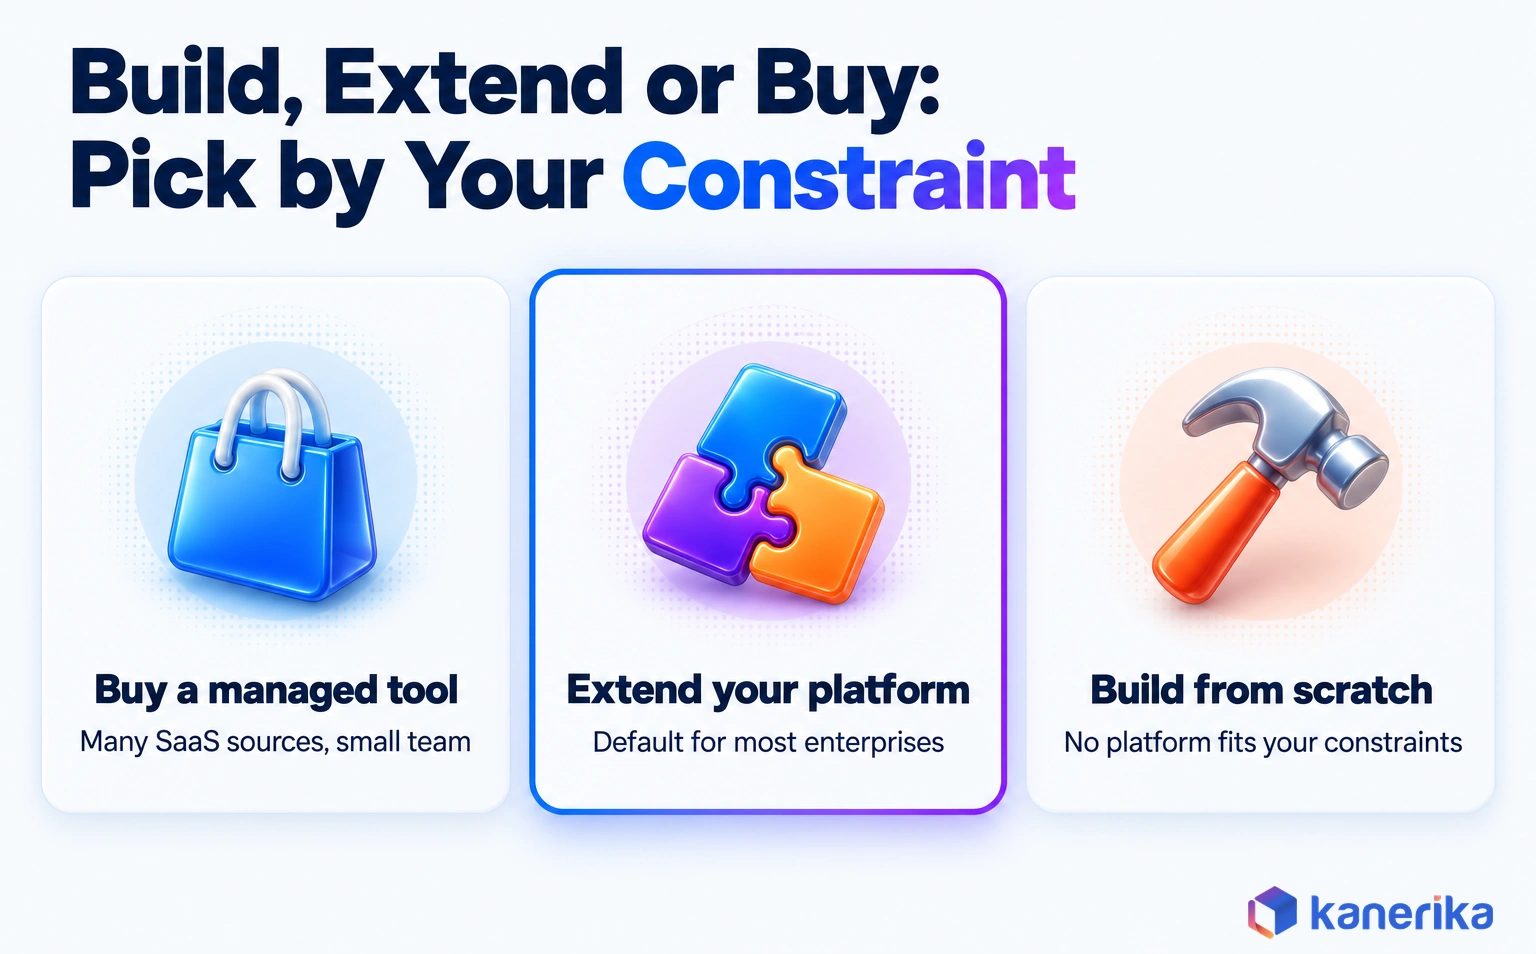
For most enterprises, extending the platform wins because you keep its scaling, security and support. You then add only the thin layer of standards that makes pipelines consistent.
Building from scratch makes sense when no platform fits your constraints. Buying makes sense when you have many standard SaaS sources and a small team.
| Factor | Build (from scratch or on open source) | Extend your platform | Buy a managed tool |
|---|---|---|---|
| Control | Full | High, but only within the platform | Low to medium |
| Skills needed | Strong software engineering, or Python and operations on open source | Platform and data engineering | Configuration and SQL |
| Governance | Whatever you build or add | Platform security, plus your rules | Vendor controls, plus your rules |
| Time to first pipeline | Slowest from scratch, medium on open source | Fast | Fastest, especially for supported sources |
| Lock-in | Low vendor lock-in, though reliance on a few engineers is high | Tied to the platform | Tied to the vendor’s connectors and pricing |
Platform-Native Options in 2026
As of October 2026, each major platform ships most of the parts a framework needs. Your job is to choose the parts and add the rules.
- Microsoft Fabric: Data Factory combines pipelines, Copy job with CDC, Dataflow Gen2 and Mirroring into OneLake. Our overview of Data Factory in Microsoft Fabric also walks through each piece.
- Databricks: Lakeflow pipelines are built on Apache Spark Declarative Pipelines, so they handle batch and streaming in SQL or Python.
- Snowflake: dynamic tables materialize a query and keep it current against a target lag, while Snowflake tracks the dependencies.
- Apache Airflow 3.x: an open-source orchestrator, especially for teams that want code-defined workflows across several platforms.
- dbt: versioned SQL transformations, part of one company with Fivetran since their merger closed on June 1, 2026.
- Informatica: a long-standing enterprise integration suite, owned by Salesforce since its acquisition closed on November 18, 2025.
Vendor consolidation is a good reason to keep your framework’s rules in your own repository. If a tool changes owner or pricing, your standards, configuration and tests move with you. Our comparison of data integration tools also covers the wider market.
Which Approach Fits Your Scenario
Your estate usually decides the answer before any feature comparison does. Match your situation to the closest row below, then treat the build plan as a starting point for your own pilot.
| Scenario | How to build it | What to watch for |
|---|---|---|
| Microsoft-centric estate | Extend Fabric Data Factory with metadata-driven pipelines and shared notebooks | Settings copied into each pipeline instead of read from one store |
| Lakehouse on Databricks | Extend Lakeflow pipelines with shared modules and a common run log | Quality rules hidden in notebooks that nobody reviews |
| Snowflake-first warehouse | Use dynamic tables for transforms, while an orchestrator runs extract and load | Target lags tighter than reports need, so compute cost rises |
| Many small SaaS sources, small team | Buy managed ingestion, then add naming, quality gates and ownership | Connector updates that change schemas before anyone notices |
| Strict on-premises or regulatory limits | Build in code or on open source, but only on approved infrastructure | Credentials in scripts and gaps in the audit trail |
What Drives Effort and Cost
Effort grows with five factors, and the tool’s license is only part of one. Source count and variety come first, because each new type of source needs a module and tests. Transformation complexity comes next, since unique business logic resists configuration.
Governance needs also add work for masking, lineage and audit, and an enterprise data governance program decides how much. Team skills decide whether you extend a platform quickly or spend months learning a new one.
Run cost matters over time, especially at high volume. A pipeline that reloads full tables every hour costs more than an incremental one, so the framework’s load patterns shape the bill. On Databricks, our guide to Databricks performance optimization covers the tuning side.
Common ETL Framework Mistakes to Watch For
Each of the mistakes below shows up often in pipeline reviews, but each one also has a straightforward fix. Read them as a checklist before you finalize your own design.
- Retries that are not idempotent. A retry that appends the same batch twice is how revenue doubles overnight. Fix it with merge-on-key loads, or with batch IDs checked against the run log.
- Hard-coded credentials and paths. Secrets in scripts leak, and paths break when environments change. Read both from a vault and from configuration instead.
- No schema-drift handling. A renamed column should stop a load with a clear alert. Add a contract check before every load.
- No reconciliation. A job can report success and still lose rows. Compare counts and key totals between source and target on every run.
- Monitoring added last. Teams that bolt on alerts after go-live learn about failures from their users. Build logging and alerts into the first module instead.
- One giant job. A single job that extracts, transforms and loads everything cannot restart halfway. Split the work into steps so each has a checkpoint.
- A framework nobody owns. Without an owner, standards drift and exceptions pile up. Name a platform owner, then review changes like product code.
Once the framework is stable, tuning comes next. Our guide to ETL process optimization techniques covers that work in detail.
Kanerika Service
Assess Your ETL Framework
Kanerika’s data integration team reviews your pipelines, standards, quality gates and restart logic, then plans a framework on the platform you already run.
Explore Data Integration ServicesHow to Measure Your ETL Framework: Six Run-Log KPIs
A framework is working when adding a source gets faster and failures get boring. Six numbers show whether that is happening, since each one comes straight from the run log.
Track them every month, then compare them with the baseline from step one. Feed the same run data into your data observability tooling, so alerts and trends live in one place.
Here is a concrete reading. Say the step-one baseline shows three weeks to onboard a new source and two hours to recover a failed run. If the pilots cut onboarding to four days while recovery stays at two hours, reuse is working but restart logic still needs attention.
| KPI | What it tells you | Direction to aim for |
|---|---|---|
| Time to onboard a new source | Whether reuse is real | Falling over time |
| Share of pipelines on the framework | Adoption across teams | Rising until every pipeline is on it |
| Failed-run recovery time | Whether restart logic works | Falling |
| Freshness SLA hit rate | Whether data arrives before reports need it | Rising |
| Rows quarantined | Source quality and contract health | Stable or falling, so long as someone reviews them |
| Cost per run | Efficiency of load patterns | Flat or falling while volume grows |
How Kanerika Builds and Modernizes ETL Frameworks
Kanerika’s data engineering services team builds ETL frameworks in four stages, often while modernizing an older integration estate. To begin with, we inventory existing jobs and score them by pattern, complexity and business risk. We then define the metadata model and the standards every pipeline will follow.
Then we convert or rebuild jobs with reusable modules, using FLIP, Kanerika’s intelligent workflow automation platform with DataOps and data platform migration use cases. Its migration accelerators cover SSIS, Informatica and DataStage sources, and we validate with reconciliation before any cutover.
On SSIS estates, FLIP first scans packages, schemas and dependencies, then flags complex packages for an engineer to review. Parity tests then compare outputs with the old system while production keeps running. FLIP accelerators are also listed on the Azure Marketplace.
For example, one large enterprise relied on complex SSIS pipelines. Kanerika built an automated framework to extract, analyze and migrate those pipelines into Microsoft Fabric, with PySpark notebooks and Power Query for transformations. The team also added role-based access, encryption and monitoring.
The results were 30% faster data processing, 40% lower infrastructure and maintenance costs, 25% less manual maintenance and 99.9% data integrity during migration.
If you are planning a similar move, our ETL migration guide covers sequencing. Our SSIS to Microsoft Fabric migration service then handles the conversion. Our data integration services team can also assess your current framework against the components above.
Case Study
40% Lower Costs: SSIS to Microsoft Fabric Migration
Kanerika built an automated framework to extract, analyze and migrate complex SSIS pipelines into Microsoft Fabric, with 30% faster processing and 99.9% data integrity.
Read the Case Study →So, What Is the Best Way to Build an ETL Framework?
Build it on the platform you already run, then spend your effort on the shared layer every pipeline inherits. Standardize configuration, quality gates and restart logic before you add more pipelines, because each new job copies whatever habits exist.
Pilot on two workloads that differ, fix what they expose, then onboard the rest in waves. After that, measure onboarding time, recovery time and freshness every month.
Extend your platform with one shared control layer, and watch for unsafe retries, schema drift and missing reconciliation.
Frequently Asked Questions
What is an ETL framework?
An ETL framework is the shared layer of standards, configuration and reusable code that every extract, transform and load job runs on. It defines how sources are registered, how loads are logged and checked, and how failed runs recover. Individual pipelines then describe only what is unique to them, so new sources are faster to add and support.
Why do businesses need an ETL framework?
Without one, every pipeline handles retries, logging and quality checks in its own way. That creates hidden duplicates, silent data loss and long investigations when something breaks. A framework writes those rules once, so every job behaves the same. Teams onboard sources faster, recover from failures sooner, and can show auditors which checks ran on which data.
How does an ETL framework support scalability?
It scales by reuse. New sources become configuration entries that call tested modules, so the team does not write a new job each time. Incremental and CDC loads move only changed data, which keeps run times and costs in check as volumes grow. The platform supplies the compute, while the framework keeps behavior consistent across every pipeline.
Should you build a custom ETL framework or use off-the-shelf tools?
For most enterprises, extending the platform you already run works best. You keep its scaling and security and add your own standards on top. Build from scratch only when no platform fits your constraints. Buy managed ingestion when you have many standard SaaS sources and a small team. Kanerika helps teams assess which path fits their estate.
Can you build an ETL framework using Python?
Yes. Python is a common choice for custom frameworks, often paired with an orchestrator such as Apache Airflow and libraries for database access and validation. It suits teams with strong engineering skills and unusual sources. It also means you own testing, security, logging and upgrades yourself, so extending a platform is often faster for standard workloads.
What is the difference between ETL and ELT frameworks?
In ETL, data is transformed before it lands in the warehouse. In ELT, raw data lands first and the warehouse or lakehouse engine transforms it. The framework’s duties stay the same in both cases. It still needs configuration, run state, quality gates and restart logic. Only the place where the transformation runs is different between the two.
Is ETL outdated, and what will replace it?
ETL is still widely used, though its form keeps changing. By 2026, ELT, streaming, change data capture and zero-ETL replication handle many loads that once ran as nightly batch jobs. Each of these still moves and reshapes data, so each still needs quality rules, lineage, ownership and recovery. Those shared rules are exactly what an ETL framework provides.
Will ETL be replaced by AI?
AI is unlikely to replace ETL, but it is changing how pipelines get built. AI assistants can draft mappings, generate transformation code and flag anomalies in loads. Someone still has to define the rules, review the logic and own the results. A framework gives AI-generated pipelines the same checks, logging and restart logic as hand-written ones.
Which is the best ETL tool?
No single tool is best for every team. The right choice depends on the platform you already run, your sources, your team’s skills and your governance needs. Fabric Data Factory suits Microsoft estates, Lakeflow suits Databricks lakehouses, and dynamic tables suit Snowflake-first teams. Managed ingestion tools suit many SaaS sources with a small team.
Can I use SQL for ETL?
Yes. SQL is the most common language for the transform step, and ELT designs often run almost entirely in SQL inside the warehouse. Tools such as dbt organize SQL transformations into versioned, tested models. ETL itself is a process and SQL is a language, so most frameworks combine SQL with an orchestrator and extract modules.
Is ETL a coding language?
No. ETL is a process for extracting, transforming and loading data, and you can implement it in several languages. Teams use SQL, Python, Spark or low-code visual designers in tools such as Fabric Data Factory. ETL is also a backend activity, since it runs on servers and data platforms instead of in the interface people see.
Is ETL the same as an API?
No. An API is an interface that lets one system request data or actions from another. ETL is a process that moves data from sources into a target, often in batches. An API is frequently one of the sources an ETL pipeline extracts from. The framework then handles paging, rate limits, retries and loading for that source.
What is the difference between an ETL framework and an ETL pipeline?
An ETL pipeline is one flow of data from a source to a target, such as a nightly sales load. An ETL framework is the shared layer that all pipelines run on. It supplies configuration, run state, quality gates, logging and restart logic. Pipelines come and go with business needs, while the framework outlives every one of them.
What are the core components of an ETL framework?
A complete ETL framework has six parts. A configuration store holds sources, mappings and schedules. Reusable modules handle extract and load patterns. A transformation layer keeps business rules versioned. Orchestration tracks run state and watermarks. Quality gates quarantine bad rows. Observability and security add logs, alerts, lineage, a secrets vault and an audit trail.
What are the 5 steps of the ETL process?
A common five-step view is extract, clean, transform, load and analyze. Data is pulled from source systems, then checked for errors and duplicates. Business rules reshape it to fit the target model. The result is loaded into a warehouse or lakehouse. Reports and models then read it, and a framework adds checks at each step along the way.
What is a metadata-driven ETL framework?
A metadata-driven ETL framework stores each source’s details as configuration instead of code. One generic pipeline reads that configuration at run time to know what to extract, how to load it and which checks to run. Adding a source becomes a new configuration row. The approach suits many similar sources, while complex logic still lives in reviewed code.
How does an ETL framework improve data quality?
It runs the same checks on every load. Data contracts confirm columns, types and keys before data is written. Reconciliation compares row counts and totals between source and target. Rows that fail a rule move to a quarantine table with the reason attached. Because every pipeline inherits these gates, bad data is caught before it ever reaches reports.
How do you handle errors and restarts in an ETL framework?
Make every load idempotent, so running it twice gives the same result as running it once. Store watermarks and checkpoints in a run log, so a failed job resumes from its last good point. Retry with exponential backoff, send rejected rows to quarantine, and alert a named owner when automatic recovery cannot fix the problem on its own.
How do you test an ETL framework?
Test it at four levels. Unit tests check each module with small fixtures. Reconciliation tests compare counts and key totals on real data. Performance tests run a load at production volume. Failure tests break things on purpose, such as killing a job mid-load or renaming a column, to prove the restart logic works every single time.
Can ETL frameworks handle real-time data?
Yes, as long as the framework covers streaming and change data capture as well as batch. Streaming jobs still need checkpoints, schema contracts and a dead-letter path for bad events. CDC reads source change logs to keep targets close to current. The control layer stays the same, while the timing of each load gets much shorter.