TL;DR
Plan a Databricks deployment foundation first, and on a new project let no workload go live until it is built. That foundation means identity, network, Unity Catalog and compute policies with tags and budgets. Teams with a working pilot rebuild it on the foundation instead of promoting it. Projects driven by legacy jobs move their workloads onto it in waves. Use one Unity Catalog metastore per region and give access to groups only. Automate the build in code and go live only after a written checklist passes.
Key Takeaways
- A Databricks deployment is the platform under your workloads, so it covers the account, identity, network, Unity Catalog, compute rules, automation and monitoring.
- Make four decisions before you build: workloads and metrics, the cloud, the workspace topology and serverless versus classic compute.
- Unity Catalog allows one metastore per region, so plan catalogs by environment or domain and grant access to groups.
- Implement in eight steps, with guardrails set alongside the workspaces and the first workloads only after identity, network and governance.
- Cost control starts on day one, well before the first bill, with compute policies, auto-termination, tags, budgets and the system.billing.usage table.
- Pick greenfield, pilot-first or migration-led by your starting point, then pass a written go-live checklist before production.
From a Working Pilot to a Production Platform
Picture a data team six weeks into a Databricks pilot. The demand forecast notebook runs every morning, the dashboard refreshes, and the sponsor now wants it live before quarter end.
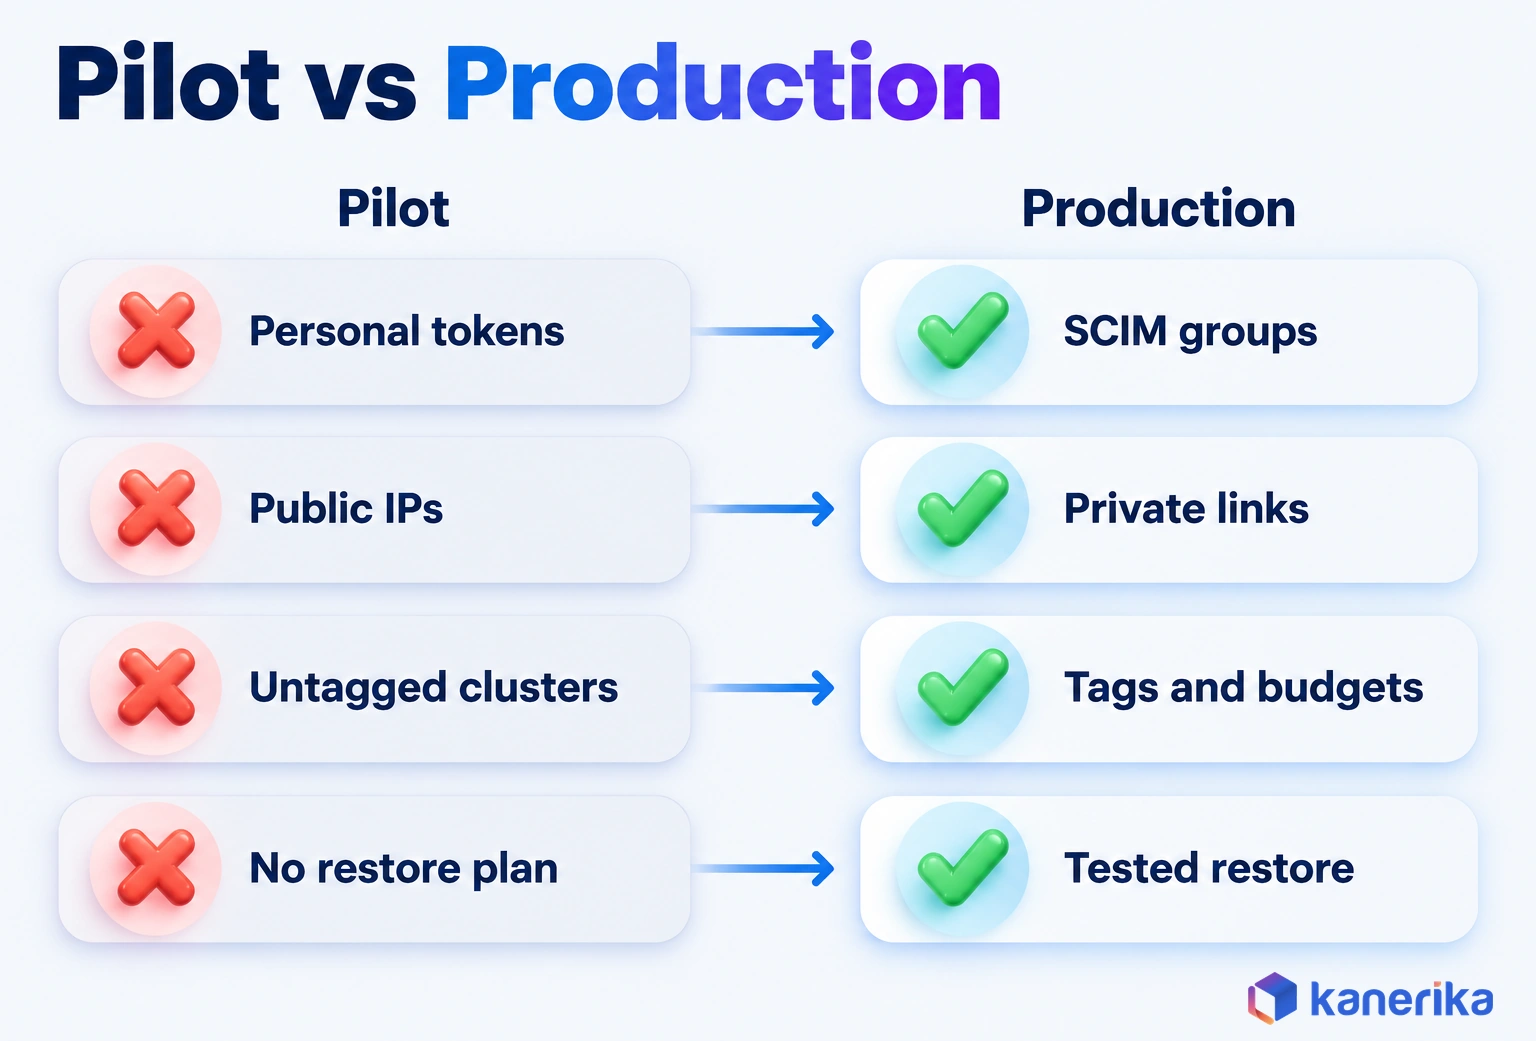
Then the review meeting starts. Security asks who can read the customer tables, but the honest answer is three engineers with personal access tokens. Networking also asks why the clusters reach storage over public IP addresses.
Finance asks last. Which cost center pays for an all-purpose cluster that has run nonstop since the pilot began?
None of those questions is about the notebook. Instead, they are about the platform underneath it, which the pilot never built.
This guide covers that platform layer. You will see what a Databricks deployment includes, which decisions come before the build and the order to implement them in. Finally, it covers the cost controls, automation and go-live checks that turn a working notebook into a service the business can rely on. Our Databricks best practices guide covers the governance, compute and CI/CD habits that keep the platform stable.
What a Databricks Deployment Actually Includes
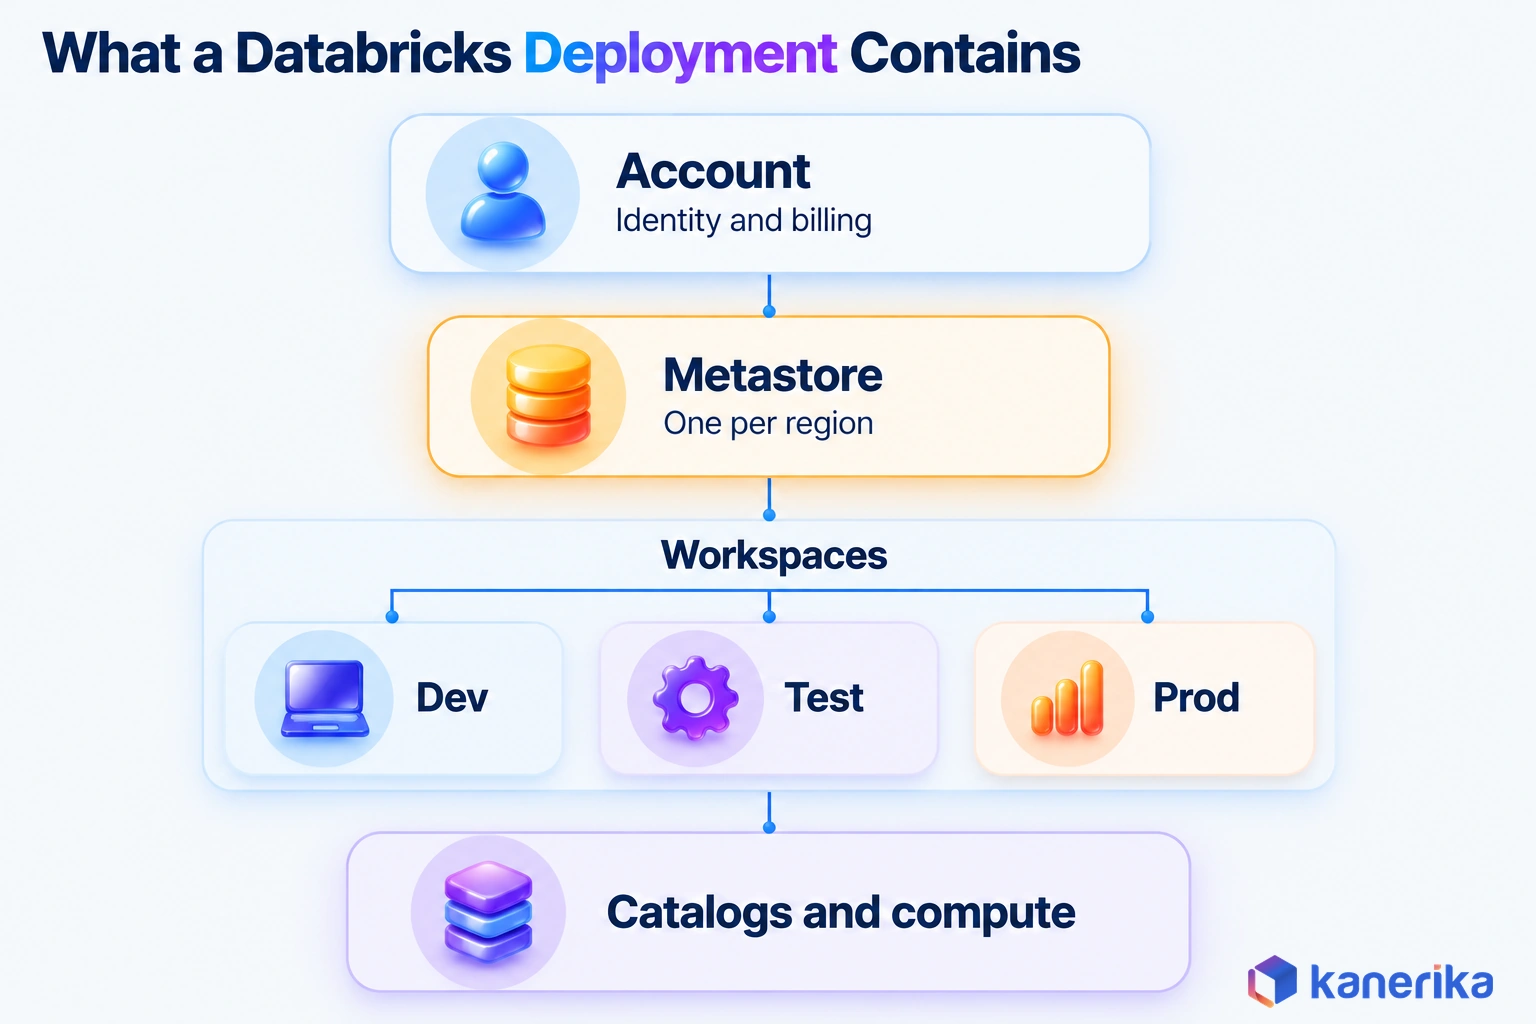
A Databricks deployment is the platform your workloads run on rather than the workloads themselves. In practice, it covers the account, the workspaces, the network path to your data, the governance layer and the rules for compute.
Databricks splits that platform into two planes. The control plane runs in Databricks’ own cloud account and hosts services such as the web application, the job scheduler and the APIs. Your data is processed in the compute plane.
That compute plane comes in two forms. On the classic compute plane, clusters run inside your own cloud account and network, so you own the networking. On the serverless compute plane, Databricks runs the machines for you and manages capacity.
The second split is between the account and its workspaces. The account sits on top, so it holds users, groups, billing and the Unity Catalog metastores. Workspaces, meanwhile, are where people build notebooks, jobs, pipelines and dashboards, and one account can hold many of them.
Databricks reports more than 20,000 customer organizations, including 70% of the Fortune 500, on its company page. Adoption at that scale means the components are mature and well documented. What separates a deployment that holds from one that stalls is the order of decisions.
Still weighing the lakehouse model itself? Start with our comparison of a data lake vs a lakehouse, then come back once that question is settled.
What Changed for Deployments in 2026
Three platform changes affect any plan drawn up as of October 2026, especially on Azure.
Microsoft retired the Azure Databricks Standard tier on October 1, 2026, according to the Azure Databricks pricing page. Even before that, no new Standard workspaces could be created after April 1, 2026. Every new Azure workspace is Premium, so budget for Premium rates from the start.
The second change is serverless workspaces. They come preconfigured with serverless compute and default storage, and Databricks documents them as a production option for organizations that run serverless only. However, your region must support serverless first, as the serverless workspace documentation notes.
The third is a rename. As of October 2026, the docs call Databricks Asset Bundles Declarative Automation Bundles, so older runbooks may still use the former name.
Databricks Deployment Decisions to Make Before You Build
Four decisions shape everything after them, and each one gets expensive to reverse once data and users arrive. Make them on paper before anything is built, with the platform owners in the room. Take them in this order: workloads first, then the cloud, the workspace topology and the compute plane.
Workloads and Success Metrics
Start with what the platform must run, because the workload mix drives compute choices, network design and cost. Then name the workload types and the first two or three use cases in each.
- BI and SQL analytics: dashboards and ad hoc queries, such as weekly sales reviews, on SQL warehouses.
- Batch pipelines: ingestion and transformation jobs, such as nightly ERP loads, that build bronze, silver and gold tables.
- Streaming: near-real-time feeds such as orders, sensor events or clickstream.
- ML and AI: feature engineering, model training, model serving and AI agents.
Then set targets you can measure at go-live. A goal like “faster insights” can never pass or fail a review, so write targets in this shape instead:
- The daily sales gold table lands before 6 a.m. Eastern on 99% of business days.
- The 20 most-used dashboard queries return in under 10 seconds when the month-end rush hits.
- Every job and SQL warehouse carries a cost-center tag, so no untagged spend remains after week two.
- No user holds a direct grant on production data, because all access flows through groups.
Choosing the Cloud: AWS, Azure or Google Cloud
Databricks runs on all three major clouds, and the platform also behaves much the same on each. The practical question is where your identity provider, network and data already live, because moving those is the expensive part.
The table sets out what differs by cloud, but it deliberately makes no “best cloud” call. If you are weighing Databricks against native AWS services rather than choosing a host cloud, see our Databricks vs AWS comparison.
| Cloud | Identity | Private networking | Fits estates that | Tier notes |
|---|---|---|---|---|
| AWS | SSO and SCIM from your identity provider, and IAM roles for storage | Customer-managed VPC, then back-end PrivateLink for classic compute | Already run on S3 and AWS networking | Back-end PrivateLink needs the Enterprise tier |
| Azure | Microsoft Entra ID and SCIM provisioning | Your own VNet; secure cluster connectivity (no public IP) is on by default | Run on Microsoft 365, Entra ID and ADLS | Premium only since the Standard tier retired on October 1, 2026 |
| Google Cloud | SSO and SCIM, as on the other clouds | Customer-managed VPC | Already run on Google Cloud Storage and BigQuery | Check tiers on the Databricks pricing page before sizing |
Azure teams that also run Microsoft Fabric have one more option. Unity Catalog catalog federation can query Fabric Lakehouse and Warehouse data read-only, as described in Microsoft’s OneLake federation guide. Before splitting workloads across the two, read our Microsoft Fabric vs Databricks breakdown.
Workspace Topology: One, Per Environment or Per Business Unit
Workspace topology decides how many workspaces you run and what separates them. All workspaces in a region share one Unity Catalog metastore, so topology isolates compute and admin rights, not governance.
A workspace boundary separates clusters, SQL warehouses, workspace admins and workspace-level settings such as compute policies. It does not decide who can read a table, because grants on catalogs and tables live in the shared metastore. That difference is where most topology mistakes start.
For example, take a retail analytics team that starts on one shared workspace. Six months later, finance wants its own budget and access boundary. Splitting a live workspace means moving jobs, permissions and users while reports keep running, whereas deciding up front costs an afternoon.
| Pattern | When it fits | Watch out for |
|---|---|---|
| One workspace, catalogs per environment | When one small team works in one domain | Dev and prod share admins and compute limits |
| One workspace per environment (dev, test, prod) | Most enterprises with a central data team, since code moves through CI/CD | Three of everything, so manage them as code |
| Per business unit and environment | When units need separate budgets or regulated data must stay apart | Workspace sprawl unless standards stay central |
For most central data teams, one workspace per environment is the right default. It keeps dev changes away from production compute and admins, and three workspaces stay manageable when Terraform builds them.
Add a business-unit split only when a unit needs its own budget, its own admins or a hard boundary for regulated data. Finance, HR and regulated lines of business are the usual cases. Below that bar, catalogs per domain give the separation without the sprawl.
Serverless or Classic Compute Plane
The compute plane choice decides who runs the machines and how much networking you build. Serverless hands capacity to Databricks, while classic keeps clusters inside your cloud account.
| Aspect | Serverless | Classic |
|---|---|---|
| Who runs compute | Databricks, in its own cloud account | You, in your cloud account |
| Networking work | Less work, since serverless-only workspaces on AWS need no customer-managed VPC | Customer-managed VPC or VNet, private connectivity and firewall rules |
| Storage | Default storage included with serverless workspaces | You connect your own cloud storage |
| Cost levers | Pay per use, so little capacity sits idle | Instance types, auto-termination and spot instances |
| Best fit | Teams that run serverless only, when their region supports it | Custom networking, specific instance types and spot capacity for fault-tolerant jobs |
You can also mix the two inside one deployment. A common split puts BI on serverless SQL warehouses and heavy pipelines on classic job compute. Then write that choice into the compute policies covered later.
Kanerika Service
Databricks Consulting, Implementation and Migration
Kanerika’s certified Databricks experts design the landing zone, workspace topology and Unity Catalog layout, then bring your first workloads into production.
Explore Databricks ServicesLanding Zone: Network and Identity Foundations
A landing zone is the network and identity groundwork a workspace sits on. Build it before the first workspace, because changing the network design after users and jobs arrive means rework and downtime.
The order matters more than the tooling. So set the landing zone up in this sequence:
- Network: a customer-managed VPC or VNet with subnets per workspace as well as room for cluster growth.
- Private connectivity: private links so that traffic between your network and the control plane stays off the public internet. On AWS, back-end PrivateLink needs the Enterprise tier and a customer-managed VPC for classic compute, per the PrivateLink documentation.
- No public IPs: on Azure, secure cluster connectivity defaults to on in the portal, while serverless compute has no public IPs. Microsoft also plans to require it in a future release, according to its secure cluster connectivity guide.
- Single sign-on: connect your identity provider at the account level rather than workspace by workspace.
- SCIM and account-level groups: sync groups such as data-engineers-prod from the directory, so access follows HR changes.
- Service principals for automation: CI/CD pipelines and scheduled jobs run as service principals, so no job breaks when a person leaves.
Serverless-only workspaces skip much of the first two steps, since they do not need a customer-managed VPC. The identity work, however, stays the same either way.
For control-by-control depth on encryption, audit logs and access, see our guide to Databricks security controls, especially before a compliance review.
Unity Catalog Setup Order
Unity Catalog is the governance layer that decides who can read, write and share every table, volume, model and function. It is enabled automatically for workspaces created after November 8, 2023, per the Unity Catalog setup guide, but the catalog layout still needs a deliberate design.
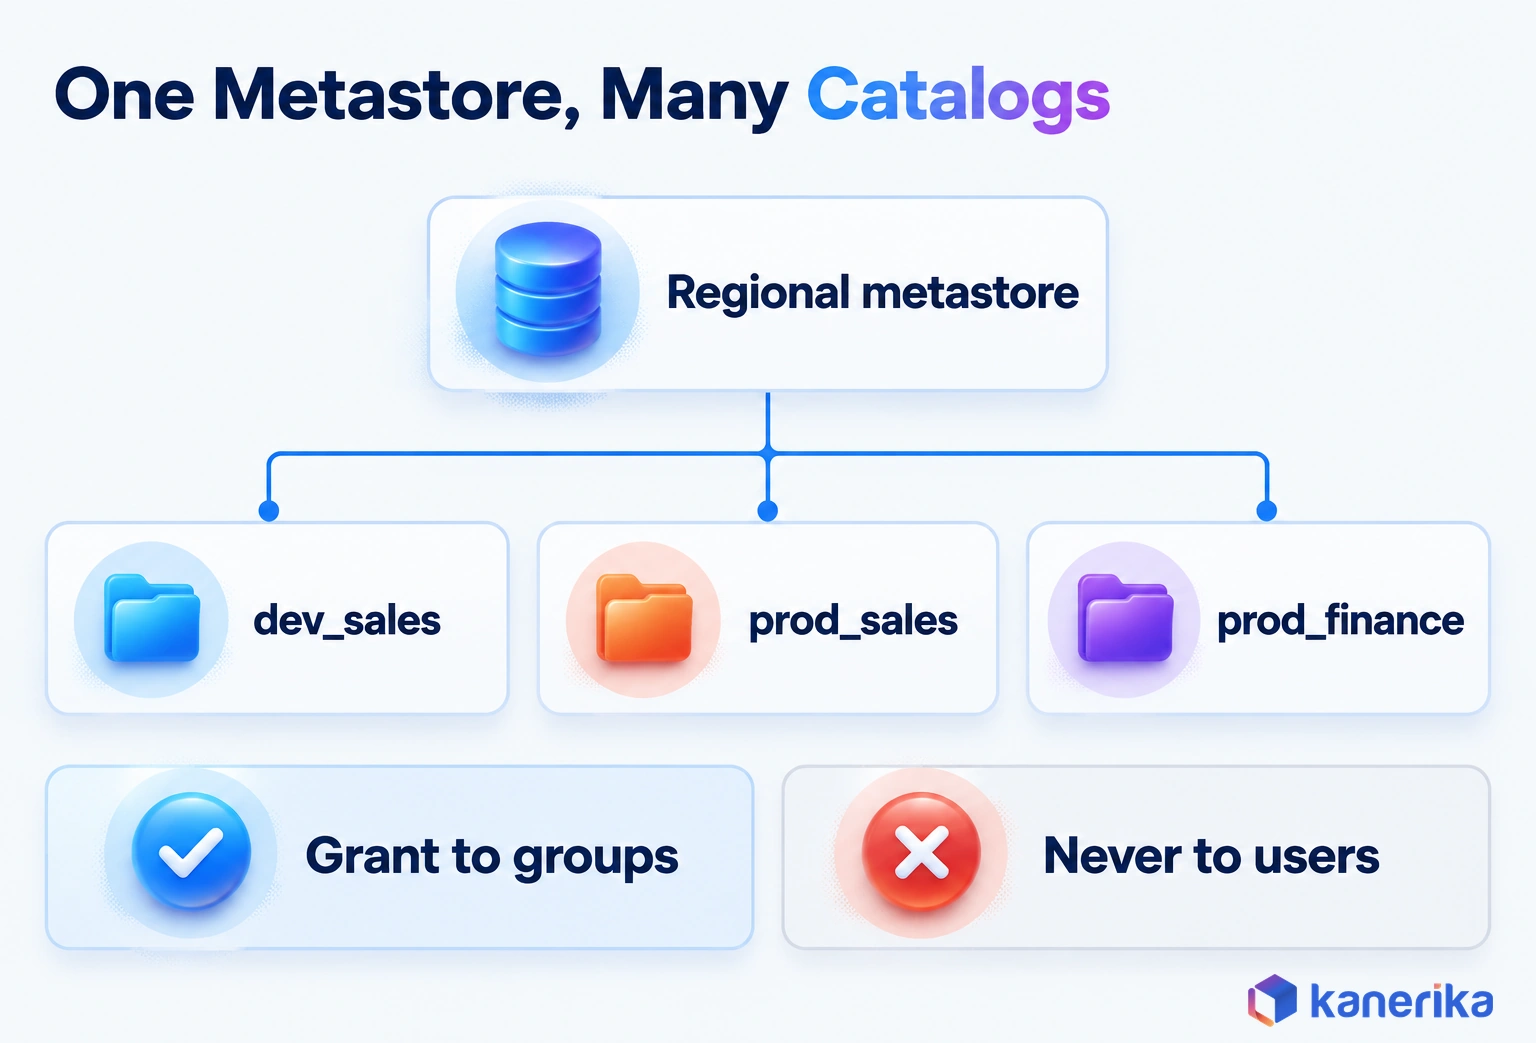
The design starts from one rule. Databricks allows only one metastore per region, and every workspace in that region shares it, according to its Unity Catalog best practices. So a US East deployment with dev, test and prod workspaces still has one metastore, and catalogs provide the separation.
- Confirm the regional metastore and assign every workspace in the region to it before anything else.
- Create storage credentials and external locations so Unity Catalog can reach the cloud storage paths it reads or writes.
- Create catalogs by environment, domain or both, such as dev_sales, prod_sales and prod_finance. Databricks notes that catalogs often map to environment, team, business unit or a mix.
- Assign ownership to groups, not users, so a resignation never orphans a production catalog.
- Set managed storage at the catalog or schema level so managed tables land in the right storage account.
- Grant privileges last, to groups only, and limit production read access to the teams that need it.
Now picture the finance team asking for a sandbox. With this layout you simply add a dev_finance catalog, then grant the finance-analysts group access. There is no new metastore, no new workspace and no per-user grants.
How to Implement Databricks Step by Step
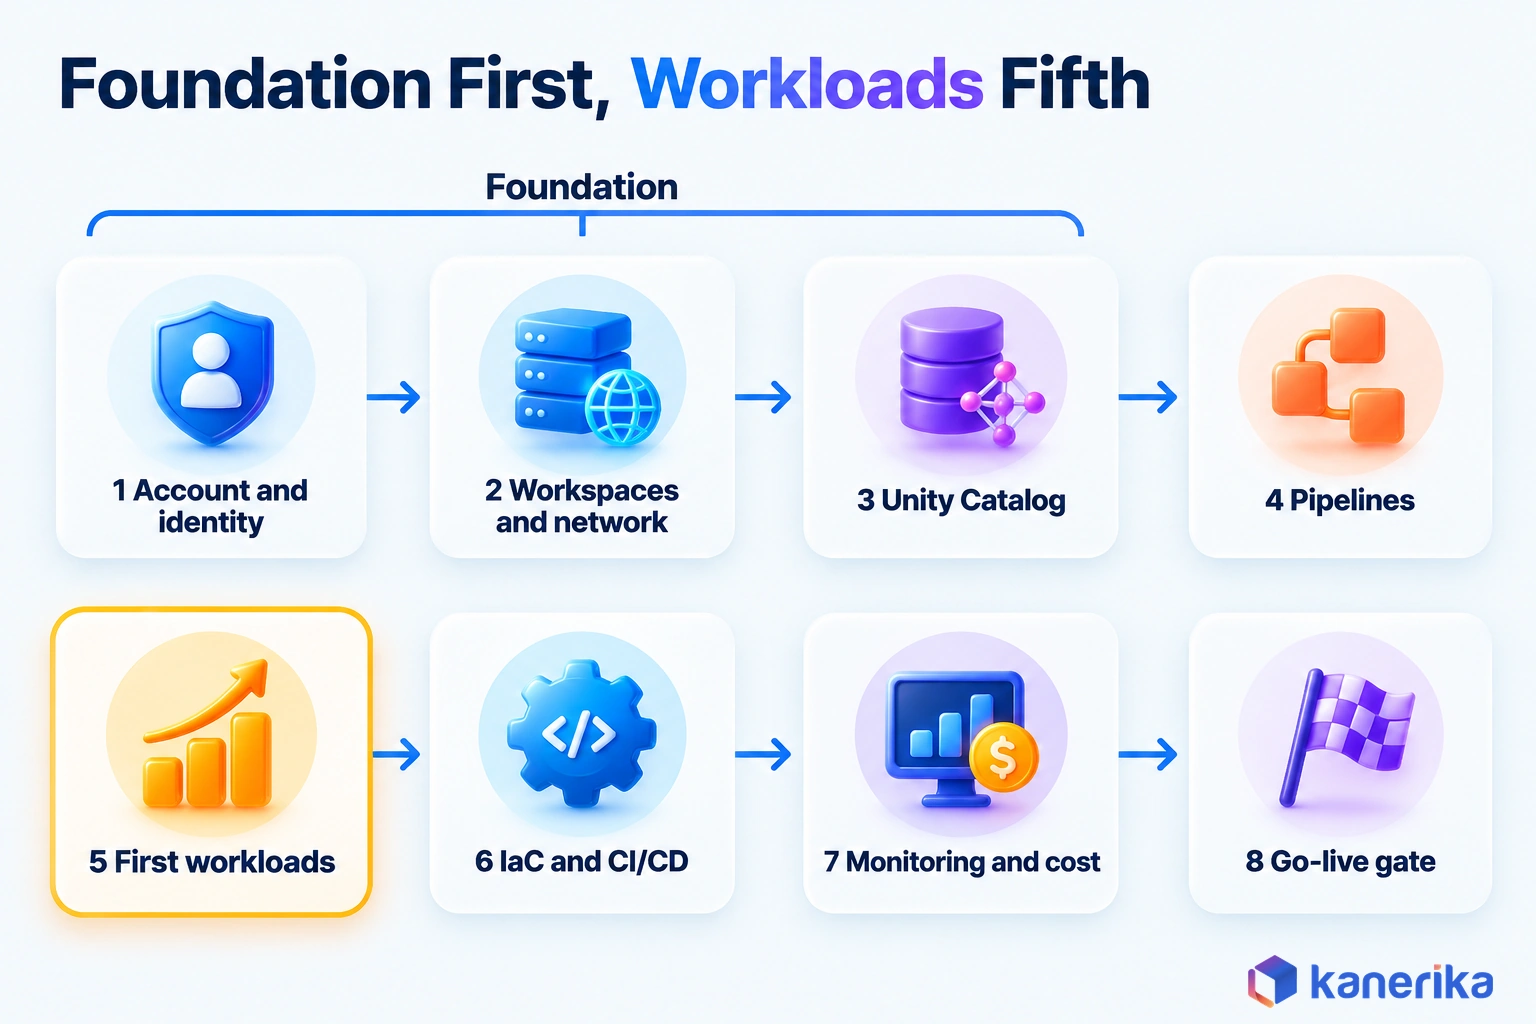
Databricks implementation follows a fixed order: foundations first, workloads fifth and operations last. Each step has an owner and a concrete output, so progress stays visible and nothing gets skipped.
The order exists for a reason. A pipeline built before Unity Catalog needs its permissions rebuilt, and a job built before compute policies needs its cluster settings rewritten. That is why policies, tags and budgets go in with the workspaces at step two, two steps before the first pipeline.
- Account and identity (owner: platform admin): set up SSO, SCIM sync and account-level groups first, because every later step depends on them.
- Workspaces and network (owner: cloud and network team with the platform admin): create dev, test and prod workspaces once the network design is agreed. Apply compute policies, cost tags and budgets in the same step, before anyone logs in.
- Unity Catalog (owner: data governance lead): assign the metastore, then add external locations, catalogs and group grants.
- Ingestion and transformation pipelines (owner: data engineering): land the first sources in bronze, silver and gold tables before any dashboard depends on them.
- First workloads (owner: workload leads): run the first use cases under the policies set in step two, using MLflow on Databricks for model training and tracking.
- Infrastructure as code and CI/CD (owner: platform engineering): manage infrastructure with Terraform and jobs with bundles, so a pipeline deploys to test and prod.
- Monitoring and cost (owner: platform admin with FinOps): turn on usage dashboards and job failure alerts before real users arrive. Then review spend against the step-two budgets.
- Disaster recovery and the go-live gate (owner: platform lead with security): finally, test a restore and sign the production-readiness checklist.
Where the Steps Overlap
Steps two and three can overlap once the network design is agreed. Infrastructure as code also starts earlier than its number suggests. Terraform builds the workspaces, policies and catalogs from step two, and pipeline code lives in Git from step four.
Writing that code early means step six adds a gate rather than a rewrite. From then on, test and prod change only through the CI/CD pipeline, so code becomes the only route to production.
Compute and Cost Controls From Day One
Databricks bills by usage, so cost control is a design choice rather than a monthly cleanup. The cheapest moment to set guardrails is before anyone has a habit to break, which is why step two applies them.
Consider an analyst who starts a large all-purpose cluster for a one-off query on a Friday afternoon. Without auto-termination, it then runs all weekend. A compute policy would have capped its size and shut it down once it sat idle.
| Control | What it prevents | Where you set it |
|---|---|---|
| Compute policies | Oversized clusters and unapproved instance types | Workspace admin settings, then assigned to groups |
| Auto-termination | Clusters left running when nobody uses them | Compute policy or cluster settings |
| Job compute for scheduled work | Production jobs competing with analysts on all-purpose clusters | Job definitions, such as those in bundles |
| Spot instances | Paying more than spot rates for fault-tolerant batch work | Cluster settings on classic compute |
| Tags | Spend that nobody can trace to a team or project | Policies, clusters, SQL warehouses and jobs |
| Budgets | Overspend discovered weeks later | Account console |
A compute policy is a short JSON definition. The example below follows the syntax in the Databricks compute policy reference, using AWS instance types. It fixes auto-termination at 30 minutes and caps autoscaling at 25 workers. It also limits instance types and only accepts approved cost-center tags.
{
  "autotermination_minutes": {
    "type": "fixed",
    "value": 30,
    "hidden": true
  },
  "autoscale.max_workers": {
    "type": "range",
    "maxValue": 25,
    "defaultValue": 5
  },
  "node_type_id": {
    "type": "allowlist",
    "values": ["i3.xlarge", "i3.2xlarge", "i3.4xlarge"]
  },
  "custom_tags.cost_center": {
    "type": "allowlist",
    "values": ["sales", "finance", "supply_chain"]
  }
}
Assign the policy to the groups that create compute, so every new cluster inherits these limits without a manual review.
Spot Capacity, Budgets and the Billing Table
Spot capacity matters most for fault-tolerant batch jobs. AWS prices EC2 Spot Instances at up to 90% off On-Demand, although that capacity can be reclaimed. So keep the driver on demand, and use spot workers only for jobs that retry cleanly.
Budgets give early warning rather than exact billing. Databricks budgets send email alerts at monthly thresholds, can take up to 24 hours to notify, and use list prices without discounts. For the real numbers, Databricks points to the system.billing.usage table as the source of truth.
For example, a short query against that table shows where usage goes each day:
SELECT usage_date,
       sku_name,
       custom_tags['cost_center'] AS cost_center,
       SUM(usage_quantity) AS dbus
FROM system.billing.usage
WHERE usage_date >= current_date() - INTERVAL 30 DAYS
GROUP BY usage_date, sku_name, custom_tags['cost_center']
ORDER BY usage_date DESC, dbus DESC;
Rows with a null cost_center are your untagged spend, so that is the first number to drive to zero. Once the platform runs, the focus moves to query and cluster tuning, covered in our Databricks performance optimization guide.
Talk to Kanerika
Plan Your Databricks Deployment With an Expert
Bring your workloads, cloud and current setup. Kanerika will walk through the four decisions, the landing zone and the build order for your estate.
Schedule a Demo →Automating the Deployment: Terraform, Bundles and CI/CD
Automation means every workspace, catalog, job and permission can be rebuilt from code. Without it, dev, test and prod drift apart until nobody can say for sure which settings production really has.
Two tools split the job. The Databricks Terraform provider manages workspaces and the cloud infrastructure around them. It aims to support all Databricks REST APIs, and it also includes a Unity Catalog setup guide. Bundles, covered in our asset bundles guide, manage what runs inside a workspace, such as jobs and pipelines, versioned with the code.
| Tool | What it manages | Typical owner |
|---|---|---|
| Databricks Terraform provider | Workspaces, network, catalogs, grants and policies | Platform or cloud engineering |
| Declarative Automation Bundles | Jobs, pipelines and their compute settings per environment | Data engineering |
| Git folders | Notebooks and code on Git branches inside the workspace | Each developer |
| CI runner (GitHub Actions, Azure DevOps or GitLab) | Validation and tests, then deployment to test and prod | Platform engineering |
A bundle is a small YAML file at the root of a repository. This one defines a dev target and a prod target, so the same pipeline code deploys to both:
bundle:
  name: sales_pipelines

targets:
  dev:
    mode: development
    default: true
    workspace:
      host: https://<dev-workspace-url>
  prod:
    mode: production
    workspace:
      host: https://<prod-workspace-url>
The CI runner calls databricks bundle validate on every pull request and then databricks bundle deploy -t prod after approval. Production deploys also run as a service principal, which is why the landing zone created those first.
Kanerika Service
Data Engineering Services
Kanerika builds and runs ingestion, transformation and streaming pipelines on Databricks, deployed as code with tests, monitoring and cost tags from day one.
Explore Data EngineeringMonitoring, Operations and the Go-Live Checklist
Go-live works best as a gate with written pass conditions. The workspace moves to production when every check below passes, and a failed check keeps it in pilot whatever the project plan says.
Monitoring is also part of that gate. Job failure alerts, pipeline freshness checks and the billing views from the cost section should already be running before real users arrive.
| Area | Check | Pass condition |
|---|---|---|
| Identity | Users and groups sync through SCIM | No local users, so every grant goes to a group |
| Network | Private connectivity tested end to end | No public IPs on compute, while storage is reached privately |
| Governance | Catalog ownership and grants reviewed | Every production catalog owned by a group |
| Cost | Policies, tags and budgets live | No untagged spend in the last 7 days |
| Automation | Production deploys only through CI/CD | No manual job edits in prod since launch |
| Monitoring | Alerts route to an on-call owner | A test failure reaches the owner |
| Recovery | Restore drill completed before launch | A production table restored within the target time |
| Support | Runbook and owners documented | Every workload has a named owner |
Recovery is the easiest check to defer and the costliest to skip. Run the restore drill before launch, when a failed drill only moves a date instead of losing data. For a wider review before the build starts, work through our Databricks readiness checklist.
Team, Scope and the Drivers of Effort
How long a Databricks deployment takes depends on scope rather than on the platform. A single-region, serverless-first build for one team is a different project from a multi-region, regulated estate.
The team matters as much as the plan. A typical deployment needs these roles, even when one person covers two of them:
- Platform admin: account, workspaces, policies and budgets.
- Cloud and network engineer: VPC or VNet, private connectivity and DNS.
- Data engineers: pipelines, tables and data quality checks.
- Governance lead: catalog design and ownership, then regular access reviews.
- Analytics or ML leads: the first workloads and their success metrics.
- FinOps owner: tags, budgets and monthly cost reviews.
Week ranges quoted without your context rarely hold, so the table lists the drivers that move effort most. Then score your project against each row to size it honestly.
| Driver | Lighter effort | Heavier effort |
|---|---|---|
| Workspace count | One to three workspaces in one region | Many business units across several regions |
| Network model | Serverless-only workspaces | Classic compute with private connectivity everywhere |
| Compliance scope | Internal analytics data | Regulated data that needs audit evidence |
| Data sources | A few cloud sources with ready connectors | Many on-premises systems and custom APIs |
| Starting point | Greenfield | Migration of legacy jobs and reports |
| Team skills | Spark, SQL and Terraform in-house | New to the cloud and to Databricks |
Budget follows the same drivers. Plan for Databricks usage, cloud infrastructure and the people time to build and run the platform, then track all three from the first month.
Skills gaps tend to surface first in Spark tuning and infrastructure as code. So if you are hiring Databricks talent for those skills, the podcast episode below covers what to look for in Databricks developers.
Common Databricks Deployment Mistakes
The mistakes below appear in deployments of every size, and each one has a cheap fix when you catch it early. Most of them come from treating the pilot setup as the production design.
- No change plan for users: analysts get a new platform without training, so they keep exporting to spreadsheets. Fix it by training a champion per team before go-live.
- Recreating legacy jobs as they are: copying stored procedures line by line also copies their old workarounds. Instead, redesign each job around bronze, silver and gold layers.
- Per-user grants: access given to individuals breaks when people change roles. Grant to account-level groups synced by SCIM instead.
- No tags: spend cannot be traced to a team, so cost reviews turn into arguments. Enforce tags through compute policies from day one.
- All-purpose compute for production jobs: scheduled jobs share interactive clusters and compete with analysts for capacity. Run production on job compute defined in bundles instead.
- No outbound path on new Azure VNets: Microsoft changed the default for new virtual networks after March 31, 2026. Their subnets now default to private, with no outbound internet access, per Microsoft’s default outbound access guide. The secure cluster connectivity guide adds that new VNet-injected Databricks workspaces need an explicit outbound method. Put a NAT gateway on both workspace subnets before the first cluster starts.
- No rollback path: a bad deploy reaches prod with no way back. Version everything in Git so you can redeploy the last good bundle.
Which Deployment Approach Fits Your Enterprise?
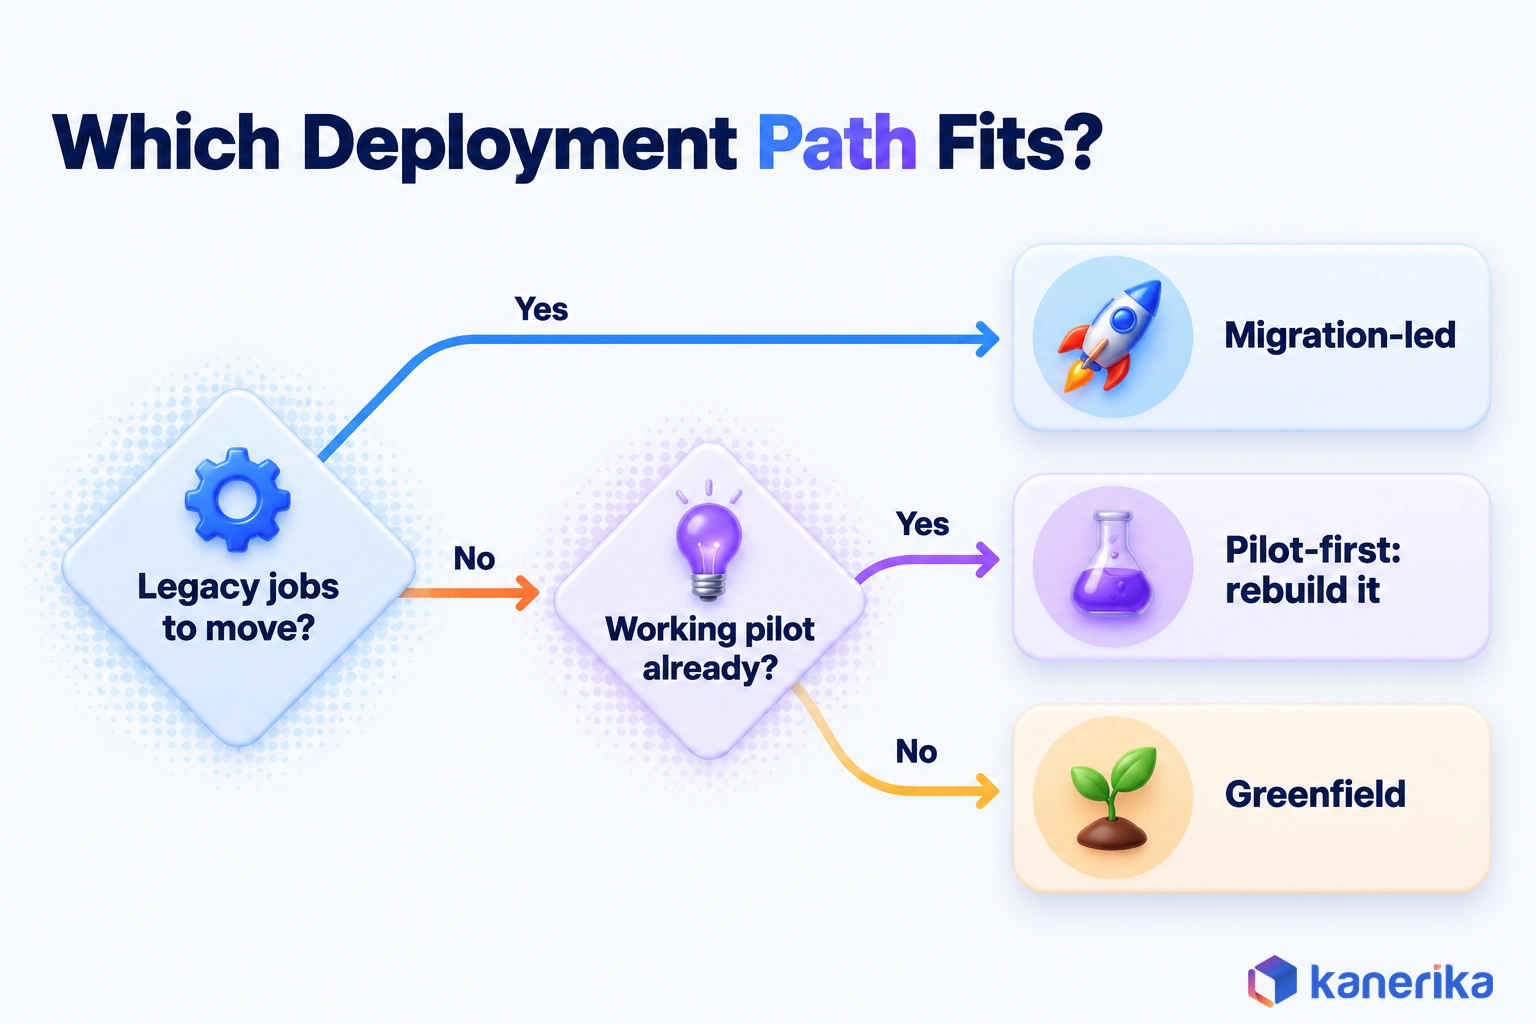
How you plan and implement Databricks depends on where you start. A company with no platform, for instance, needs a different first move than a team with a working pilot or an enterprise retiring legacy systems.
| Approach | Choose it when | How to plan it | How to implement it |
|---|---|---|---|
| Greenfield | No existing platform or pilot | Make the four decisions, then design the landing zone and catalogs | Run all eight steps in order, then onboard workloads |
| Pilot-first | A pilot works but was built by hand | Treat the pilot as a requirements document | Rebuild it on the new foundation, then retire the pilot workspace |
| Migration-led | Legacy jobs, warehouses or reports must move | Inventory and rank the legacy workloads | Build the foundation before moving workloads in waves |
Migration-led projects add workload conversion as well as cutover planning on top of the foundation. That work has its own playbook, covered in our guide to migrating legacy systems to Databricks.
Whichever row fits, the foundation steps do not change. Only the source of the first workloads does, which is why the approach is a planning decision rather than a different architecture.
Worked Example: A US Distributor on Azure
Picture a US distributor with ERP, warehouse and e-commerce data and no existing lakehouse. It already runs Microsoft 365 and Entra ID, so Azure is the natural host, and the approach is greenfield.
The team plans three workspaces, dev, test and prod, in one region with one metastore. Catalogs split by environment and domain, such as dev_sales, prod_sales and prod_supply_chain. All three workspaces are Premium, since the Standard tier is retired.
Compute is mixed. Analysts query serverless SQL warehouses, while the nightly ERP pipelines run on classic job compute with spot workers for the steps that retry cleanly.
Terraform on Azure builds the workspaces and catalogs, while bundles deploy the pipelines from Git. The first gold table reaches finance only once the restore drill passes and every warehouse carries a cost-center tag.
How Kanerika Deploys Databricks
Kanerika delivers Databricks consulting, implementation and migration services with certified experts. Its deployments run in five stages, so they mirror the order in this guide:
- Assess: workloads, data sources, skills and success metrics.
- Design: the landing zone and workspace topology, then the Unity Catalog layout.
- Build the foundation as code: Terraform for infrastructure and bundles for jobs, with compute policies, tags and budgets in place before workloads arrive.
- Pilot workloads: two or three use cases on the new foundation, measured against the agreed targets.
- Production and FinOps: the go-live gate, then monitoring and monthly cost reviews.
Migration-led projects also add Kanerika’s FLIP migration accelerators to the same sequence. Pipeline and modeling work runs through our data engineering services.
One example comes from a financial services data modernization project. The firm needed faster fraud and settlement reporting from data held in protected S3 storage. Kanerika built Airflow 2.0 ingestion pipelines, then processed and enriched the data in Databricks before loading it into Dremio for reporting.
The results were a 90% reduction in data lag from source to consumption and a 96% reduction in reporting latency, down from a three-day cycle. The firm also saw a 100% increase in BI adoption across reporting teams.
Case Study
90% Less Data Lag with Databricks and Airflow
A financial services firm moved fraud and settlement data from protected S3 through Airflow 2.0 pipelines into Databricks and Dremio, cutting data lag by 90% and reporting latency by 96%.
Read the Case Study →Bottom Line: Plan the Foundation, Then Implement in Order
A Databricks deployment succeeds or stalls on its foundation. Plan the four decisions first, then build identity, network and Unity Catalog before any workload arrives.
After that, implement in the eight-step order, automate from the start and let a written checklist decide go-live. That is how to plan and implement a Databricks deployment that holds up in 2026.
Frequently Asked Questions
What is deployment in Databricks?
Deployment in Databricks means setting up the platform your workloads run on. That covers the account, identity and single sign-on, workspaces, the network path to your data, Unity Catalog governance, compute policies, automation and monitoring. The result is a governed, repeatable environment where many teams can run production work safely, with clear owners and tracked costs.
Where can Databricks be deployed?
Databricks runs on Amazon Web Services, Microsoft Azure and Google Cloud. On each cloud, you pick regions for data residency and latency. You also choose between classic compute in your own cloud account and serverless compute run by Databricks. Most enterprises pick the cloud where their identity provider, network and data already live.
What are the main enterprise use cases for Databricks?
Enterprises use Databricks for four main workload types. Batch pipelines build bronze, silver and gold tables, while BI teams run SQL analytics on SQL warehouses. Streaming handles feeds such as orders or sensor events. Machine learning and AI cover feature engineering through model serving. Most deployments start with two or three use cases and expand from there.
How do I choose between Azure and AWS for a Databricks deployment?
Choose the cloud where your identity provider, network and data already live, because moving those costs more than any platform difference. Teams on Microsoft 365 and Entra ID often lean to Azure, while S3-heavy estates often lean to AWS. Check the tier rules as well, since Azure is Premium only and AWS back-end PrivateLink needs the Enterprise tier.
What security measures are essential for production Databricks deployments?
Start with single sign-on and SCIM at the account level, account-level groups and service principals for automation. Add private connectivity, no public IPs on compute and Unity Catalog grants to groups. Then turn on audit logging, review access on a schedule and test every control before go-live, so production starts from a known, checked state.
Can Databricks integrate with existing data platforms and BI tools?
Yes. Databricks connects to common cloud storage, databases and SaaS sources for ingestion, and BI tools such as Power BI and Tableau query its SQL warehouses. On Azure, Unity Catalog catalog federation can also query Microsoft Fabric Lakehouse and Warehouse data read-only. Plan these connections during the workload decisions, before the landing zone is built.
What drives Databricks deployment costs and how can I control them?
Costs come from Databricks usage, cloud infrastructure and the people who build and run the platform. Usage grows with compute size, idle time and workload volume. Control it with compute policies, auto-termination and job compute for scheduled work. Add spot instances for fault-tolerant jobs, tags and budgets, then check real spend in the system.billing.usage table.
What common mistakes should organizations avoid during Databricks implementation?
The usual mistakes are skipping a change plan for users, copying legacy jobs as they are, granting access to individuals and leaving compute untagged. Others include running production jobs on all-purpose compute, deferring the private connectivity decision and having no rollback path. Most of them trace back to promoting a pilot instead of building a proper foundation first.
How long does a typical enterprise Databricks deployment take?
There is no reliable standard duration, because effort depends on scope. The biggest drivers are workspace count, the network model, compliance scope, the number and type of data sources, and whether you are migrating legacy jobs. Team skills matter too. A single-region, serverless-first build for one team is far smaller than a regulated, multi-region estate.
Should enterprises use serverless or classic Databricks workspaces?
Use serverless workspaces when your teams can run on serverless compute only and your region supports it. They come with serverless compute and default storage, and on AWS they need no customer-managed VPC. Choose classic when you need custom networking, specific instance types or spot capacity. You can also mix serverless SQL warehouses with classic job compute.
What is the role of Unity Catalog in a Databricks deployment?
Unity Catalog is the governance layer that controls access to tables, volumes, models and functions across workspaces. Databricks allows one metastore per region, shared by every workspace in it. It enables Unity Catalog automatically for workspaces created after November 8, 2023. Plan catalogs by environment or domain, and grant privileges to groups so access survives staff changes.
How do you automate Databricks deployment with Terraform and CI/CD?
Use the Databricks Terraform provider for workspaces, network, storage, catalogs and grants. Use Declarative Automation Bundles for jobs and pipelines, and keep both in Git. A CI runner validates bundles on every pull request and deploys to test and prod after approval. It runs as a service principal, so no production change depends on a personal account.
How do I monitor and maintain performance in my Databricks environment?
Set up job failure alerts, pipeline freshness checks and usage dashboards built on the system.billing.usage table before go-live. Review failures, untagged spend and access requests every week. For performance, track slow queries and cluster utilization. Then tune table layout, file sizes and compute sizing on a regular schedule as data volumes and users grow.
Is Databricks a database or ETL tool?
Databricks is a lakehouse platform. It stores data in open table formats on cloud storage and runs SQL analytics, data engineering pipelines, streaming and machine learning on that data. Teams use it for ETL work and for warehouse-style querying, with Unity Catalog governing access. So it covers both roles inside one governed platform.
Can Databricks be deployed on AWS?
Yes. Databricks on AWS runs the control plane in the Databricks account and the compute plane either in your own AWS account or on serverless compute. Classic deployments use a customer-managed VPC, and back-end PrivateLink needs the Enterprise tier. Serverless-only workspaces do not need a customer-managed VPC, which shortens the network setup.
Is Databricks SaaS or PaaS?
Databricks sits between the two. The control plane, with the web app, scheduler and APIs, is delivered as a managed service, much like SaaS. On the classic compute plane, clusters run in your own cloud account, which feels more like PaaS. Serverless compute hands that part to Databricks as well, moving the experience closer to SaaS.
What makes Databricks different from other data platforms?
Databricks runs data engineering, SQL analytics, streaming and machine learning on one copy of data in open formats, rather than splitting them across separate systems. Unity Catalog governs tables, files, models and functions in one place. It also runs on AWS, Azure and Google Cloud, so the same skills and patterns carry across clouds.
What is a major weakness of Databricks?
The main weakness is that cost and complexity grow quickly without guardrails. Usage-based billing means idle clusters, oversized compute and untagged jobs can turn into surprise bills. The platform also expects Spark, SQL and cloud networking skills. Compute policies, auto-termination, tags, budgets and a trained platform team keep both problems in check from day one.
Should I use Databricks or AWS native services?
It depends on your workload mix and your team. Databricks suits teams that want one platform for pipelines, SQL analytics and machine learning under shared governance. AWS native services suit teams already standardized on them that prefer a separate managed tool for each job. Compare total cost and skills before deciding, one workload at a time.
How is Databricks deployed in Azure?
Azure Databricks is set up from the Azure portal or from infrastructure code, with Microsoft Entra ID handling identity. You pick a region, a virtual network for classic compute and private connectivity options. Every new workspace uses the Premium tier, as the Standard tier was retired on October 1, 2026. Secure cluster connectivity is enabled by default.