TL;DR
Agentic BI replaces the investigative half of dashboard work, so use it when people need the reason behind a number and keep dashboards when they only need to watch one. An agentic BI system takes a business goal, plans the analysis, queries governed data, explains what it found and then drafts the next step for a person to approve. Microsoft Fabric and Power BI, Databricks, Snowflake and Looker all ship agent access to governed data models. Accuracy depends more on clear business definitions in the semantic layer than on the language model. Regulated reports, stable executive scorecards and at-a-glance monitoring should stay on dashboards because they need fixed logic. Start with one investigative workflow in read-only mode, test the agent on real historical questions, and add supervised actions only after it passes.
Key Takeaways
- Agentic BI pairs an AI agent with governed business data so it can plan an analysis, run the queries, explain the result and propose an action.
- It replaces investigative workflows such as variance analysis, while monitoring, regulated reporting and executive scorecards stay on dashboards.
- The semantic layer decides accuracy, because models score well on curated benchmarks but drop sharply on real enterprise schemas without business context.
- Platform path and level of autonomy are two separate decisions, and every pilot should start in read-only mode.
- Access control, approval gates, audit logs and a tested question set belong outside the model, before any agent touches production data.
- Cost per accepted investigation is a better measure than license cost, since rejected answers still use capacity and analyst time.
Monday’s Revenue Review Starts With a Question, Not a Dashboard
Picture a VP of sales at 8:15 on a Monday morning. Her weekly bookings tile shows an 8% drop against the prior week, and the revenue review starts at 9. (That figure is illustrative, but the situation is familiar to any revenue team.)
The dashboard has done its job, since it shows that something moved. Still, it cannot say why. To find out, the VP would normally message an analyst, who then filters by region, product and segment and cross-checks the CRM for deals that slipped.
That takes hours, but the meeting starts in 45 minutes.
Agentic BI is built for that gap between seeing a number and understanding it. An agent takes the question and works through the same steps the analyst would. When it finishes, it returns an explanation with its evidence and drafts follow-up tasks for the VP to approve.
This guide covers how that works and which dashboards it replaces. It also covers which dashboards to leave alone and how to roll the approach out safely.
What Is Agentic BI?
Agentic BI is business intelligence in which an AI agent pursues an analytical goal on its own. It plans the analysis, queries governed data and reasons over the results. Then it proposes or takes an action under rules you set.
The difference from earlier tools is the loop. A chart answers one question, while an agent keeps asking the next one until the goal is met.
Take the bookings drop as an example. A conversational tool answers “show bookings by region” with a chart. By contrast, an agent given “explain the bookings drop” decides for itself to break the number down by region and then by product. After that, it checks deal stages in the CRM and stops once it can support an explanation with data.
Five traits separate a genuine agent from a chat window on top of a report:
- A goal, not a query. It works toward an outcome such as “explain the variance” rather than a single lookup.
- A plan. It breaks the goal into ordered steps and revises them as results come in.
- Tool use over governed data. It calls semantic models, SQL engines and business applications through approved connections.
- Memory and context. It carries business definitions, earlier findings and the user’s role across every step.
- Action under rules. It drafts tasks, alerts or updates, but executes them only inside limits a person has approved.
If you want a refresher on the reporting stack underneath, our guide to business intelligence covers the basics.
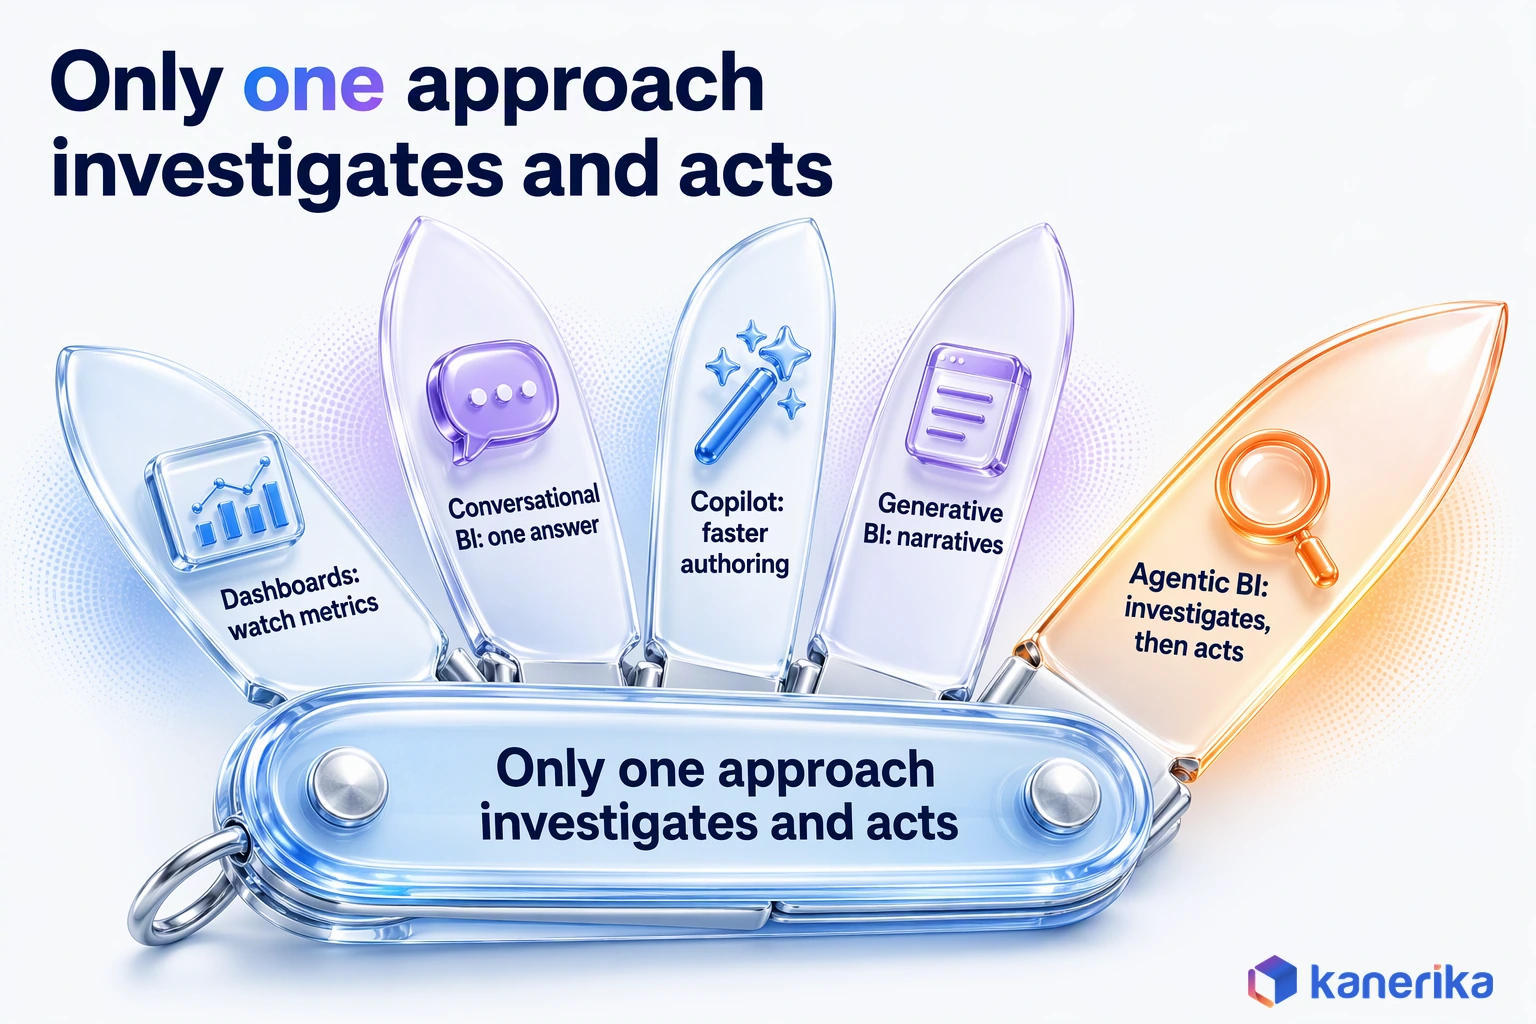
Agentic BI vs Dashboards, Conversational BI, Copilot and Generative BI
These terms get used loosely, so it helps to compare them on what each one actually does. The table below separates them by who starts the work, what comes back and whether anything happens next.
| Approach | Who asks | What it returns | Multi-step? | Takes action? | Best for |
|---|---|---|---|---|---|
| Dashboards | The designer, in advance | Fixed visuals | No | No | Monitoring known metrics |
| Conversational BI | The user, one question at a time | An answer or chart | No | No | Quick ad hoc lookups |
| Copilot in BI tools | The user, inside a report | Summaries, visuals and DAX help | Limited | No | Faster report authoring |
| Generative BI | The user or a schedule | Generated reports and narratives | Limited | No | Written explanations of data |
| Agentic BI | The user, by setting a goal | A tested explanation, then proposed next steps | Yes | Yes, but only within approved limits | Investigations and exceptions |
Two neighbors in particular deserve a closer look. Generative BI writes reports and narratives, and our guide covers it in depth. Similarly, Copilot in Power BI helps people build and read reports. An agent goes further because it decides the next step itself.
Why Agentic BI Is Getting Attention in 2026
The short reason is that, by November 2026, the major data platforms let agents reach governed business data instead of raw tables. For example, Microsoft lists the Fabric data agent as a generally available feature. It answers conversational questions over lakehouses, warehouses, semantic models and KQL databases.
Other platforms also moved the same way. Databricks Genie answers questions grounded in data governed through Unity Catalog. Meanwhile, Snowflake describes Cortex Analyst as a fully managed, LLM-powered feature that answers business questions over semantic models. As checked in November 2026, Snowflake’s documentation recommends moving to Cortex Agents, which supports every Cortex Analyst capability. Looker’s Conversational Analytics also adds data agents, plus scheduled agentic workflows in preview, on top of LookML models.
The caution is just as real, though. In a June 25, 2025 forecast, Gartner predicted that over 40% of agentic AI projects will be canceled by the end of 2027. It named rising costs, unclear business value and weak risk controls as the causes. The same release estimated that only about 130 of the thousands of vendors claiming agentic AI are real. Gartner calls the rest “agent washing.”
Even so, Gartner expects at least 15% of day-to-day work decisions to be made autonomously by 2028. It also expects agentic AI in 33% of enterprise applications by then. So the direction is clear, but the projects that survive will be the ones with a measurable use case and real controls. Analytics fits that test well because its questions have known answers you can check.
AI Assessment
How Ready Is Your Organization for Agentic BI?
Score your data, governance and team readiness with Kanerika’s AI maturity assessment, and see which gaps to close before an agent pilot.
Start Your AI Assessment →Where Agentic BI Earns Its Keep First
The best first use cases share one pattern: a recurring question whose answer takes an analyst hours of slicing and cross-checking.
- Finance variance. Explain why actuals missed the forecast, such as by cost center, vendor or account.
- Revenue operations. Trace a bookings or pipeline drop to region, product, deal stage and slipped deals.
- Supply chain exceptions. Find the root cause when shipments run late across carriers, lanes and suppliers.
- Customer churn. Spot which accounts show early warning signs and which signals moved first.
- Inventory reconciliation. Match system stock to ledger entries, then group mismatches by likely cause.
What these have in common is an answer an analyst can check, such as the cost center or carrier that caused the miss. That makes them the safest place to prove an agent before retiring the drill-down dashboard that served the same question.
How Agentic BI Works: From Question to Action
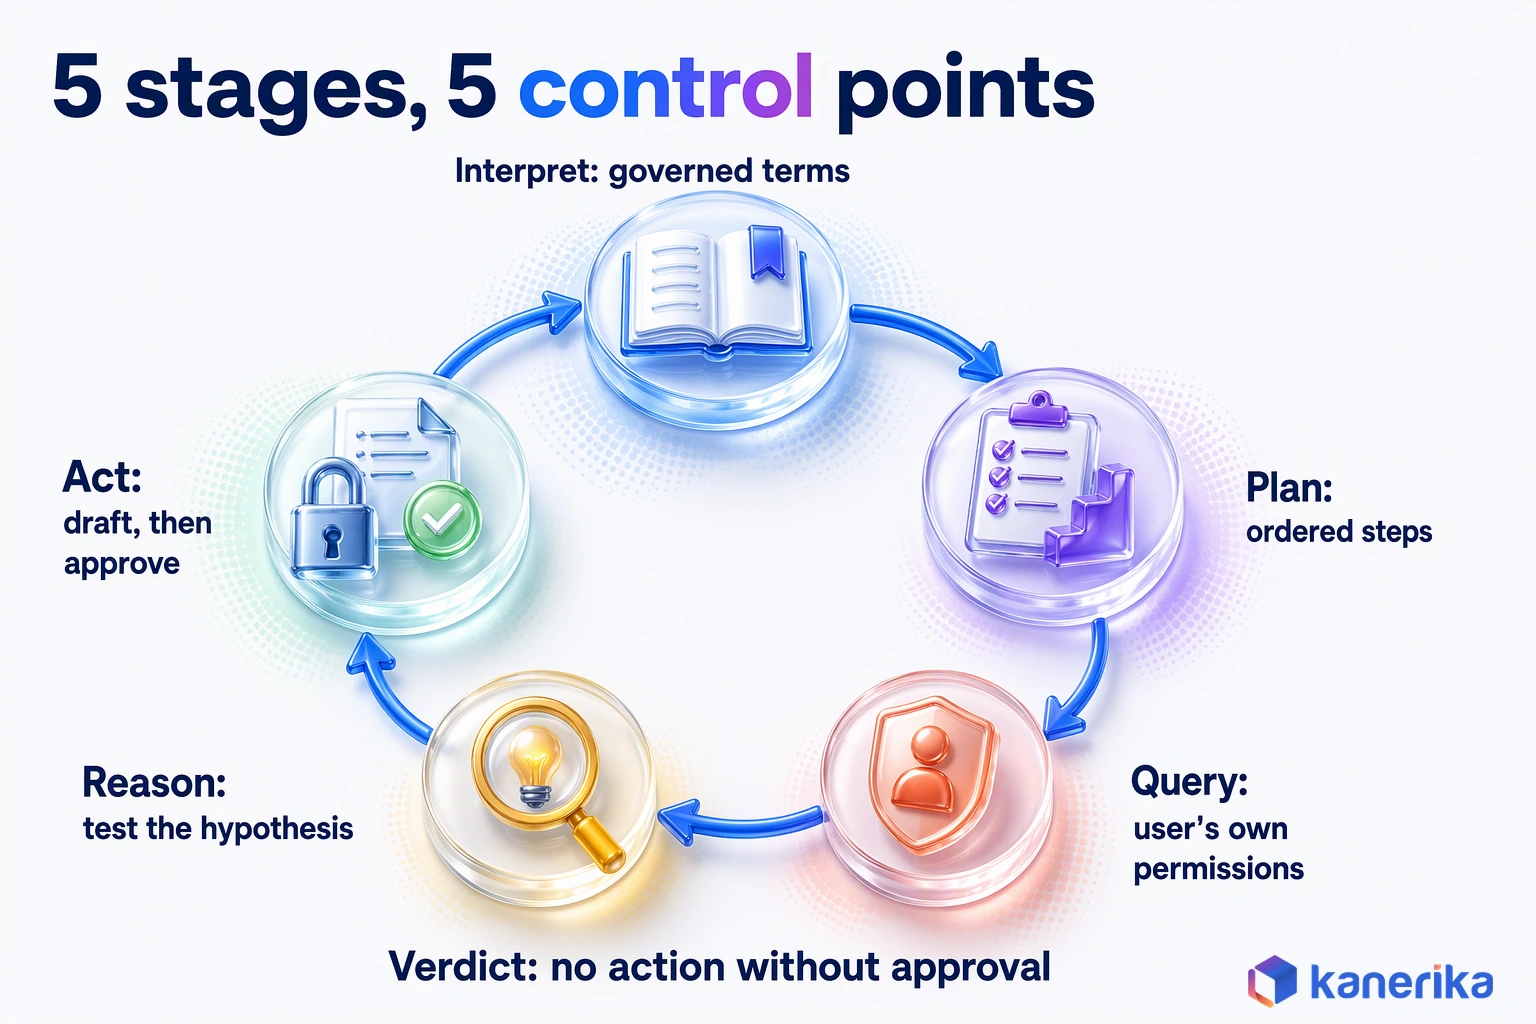
Every agentic analytics system runs the same basic loop, whatever the vendor calls it. It interprets the question, plans the steps, queries governed data, reasons over what comes back and then acts. Each stage needs its own control point, so most of the design work goes there.
Interpretation maps the user’s words to business terms, so “bookings” resolves to one governed measure rather than a guess. Planning then turns the goal into ordered steps. After that, the query stage calls the semantic model or SQL engine with the user’s own permissions.
Some designs also add a retrieval step over documents, a pattern our guide to agentic RAG explains. Reasoning compares results, tests a hypothesis and decides whether another query is needed. Action comes last because it carries the most risk, so it usually stays limited to drafts until a person approves.
Microsoft’s guide to creating a Fabric data agent shows this loop in a shipping product. The agent picks NL2SQL, NL2DAX or NL2KQL for each source, then shows its generated query and each step. Its queries are read-only, so no data can be created, updated or deleted. The same guide lists “What is the root cause of our sales spike?” as out of scope. Multi-step diagnosis therefore still needs an orchestration layer or an analyst on top.
For a deeper look at planners, memory and tool calling, see our guide to AI agent architecture.
A Worked Example: Investigating a Bookings Drop
Here is how the Monday question plays out step by step. As before, the numbers are illustrative.
- The VP asks why weekly bookings fell 8% against the prior week.
- Next, the agent breaks the goal into checks by region, product line, customer segment and deal stage.
- It queries the governed Bookings and Pipeline measures in the semantic model, using the VP’s own access rights.
- Once one region shows up as the main source of the drop, it checks the CRM and sees several large deals moved to the next quarter.
- Then it writes a short explanation, lists the queries it ran and flags anything it could not confirm.
- Finally, it drafts follow-up tasks for the regional sales lead and waits for the VP to approve them.
Notice what the agent did not do. It never invented a definition of bookings, never read data the VP could not see and never sent a task on its own.
Why the Semantic Layer Decides Accuracy
The semantic layer is the set of governed business definitions between raw tables and the people who ask questions. For instance, it tells the agent that “net revenue” means invoiced amount minus credits in US dollars, not whichever column looks closest. Public benchmarks show why this matters so much.
| Benchmark | What it tests | Result |
|---|---|---|
| BIRD | 12,751 question-SQL pairs over 95 databases (33.4 GB) | Top overall entry at 83.40% test execution accuracy, compared to 92.96% for humans (leaderboard as checked November 2026) |
| Spider 2.0 | 632 real enterprise text-to-SQL workflow problems | At release, o1-preview solved 17.1% and GPT-4o 10.1%, while GPT-4o scored 86.6% on Spider 1.0 |
| Spider 2.0, later leaderboard | The Snow, Lite and DBT settings of the same tasks | Top agent systems pass 90% on Spider 2.0-Snow, but the Lite and DBT settings still top out near 76% and 66% (as of November 2026) |
Overall, the pattern is consistent. Models do well on curated test databases but fall off on large enterprise schemas. The gap closes when systems get detailed business context. That context is exactly what a semantic model, a metrics layer or a data fabric or data virtualization layer supplies.
Snowflake’s own documentation makes the same point: Cortex Analyst relies on semantic models because raw schemas “lack critical knowledge like business process definitions and metrics handling.” Kanerika’s Karl agent follows that logic in practice. On a manufacturing project, its Data Dictionary translated coded ERP fields into business terms before users asked a single question.
Datasheet
Karl Data Insights AI Agent for Microsoft Fabric
A short overview of Karl, Kanerika’s data insights AI agent for Microsoft Fabric, for teams that want plain-language answers over governed data.
View the Datasheet →Will Agentic BI Replace Your Dashboards?
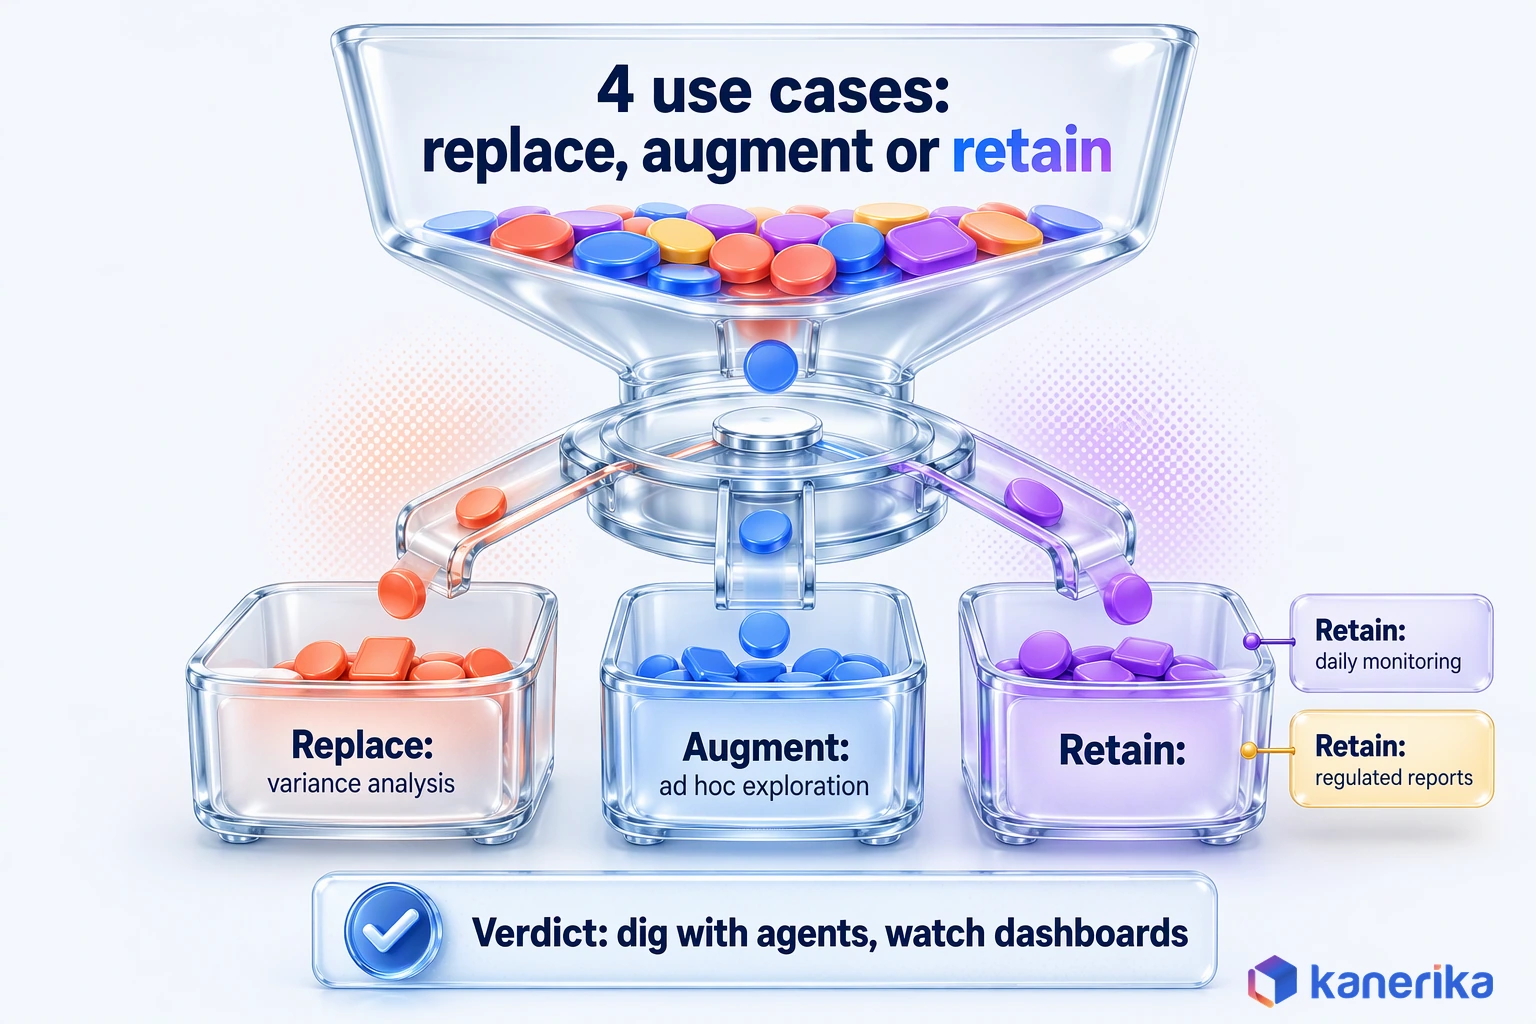
Agentic BI replaces some dashboard work, not dashboards as a whole. The useful rule is simple: replace investigative workflows, augment exploration and retain anything regulated, stable or meant to be read at a glance. So a dashboard that exists only so someone can dig for the cause of a change is a strong candidate.
Monitoring works differently. An operations lead who checks the same five metrics every morning gains nothing from typing a question, because the picture loads faster than any answer. Regulated reports such as statutory filings also need fixed, approved logic that never varies with a prompt. In those cases, good data visualization still does the job better.
| Use case | Decision | Why |
|---|---|---|
| Variance and root-cause analysis | Replace | Multi-step slicing is what agents do best |
| Exception triage (late orders, stock gaps) | Replace | Recurring questions have checkable answers |
| Ad hoc exploration by business users | Augment | The agent speeds up questions, while the analyst still frames them |
| Self-service report building | Augment | Copilot-style help shortens authoring time |
| Operational monitoring | Retain | A glance beats a conversation |
| Regulated and statutory reporting | Retain | Logic must be fixed, approved and auditable |
| Executive scorecards | Retain | Stable views build trust over time |
This also changes the case for self-service business intelligence. Instead of training every user to build reports, teams can let people ask an agent. Report building then stays with the analysts who own the logic.
The infographic below condenses the table to four use cases that cover all three decisions. Variance analysis is replaced, ad hoc exploration is augmented, and monitoring and regulated reports stay on dashboards.
Agentic BI Platform Paths Compared
As of November 2026, every major data platform documents a route to agentic analytics, and the right one usually follows the platform you already run. The table compares five paths by the semantic layer each relies on and where governance is enforced. It sticks to documented capabilities and leaves out prices, since those change often.
| Path | Semantic layer it relies on | Governance anchor | Best fit | Watch-out |
|---|---|---|---|---|
| Microsoft Fabric and Power BI (Fabric data agents, Copilot, Power BI MCP servers, Fabric IQ) | Power BI semantic models, lakehouses, warehouses and ontologies | Row-level and object-level security, with Purview controls for data agents in preview | Organizations standardized on Power BI | Needs paid F2+ Fabric or Premium P1+ capacity, since trial and free SKUs are not supported |
| Databricks Genie | Trusted data, metrics and business rules set by data teams | Unity Catalog | Lakehouse-first teams on Databricks | Quality depends on how well data teams configure each Genie agent |
| Snowflake Cortex Analyst | Semantic models and semantic views | Snowflake access controls | Snowflake-centric warehouses | Accuracy drops when raw schemas lack a semantic model |
| Looker Conversational Analytics | LookML model metadata over Explores | Looker model permissions | Teams with mature LookML | Limited to what the LookML model exposes |
| Custom agent over MCP | Whatever semantic model or API you expose | Your own identity and policy layer | Cross-system workflows and unique rules | You own testing, security and upkeep |
For working patterns, see our guide to agentic AI applications in Microsoft Fabric. Our reviews of Genie’s features and limits and where Snowflake Cortex breaks go deeper on those two paths. Kanerika’s Microsoft Fabric and Power BI practices also cover both platforms.
Inside the Microsoft Path: MCP Servers and Fabric IQ
The Microsoft path has the most moving parts, so it is worth a closer look. Microsoft’s Power BI MCP servers overview describes two servers. The Authoring MCP server creates and changes semantic models, with a generally available local server and a hosted endpoint in preview.
The second, Fabric IQ, is the consumption side: it answers natural-language questions over semantic models and ontologies while respecting row-level and object-level security. It is the supported path for data answers in Microsoft 365 Copilot, Copilot Studio, Foundry and custom agents.
Both servers build on the Model Context Protocol, an open-source standard for connecting AI applications to external systems. That is also why MCP anchors the custom path. On the report side, Microsoft’s Copilot documentation lists the report Copilot pane as generally available, while the standalone Power BI agent is in preview. Our explainer on how MCP works covers the protocol itself.
Setting up a first Fabric data agent takes five configuration steps, all drawn from Microsoft’s setup guide:
- Capacity and tenant. Confirm a paid F2+ or Premium P1+ capacity, then enable cross-geo processing and storing for AI if your region requires it.
- Sources. Choose New Item, then Fabric data agent, and add up to five sources, such as semantic models, lakehouses or warehouses.
- Scope. In the Explorer pane, tick only the tables the agent may use, and give them descriptive names.
- Instructions and examples. Define business terms in up to 15,000 characters of instructions, and add example queries for lakehouse, warehouse and KQL sources.
- Publish. Test against known questions, then publish with a clear description. Users need only Read permission on the semantic model.
The Snowflake path is configured differently. You define a semantic view, then grant a role the SNOWFLAKE.CORTEX_ANALYST_USER database role plus SELECT on the referenced tables.
Choosing an Agentic BI Approach: A Decision Framework
The right approach depends less on which model is smartest and more on how your data and definitions are organized. Start from your situation and pick the matching row. Note that one row says to wait, because an agent on top of conflicting definitions only spreads the conflict faster.
Talk to Kanerika
Choosing an Agentic BI Platform Path?
Comparing Fabric, Databricks, Snowflake or a custom agent? Kanerika will map your semantic models, access rules and first investigative workflow, then recommend a path and a read-only pilot.
Schedule a Demo →| Your situation | Pick | Why |
|---|---|---|
| One BI ecosystem with governed semantic models | Extend your platform’s native agent | Security and definitions already live there |
| Questions span CRM, ERP and BI, as in revenue operations | An orchestration layer over several sources | No single platform agent sees every system |
| Strict audit needs and unique business rules | A custom, bounded agent over MCP | You control every tool, log and limit |
| Teams disagree on core metric definitions | Fix the foundation first | Otherwise an agent repeats the disagreement at scale |
| Questions are few, small and stable | Platform conversational tools only | A full agent adds cost without new answers |
| Only stable executive reporting is needed | Keep dashboards | Nothing is being investigated |
Choose the Autonomy Level Separately
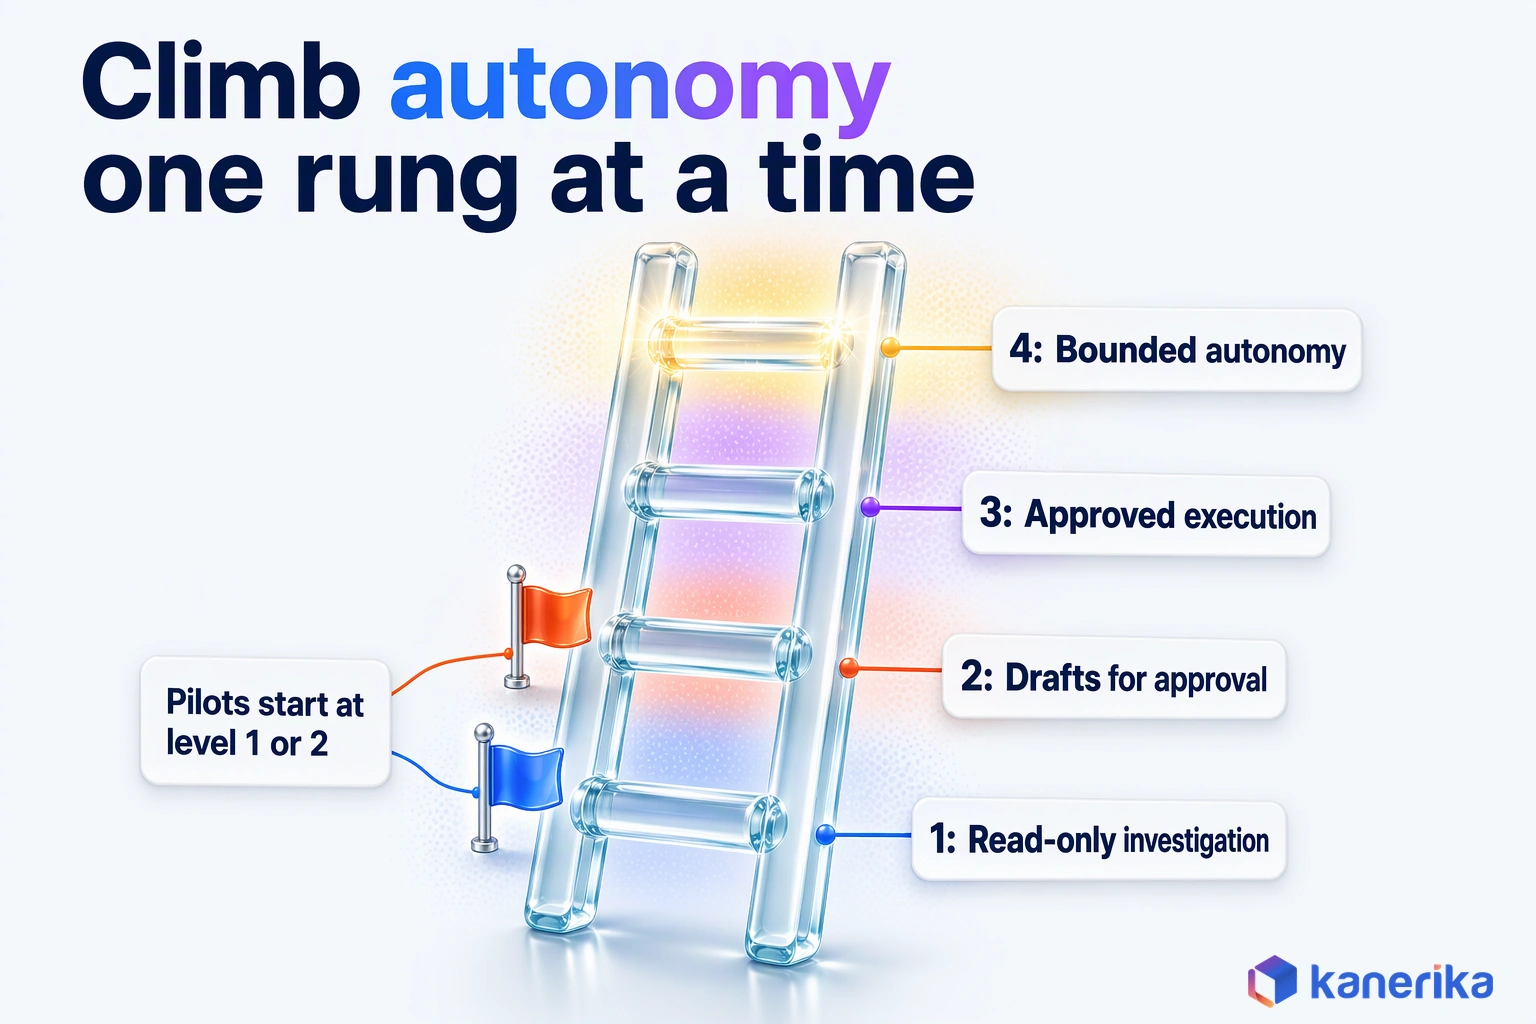
Platform choice and autonomy are, in practice, two different decisions. A team can run the most capable platform agent and still keep it read-only for months. Matching autonomy to the risk of each action is what keeps a pilot safe.
- Read-only investigation. The agent queries and explains, so nothing changes outside the conversation.
- Recommendations and drafts. The agent drafts tasks, emails or tickets, and a person sends them.
- Human-approved execution. The agent executes an action only after a named approver clicks yes.
- Bounded autonomy. The agent acts alone, but only on reversible, low-risk actions inside set limits, with every step logged.
Enterprise pilots generally belong at level 1 or 2. Move up one level at a time, and only when the agent’s answers have held up against analyst review.
Worked Decision: A Revenue Operations Team
Here is how a hypothetical revenue operations team would apply both decisions.
- Situation. Bookings live in Power BI, while pipeline sits in the CRM and contract terms in the ERP.
- Need. Explain weekly pipeline changes before the Monday review.
- Pick. An orchestration layer that calls the Power BI semantic model and the CRM, at autonomy level 2.
- Rejected. The Power BI agent alone, because it cannot see CRM deal history.
- Pilot boundary. One region with read access only, so drafts go to the operations lead.
- Advance condition. Analysts agree with the agent’s explanations across a full quarter of weekly reviews.
- Fallback. If accuracy stalls, keep the analyst workflow and fix pipeline-stage definitions first.
Governance, Risk and Evaluation
Governance for an analytics agent means the controls that decide what it can see, what it can do and how you prove what it did. The most important design choice is to keep those controls outside the model. After all, a prompt that says “do not show salary data” is a request, while row-level security is a rule.
Microsoft’s stack shows what that looks like in practice. Fabric IQ answers questions while respecting row-level and object-level security, so a regional manager sees only their region’s rows. Fabric data agents run under the user’s own Entra ID identity, and their generated queries cannot change data. Purview controls that audit prompts and responses are in preview, and our Microsoft Purview guide covers the wider setup.
The NIST AI Risk Management Framework, released January 26, 2023, is a sensible voluntary reference. NIST then added a Generative AI Profile, NIST-AI-600-1, on July 26, 2024. For wider program design, see our guides to responsible AI and AI governance best practices.
A practical baseline for any production pilot looks like this:
- Identity-aware access, so the agent queries with the user’s own permissions.
- Separate read and write paths, with write tools switched off by default.
- Approval gates on every action that changes a record or sends a message.
- Audit logs of each prompt, query, result and action.
- Abstention, so the agent says “I can’t confirm this” instead of guessing.
Failure Modes and the Control for Each
Each failure below is a known risk for analytics agents. Each also has a control that does not depend on the model behaving well.
| Failure mode | What goes wrong | Control |
|---|---|---|
| Wrong metric | The agent picks a column that looks right but is not the governed measure | Query only certified semantic-model measures |
| Data exposure | A user sees rows they are not entitled to | Row- and object-level security enforced at the data layer |
| Prompt injection | Text inside data or documents redirects the agent | Treat retrieved text as data, then restrict tools and review actions |
| Wrong action | A task or update goes to the wrong owner | Approval gates and reversible actions only |
| Stale data | The answer uses yesterday’s load as if it were live | Show data freshness in every answer |
| Runaway queries | Loops of expensive queries consume capacity | Step limits, query timeouts and cost caps |
| Silent drift | Accuracy slips after a model, schema or tool change | Re-run the test question set after every change |
How to Test Agent Answers Before Go-Live
Testing an analytics agent works best when you already know the right answers. The method is plain but disciplined:
- Collect 50 to 100 real questions the business asked in the past, along with the answers analysts gave.
- Group them by class, such as simple lookups, comparisons and multi-step investigations.
- Run every question through the agent, then have analysts mark each answer correct, partly correct or wrong.
- Set your own pass bar for each class, stricter for anything that feeds a financial decision.
- Re-run the full set whenever the model, the schema or the agent’s tools change.
For metrics and methods beyond answer accuracy, see our AI agent evaluation framework.
Checklist
Agentic AI Readiness Checklist
Check data foundations, access rules and controls before an agent touches production with Kanerika’s agentic AI readiness checklist.
Get the Checklist →Data Residency and Private Deployment
Before a pilot, map where prompts, query results and logs travel. Platform-native agents run inside your existing tenant and capacity, which simplifies residency reviews. Check the AI settings too, though: Fabric data agents, for example, may require cross-geo processing for AI to be switched on in some regions. A custom agent that calls an external model needs a full data review, though. That review should cover where logs are stored and for how long.
What Agentic BI Costs to Run, and Who Owns It
Running an analytics agent costs more than the license line suggests, because people and preparation make up much of the spend. The main cost drivers fall into five groups, and none of them is optional.
| Cost driver | What it covers |
|---|---|
| Platform capacity or consumption | The compute your BI or data platform bills for agent queries |
| Model calls | Language model usage for planning, reasoning and answers |
| Semantic-model work | Defining, certifying and documenting the measures the agent uses |
| Evaluation | Building and re-running the historical question set |
| Review time | Analysts checking answers and approvers checking actions |
For that reason, a useful unit is cost per accepted investigation. To get it, add delivery, run and review costs, then divide by the investigations whose answers people actually accepted. Rejected answers still cost money, so the measure rewards accuracy rather than volume.
A hypothetical example shows the time side. Suppose an agent handles 100 investigations a month that each took an analyst 45 minutes. In that case it frees up 75 analyst hours, before review time comes off that figure.
Ownership needs three named roles. In the business, a metric owner approves each definition; in the data team, an agent owner runs the tools, tests and limits; and an analyst reviewer checks answers during the pilot.
A Staged Rollout Plan for Agentic BI
A staged rollout keeps the first agent small enough to test and safe enough to trust. Each stage below has an exit criterion, and the agent moves on only when it meets it.
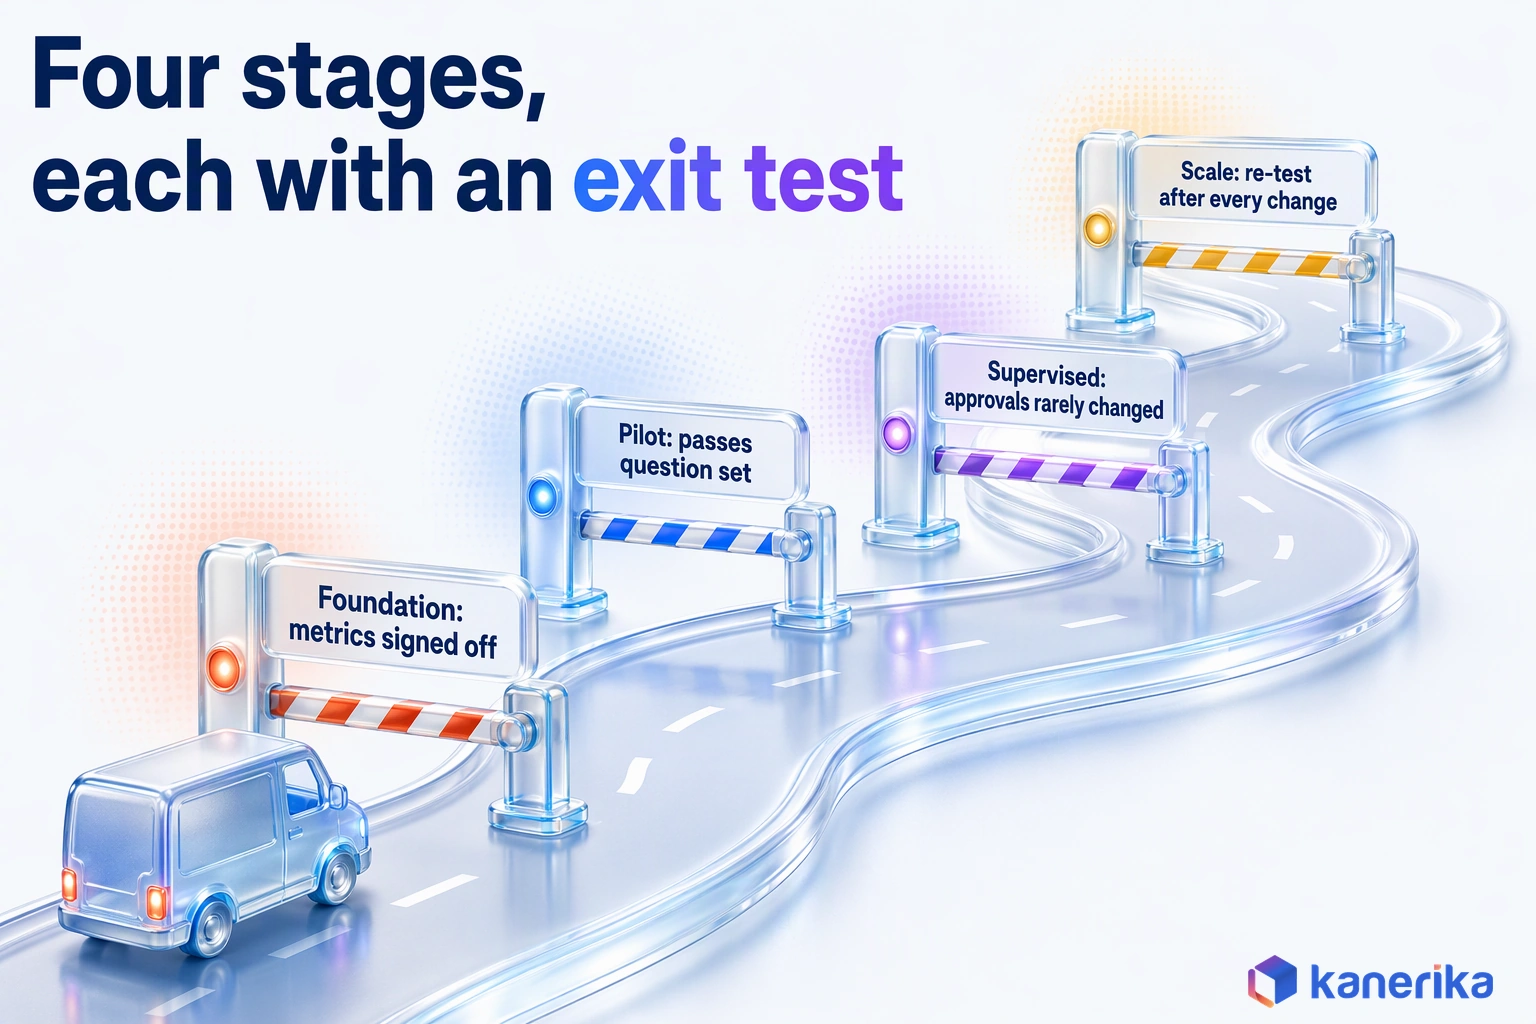
Stage 1, foundation. Pick one investigative workflow and certify the measures it depends on. This is usually where data transformation work shows up, because definitions often live in scattered SQL. Set access rules at the data layer, then exit once the metric owner signs off and permissions are tested.
Stage 2, advisory pilot. Run the agent read-only for a small group, measured against the historical question set. Exit when answers meet the pass bar for each question class. On Fabric, keep testing in the draft version, because publishing creates a separate copy that colleagues query. Git integration and deployment pipelines then promote the agent from development to test and production.
Stage 3, supervised actions. Turn on drafts and human-approved actions for the same workflow. Exit when approvers rarely change what the agent proposes and every action is logged.
Stage 4, bounded autonomy and scale. Allow reversible, low-risk actions within limits, then add the next workflow, which starts again at Stage 1. Exit is ongoing, so the question set is re-run after every change.
Two shortcuts undermine this plan. One is skipping Stage 1 because a demo looked impressive on sample data. The other is widening the scope mid-pilot, since you then cannot tell whether accuracy changed because of the agent or the new questions.
Keep the evidence from each stage in one place, including test results, approval logs and sign-offs. That way, the metric owner and the risk team can review it before the next stage begins.
How Kanerika Delivers Agentic BI
Kanerika builds analytics agents that work inside a client’s existing data platform and governance. Our core tool is Karl, a data analytics AI agent that lets business users ask questions of their data in plain language. According to Kanerika, Karl users see 62% time saved on data analysis, 5x faster business decisions and a 78% increase in team efficiency.
Our delivery method follows the rollout stages above. We start with discovery of one investigative workflow, build the metric and access foundation, and then run a read-only pilot against a historical question set. Supervised actions come next, and scale follows.
Kanerika is a Microsoft Solutions Partner for Data and AI with the Analytics Specialization. Our agentic AI services and data analytics services cover the full path, from metric foundations to production agents.
Challenge. A leading UK-based manufacturer and distributor of building products ran inventory on Microsoft Navision. Its Item Ledger Entries used coded fields, so business teams relied on technical staff to write SQL for every inventory question.
What we built. Kanerika trained Karl on the company’s transaction data and business logic. A Data Dictionary also translated coded ERP fields into business terms, so users could ask questions in their own words.
Result. Weekly reconciliation time fell by 20 to 30%, and time-to-insight was cut by over 50% through natural-language queries. Karl also detected 10+ recurring variance patterns automatically, so teams could act on the top 5 to 10 mismatch drivers. The full case study describes the setup.
Case Study
30% Faster Inventory Reconciliation with Karl
A UK building products manufacturer and distributor used Karl and a Data Dictionary over Microsoft Navision data to cut time-to-insight by over 50% and detect 10+ recurring variance patterns automatically.
Read the Case Study →Is Agentic BI Replacing the Dashboard? The Short Answer
Yes for investigation, but no for monitoring. An agent is the better tool when someone needs the reason behind a change. A dashboard still wins when someone only needs to watch a known number.
The practical move is to take one recurring investigation, such as a weekly variance review, and run an agent on it in read-only mode. Certify the measures it needs, test it on past questions and let analysts judge the answers. If it holds up, that workflow no longer needs its drill-down dashboard.
So agentic BI replaces the dashboards built for digging, while the dashboards built for watching stay exactly where they are.
Frequently Asked Questions
What is the meaning of agentic BI?
Agentic BI is business intelligence in which an AI agent works toward an analytical goal on its own. It plans the analysis, queries governed data, reasons over the results and proposes or takes an action under rules people set. A dashboard shows that a number moved, while an agent investigates why it moved and suggests what to do.
Does Power BI have agentic AI?
Yes. Copilot in Power BI requires paid Fabric F2 or Premium P1 capacity, and its report pane is generally available while a standalone Power BI agent is in preview. Microsoft also offers Power BI MCP servers, including Fabric IQ, which lets custom agents and Copilot Studio answer questions over semantic models while respecting row-level and object-level security.
What is the biggest reason agentic BI fails in production?
The risk to address first is weak data foundations, especially conflicting or undocumented metric definitions. An agent cannot pick the right measure if three teams define revenue differently, so it repeats the confusion faster. Gartner also points to rising costs, unclear business value and weak risk controls as the reasons it expects many agentic projects to be canceled.
Does agentic BI replace data analysts?
No. It changes what analysts spend time on. Agents take over repetitive slicing and cross-checking for recurring questions, while analysts frame new problems, certify metric definitions, review agent answers and judge edge cases. During a pilot, analysts are also the reviewers who decide whether the agent’s answers are good enough to move to the next stage.
How long does it take to deploy agentic BI?
Timing depends on the state of your data more than on the agent. A team with certified semantic models can move quickly to a read-only pilot, while a team with conflicting definitions must fix those first. Plan in stages covering foundation, advisory pilot, supervised actions and bounded autonomy, and advance only when each exit criterion is met.
What is the Power BI MCP Server and why does it matter?
Microsoft now provides two Power BI MCP servers. The Authoring server creates and changes semantic models, and Fabric IQ answers natural-language questions over semantic models and ontologies while respecting row-level and object-level security. They matter because any MCP-compatible agent can use the same governed definitions and permissions that Power BI reports already rely on.
How is agentic BI different from generative BI?
Generative BI produces content, such as written report summaries, narratives or generated visuals, usually in response to a request. Agentic BI pursues a goal through several steps, deciding which queries to run, checking other systems and proposing actions for approval. Generative output is often one part of an agent’s answer, but the agent also plans and acts.
What does agentic BI cost to run?
Costs come from five areas, which are platform capacity or consumption, language model calls, semantic-model work, evaluation and human review time. A useful measure is cost per accepted investigation, meaning delivery, run and review costs divided by the investigations people accepted. That measure rewards accuracy, because rejected answers still consume capacity and analyst time.
Which platforms support agentic BI today?
Microsoft Fabric and Power BI offer Fabric data agents, Copilot and Power BI MCP servers. Databricks offers Genie, governed through Unity Catalog. Snowflake offers Cortex Analyst, which relies on semantic models and semantic views. Looker offers Conversational Analytics with data agents. Teams can also build custom agents over the open Model Context Protocol.
How do you test agentic BI answers before go-live?
Collect 50 to 100 real questions the business asked before, along with the answers analysts gave. Group them by type, run each through the agent and have analysts mark every answer correct, partly correct or wrong. Set a pass bar for each question type, and re-run the full set after any model, schema or tool change.
Is BI replaced by AI?
No. AI replaces part of BI work rather than BI itself. Agents take over investigative tasks such as variance analysis and exception triage, where an analyst used to slice data for hours. Monitoring dashboards, regulated reports and executive scorecards stay, because they need fixed, approved logic and are faster to read at a glance than any conversation.
Is agentic AI already in use?
Yes. Microsoft lists the Fabric data agent as generally available, Databricks offers Genie, Snowflake offers Cortex Analyst and Looker offers Conversational Analytics with data agents. Gartner expects agentic AI in 33% of enterprise applications by 2028, but it also warns that only about 130 of the thousands of vendors claiming agentic AI are genuine.
What are the 4 pillars of BI?
BI is commonly described through four pillars, which are data collection, data storage and integration, analysis, and reporting or visualization. Agentic BI adds a fifth working layer on top of them. An agent uses the governed data and semantic models from the first three pillars to investigate questions, then hands results back through reports, alerts or drafted tasks.
What exactly is agentic?
Agentic describes software that pursues a goal through several steps instead of answering one prompt. An agentic system plans its work, calls tools such as databases or business applications, checks the results and decides what to do next. The level of independence varies, from read-only analysis through drafted actions to bounded autonomy inside approved limits.
How is agentic BI different from Copilot in Power BI?
Copilot in Power BI helps people author and understand reports, for example by summarizing a page, suggesting visuals or writing DAX. An analytics agent takes a goal such as explaining a bookings drop, decides which queries to run, checks other systems like the CRM and drafts follow-up tasks. Copilot assists a person, while an agent runs the investigation.
How does Microsoft Fabric support agentic BI?
Fabric data agents are generally available for conversational questions over lakehouses, warehouses, semantic models and KQL databases on paid F2 or Premium P1 capacity. Power BI MCP servers let agents create semantic models or query them through Fabric IQ. Purview controls for data agents, including audit of prompts and responses, are in preview according to Microsoft documentation.
Is agentic BI accurate enough for enterprise use?
It can be, but accuracy depends on business context. On Spider 2.0’s 632 enterprise tasks, GPT-4o solved only 10.1% at release, against 86.6% on Spider 1.0. Top agents now pass 90% on the Snow setting, but Lite and DBT top out near 76% and 66%. A governed semantic layer and a tested question set make the real difference.
Is agentic AI different from AI?
Agentic AI is one kind of AI. Most AI tools respond to a single input, such as a prompt that returns text or a model that returns a forecast. Agentic AI adds planning, tool use, memory and action, so it can work through several steps toward a goal and act on the outcome within limits people approve.