TL;DR
For cloud data integration, match the tool to the job: batch loads for reports, change capture for busy databases. The goal is one shared copy of business data in a cloud warehouse. Daily finance reports run well on batch tools such as Fivetran. Stock and order data that changes by the minute needs change capture or mirroring. Live events need streaming, and apps that update each other need an app connector. Before you sign, test deleted records and add up the full monthly cost.
Key Takeaways
- Decide how fresh the data must be before you pick a tool, because freshness decides the pattern.
- Managed batch ELT is the sensible default for reporting, and CDC or mirroring earns its cost when rows change often.
- Test every connector on deletes, schema changes and a full historical reload before you sign.
- Price the whole flow, including target compute, network egress and monitoring time, as well as the connector licence.
- Hybrid estates need an integration runtime inside your own network, such as the Azure Data Factory self-hosted integration runtime.
- Settle access, PII handling and ownership before the first pipeline reaches production.
The Board Pack With Two Revenue Numbers
Picture the Monday before a board meeting. Finance has pulled an ERP export into a spreadsheet, while sales has run its own revenue report from the CRM.
Both teams are confident, and the two revenue figures in the board pack still do not match. Nobody made a mistake. The ERP export ran at 6 a.m., the CRM report ran at noon, and then a batch of cancelled orders was deleted in between.
That gap is exactly what cloud data integration closes. It gives every team the same records, refreshed on a known schedule, in one governed place, so the numbers finally agree.
This guide explains how it works, which patterns and tools fit which use cases, what it costs and how to choose.
What Is Cloud Data Integration?
Cloud data integration is the process of combining data from many sources in a cloud warehouse or lakehouse. The work runs on managed cloud services instead of servers you own. As a result, reports, apps and AI models can all share one consistent copy of business data.
Take a mid-size distributor, for example. Its orders live in an on-premises SQL Server database, its sales pipeline lives in Salesforce, and its online store runs on Shopify.
A cloud integration service pulls from all three on a schedule and lands the raw records in a cloud warehouse. Then it joins them, so one customer has one order history.
The idea is older than the cloud. What changed is who runs the plumbing. Traditional on-premises integration ran on fixed servers that the team sized and patched, with connectors it maintained itself. In the cloud model the vendor maintains the connectors and the compute, so the team can spend its time on the data itself.
What Makes an Integration “Cloud”
An integration counts as cloud when most of the moving parts are rented and run for you. In practice, five traits usually show up together.
- Managed runtime: the vendor runs and patches the engine that moves the data.
- Cloud target: data lands in a cloud warehouse or lakehouse instead of an on-premises database.
- Elastic compute: capacity grows for a large backfill and then shrinks again.
- Consumption billing: you pay per row, per hour or per unit of compute, so there is no fixed server to size.
- Vendor-maintained connectors: when a SaaS API changes, the vendor updates the connector.
A hybrid setup still counts. The runtime may sit inside your network to reach an old ERP, while the target and the control plane live in the cloud.
Cloud Data Integration vs ETL, Ingestion, Migration and iPaaS
These terms often get used as if they mean the same thing, and that confusion shows up later in project scopes. Each one describes a different slice of the work, so it helps to separate them before you buy anything.
| Term | What it covers | When you need it |
|---|---|---|
| Cloud data integration | Combining many sources into one consistent, governed dataset in the cloud | Shared reporting, analytics and AI on joined data |
| ETL / ELT | The order of the extract, transform and load steps inside a pipeline | Every integration uses one; ELT is the usual cloud choice |
| Data ingestion | Moving raw data from a source into a landing zone | The first step of integration, often automated |
| Data migration | A one-time move from an old system to a new one | Replatforming, then switching the old system off |
| iPaaS | Connecting applications so they trigger and update each other | App-to-app workflows such as order-to-invoice |
Kanerika’s guides on data integration vs ETL, data ingestion vs data integration and data migration vs data integration go deeper on each pair. In short, integration is the ongoing discipline, and the other terms are parts of it or one-off projects beside it.
How Cloud Data Integration Works, Step by Step
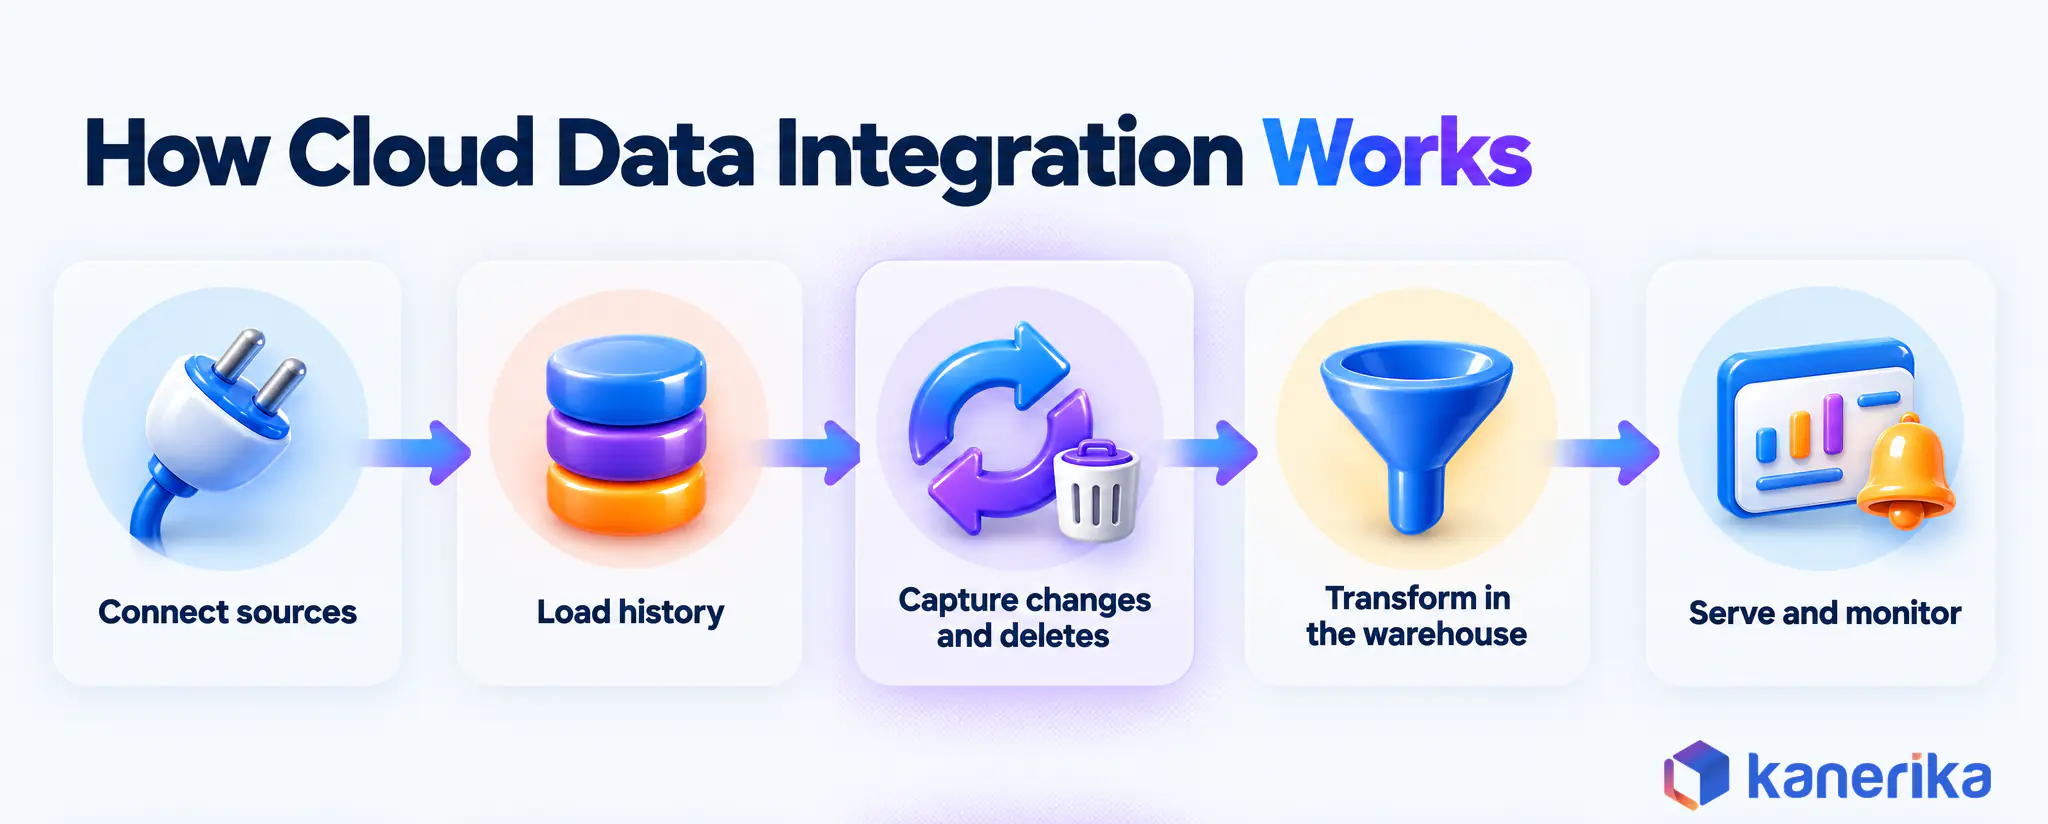
Every cloud integration follows the same basic life cycle, whatever tool runs it. The steps below are also where projects either hold together or quietly drift.
The step teams skip most often is the one that carries deletes. A standard incremental pull asks a source for rows that are new or changed since the last run. A deleted row is neither, so it never arrives, and the warehouse keeps counting it.
- Connect and authenticate. Register each source with a service account or managed identity, and keep the secret in a vault.
- Run the initial historical load. Copy the full history once, in chunks, and record row counts per table.
- Switch to incremental loads or CDC. Pick up only new and changed rows, and confirm that deletes travel too.
- Land raw data first. Write source records unchanged into a raw zone, which is the ELT pattern.
- Transform into business records. Apply data transformation inside the warehouse to join, clean and deduplicate, so one order means one order.
- Serve the output. Publish governed tables to BI, applications and AI workloads.
- Monitor freshness and failures. Alert when a table is late, empty or suddenly smaller than it was yesterday.
Kanerika ran into the delete problem directly on a QAD ERP project for a global manufacturer. Standard pulls missed deleted records and also slowed down on the largest tables. For that reason, the final design used change-aware replication, which the section on how Kanerika delivers describes.
Scheduling, retries and alerting across these steps are where automated data integration pays off. The same steps also form the front half of any data analytics pipeline that feeds dashboards.
Integration Patterns: Batch ELT, ETL, CDC, Streaming, API/iPaaS and Zero-Copy
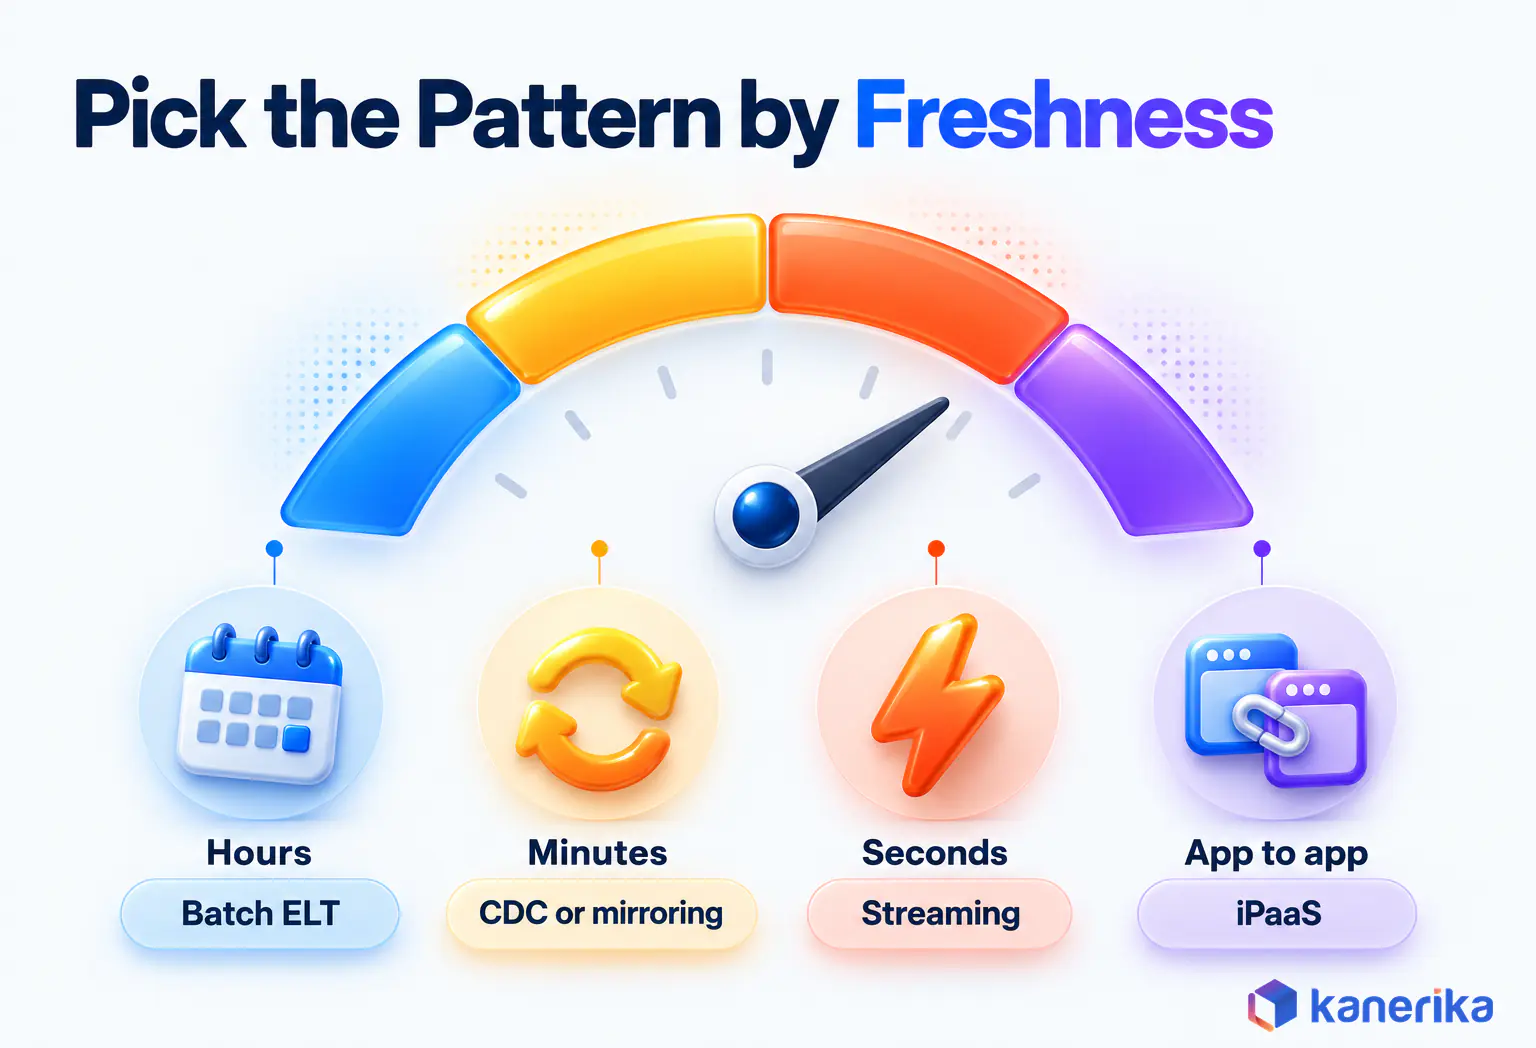
A pattern is the way data travels from source to target, and it matters more than the brand of tool. So the useful question is simple: how fresh must the data be when someone uses it?
Two ideas often get mixed up here. ETL and ELT describe where the transformation happens, before loading or after it. Batch and streaming describe timing, on a schedule or continuously.
That means CDC can feed an ELT design, and a streaming job can still transform data before it loads.
Choosing Between the Patterns
For most reporting, batch ELT is the sensible default. It is cheap to run and easy to rerun, because the cloud warehouse does the heavy transformation. The ETL vs ELT guide covers that trade-off in more depth.
| Pattern | Use it when | Trade-off | What to test |
|---|---|---|---|
| Batch ELT | Reporting refreshes daily or hourly | Data is only as fresh as the last run | Full reload, late-arriving rows |
| ETL | Data must be masked or reshaped before it lands | More logic to maintain outside the warehouse | Transformation failures, safe reruns |
| CDC (change data capture) | Database rows change often and deletes matter | Needs log access on the source and careful ordering | Deletes, repeated updates to one row, replay after an outage |
| Streaming | Events such as clicks, sensor readings or payments need action in seconds | Higher running cost and harder debugging | Late and out-of-order events, duplicates |
| API / iPaaS | Applications must trigger and update each other | Logic per workflow, weak for bulk history | Rate limits, retries, error queues |
| Zero-copy / mirroring | You want a continuously replicated copy without building pipelines | Limited to supported sources | Supported tables, latency, delete handling |
| Data virtualization | Light, ad hoc queries against sources in place, without copying data | Every query hits the live source, so it is weak for heavy history and large joins | Query latency, load on the source, permission pass-through |
Zero-Copy Mirroring in Microsoft Fabric
Mirroring deserves a closer look because it changes the build effort. Microsoft Fabric Mirroring continuously replicates data into OneLake, which Microsoft describes as low-cost and low-latency. Supported sources include Azure SQL, SQL Server, Snowflake, Oracle, Google BigQuery, SAP Datasphere, Cosmos DB and PostgreSQL.
For a source without a built-in option, open mirroring lets any developer write change data into a mirrored database through public APIs. The data then sits in the open Delta Lake format as part of a wider Microsoft Fabric estate.
Kanerika Service
Data Integration Services
Kanerika designs and builds cloud data integration on Microsoft Fabric, Databricks and Snowflake, from connector proofs on live data to monitored production pipelines.
Explore Data Integration ServicesDeployment Models: Cloud-to-Cloud, Hybrid and Multicloud
The deployment model answers a different question from the pattern: where does the integration engine run, and how does it reach your data? Choose it separately, because a single pattern can run in any of the three models.
Cloud-to-cloud is the simple case. For instance, a SaaS app such as Salesforce sends data to a cloud warehouse, and the vendor’s runtime handles both ends.
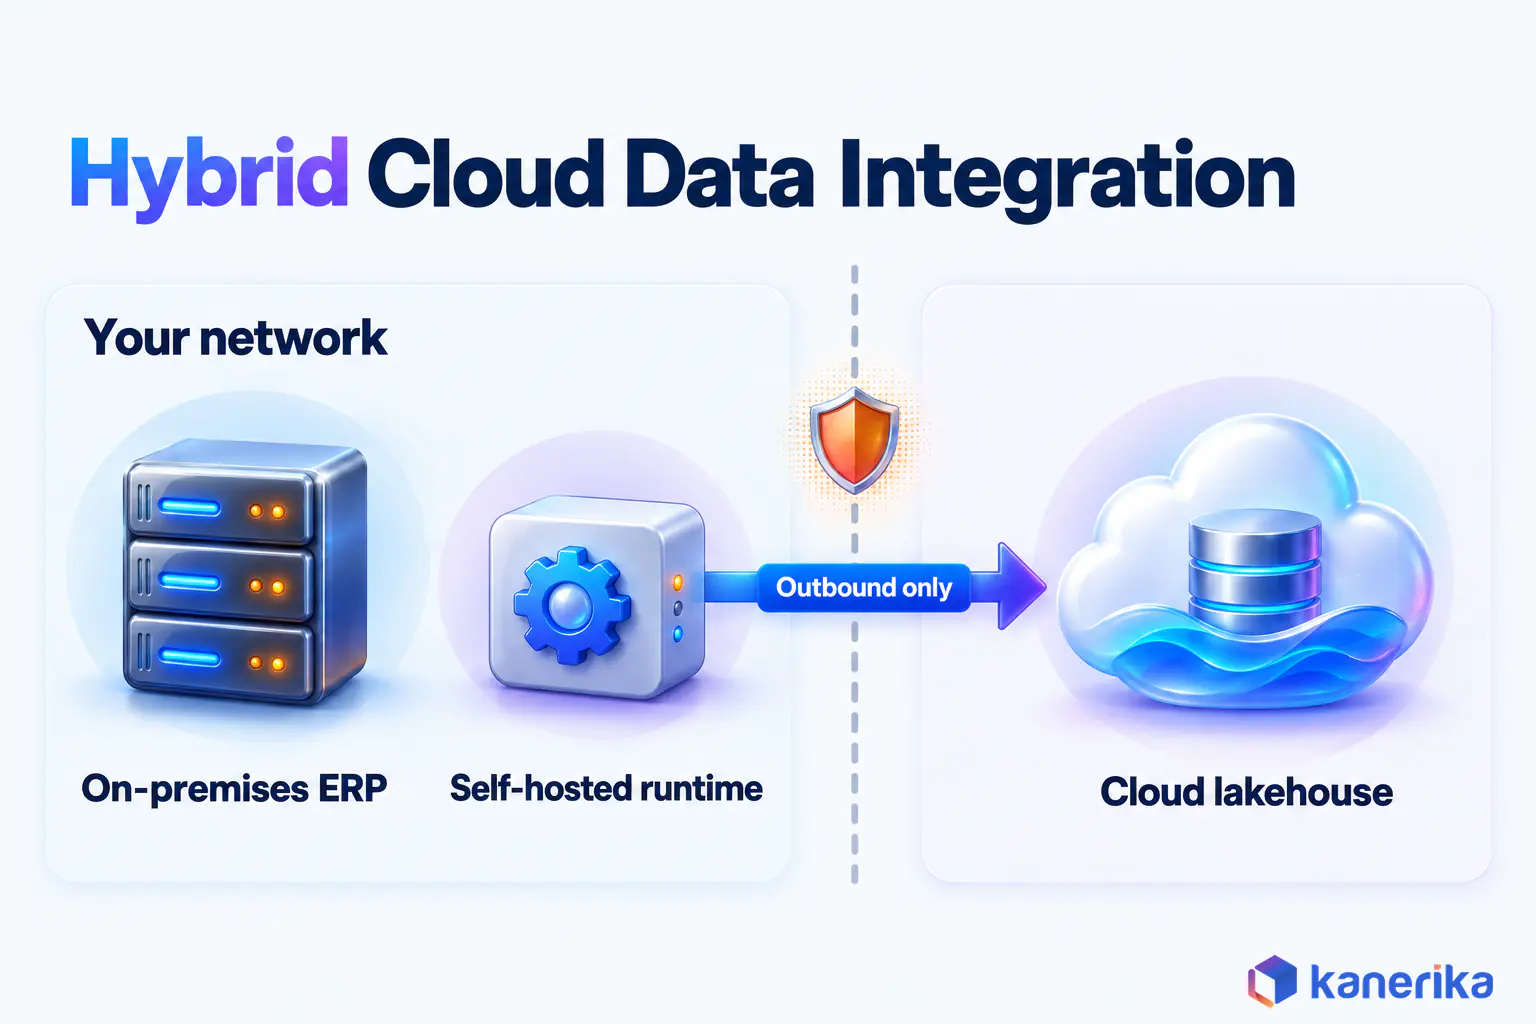
Hybrid is the common case for any company with an on-premises ERP. Since a database in a private data center is not reachable from the public internet, a small runtime is installed inside your network. Azure Data Factory calls this a self-hosted integration runtime, one of three runtime types alongside Azure and Azure-SSIS.
Multicloud adds a third twist. Data may start in AWS, land in a Snowflake account on Azure and then feed Power BI. In that case, egress fees and identity across clouds become design inputs.
| Model | Where the runtime runs | Network path | Who maintains it |
|---|---|---|---|
| Cloud-to-cloud | The vendor’s managed cloud | Public endpoints over TLS, or private links | The vendor |
| Hybrid | A self-hosted runtime on a machine inside your network | Outbound from your network to the cloud service | You run and patch the host machine |
| Multicloud | Managed runtimes in one or more clouds | Cross-cloud transfer, often billed as egress | Shared, with you owning cost and identity design |
Topology is the last layer to settle. Early integrations were often point-to-point scripts, one per pair of systems, so a growing estate collected dozens of fragile links. A hub-and-spoke design instead routes every source through one platform or iPaaS, which gives a single place to monitor, secure and change the flows.
Top Cloud Data Integration Tools, Grouped by Role
A shortlist is easier to build by role than by brand, because each tool is built for one kind of job. The table below lists eight cloud-native options across those roles, along with the billing model to check before you buy.
Platform alignment usually narrows the list fast. A team standardized on Microsoft Fabric looks first at Data Factory and Mirroring, while a Databricks or Snowflake shop starts with its own platform connectors.
The Shortlist by Role
| Tool | Role | Best fit | Pricing model to check | Source |
|---|---|---|---|---|
| Azure Data Factory / Fabric Data Factory | Orchestrated batch ETL and ELT | Microsoft estates, with hybrid sources reached through the self-hosted runtime | Check Microsoft’s pricing page at your volume | Microsoft Learn |
| Microsoft Fabric Mirroring | Zero-copy style continuous replication | Supported databases into OneLake with low latency | Described by Microsoft as low-cost; confirm for your sources | Microsoft Learn |
| AWS Glue | Managed ETL on AWS | AWS-centered lakes and warehouses | Per DPU-hour, $0.44, and the price varies by region | AWS Glue pricing |
| Google Cloud Dataflow | Unified stream and batch processing on Apache Beam | Event streams and large batch jobs on Google Cloud | Check Google Cloud pricing at your volume | Google Cloud docs |
| Databricks Lakeflow Connect | Managed ingestion connectors | Databases (CDC and query-based) and SaaS apps such as Salesforce, HubSpot, Jira and Workday into a lakehouse governed by Unity Catalog | Check Databricks pricing at your volume | Databricks docs |
| Snowflake Openflow + Snowpipe | Integration service built on Apache NiFi, plus continuous file loading | Snowflake accounts with structured and unstructured sources | Snowpipe: fixed credits per GB loaded; Openflow: check Snowflake pricing | Snowflake docs |
| Informatica IDMC (now part of Salesforce) | Enterprise integration and data management suite | Large, mixed estates with many source types | Quote from the vendor | Salesforce newsroom |
| Fivetran | Managed ELT connectors | Many SaaS sources and small data teams | Monthly active rows (MAR), with a Free plan up to 500,000 MAR | Fivetran pricing |
How the Cloud-Native Services Split
The three cloud-native services split along their home clouds. Data Factory orchestrates batch ETL and ELT for Microsoft estates, and its self-hosted runtime reaches sources behind the firewall. AWS Glue, by contrast, is the managed ETL engine on AWS, billed per DPU-hour. Google Cloud Dataflow runs stream and batch jobs on one Apache Beam model, which suits event streams on Google Cloud.
An independent tool is the better pick when your sources outgrow one platform’s connectors. Fivetran suits many SaaS sources and a small data team, while Informatica suits large, mixed estates with many source types.
Files, Streams and App-to-App Sync
Two rows need a word of context. Snowpipe loads files continuously, and its Snowpipe documentation notes that the data is typically queryable within minutes. Openflow, by comparison, runs in Snowflake deployments on AWS, Azure and Google Cloud commercial regions, with a bring-your-own-cloud option on AWS.
App-to-app sync is a separate category. Tools in the iPaaS group, such as Boomi and MuleSoft, connect apps through APIs and workflows. These tools sit beside the ones above rather than replacing them.
For a wider vendor list with feature detail, see the full comparison of data integration tools. A head-to-head of three common choices sits in the Informatica vs Azure Data Factory vs Talend guide.
Checklist
Data Integration Checklist
A downloadable checklist to plan a data integration project and check each connector and control before go-live.
Get the Checklist →What a Connector Must Prove Before You Buy
A demo connector always works on a clean sample table, especially one the vendor picked. So ask for a proof on your own data instead, and score each item below as pass or fail.
- Updates: a changed row arrives once, with the newest values.
- Deletes: a deleted source row is removed or flagged in the target.
- Schema drift: a new or renamed column does not break the load.
- Historical reload: a full backfill runs without duplicating rows.
- Outage recovery: after a stop, the connector replays from where it left off.
- Source load: extraction does not slow the production database at peak hours.
- Cost at your volume: the quote uses your real row counts or compute hours.
- Monitoring: run logs, row counts and alerts you can route to your on-call channel.
A connector that fails on deletes or replay can look fine for weeks, but then it starts a reconciliation fight. Treat those two as hard stops.
Cloud Data Integration Use Cases
Use cases are where the pattern and tool choices finally become concrete. Each scenario below pairs a common business need with the pattern that fits it and example tools from the shortlist above.
| Scenario | Pattern | Example tools | Why |
|---|---|---|---|
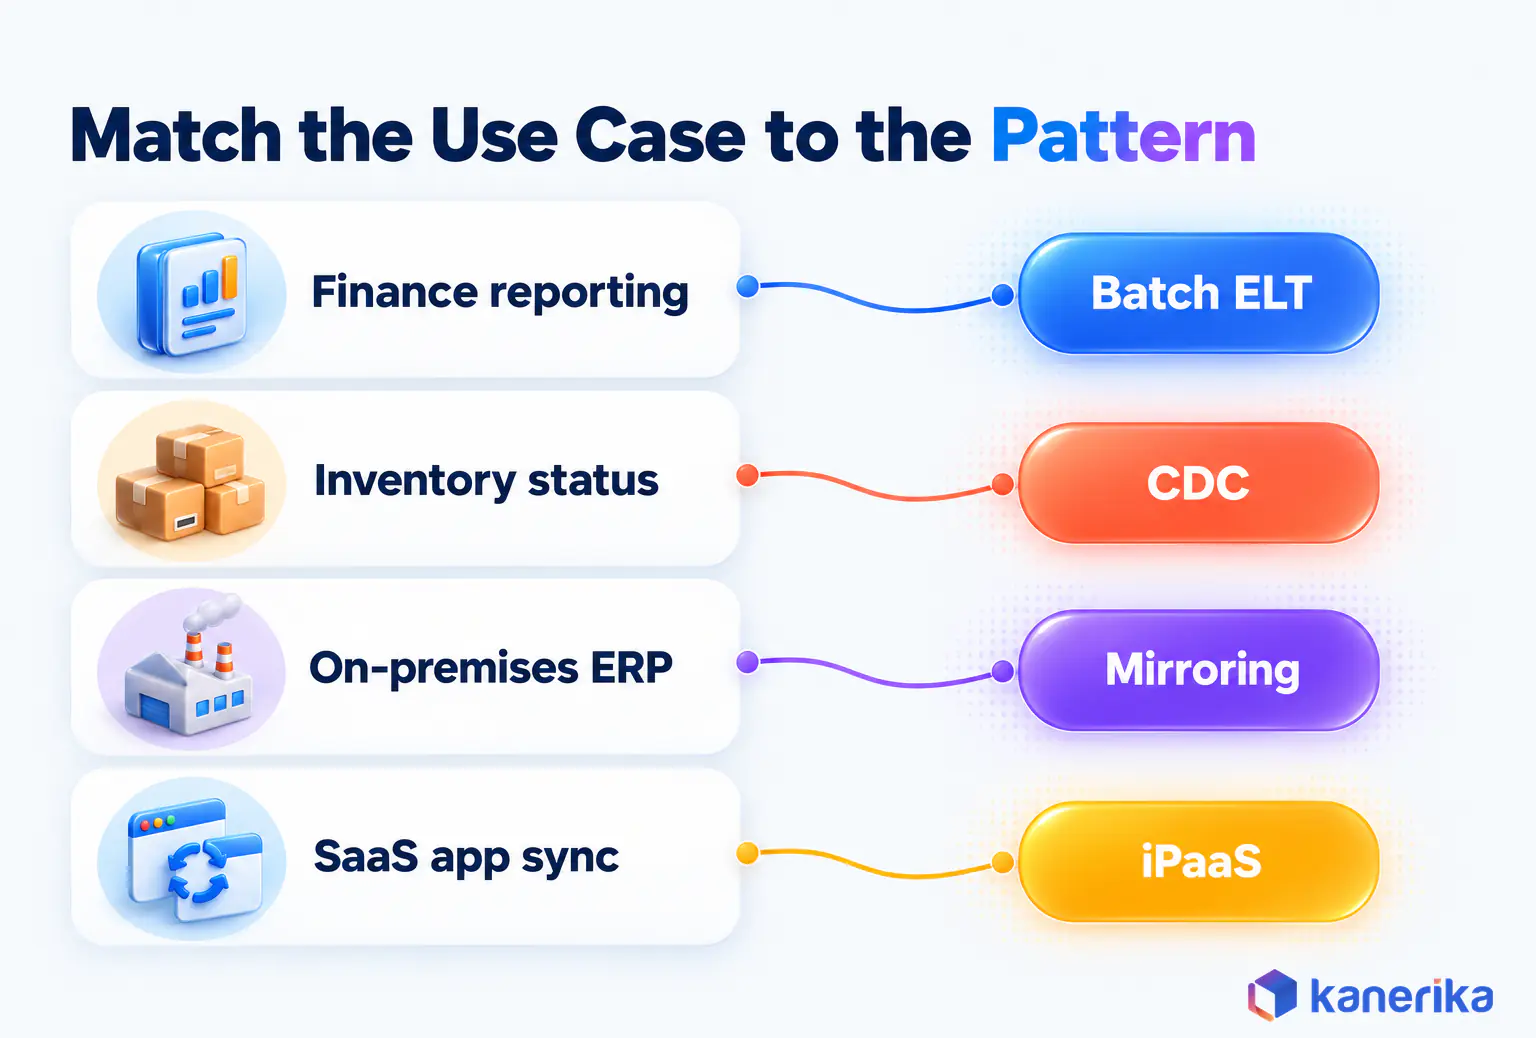
| Finance and management reporting | Batch ELT | Fivetran, Data Factory, AWS Glue | A daily or hourly refresh is enough, and reruns are cheap |
| Inventory and order status | CDC | Fabric Mirroring, Lakeflow Connect database connectors | Rows change constantly and deletes matter |
| On-premises ERP into a lakehouse | Hybrid runtime or mirroring | Data Factory self-hosted runtime, open mirroring | The source sits behind the firewall |
| SaaS sync and reverse ETL | API / iPaaS | An iPaaS such as Boomi or MuleSoft | Apps need to update each other |
| Governed data for AI and RAG | Incremental loads plus access control | Lakeflow Connect (Unity Catalog) or Openflow | Models must not answer from stale or deleted data |
| Legacy ETL modernization | Batch ELT or ETL rebuilt in the cloud | Fabric Data Factory, AWS Glue | Old servers and licences can retire |
Consolidated Finance and Management Reporting
Monthly close needs numbers that agree, and it rarely needs them by the second. A batch ELT flow pulls the general ledger, billing and CRM each night, lands them raw and then builds reporting tables in the warehouse.
When a load fails, the team simply reruns it the next morning with little risk. This pattern also ends the two-revenue-numbers problem from the opening scenario, because every report now reads from the same tables. Managed ELT connectors or Data Factory pipelines usually cover it, and cost stays predictable since the schedule is fixed.
Near-Real-Time Inventory and Order Status
Inventory is the classic case for change data capture. Stock levels and order states change all day, so a nightly batch leaves customer service quoting yesterday’s numbers. A CDC connector instead reads the database change log and sends each insert, update and delete within minutes.
The hard part is deletes and ordering. When a cancelled order is deleted at the source, it must also disappear from the dashboard. Two updates to the same row must land in the right sequence as well. Test both before go-live, since these are the defects users notice first.
Two settings prevent most of those defects. On the source, keep transaction log retention longer than the longest outage you expect, or the connector loses its place and needs a full resync. On the target, apply changes in commit order using the log sequence number, not the arrival time.
On-Premises ERP into a Cloud Lakehouse
Many manufacturers still run their ERP in their own data center. Because the integration engine has to reach it from inside the network, a self-hosted runtime or mirroring agent sits next to the database.
Large ERP schemas also raise two more issues. Hundreds of tables need connecting without hand-building each pipeline, and the busiest tables must not slow the system that runs the plant. Open mirroring suits this case because changes are written into the lakehouse as they happen, which avoids repeated full scans.
SaaS Application Sync and Reverse ETL
Some integrations run in the other direction. For example, sales wants a customer health score from the warehouse inside the CRM, while support wants order status inside its ticketing tool.
This is reverse ETL, or app-to-app data synchronization, and it usually runs through an iPaaS or a dedicated reverse-ETL tool. API limits are the main constraint here, so plan for them early. Each SaaS API caps how many calls you can make, so a sound API integration design batches updates and queues failures for retry.
Governed Data for AI and RAG
AI assistants and retrieval-augmented generation (RAG) apps answer from whatever data they are given. So if a policy document is withdrawn or a customer asks for deletion, the integration layer must remove that record from the index too.
That is why incremental loads, delete handling and access control matter more here than raw speed. Treat the AI pipeline as another governed consumer that reads from the same certified tables as BI. Row-level rules then apply before data reaches a model. The guide to cloud analytics tools shows how that shared layer also serves reporting.
Modernizing Legacy ETL into Cloud Pipelines
Older estates often run hundreds of SSIS packages or Informatica PowerCenter mappings on servers that are expensive to keep. Modernization rebuilds those flows on a cloud service, usually as ELT, and then retires the old servers and licences.
Treat it as a migration and an integration at once. First inventory every package, then decide which to rebuild, merge or drop, and run old and new side by side until the outputs match. Compare row counts and totals per table on each parallel run, so a mismatch points to one package instead of the whole estate. The episode below discusses why Fabric is becoming a common destination for SSIS migrations.
Benefits of Cloud Data Integration
The benefits are easiest to see from the business side, so start there. When every team reads from one integrated copy, meetings stop being about whose number is right.
Poor data also carries a real price. Wrong figures lead to wrong stock orders, missed invoices and hours lost reconciling reports. Those costs rarely appear as one line in a budget, which is why they go unfixed for so long. Integration alone does not fix quality, but it creates the single place where quality rules can run.
Take the board pack with two revenue numbers from the opening. Once finance, sales and operations read the same certified tables, the 6 a.m. ERP export and the noon CRM report can no longer disagree. Scheduled loads also replace the manual exports and spreadsheet merges that produced two numbers in the first place. Analysts also stop rebuilding the same merge in a spreadsheet every month, so their time goes to the questions behind the numbers.
The same tables matter for AI. An assistant that reads governed, current data gives the answer finance would give. One fed from stale exports simply repeats the old revenue argument, only faster.
None of these arrive on their own, though. They depend on the pattern, the tests and the ownership choices covered in the rest of this guide.
What Cloud Data Integration Costs
Cloud integration is billed by use, so the cost follows your data volume and your design choices. The connector licence is only one line of the bill, and it is often not the largest.
Pricing units differ by vendor, which makes quotes hard to compare. For instance, Fivetran prices on monthly active rows (MAR) and has a Free plan up to 500,000 MAR. AWS Glue bills ETL jobs at $0.44 per DPU-hour, although the price varies by region.
AWS also gives its own worked example. A Glue job that runs on 6 DPUs for 15 minutes uses 1.5 DPU-hours. At $0.44 per DPU-hour, that job costs $0.66.
Run that job every 15 minutes and it runs 96 times a day. At $0.66 a run, that comes to about $63 a day, or roughly $1,900 a month at the $0.44 rate. The figure is illustrative and excludes target compute, so the schedule is a cost decision as well as a freshness one.
Talk to Kanerika
Want a Cost Model for Your Own Sources?
Kanerika maps your sources, freshness needs and volumes to a pattern and a full running-cost estimate before you commit to a tool.
Book a Working Session →| Cost driver | How it is billed | How to control it |
|---|---|---|
| Connector or licence | Per row (MAR), per DPU-hour or per subscription | Sync only the tables and columns you use |
| Target compute | Warehouse or lakehouse compute for transforms and queries | Incremental models, auto-suspend, right-sized clusters |
| Network egress | Per GB of data leaving a cloud or region | Keep source, runtime and target in the same region where you can |
| Self-hosted runtime hosts | Machine cost inside your network | Size for peak loads and share hosts across pipelines |
| Engineering and monitoring time | Staff hours | Standard templates, alerts and clear ownership |
The business case behind these numbers, such as build versus buy, is covered in the guide to enterprise data integration methods and costs.
Challenges, Security and Governance
Integration failures tend to be quiet. A pipeline keeps running and the dashboard keeps loading, while the numbers drift until someone in finance notices.
Picture the board pack from the opening. A CRM admin renames a revenue column, the connector stops loading it, and the sales table keeps refreshing without that field. No job fails, so the gap only surfaces days later when finance cannot reconcile the month.
Security adds a second layer of risk. Data in motion often includes customer and employee PII, and each connector also holds a credential that can read a production system. Give every risk a named owner, because a control without an owner lapses.
| Risk | Control | Owner |
|---|---|---|
| Leaked credentials | Managed identities, secrets in a vault, regular rotation | Platform team |
| PII in transit | TLS everywhere, with masking or tokenization before landing | Data security lead |
| Schema drift | Schema-change alerts and contract tests | Data engineering |
| Silent failures | Freshness, row-count and volume alerts | Pipeline owner |
| Duplicate loads | Idempotent merges keyed on business IDs | Data engineering |
| Residency and compliance | Region pinning and a data-flow map per regulation | Compliance and legal |
| Cost overrun | Budgets, alerts and per-pipeline cost tags | FinOps or platform owner |
Regulation follows the data wherever it travels. So map which personal data crosses which region before you decide where the runtime and the target live. Otherwise, data sovereignty rules can rule out a region late in the project.
For the policy side, see the guides on data security, GDPR and CCPA compliance and data governance principles.
How to Choose: A Decision Framework
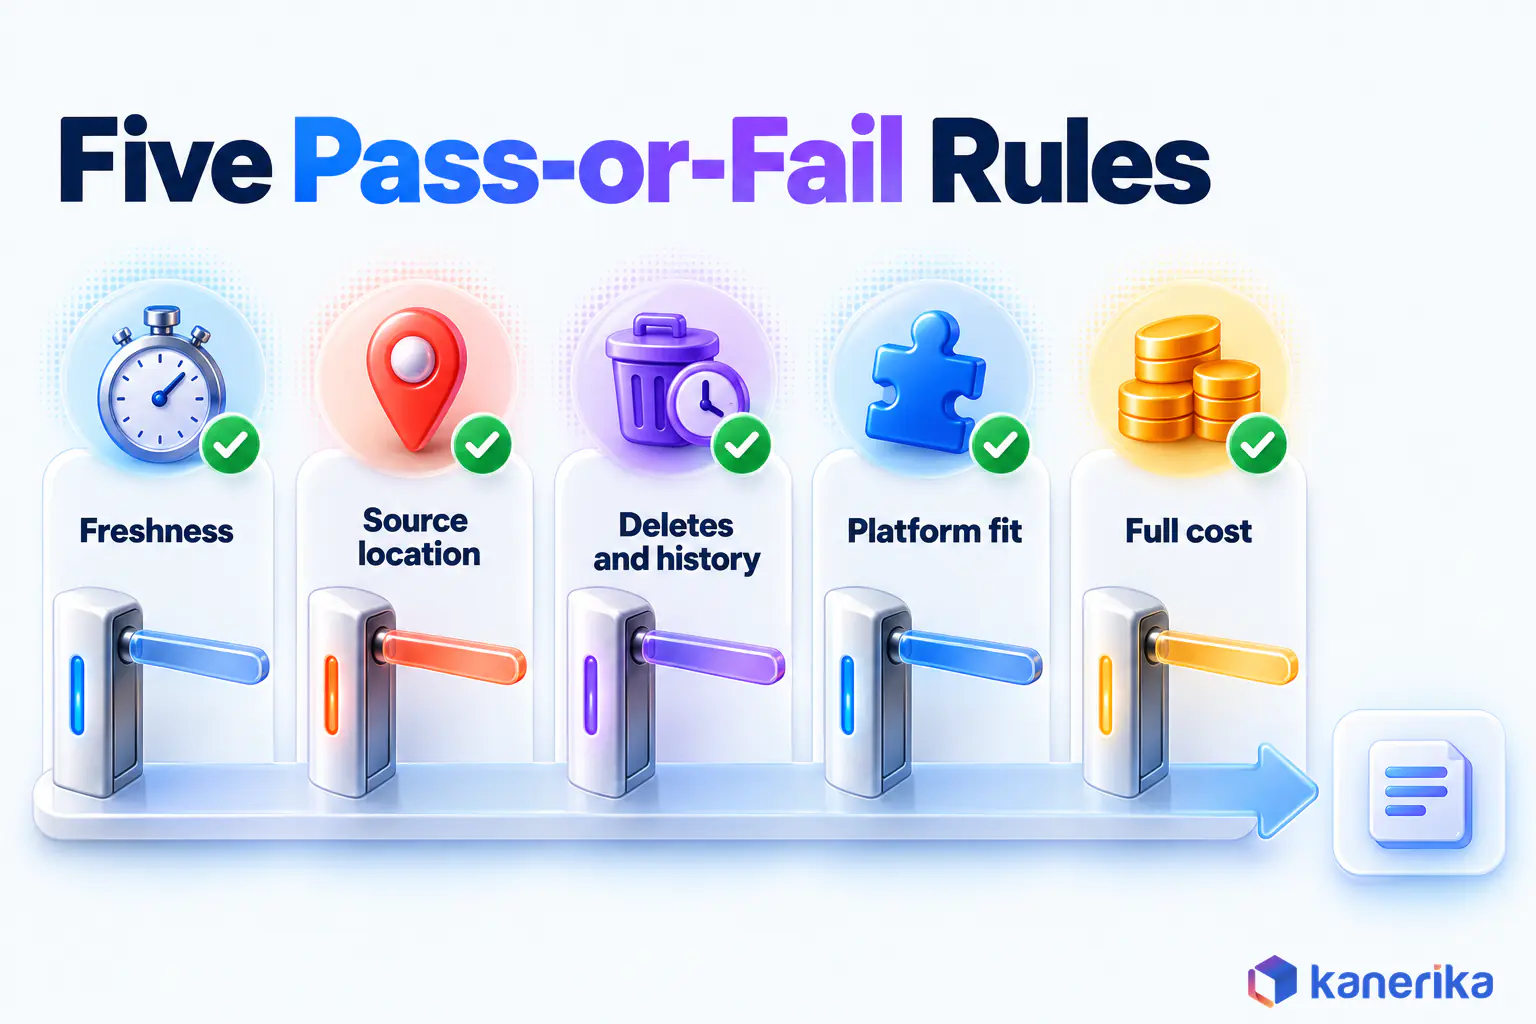
A good choice starts from the business output and works back to the vendor list. Run the five rules below as pass-or-fail filters, and only then compare the survivors on price and fit.
- Freshness: write down how old the data may be when it is used, per table. That answer picks the pattern.
- Sources and location: list every source and where it runs. Anything behind a firewall needs a self-hosted runtime or a mirroring agent.
- Deletes and history: the tool must carry deletes and support a full reload without duplicates.
- Platform fit: prefer the integration service native to your warehouse or lakehouse, unless it lacks a source you cannot do without.
- Full cost: price connector, compute, egress and people at your real volume, then compare.
Worked Example: ERP and CRM for Inventory Reporting
Here is how the rules play out on a common shape of problem. A distributor wants inventory reporting from an on-premises ERP and a cloud CRM, and stock figures must be no more than 15 minutes old.
Rule 1 sends the ERP stock and order tables to CDC, because a nightly batch is far too slow. Rule 2 then puts a runtime or mirroring agent next to the ERP. Since the CRM fields in scope change only a few times a day, a batch ELT connector on an hourly schedule is enough.
Rules 3 to 5 then narrow the shortlist. If the lakehouse is Fabric, mirroring or open mirroring handles the ERP side. On Databricks, the Lakeflow Connect database connectors fill the same role. The answer is two patterns in one design, which is normal for a mixed estate.
For the wider list of habits that keep pipelines healthy after launch, see the data integration best practices guide. Teams weighing outside help can also start with this overview of data integration companies.
Trends to Plan For
A few shifts are already visible in vendor documentation and announcements, so they are worth designing around. None of them changes the decision rules above, but each one changes which tool passes them.
- Zero-copy replication: with Fabric Mirroring and open mirroring, the effort moves from building pipelines to checking supported tables and delete handling, which is rule 3 above.
- Connectors inside the platform: because Lakeflow Connect and Openflow sit inside the data platform, platform fit (rule 4) settles the shortlist sooner.
- Vendor consolidation: Salesforce completed its acquisition of Informatica on November 18, 2025, folding a major integration vendor into a larger platform.
- AI agents need fresh, governed data: an agent that acts on stale or deleted records makes real mistakes, so delete handling becomes an AI requirement.
The practical response is to keep your integration layer portable. Land data in open formats where you can, and avoid logic that only one vendor’s tool can run.
How Kanerika Delivers Cloud Data Integration
Kanerika starts every integration from the business output, then works back to the sources. The work runs in four stages, and each one has an exit check before the next begins.
- Baseline: agree the reports or decisions the data must serve, and list every source, owner and freshness need.
- Prove: test the chosen pattern and connector on live data, including deletes, schema changes and a full reload.
- Build and validate: build the production flows, then reconcile row counts and totals against the source before sign-off.
- Operate and measure: hand over run logs, alerts and freshness targets, and track them after go-live.
The QAD project mentioned earlier shows this in practice. It involved a global manufacturer running QAD across multiple sites, with no ready-made connection to Fabric.
Kanerika built a QAD connection on open mirroring that sends new, changed and deleted records into Fabric. Each site also got its own separate space, with run logging and alerts. Before rollout, the team fixed 7 QAD data issues; reloads now produce 0 duplicate records, and 200+ QAD tables are connected to Fabric.
Case Study
Bringing Live QAD ERP Data into Microsoft Fabric with Open Mirroring
A global manufacturer connected 200+ QAD tables to Fabric through open mirroring, fixed 7 QAD data issues before rollout and reloads data with 0 duplicate records.
Read the Case Study →Kanerika is a Microsoft Solutions Partner with Databricks and Snowflake partnerships, and it holds ISO 27001 and SOC II certifications. Its data integration services cover the same four stages for Fabric, Databricks and Snowflake estates. To scope your own sources, download the Data Integration Checklist or book a working session with the team.
Bottom Line: Matching Tools to Use Cases
Start from the use case and its freshness need, then pick the pattern, and only then the tool. Batch ELT through Fivetran, Data Factory or Glue covers reporting, while CDC, Fabric Mirroring or Lakeflow Connect covers fast-changing databases.
Dataflow or Openflow handles event streams, and an iPaaS handles app-to-app sync. Choose cloud data integration tools by use case first and platform second, and test deletes before you sign.
Frequently Asked Questions
What is cloud data integration?
Cloud data integration is the process of combining data from applications, databases and files into one consistent dataset in a cloud warehouse or lakehouse. Managed cloud services handle the connectors, compute and scheduling. The result is a single governed copy of business data that reports, applications and AI models can all use with confidence.
What is an example of cloud data integration?
A distributor keeps orders in an on-premises SQL Server database, its sales pipeline in Salesforce and its online store in Shopify. A cloud integration service pulls from all three on a schedule, lands the raw records in a cloud warehouse and joins them. Each customer then has one order history that every team reads.
What are the biggest challenges in cloud data integration?
The most common problems are silent failures, missed deletes, schema drift and duplicate loads after a reload. Security adds leaked credentials and PII moving between regions. Cost overruns come from frequent schedules, egress and oversized compute. Each risk needs a named owner and a control such as freshness alerts, contract tests or budgets with alerts.
How does cloud data integration work?
It connects and authenticates each source, runs one full historical load, then switches to incremental loads or change data capture that also carry deletes. Raw data lands in the cloud target first. Transformations then build clean business records, which are served to BI, apps and AI, while monitoring tracks freshness and failures.
Is data integration the same as ETL?
Data integration is the wider discipline of combining sources into one consistent, governed dataset and keeping it current. ETL is one method inside that discipline, describing the order of the extract, transform and load steps. An integration program can also use ELT, change data capture, streaming or API-based sync to reach the same goal.
What is the difference between ETL and ELT in cloud integration?
ETL transforms data before loading it into the target, which helps when data must be masked or reshaped first. ELT loads raw data first and transforms it inside the cloud warehouse or lakehouse. ELT is the usual cloud default because warehouse compute scales on demand and raw data stays available for reprocessing later.
How does cloud data integration support real-time analytics?
Real-time analytics needs data that arrives within seconds or minutes of a change. Change data capture reads database logs and sends inserts, updates and deletes as they happen, while streaming services process events continuously. Mirroring can also keep a replicated copy current. Dashboards and alerts then read from tables that stay close to the source.
What is the difference between iPaaS and cloud data integration?
An iPaaS connects applications so they trigger and update each other through APIs and workflows, such as creating an invoice when an order closes. Cloud data integration moves and combines data into a warehouse or lakehouse for analytics. Many enterprises use both, with iPaaS for app-to-app sync and integration pipelines for shared reporting.
When should you use CDC instead of batch loading?
Use change data capture when database rows change often, when deleted records must disappear from reports, or when users need data that is minutes old. Batch loading is simpler and cheaper for daily or hourly reporting. Many designs use both, with CDC for busy operational tables and batch ELT for slower sources such as CRM fields.
Can cloud data integration connect on-premises databases?
Yes. A hybrid design installs a small runtime inside your own network, next to the database, which sends data outbound to the cloud service. Azure Data Factory calls this a self-hosted integration runtime. Mirroring agents and open mirroring connections work in a similar way, so firewalled ERP and SQL Server systems can feed a cloud lakehouse.
How much does cloud data integration cost?
Cost depends on volume, freshness and design. Connector pricing varies by vendor, for example Fivetran bills on monthly active rows and AWS Glue at $0.44 per DPU-hour, varying by region. Target compute, network egress, self-hosted runtime machines and engineering time add to the bill, so price the full flow at your real volume.
How do you secure cloud data integration pipelines?
Use managed identities and keep secrets in a vault with regular rotation. Encrypt data in transit with TLS and mask or tokenize PII before it lands. Pin regions to meet residency rules, apply access control on the target tables and alert on unusual volumes. Give each control a named owner so it stays in place.
What are the main types of cloud data integration?
The main patterns are batch ELT, ETL, change data capture, streaming, API or iPaaS integration and zero-copy mirroring. Batch ELT suits daily or hourly reporting. CDC and mirroring suit database rows that change often. Streaming handles events that need action in seconds, and iPaaS connects applications that must update each other directly.
Is cloud data integration the same as data migration?
No. Data migration is a one-time move from an old system to a new one, after which the old system is switched off. Cloud data integration is ongoing, keeping many live sources combined and current in the cloud. A migration project often sets up the integration flows that continue running after the move is complete.
Why is cloud data integration important for businesses?
It gives every team the same numbers from one governed source, refreshed on a known schedule. That ends arguments over whose report is right and replaces manual exports. It also creates one place where data quality rules can run, so errors are caught before they reach a board report or an AI assistant.
Which industries benefit most from cloud data integration?
Any industry with many systems benefits, and the gains are clearest where data changes quickly. Manufacturers connect ERP and plant data, retailers and distributors track inventory and orders, and banks and insurers consolidate customer records under strict controls. Healthcare and pharma teams use it to combine clinical, operational and financial data for governed reporting.
Will AI replace ETL?
AI is unlikely to remove the need for ETL or ELT pipelines, because models depend on fresh, correct and governed data to work at all. AI assistants can help write transformations, map fields and flag anomalies. The pipelines that extract, load, test and secure data still have to exist, and someone still has to own them.
What does CDI mean in data integration?
CDI usually stands for Cloud Data Integration, the name of Informatica’s cloud integration service within its Intelligent Data Management Cloud, also called IDMC. Salesforce completed its acquisition of Informatica on November 18, 2025. In general use, CDI can also refer simply to cloud data integration as a practice, whichever vendor provides the service.
What are the steps of an ETL process?
An ETL process has three core steps. Extract reads data from source systems such as databases and SaaS apps. Transform cleans, joins and reshapes that data into business records. Load writes the result into a warehouse or lakehouse. In ELT the last two steps swap, so raw data lands first and transforms there.
How do AWS, Azure and Google Cloud integration services help?
Each cloud offers managed services that remove server upkeep. Azure Data Factory orchestrates pipelines and reaches on-premises sources through a self-hosted integration runtime. AWS Glue runs managed ETL jobs billed per DPU-hour. Google Cloud Dataflow runs unified stream and batch processing on Apache Beam. Teams usually pick the service native to their main cloud.
What is the best cloud data integration tool?
There is no single best tool, because the right choice depends on the workload. Start with how fresh the data must be and where the sources run. Batch ELT tools such as Fivetran suit reporting, CDC or mirroring suits busy databases, and platform connectors suit teams standardized on Fabric, Databricks or Snowflake.