TL;DR
Business intelligence for manufacturing works best as curated extracts for one plant with one decision, then one shared data platform once plants or decisions multiply. It links production, quality, maintenance and cost data, so every team sees the same numbers. Start with lost machine time, faulty batches and repeat breakdowns. Agree how each measure is calculated, and who owns it, before building dashboards. Data cleanup costs more than software, since Power BI Pro is $14 per user per month, paid yearly, as of November 2026. Kanerika did this for a steel mill services provider, cutting storage expenses by 25% and raising productivity by 40%.
Key Takeaways
- Manufacturing BI works at plant grain (line, asset, lot, shift and order), and that is what separates it from finance-led reporting.
- Start with one decision, such as approving overtime or releasing a held lot, and then build only the data that decision needs.
- Agree on OEE, planned downtime and scrap definitions before building charts, because otherwise plant comparisons mislead.
- One plant with one decision can run well on curated extracts, while a plant network needs a shared lakehouse or warehouse with one semantic layer.
- Streaming data earns its cost only when someone can act within minutes, so most cost and quality decisions run fine on hourly or daily refresh.
- Judge a pilot on reconciliation, adoption and a validated benefit that finance accepts.
Three Versions of Yesterday’s Output
It is 7:30 on a Tuesday, and the production meeting has already stalled. According to the MES, Line 3 made 4,120 good units on second shift. Meanwhile the ERP shows 3,960, because two pallets posted after midnight.
A third figure sits in the shift lead’s spreadsheet: 4,300, since it counts rework that passed on the second try. (These figures are illustrative, but anyone who has run a plant has sat through this meeting.)
Still, nobody in the room is wrong. Each system answers a slightly different question, and none of them was built to agree with the others. So the first twenty minutes go to arguing about numbers, while the overtime call for Line 3 waits until lunch.
Business intelligence for manufacturing exists to end that meeting. It pulls machine, production, quality and business data into one model and defines each measure once. Then it puts the result in front of the person who has to act.
The sections below cover the use cases with worked examples and the KPIs to define first. They also explain how the data flows and how to choose an approach for one plant or twenty.
What Business Intelligence for Manufacturing Means in 2026
Business intelligence for manufacturing turns plant and business data into decisions that people on and around the shop floor can act on. What sets it apart from ordinary reporting is the grain. A useful manufacturing model knows which line, asset, lot, shift and production order every number belongs to.
Think about a scrap figure, for example. A finance report can say scrap cost $180,000 last quarter, and that may well be accurate. Still, a plant manager cannot act on it until the number is broken down by line, product, shift and defect code. Manufacturing BI does that breakdown by design, so the scrap number arrives with its cause attached.
The data comes from systems that were never meant to talk to each other. Manufacturing execution systems (MES) record production events, while ERP holds orders, costs and inventory. Quality systems, maintenance systems and process historians also hold a slice each. BI joins them on shared identifiers and then serves the result as dashboards, alerts and reports that match how the plant runs.
How Manufacturing BI Differs From Enterprise BI
Enterprise BI usually starts from finance and sales data, refreshed daily and read by managers. Manufacturing BI, by contrast, has to cope with machine data that changes by the second. Its users also stand at a line rather than sit at a desk. The four differences below decide most design choices.
| Dimension | Enterprise BI | Manufacturing BI |
|---|---|---|
| Grain | Customer, account, month | Line, asset, lot, shift, production order |
| Sources | ERP, CRM, finance systems | MES, historian, SCADA, quality and maintenance systems as well as ERP |
| Freshness | Daily or weekly | Minutes for line decisions, but daily for cost and planning |
| Users | Analysts and managers | Operators and supervisors as well as engineers and network leaders |
Why It Matters Now
Downtime is the clearest reason. Siemens’ True Cost of Downtime 2024 report looks at the world’s 500 biggest companies. It puts their loss from unplanned downtime at almost $1.4 trillion a year, equal to 11% of their revenues.
The same report finds that an hour of a stopped automotive line costs $2.3 million. Few plants lose that much per hour, but the direction holds everywhere. When a stop costs real money, the gap between fault and decision matters. Most of that gap is spent finding data and agreeing on it.
Plants also carry more data than ever, from sensors, connected machines and cloud ERP. Yet more data without shared definitions only produces more versions of the truth. BI is the layer that turns the extra signal into one answer people trust.
What Manufacturers Gain
The gains are measurable only when each one is tied to a KPI with a baseline. Vague promises of “better visibility” do not survive a finance review, so each outcome below links to a KPI defined later in this guide.
- Higher OEE, because teams find the largest availability, performance and quality losses per line.
- Lower scrap rate, since defects link back to lot, machine, shift and supplier.
- Less unplanned downtime once repeat failure patterns per asset are visible.
- Better schedule attainment, because supervisors see which orders slip, and why, before the shift ends.
- Accurate cost per unit when overtime, scrap and energy are tied to the products that caused them.
- Faster lot release, as traceability queries take minutes instead of days.
Case Study
25% Lower Storage Costs for Steel Manufacturing on Azure
An on-site industrial steel mill services provider moved off a legacy system to Dynamics AX, Azure and Power BI dashboards, cutting storage expenses by 25% and lifting productivity by 40%.
Read the Steel Case Study →Manufacturing BI Use Cases, With Worked Examples
A use case is worth building when it supports a decision that someone makes often and that costs money when made badly. That test filters out most of the “nice to see” dashboards plants collect over time. The table below therefore lists the eight use cases that pass it most often, with the decision each one supports.
Eight Use Cases at a Glance
| Use case | Decision supported | Main sources | Measures | Owner | Example action |
|---|---|---|---|---|---|
| OEE loss analysis | Where to recover capacity before adding shifts | MES, historian | OEE, availability, performance, quality | Production manager | Fix a recurring changeover delay before approving overtime |
| Quality and traceability | Hold, release or recall a lot | QMS, MES, ERP | First pass yield, scrap, defects by lot | Quality manager | Quarantine lots once one supplier batch is suspect |
| Maintenance and downtime | Which asset to service first | CMMS, historian | Downtime %, failure count, repair time | Maintenance lead | Move a pump overhaul forward when stops repeat |
| Inventory and suppliers | What to reorder and from whom | ERP, supplier portals | Inventory turns, on-time delivery | Materials planner | Shift volume to a reliable supplier so the line keeps running |
| Cost and margin by product | Which products to reprice | ERP, MES | Cost variance, scrap cost, overtime | Plant controller | Reprice a SKU whose real cost runs higher than standard |
| Energy per unit | When and where to run energy-heavy jobs | Meters, historian, MES | kWh per unit | Facilities or EHS lead | Move a furnace run off peak hours |
| Workforce and shifts | How to staff and train | MES, HR, scheduling | Output per labor hour, attainment | Operations manager | Pair a new crew with a mentor shift until output matches |
| Cross-plant benchmarking | Where to invest across the network | All plant models | Normalized OEE, cost per unit | VP of operations | Copy one plant’s changeover method rather than only ranking plants |
The first three rows carry most of the early value, in discrete and process plants alike. That is because they touch capacity, quality and uptime, which are the three numbers a plant manager is judged on.
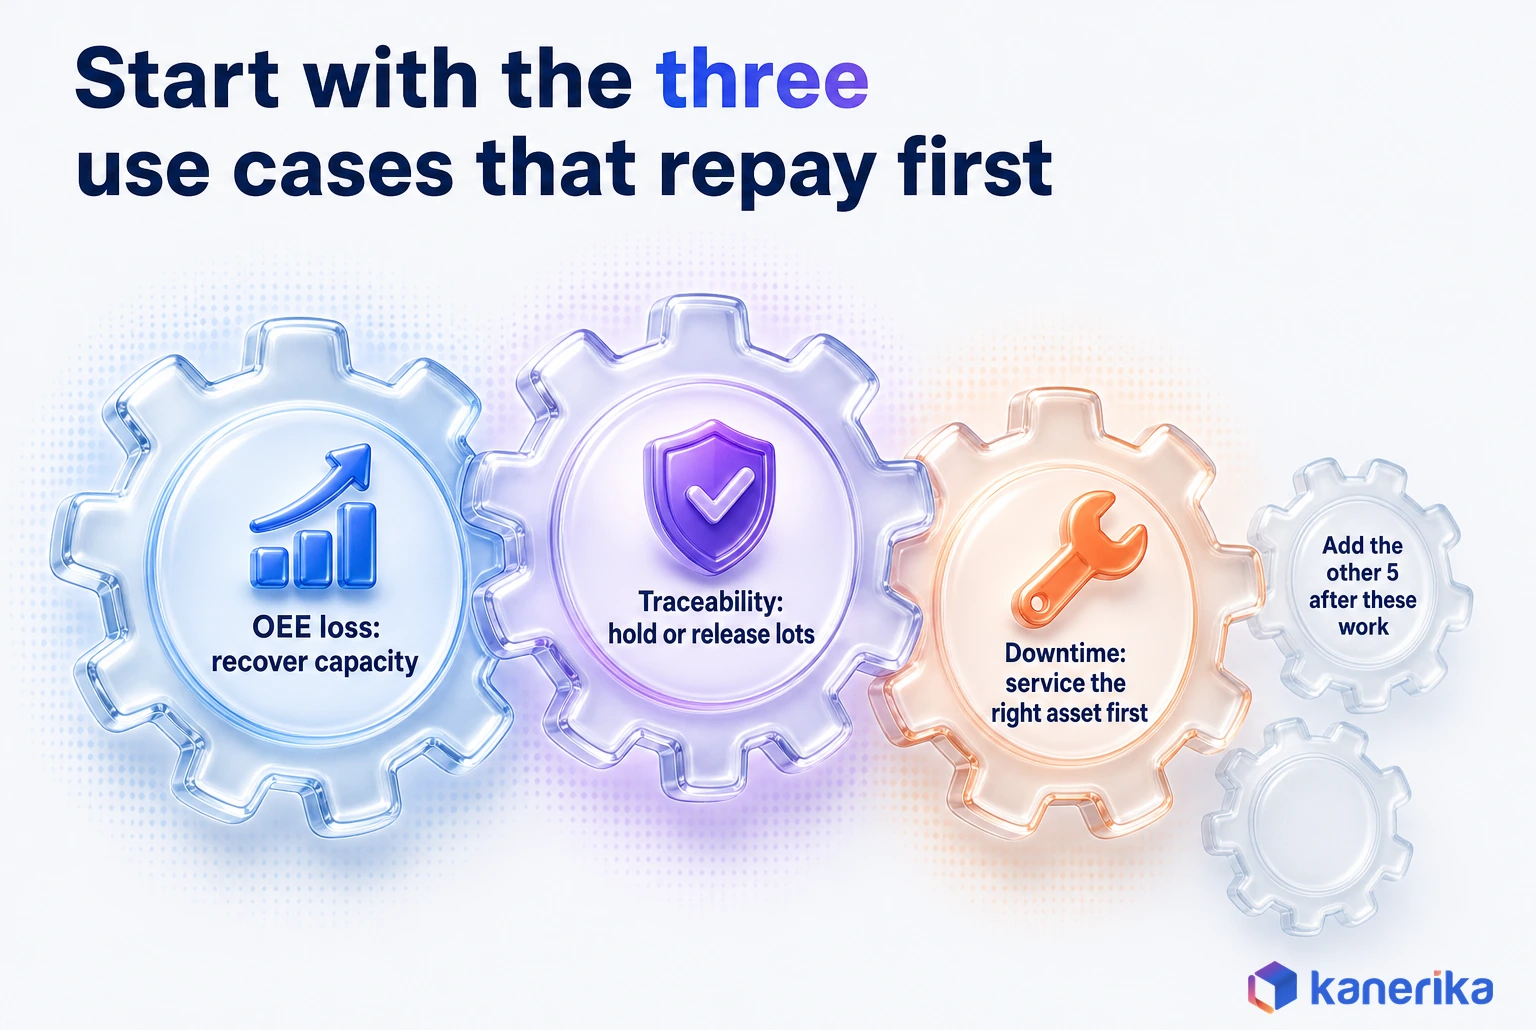
Production Performance and OEE Loss Analysis
OEE loss analysis shows where planned production time goes. Instead of one OEE number per line, a good model splits the loss into stops, slow cycles and defects. It then ranks the reasons inside each.
Here is how a supervisor might use it before approving overtime. The numbers are illustrative.
- Frame the decision. Line 2 is 600 units behind the weekly plan, so the request is a Saturday shift.
- Split the gap. The model shows availability at 78%, performance at 91% and quality at 98%, so stops are the main loss.
- Rank the stops. Changeovers account for half the stop minutes, and one product pair causes most of them.
- Check the pattern. The long changeovers happen mostly on second shift, where the setup checklist is not used.
- Choose the action. Resequence that product pair and apply the checklist, then recheck output after three days.
- Decide on overtime. If recovered minutes cover the 600 units, the Saturday shift is canceled; otherwise it runs, now with a known cause.
The value is not the chart itself. Rather, the supervisor made a cost decision on evidence in one sitting, and because the action is logged, the result can be checked later.
Quality, Yield and Lot Traceability
Traceability answers one question under pressure: which finished lots contain the suspect material? To answer it, the model follows a chain from supplier lot to production order. From there it runs through machine, shift and inspection results to each finished lot.
When those links live in different systems, a recall query can take days of spreadsheet work. A BI model that holds the chain as related tables, however, answers it in minutes. The same model also shows first pass yield and defect rates by supplier, line and shift. Quality teams can then see a drifting process before it produces a held lot.
Visual inspection data fits here too. Cameras that classify defects produce counts and images, and BI then turns those counts into trends by line and lot. For the inspection side itself, see Kanerika’s guide to machine vision AI.
Maintenance and Downtime Analytics
Maintenance analytics joins work orders from the CMMS with stop events and sensor data from the historian. As a result, it shows which assets fail most, how long repairs take and which failures repeat after a fix.
BI shows the pattern, while a model predicts the next failure. For example, a dashboard can reveal that a press loses hours every month to hydraulic faults. Forecasting when the next fault will hit, though, is a machine learning job, covered in Kanerika’s guide to AI in manufacturing. Some of that scoring also runs on devices beside the machine, a pattern explained in the guide to edge AI.
For a maintenance lead, the practical win is priority. Ranking assets by downtime minutes and cost per hour tells the team which work order to start first. BI makes that ranking visible every morning.
Kanerika Service
Data and AI for Manufacturing Plants
Kanerika’s manufacturing practice connects MES, ERP, quality and maintenance data so plant teams can act on OEE, downtime and quality figures they trust.
Explore Manufacturing SolutionsInventory, Materials and Supplier Performance
Materials decisions sit between the plant and the supply chain, so they need data from both. BI tracks inventory turns, stockouts, supplier on-time delivery and incoming quality, so planners can see which parts put the schedule at risk.
Say one supplier’s late deliveries caused three line stops in a month. The planner then has a reason to rebalance volume, but only if plant data and supplier data sit in one model. Demand forecasting and replenishment go further, as the guides to supply chain analytics and predictive analytics in supply chain explain. Outbound freight follows the same logic, as explored in AI in transportation and logistics.
Manufacturing Cost and Margin by Product
Standard costs hide a lot. A product can look profitable at standard even though its real cost runs higher. Scrap, rework and overtime on its lines push that cost up.
Cost BI joins ERP cost data with MES production data at the order level. The plant controller can then see cost variance by product, line and shift, and so trace a margin drop to its source. Often the answer is a single product that changes over badly or scraps more than its peers.
Energy per Unit Produced
Energy is a growing share of cost in many plants, yet it is easy to measure badly. Meter data shows what a building used, whereas energy per unit shows what each product cost to make. Joining meter readings with production counts by line and hour gives that figure. It often shows that idle running or peak-hour scheduling drives the bill.
Take an illustrative case. A plant charts kWh per unit by hour and sees that furnace runs on the peak tariff cost far more per unit than the same runs at night. Moving one furnace run off peak lowers its energy cost per unit without changing output.
Workforce and Shift Performance
Shift comparisons help when they explain differences in output, such as a crew that skips a setup step. They hurt, though, when they turn into rankings of individuals without context.
Good practice is to report at crew and shift level, with role-based access so a supervisor sees only their own teams. Product mix, machine condition and staffing levels should also sit beside the output figures. After all, the aim is to find training and staffing fixes that lift the whole crew.
Cross-Plant Benchmarking
Comparing plants is the use case most likely to go wrong. Two plants can report the same OEE even though one runs long batches of a simple product. The other may run short batches of complex ones.
Fair comparison therefore needs normalization for product mix, shared definitions of planned downtime and a common calendar. Once those are in place, benchmarking shows which plant has solved a problem the others still have. Leaders can then copy the method instead of only ranking the results.
The Manufacturing KPIs to Define Before Building Dashboards
KPI definitions decide whether manufacturing BI is trusted. If one plant counts a planned changeover as downtime while another does not, their OEE figures cannot be compared, however good the dashboard looks. That single disputed definition has derailed more plant comparisons than any technical problem.
The fix is a KPI dictionary written before the first chart. Each measure gets a formula, a source system, an owner who settles disputes and a note on the common trap. OEE follows the standard definition from OEE.com: availability times performance times quality. It can also be computed as good count times ideal cycle time, divided by planned production time.
Talk to Kanerika
Planning a KPI Layer Your Plants Will Trust?
Bring your current OEE and downtime definitions. Kanerika will map where your plants disagree, which sources need work and what a bounded first pilot should cover.
Book a Planning Session →Twelve KPIs and Their Definition Traps
| KPI | Formula | Source system | Owner | Common definition trap |
|---|---|---|---|---|
| OEE | Availability x Performance x Quality | MES | Production manager | Plants disagree on what counts as planned time |
| Availability | Run time / planned production time | MES, historian | Production manager | Short stops left out because nobody logs them |
| Performance | (Ideal cycle time x total count) / run time | MES | Process engineer | Ideal cycle time set slower than the machine can run |
| Quality | Good count / total count | MES, QMS | Quality manager | Reworked units counted as good even when they failed first |
| First pass yield | Units good on first attempt / units started | QMS, MES | Quality manager | Rework hidden in the good count |
| Scrap rate | Scrapped units / units started | MES, ERP | Plant controller | Scrap posted late, so it lands in the wrong shift |
| Downtime % | Unplanned stop time / planned production time | MES, CMMS | Maintenance lead | Planned and unplanned stops mixed together |
| Cycle time | Run time / units produced | MES, historian | Process engineer | Averages hide slow outliers, especially after changeovers |
| Schedule attainment | Orders completed on plan / orders planned | ERP, MES | Production planner | Plan changed after the fact so attainment looks better |
| Inventory turnover | Cost of goods sold / average inventory | ERP | Materials manager | Consignment stock included even though the plant does not own it |
| On-time delivery | Orders shipped by promise date / orders shipped | ERP | Customer service lead | Promise dates edited once an order slips |
| Energy per unit | kWh / good units | Meters, MES | Facilities lead | Shared meters split by guesswork rather than by line |
Not every plant needs all twelve on day one. Instead, pick the four or five that serve the first decision, publish their definitions and then add the rest as the use cases expand.
How Manufacturing BI Works: From Machine Signal to Decision
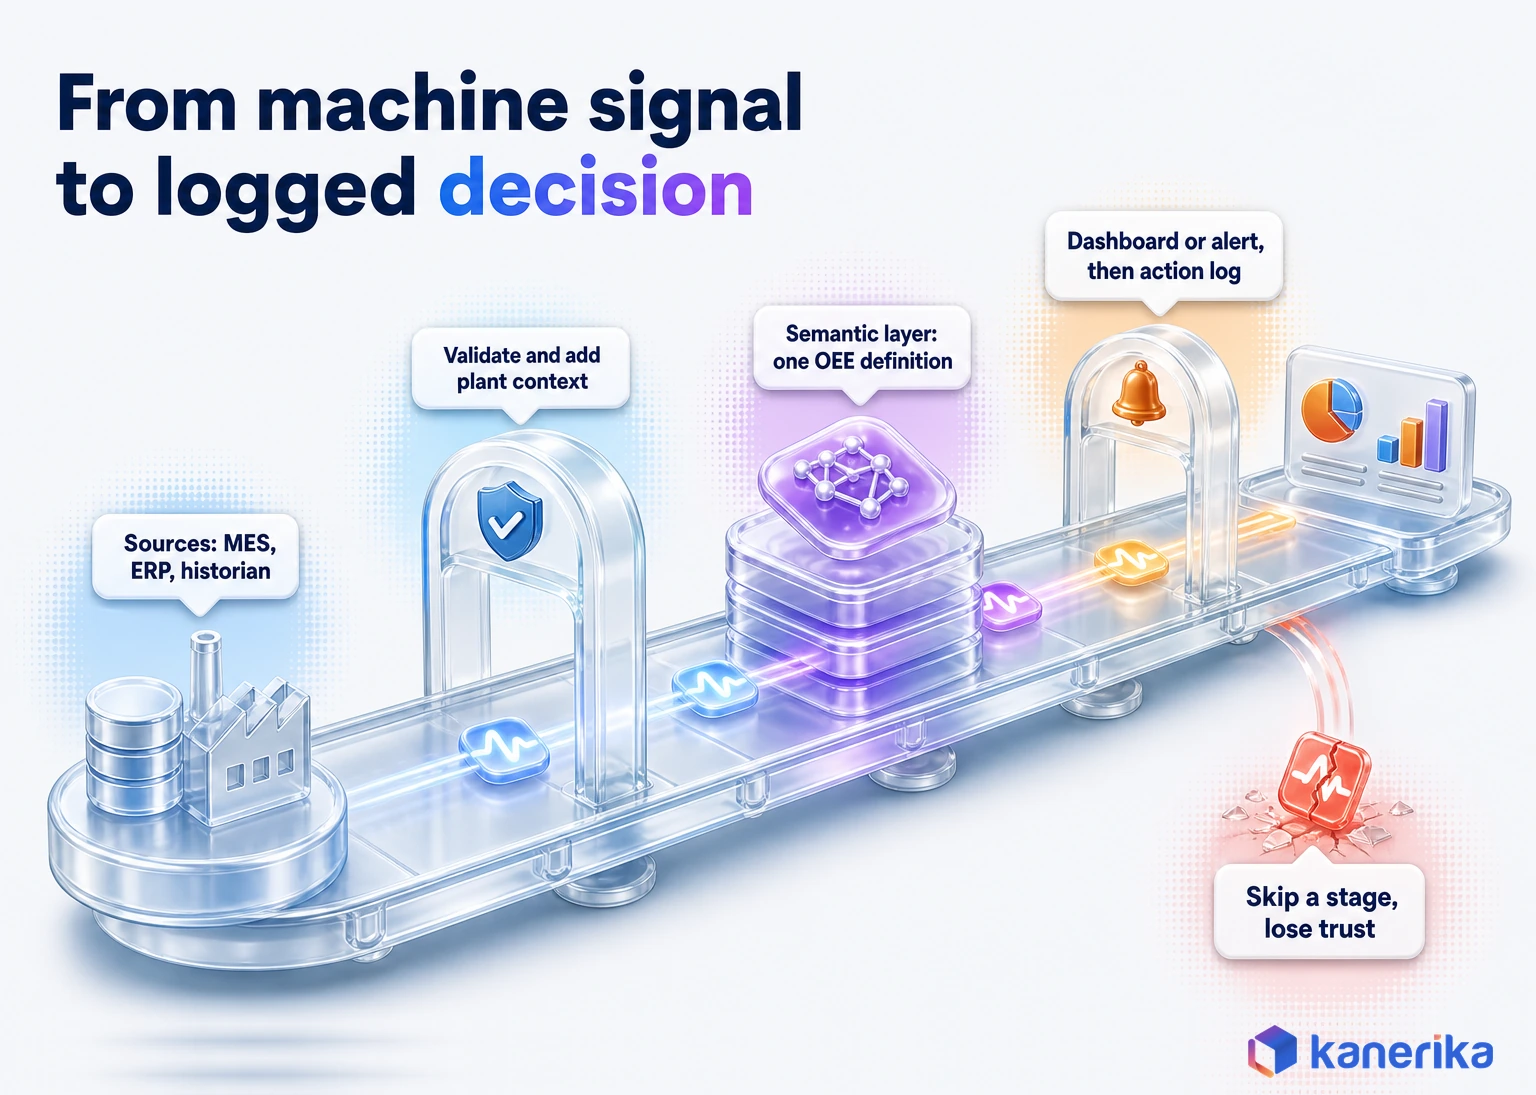
Every manufacturing BI system moves data through the same path, whatever the tools. Signals and transactions leave the source systems, get checked and given plant context, then land in a lakehouse or warehouse. From there they pass through a semantic model before they reach a dashboard or alert, and the action someone takes is logged.
Each stage, in other words, exists to stop a specific failure. Skipping validation lets bad counts reach the dashboard, while skipping the semantic model lets each report define OEE its own way. Without the action log, nobody can prove the system changed anything.
The Data Sources and Where They Sit
The ISA-95 standard (IEC 62264) describes how enterprise and control systems connect. Its levels are a handy map of where each data source sits and, as a result, how fresh its data can be.
| System | ISA-95 level | What it contributes | Typical refresh |
|---|---|---|---|
| Sensors, devices | Levels 0-1 | Raw machine signals, states and counts | Seconds, but read through a historian |
| PLCs, DCS, historian | Level 2 | Control states, time-series process data and stop events | Seconds to minutes |
| SCADA, MES | Level 3 | Supervisory views, production orders, counts, genealogy and downtime reasons | Minutes |
| QMS, CMMS | Level 3 | Inspections and defects as well as work orders and repairs | Minutes to hourly |
| ERP | Level 4 | Orders, costs, inventory and suppliers | Hourly to daily |
Crossing the OT/IT Boundary Safely
The plant floor network (OT) runs machines, while the business network (IT) runs reporting. BI needs data from the first without ever putting it at risk.
The safe pattern is therefore read-only. BI reads from historian replicas, MES databases or published interfaces, never directly from PLCs. Extraction jobs are throttled so they cannot slow a production system during a shift. Above all, BI never writes back to control systems or touches safety interlocks. Its job is to inform people, who then act through the proper tools.
Resolving Plant Context Before Charts
Raw data from a plant rarely lines up on its own, even within one site. So before any chart is built, the pipeline has to settle five things.
- Identifiers. Map each machine, line and product code to one master ID, so MES, ERP and CMMS records join.
- Units. Convert pieces, kilograms, meters and batches to one standard unit per measure.
- Shift calendars and time zones. Assign every event to the right shift and plant day, especially for overnight shifts.
- Late postings. Decide how to handle counts and scrap posted after the shift closes.
- Lineage. Record where each number came from, so a disputed figure can be traced in minutes.
The Semantic Layer: One Definition of OEE for Every Plant
The semantic layer is where the KPI dictionary becomes code. Measures such as OEE, scrap rate and downtime are defined once in a shared model, and every report reads from it. When a definition changes, it then changes everywhere at the same time.
Checklist
Business Intelligence Strategy and Readiness
Assess BI strategy, data foundations, dashboard usage, governance and modernization readiness for enterprise analytics.
Get the Checklist →To illustrate, here is what the OEE definition from the KPI table looks like as a Power BI measure. Table and column names are examples.
-- OEE = (Good Count x Ideal Cycle Time) / Planned Production Time
OEE % =
DIVIDE (
    SUMX ( Production, Production[GoodCount] * RELATED ( Product[IdealCycleTimeSec] ) ),
    SUM ( Schedule[PlannedProductionSec] )
)
This is also what makes cross-plant comparison honest. A plant cannot quietly use its own OEE formula when every report reads the same measure. Plant-level row security then lets each site see its own data, while the network team sees all of it.
Batch or Streaming: Match Freshness to the Decision Window
Real-time data sounds better, but it costs more to build and run. The right refresh rate is set by how fast someone can act on the number.
| Decision | Window to act | Refresh that fits |
|---|---|---|
| Stop a line drifting out of tolerance | Seconds to minutes | Streaming with alerts |
| Rebalance a shift’s work | During the shift | Every 5 to 15 minutes |
| Approve overtime or resequence orders | Same day | Hourly |
| Review cost, scrap and supplier trends | Weekly or monthly | Daily batch |
For the cases that need streaming, Microsoft Fabric’s Real-Time Intelligence is one worked example. Its Real-Time hub catalogs streaming data. Eventstreams then ingest it without code, through connectors that include Kafka, database CDC feeds and MQTT. Eventhouse stores live and historical data together, and Activator sets alerts and actions when a value crosses a threshold.
A packaging line, for instance, is a good fit. A temperature reading from a sealer can trigger an alert to the line lead within seconds. The same readings also feed the daily quality trend. Scoring on the device itself is the domain of edge AI, which can sit in front of this stream.
Where AI and Natural-Language Analytics Fit
AI assistants can answer plain-language questions, such as why scrap rose on Line 4 last week. Even so, they are only as good as the measures underneath. An assistant that reads a governed semantic model gives the same OEE as the dashboard, whereas one that queries raw tables invents its own definitions.
So the order matters: govern the measures first, then add natural-language access. The mechanics are covered in Kanerika’s guides to agentic BI and generative BI. For the line between reporting on the past and forecasting the future, see business intelligence vs predictive analytics.
Implementation Approaches Compared
Manufacturing BI can be built five ways, from the reports already in ERP and MES to a shared data platform fed by live events. Each one fits a different stage of maturity and a different number of plants.
The comparison below is the starting point for the decision framework in the next section.
| Approach | Best fit | Strength | Limit |
|---|---|---|---|
| Existing ERP and MES reporting | Early stage, one plant | No new build, since the data is already there | Each system reports alone, so there is no cross-source view |
| BI over curated extracts | One plant, one or two decisions | Fast to start and low cost | Extracts multiply, and then definitions drift between files |
| Shared lakehouse or warehouse with a semantic layer | Several plants or many use cases | One definition per KPI, so data is reused | Needs data engineering and governance effort up front |
| Hybrid enterprise model | Large networks with strong local teams | Central core while local teams keep freedom | Needs clear rules on what stays central |
| Event-fed operational BI | Lines where minutes matter | Alerts and actions within seconds | Higher cost, and it needs the shared core first |
Plants still on legacy on-premises report servers sit in the first row. Moving them to cloud BI is usually less about the tool than about a shared, governed data layer every plant can reach. A move that only copies old reports to a new tool keeps the old disagreements.
Decision Framework: Which Approach Fits Your Plant Network
The right approach depends on how many plants you run, how many decisions you want to support and how fast those decisions happen. The scenario table gives a stated pick for each common situation, so you can start with the row that matches yours.
| Scenario | Stated pick | Why | Expand when |
|---|---|---|---|
| One plant, one urgent decision | BI over curated extracts | Proves value in weeks because little needs building | Once a second decision needs the same data |
| One plant, several use cases | Shared lakehouse or warehouse with a semantic layer | Stops extracts and definitions from multiplying | As soon as a second plant joins |
| Two to ten plants, central operations team | Shared lakehouse or warehouse with a semantic layer | One OEE definition makes comparison fair | When local teams need their own models |
| Large network, strong local teams | Shared foundation, run as a hybrid model | Central KPIs, while local teams build on top | When lines need minute-level alerts |
| Lines where minutes matter | Shared foundation plus event-fed operational BI | Streaming extends the governed core rather than replacing it | Once alerts prove they change outcomes |
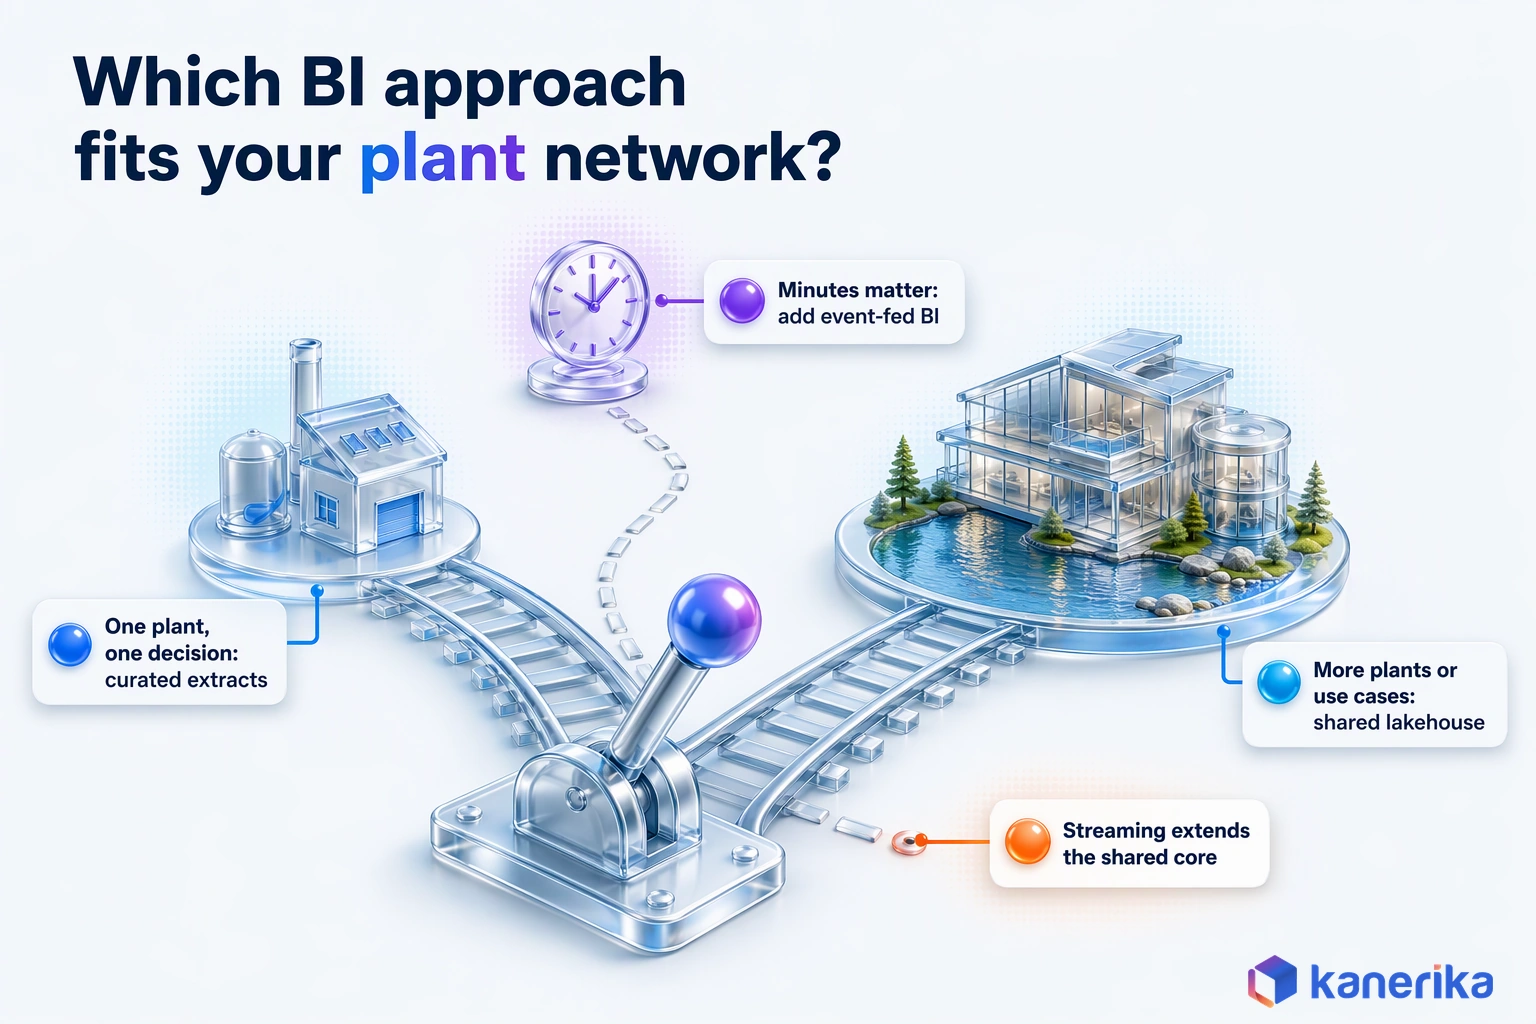
The pattern is simple. Curated extracts win for one plant with one decision, but a shared foundation wins as soon as plants or use cases multiply. The hybrid model and streaming both extend that foundation rather than replace it.
Five Selection Gates
Before committing, run the candidate approach through five gates. If it fails one, either fix the gap first or choose a smaller approach.
- Decision. Is there a named decision and an owner, as well as a current method that can serve as a baseline?
- Data. Do the sources for that decision exist, and do they reconcile within a tolerance the owner accepts?
- Latency. Does the refresh rate match the window in which someone can act?
- Reuse. Will a second use case or plant reuse the same data and measures later?
- Ownership. Who owns the KPI definitions, the pipelines and the support after go-live?
Worked Example: A Three-Plant Manufacturer
Picture a manufacturer with three plants making similar products on different MES versions. The numbers below are assumptions for illustration, not benchmarks or Kanerika results.
- Decision. The VP of operations wants to know where to recover capacity before buying a fourth line.
- Gate check. All three plants record stops and counts, but they define planned downtime differently, so the data gate fails until definitions align.
- Pick. Three plants and a comparison question point to a shared lakehouse with one semantic layer.
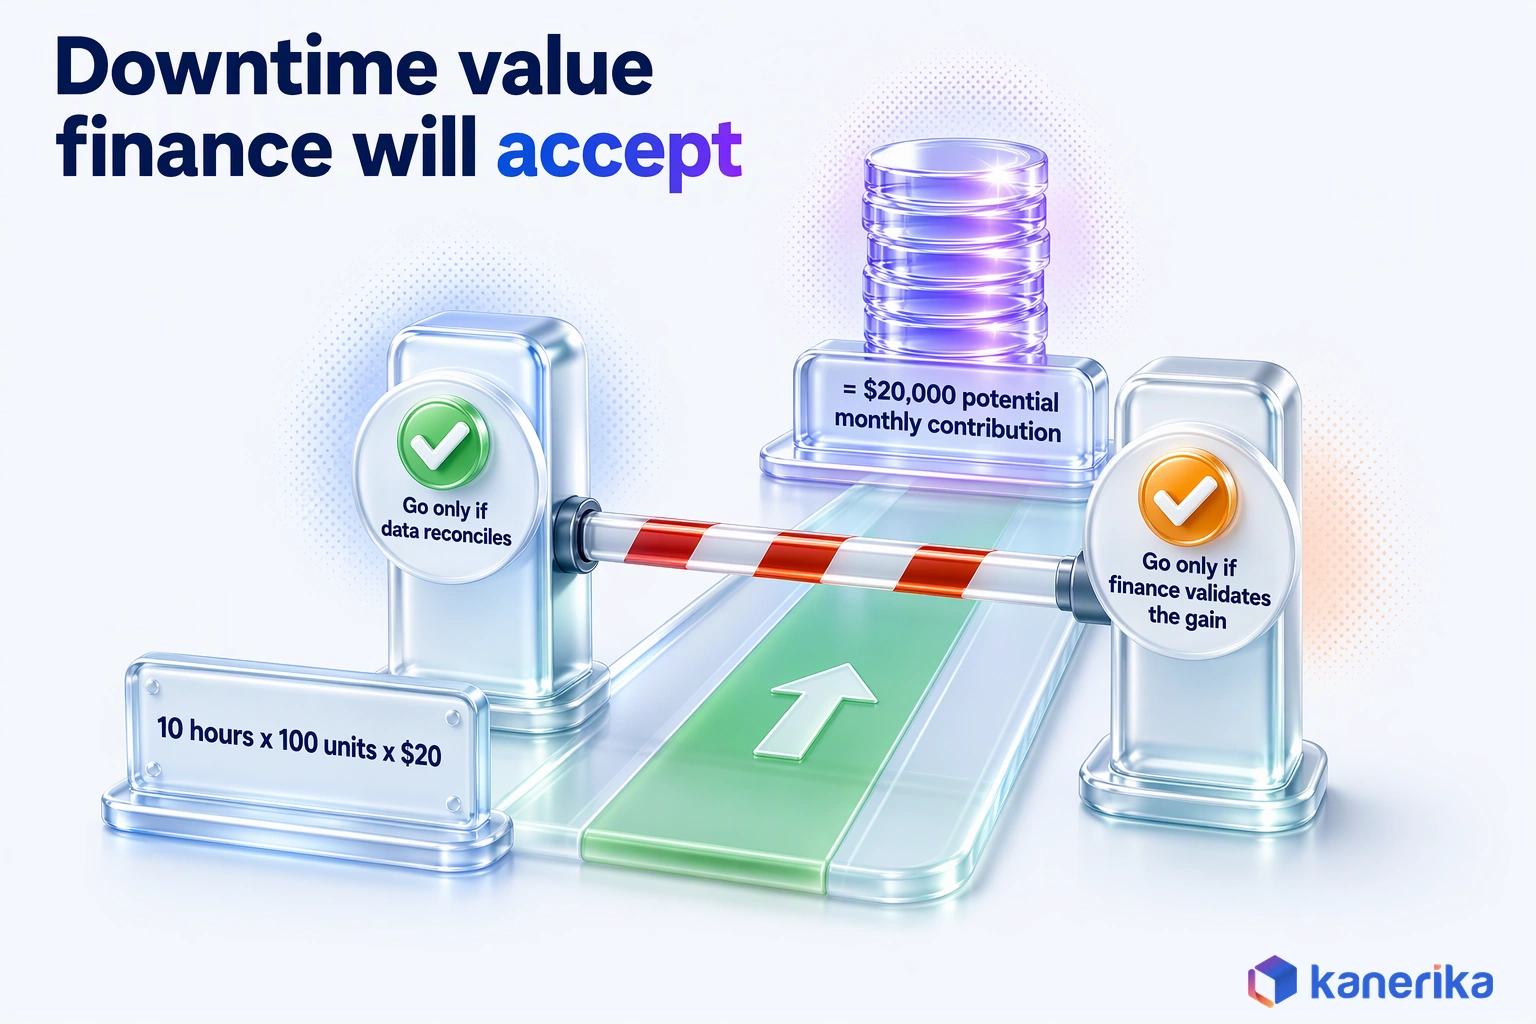
- Value estimate. Assume one line recovers 10 hours a month at 100 good units an hour and $20 contribution margin per unit. That is $20,000 of potential monthly contribution.
- Pilot scope. Start with OEE loss analysis on two lines in one plant, then add the other plants once the measures reconcile.
The estimate is only as good as its inputs, so finance should agree on the margin and the baseline before the pilot starts. The same formula also appears in the ROI section below.
Choosing BI Tools by Requirement, Not Feature Lists
Feature lists from BI vendors look much alike, so they rarely settle a choice. Requirements, on the other hand, do. Start from what the plants already license, what the sources can connect to and how much support the team can carry.
| Requirement | Question to ask |
|---|---|
| Existing licensing | What do you already pay for through Microsoft, SAP or another vendor? |
| Source connectivity | Can it read your MES, historian, QMS and ERP without custom code? |
| Semantic modeling | Can KPIs be defined once and then reused by every report? |
| Refresh | Does it support the freshness each decision needs, including streaming when required? |
| Row-level access per plant | Can each plant see only its own data while network leaders see all of it? |
| Deployment | Cloud, on-premises or hybrid, and does that match plant network rules? |
| Auditability | Can you trace a figure back to its source and also see who changed a measure? |
| Support burden | Who keeps it running after go-live, and do they have the skills? |
Licensing is a smaller part of the bill than many teams expect. As of November 2026, Power BI pricing lists Pro at $14.00 and Premium Per User at $24.00, each per user per month, paid yearly. Data preparation and KPI agreement usually cost more than seats.
For plants already on Microsoft 365 and Azure, Power BI and Microsoft Fabric are a natural fit, since identity and security carry over. Teams weighing Power BI against Tableau can find the head-to-head in Power BI vs Tableau.
Cost, Effort and ROI: Building the Business Case
Most of the effort in manufacturing BI goes into data, not dashboards. Source access, identifier mapping and KPI agreement take longer than building the reports. So a business case that budgets only for licenses and dashboard design will run short.
The table shows where effort goes and what evidence to gather before estimating each workstream.
| Workstream | Effort driver | Evidence before estimating |
|---|---|---|
| Source access | Number of systems, versions and network rules | A list of systems per plant, together with their owners |
| Data mapping | How many identifiers differ across systems | A sample of machine and product codes from each source |
| KPI definitions | How far plants disagree today | Each plant’s current OEE and downtime formulas |
| Data platform | Volume, refresh needs and reuse | Expected use cases over the next year |
| Reports and alerts | Number of decisions and user groups | A named owner per decision |
| Adoption | Shifts, sites and training needs | Who uses the data today, and how |
An ROI Formula Finance Will Accept
Finance teams trust ROI cases that show their working. The formula for downtime value is simple: recovered hours times good units per hour times contribution margin. The harder part is agreeing on each input before the project starts.
- Cost lines. List licenses, platform capacity, build effort, support and training.
- One-time versus recurring. Separate build costs from monthly run costs, since finance treats them differently.
- Benefit types. Count recovered capacity and lower scrap, as well as less overtime and fewer expedited shipments.
- Baseline window. Agree on the months used as the “before” figure, and exclude unusual periods.
- Finance sign-off. Have the plant controller approve the margin and baseline in writing before the pilot starts.
Pilot Acceptance and Stop/Go Criteria
A pilot needs exit criteria agreed at the start, or else it drifts into a permanent project. Set the thresholds with the plant owner, because the right tolerance differs by product and process.
| Criterion | What to check |
|---|---|
| Data completeness | Share of shifts, lines and orders with full data |
| Reconciliation tolerance | Gap between BI totals and the system of record |
| Freshness | Data arrives before the decision window closes |
| Owner | A named person owns each KPI and settles disputes |
| Adoption | The intended users open it during their own meetings |
| Action completion | Logged actions are carried out and then checked |
| Validated benefit | Finance agrees the measured gain against the baseline |
Kanerika ran this kind of bounded pilot for a food and pharma manufacturer, covered under Results From Industrial Clients below. A validation framework checked that its data was complete before anyone relied on it.
Risks, Governance and Common Mistakes
Manufacturing BI fails in predictable ways, and almost all of them come down to trust in the numbers. Once supervisors catch a dashboard showing a wrong number, they go back to their spreadsheets. Each risk below therefore has a control that prevents it.
| Risk | Control |
|---|---|
| Plants define KPIs differently | A KPI dictionary with one owner per measure |
| Numbers do not match the system of record | Daily reconciliation reports, so gaps surface before meetings |
| Dashboards built with no decision in mind | Each report tied to a named decision and owner |
| Extraction slows production systems | Read-only replicas and throttled jobs |
| Wrong people see plant or personal data | Row-level security by plant and role |
| Shift data used to rank individuals | Report at crew level, with context alongside output |
| AI assistants invent their own definitions | Natural-language tools read only governed measures |
| Pilot never ends | Stop/go criteria agreed before the pilot starts |
| No one owns the system after go-live | Named owners for pipelines, models and support |
In the end, the common thread is ownership. Every KPI, pipeline and report needs a person who answers for it, and governance is mostly the habit of writing those names down.
How Kanerika Delivers Manufacturing BI
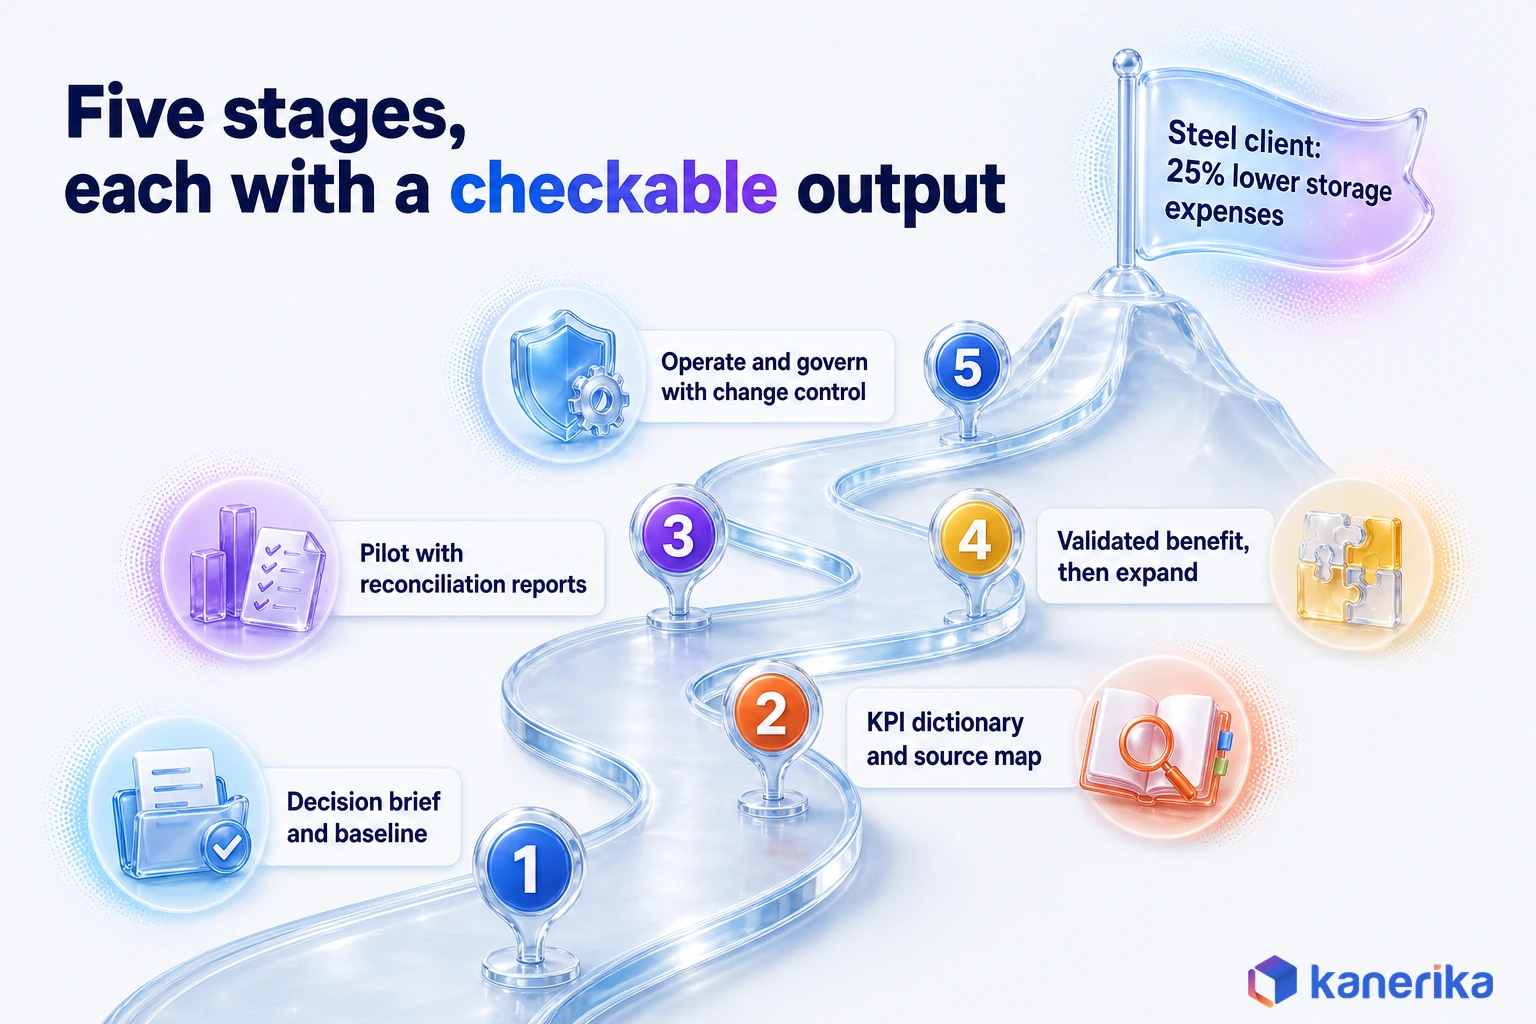
Kanerika builds manufacturing BI in five stages, each with a defined output. Every stage ends with something the plant can check, from a KPI dictionary to a reconciliation report.
- Select the decision and baseline. Pick one decision with an owner and record how it is made today. Output: a decision brief with baseline figures.
- Validate sources and define measures. Profile the MES, ERP, quality and maintenance data, then map identifiers and write the KPI dictionary. Output: a source map and signed-off definitions.
- Run a bounded pilot. Build the semantic model and the first reports on a small scope, with stop/go criteria. Output: a working pilot and reconciliation reports.
- Validate benefit and expand. Measure the gain against the baseline with finance, then add lines, plants or use cases. Output: a validated benefit and an expansion plan.
- Operate and govern. Hand over ownership, monitoring and change control for measures. Output: a support model and an access review cycle.
The Artifacts Behind Each Stage
Artifacts matter more than slide decks. A KPI dictionary lists each measure with its formula, source system, owner and known traps. Alongside it, a source map shows which system holds each identifier and how the codes join across MES, ERP and CMMS.
Reconciliation reports compare BI totals with MES and ERP totals for every shift and plant. A gap then shows up as a number with a cause, rather than as a complaint in the morning meeting. Change control closes the loop, so a measure only changes after its owner approves the new definition.
The 25% figure on the stage map is a client result, not a promise. It comes from the steel mill services provider described below.
The work runs through Kanerika’s data analytics services, built on Power BI and Microsoft Fabric. Meanwhile the manufacturing industry practice brings the plant context.
Results From Industrial Clients
Steel mill services provider. An on-site industrial steel mill services provider focused on North America, with a 96-year history, ran on a legacy system. Its complex interface and weak real-time analysis slowed decisions, so Kanerika organized the data with Dynamics AX and Azure and built Power BI dashboards. The result was a 25% reduction in storage expenses, a 40% productivity improvement and a 2.5% revenue increase, as the case study shows.
Southern States Material Handling (SSMH). SSMH, an industrial equipment and material handling provider, had service, parts, rental and sales data spread across separate systems. Kanerika unified it on Microsoft Fabric and Power BI with role-based dashboards. SSMH then reached 90% data accuracy and KPI reliability as well as 85% higher operational visibility, detailed in the SSMH case study.
Food and pharma manufacturer. When a pilot needs to de-risk the full build, Kanerika’s Microsoft Fabric data foundation case study for a food and pharma manufacturer shows the model. The four-week Proof of Value on Microsoft Fabric brought data from six business platforms into a bronze layer. A validation framework then checked that the data was complete before scale-up.
Karl for Plain-Language Questions
For natural-language questions on top of governed data, Kanerika’s Karl is a data analytics AI agent with pre-built analytics agents for manufacturing. It delivers answers in Teams, Power BI and Fabric, and because it runs in the client’s environment, it inherits existing access controls. Karl’s product page reports a 50% reduction in time-to-insight and 30% faster inventory reconciliation.
Kanerika Service
Data Analytics Services for Manufacturers
From KPI dictionary to semantic model and reconciliation reports, Kanerika builds manufacturing BI on Power BI and Microsoft Fabric, one validated decision at a time.
Explore Data Analytics ServicesBusiness Intelligence for Manufacturing: The Short Answer
Start with one decision that costs money when made badly, such as overtime, lot release or which asset to service first. Then define the KPIs it needs once, with an owner, and build only the data that decision requires.
For one plant with one decision, BI over curated extracts proves value quickly. For a plant network, however, a shared lakehouse or warehouse with one semantic layer keeps OEE comparable. It also lets each new use case reuse the same foundation.
So the approach to business intelligence for manufacturing comes down to scale: curated extracts for one plant with one decision, then a shared, governed foundation as plants multiply.
Frequently Asked Questions
What is business intelligence in manufacturing?
Business intelligence in manufacturing turns plant and business data into decisions people can act on. It joins MES, ERP, quality, maintenance and historian data at the grain of line, asset, lot and shift. Supervisors and managers then see measures such as OEE, scrap and downtime in one trusted model instead of several conflicting reports.
What data sources does manufacturing BI use?
The main sources are the MES for production orders and counts and the ERP for costs and inventory. Quality and maintenance systems add defects and work orders, while process historians add time-series machine data. Each source covers one slice of plant activity, so mapping their identifiers to each other is the main integration task.
What is the difference between manufacturing BI and manufacturing analytics?
Manufacturing BI reports what happened and why, using governed measures such as OEE and scrap rate. Manufacturing analytics is the wider field that also includes forecasting, optimization and machine learning. In practice the two share one data foundation, and predictive models are more reliable when they read the same definitions the BI reports use.
How do you govern KPI definitions across multiple plants?
Write a KPI dictionary that gives each measure one formula, one source system and one owner who settles disputes. Build those definitions into a shared semantic model so every report reads the same measure. Run reconciliation reports against MES and ERP totals, and change a definition only through a reviewed, logged process.
What should a manufacturing BI pilot include?
A good pilot covers one decision with a named owner, a recorded baseline and a small scope, such as two lines in one plant. It needs stop or go criteria agreed up front. These include data completeness, reconciliation tolerance, freshness and adoption, plus a benefit that finance validates against the baseline before rollout widens.
How does manufacturing BI differ from standard enterprise BI?
Enterprise BI mostly reports finance and sales data by customer or month, refreshed daily. Manufacturing BI works at the grain of line, asset, lot and shift, and it reads machine data that can change by the second. Its users include operators and supervisors on the floor, so freshness and simple views matter more.
What KPIs should manufacturers track with BI?
Start with the measures your first decision needs, usually OEE and its three parts, first pass yield, scrap rate and unplanned downtime. Add cycle time, schedule attainment, inventory turnover, on-time delivery and energy per unit as use cases grow. Write each definition down with a formula, a source system and one owner.
What is OEE and how does BI improve it?
OEE, or overall equipment effectiveness, multiplies availability, performance and quality to show how much planned time produces good output. BI improves it by splitting the loss into stops, slow cycles and defects, then ranking the reasons by line and shift. Teams fix the largest loss first and check the result against a baseline.
How long does a manufacturing BI implementation take?
There is no fixed timeline, because scope drives it, especially the number of plants, source systems and KPIs that need agreement. A bounded pilot usually comes first. A four-week Proof of Value on Microsoft Fabric, for example, brought data from six business platforms into one governed layer. Wider rollouts then expand plant by plant.
What is the role of AI in manufacturing BI?
AI adds forecasting and plain-language questions on top of BI. Models can predict failures or demand. Assistants can explain, for example, why scrap rose on one line. Both work well only when they read governed, consistently defined measures. So the KPI dictionary and semantic model should be in place before any AI tool is added.
What are examples of business intelligence in manufacturing?
Common examples include OEE loss analysis to recover line capacity and lot traceability to decide which batches to hold. Downtime analysis ranks assets for maintenance. Others cover cost and margin by product, energy per unit, supplier on-time delivery and cross-plant benchmarking. Each one ties to a named owner and a decision made again and again.
Does manufacturing BI need real-time data?
Only for decisions that someone can act on within minutes, such as stopping a line drifting out of tolerance. Rebalancing a shift works with refreshes every few minutes, while cost, scrap and supplier reviews run well on daily batches. Matching refresh to the decision window keeps build and running costs under control.
How much does a manufacturing BI implementation cost?
There is no fixed price, because cost scales with the number of plants, sources and KPIs. Most of it goes to source access, identifier mapping and KPI agreement rather than software. Microsoft lists Power BI Pro at $14.00 per user per month as of November 2026. Platform capacity, build effort, training and support make up the rest.