TL;DR
The 7 AI privacy risks businesses face in 2026 are training reuse, shadow AI, memorization, over-shared retrieval, undeleted logs, profiling, and vendor transfers. AI privacy means control over how AI systems collect, infer, store, share and delete personal data. Several of these risks start in retrieval, prompts and logs rather than inside the model.
EU AI Act transparency duties have applied since August 2026, and Annex III high-risk duties follow on 2 December 2027. California’s CCPA rules on risk assessments and automated decisions took effect on 1 January 2026. Each of the seven has a named first control, such as permission-aware retrieval or prompt DLP, so a business can start fixing all of them this quarter.
Key Takeaways
- Personal data enters an AI system at five points, so each point needs its own control rather than one policy for everything.
- Shadow AI is now measurable, because IBM linked it to one in five breaches and $670,000 in extra breach cost.
- Copilots and agents inherit whatever their search index can read, so access has to be enforced inside retrieval.
- Erasure requests must reach chat logs, vector stores and backups as well as the source record.
- The EU AI Act has banned workplace emotion recognition since February 2025, while its high-risk rules start on 2 December 2027.
- A six-step program, with a named owner for each step, turns the seven fixes into routine work.
The Copilot That Answered Too Well
Picture a support team that connects a new AI copilot to its CRM. An agent asks for a summary of a billing ticket, and the answer arrives in seconds.
The summary is accurate. It also contains another customer’s home address and full order history. That happened because the search index behind the copilot ignored the source system’s permissions.
Nobody attacked anything, and no firewall failed. This scenario is illustrative, but it shows the shape many AI privacy failures take, a design gap rather than a break-in. The data was already inside the company, so the AI simply handed it to the wrong person.
That gap is risk 4 in the list below. The other six follow the same pattern, so each one comes with a first control a business can put in place now.
What Is AI Privacy, and Why Is It Harder Than Ordinary Data Privacy?
AI privacy is the practice of controlling how AI systems collect, infer, store, share and delete personal data. It covers the models a business trains, the copilots it buys and the prompts its staff type every day.
Ordinary data privacy assumes data sits in known tables with known owners. AI breaks that assumption in three ways. A model can infer facts nobody shared and reuse data for purposes nobody approved. It can also remember fragments of training data after the source file is gone.
Take a retailer that trains a churn model on loyalty-card data. The model may learn that certain baskets signal pregnancy or illness. As a result, the business holds sensitive inferences it never collected directly. Its privacy team then has to treat them with the same care as the raw records.
For that reason, AI needs its own privacy controls rather than a footnote in the existing policy. Wider issues such as hallucination, bias and IP misuse belong to the broader set of generative AI risks, while this guide stays with personal data.
AI Privacy vs. AI Security vs. AI Governance
The three terms overlap, which is why ownership often falls between teams. The table separates them by the question each one answers.
| Discipline | Question it answers | Typical owner | Example control |
|---|---|---|---|
| AI privacy | Should this personal data be used here, by whom, and for how long? | Privacy office or DPO | Purpose register and retention schedule |
| AI security | Can someone steal, poison or misuse the system? | CISO and security team | Prompt-injection testing before launch |
| AI governance | Which AI uses are allowed, who approves them, and how are they checked? | AI steering group or risk committee | Use-case approval and a model inventory |
In practice the three share one inventory of AI systems and one set of data maps, and our guide to AI governance covers the operating model that ties them together.
On-Demand Webinar
Data Security Risks in AI: How Microsoft Purview Helps
Privacy and security teams share one inventory of AI systems and data. Kanerika’s on-demand session shows how Microsoft Purview discovers, labels and protects sensitive data before AI tools can expose it.
Watch the Webinar →How Personal Data Moves Through an AI System
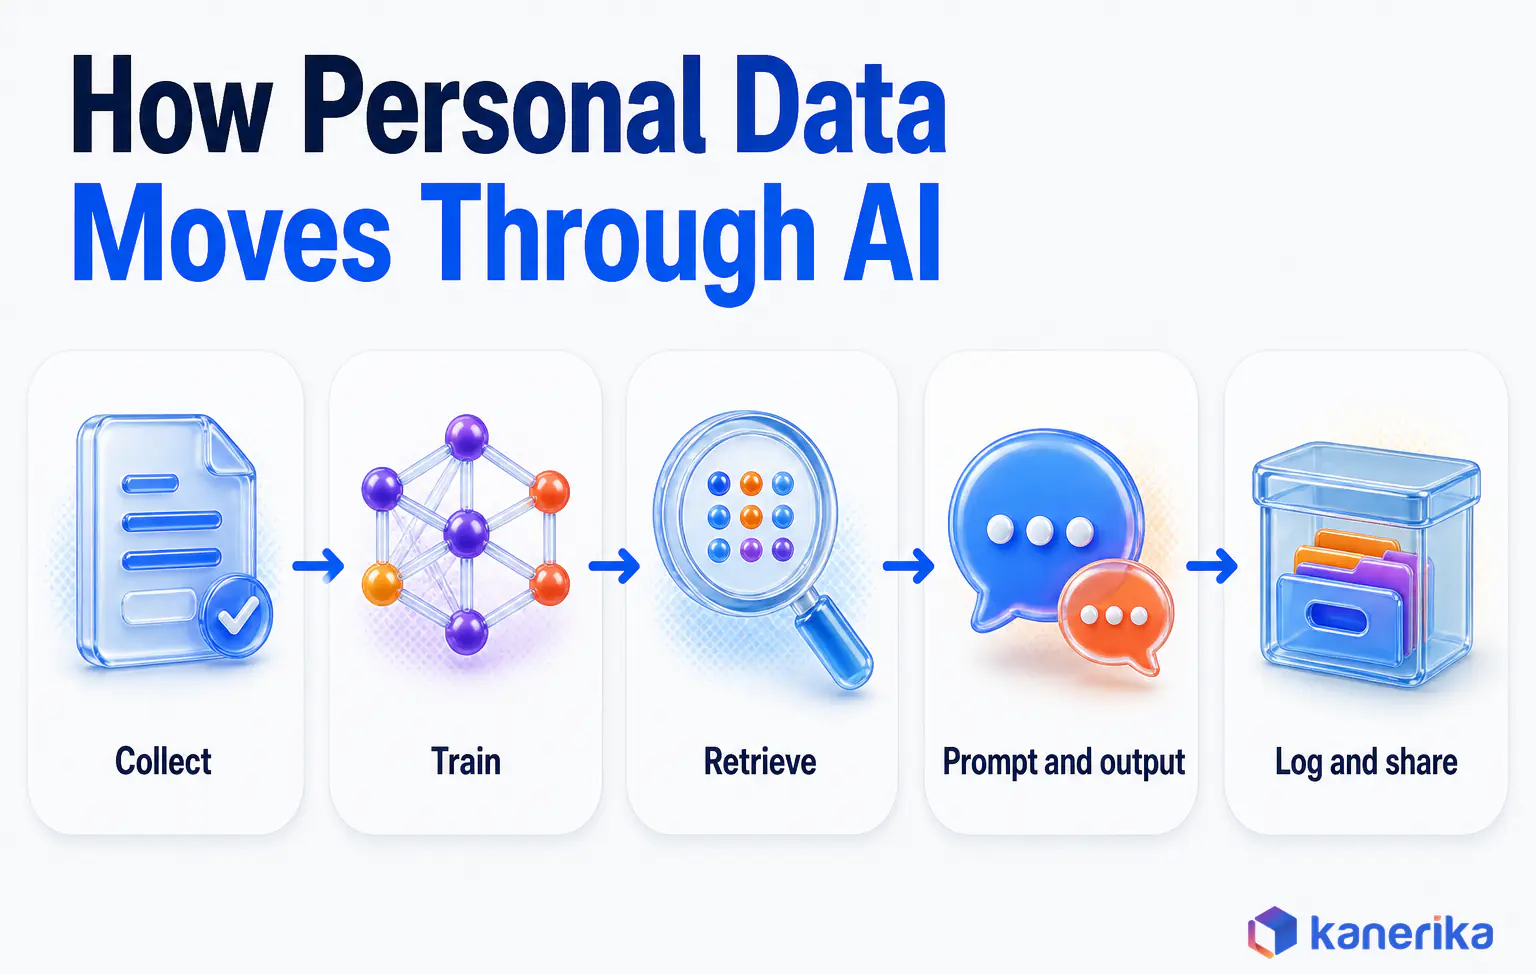
Privacy risk follows the data, so the first job is to see where personal data enters and leaves an AI system. A typical copilot or RAG application touches five points, and each one fails in a different way.
The data itself varies widely. It includes identifiers such as names and account numbers, behavioral records such as clicks and purchases, and biometric data such as faces and voices. Location trails and the content of emails, chats and calls are in scope too.
- Collection. Data arrives from forms, apps, sensors, call recordings and third parties, often under consent written for another purpose.
- Training and fine-tuning. Records are copied into training sets, so they shape model weights and can be memorized.
- Retrieval. RAG pipelines, copilots and agents search document stores and business systems when a user asks a question.
- Prompts and outputs. Employees and customers type, paste or upload data into the model, and the answers can reveal, combine or infer personal data that then gets copied into emails, tickets and reports.
- Logs, embeddings and vendors. Chat histories, vector stores, backups and provider systems keep copies long after the conversation ends.
Each point needs a different control. For example, a training-set filter does nothing for a copilot that reads the CRM live. Likewise, a retention rule on chat logs does nothing for data a vendor keeps. The list that follows tracks this path from start to finish.
The 7 AI Privacy Risks Businesses Face in 2026
These seven risks run along the data path, from what goes into a model to who holds copies afterwards. Each one ends with the first controls that reduce it, so the list doubles as a starting plan.
The stakes are concrete. IBM’s breach research shows the problem growing. In 2025, 13% of organizations reported breaches of AI models or applications, and 97% of those lacked proper AI access controls. Its 2026 study of 602 organizations put the global average breach at a record $4.99 million.
1. Customer Data Reused for AI Training Without a Valid Purpose
Purpose creep is the oldest privacy problem, and AI has made it tempting again. Data collected to ship orders or answer tickets starts to look like free training material once a data science team needs examples.
Regulators on both sides of the Atlantic have pushed back. In February 2024, the US Federal Trade Commission warned companies about quietly changing their terms of service to allow AI training. A surreptitious, retroactive change, it said, may be unfair or deceptive.
Europe went further. The EDPB’s Opinion 28/2024, adopted on 18 December 2024, said unlawfully processed training data can affect whether a model may lawfully be deployed. The exception is a model that is properly anonymised.
How to reduce it
- Keep a purpose register that lists every dataset approved for training, along with the reason it was approved.
- Run a legal-basis check before any personal data enters a training or fine-tuning set.
- Give customers clear notice before a policy change adds AI training, and never apply it retroactively.
2. Employees Pasting Sensitive Data Into Unapproved AI Tools (Shadow AI)
Shadow AI is any AI tool staff use without approval, from a free chatbot to a browser extension that summarizes email. It spreads because the tools are useful, and also because the approved option is often slower or missing.
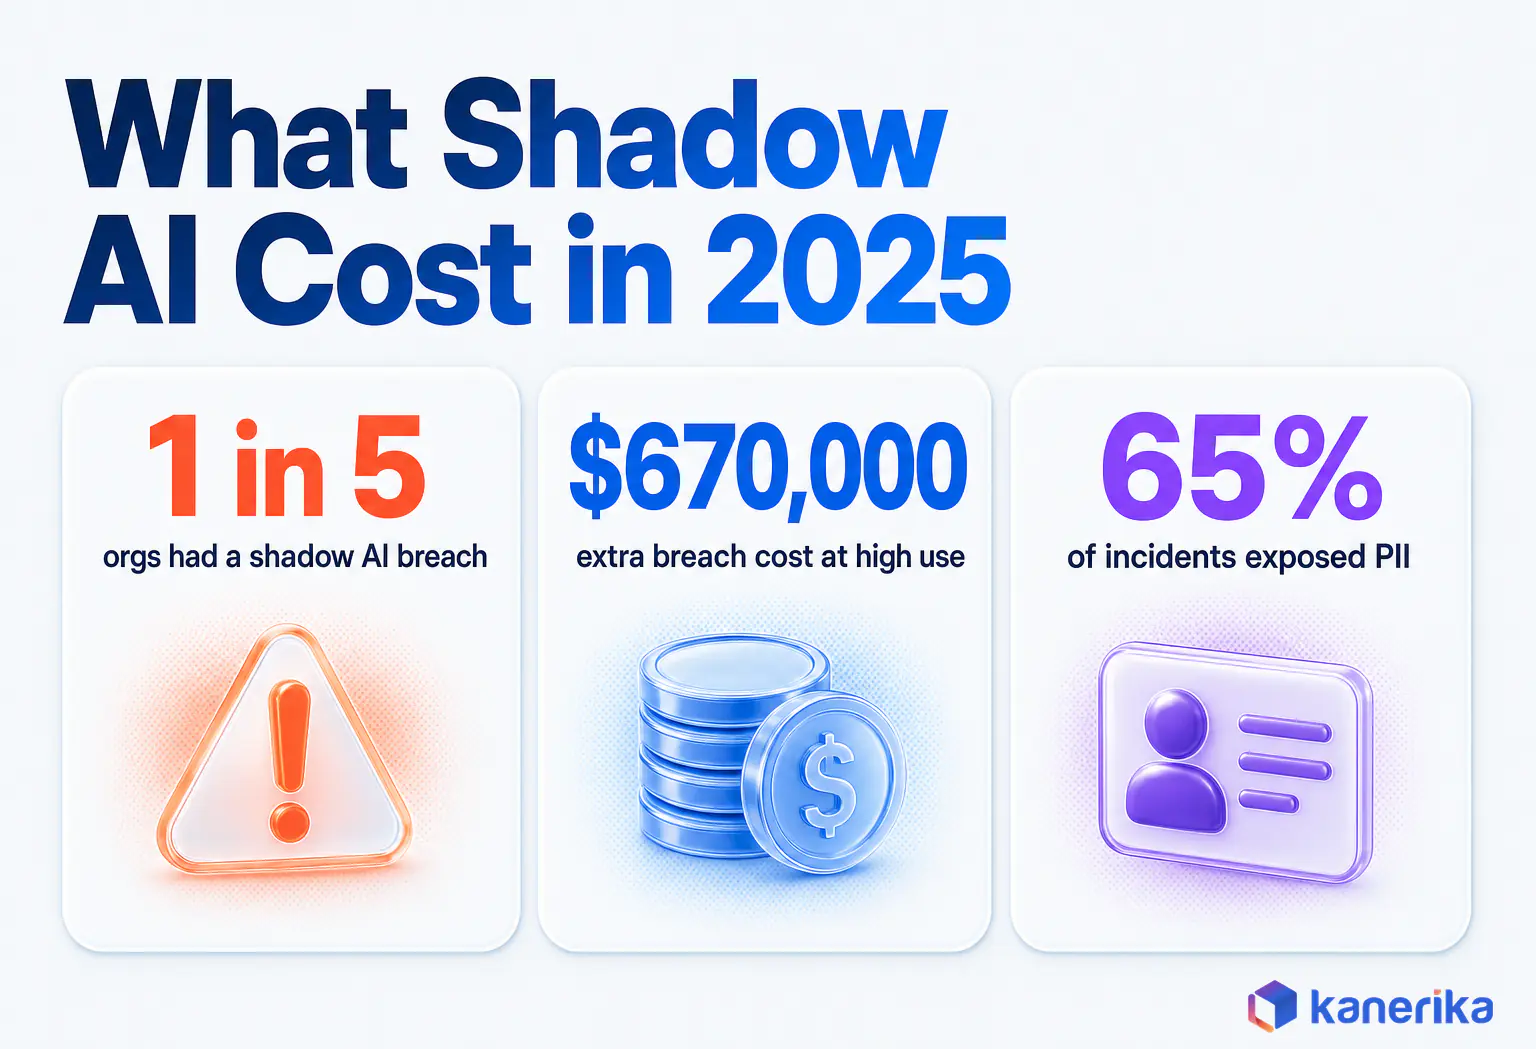
The cost is now measurable. IBM’s 2025 study also found that one in five organizations had a breach involving shadow AI. High levels of shadow AI also added $670,000 to the average breach cost.
Personal data was compromised in 65% of those shadow AI incidents, compared to 53% across all breaches. Even so, only 37% of organizations had policies to manage AI or detect shadow AI at all.
A ban alone leaves the demand in place. The safer route is an approved tool with guards on what goes into it. Our shadow AI policy guide covers detection and policy design in detail.
How to reduce it
- Provide an approved enterprise AI tool, with contract terms that rule out training on your data.
- Add prompt-level DLP so personal data is blocked or masked before it reaches any model.
- Publish a short AI use policy, then monitor traffic to unapproved AI domains.
3. Models That Memorize and Leak Training Data
Large models learn more than patterns. They can also store exact snippets of training data, such as names, emails and phone numbers. Then the right prompt can make them repeat those details.
Researchers showed this at scale. In a paper published on 28 November 2023, Nasr and colleagues extracted gigabytes of training data from open and closed models, including ChatGPT. One attack made the model emit training data 150 times more often than when it behaved normally.
OWASP lists sensitive information disclosure as LLM02 in its 2025 list of LLM risks, and data sanitization is among its first fixes. Fine-tuned models carry the same risk, especially when the dataset is small and sensitive.
How to reduce it
- De-identify personal fields and remove duplicate records before training or fine-tuning.
- Red-team every model release with extraction tests that probe for memorized personal data.
- Filter outputs for personal data patterns before answers reach users.
For prompt injection and the wider attack surface, see our guide to generative AI security controls.
4. Copilots, RAG and AI Agents That See More Than the User Should
This is the risk from the opening scenario, and it grows with every system a copilot connects to. Retrieval-augmented generation searches company content at answer time, so an answer is only as private as the index behind it.
When the index runs under a service account that can read everything, every user inherits that account’s access. Agents raise the stakes further, since they act as well as read. They send emails, update records and call other tools.
IBM’s 2026 research found that about one in five organizations reported an AI-related breach. Of those, 92% lacked proper AI access controls.
How to reduce it
- Make retrieval permission-aware, so results are trimmed to the asking user’s rights before the model sees them.
- Apply sensitivity labels to source content, then keep labelled items out of broad indexes.
- Give each agent its own least-privilege identity, with logged actions and human approval for high-impact steps.
Our guide to agentic AI governance covers agent permissions in depth. Later in this post, the Kanerika case study shows the retrieval fix working in production.
5. Prompts, Logs and Embeddings Nobody Deletes
Every AI interaction leaves copies behind. Prompts land in chat histories, documents become embeddings in a vector store, and both end up in backups and vendor logs.
Those copies matter the moment a customer asks for erasure. The request has to reach the chat log, the vector store and the backup, rather than just the CRM record. Removing data from a model that has already been trained is harder still, because it usually means retraining.
Old copies also widen exposure, because a two-year-old chat log that nobody needs can still leak.
How to reduce it
- Extend the retention schedule so it names every AI store, including prompts, embeddings and evaluation sets.
- Test deletion by tracing one dummy record through every store until it is gone everywhere.
- Set short default retention for chat logs, and switch off provider-side history when it is not needed.
Checklist
Generative AI Checklist for Secure AI Adoption and Governance
Retention, access and vendor terms are easy to miss when a new AI tool goes live. Kanerika’s downloadable checklist helps teams confirm the security and governance basics before rollout.
Get the Checklist →6. Profiling, Inference and Biometric Processing
AI is very good at guessing what people never said. For example, purchase patterns can suggest a health condition, location trails can point to a religion, and writing style can hint at age or mood.
Biometric data draws the heaviest penalties. On 3 September 2024, the Dutch data protection authority fined Clearview AI EUR 30.5 million. The fine was for building a facial recognition database of more than 30 billion photos. It also added penalty orders worth up to EUR 5.1 million if the violations continue.
The EU AI Act now bans several of these uses outright. Since February 2025 it has prohibited untargeted scraping to build facial recognition databases, as well as emotion recognition in workplaces and education. Biometric categorisation that deduces protected traits is banned too.
How to reduce it
- Run a privacy impact assessment before any profiling or biometric use reaches production.
- Keep a banned-use list that mirrors the EU AI Act prohibitions, even if a team works outside the EU.
- Require human review whenever a significant decision rests on inferred traits.
The fairness side of profiling, including bias in automated decisions, is covered in our guide to AI ethical concerns.
7. Third-Party AI Vendors and Cross-Border Data Transfers
Few businesses build every model themselves. Each AI vendor in the chain may store prompts or use them to improve its own models. It may also pass them to sub-processors or process them in another region.
Picture a meeting transcription tool rolled out to a sales team. The recordings hold client names, deal terms and personal remarks. Yet the default settings may send them to a region the privacy notice never mentioned. The data crosses a border even though nobody signed anything unusual.
Under GDPR, personal data can generally leave the EU only to a country with an adequacy decision. Otherwise it needs safeguards such as standard contractual clauses (GDPR Chapter V). That makes a silent region change a legal problem as well as a contract one.
How to reduce it
- Use a vendor checklist that covers training opt-out, retention, sub-processors, processing region and breach notice.
- Write those answers into the contract and data processing terms, rather than relying on the sales deck.
- Pin processing to approved regions, then review the vendor list at every renewal.
Kanerika Service
AI Governance Services
Need the seven controls designed, owned and audited as one program? Kanerika helps enterprises set up AI policies, data protection and oversight that keep copilots, agents and vendors inside privacy rules.
Explore AI Governance ServicesAI Privacy Risks Mapped to Controls and Owners
This table pulls the seven risks into one view, with the first control for each and the team that usually owns it.
| Risk | Where it happens | First control | Owner | Rule that applies |
|---|---|---|---|---|
| 1. Training data reuse | During training and fine-tuning | Purpose register, then a legal-basis check | Privacy office | GDPR, EDPB Opinion 28/2024, FTC guidance |
| 2. Shadow AI | When staff paste prompts and uploads | Approved AI tool plus prompt DLP | Security | GDPR, CCPA |
| 3. Memorization and leakage | Model weights and outputs | De-identified training data, then extraction tests | Data science | GDPR, OWASP LLM02 guidance |
| 4. Over-shared retrieval | When RAG, copilots and agents search | Permission-aware retrieval and scoped agent identities | Data platform | GDPR, CCPA cybersecurity audits |
| 5. Undeleted prompts and logs | Logs, embeddings and backups | AI-wide retention schedule, then a deletion test | Data platform with privacy | GDPR erasure, CCPA deletion |
| 6. Profiling and biometrics | When outputs infer traits | Impact assessment before launch, plus a banned-use list | Privacy office with legal | EU AI Act bans, CCPA ADMT rules |
| 7. Cross-border vendor transfers | Once data reaches vendor systems | Checklist before signing, then region pinning | Procurement with legal | GDPR transfer rules, CCPA contracts |
No single team owns all seven. That is why the program section below assigns every activity to a named owner.
What AI Privacy Rules Expect in 2026
Rules differ by region, but they ask for similar things. Know what personal data each AI system uses, justify that use, limit access, and explain significant automated decisions.
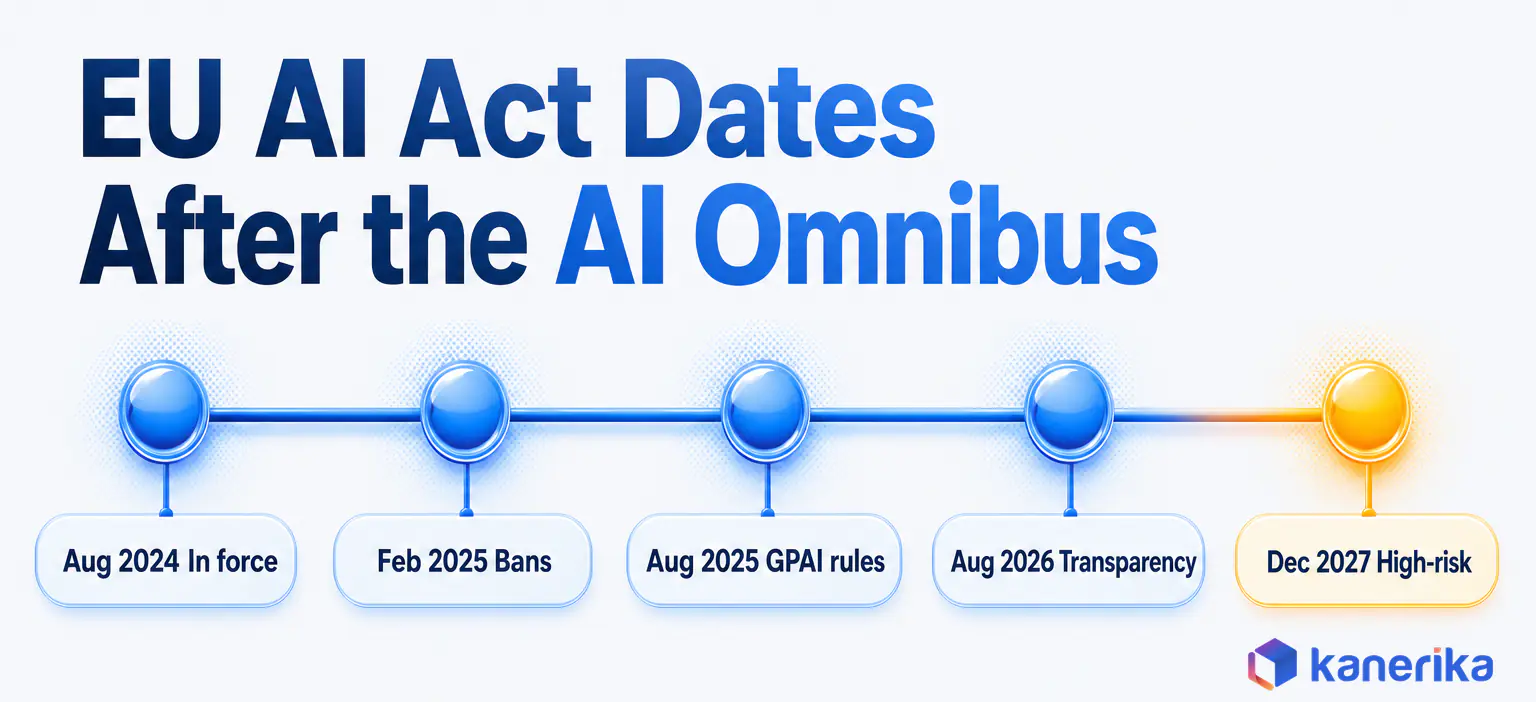
Dates matter more than usual, because the EU timeline moved. The AI Omnibus amendment entered into force on 27 July 2026. The European Commission’s AI Act page now lists 2 December 2027 for Annex III high-risk obligations and 2 August 2028 for high-risk AI built into regulated products. Older guides that still say August 2026 for high-risk systems are out of date.
In the US, California moved first on automated decisions. The CCPA regulations approved in September 2025 took effect on 1 January 2026. They cover risk assessments, annual cybersecurity audits, and consumer access and opt-out rights for automated decision-making technology.
| Rule | What it asks of AI systems | Key date |
|---|---|---|
| GDPR with EDPB Opinion 28/2024 | Lawful basis for training and deployment, plus case-by-case anonymity tests | Opinion adopted 18 Dec 2024 |
| EU AI Act, after the AI Omnibus | Bans on certain biometric and emotion uses, transparency duties, high-risk obligations | Bans since 2 Feb 2025; transparency 2 Aug 2026; Annex III high-risk 2 Dec 2027 |
| California CCPA regulations | Risk assessments, annual cybersecurity audits, access and opt-out rights for ADMT | Effective since 1 Jan 2026 |
| NIST AI RMF Generative AI Profile (AI 600-1) | Voluntary practices for managing generative AI risks, such as privacy | Published 26 Jul 2024 |
The NIST Generative AI Profile is voluntary, but it gives US teams a shared reference when no binding AI rule applies. For obligations law by law, see our GDPR and CCPA compliance guide. New laws as they pass are tracked in our coverage of AI regulation. Privacy teams that want a certifiable standard can look at ISO 27701 certification.
Which Privacy-Preserving Technique Fits Which AI Use Case?
Controls decide who can see data. Privacy-preserving techniques change the data itself, so less personal information exists to leak in the first place.
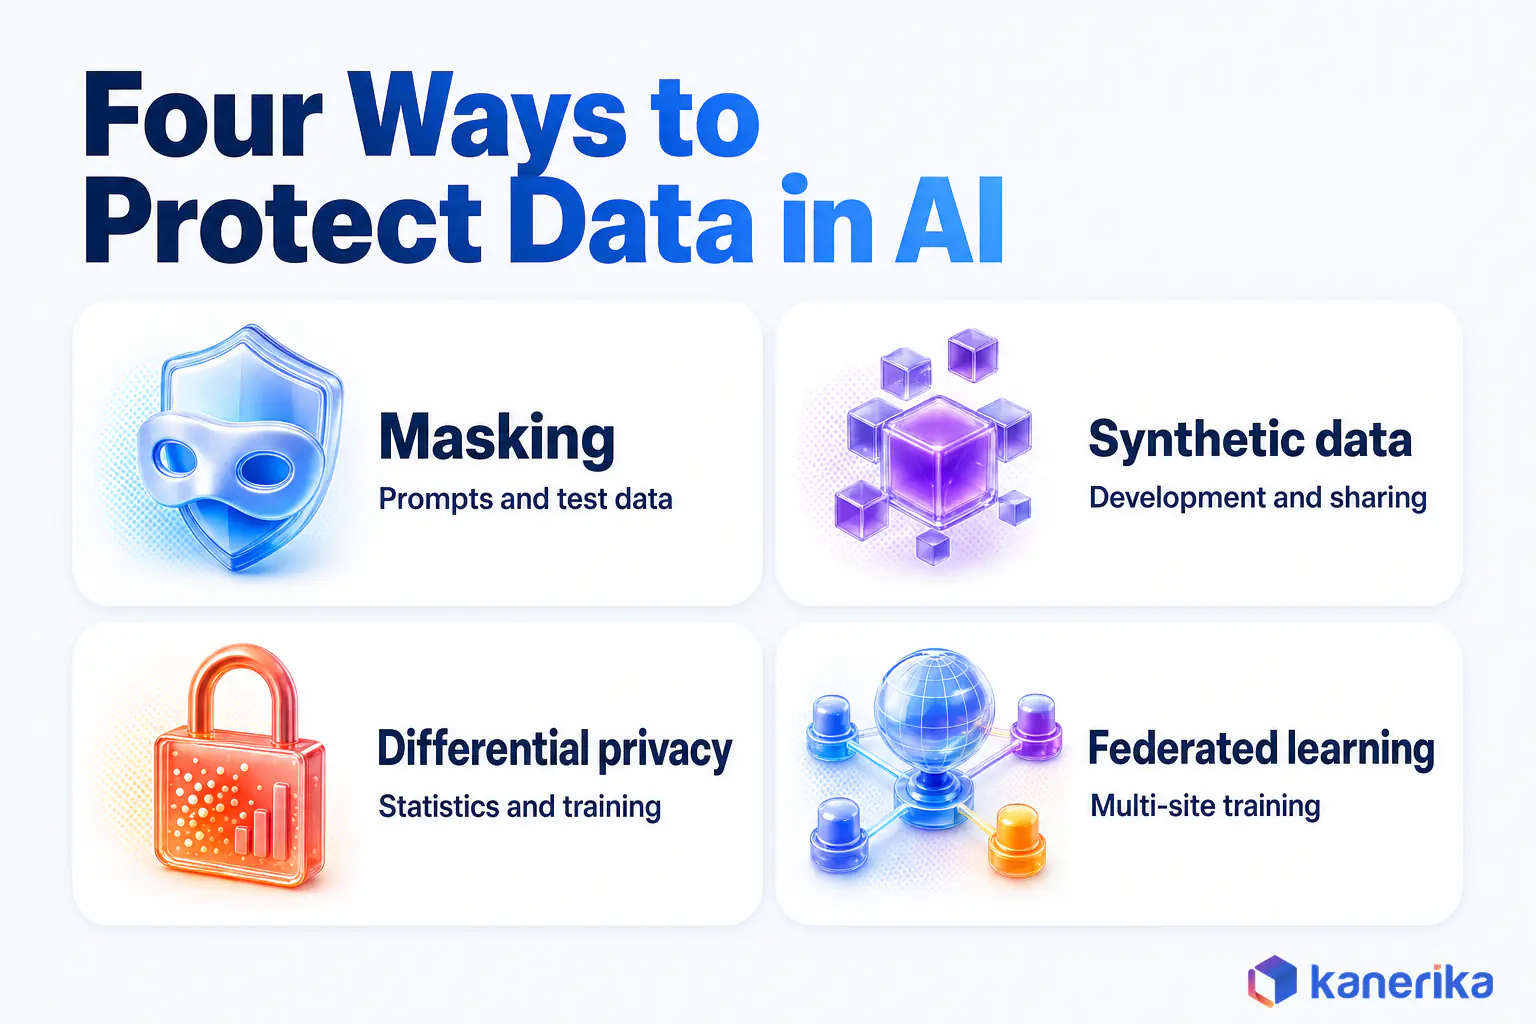
No single technique fits every case, since each one costs something in accuracy or effort. The table compares four common options by what they protect and where they work best.
| Technique | What it protects | Best for | Trade-off |
|---|---|---|---|
| Masking and tokenization | Direct identifiers such as names, IDs and card numbers | Prompts, test data, analytics | Indirect details can still re-identify people |
| Synthetic data | Real records, replaced by generated look-alikes | Model development, testing, sharing with vendors | Rare cases and edge patterns may be lost |
| Differential privacy | Individuals inside aggregate results and trained models | Statistics and training on sensitive datasets | Added noise reduces accuracy, especially for small groups |
| Federated learning | Raw data, since it stays on local devices or sites | Training across hospitals, branches or devices | Harder to run, and model updates can still leak details |
A practical pattern combines them. Masking cleans prompts and documents, while synthetic data feeds development. Differential privacy or federated learning then protects training on the most sensitive sets.
AI can also work for privacy rather than against it. Classifiers find personal data hidden in unstructured files, and redaction agents strip it from documents before they reach a model. Our guide to data anonymization techniques explains each method in more depth.
A 6-Step AI Privacy Program for Enterprises
A program turns the seven fixes into routine work. Each step names an action, an artifact and a decision rule, so progress can be checked rather than assumed.
- Inventory AI systems and map data flows. List every model, copilot, agent and AI vendor, then trace personal data through the five points. The artifact is an AI system register, and no system goes live without an entry.
- Classify and minimize data before it reaches a model. Label sensitive fields, then strip what the use case does not need. The artifact is a minimization record, so a field the outcome does not need never enters a prompt, index or training set.
- Run a privacy impact assessment for high-risk uses. Cover profiling, biometrics, automated decisions and health or children’s data. The artifact is a DPIA or CCPA risk assessment. High residual risk means a redesign or a documented sign-off.
- Enforce access in retrieval and agent identities. The artifact is an access design per AI system. Results are trimmed to the user’s permissions, and every agent runs under its own scoped identity.
- Review vendor terms. The artifact is the risk 7 checklist plus signed data processing terms. Unless the vendor rules out training on your data and names a processing region, there is no contract.
- Test before launch, monitor after, and keep an incident playbook. The artifact is a test report plus a monitoring view. A failed leakage test blocks release until it is fixed.
Our AI compliance framework guide shows how these steps fit a wider control set with evidence for auditors.
Who Should Own AI Privacy Inside an Enterprise?
Gaps open at the handoffs between teams, so ownership is worth agreeing before the first system goes live. A workable split looks like this.
- Privacy office or DPO is accountable for the AI system register and impact assessments, and leads the response to any privacy incident.
- Security owns access in retrieval, agent identities and incident containment.
- Data and platform teams build the register, run retrieval controls and apply retention rules across AI stores.
- Business owners complete impact assessments for their use cases, since they know why the data is needed.
- Legal and procurement sign off vendor terms, then review them at every renewal.
The exact split varies by company size, and a smaller firm may merge privacy and legal into one seat. Still, every activity needs one accountable owner. Shared ownership tends to mean no ownership at all.
How Kanerika Builds Privacy Into Enterprise AI
Kanerika starts every enterprise AI engagement with the data path rather than the model. So the first deliverable is a map of where personal data enters, moves and rests across the planned system. That map also names every store that holds prompts, embeddings or logs, which turns risks 1 and 5 into concrete purpose and retention decisions.
Classification and labelling come next, usually with Microsoft Purview for sensitivity labels, DLP policies and AI data discovery. Susan, Kanerika’s PII redaction agent, then removes names, dates, locations and numbers from documents before they reach a model. Its product page states that it adheres to GDPR, CCPA and HIPAA standards. Because labels travel with the content, DLP rules can then stop a labelled file from reaching an unapproved AI tool.
Access is enforced inside retrieval rather than bolted on afterwards. That choice decided the outcome for an investment bank. Its access controls sat outside the retrieval process, so every new retrieval path reopened a compliance question.
Kanerika built chat-based retrieval across the bank’s document repositories and databases, with KlarityIQ handling the unstructured documents. Role-based access control was applied at the retrieval layer itself. As a result, information retrieval became 43% faster, with 100% role-based compliance at the point of retrieval. The bank also saw a 35% gain in workforce efficiency.
Case Study
43% Faster Document Retrieval for an Investment Bank
Kanerika built chat-based retrieval across an investment bank’s document repositories and databases, with role-based access control applied inside the retrieval layer. Information retrieval became 43% faster with 100% role-based compliance at the point of retrieval.
Read the Case Study →That project is the direct fix for risk 4. Kanerika also holds ISO 27001 and ISO 27701 certification and SOC 2 compliance, so the same discipline applies to client data during delivery. Teams that want one partner across policy, platform and delivery can start with our AI governance services.
Wrapping Up
AI privacy failures rarely look dramatic. A copilot reads too widely, a log is kept too long, or a vendor term goes unread. The rules now attach dates and fines to those gaps, from the EU AI Act bans to California’s CCPA regulations. The good news is that every one of the 7 AI privacy risks businesses face in 2026 has a named first control, from a purpose register for training data to region pinning for vendors, and each can start this quarter.
Frequently Asked Questions
What is AI privacy?
AI privacy is the practice of controlling how AI systems collect, infer, store, share and delete personal data. It covers models a business trains, copilots it buys and prompts its staff type. It differs from ordinary data privacy because AI can infer facts nobody shared and remember training data long after the source is deleted.
What are the biggest AI privacy risks for businesses in 2026?
The seven biggest risks are customer data reused for training, shadow AI, model memorization, copilots that over-share through retrieval, prompts and logs nobody deletes, profiling and biometric processing, and third-party vendor transfers. Each has a clear first control, such as a purpose register, prompt DLP, permission-aware retrieval, retention limits or a vendor checklist.
How can businesses improve privacy in AI systems?
Start with an inventory of every AI system and the personal data it touches. Then minimize data before it reaches a model, run impact assessments for high-risk uses and enforce access inside retrieval. Review vendor terms, set retention limits for prompts and logs, and test for leakage before launch. Assign each step a named owner.
What is the difference between AI privacy and AI security?
AI privacy asks whether personal data should be used, by whom and for how long. AI security asks whether someone can steal, poison or misuse the system. Privacy is usually owned by the privacy office or DPO, while security sits with the CISO. Both rely on the same AI system inventory and data maps.
Does GDPR apply to AI systems?
Yes, whenever an AI system processes personal data of people in the EU. That includes training, fine-tuning, retrieval and outputs. The EDPB’s Opinion 28/2024 says model anonymity is assessed case by case. It adds that unlawfully processed training data can affect whether a model may be lawfully deployed, unless the model is anonymised.
What does the EU AI Act require for privacy in 2026?
Bans on untargeted facial scraping, workplace emotion recognition and biometric categorisation of protected traits have applied since February 2025. Transparency duties apply from 2 August 2026. After the AI Omnibus, which entered into force on 27 July 2026, Annex III high-risk obligations start on 2 December 2027 rather than August 2026.
Do US privacy laws regulate AI decision-making?
Some do. California’s CCPA regulations, effective 1 January 2026, require risk assessments and annual cybersecurity audits for covered businesses. They also give consumers access and opt-out rights for automated decision-making technology. At the federal level, the FTC has warned that quietly changing terms to allow AI training may be unfair or deceptive.
Is AI a threat to privacy?
AI can threaten privacy when it is deployed without controls. It can expose data through over-permissioned copilots, leak memorized training records, or infer sensitive traits like health or religion. Many of these problems arise without any attacker involved. Data inventories, access controls inside retrieval and short retention periods reduce the threat to a manageable level.
Can AI access your personal information?
Yes, when it is connected to systems that hold it. A copilot or AI agent can read whatever its search index or service account can reach, including CRM records, emails and files. Training data may also include personal details. Permission-aware retrieval and least-privilege agent identities limit what an AI tool can see to what each user may see.
Does AI collect data without consent?
It can. Some AI tools log prompts and uploads by default, and some vendors have changed their terms to allow training on customer data. The US FTC warned in February 2024 that quiet, retroactive terms changes may be unfair or deceptive. Businesses should check consent, notices and vendor terms before personal data enters any AI system.
Can I trust AI tools with personal or customer information?
Only after checking how the tool handles data. Confirm whether the vendor trains on your inputs, how long it keeps prompts, which sub-processors it uses and where processing happens. Prefer enterprise plans with contractual no-training terms. Then mask or redact personal data before it is sent, so less sensitive information leaves your control.
What is shadow AI and why does it create privacy risk?
Shadow AI is any AI tool employees use without approval, such as free chatbots or browser extensions. Staff paste customer data, contracts or code into them, outside company controls. IBM’s 2025 research found one in five organizations had a breach involving shadow AI, and high shadow AI use added $670,000 to breach costs.
Can AI models leak their training data?
Yes. Research by Nasr and colleagues in 2023 extracted gigabytes of training data from open and closed language models, including ChatGPT. Models can memorize names, emails and phone numbers and repeat them under the right prompts. De-identifying training data, running extraction tests before release and filtering outputs for personal data all reduce the risk.
Can anonymized data be re-identified by AI?
Often, yes. Masking direct identifiers such as names leaves indirect details like location, age and purchase history, and AI is good at linking those back to a person. The EDPB says a model’s anonymity must be assessed case by case. Combining masking with synthetic data or differential privacy gives much stronger protection than masking alone.
Which privacy-preserving techniques work best for AI?
It depends on the use case. Masking and tokenization suit prompts and test data. Synthetic data works well for development and vendor sharing. Differential privacy protects individuals in statistics and trained models, while federated learning keeps raw data on local sites. A program can combine two or more techniques, matched to how sensitive each dataset is.