TL;DR
Virtual large language models are really vLLM, a serving engine rather than a new model, so self-host it for steady or data-resident traffic and use an API for spiky volume. The engine is open-source software from UC Berkeley’s Sky Computing Lab, released under the Apache license. Its “virtual” comes from virtual memory, since the PagedAttention method stores the KV cache in fixed-size pages, the way an operating system pages RAM. The SOSP 2023 paper behind it reports near-zero KV-cache waste and 2-4x the throughput of FasterTransformer and Orca at the same latency. It runs open-weight models such as gpt-oss, Qwen and Mistral Small 4 behind an OpenAI-compatible API, but it cannot run closed models like GPT-6.1 Sol. Self-hosting pays off only when your full cost per million tokens, counting GPUs, idle time and staff, beats the cheapest API tier that meets your quality bar.
Key Takeaways
- A “virtual large language model” is almost always vLLM, an open-source serving engine, not a new class of model.
- The “virtual” refers to virtual memory: PagedAttention splits the KV cache into small blocks mapped through a block table.
- The SOSP 2023 paper reports near-zero KV-cache waste and 2-4x the throughput of FasterTransformer and Orca at the same latency.
- vLLM serves open-weight models such as gpt-oss-120b, Qwen3.8-27B and Mistral Small 4, while closed models like GPT-6.1 Sol stay API-only.
- Major hosted APIs list input prices from $0.10 per million tokens, so self-hosting only wins at steady volume or under strict data rules.
- Production use needs a gateway for access, quotas and logs, plus monitoring and a plan for vLLM’s fast release cadence.
Why Your GPU Bill Is Mostly Memory, Not Math
Picture a platform team that has just moved an internal assistant onto its own rented GPUs. The pilot goes well, so the help desk rolls it out to every agent on a Monday morning. By lunch, response times have climbed, yet the GPU compute graphs show cores waiting for work.
The bottleneck is memory, not math. Every live conversation keeps a cache of attention data on the GPU, because each new word depends on all the words before it. A naive server also reserves room for the longest possible answer before it writes a single word, so the card runs out of space long before it runs out of compute.
That gap between reserved memory and used memory is the problem virtual large language models were built to solve. This guide explains what the term means and how the paging works. It then shows where the engine sits in an enterprise stack and when it beats paying an API per token.
What Is a Virtual Large Language Model?
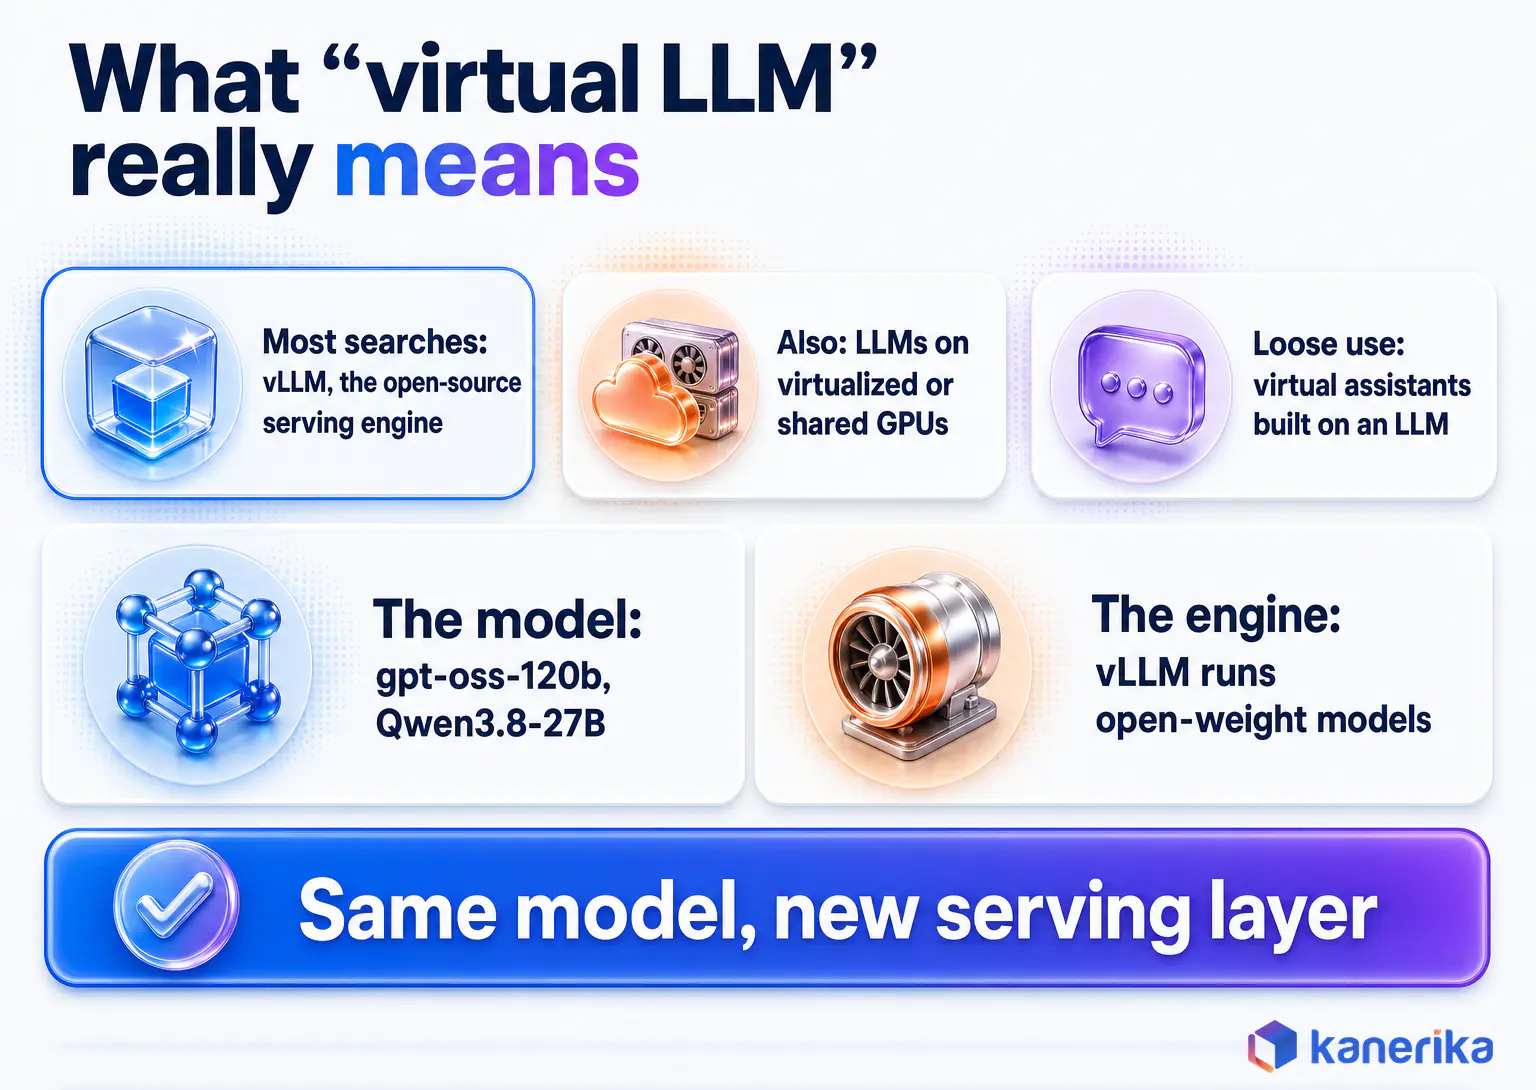
A virtual large language model is, in nearly every search, a reference to vLLM. That is open-source software that serves large language models, rather than a model itself. The confusion is easy to understand, because the name reads like a model category, the way “small language model” does.
A model such as gpt-oss-120b is the trained network that writes the text. By contrast, the vLLM engine loads that open-weight network onto GPUs, schedules incoming requests and streams answers back. So if you swap the engine, the model’s answers stay the same while speed and cost change. Closed models such as GPT-6.1 Sol never reach your engine at all, because they stay behind their vendor’s API.
If you are still sorting out the wider vocabulary, our guide to generative AI vs LLM shows where language models sit inside generative AI. For a direct look at the two acronyms, read LLM vs vLLM.
The phrase carries three meanings in practice, but only the first is what most technical readers are looking for.
| Meaning | What it refers to | Example |
|---|---|---|
| vLLM, the serving engine | Open-source software that runs open-weight LLMs on GPUs | vLLM v0.33.0 serving gpt-oss-120b |
| LLMs on virtualized or shared GPUs | Any model running on partitioned, pooled or cloud GPUs | A model on an NVIDIA MIG slice in Kubernetes |
| Loose “virtual assistant” usage | Chatbots and assistants powered by an LLM | A help desk assistant built on an API model |
The rest of this guide uses the first meaning. It also returns to the second in the architecture section, because shared GPUs are where vLLM usually runs.
Where the “Virtual” in vLLM Comes From
Operating systems, in fact, solved a similar problem decades ago. A program sees one continuous block of memory, but the system stores it in small, fixed-size pages scattered across physical RAM. A page table then maps each logical address to wherever the data really lives.
The vLLM engine applies that idea to the KV cache, the working memory a model keeps for each request. The method is called PagedAttention, and Kwon and colleagues introduced it in the SOSP 2023 paper on efficient memory management for LLM serving. So the “virtual” describes virtual memory in the serving layer, while the model’s weights stay exactly as trained.
The project began at UC Berkeley’s Sky Computing Lab, and it has grown quickly since then. Its GitHub repository lists more than 2,000 contributors and over 96,000 stars as of November 3, 2026.
Why Serving LLMs Is Hard
Serving a model means keeping it loaded and answering many users at once, which is a different job from training it. Our explainer on AI inference vs training covers the split, and serving is the inference side repeated all day.
A model built on the transformer architecture writes text one token at a time. Each new token needs attention data from every token before it, so the server keeps that data on the GPU instead of recomputing it. Four problems follow from that one design choice.
1. The KV Cache Grows With Every Token
The KV cache stores the key and value vectors that attention layers computed for earlier tokens. It is per request, since each conversation has its own history. It is also dynamic, because nobody knows in advance whether an answer will run to ten tokens or two thousand.
For example, a short chat reply and a long report draft can share the same GPU with very different memory needs. The server has to make room for both without knowing which is which.
2. Memory Fragmentation Wastes GPU Capacity
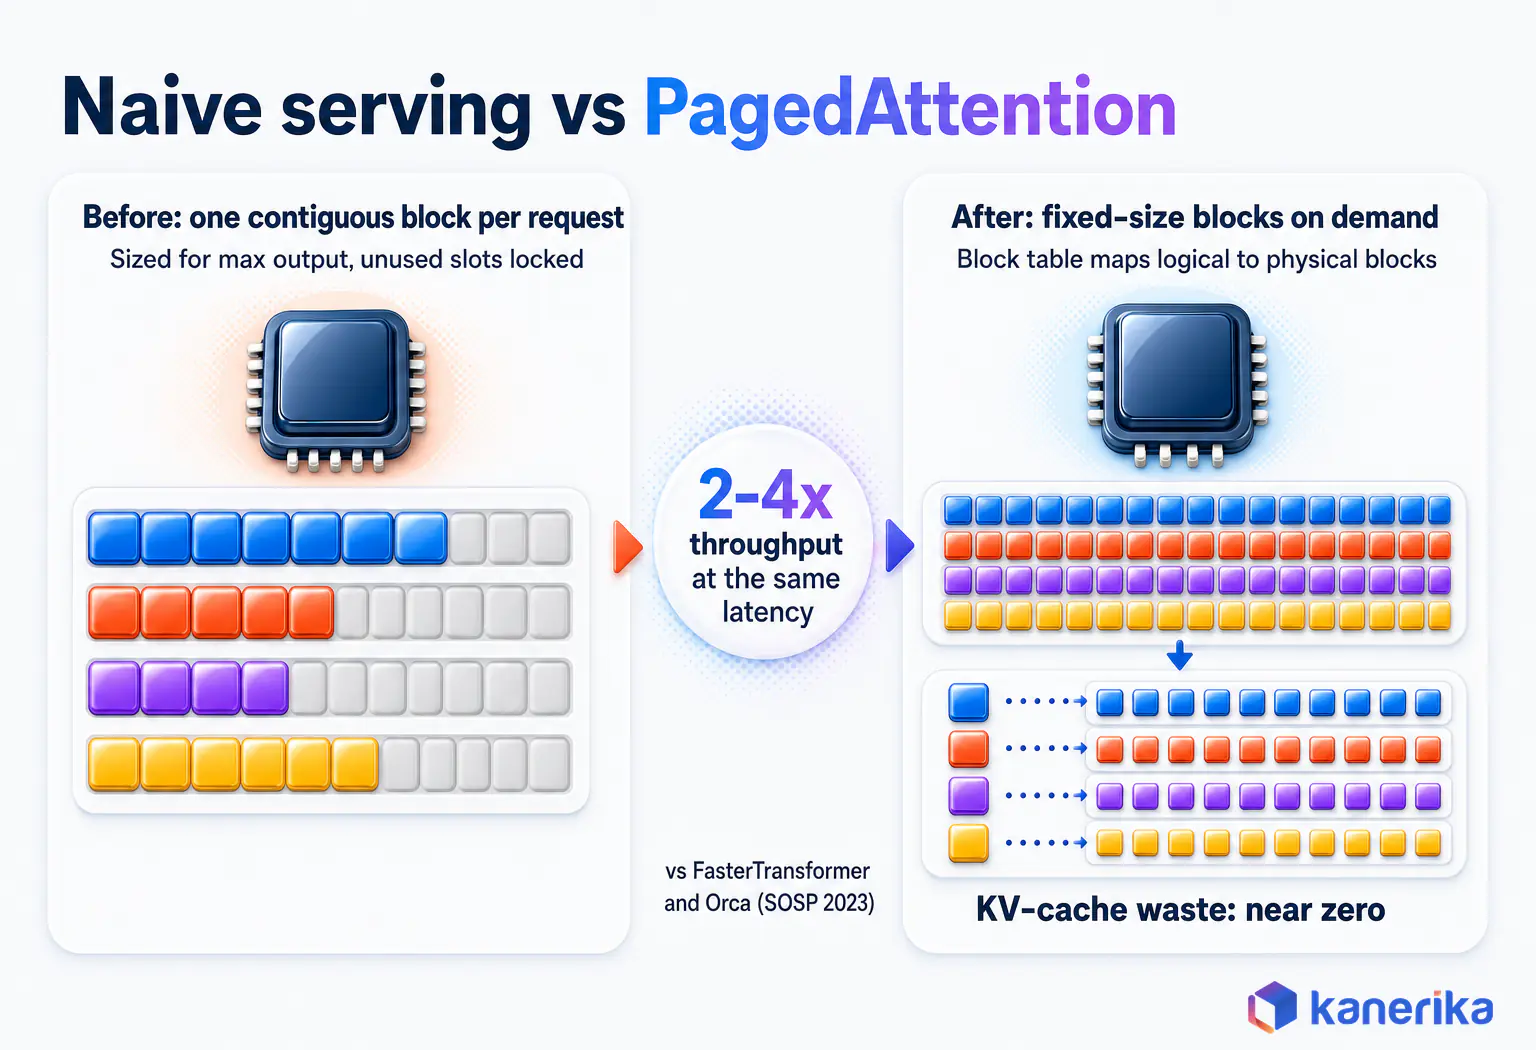
Older serving systems handle that uncertainty by reserving one contiguous block per request, sized for the maximum possible output. So if the answer ends early, the unused part of the block stays locked until the request finishes.
The free memory that remains is also chopped into gaps between reservations. As a result, a new request may not fit in any single gap, even when the total free space would be enough. Those reserved-but-unused slots and scattered gaps are exactly the waste PagedAttention targets.
3. Concurrency and Long Prompts Collide
Batch size, the number of requests a GPU processes together, is capped by how many KV caches fit in memory. Fewer caches in memory therefore means fewer users served per card.
Long prompts also make it worse. For instance, a retrieval app that adds a long document to every prompt fills memory quickly, so the batch shrinks just when demand rises.
4. Cost per Token Follows GPU Utilization
A GPU costs the same per hour whether it is busy or idle. When memory limits the batch, compute cores wait, and so the price of every token you generate goes up.
That makes serving efficiency a finance question as much as an engineering one. In short, throughput per GPU sets your cost per million tokens, and that is the number to hold up against an API bill.
Kanerika Service
LLM Development Services
Kanerika builds and deploys large language model applications, including models served on your own infrastructure with security, monitoring and cost control.
Explore LLM DevelopmentHow vLLM Works: PagedAttention, Batching and Scheduling
The vLLM engine keeps GPUs busy by changing how memory is handed out and how requests are grouped, while the model itself is untouched. Think of a parking garage that stops reserving a whole row for every car and instead assigns single bays as cars arrive. More cars fit, and nobody waits for a row to clear.
The same idea applied to a GPU runs in four steps:
- A request arrives, and vLLM processes its prompt to build the first KV entries.
- The KV cache is split into fixed-size blocks, each holding keys and values for a short run of tokens.
- A block table maps each request’s logical blocks to physical blocks anywhere in GPU memory, so blocks never need to sit side by side.
- New blocks are allocated only when the previous one fills, and they return to the free pool the moment the request ends.
Each step removes one source of waste from the naive design, and together they let far more requests share a single card.
PagedAttention and the Block Table
Because blocks are small and handed out on demand, waste is limited to the unfilled part of the last block in each request. The PagedAttention paper therefore reports near-zero KV-cache waste. It also measured 2-4x higher throughput than FasterTransformer and Orca at the same latency.
The block table makes sharing possible too. When one prompt asks for several sampled answers, or many requests begin with the same system prompt, they can point to the same physical blocks. A block is then copied only when one request needs to write something different, a technique called copy-on-write.
Continuous Batching and Chunked Prefill
Static batching collects a group of requests, runs them together and holds the group until the longest answer finishes. Short answers therefore sit idle while one long answer completes.
The vLLM scheduler uses continuous batching instead, so requests join and leave the running batch at every generation step. Chunked prefill also splits a long prompt into pieces, which stops one large document from stalling everyone else’s tokens.
Other Optimizations in the Engine
Paging and batching are the core of the engine, but the project README lists several more features that matter once you reach production:
- Prefix caching reuses KV blocks for repeated prompt openings, such as a long shared system prompt.
- Speculative decoding lets a fast draft method (n-gram, suffix or EAGLE) propose tokens that the main model checks in one pass.
- Quantization support for FP8, MXFP4, NVFP4, INT8, INT4, GPTQ/AWQ and GGUF shrinks weights and frees memory.
- Parallelism across tensor, pipeline, data, expert and context dimensions splits large models over many GPUs.
- Disaggregated prefill and decode runs prompt processing and token generation on separate workers.
- Structured outputs constrain responses to a schema, which helps apps that parse JSON.
Still, one limit deserves a plain statement. PagedAttention saves memory, but it does not remove the compute cost of long context. A very long prompt still takes real GPU time to process.
vLLM vs Naive LLM Serving
The fair comparison for vLLM is naive serving, meaning static batching on a plain Transformers stack with contiguous memory. The model can be identical on both sides of the table below, so only the serving method changes.
| Aspect | Naive serving | vLLM |
|---|---|---|
| KV-cache allocation | One contiguous block per request, sized for maximum output | Fixed-size blocks allocated on demand |
| Memory waste | Reserved but unused slots, plus fragmentation | Near zero, limited to the last block (SOSP 2023) |
| Batching | Static: the batch waits for its longest request | Continuous: requests join and leave every step |
| Request sharing | Each request stores its own copy | Shared prefixes and samples reuse blocks through copy-on-write |
| Throughput | Baseline | 2-4x vs FasterTransformer and Orca at the same latency (paper) |
| API surface | Custom code per project | OpenAI-compatible server, plus Anthropic Messages API and gRPC |
| Hardware | Often tied to one vendor | NVIDIA, AMD and Intel GPUs, x86/ARM/PowerPC CPUs, plugins for Google TPU, Intel Gaudi, Huawei Ascend and Apple Silicon |
The throughput figure is the paper’s measurement against those two systems, not a promise for your workload. Treat it instead as the reason to run your own load test with real prompts, which the deployment steps below include.
Benefits of Virtual Large Language Models
The benefits come down to doing more work with the same GPUs, through an interface your developers already know. Five stand out for enterprise teams.
- Higher throughput. Continuous batching and paging let one GPU serve more requests at once. The SOSP 2023 paper measured 2-4x the throughput of FasterTransformer and Orca at the same latency.
- Memory efficiency. Near-zero KV-cache waste means more conversations fit in the same memory. Quantized weights also free room for longer context or bigger batches.
- Lower cost per token at high utilization. When the GPU stays busy, its hourly price is spread over more tokens. But the saving disappears if the card sits idle overnight, so volume decides the outcome.
- OpenAI-compatible API. Apps written for the OpenAI SDK can switch to vLLM by changing the base URL. That makes it easy to test a self-hosted model against a hosted one with the same code.
- Open source under Apache 2.0. You can run, modify and ship vLLM commercially without license fees. More than 2,000 contributors keep it moving fast, which is both a strength and an upgrade burden.
Those benefits only land if the rollout is planned well, so check data, security and model choices before the first GPU is ordered. The checklist below walks through those questions in order.
Checklist
Generative AI Checklist
Work through data readiness, model choice, security and governance questions before you move an LLM pilot into production.
Get the Checklist →Virtual LLM Serving Architecture and Shared GPUs
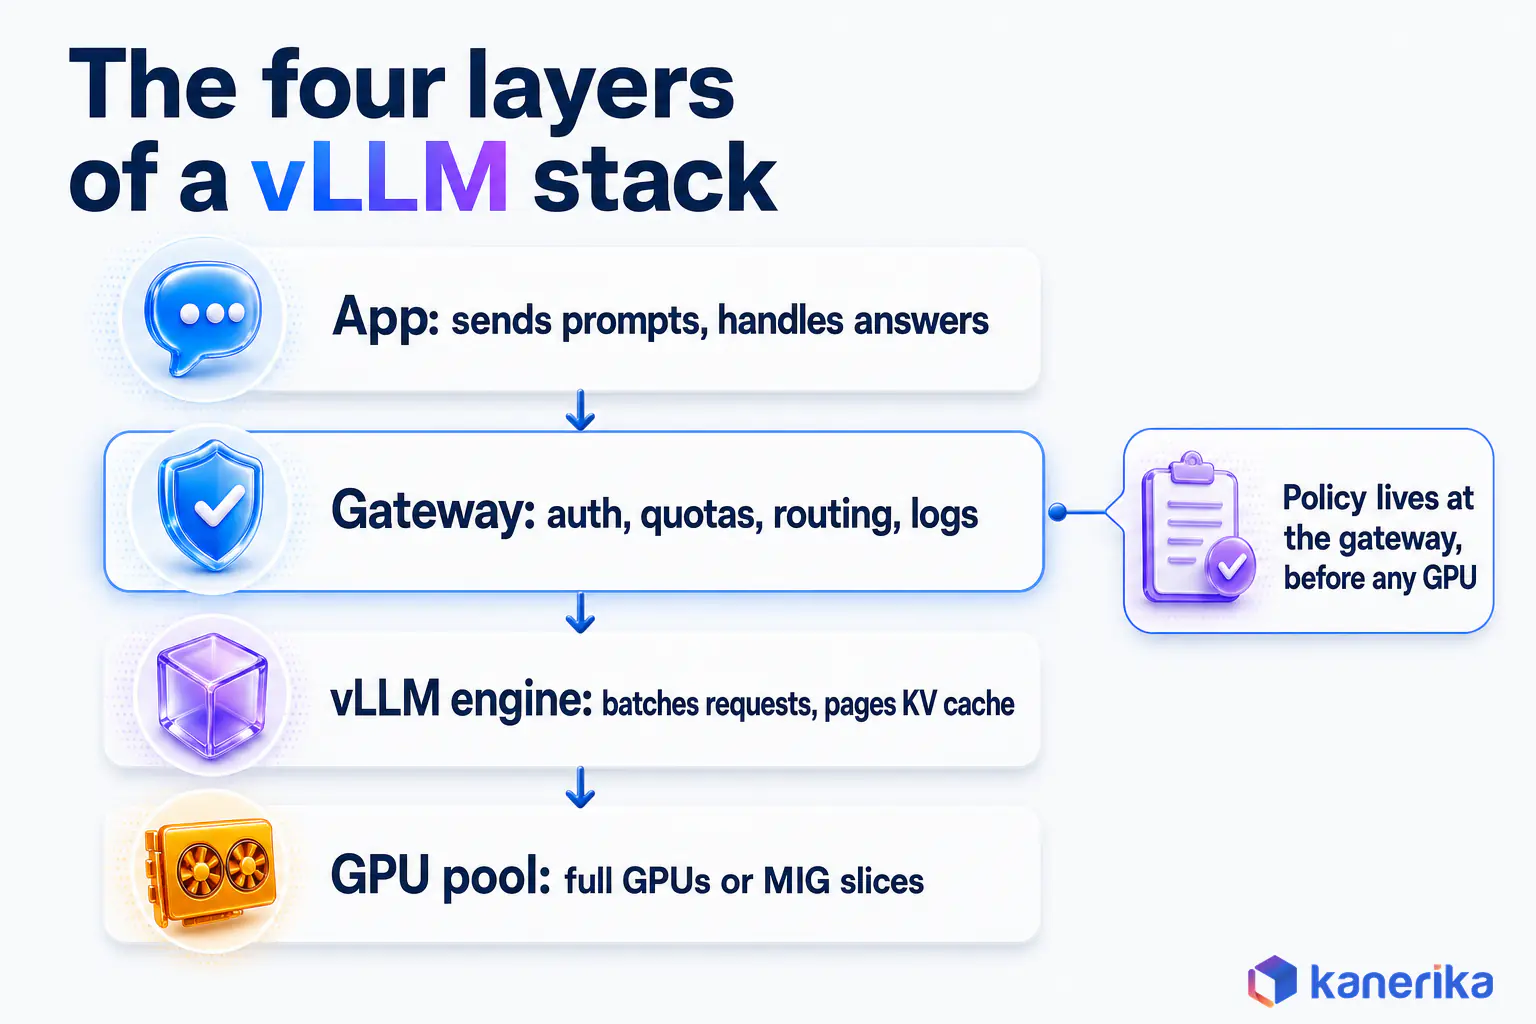
A production deployment of vLLM is a stack of four layers, and the engine is only one of them. Picture a restaurant. The app is the dining room, the gateway is the host stand, vLLM is the kitchen and the GPU pool is the stoves.
Each layer has a job the others cannot do well, so mixing them up creates gaps in security and cost control.
The Four Layers of a vLLM Stack
- Application: the chat interface, agent or batch job that sends prompts and handles answers.
- Gateway: authentication, quotas, routing between models and request logs. Our guide to the LLM gateway covers this layer in depth.
- Inference engine: vLLM, which batches requests, manages the KV cache and streams tokens.
- GPU pool: the physical or cloud GPUs, often shared across teams and models.
Keeping policy in the gateway means the engine can be upgraded or swapped without rewriting access rules. It also gives finance one place to read token usage by team.
Running on Virtualized or Partitioned GPUs
This is also where the second meaning of “virtual” becomes real. NVIDIA Multi-Instance GPU, or MIG, splits one physical GPU into isolated instances, each with dedicated compute and memory, according to the NVIDIA MIG user guide.
A small model can then run on one slice while another team uses the next, and neither can see the other’s memory. Kubernetes then schedules those slices like any other resource, which is how many platform teams share expensive GPUs fairly.
Scaling Out: Ray Serve LLM and llm-d
One vLLM server tops out at the GPUs it controls, so teams add an orchestration layer above it to scale across nodes. For example, Ray Serve LLM works with vLLM and adds prefix-aware and KV-aware routing, fractional GPU serving and prefill/decode disaggregation.
Prefix-aware routing sends each request to the replica that already caches its prompt prefix. That saves recomputation. The llm-d project takes a Kubernetes-native approach to distributed serving and reached v1.0.0 on October 20, 2026.
vLLM vs Other LLM Serving Engines
vLLM is one of several serving engines, so the right choice depends on your hardware, your model and how much tuning your team wants to own. The table gives each project’s status as of November 3, 2026, taken from its GitHub releases page or README.
| Engine | Role | Status (November 3, 2026) | Best fit |
|---|---|---|---|
| vLLM | General-purpose open-source serving engine | v0.33.0, released November 2, 2026 | Most open-weight models on mixed hardware |
| SGLang | Open-source serving engine, the closest alternative | v0.5.23, released November 2, 2026 | Teams benchmarking both on the same model |
| TensorRT-LLM | NVIDIA’s optimized inference library | v1.4.0rc2 release candidate, October 28, 2026 | NVIDIA-only fleets tuned for peak speed |
| Text Generation Inference (TGI) | Hugging Face serving server | Maintenance mode, repo archived; Hugging Face recommends vLLM and SGLang | Existing installs only, with a migration plan |
| Ollama | Local runner for desktops and laptops | v0.40.14, released November 3, 2026 | Single-user and local development |
| FasterTransformer | NVIDIA’s earlier inference library | Development moved to TensorRT-LLM | Legacy only; no new projects |
NVIDIA Dynamo is another name you will meet in multi-node setups, so check its own documentation before planning around a version. For deeper head-to-heads, read SGLang vs vLLM, our roundup of vLLM alternatives and vLLM vs Ollama.
Which Models Can You Serve with vLLM in 2026?
vLLM can only serve models whose weights you can download, so the first filter is license and access rather than benchmark scores. According to its README, the project supports more than 200 model architectures on Hugging Face.
Closed models such as GPT-6.1 Sol, Claude Opus 5.5 and Gemini 4 Argon are offered only through their vendors’ APIs. Since no self-hosted engine can run them, the table covers open-weight options only.
| Model | Size | License | What to know |
|---|---|---|---|
| gpt-oss-120b | 117B total, 5.1B active | Apache 2.0 | Fits a single 80GB GPU such as an H100 |
| gpt-oss-20b | 21B total, 3.6B active | Apache 2.0 | Runs within 16GB of memory |
| Qwen3.8-27B | 27B, dense | Apache 2.0 | 262,144-token native context, extendable to 1M |
| Mistral Large 4 | 1T total, 52B active | Custom Mistral license | Model card recommends vLLM; NVFP4 checkpoint supports vLLM and SGLang |
| Mistral Small 4 | 119B total, 6.5B active | Apache 2.0 | 256k-token context |
| DeepSeek V4.1-Flash and V4-Pro | See model cards | MIT on Hugging Face | Broad commercial use allowed |
| GLM-5.3 | 753B | Custom license | Read the terms before commercial use |
Bigger, however, is not always better for a narrow task. Our guide to small language models explains when a compact model beats a frontier one. Similarly, parameter-efficient fine-tuning shows how to adapt an open-weight model to your data before you serve it.
For the wider field, our lists of open-source LLMs and top LLMs track new releases. Pick two or three candidates, then test them on your own prompts before committing hardware.
Talk to Kanerika
Plan Your LLM Serving Stack
Talk to Kanerika about whether to self-host open-weight models or stay on an API, based on your token volume, data rules and latency needs.
Talk to an Expert →Self-Hosted vLLM vs Hosted API: What It Costs
Self-hosting swaps a per-token bill for a per-hour GPU bill, so the real question is which one is smaller at your volume. Hosted prices have also fallen far enough that the bar is high.
Hosted API Prices per Million Tokens
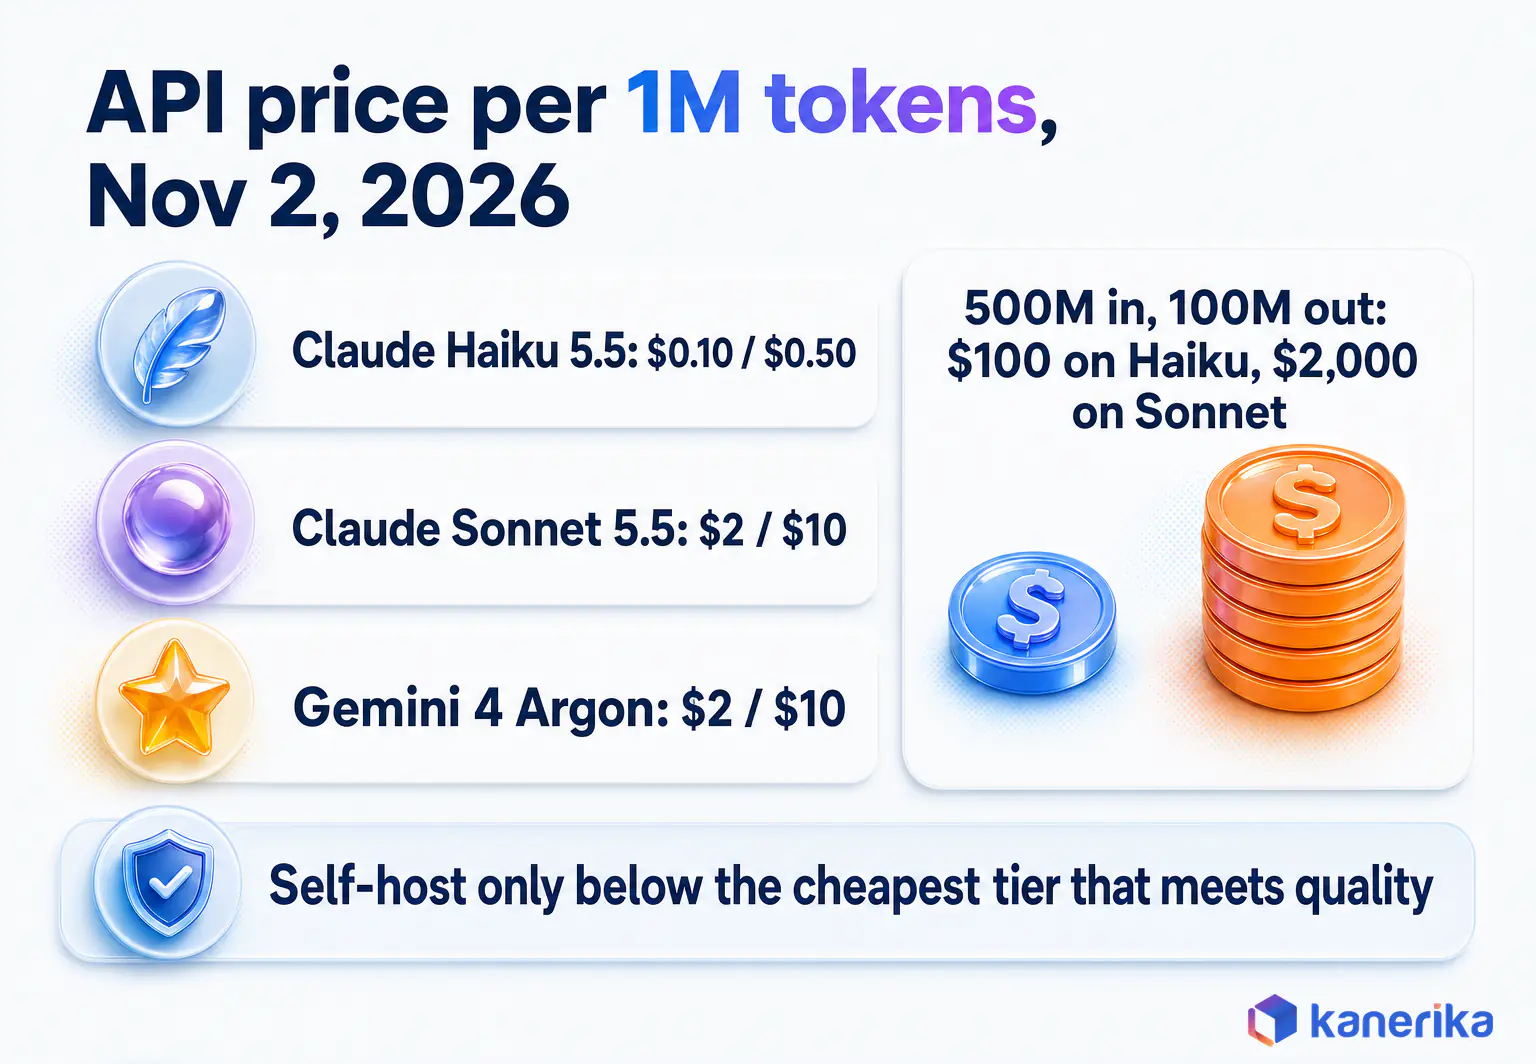
The table lists prices per 1 million tokens as of November 2, 2026, from each vendor’s pricing page, including Claude pricing and Mistral pricing.
| Hosted model | Input per 1M | Output per 1M | Notes |
|---|---|---|---|
| Claude Haiku 5.5 | $0.10 | $0.50 | Up to a 100K-token prompt; output $2.50 above that |
| GPT-6 Luna | $0.10 | $0.50 | Lowest OpenAI tier listed |
| DeepSeek V4.1-Flash | $0.15 | $0.60 | Off-peak rate; peak is double |
| Mistral Large 4 | $0.70 | $2.10 | Also open-weight, so it can be self-hosted |
| GPT-6.1 Terra | $1 | $5 | Batch and Flex 50% lower |
| Claude Sonnet 5.5 | $2 | $10 | Claude Opus 5.5 Batch is also $2 / $10 |
| GPT-6.1 Sol | $2 | $10 | 2x input and 1.5x output over 272K tokens; Batch and Flex 50% lower |
| Gemini 4 Argon | $2 | $10 | Through November 30, 2026; $4 / $20 from December 1, 2026 |
A worked example shows the stakes. Take a support workload of 500 million input tokens and 100 million output tokens a month. That costs $100 on Claude Haiku 5.5 ($50 plus $50), but $2,000 on Claude Sonnet 5.5 ($1,000 plus $1,000).
When Self-Hosting Beats the API
To beat those numbers, a self-hosted server must match the quality for less after every cost is counted. The list is longer than the GPU line on a cloud invoice:
- GPU hours, including nights and weekends when traffic is low.
- Idle headroom kept free for traffic peaks.
- Engineers on call for upgrades, outages and model changes.
- Storage, networking, monitoring and security tooling.
Overall, the decision rule is simple to state. Self-host when sustained utilization, data residency or latency make your cost per million tokens lower than the cheapest API tier that meets your quality bar. For broader spend control, see cloud cost management, and for data that must never leave your network, see our guide to private LLMs.
How to Deploy vLLM: From First Server to Production
Getting a first vLLM server running takes minutes, while making it production-ready takes the rest of the work. The steps below follow that order, from license check to autoscaling.
- Pick an open-weight model and check its license. Apache 2.0 and MIT allow broad commercial use, while custom licenses need a legal read.
- Check the hardware. The vLLM GPU install guide lists Linux and NVIDIA GPUs with compute capability 7.5 or higher, such as T4, A100, L4, H100 and B200.
- Install vLLM with
uv pip install vllm --torch-backend=autoin a clean Python environment, then runvllm download-kernelsso startup does not compile kernels. - Start the OpenAI-compatible server with
vllm serveand your model name, then point an app at it by changing the SDK base URL. - Tune memory, context and parallelism. Set GPU memory use, maximum context length and tensor parallelism to match your model and traffic.
- Put a gateway in front for authentication, rate limits and token quotas.
- Load-test with real prompts, then add autoscaling through Kubernetes, Ray Serve or llm-d.
On a supported machine, the first commands look like this:
# install on Linux with a supported NVIDIA GPU
uv pip install vllm --torch-backend=auto
vllm download-kernels

# start an OpenAI-compatible server with an open-weight model
vllm serve openai/gpt-oss-20b
The server listens on port 8000 by default, so an app using the OpenAI SDK sets its base URL to http://localhost:8000/v1 and keeps the rest of its code. For the wider rollout plan, including model ownership and governance, read our guide to enterprise LLM adoption.
Enterprise Use Cases for Virtual Large Language Models
Virtual large language models earn their place where request volume is high, prompts repeat, or data cannot leave your network. Four patterns cover most enterprise demand.
Customer Support and Chat at High Concurrency
Support chat is the classic fit. Thousands of short conversations arrive at once, while continuous batching keeps the GPU full as they start and end at different times.
Every conversation also tends to share the same long system prompt with policies and tone rules. Prefix caching stores that prompt once and reuses it, so each new chat starts faster.
Retrieval-Augmented Generation Over Private Data
Retrieval-augmented generation, or RAG, adds passages from your own documents to each prompt before the model answers. Those prompts run long, so paged memory and chunked prefill help most.
Keeping the model in your own environment also keeps sensitive documents off third-party servers. Our guide to building a RAG pipeline covers retrieval design, and Kanerika’s RAG development services team builds these systems end to end.
Agents and Multi-Agent Workflows
Agents call a model many times per task: to plan, to choose a tool, to read the result and to try again. Because one user request can turn into dozens of model calls, cost per token matters more than it does for a single chat.
Those agent workloads are where a self-hosted engine can pay off fastest. Agents in multi-agent AI systems often share instructions and context, so prefix caching and shared KV blocks cut repeated work across the whole chain.
Batch Document and Text Processing
Overnight jobs that summarize contracts, tag tickets or extract fields process millions of tokens with no user waiting. Throughput matters more than latency here, so large batches on a busy GPU give the lowest cost per document.
These jobs often reuse one long instruction block for every file, and prefix caching avoids processing it again each time. Still, some of the tasks, such as scoring or classifying, are prediction jobs rather than generation, a split explained in generative vs predictive AI.
Challenges, Limits and When You Do Not Need vLLM
vLLM solves a memory problem, but running it still means owning servers, upgrades and on-call duty. Five limits deserve a place in any business case.
- GPUs are needed for the full benefit. CPU and other backends exist, but the headline speed gains assume accelerator hardware.
- The operating burden falls on your team. A small team may spend more time running the engine than building the product.
- Releases move fast. Version 0.32.0 shipped on October 18, 2026 and v0.33.0 on November 2, 2026, so upgrades and regression tests are routine work.
- Long context still costs compute. Paging saves memory, but processing a long prompt still takes GPU time.
- Closed models are off the table. If your quality bar needs GPT-6.1 Sol or Claude Opus 5.5, you must use their APIs.
None of these limits rules vLLM out, yet each one changes the cost math in the previous section.
When a Hosted API or a Local Runner Is the Better Choice
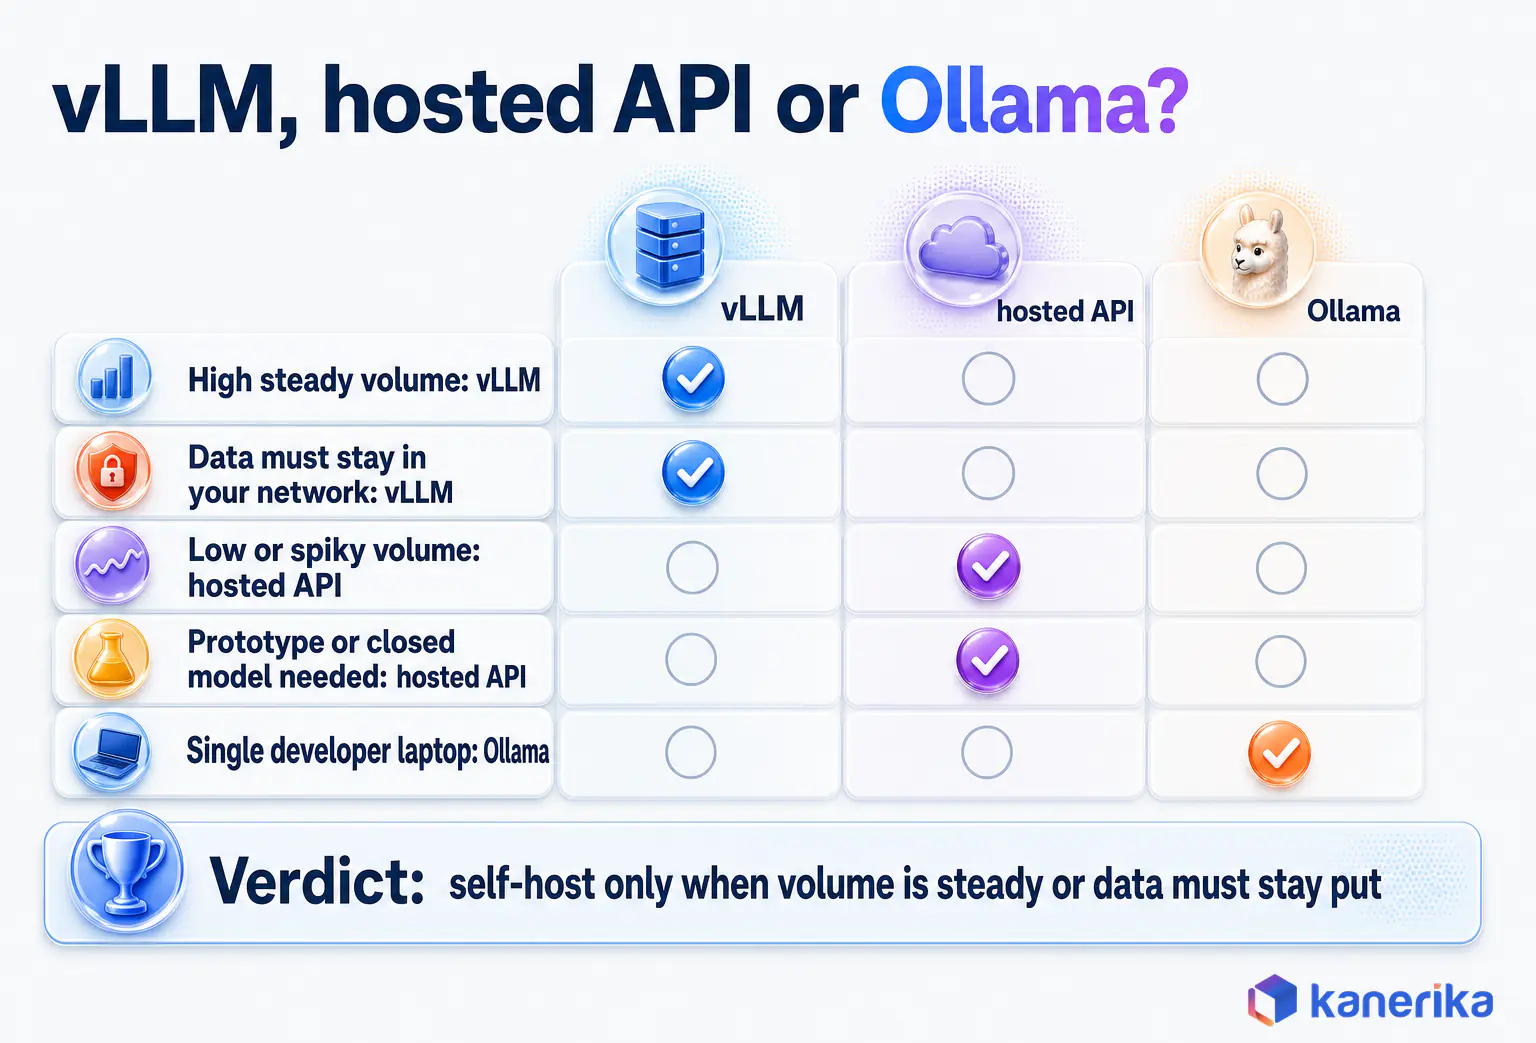
Low or spiky traffic rarely keeps a GPU busy, so a hosted API is usually cheaper and simpler. Prototypes belong on an API too, since you can switch models in a day.
For a single developer on a laptop, however, Ollama is the lighter tool. It runs models locally with little setup, and our guide to edge AI covers the wider case of running models on devices instead of servers.
What to Watch Through 2027
Three trends are shaping the next releases. First, disaggregated prefill and decode puts prompt processing and generation on separate workers. Second, new quantization formats such as NVFP4 shrink memory further.
Finally, Kubernetes-native serving projects like llm-d are making multi-node deployment a standard platform pattern rather than a custom build. All three aim at the number this guide keeps returning to: tokens served per GPU hour.
Running vLLM in Production: Monitoring, Security and Governance
A self-hosted model is your system to secure, so the controls a vendor would run for you become your team’s job. Two public references help frame that work.
The OWASP Top 10 for LLM applications lists LLM10:2025 Unbounded Consumption, the risk of users or attackers running up compute with oversized or repeated requests. The NIST AI 600-1 Generative AI Profile, published July 26, 2024, then maps generative AI risks to concrete controls.
A practical production checklist for vLLM looks like this:
- Enforce authentication and role-based access at the gateway, never on the engine alone.
- Set rate limits, maximum tokens per request and per-team quotas to contain unbounded consumption.
- Log prompts, responses and token counts, with retention rules that match your data policy.
- Track latency, throughput, queue depth and GPU memory, and alert when they drift.
- Pin vLLM versions, test each upgrade on real prompts and keep a rollback path.
- Record which model version and license served each answer, for audits.
Our guides to LLM observability and LLM security go deeper on each control, from tracing to prompt injection defense.
Kanerika Service
AI Governance Services
Kanerika sets up access control, usage quotas, audit logging and risk reviews so self-hosted and API-based models meet your security and compliance rules.
Explore AI GovernanceHow Kanerika Builds Private, Production LLM Serving
Kanerika helps enterprises decide whether to serve models themselves, then builds the serving layer when the answer is yes. The work usually starts with a question about volume, not technology.
A practical first step is to run the use case on a hosted API, log real token volumes for a month and then decide. That evidence shows whether self-hosting can beat the API price at all, before anyone buys or reserves GPUs.
Kanerika’s Four Delivery Stages
When the numbers favor self-hosting, delivery then follows four stages:
- Use-case and volume assessment. Decide API first or self-host from token volume, data residency and latency needs.
- Model and engine selection. Review open-weight licenses, choose vLLM or SGLang and trial quantized versions against your quality bar.
- Secure serving layer. Build a gateway with role-based access, quotas and audit logs, backed by kanGuard, Kanerika’s tool for unauthorized access prevention and data security.
- Integration and operations. Connect RAG and agents through FLIP, Kanerika’s agentic workflow automation platform, then add observability, load tests and monthly tracking of cost per million tokens.
Kanerika’s LLM development services cover models deployed on your own infrastructure, while its generative AI services handle the application layer on top. The team is also a Microsoft Solutions Partner for Data and AI and holds ISO 27001 and SOC 2 Type II certifications.
That LLM work also shows up in client results. For a global company present in more than 40 countries, Kanerika built LLM-driven AI ticket response. The system reached 80% ticket auto-resolution, with lower staffing costs and faster query resolution.
Case Study
80% Ticket Auto-Resolution with LLM-Driven AI
A global company present in 40+ countries used Kanerika’s LLM-driven AI ticket response to auto-resolve 80% of tickets, reduce staffing costs and speed up query resolution.
Read the Case Study →So, what are virtual large language models? They are ordinary LLMs served through vLLM, an engine that pages GPU memory the way an operating system pages RAM. Run them yourself when steady volume or data rules justify the GPUs, and rent an API when they do not.
Frequently Asked Questions
What is a Virtual Large Language Model (vLLM)?
A virtual large language model usually means vLLM, an open-source engine that serves large language models efficiently. It is not a new kind of model. vLLM loads open-weight models onto GPUs and answers many requests at once. The name comes from virtual memory, because its PagedAttention method stores each request’s KV cache in small pages.
What's the difference between LLM and vLLM?
An LLM is the trained model that understands and generates text, such as gpt-oss-120b or Claude Opus 5.5. vLLM is software that runs open-weight LLMs in production. It manages GPU memory, batches requests and exposes an API. You can serve the same LLM with or without vLLM, and the answers stay the same while throughput changes.
Which frameworks support vLLMs?
Ray Serve LLM is built to run vLLM across clusters, adding prefix-aware routing and fractional GPU serving. llm-d offers Kubernetes-native distributed serving and reached v1.0.0 on October 20, 2026. Kubernetes itself schedules vLLM pods and NVIDIA MIG slices. Engines such as SGLang and TensorRT-LLM are alternatives to vLLM rather than frameworks around it.
What is the future of vLLMs?
Expect wider use of disaggregated prefill and decode, which run prompt processing and generation on separate workers. New quantization formats such as NVFP4 will cut memory further. Kubernetes-native projects like llm-d are turning multi-node serving into a standard platform pattern, and fast vLLM releases mean model support keeps growing through 2027.
Is GPT-6.1 Sol a vLLM?
No. GPT-6.1 Sol is a closed OpenAI model, and vLLM is a serving engine. Sol is available only through the OpenAI API at $2 per million input tokens and $10 per million output tokens, so you cannot load it into vLLM. The open-weight gpt-oss models from OpenAI are the ones you can serve yourself with vLLM.
Is ChatGPT a vLLM?
No. ChatGPT is the OpenAI chat product, built on closed OpenAI models and serving systems. It is not vLLM and does not run on your hardware. If you want a ChatGPT-style assistant on your own servers, you could pair an open-weight model such as gpt-oss-120b with vLLM and a chat interface your team controls.
What is PagedAttention and why does it matter?
PagedAttention is the memory method at the heart of vLLM, introduced by Kwon et al. at SOSP 2023. It stores the KV cache in fixed-size blocks mapped through a block table, like pages in an operating system. That cuts memory waste to near zero, so more requests fit on each GPU and throughput rises.
Is vLLM free and open source?
Yes. vLLM is released under the Apache 2.0 license, so you can use, modify and deploy it commercially without license fees. It has more than 2,000 contributors and over 96,000 GitHub stars as of November 3, 2026. The software is free, but the GPUs, hosting and engineering time to run it are not.
Can you run an LLM on a virtual machine or a virtualized GPU?
Yes. Cloud GPU virtual machines are the most common place to run vLLM. NVIDIA MIG can also split one physical GPU into isolated instances with dedicated compute and memory, so smaller models share hardware safely. Kubernetes schedules those instances, and vLLM runs inside each container like any other service your platform team manages.
Is self-hosting an LLM with vLLM cheaper than using an API?
Only at steady, high volume. Hosted prices start at $0.10 per million input tokens on Claude Haiku 5.5 and GPT-6 Luna, which is a low bar. Self-hosting wins when sustained GPU use, data residency or latency needs bring your full cost per million tokens below the cheapest API tier that meets quality.
What is an example of a vLLM?
vLLM itself is the main example, an Apache 2.0 project started at UC Berkeley’s Sky Computing Lab. A typical setup runs gpt-oss-20b or Qwen3.8-27B through vLLM behind an OpenAI-compatible endpoint. SGLang is a similar open-source serving engine, and teams often test both on the same model before choosing one for production.
What is the difference between LLM and AI?
AI is the broad field of building systems that perform tasks needing human-like judgment, from vision to planning. An LLM is one type of AI model, trained on large amounts of text to predict and generate language. Every LLM is AI, but most AI systems are not LLMs, such as fraud scoring or image recognition models.
What are the two types of LLM?
For serving decisions, the useful split is open-weight versus closed. Open-weight models such as gpt-oss and Mistral Small 4 publish their weights, so you can run them yourself with vLLM. Closed models such as GPT-6.1 Sol and Claude Opus 5.5 are available only through vendor APIs, so you pay per token instead.
What does virtual model mean?
In the vLLM sense, virtual refers to virtual memory, not to a simulated model. The engine maps each request’s memory to small physical blocks on the GPU, much as an operating system maps programs to RAM pages. The term is also used loosely for models on virtualized GPUs or for virtual assistants built on an LLM.
How do vLLMs differ from traditional LLM serving?
Traditional or naive serving reserves one large memory block per request and waits for a whole batch to finish. vLLM allocates small blocks on demand and lets requests join or leave the batch at every step. The PagedAttention paper reports near-zero memory waste and 2-4x the throughput of FasterTransformer and Orca at equal latency.
What are the main benefits of vLLMs?
The main benefits are higher throughput per GPU, near-zero KV-cache waste and a lower cost per token when the hardware stays busy. It also has an OpenAI-compatible API, so apps switch by changing a base URL. It is free under Apache 2.0 and supports more than 200 model architectures from Hugging Face.
What are common use cases of vLLMs?
Common uses include high-concurrency support chat, retrieval-augmented generation over private documents, agent workflows that call a model many times and overnight batch jobs such as summarizing or tagging files. These share two traits. Request volume is high, and many prompts repeat the same instructions, which prefix caching can reuse instead of processing again.
What challenges do vLLMs face?
vLLM needs GPUs for its full benefit, and your team must run upgrades, monitoring and on-call support. Releases arrive quickly, with v0.32.0 on October 18 and v0.33.0 on November 2, 2026. Long prompts still cost compute, and closed models such as GPT-6.1 Sol cannot be served on your own hardware at all.