TL;DR
For a Microsoft Fabric migration, upgrade supported Data Factory pipelines first, move Synapse warehouses with the Migration Assistant, and keep SSIS on Azure unless it fits the preview. Mapping Data Flows that use flowlets, UDFs or a managed virtual network should also stay on Azure until the preview upgrade supports them. Power BI estates on P SKUs should move to F SKUs, because as of November 2026 Microsoft is retiring P per-capacity SKUs. Size the F SKU from a pilot rather than a guess, since a pay-as-you-go F64 cost $11.52 an hour in East US in November 2026. Then migrate in waves, run old and new side by side, and reconcile totals before switching triggers on. Retire the Azure resources only after a wave passes reconciliation, its refresh SLA and a tested rollback window.
Key Takeaways
- A Fabric migration moves workloads, their dependencies and the operating model, so it is never just a data copy.
- Microsoft’s built-in upgrade assesses Azure Data Factory pipelines first, then upgrades the supported ones incrementally, without scripts.
- SSIS integration runtimes are not available in Fabric. The Invoke SSIS Package activity is still in preview as of November 2026, so most packages stay in Azure Data Factory for now.
- The Fabric Migration Assistant accepts a DACPAC, SQL scripts or a direct connection when the source is a Synapse dedicated SQL pool.
- Pay-as-you-go Fabric capacity costs $0.18 per CU-hour in East US as of November 2026, so an F64 runs about $8,410 for a 730-hour month.
- Hard gates such as feature support, identity and reconciliation decide the order of waves before any benefit scoring does.
A Synapse Renewal Meets Month-End Close
Picture a finance data team in late October. Its Synapse dedicated SQL pool is up for renewal, while about 300 Azure Data Factory pipelines and some 40 SSIS packages feed the warehouse. On top of that, its Power BI reports sit on a P1 capacity that Microsoft is retiring. (An illustrative scenario, not a named client.)
The CFO wants one platform and one bill. The data lead, though, has a month-end close in three weeks, so a single wrong total in the ledger reports is not an option.
Both of them are right. That is the exact tension a Fabric migration plan has to resolve. The team must consolidate on one capacity without breaking the numbers the business closes its books on.
This guide gives that team a plan. It covers what actually moves and which approach fits each workload. After that, it compares the tools, then lays out a seven-step sequence, capacity cost and a go/no-go checklist for cutover.
What a Microsoft Fabric Migration Actually Moves
A Microsoft Fabric migration moves Azure analytics workloads onto one Fabric capacity and OneLake. That usually means Data Factory pipelines, Synapse warehouses and Power BI capacity. The data is the easy part, while the dependencies around it take most of the effort.
A pipeline that copies a table, for example, also relies on a linked service, an integration runtime and a trigger schedule. It may also need a key vault secret, plus a person who gets paged when it fails. So moving the table alone gives you a copy of the data and a broken process.
Workloads, Dependencies and the Operating Model
Scope the migration across seven layers before anyone copies a single row. The copy pipeline above already touches four of them at once: sources, orchestration, identity and monitoring. Each layer therefore needs an owner and a test, or the key vault secret and the trigger schedule become nobody’s job.
- Sources and ingestion: databases, files and APIs, as well as the integration runtimes that reach them.
- Transformations and orchestration: pipelines, Mapping Data Flows, notebooks, stored procedures and triggers.
- Storage and serving: data lake folders, Synapse dedicated SQL pools and lake databases.
- Semantic models and reports: Power BI datasets and Analysis Services models, then the reports built on them.
- Identity, permissions and lineage: Entra ID groups, managed identities, workspace roles and Purview scans.
- Deployment and monitoring: Git, release pipelines and alerts, plus the on-call runbook.
- Retention and retirement: how long the Azure resources stay up, and who signs off before they shut down.
Analysis Services models carry their own conversion questions, so the SSAS to Fabric migration guide covers that layer in depth. Teams whose source is Databricks rather than Azure face a different first layer, explained in how to migrate from Databricks to Microsoft Fabric.
One Known Gotcha per Layer
Each layer has at least one trap that Microsoft documents but teams still hit in the pilot. The table lists one per layer, taken from Microsoft Learn pages checked in November 2026, so the pilot can test for it on purpose.
| Layer | Gotcha | What to do |
|---|---|---|
| Sources and ingestion | Self-hosted runtimes become on-premises data gateways, so one gateway may carry loads several runtimes once split | Size gateway throughput, then validate DNS, egress and firewall rules per connector |
| Transformations and orchestration | Core activities have equivalents, yet retry policies, timeouts, REST pagination and system variables can differ | Compare those settings for each upgraded pipeline |
| Storage and serving | The Migration Assistant holds back dependent objects until the objects they rely on are fixed | Fix primary objects first, and check identity columns in Fabric Data Warehouse, which behave differently |
| Semantic models and reports | On a P capacity, Fabric items stay disabled until an admin enables Fabric | Switch Fabric on for that capacity before the pilot |
| Identity, permissions and lineage | SQL-authenticated users and column-level encryption need changes to work in Fabric | Move users to Entra ID and fix security objects before copying data |
| Deployment and monitoring | The SSIS preview activity writes package logs to OneLake only when logging is enabled | Turn on logging in every SSIS activity you test |
| Retention and retirement | P capacities are sold only to customers that hold them on an active Enterprise Agreement | Align P capacity retirement with the agreement’s renewal date |
Azure-to-Fabric Mapping Reference
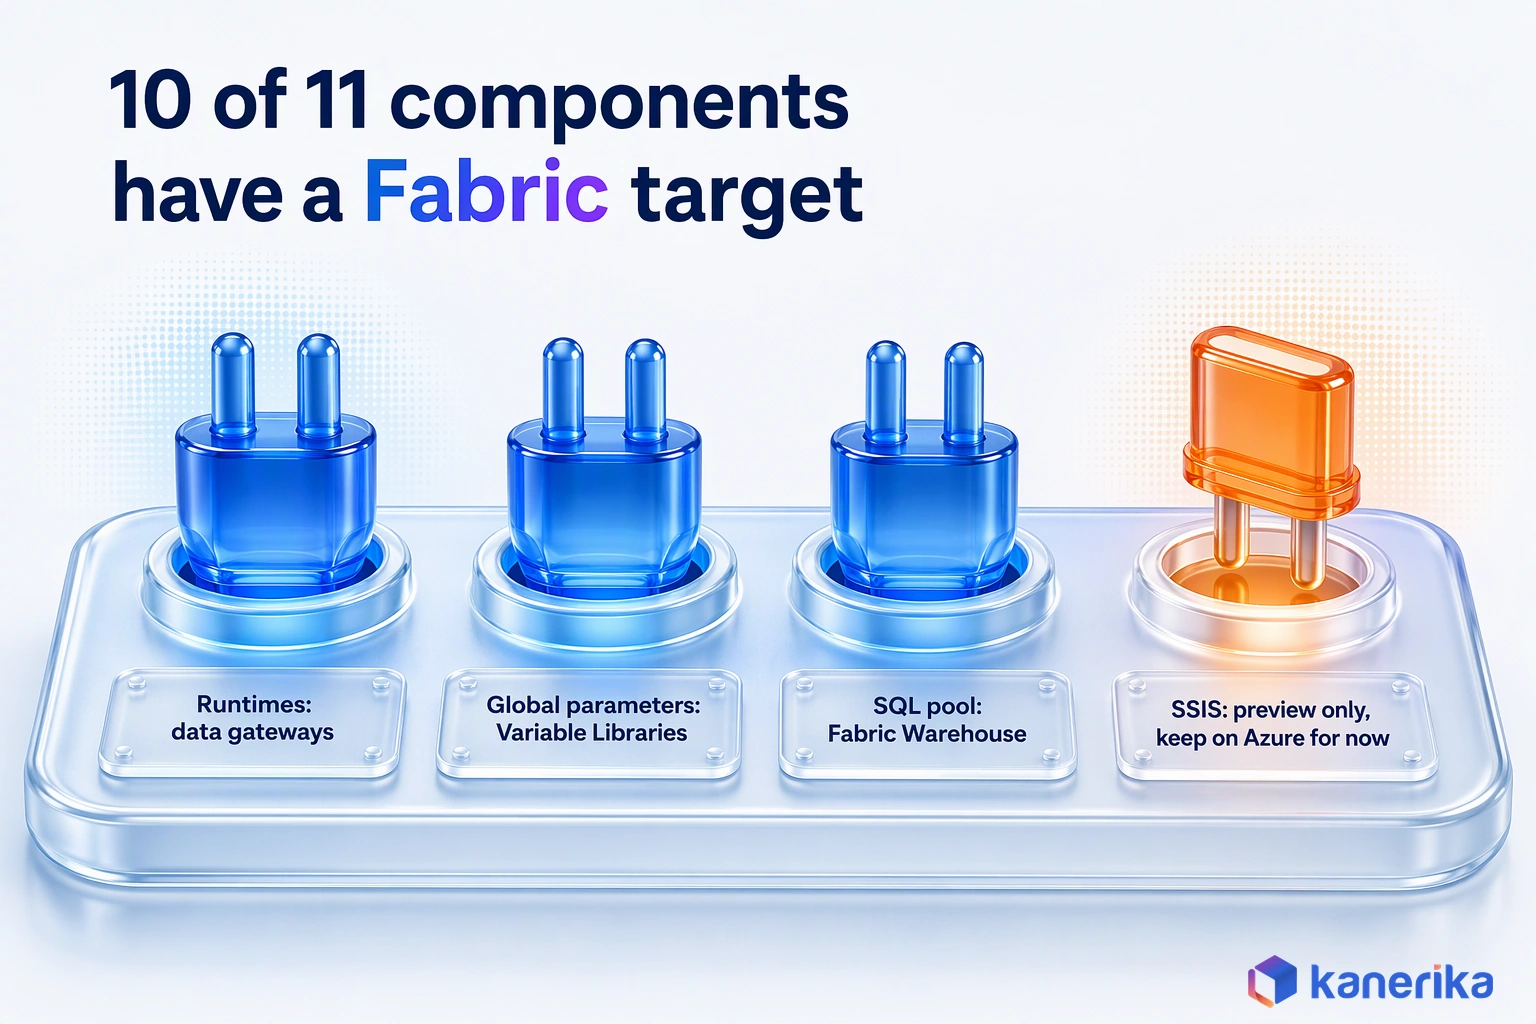
Ten of the eleven Azure components below have a full Fabric target. SSIS is the exception, with only a preview activity that has hard limits. Fabric’s Invoke SSIS Package activity runs .dtsx packages stored in OneLake, yet in preview it cannot reach on-premises or private-network sources or use custom components. The table maps each component and shows whether its path is direct, guided or in preview.
| Azure component | Fabric target | Path | Status |
|---|---|---|---|
| ADF linked services and datasets | Fabric connections | Built-in upgrade, or rebuild when needed | Direct mapping |
| Self-hosted integration runtime | On-premises data gateway | Install the gateway, then register it | Direct mapping |
| VNet-enabled Azure integration runtime | Virtual network data gateway | Configure the gateway inside the VNet | Direct mapping |
| SSIS integration runtime | Invoke SSIS Package activity (preview) | Run from OneLake if no on-prem, private-endpoint or custom components; else keep in ADF and call from Fabric | Preview, limited |
| Mapping Data Flows | MDF transforms in Dataflow Gen2 | Built-in upgrade when the flow is eligible | Preview, limited (Nov 2026) |
| Global parameters | Variable Libraries | Convert to workspace level before upgrade | Direct mapping |
| Change data capture | Copy job | Rebuild | Direct mapping |
| Airflow DAGs | Fabric Apache Airflow | Move DAG code | Direct mapping |
| Synapse dedicated SQL pool | Fabric Data Warehouse | Migration Assistant | Supported source |
| Synapse Spark notebooks, job definitions, lake databases | Fabric Data Engineering items | Code first, then metastore and data | Guided, phased |
| Power BI P SKU capacity | F SKU capacity | Reassign workspaces | P SKUs retiring |
The connection, gateway and parameter rows come from Microsoft’s Data Factory migration best practices. The Spark row follows the phased Synapse to Fabric Data Engineering guidance. That guidance moves pools, notebooks and job definitions first, then the Hive Metastore and data later.
Kanerika Service
Azure to Microsoft Fabric Migration Services
Kanerika assesses your Data Factory, Synapse and Power BI estate, converts supported workloads with FLIP and runs each wave through reconciliation and cutover.
Explore the Migration ServiceWhy Teams Migrate Now, and When to Wait
Like any data modernization program, a migration earns its cost when a deadline or a consolidation goal is real. It wastes money, though, when important features are still missing, and most estates have workloads in both camps.
So the useful question is not whether to move, but which workloads move first. The two lists below sort the reasons.
Triggers That Justify Migrating Now
- P SKU retirement: as of November 2026, Microsoft is retiring Power BI Premium per-capacity SKUs and recommends F SKUs, according to the Fabric licensing documentation.
- One capacity and one lake: Data Factory, Synapse workloads and Power BI can share a single Fabric capacity and OneLake instead of three separate bills.
- Delivery tooling: Fabric deployment pipelines give built-in dev, test and prod promotion in place of ARM-template release pipelines, and Git integration sits beside the data.
- Renewal dates: when a reserved capacity or enterprise agreement comes up for renewal, it is a natural point to stop paying for the old stack.
Microsoft also points to a Forrester Total Economic Impact study, published in June 2024, that reports a 379% ROI over three years. Microsoft commissioned that study, and it models a composite organization. So treat it as a directional benchmark rather than a forecast for your estate.
Reasons to Wait
- Your Mapping Data Flows use flowlets, the Data Flow Library, UDFs or a managed virtual network, which all sat on the preview’s limitation list in November 2026.
- Most of the logic lives in SSIS packages, so it needs its own conversion track.
- No one owns the capacity budget, so nobody can approve an F SKU or a reservation.
- Regulated data has no mapped control set for Fabric workspaces yet.
Waiting does not mean doing nothing, because you can still inventory, classify and pilot. If the target platform is really Databricks rather than Fabric, the planning pattern in the Informatica to Databricks migration guide is the better fit.
Migration ROI Calculator
Estimate Your Azure to Fabric Migration ROI
Compare what your Azure analytics estate costs today with a Fabric target, and see where migration effort and savings land before you plan the first wave.
Calculate Migration ROI →Four Migration Approaches: Mount, Upgrade, Rebuild, Replatform
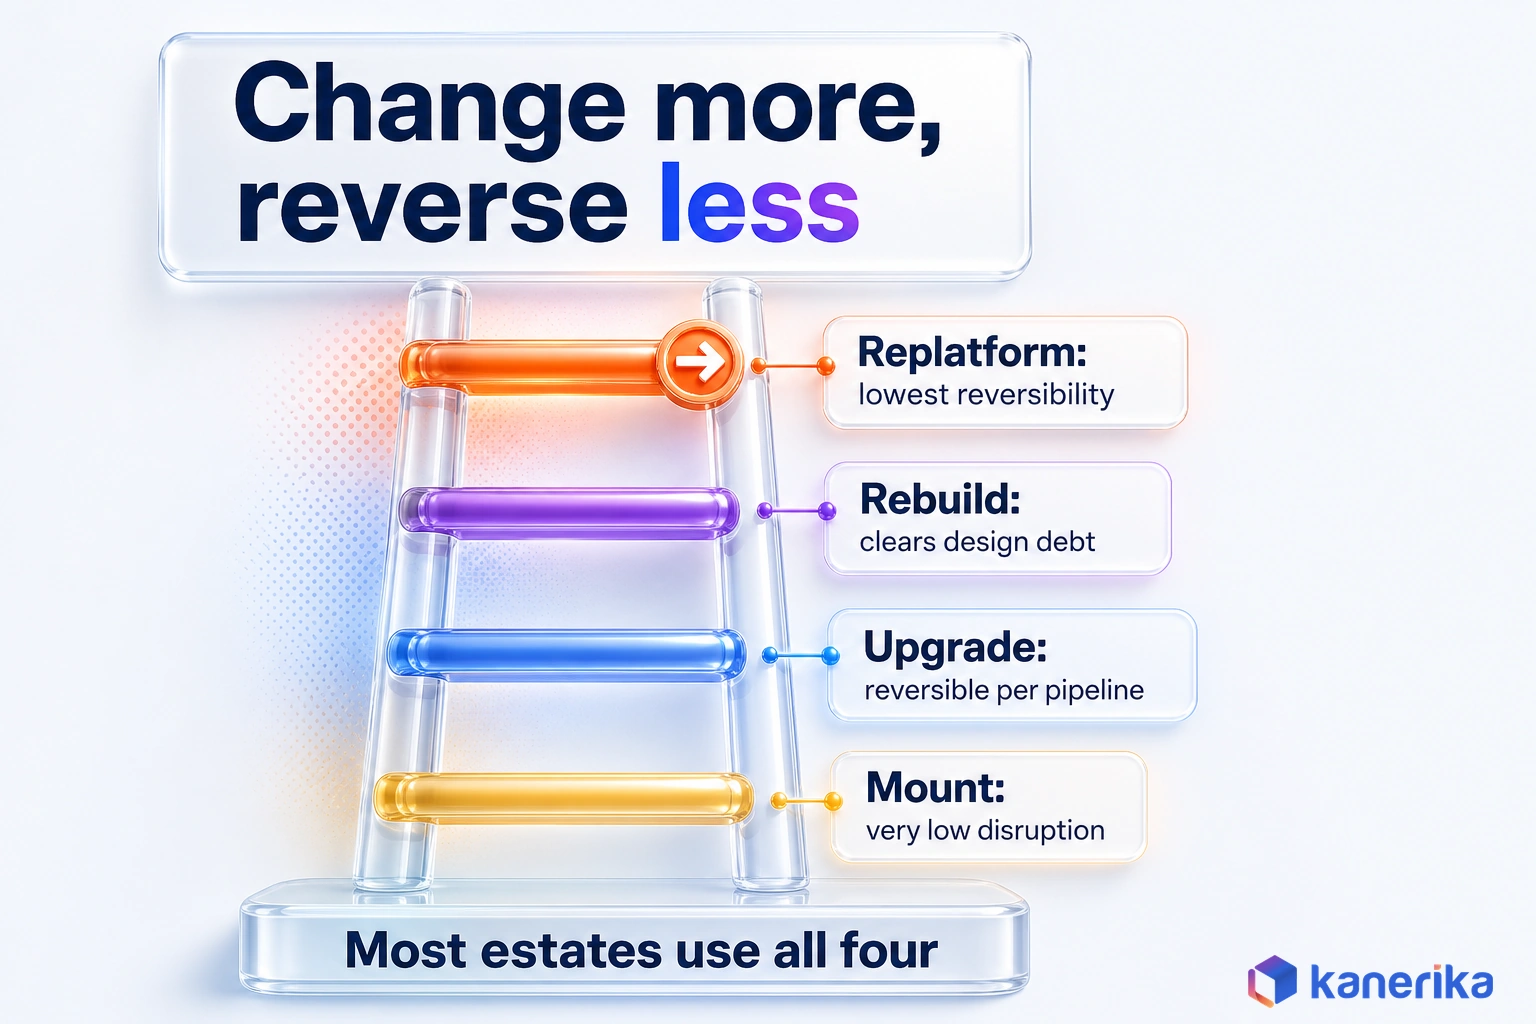
Microsoft’s own documentation names several paths away from Azure Data Factory, and they differ mainly in how much changes at once. Choosing one per workload, rather than one for the whole estate, also keeps risk small.
Mount brings an existing Data Factory into a Fabric workspace as an item, so pipelines keep running unchanged while the team learns Fabric. Built-in upgrade runs an assessment in Data Factory first, then upgrades the supported pipelines incrementally, with no scripts. Microsoft describes both in its migrate from Azure Data Factory guide.
Rebuild redesigns the logic in Dataflow Gen2, Warehouse SQL or notebooks, with Warehouse SQL suited to set-based ELT. It costs more effort, yet it lets you drop dead pipelines and fix old design debt instead of carrying it over.
Replatform goes further still and re-architects the data model onto a lakehouse or warehouse in OneLake. It suits teams that had already planned a redesign.
| Approach | What moves | Effort | Disruption | Reversibility | Best for |
|---|---|---|---|---|---|
| Mount | The whole factory, unchanged | Low | Very low | High | Continuity while you plan |
| Built-in upgrade | Supported pipelines and activities | Low to moderate | Low | High, per pipeline | Copy and orchestration pipelines |
| Rebuild | Logic, redesigned in Fabric items | Moderate to high | Medium | Partial | Unsupported features, especially design debt |
| Replatform | Data model and architecture | High | High | Low | A planned lakehouse or warehouse redesign |
A typical estate uses all four. Teams often mount first for continuity and then upgrade the simple pipelines. After that, they rebuild what the upgrade cannot carry.
Microsoft Fabric Migration Tools Compared
Several tools automate parts of the move, but none of them automates all of it. The table shows where each one stops.
| Tool | Source | What it automates | What stays manual |
|---|---|---|---|
| Built-in ADF upgrade | Azure Data Factory | Assessment, then upgrade of supported pipelines | Unsupported activities, SSIS and testing |
| Fabric Migration Assistant | Synapse dedicated SQL pool and other warehouses | Schema and code conversion from a DACPAC, scripts or a connection | Fixing scripts that fail, then validating data |
| Spark Migration Assistant plus phased guidance | Synapse Spark | Moves supported Spark items: notebooks, Spark job definitions and pools | Hive Metastore, data and code refactoring |
| Partner accelerators such as Kanerika FLIP | ADF and Synapse estates | Conversion of connections, data flow logic and schedules | Edge cases flagged for review, then sign-off |
| Copilot and LLMs | Any code | Documentation, explanations and suggested fixes | Every change still needs human approval |
The Migration Assistant documentation confirms that Copilot can help fix scripts the assistant could not convert into Fabric Data Warehouse objects. That pattern, where a model proposes and a person approves, is also the safe use of AI-powered data migration in general.
Tooling follows the approach, not the reverse. So pick mount, upgrade, rebuild or replatform for each workload first, then choose the tool that automates that path.
This guide does not re-teach the Fabric pipeline features, since a separate guide already does. For those details, see Data Factory in Microsoft Fabric.
Kanerika Service
FLIP Migration Accelerators
FLIP converts linked services, data flow logic and triggers into Fabric items and flags edge cases for review, across 24 supported migration paths.
Explore FLIPDecision Framework: Which Approach for Which Workload
A good migration decision checks what can break before it counts what can be gained. Teams that score benefits first tend to pick the highest-value workload, which is often the one with the most unsupported features.
Hard Gates Before You Score Benefits
Run each workload through six gates in order. When a workload fails a gate, it either waits or moves to a different approach.
- Supported features: every activity, connector and data flow feature has a Fabric path.
- Region, network and identity: the capacity region, gateways and Entra groups are ready before data lands.
- Reconciliation: you can compare row counts and totals between old and new outputs.
- Performance and rollback: the refresh SLA holds in a test, and the old path can still be switched back on.
- Budget and owners: a named person owns the capacity spend, as well as the workload after cutover.
- Priority: only then rank by business value, renewal dates and risk.
Pick by Scenario
Once the gates are clear, most workloads fall into a familiar pattern. The table gives the default pick for each one.
| Scenario | Pick | Why |
|---|---|---|
| Simple copy and orchestration pipelines | Built-in upgrade | Supported activities move, so rework stays low |
| Mapping Data Flows with flowlets or UDFs | Stay on Azure, or rebuild | Both on the preview limitation list (Nov 2026) |
| SSIS packages | Keep on Azure, then call from Fabric | The Fabric SSIS activity is preview and cannot reach on-premises or private sources |
| Synapse dedicated SQL pool warehouse | Migration Assistant to Fabric Data Warehouse | A supported source, so conversion is automated |
| Synapse Spark with a Hive Metastore | Phased Spark migration, starting with the Spark Migration Assistant | Code moves first, then metastore and data |
| Power BI only, on a P SKU | Move workspaces to an F SKU | P SKUs are retiring, so move early |
| Pipelines with heavy design debt | Rebuild | Cheaper to redesign than to carry the debt |
SSIS-heavy estates need a separate plan for package conversion. The SSIS to Fabric migration guide covers that work step by step.
Talk to Kanerika
Planning Your First Fabric Wave?
Bring your pipeline inventory. Kanerika will run it through the six gates and propose a pilot domain, an approach per workload and a cutover plan.
Schedule a Demo →Worked Example: Move Reporting First, Keep SSIS on Azure
Return to the finance team from the opening. The example is illustrative, but the logic carries over to most estates.
- Move the Power BI workspaces from the P1 to an F SKU first, because that change has a fixed deadline and little logic risk.
- Run the Migration Assistant on the Synapse dedicated SQL pool, then point the reports at the new Fabric warehouse.
- Upgrade the copy pipelines that feed the warehouse, while the rest of the factory stays mounted for continuity.
- Leave the 40 SSIS packages on Azure, called from a Fabric pipeline, until a later wave tests them against the preview activity or converts them.
The wave passes only when three acceptance criteria hold. Ledger totals must match the old warehouse exactly, and every report must refresh inside its SLA. The team also keeps a two-week rollback window.
Step-by-Step Migration Sequence
The sequence below turns the decisions into waves. Each step produces an output that the next step depends on, so skipping one usually means doing it later under pressure. The graphic shows five milestones; gateway and connection setup (step four) sits between the pilot and the first wave.
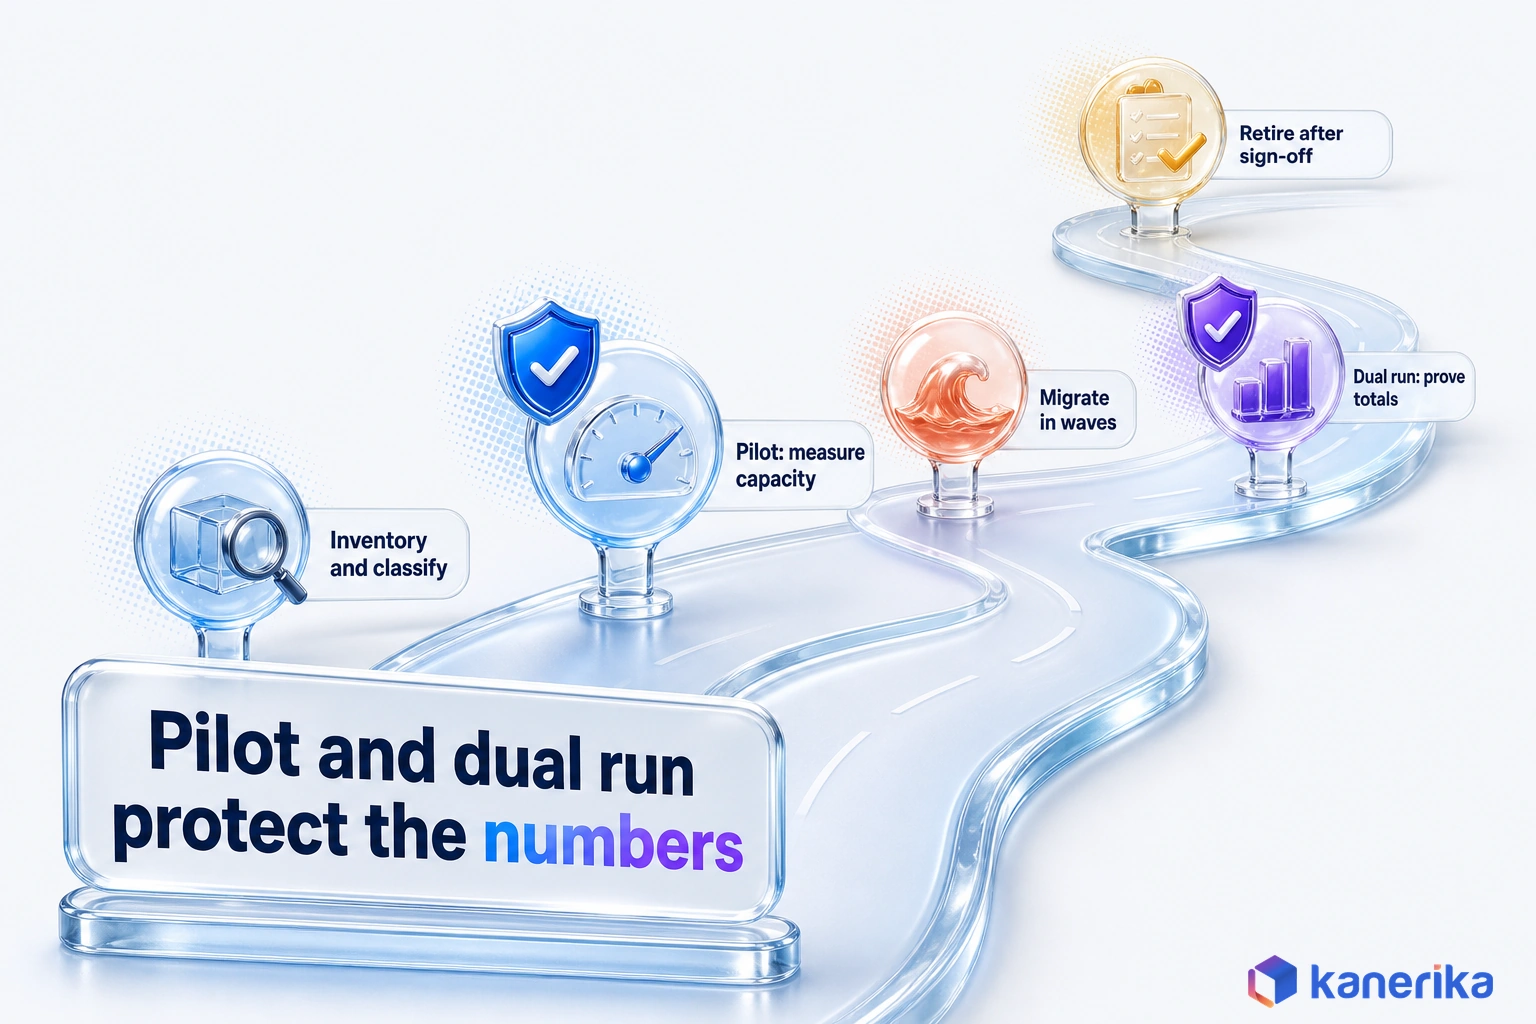
- Inventory: list every pipeline, data flow, linked service, integration runtime, trigger and report, along with its owner.
- Classify: tag each item with an approach, then note the gates it passes or fails.
- Pilot one domain: move one business domain end to end, so capacity and effort are measured rather than guessed.
- Build gateways and connections: set up on-premises and virtual network gateways, connections and Variable Libraries before the first wave.
- Migrate in waves: group workloads by domain and dependency rather than by tool.
- Dual run and reconcile: run old and new in parallel, then compare outputs for every scheduled load.
- Retire: switch off the Azure resources only after sign-off, and then remove their cost.
Steps three and six do the most to protect the numbers. A pilot shows the real capacity load, while the dual run proves the totals before anyone depends on them.
Design Cutover and Rollback Before the Pilot
Cutover is the moment the new pipeline becomes the one that counts. Plan it before the pilot starts, because the pilot is where you rehearse it.
- Keep triggers on the new pipelines switched off until reconciliation is signed off.
- Decide who flips the switch, as well as who can reverse it.
- Write down the rollback trigger, such as a total that differs by any amount.
- Keep the old pipelines runnable during the full rollback window.
Reconciliation works best as a query that runs on both sides and produces the same small summary. You run the sketch below against the old Synapse pool and the new Fabric warehouse, then compare the two result sets.
-- Run on the old Synapse pool and on the new Fabric warehouse,
-- then compare the two outputs line by line.
SELECT
    fiscal_period,
    COUNT(*)              AS row_count,
    SUM(amount)           AS total_amount,
    MIN(posting_date)     AS first_posting,
    MAX(posting_date)     AS last_posting
FROM finance.gl_entries
WHERE fiscal_period >= '2026-01'
GROUP BY fiscal_period
ORDER BY fiscal_period;
Any difference in a count or a total blocks the cutover for that wave. Large estates often script this check with one of the data reconciliation tools built for migrations. The table and column names here are placeholders, so swap in your own ledger table.
Fabric Capacity Sizing and Migration Cost
Fabric pricing starts with capacity, which is measured in capacity units, or CUs. The migration then adds one-time costs on top, and both are easier to estimate after a pilot than before it.
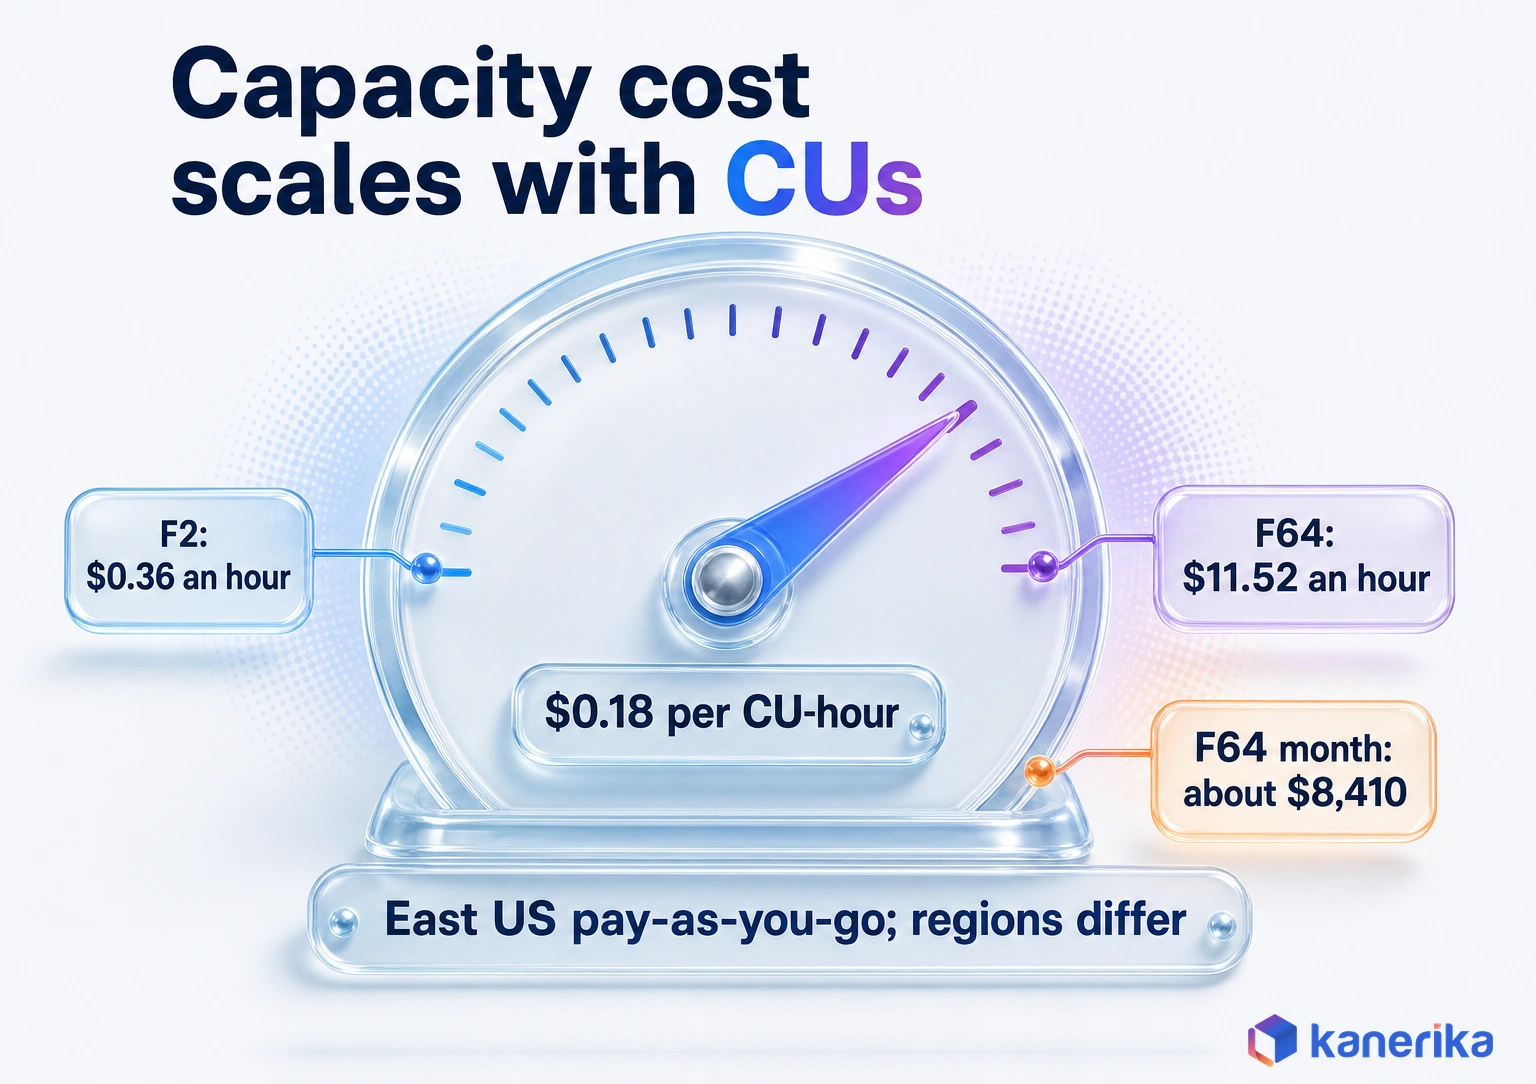
In November 2026, the Azure Retail Prices API listed pay-as-you-go Fabric capacity at $0.18 per CU-hour in East US. An F2 has 2 CUs, so it costs $0.36 an hour, while an F64 has 64 CUs and costs $11.52 an hour. Over a 730-hour month, that F64 therefore comes to about $8,410.
Azure bills capacity per second with a one-minute minimum, and a yearly reservation is optional. F64 is also the smallest SKU on which viewers with only a free license can open Power BI content. Below F64, every viewer needs a Pro or PPU license, which often decides the SKU for a large report audience on its own. The Microsoft Fabric capacity planning guide covers how to read pilot usage against each SKU.
SSIS packages tested on the preview activity add their own meter. Microsoft bills SSIS uptime at 1.35 CU hours per vCore, and each workspace gets a fixed 4 vCores during preview. The runtime also stays up for 30 minutes after the last package finishes, so a nightly batch pays for that tail as well.
What a Migration Budget Includes
Capacity is only one line, because the move itself carries one-time costs. Regional prices also differ, so check the Azure Fabric pricing page before you budget.
For teams in the Midwest, see our data migration services in Ohio.
| Cost line | One-time or ongoing | How to estimate |
|---|---|---|
| Fabric capacity | Ongoing | Pilot CU usage, times CU-hour price, times hours run |
| Dual-run period | One-time | Azure plus Fabric costs during each wave’s window |
| Conversion effort | One-time | Pipeline count, activity types and unsupported features |
| Testing and reconciliation | One-time | Outputs that need sign-off before each wave closes |
| Gateways and networking | One-time, then ongoing | Gateway hosts and virtual network setup |
| Training and runbooks | One-time | Teams that own Fabric once cutover ends |
Effort scales with the number of pipelines, the activity types they use and the share of unsupported features, rather than data volume alone. For example, a 5 TB warehouse with clean SQL can move faster than 200 pipelines full of custom data flows.
Full SKU tiers and reservation options are covered in understanding Microsoft Fabric pricing. Microsoft also runs programs that offset migration costs, as explained in how to reduce Microsoft Fabric migration costs with Microsoft funding.
Governance, Security and Identity During Migration
Permissions do not travel with the data, so every access rule has to be rebuilt on the Fabric side. The safest order is to map controls before data lands, not after users start asking for access.
Fabric uses workspace roles, connections and gateways, which are new objects to many Azure teams. Lineage needs the same care, because Microsoft Purview has to scan the Fabric tenant before data lineage shows up for the new items. The table pairs each Azure control with its Fabric counterpart, then gives the check to run before cutover.
| Azure control | Fabric equivalent | Owner | Migration check |
|---|---|---|---|
| Resource and data access roles | Workspace roles and item permissions | Platform admin | Each Entra group keeps the same reach, no more |
| Linked service credentials, managed identity | Connections with stored credentials | Data engineering lead | No personal accounts in production connections |
| Integration runtimes | On-premises and virtual network gateways | Infrastructure team | Gateway throughput tested at peak load |
| Purview scans and lineage | Purview scans of the Fabric tenant | Data governance lead | Lineage visible before cutover |
| ARM templates and release pipelines | Git integration and deployment pipelines | DevOps owner | Dev, test and production kept apart |
For sensitivity labels, domains and policy design, see the Microsoft Fabric governance guide. This section only covers the controls that must exist before cutover.
Mistakes That Stretch a Microsoft Fabric Migration
Most delays come from a short list of avoidable mistakes, and each one has a cheap fix when you catch it early. The graphic pairs five of them with a fix each, while all seven below show up across ADF, Synapse and Power BI moves.
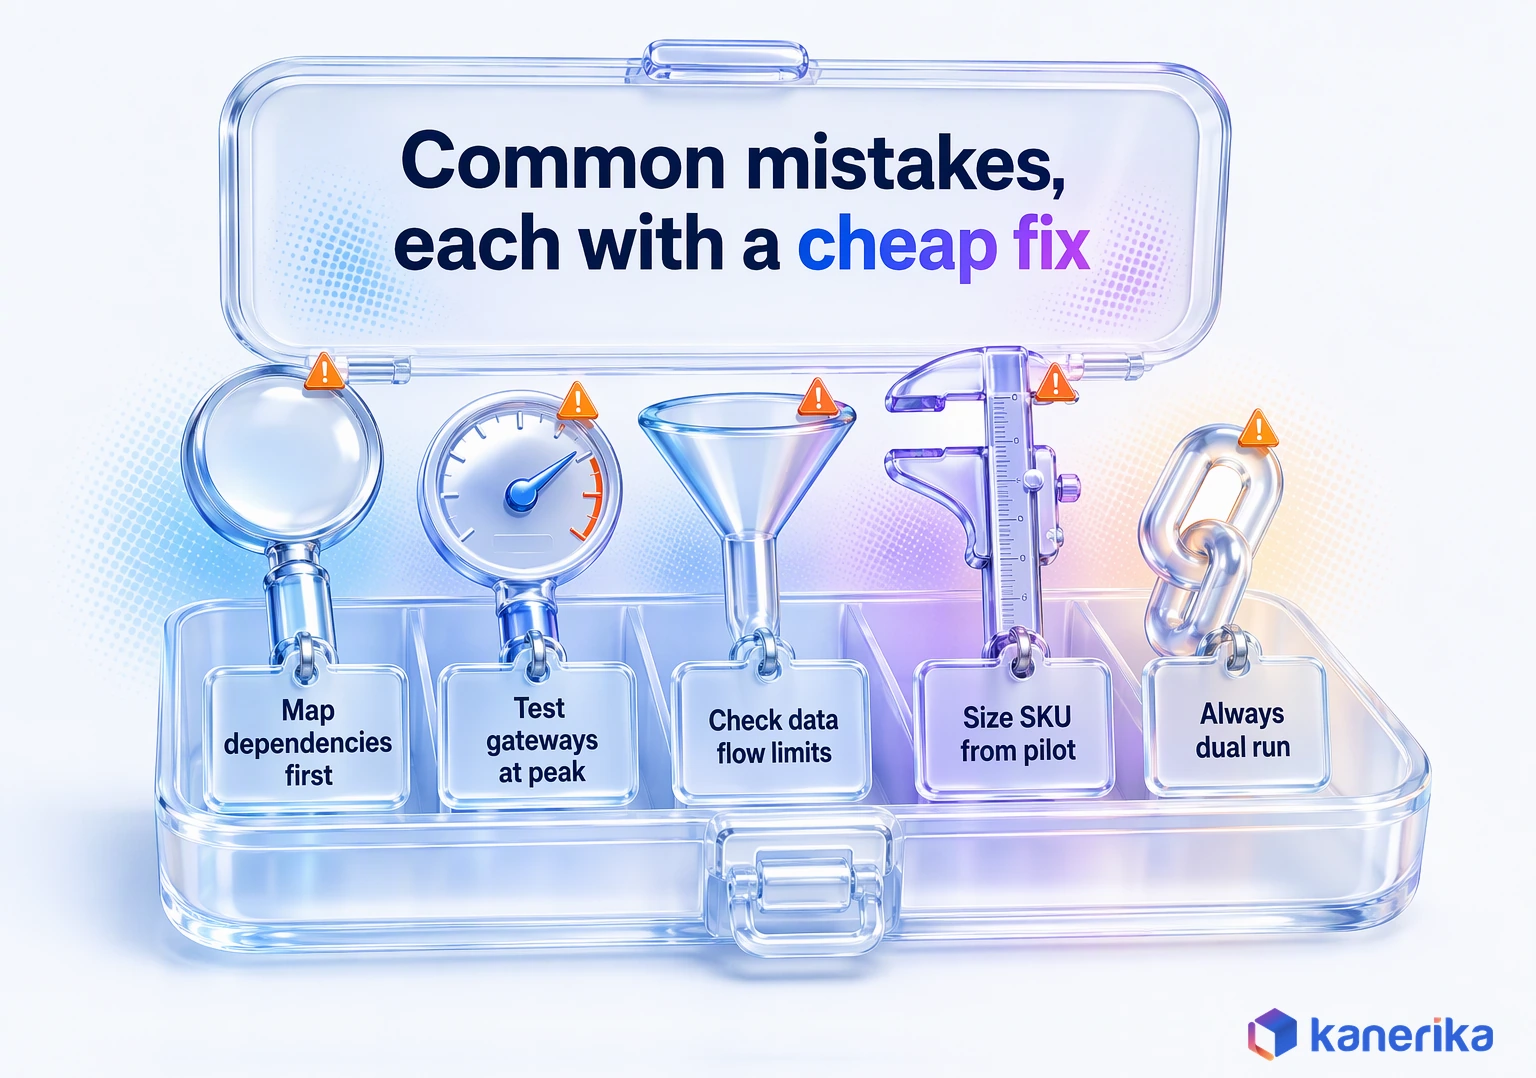
- Copying data before mapping dependencies. The tables arrive, but the triggers and key vault secrets that ran them do not. Finish the inventory first.
- Treating the gateway as a like-for-like swap. A self-hosted runtime that served one factory may choke once it becomes a shared gateway, so size it and test it at peak load.
- Assuming every Mapping Data Flow upgrades. Flowlets, UDFs and managed virtual networks were still on the limitation list in November 2026. Check each flow against that list before you schedule it.
- Leaving global parameters behind. Microsoft’s guidance is to convert them to workspace-level Variable Libraries, and doing it before the first upgrade keeps every upgraded pipeline reading one set of values.
- Skipping the dual run. Without one, the first sign of a wrong total is a finance user at month-end. Reconcile counts and totals for every wave instead.
- Who repoints the reports? If nobody owns that question, Power BI datasets keep reading the old warehouse long after cutover. List each one, then repoint and test it.
- Sizing capacity from a guess. Pilot CU usage is the only number worth buying an F SKU on.
Several of these mirror the common data migration challenges seen on any platform move, and the wider data migration risks still apply. The Fabric-specific twist is that feature support changes often, so recheck the limitation list and the Microsoft Fabric latest updates before each wave.
How Kanerika Runs Azure to Fabric Migrations
Kanerika runs Azure to Fabric migrations in five stages, with automation doing the repetitive conversion while engineers handle the edge cases. The approach also follows the gates and waves described above.
- Assess: inventory pipelines, integration runtimes and linked services, then classify each one.
- Convert with FLIP: turn linked services into connections and triggers into schedules. Data flow logic moves to Dataflow Gen2 or notebooks, while edge cases go to manual review.
- Validate: test each converted item for functional parity with the original.
- Cut over: move in waves, with dual running and reconciliation.
- Hand over: deliver runbooks so the client team owns the new platform.
Kanerika’s Azure to Fabric migration service page states that automated migration with FLIP typically cuts total effort by 70 to 83% compared with a manual rebuild. It also cites about 2,425 hours saved in complex environments.
FLIP accelerators cover 24 supported migration paths. The offer is also listed on Microsoft Marketplace, where it can count toward an Azure consumption commitment.
Case Study: A Packaging Leader Moves ADF and Synapse to Fabric
One engagement shows the stages at work. A global leader in packaging solutions had data workflows scattered across Azure Data Factory and Synapse. An intermediate Parquet conversion step also caused latency and failures, and there was no unified governance model.
Kanerika migrated the workloads to Fabric with its migration utility and built a direct SAP C4C to Fabric integration, which removed the Parquet step. Alongside that, the team set up a governance framework for naming, version control and documentation. Other SAP sources follow similar routes, covered in SAP data integration.
As reported on the case study page, the client saw 30% lower cloud and data costs and a 50% improvement in its data pipeline. Insights and reporting also became 80% faster, and the full Azure Data Factory to Microsoft Fabric case study describes the setup.
This pattern matches the mistakes list above. Instead of copying an intermediate step into Fabric, the team removed it, and it set governance rules before the waves rather than after them.
Case Study
80% Faster Insights with Azure to Microsoft Fabric
A global leader in packaging solutions moved scattered ADF and Synapse workflows to Fabric, cutting cloud and data costs by 30% and speeding insights and reporting by 80%.
Read the Case Study →Go/No-Go Checklist Before Cutover
A wave is ready to cut over when every item below is a yes. One “no” means the wave waits, even if the calendar says otherwise.
- Every item in the wave has passed the six hard gates.
- Row counts and totals match between old and new outputs for at least one full business cycle.
- Refresh times stay inside the agreed SLA on the chosen F SKU.
- Gateways have been tested at peak load.
- Workspace roles and connections are mapped, with no personal accounts in production.
- Every Power BI report points at the new source, and its owner has checked it.
- The rollback trigger, owner and window are written down.
- Triggers on the new pipelines are ready to switch on, while the old ones are ready to switch off.
- A named owner has signed off the capacity budget and the run cost.
So, how do you move Azure Data Factory, Synapse and Power BI workloads to Fabric? Upgrade the supported pipelines, move warehouses with the Migration Assistant and shift P SKUs to F SKUs. Keep SSIS on Azure unless packages fit the preview activity’s limits, then cut over wave by wave, only when this checklist reads yes.
Frequently Asked Questions
Is Azure Data Factory going away?
Microsoft has not announced a retirement date for Azure Data Factory, and it continues alongside Fabric Data Factory. New investment is concentrated in Fabric, though, which is why Microsoft provides a mount option and a built-in upgrade for moving pipelines. Plan a gradual move in waves rather than a rushed switch driven by deprecation rumors.
Will Microsoft Fabric replace Azure?
No. Fabric runs on Azure and uses an Azure subscription for F SKU capacity, so it does not replace Azure as a cloud. It does bring analytics services such as Data Factory, data warehousing, Spark and Power BI into one capacity and one data lake, which can replace several separate Azure analytics resources over time.
Does Fabric support every Azure Data Factory connector?
Not always, and connector support changes as Microsoft ships updates. Check the Fabric connector list for every source and sink in your inventory before you plan a wave. A pipeline that depends on an unsupported connector should stay on Azure, be mounted for continuity, or be redesigned around a supported connector or a gateway path.
How do I handle SSIS packages during a Fabric migration?
Fabric has no SSIS integration runtime, so keep the packages running in Azure Data Factory and call those pipelines from Fabric. That lets you move everything around them first. Convert the packages in a later wave, once their logic is documented and tested. The SSIS to Fabric migration guide on our blog covers the conversion paths.
Why migrate Azure Data Factory to Fabric?
Moving to Fabric puts pipelines, warehousing, Spark and Power BI on one capacity and one data lake, with Git integration and deployment pipelines in the same workspace. It also prepares Power BI estates for the retirement of P SKUs. The case is strongest when a renewal date or consolidation goal makes the timing clear.
How do I connect Azure Data Factory to Fabric?
The simplest link is to mount your Azure Data Factory as an item inside a Fabric workspace, which keeps its pipelines running unchanged. Fabric pipelines can also call Azure Data Factory pipelines, which is how teams keep SSIS packages running during a migration. Both options let the two platforms work together while you move workloads in waves.
Is Microsoft Fabric better than Azure Data Factory?
It depends on the workload. Fabric adds one capacity, OneLake and closer ties to Power BI, while Azure Data Factory still runs SSIS and some Mapping Data Flow features that Fabric does not fully support yet. For simple pipelines, Fabric is usually the better long-term home, and for SSIS-heavy estates Azure stays practical for longer.
How do I migrate an ADF pipeline to Fabric step by step?
Run the built-in assessment in Azure Data Factory first. Create the Fabric connections and gateways the pipeline needs, and convert global parameters to Variable Libraries. Then upgrade the pipeline, keep its new trigger off and run it alongside the original. Switch the trigger on only after the outputs reconcile, and keep the old pipeline ready for rollback.
What is the difference between ADF and Fabric pipelines?
Both orchestrate activities, but Fabric pipelines live in a Fabric workspace and use connections rather than linked services and datasets. Fabric replaces integration runtimes with gateways and global parameters with Variable Libraries. Change data capture moves to Copy job and Airflow DAGs move to Fabric Apache Airflow, so the logic is similar but the objects differ.
Is Microsoft Fabric the future of Microsoft analytics?
Microsoft is concentrating new analytics features in Fabric, retiring Power BI Premium P SKUs in favor of F SKUs and publishing migration paths from Data Factory and Synapse. That makes Fabric the strategic direction. Existing Azure services remain supported, though, so teams can move at the pace their feature support, budget and reconciliation gates allow.
What is the difference between Azure Synapse and Microsoft Fabric?
Synapse is a set of Azure analytics services, including dedicated SQL pools and Spark pools, billed and managed as separate resources. Fabric is a software-as-a-service platform where warehousing, Spark, data integration and Power BI share one capacity and OneLake. Fabric offers migration paths for Synapse dedicated SQL pools and Synapse Spark workloads.
Why use Fabric over separate Azure services?
One capacity replaces several separately sized resources, and OneLake gives every workload the same copy of the data. Teams also get Git integration, deployment pipelines and Copilot in one workspace. Separate Azure services still make sense where Fabric lacks a feature you rely on, such as SSIS, so many estates run both for a while.
Can I migrate ADF pipelines directly to Fabric?
Yes, for supported pipelines. Microsoft’s built-in upgrade runs an assessment in Azure Data Factory, then upgrades supported pipelines incrementally without scripts. You can also mount the whole factory in Fabric for continuity. Pipelines using SSIS, or Mapping Data Flow features on the preview limitation list, need a rebuild or must stay on Azure for now.
Do Mapping Data Flows migrate to Microsoft Fabric?
Eligible ones do. The built-in upgrade moves them to Mapping Data Flow transforms in Dataflow Gen2 and keeps Spark execution, but this path is in preview. Flows that use flowlets, the Data Flow Library, UDFs, a managed virtual network or direct Dataflow Gen2 execution are on the limitation list, so check every flow before planning its wave.
How do I migrate a Synapse dedicated SQL pool to Fabric?
Use the Fabric Data Warehouse Migration Assistant, which accepts a DACPAC, a zip of SQL scripts or a direct connection, and lists Synapse dedicated SQL pools as a supported source. It converts schema and code, and Copilot can help fix scripts that fail. Then move the data, repoint reports and reconcile totals before cutover.
What happens to Power BI Premium P SKUs?
Microsoft is retiring Power BI Premium per-capacity P SKUs and recommends moving to Fabric F SKUs. F64 lists P1 as its compute reference, though that is not a licensing equivalence. Plan the move as its own early wave, reassigning workspaces to the F SKU capacity and checking refresh times and report access before the P SKU ends.
How much does Fabric capacity cost for a migration?
The Azure Retail Prices API lists pay-as-you-go Fabric capacity at $0.18 per CU-hour in East US. An F2 costs $0.36 an hour and an F64 about $11.52, or roughly $8,410 for a 730-hour month. Billing is per second with a one-minute minimum, and regional prices differ, so check the pricing page before budgeting.
How long does an Azure Data Factory to Fabric migration take?
It depends on pipeline count, activity types and how many features lack a Fabric path, more than on data volume. A small estate of simple copy pipelines can move in a few waves, while hundreds of pipelines with custom data flows and SSIS packages take much longer. Run a pilot domain first and estimate from its measured effort.
Are Azure Data Factory and Fabric Data Factory the same?
They share the same pipeline concepts and much of the same activity model, but they are different products. Fabric Data Factory runs inside a Fabric workspace and uses connections, gateways and Dataflow Gen2, while Azure Data Factory uses linked services, integration runtimes and Mapping Data Flows. That is why some items map directly and others need conversion.
Do you need Azure to use Microsoft Fabric?
You need a Microsoft Entra tenant, and you buy F SKU capacity through an Azure subscription. Organizations that still hold Power BI Premium P SKUs can run Fabric on that capacity until they move. You do not need existing Azure Data Factory or Synapse resources, because Fabric includes its own data integration, warehousing and Spark workloads.
Is Azure Synapse being retired?
Microsoft has not announced a retirement date for Azure Synapse Analytics in the pages reviewed for this guide. It does publish migration paths, including the Migration Assistant for dedicated SQL pools and phased guidance for Synapse Spark. Treat Synapse as a supported service with a clear successor, and move it when your gates and renewal dates line up.
Do I need special licensing for Microsoft Fabric?
Fabric uses capacity licensing through F SKUs, which range from F2 to F2048 and are measured in capacity units. Users with a free license can view shared content only on F64 or larger capacities, which matters for large report audiences. Microsoft is retiring Power BI Premium per-capacity P SKUs in favor of F SKUs.
Can I run ADF and Fabric pipelines at the same time?
Yes. Mounting an Azure Data Factory as an item in a Fabric workspace keeps existing pipelines running unchanged while you upgrade or rebuild others. Running both side by side is also how you dual run a wave, comparing row counts and totals from the old and new pipelines before switching the new triggers on and the old ones off.
What happens to my integration runtimes in a Fabric migration?
Self-hosted integration runtimes map to the on-premises data gateway, and VNet-enabled Azure integration runtimes map to virtual network data gateways. SSIS integration runtimes are not available in Fabric, so those packages keep running through Azure Data Factory. Test gateway throughput at peak load, because one gateway may now serve workloads that several runtimes handled before.