TL;DR
Choose native Azure monitoring tools for an Azure-only estate, and a third-party platform such as Datadog, Dynatrace or New Relic for a multi-cloud one. The native stack links Azure Monitor, Log Analytics, Application Insights, Managed Prometheus and Azure Managed Grafana into one system. AKS-heavy teams should add Managed Prometheus with Managed Grafana, and regulated estates also need Microsoft Sentinel as a separate security layer. Log ingestion drives the bill, with Analytics Logs at $2.30 per GB and Basic Logs at $0.50 (East US list prices, November 2026). Moving 40 of 80 GB a day of verbose logs to Basic cuts ingestion cost by about 39%. Instrument with OpenTelemetry so the backend stays swappable, and prove any tool on one critical service for 30 days before you buy.
Key Takeaways
- Azure monitoring tools cover four layers, platform, application, network and security, and each layer needs its own signals and alerts.
- Azure Monitor is the hub: Log Analytics stores logs, Application Insights traces applications, and Managed Prometheus with Grafana covers Kubernetes.
- Third-party platforms earn their cost when you run several clouds or need one service view across many subscriptions.
- Table plans, data collection rules, sampling, retention and a daily cap are the five levers that control Log Analytics spend.
- Enforce diagnostic settings with Azure Policy and give every alert a named owner, or coverage drifts as the estate grows.
- Monitoring depends on knowing which services exist and who owns them, so build that inventory before you pick tools.
The Dashboard Is Green, but Checkout Is Failing
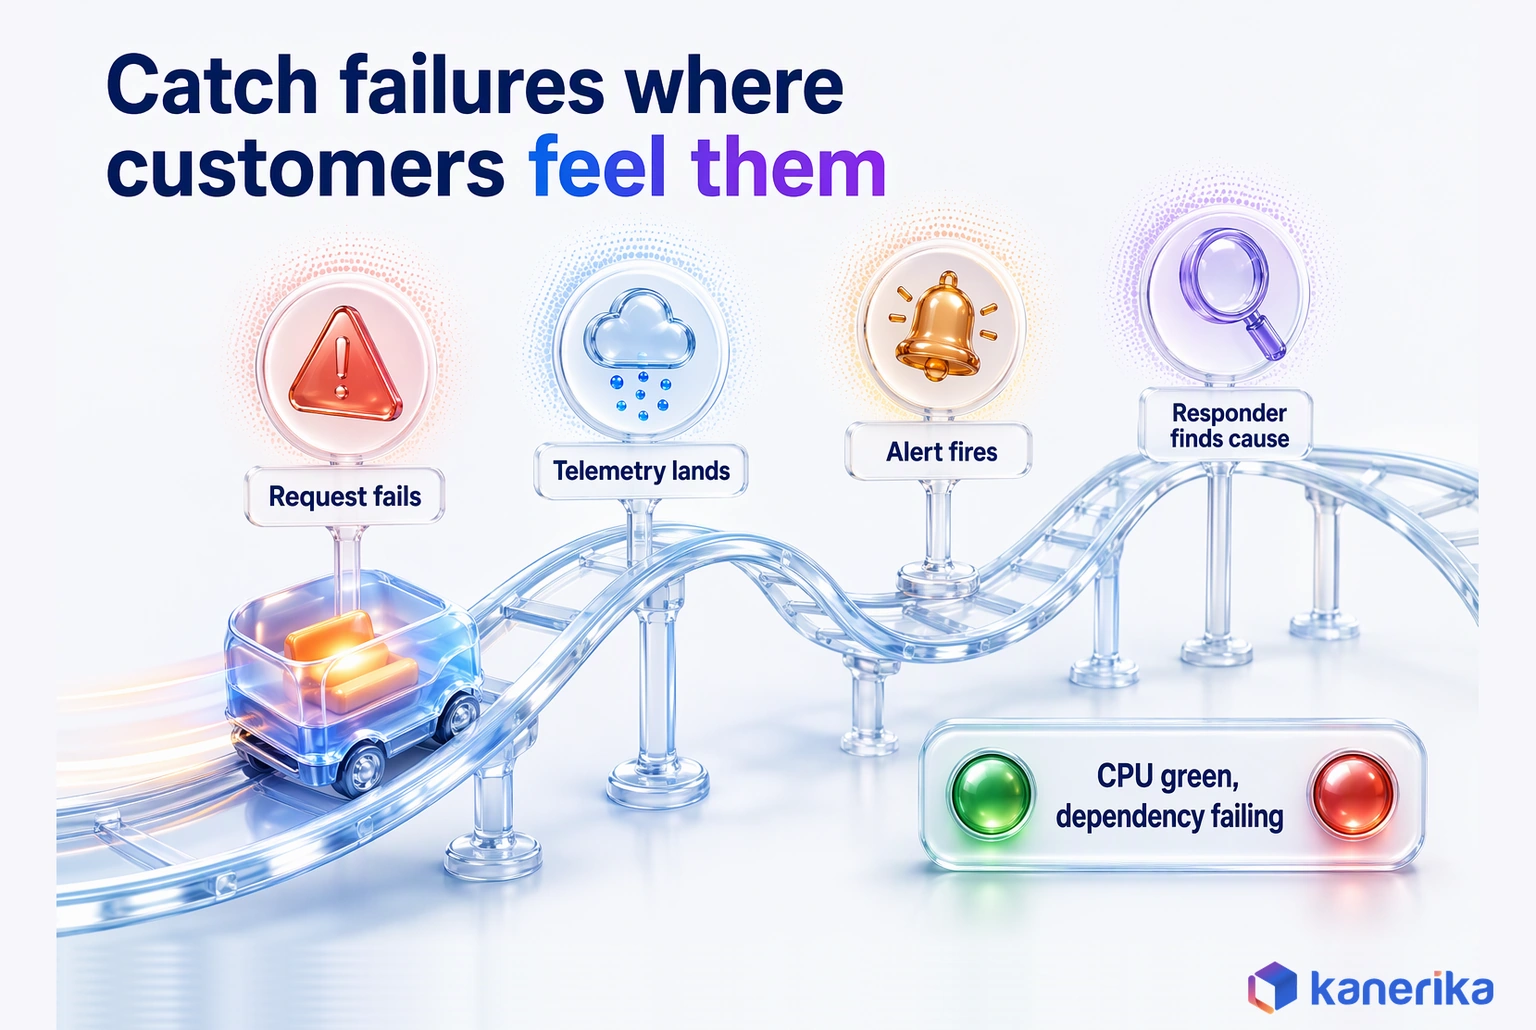
Picture a Friday evening at an online retailer. Every tile on the operations dashboard is green. Its checkout service runs on Azure Kubernetes Service (AKS), and the pods look healthy with CPU near 40%. Even so, completed orders have fallen sharply in twenty minutes.
The cause sits one hop away. A payment provider’s API has started timing out, so every checkout call waits, retries and then fails. No alert fired, because every rule in the workspace watched CPU, memory and pod restarts.
That gap is exactly what Azure monitoring tools exist to close. Infrastructure health and customer experience are different questions, and a good stack answers both of them quickly.
This guide explains what the tools cover and how the native stack fits together. It also compares third-party platforms and prices a real logging bill. Finally, a decision table by estate type helps you pick a stack and defend the choice.
What Azure Monitoring Tools Cover in 2026
Azure monitoring tools collect signals from your cloud resources and applications, then turn them into alerts, dashboards and answers during an incident. The easiest way to understand the category is by layer, because each layer fails in its own way.
At the base, the platform layer is the infrastructure itself: virtual machines, databases, storage accounts and AKS nodes. The application layer is the code your customers touch, including every call it makes to a database or an outside API. In the checkout story, for example, the platform layer was healthy while the application layer was broken.
Two more layers sit around those. First, the network layer covers the paths between subnets, regions and your data center. Second, the security layer watches identities and threats, and it usually belongs to a different team with different tools. That team often runs it as part of a zero trust data security program. Taken together, a complete monitoring setup gives each layer a signal source, an owner and at least one alert that reflects what customers feel.
| Layer | Example signal | Native Azure tool |
|---|---|---|
| Platform | VM CPU, disk latency, HTTP 5xx on App Service, AKS node pressure | Azure Monitor metrics and resource logs, Container insights |
| Application | Request duration, failed dependency calls, exceptions | Application Insights |
| Network | Connection failures, packet loss, latency between regions | Network Watcher |
| Security | Risky sign-ins, threat detections, policy violations | Microsoft Sentinel |
Read the table from left to right when you plan coverage. If a row has no signal flowing yet, then that layer is blind, and an incident there will reach customers before it reaches your team.
Case Study
90% Fewer Security Vulnerabilities with IT Optimization
See how a leading global logistics provider gained visibility across regionally spread servers and clear ownership of every hosted application, the groundwork monitoring depends on.
Read the Case Study →The Signals and Metrics That Matter
Every layer produces four kinds of telemetry. Metrics are numbers sampled over time, and logs are timestamped records. Traces follow one request across services, while events record changes such as a deployment or a scaling action. Good monitoring therefore joins them, so a spike on a chart leads straight to the trace and the log line behind it.
Still, you do not need hundreds of charts to start. Instead, a short list per layer catches most incidents:
- Platform: CPU, memory, disk latency and HTTP 5xx rate for each resource.
- Application: request rate, error rate and duration, plus the failure rate of each dependency.
- Containers: pod restarts, pending pods and node memory pressure.
- Network: connection failures, cross-region latency and packet loss.
- Data and AI: pipeline run failures, data freshness, model latency and token use.
- Security: failed sign-ins and new high-severity incidents.
- Cost: billable gigabytes ingested per day, broken down by table.
The last row surprises many teams, because telemetry has its own bill, and it grows quietly with every new resource that sends logs.
How Azure Monitoring Works: Following One Failed Request
Azure monitoring works as a path. Telemetry leaves the workload, lands in a store, gets checked by a rule and then reaches a person who can act. Following one failed checkout request through that path shows where each tool earns its place.
- The request fails. Application Insights records the checkout request, the slow call to the payment API and the exception it threw.
- Telemetry lands in a workspace. Request, dependency and exception records flow into a Log Analytics workspace, where they can be queried with Kusto Query Language (KQL).
- Platform metrics flow in parallel. AKS node and pod metrics reach Azure Monitor metrics and Managed Prometheus, so the cluster view stays current.
- An alert rule evaluates a condition. For example, a rule checks whether the payment dependency failure rate stays above 5% for five minutes.
- An action group notifies people. The alert pages the on-call engineer and posts to the team channel with a link to the evidence.
- Diagnosis follows. From there, the engineer opens the end-to-end transaction view, follows the trace to the payment call and confirms the pattern with a KQL query.
- The loop closes. After the fix, the team keeps the new alert and adds a dashboard tile, so the same failure shows up in minutes next time.
What the Walk-Through Reveals
Now notice what made the difference in that walk-through. The CPU metric never moved, but the dependency signal did. In other words, a stack that collects traces and alerts on customer-facing symptoms catches the failure, while one that only watches infrastructure stays green.
The path also shows where delays tend to hide. An alert window that is too long, an action group that emails a shared inbox, or a workspace nobody can query all add minutes. Those minutes are where checkout revenue leaks while the team is still finding the problem.
The Native Azure Monitoring Stack, Explained as One System
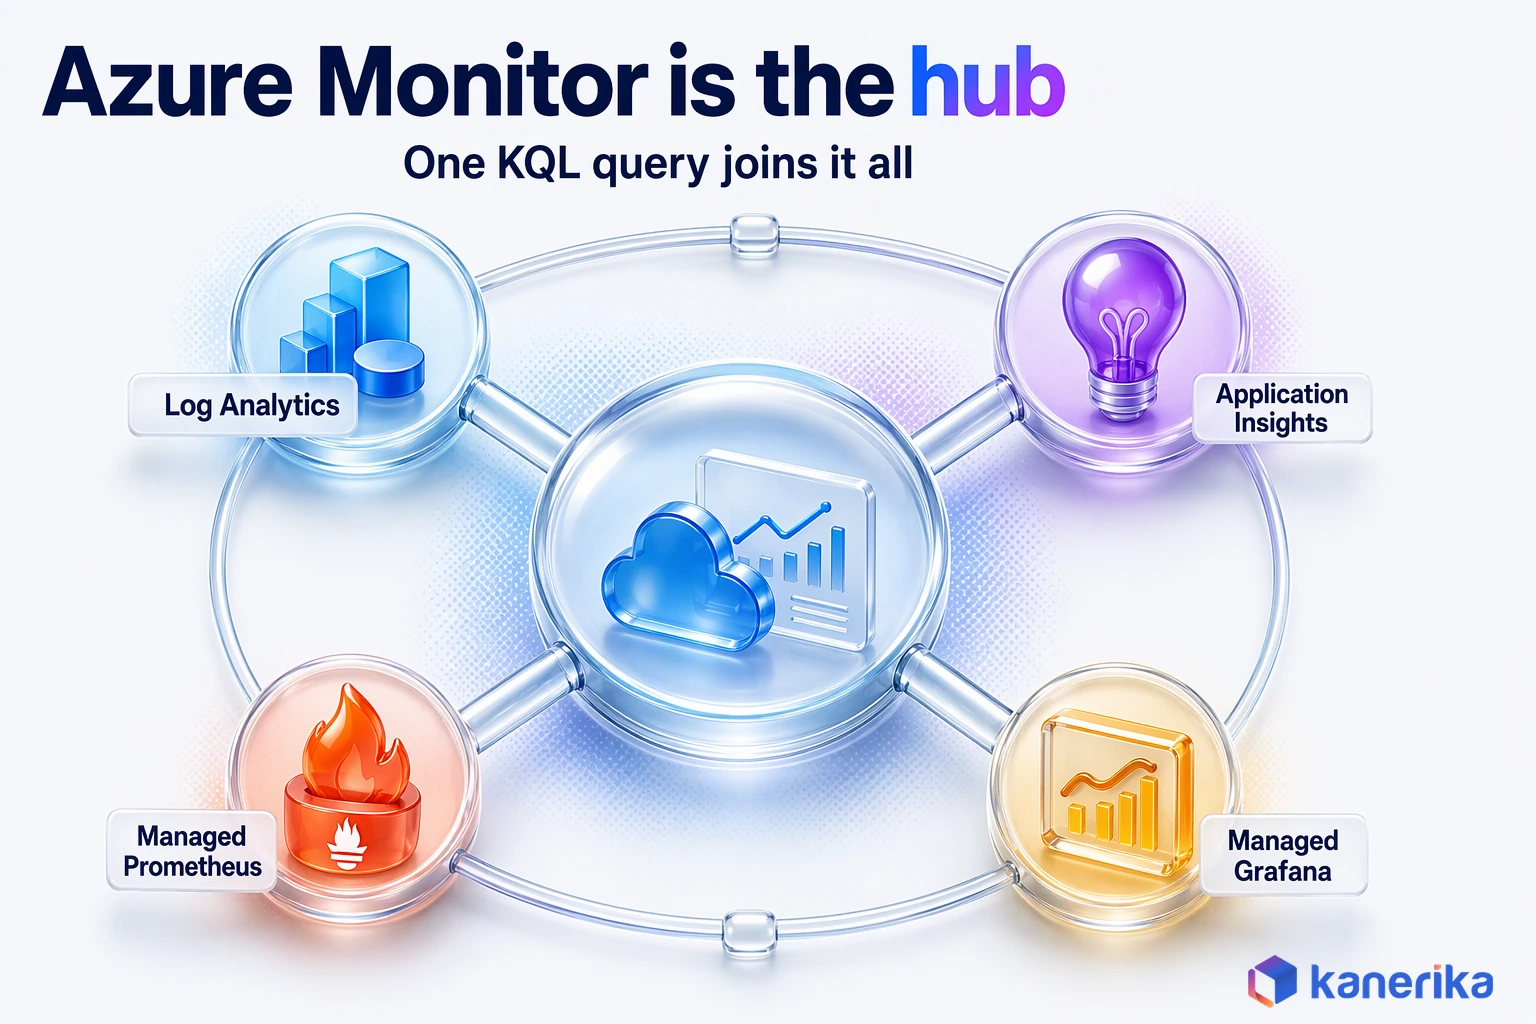
The native stack is easier to judge once you see it as one system with a hub, rather than seven separate products. Azure Monitor is the hub: it holds platform metrics, runs alert rules and sends notifications through action groups.
Everything else feeds that hub or reads from it. For example, Log Analytics is the log store, and Application Insights writes its application telemetry there. Azure Monitor managed service for Prometheus collects Kubernetes metrics without a Prometheus server for you to run. Azure Managed Grafana is a fully managed service, operated and supported by Microsoft, that draws dashboards across those stores.
| Component | What it watches | Where its data goes | Verified note |
|---|---|---|---|
| Azure Monitor (metrics, alerts) | Platform metrics, alert rules, action groups | Azure Monitor metrics store | The hub other components report into |
| Log Analytics | Logs and traces, queried with KQL | Log Analytics workspace | Analytics ingestion includes 31 days of retention |
| Application Insights | Requests, dependencies, exceptions, traces | Log Analytics workspace | New apps should use an OpenTelemetry distro |
| Managed Prometheus | Kubernetes and app metrics in Prometheus format | Azure Monitor workspace | Fully managed, no Prometheus server to run |
| Azure Managed Grafana | Dashboards across sources | Reads from the stores above | Operated and supported by Microsoft |
| Network Watcher | Connectivity, flows and network paths | Storage account or workspace | Network layer only |
| Service Health | Azure incidents and planned maintenance | Activity log (AzureActivity table) | AzureActivity ingestion is free |
One Query Language, One Risk of Sprawl
The main strength of this design is that one query language reaches most of the data. For instance, a responder can join an application failure to a node event and a recent deployment in a single KQL query. In the checkout example, that join is what points the responder at the payment call instead of the cluster.
The weak spot, however, is sprawl. Teams often create a workspace per project, then find that no single query sees the whole service. So plan workspaces by data residency and access needs first, and keep the count as low as those needs allow. Our guide to the Azure landing zone shows where those workspaces sit in the wider subscription design.
Where the Native Stack Runs Out
The native stack is strongest when everything you run lives in Azure. Problems only start at the edges of that boundary.
A multi-cloud estate is the clearest case, and our overview of cloud architecture models and patterns covers the designs behind it. Azure Arc can bring servers from other clouds and data centers under Azure Monitor. Even so, managed services on AWS or Google Cloud still need their own collection and views. As a result, teams switch consoles during an incident, which is exactly when they can least afford it.
Three softer limits matter too. To begin with, business-service views across many subscriptions take deliberate design work. KQL is also a skill your team has to build, and default alert settings tend to produce noise. None of these rules the native stack out. Each one simply adds effort that a third-party platform may already cover.
Alert noise deserves a closer look, because it quietly erodes trust in the whole stack. A team that receives forty CPU warnings a week learns to ignore them, and the one real warning gets ignored too. Native alert rules can be tuned well, but someone has to own that tuning. Without an owner, the noise usually wins. Teams drowning in duplicate alerts often look at the AIOps tools that group related alerts into one incident.
Metric, Log Search and Activity Log Alerts
Choosing the right alert type is the first step in cutting that noise, because each type watches a different signal. Microsoft’s Azure Monitor alerts overview, updated July 8, 2026, lists six types, and three of them do most of the work.
Metric alerts evaluate resource metrics at regular intervals and can use dynamic thresholds, which suits CPU, latency or failed-request counts. Log search alerts run a KQL query on a schedule. They fit conditions such as more than five payment timeouts in ten minutes. Activity log alerts fire when a matching control-plane event occurs, such as a deleted resource. Service Health and Resource Health alerts belong to this family.
State matters as much as type. Stateful alerts fire once and stay quiet until the condition clears, while every activity log alert is stateless and fires on each match. Each alert routes through an action group, which can send email or SMS, start an automation runbook or open an ITSM incident. For broader runbook options, see our review of cloud automation tools.
VM Monitoring and Azure Advisor
Virtual machines need their own view, because host metrics alone cannot see inside the guest. Microsoft’s VM monitoring guide, which the older VM insights page now points to, explains the split. Host metrics such as CPU, network traffic and disk I/O are collected automatically at no cost.
Guest data needs the guest monitoring option, which installs the Azure Monitor agent and creates a baseline set of recommended alert rules. Guest logs such as Windows Event Logs and Syslog then carry ingestion and storage charges, so collect only the event levels you will act on.
Azure Advisor works on a different question: is the estate set up well? According to the Advisor overview, it analyzes configuration and usage telemetry and groups recommendations into five categories: reliability, security, performance, cost and operational excellence. Treat Advisor as a weekly review list rather than an alert source, since it flags drift slowly and does not page anyone.
Third-Party Azure Monitoring Tools Compared
Third-party Azure monitoring tools earn their cost when they solve a problem the native stack makes hard. For example, they can give one view across clouds or map dependencies automatically. They do not earn it by repeating what Azure Monitor already does inside a single subscription.
All the platforms below ingest Azure data through a native Azure integration, and all support OpenTelemetry in some form. So the real differences are pricing model, lock-in and how well each handles your hardest service. Prices are vendor list prices, checked November 14, 2026.
| Tool | Best fit | Pricing model (list, checked Nov 2026) | Lock-in risk | Proof-of-value test |
|---|---|---|---|---|
| Datadog | Multi-cloud teams wanting one SaaS for infrastructure, APM and logs | Infrastructure Pro from $15 per host per month, billed annually | Medium to high | Trace one AKS service end to end and compare alert noise |
| Dynatrace | Large estates wanting automatic dependency mapping | Full-Stack $58 per month per 8 GiB host; Infrastructure $29 per host per month | Medium to high | Check whether it names the failing dependency without help |
| New Relic | Teams wanting usage-based pricing and a free start | Free tier with 100 GB ingest per month and unlimited free basic users | Medium | Send one service’s OpenTelemetry data and price a full month |
| Grafana stack | Teams with Prometheus skills who want open formats | Free tier with 50 GB logs a month; Pro from $19 a month plus $0.40 per GB of logs written | Low | Rebuild your top five dashboards on Managed Prometheus data |
| Elastic Observability | Teams already running Elasticsearch for search or logs | Serverless, from $0.07 per GB ingested (Logs Essentials) or $0.09 (Complete) | Medium | Load one week of logs and test query speed |
| Splunk | Enterprises consolidating security and operations logs | Quote-based, priced by ingest or workload | High | Price the ingest volume of one busy subscription |
How Datadog, Dynatrace and New Relic Differ
Datadog lists more than 1,000 built-in integrations, so a team running Azure beside other clouds can watch everything in one SaaS console. Dynatrace relies on Smartscape auto-discovery, which maps dependencies between services, processes and hosts without manual setup, a fit for large estates. New Relic bills on data ingested and users, with 100 GB a month free, which suits teams that want to trial before they commit. Back in the checkout example, however, an Azure-only estate gains little from any of the three. If the payment service also ran on another cloud, Datadog’s single console or Dynatrace’s automatic map would be the first to test.
Per-Host or Usage-Based Pricing
Pricing models shape the bill more than the headline number does. Per-host pricing is easy to forecast for a stable fleet, but it rises with node count when AKS autoscales. By contrast, usage-based pricing follows data volume, so the same sampling and filtering discipline that cuts Log Analytics costs applies there as well.
Lock-in is the cost that shows up later. Proprietary agents, dashboards and alert definitions all have to be rebuilt if you leave. Similarly, a tool that scores well on day one can still be the wrong choice. That happens when moving off it would take a quarter of engineering time.
So treat each row as a hypothesis to test on your own services. Run the proof-of-value test on your own busiest service, with your own data volumes, before you sign anything.
Kanerika Service
Azure Consulting Services & Managed Cloud Solutions
Kanerika helps you choose between native and third-party monitoring, design the stack and run it as part of managed Azure operations.
Explore Azure ServicesOpenTelemetry and Avoiding Lock-In
OpenTelemetry (OTel) is the open standard for producing traces, metrics and logs. It matters for tool choice because instrumentation is the expensive part to change, and OTel keeps that part vendor-neutral.
Microsoft has also moved Application Insights in the same direction. Its OpenTelemetry guidance recommends an OpenTelemetry-based distro for new applications, with a dedicated Azure Monitor distro for Java. The OpenTelemetry status page lists traces, metrics and logs as stable for several languages, including .NET and C++. Even so, check your own language before you commit.
The practical payoff shows up during evaluation. With the OpenTelemetry Collector in place, you can send the same data to Azure Monitor and to a candidate platform at once. That way you compare both on identical telemetry, and switching later means changing an exporter rather than re-instrumenting every service.
The Collector also gives you a control point for cost and privacy. You can drop noisy attributes, mask personal data and sample traces before anything leaves your network. Those same settings then travel with you to whichever backend you choose.
Specialty Layers: Network, Security and FinOps Monitoring
Some monitoring questions sit outside application health, and each has its own specialist tool. Knowing where those boundaries fall stops teams from stretching one product to cover a job it was not built for.
Network problems often look like application problems at first. A timeout in Application Insights may really be a blocked route or an overloaded gateway, and only network evidence settles that question. Security, on the other hand, has a different audience, since threat detection belongs to the security operations team rather than the on-call engineer.
- Network: Network Watcher checks connectivity between resources, records traffic flows and shows the path a packet takes, which helps prove or rule out the network quickly.
- Security: Microsoft Sentinel is a cloud-native SIEM, available in the Defender portal and the Azure portal. Microsoft will retire the Azure portal experience after March 31, 2027, so new deployments should plan for the Defender portal. It handles threat detection and investigation, not application performance.
- Spend: Azure Cost Management tracks what you pay across the subscription, including what monitoring itself costs.
Above all, keep the Sentinel boundary clear in your design. Sentinel reads security data from a Log Analytics workspace. Even so, its rules, analysts and retention needs differ from operations monitoring. Mixing the two in one undifferentiated workspace tends to blur access rights and inflate costs.
Talk to Kanerika
Planning Your Azure Monitoring Stack?
Bring one critical service and its last incident. Kanerika will help you map signals, owners and alerts across operations and security.
Schedule a Demo →Defender for Cloud or Microsoft Sentinel?
Buyers often confuse these two products, yet they answer different security questions. Microsoft Defender for Cloud is a cloud-native application protection platform. It checks how your resources are configured (posture management) and defends workloads such as VMs, containers, storage and databases. Its foundational posture features, including the secure score, are free.
Sentinel sits one step later in the chain. It collects signals from many sources, Defender for Cloud included, and correlates them into incidents for analysts to investigate. A practical rule follows: switch on Defender for Cloud first to fix misconfigurations, then add Sentinel when a security team needs to hunt across sources. Our Azure security best practices guide covers the controls around both.
Network Evidence in the Checkout Example
Go back to the checkout example for a moment. Suppose, for instance, that the payment calls had failed because a firewall rule changed, not because the provider was slow. In both cases, Application Insights would show the same timeouts. A Network Watcher connectivity check from the AKS subnet to the provider’s endpoint would separate the two causes in minutes. For that reason, the check belongs in the runbook.
Watching What Monitoring Costs
FinOps monitoring closes the loop. Telemetry is only one line on the Azure bill. For the rest, our guide to Azure cost optimization covers compute, storage and licensing savings.
Inside the monitoring bill itself, set a budget alert in Azure Cost Management on the resource group that holds your workspaces. A sudden jump in log volume then reaches a person within days, instead of surfacing at month-end review.
Monitoring AI and Data Workloads on Azure
AI and data workloads fail in ways that classic infrastructure metrics miss. A model endpoint can return HTTP 200 with a poor answer, and a pipeline can succeed while loading yesterday’s data.
Take a support chatbot built on Azure OpenAI models through Azure AI Foundry. The signals that matter are latency per request, tokens per call, throttling responses and error rate per model deployment. Each one ties directly to user experience or cost, and Application Insights can capture them through OpenTelemetry instrumentation.
Quality is the harder signal. For this reason, teams that need prompt-level tracing, evaluation scores and drift checks usually add a dedicated tool, and our review of LLMOps observability tools compares those options. Keep prompts out of general logs unless they are masked, because they often carry customer data.
Token telemetry also doubles as a cost signal. A prompt change that adds a long system message can raise tokens per call overnight, and the invoice shows it weeks later. An alert on average tokens per call, by contrast, catches that drift on the same day. Once the alert fires, our guide to LLM inference optimization covers ways to bring latency and token cost back down.
Pipelines: Success Is Not the Same as Freshness
Data pipelines need two extra checks: did the run succeed, and is the data fresh? A daily load that silently stops is worse than one that fails loudly. Alert on freshness as well as failures.
Here is a simple example. Say a sales dashboard refreshes from a lakehouse table loaded every night at 2 a.m. If the load succeeds but writes zero rows, every run metric still stays green. A freshness alert that checks the newest record’s timestamp at 6 a.m. catches the problem before the sales team opens its morning report.
Kanerika Service
Data Engineering Services
Kanerika builds and runs data pipelines on Azure with run-failure and freshness checks designed in from the first release.
Explore Data EngineeringFor quality checks beyond what Azure Monitor provides, see our list of data observability tools. The broader habits behind reliable pipelines are covered in our data engineering best practices guide.
What Azure Monitoring Really Costs: A Worked Example
Most of an Azure monitoring bill comes from one meter: the gigabytes of logs you send to Log Analytics. The plan each table uses sets the price per gigabyte, so plan choice matters more than any other setting.
Azure has three table plans. Analytics Logs cost $2.30 per GB in East US and include 31 days of analytics retention at no extra cost. Basic Logs cost $0.50 per GB, and Auxiliary Logs cost $0.05 per GB, according to the Azure Monitor pricing page. Both cheaper plans charge per GB scanned when you query them. Basic tables can also be queried interactively for only 30 days, so both plans suit logs you rarely search.
Three more rules also shape the bill. Commitment tiers start at 100 GB per day, and the billed size of data averages about 25% less than its incoming size. In addition, some tables, such as AzureActivity, Heartbeat and Usage, carry no ingestion charge at all.
The Worked Example: 80 GB of Logs a Day
The table prices one estate that sends 80 GB of billed logs a day, then adds a 100 GB case to show the commitment tier.
| Scenario (billed GB per day) | Daily cost | 30-day cost | Change |
|---|---|---|---|
| 80 GB, all Analytics | 80 x $2.30 = $184 | $5,520 | Baseline |
| 40 GB Analytics + 40 GB Basic | $92 + $20 = $112 | $3,360 | About 39% lower |
| 40 GB Analytics + 40 GB Auxiliary | $92 + $2 = $94 | $2,820 | About 49% lower, for rarely queried logs only |
| 100 GB, pay-as-you-go Analytics | 100 x $2.30 = $230 | $6,900 | Reference |
| 100 GB, commitment tier | $196 | $5,880 | About 15% lower than pay-as-you-go |
The assumptions are simple and stated. Every figure is an East US list price checked November 14, 2026, before discounts and taxes. Volumes are billed gigabytes, and the totals leave out query charges on Basic and Auxiliary data and retention beyond 31 days.
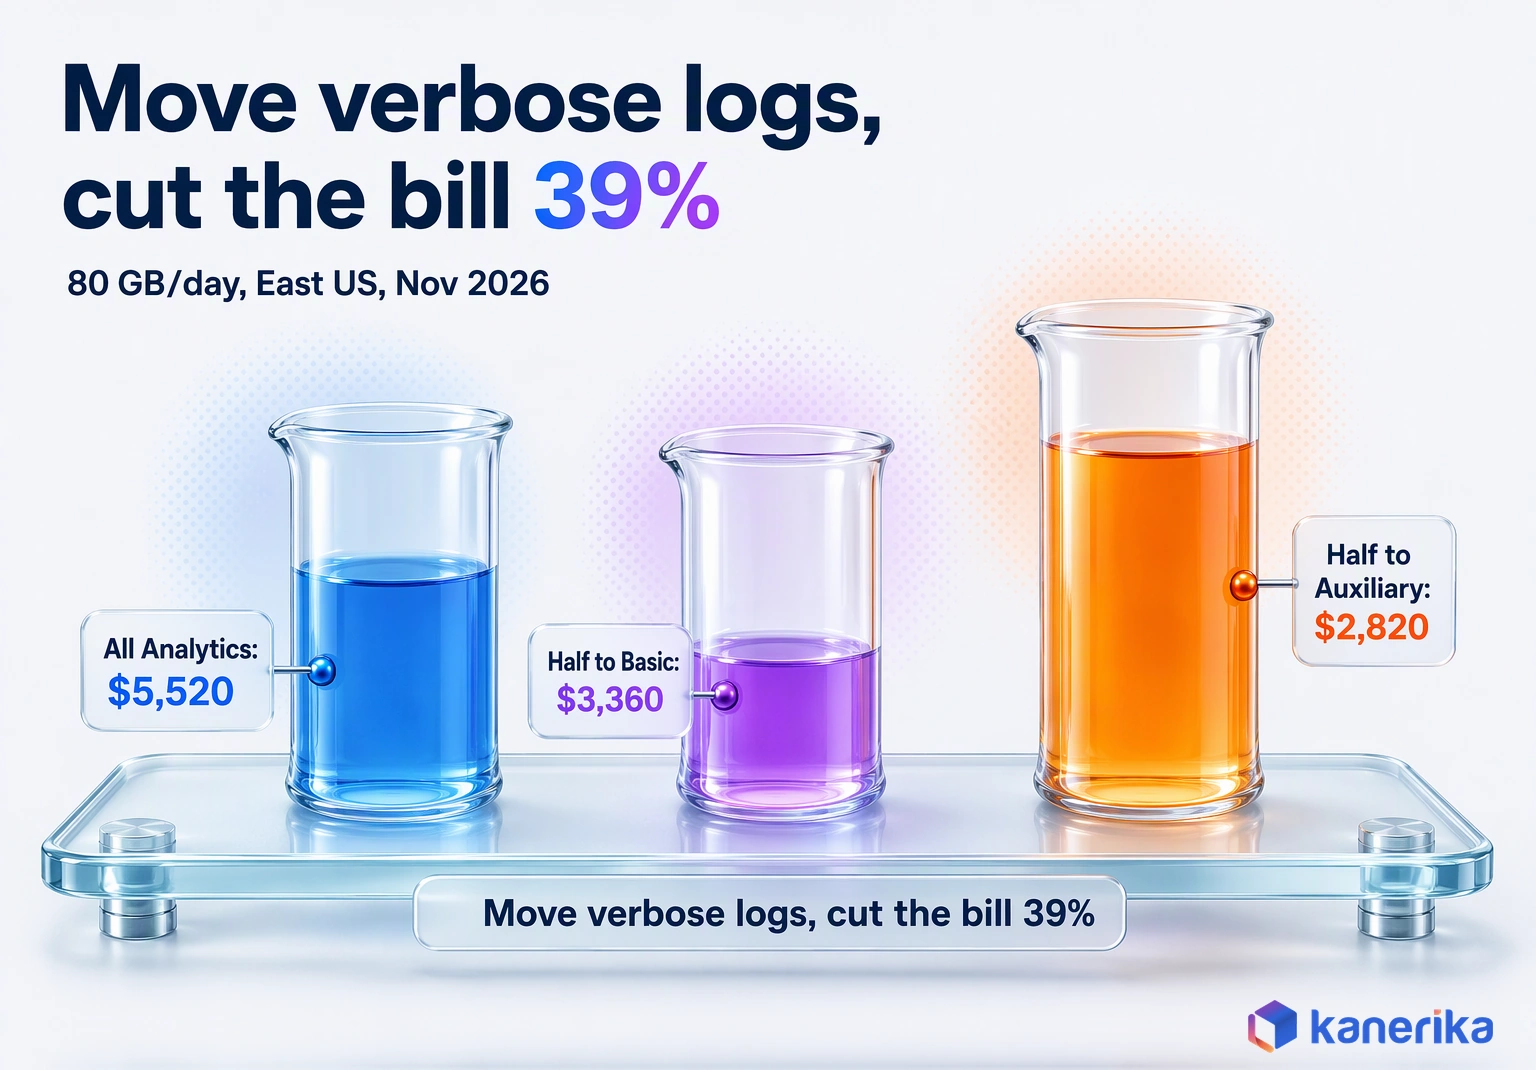
The lesson from the table, then, is that verbose container logs are the cheapest win. They are large, rarely searched and often kept only for audits, which makes them natural candidates for Basic. Retention then adds a second meter, at $0.10 per GB per month for Analytics data kept past the included period.
Five Levers That Cut Log Analytics Spend
Once you know which tables are large, five settings bring the bill under control. Apply them in this order, because the early ones remove data before you ever pay for it.
- Table plans. Move high-volume, rarely queried tables to Basic or Auxiliary, as the worked example shows.
- Data collection rules. Use transformations to drop noisy rows and unused columns before ingestion.
- Sampling. Sample high-volume, successful requests in Application Insights while keeping every failure.
- Retention. Analytics retention extends to two years, and total retention reaches 12 years, so keep interactive retention short and archive the rest.
- Daily cap. A daily cap stops billable collection for the rest of the 24-hour period, and the reset hour is fixed, so treat it as a safety net.
The order is deliberate, too. Table plans and transformations shrink what you pay for, while sampling and retention trim what remains. The cap comes last because it is blunt: once it trips, new data stops until the next reset, whatever that data contains.
Start with evidence. For example, this query reads the free Usage table and ranks your billable tables by volume over the last 30 days:
Usage
| where TimeGenerated > ago(30d)
| where IsBillable == true
| summarize BillableGB = sum(Quantity) / 1000 by DataType
| sort by BillableGB desc
The top three rows usually explain most of the bill. Fix those tables first, then review the ranking each month, since new services add new tables. A cap set without this review tends to cut off the very logs you need during an incident.
Decision Framework: Which Azure Monitoring Approach Fits Your Estate
The right monitoring approach depends less on features and more on the shape of your estate. Where workloads run, how many clouds you use and what regulators expect decide most of the answer.
The table below states a pick for each common estate. In short, it assumes a team that wants one primary tool, with specialist tools only where a layer truly needs them. If your estate spans two rows, start from the stricter one.
Read each pick as the core of the stack, not the whole of it. In practice, every row still uses Azure Service Health for platform incidents and Azure Cost Management for spend, whichever monitoring tool sits at the center.
| Estate | Pick | Why | Watch-out |
|---|---|---|---|
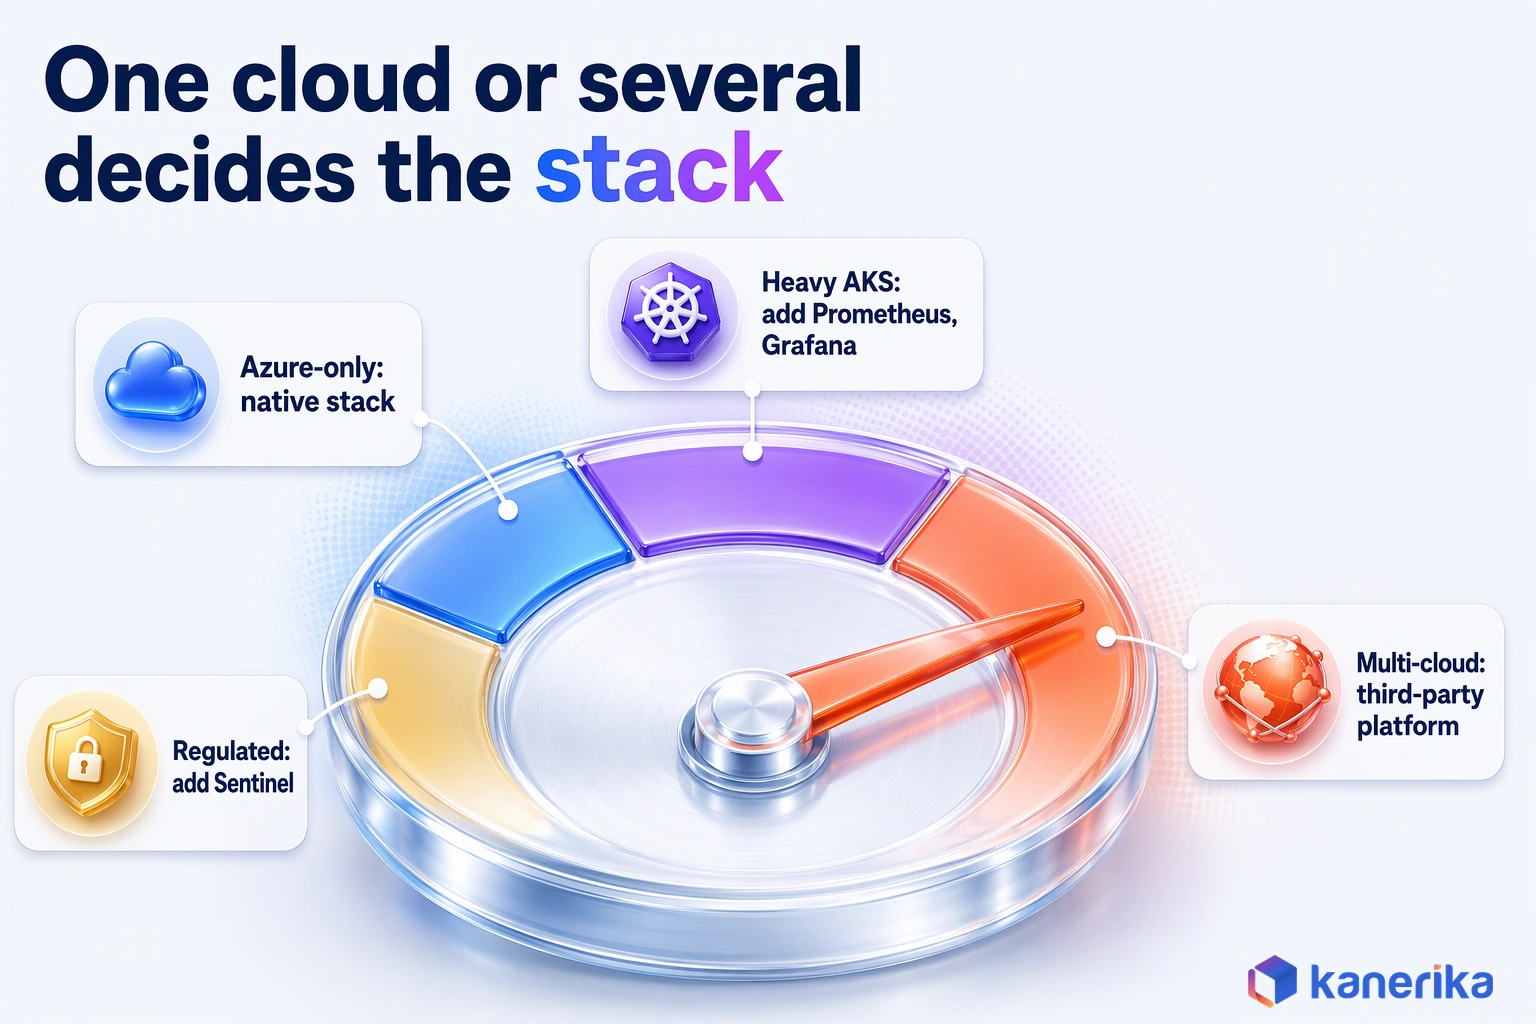
| Azure-only, mostly PaaS | Native stack: Azure Monitor, Log Analytics, Application Insights | One bill, no extra agents, one query language | Set table plans early or log costs climb |
| Azure plus heavy AKS | Native stack plus Managed Prometheus and Azure Managed Grafana | Prometheus metrics without running Prometheus servers | Watch label counts on custom metrics |
| Hybrid with on-premises | Native stack, with Azure Arc for on-premises servers | One workspace for cloud and data center servers | Network paths to the data center need their own checks |
| Multi-cloud | Third-party platform (Datadog, Dynatrace or New Relic) fed by OpenTelemetry | One service view across every cloud | Per-host bills rise as clusters autoscale |
| Regulated | Native stack plus Microsoft Sentinel, with retention set by policy | Data stays in your chosen Azure region, retention up to 12 years | Keep personal data out of logs |
When the Multi-Cloud and Hybrid Rows Apply
The multi-cloud row is the one that most often flips the decision. Suppose a growing share of your services runs on AWS or Google Cloud. In that case, our comparison of AWS vs Azure vs Google Cloud helps you judge where that estate is heading. Teams planning to stay mostly on Azure should keep the native stack as the core.
The hybrid row needs one more note. Azure Arc lets on-premises servers send data to the same Log Analytics workspace as cloud resources, so one query can span both. The link back to the data center is still its own failure point. So give it dedicated connectivity checks and an owner on the network team. If servers are still moving into Azure, our review of Azure migration tools helps you plan monitoring alongside each wave.
Even then, a third-party platform still has to beat the native stack on your own services, not on a feature list. That is where a scored evaluation and a short trial come in.
Score Vendors on Evidence, Then Run a Proof of Value
A weighted scorecard keeps the choice honest, because it forces the team to agree on what matters before the demos start. Treat the weights below as a starting point and adjust them to your estate.
| Criterion | Weight | What to test |
|---|---|---|
| Diagnostic coverage | 25 | Can it trace a failed request across every service and dependency? |
| Incident workflow | 20 | How fast does an on-call engineer reach the cause? |
| Total cost | 20 | License plus ingestion at your real volume for 12 months |
| Governance | 15 | Access control, retention settings and data residency |
| Portability | 10 | OpenTelemetry support and ease of export |
| Effort | 10 | Setup and upkeep hours for your team |
Next, run a 30-day proof of value on one critical service, such as checkout or claims intake. Send the same OpenTelemetry data to each candidate and replay at least one real past incident. Finally, score each tool against the table and let the measured results make the decision.
Governance, Best Practices and Common Mistakes
Monitoring only stays useful if someone governs it, because coverage decays as teams add resources faster than they add diagnostics. Governance here means three things: every resource sends data, the right people see it, and someone owns every alert.
Of the three, coverage is the easiest part to automate. Azure Policy and initiatives can enable diagnostic settings at scale, and built-in policies exist for many resource types. Assign them at the management group level, so that new resources start sending logs on the day they are created. Monitoring policy then becomes one part of a wider cloud governance framework rather than a separate project.
Access and retention come next, and both need deliberate settings. Use role-based access control on each workspace so that teams see their own resources. Our Azure identity management guide explains that RBAC model. Then set retention to match your compliance rules rather than the default. Because logs often carry personal data, mask it at collection with a transformation instead of hoping nobody queries it.
Checklist
Microsoft Azure Checklist
A practical checklist for planning and governing Azure workloads, from setup and access to ongoing operations.
Get the Checklist →Ownership, however, is the part tools cannot do for you. Each table, dashboard and alert needs a named owner who decides what to keep, and the same principles behind data stewardship apply to telemetry. When operations reports move into Power BI, row-level security in Power BI limits who sees which systems.
Common Mistakes to Avoid
The same mistakes repeat across most estates:
- Turning on every diagnostic category at full detail, then paying for logs nobody reads.
- Creating a new workspace for every project, so no query sees a whole service.
- Alerting on single metrics instead of customer-facing symptoms such as failed checkouts.
- Leaving alerts without an owner, so they get muted instead of fixed.
- Adding monitoring after an AI agent or pipeline ships, rather than designing it into AI agent lifecycle management from the start.
Each of these is cheap to prevent and expensive to unwind. For that reason, a quarterly review of alerts, owners and top tables catches most of them before they reach the bill or the customer.
How Kanerika Delivers Azure Monitoring in Stages
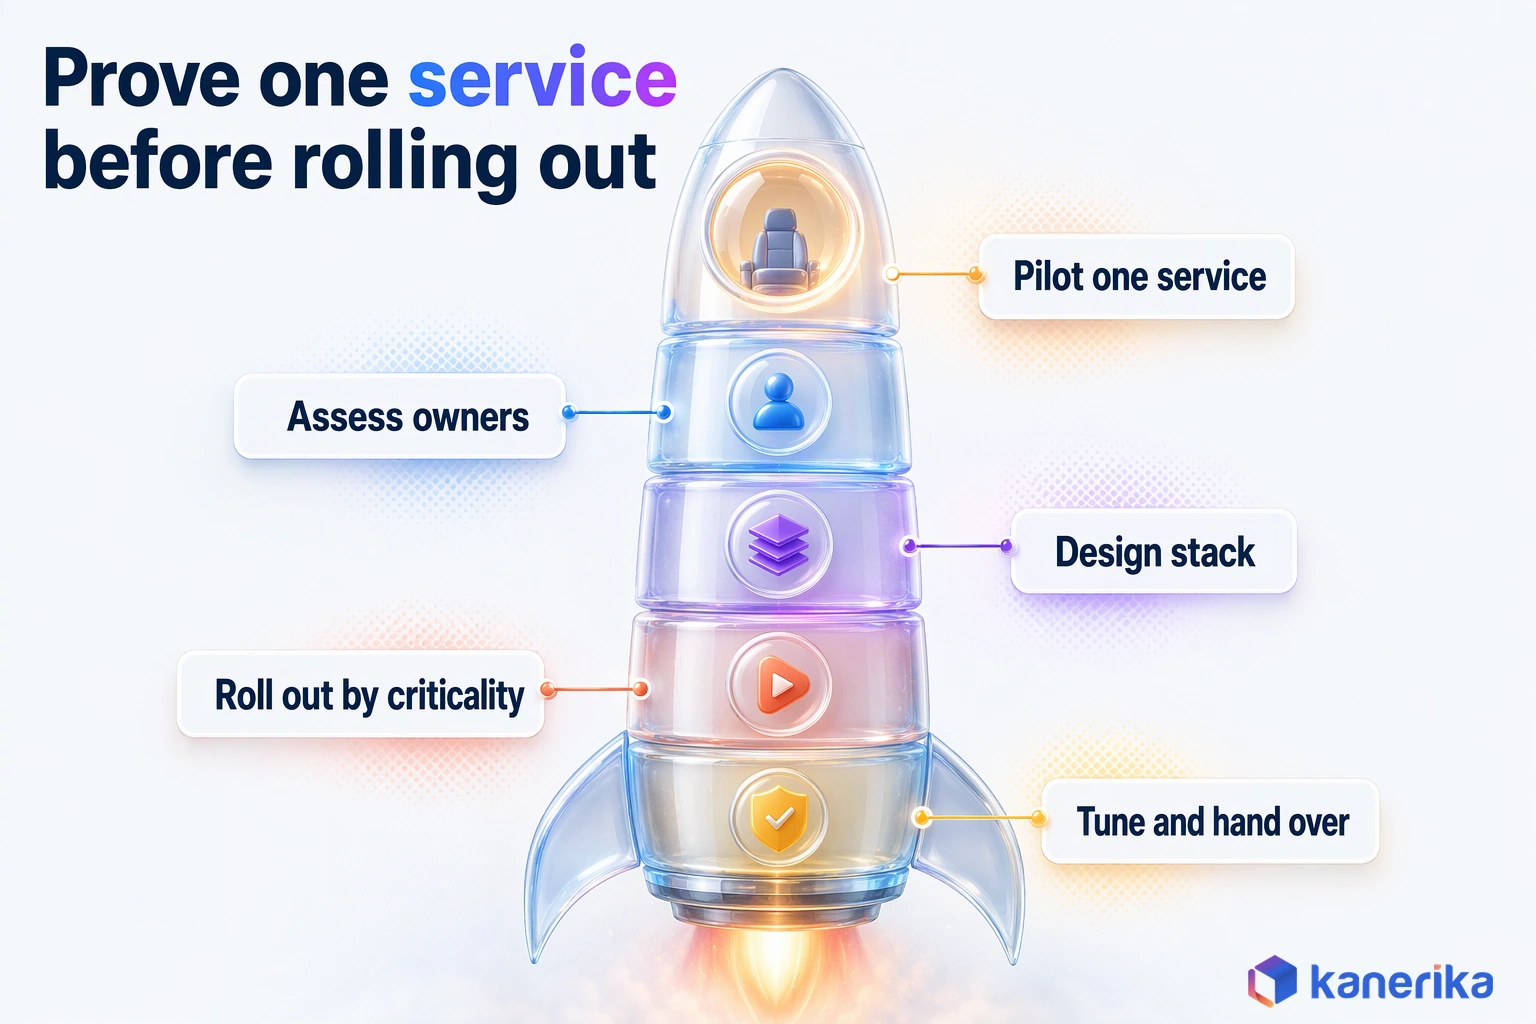
Kanerika rolls out Azure monitoring in stages, so each step proves its value before the next one starts. The order matters, because tools chosen before the inventory exists tend to watch the wrong things.
- Assess services and owners. List the business services, the Azure resources behind them and the person accountable for each.
- Design the stack and collection rules. Choose native or third-party per estate, set table plans and define data collection rules.
- Pilot one critical service. Instrument it with OpenTelemetry, build symptom-based alerts and test them against a past incident.
- Roll out by criticality. Extend coverage service by service, enforcing diagnostic settings through Azure Policy.
- Tune and hand over. Review alert noise and log volume monthly, then hand runbooks and ownership to your team.
Stage one often surprises clients most. For example, many teams discover servers and applications that nobody can name an owner for, and those blind spots are exactly where incidents start.
A Logistics Client That Built the Groundwork First
That groundwork is what Kanerika delivered for a leading global logistics provider. The client struggled with poor visibility across regionally spread servers and unclear ownership of hosted applications, and a malware incident had taken servers offline. Kanerika built an asset catalog with Power BI and Power Query, assigned clear ownership, removed redundant applications and decommissioned outdated servers.
To be clear, that project was not an Azure Monitor deployment. It is the stage-one work that any monitoring stack depends on, done at the scale of a global estate.
The IT infrastructure optimization case study reports a 90% decrease in security vulnerability, an 85% increase in accountability and 100% readiness for ITSM. Monitoring builds on that kind of inventory, since a stack can only alert the right owner when owners are known.
Kanerika’s Recommendation: Give Every Alert an ITSM Route
The case page credits one result in particular to that work. In its words, “an organized data catalog made it easy to connect with new ITSM tools.” That finding shapes Kanerika’s main recommendation for monitoring work. Build the owner list in a form your ITSM tool can read before you write the first alert rule. Each action group can then open an incident in the owning team’s queue, instead of emailing a shared inbox that nobody watches.
At the end of the stage-three pilot, Kanerika hands over the instrumented service, its symptom-based alerts, a cost baseline and the result of the replayed incident. Our advice is that every alert in that handover should carry a named owner and an ITSM route.
The handover is where many monitoring projects slip. Kanerika closes each stage with written runbooks, an owner list for every alert and a monthly review of the top billable tables. Your team then runs the stack with the same habits that built it.
For teams that want ongoing operations support rather than a one-time project, our guide to Azure managed services explains how to choose a partner. Kanerika’s Azure consulting and managed cloud services cover the design, rollout and tuning stages above.
Choosing Azure Monitoring Tools: The Bottom Line
Start from the shape of your estate. An Azure-only estate should run the native stack, and AKS-heavy teams should add Managed Prometheus with Managed Grafana. Regulated estates add Microsoft Sentinel for security, while multi-cloud estates are better served by a third-party platform fed by OpenTelemetry.
Whichever way you lean, also set table plans before the first bill and prove the choice on one critical service for 30 days. The best Azure monitoring tools for your team are the ones that catch the failing checkout before your customers do.
Talk to Kanerika
Start With One Critical Service
Kanerika will help you inventory services and owners, pilot monitoring on one service and prove the alerts against a real past incident.
Schedule a Demo →Frequently Asked Questions
What are Azure monitoring tools?
Azure monitoring tools collect metrics, logs, traces and events from Azure resources and applications, then turn them into alerts and dashboards. The native set includes Azure Monitor, Log Analytics, Application Insights, Managed Prometheus, Azure Managed Grafana and Network Watcher. Third-party platforms such as Datadog, Dynatrace and New Relic also ingest Azure data through native integrations.
Is Azure Monitor enough on its own?
For an estate that runs only on Azure, Azure Monitor with Log Analytics and Application Insights usually covers platform and application monitoring well. It becomes harder when you run several clouds, need one business-service view across many subscriptions or lack KQL skills. In those cases a third-party platform fed by OpenTelemetry may save effort.
What is the difference between Azure Monitor and Application Insights?
Azure Monitor is the overall platform that holds metrics, runs alerts and connects every monitoring component. Application Insights is the part of Azure Monitor focused on applications, recording requests, dependencies, exceptions and traces. Its data lands in a Log Analytics workspace, so application failures can be joined with platform metrics and logs in one query.
Does Azure Monitor support OpenTelemetry?
Yes. Microsoft recommends an OpenTelemetry-based distro for new applications that send data to Application Insights, and Java has its own Azure Monitor OpenTelemetry distro. OpenTelemetry keeps instrumentation vendor-neutral, so the same traces, metrics and logs can also go to another backend through the OpenTelemetry Collector during a tool evaluation or a later move.
How do I reduce Log Analytics costs?
Find your largest billable tables with a query on the free Usage table first. Then move rarely queried tables to Basic or Auxiliary plans, drop noisy rows and columns with data collection rule transformations and sample successful requests. Keep interactive retention short, and use a daily cap only as a safety net, since it stops collection.
What is the difference between Azure Monitor and Microsoft Sentinel?
Azure Monitor watches the health and performance of resources and applications, and it alerts operations teams when something breaks. Microsoft Sentinel is a cloud-native SIEM for security teams, focused on threat detection, investigation and response. Sentinel reads security data from a Log Analytics workspace, but its rules, users and retention needs differ from operations monitoring.
How much does Azure monitoring cost?
Log ingestion drives most of the cost. In East US, Analytics Logs list at $2.30 per GB, Basic Logs at $0.50 and Auxiliary Logs at $0.05, checked November 2026. Sending 80 GB a day to Analytics costs about $5,520 per 30 days, and moving half to Basic lowers that to about $3,360.
Which Azure monitoring tool is best for AKS?
For most AKS clusters, Microsoft’s managed option is Azure Monitor managed service for Prometheus with Azure Managed Grafana for dashboards, plus Container insights for logs. Prometheus metrics then flow without any Prometheus servers to run. Add Application Insights with OpenTelemetry to trace requests between services, since cluster metrics alone miss failing dependencies.
How do I monitor AI workloads on Azure?
Track latency per request, tokens per call, throttling responses and error rate for each model deployment, using OpenTelemetry instrumentation that sends data to Application Insights. Add data freshness and run-failure alerts for the pipelines feeding the model. For prompt tracing and answer quality, pair Azure Monitor with a dedicated LLM observability tool and mask personal data.
What is the difference between Azure Monitor and Datadog?
Azure Monitor is Microsoft’s native service, billed mainly on log ingestion and built around one query language for Azure data. Datadog is a third-party SaaS platform priced per host and product, with Infrastructure Pro listed from $15 per host per month billed annually. Datadog suits multi-cloud teams, while Azure Monitor suits Azure-only estates.
How does Kanerika help with Azure monitoring?
Kanerika works in five stages. The team first maps business services, resources and owners, then designs the stack, table plans and collection rules. Next it pilots one critical service with OpenTelemetry and symptom-based alerts, rolls out coverage by criticality using Azure Policy and finally tunes alert noise and log volume before handing over runbooks.
What is similar to AWS CloudWatch in Azure?
Azure Monitor is the closest equivalent to AWS CloudWatch. Both collect platform metrics and logs, run alert rules and send notifications. In Azure, logs live in a Log Analytics workspace queried with KQL, and Application Insights adds application tracing. Teams moving between the two clouds should compare query languages, retention settings and pricing models.
Is Azure Monitor free?
Parts of it carry no ingestion charge, such as the AzureActivity, Heartbeat and Usage tables. Most log data is billed per gigabyte ingested, starting at $0.05 per GB for Auxiliary Logs in East US. The legacy Free Trial tier offered 500 MB a day with seven-day retention, and new workspaces have been limited since July 2022.