TL;DR
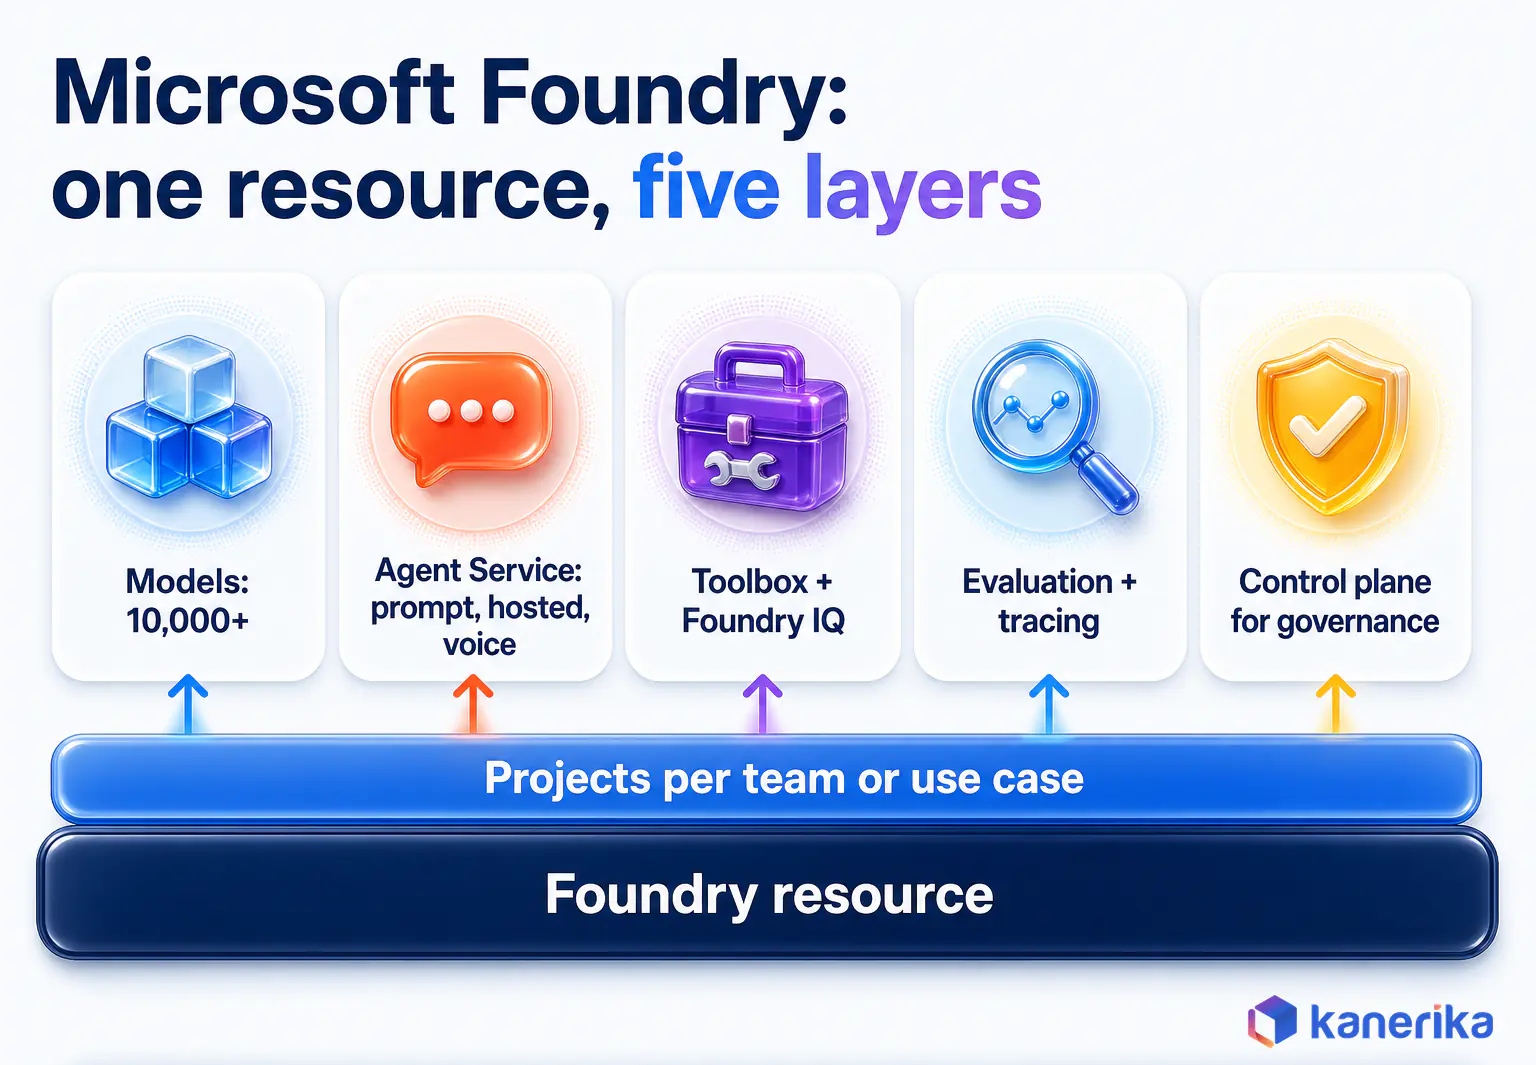
Azure AI Foundry, now called Microsoft Foundry, is the Azure platform for building and governing AI apps and agents from one resource with projects. It holds a catalog of more than 10,000 models, Foundry Agent Service, toolboxes and Foundry IQ for knowledge, built-in evaluation and tracing, and a control plane for governance. The platform itself is free, so the bill is the sum of the model, search, compute and monitoring meters you use. Start with a prompt agent on a Global Standard deployment, and move to hosted agents, Data Zone or provisioned capacity only when a measured need appears. Self-host open models with vLLM or Ollama only when your own team must run the GPUs or hold the data boundary. Every name, price and API below was checked against Microsoft Learn and the Microsoft Foundry Blog on November 3, 2026.
Key Takeaways
- Azure AI Foundry is now Microsoft Foundry, a single Azure resource with projects and one set of RBAC, networking and policy controls.
- The catalog lists more than 10,000 models, such as GPT-6.1 Sol, DeepSeek-V4-Pro, Grok 4.7, Mistral Large 3 (preview) and Microsoft’s own Phi and MAI models.
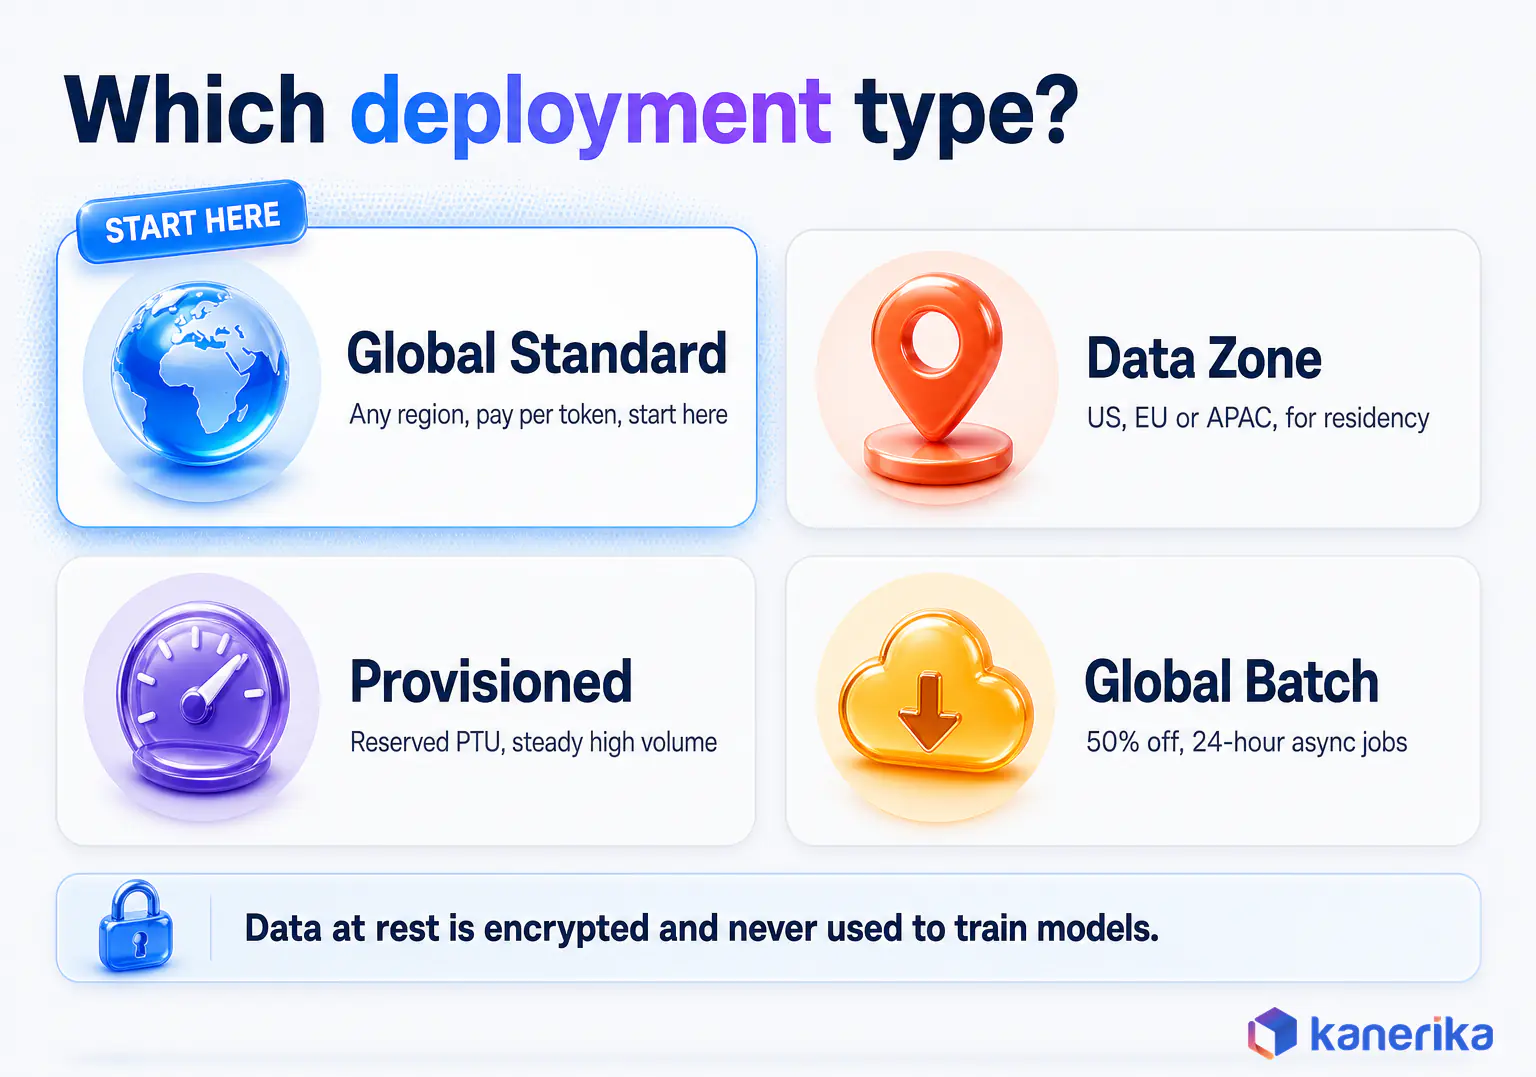
- Global Standard is the default deployment type, while Data Zone, Provisioned and Batch exist for residency, reserved throughput and async jobs at a 50% discount.
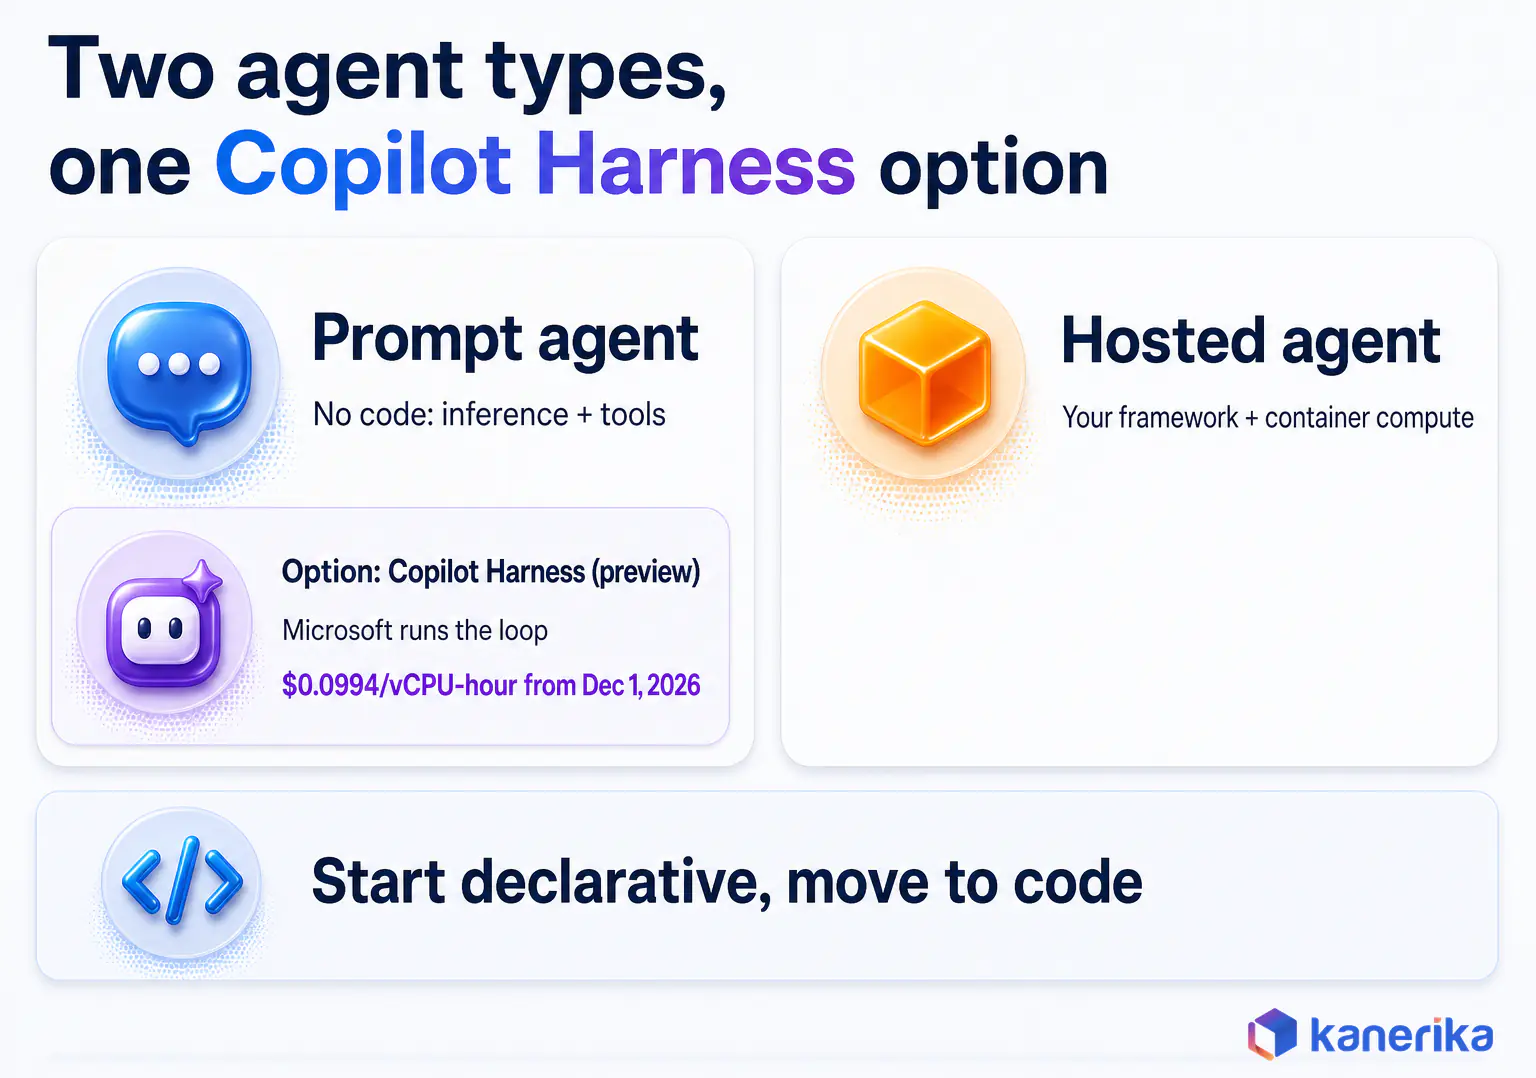
- Prompt agents need no runtime code and hosted agents run your own framework; a prompt agent can also run on the Copilot Harness (preview).
- The Foundry platform carries no fee of its own, so cost comes from model tokens, search, container compute, evaluation runs and monitoring.
- Self-host with vLLM or Ollama only when your team must own the GPUs or the data boundary, and use serverless or managed compute otherwise.
Three Governed Agents by Next Quarter
Picture a team that already runs a working chatbot on Azure OpenAI. It answers HR policy questions well, so leadership likes it. Then the brief changes to three governed agents by next quarter, one each for HR, finance and IT support.
Each new agent needs its own tools, its own slice of company data, as well as an audit trail. But none of that exists in the chatbot today. So the team has to decide what Microsoft Foundry adds on top of a model endpoint, and what it will cost to run.
The rest of this guide follows that team’s decisions in order. First comes the product’s current name and the model choice. Then come where it runs, how agents are built and what the bill will look like.
What Is Azure AI Foundry (Now Microsoft Foundry)?
Azure AI Foundry is Microsoft’s platform for building, deploying and governing AI apps and agents on Azure, though Microsoft now calls it Microsoft Foundry. Microsoft Learn says it “unifies agents, models, and tools under a single management grouping.”
RBAC, networking and policies are shared across that grouping under one Azure resource provider. Azure OpenAI is just one model provider inside Foundry, next to Anthropic, Meta, DeepSeek, Mistral and Microsoft itself. So a team calling GPT-6.1 Sol and a team calling DeepSeek-V4-Pro use the same platform and evaluation tools.
In a generative AI tech stack, Foundry covers the model and orchestration layers. Teams that want help planning that layer can also look at Microsoft Foundry consulting from Kanerika.
Old Names and APIs Mapped to New
Microsoft has renamed the product and its APIs more than once, so older tutorials use terms that no longer match the portal. Microsoft gives no rename date, so distrust any article that quotes one.
| Old name or API | Current name |
|---|---|
| Azure AI Studio, Azure AI Foundry | Microsoft Foundry |
| Azure AI Services | Foundry Tools |
| Assistants API (Agents v0.5 and v1) | Responses API (Agents v2) |
| Foundry (classic) portal | Foundry portal |
| Monthly api-version parameters | v1 stable routes (/openai/v1/) |
| Hub plus Azure OpenAI plus Azure AI Services resources | One Foundry resource with projects |
| azure-ai-inference, azure-ai-generative, azure-ai-ml and AzureOpenAI() on 5+ endpoints | azure-ai-projects 2.x plus OpenAI() on one project endpoint |
| Threads, Messages, Runs, Assistants | Conversations, Items, Responses, Agent Versions |
What Foundry Adds Beyond a Model Endpoint
A bare model endpoint takes a prompt and then returns text. Foundry, by contrast, wraps that call with the parts an enterprise agent needs:
- Agents in prompt, hosted and voice forms, as well as versioning and publishing.
- Tools such as web search, code interpreter, OpenAPI and MCP connections.
- Knowledge through Foundry IQ and Azure AI Search, so answers draw on company data.
- Evaluation with quality and safety evaluators, together with red teaming and tracing.
- Governance through an Entra identity per agent, RBAC, private networking and a control plane.
Microsoft’s own advice still keeps this in proportion. When an app only sends prompts and needs no tools, start with a single model call. Then add the agent layer once a real need appears.
Kanerika Service
Microsoft Foundry Consulting
Kanerika plans Foundry resources, projects, networking and identity, then builds and evaluates your agents.
Explore Microsoft Foundry ServicesMicrosoft Foundry Architecture: Foundry Resource, Projects and Connected Services
Foundry has a two-level structure, and getting it right early saves rework later. The top level is the Foundry resource, while the level below it is the project.
The resource is the governance boundary. Networking, identity and policy are set there, and every project under it then inherits them. Projects, in contrast, are the isolation unit, usually one per team or use case. So an HR agent and a finance agent can share a network setup without sharing files or permissions.
Connected services then attach the rest of Azure. For example, a project links to storage, Azure AI Search and Key Vault for secrets. Teams can also bring their own storage account when data must stay in a specific place, as the Foundry architecture page describes.
Two migration details also matter for existing teams. Azure OpenAI resources can be upgraded in place into Foundry while keeping the same endpoint and API keys. Hub-based projects still work, but they stay in the Foundry (classic) portal.
A practical rule is to decide the resource layout, network model and access model before anyone builds an agent. Changing a network boundary after five projects depend on it is slow, because it usually means redeploying. Teams on a wider estate often plan this alongside their Azure cloud solutions work, starting with four questions:
- How many Foundry resources do you need, for example one per region or business unit?
- Which teams or use cases, such as HR or finance, get their own project?
- Will traffic use public endpoints rather than private networking?
- Which Entra groups get owner, contributor and reader roles on each project?
Written answers become the baseline every later project inherits.
Foundry Models: What Is in the Catalog Today and How to Choose
The Foundry catalog holds more than 10,000 models from Microsoft, OpenAI, Anthropic, Meta and others. Most teams start with Foundry Models sold by Azure, since Microsoft bills and supports that subset directly.
A list that long is easier to read when grouped by model family. The table shows example model IDs from the Foundry Models sold by Azure page. The Anthropic row comes from the models from partners and community page.
| Model family | Example models in Foundry |
|---|---|
| OpenAI | gpt-6.1-sol, gpt-6.1-terra, gpt-6-astra, gpt-6-luna, GPT-5.6, GPT-5.5, GPT-4.1, gpt-oss |
| DeepSeek | DeepSeek-V4-Pro, DeepSeek-V4-Flash (1M-token input) |
| Grok | Grok 4.7, Grok 4.6, Grok 4.3 |
| Kimi | Kimi K2.6 and K2.5 (both preview) |
| Mistral | Mistral Large 3 (preview) |
| Qwen | Qwen3.8-27B (preview, fine-tuning only, not serverless) |
| Cohere | Cohere models |
| Black Forest Labs | FLUX image models |
| Microsoft | Model Router, MAI, Phi |
| Anthropic | Claude Opus 5.5 (GA) |
| Meta | Meta models |
Checked against Microsoft Learn and the Microsoft Foundry Blog on November 3, 2026.
GPT-6.1 Sol gives a sense of scale, since in Foundry it has a context window of 1,050,000 tokens, of which 922,000 can be input. It also allows up to 128,000 output tokens and makes tool calls through the Responses API only.
Claude models in Foundry come in two hosting versions, Hosted on Azure and Hosted on Anthropic infrastructure. So check which one your residency rules need before deploying.
How to Choose a Model
Choosing well is mostly a testing habit, so test before you commit:
- Shortlist two or three models that fit your context length, modality and license needs.
- Build a task set from real prompts and the answers you expect.
- Then score each candidate with Foundry evaluators on quality, cost and latency.
- Use model router when task difficulty varies, so simple requests go to a cheaper model. Microsoft also added preview controls for it in September 2026.
- Use instant access (preview) to call supported models by name with no deployment while you test.
Teams that also run open-source LLMs outside Azure often put an LLM gateway in front of every provider, so that routing and logging stay consistent.
Deployment Types: Global Standard, Data Zone, Provisioned and Batch
A deployment type decides where inference runs and how you pay for it. It affects residency as well as cost.
Microsoft’s guidance on deployment types is direct. Start on Global Standard, because it gets new models first, has the lowest price and covers the most regions. Move only when you have a residency rule, a need for reserved throughput or a batch workload.
| Deployment type | Where inference runs | Billing | Use when |
|---|---|---|---|
| Global Standard | Any Azure region | Pay per token | Default for most workloads |
| Global Provisioned | Any Azure region | Reserved PTU | Steady high volume |
| Global Batch | Any Azure region | 50% discount, 24-hour turnaround | Async jobs such as bulk classification |
| Data Zone Standard, Provisioned or Batch | Within the US, EU or APAC zone | Per token, PTU or batch | Zone-level residency rules |
| Standard and Regional Provisioned | Within your Azure geography | Per token or PTU | Geography-level residency rules |
| Developer | Any Azure region (no residency guarantee) | Pay per token | Testing fine-tuned models for 24 hours, no SLA |
One point still confuses many security reviews. Data at rest stays in the geography you designate, but a Global deployment may process inference in any region. So if a regulator cares where prompts are processed, Data Zone or a regional type is the safer start.
A finance team scoring invoices overnight is a good Batch candidate, since nobody waits for the answer. A support agent with steady daytime traffic may justify Provisioned capacity, but only once its load has been measured.
Self-Hosting Open Models (vLLM, Ollama) vs Managed Foundry Deployments
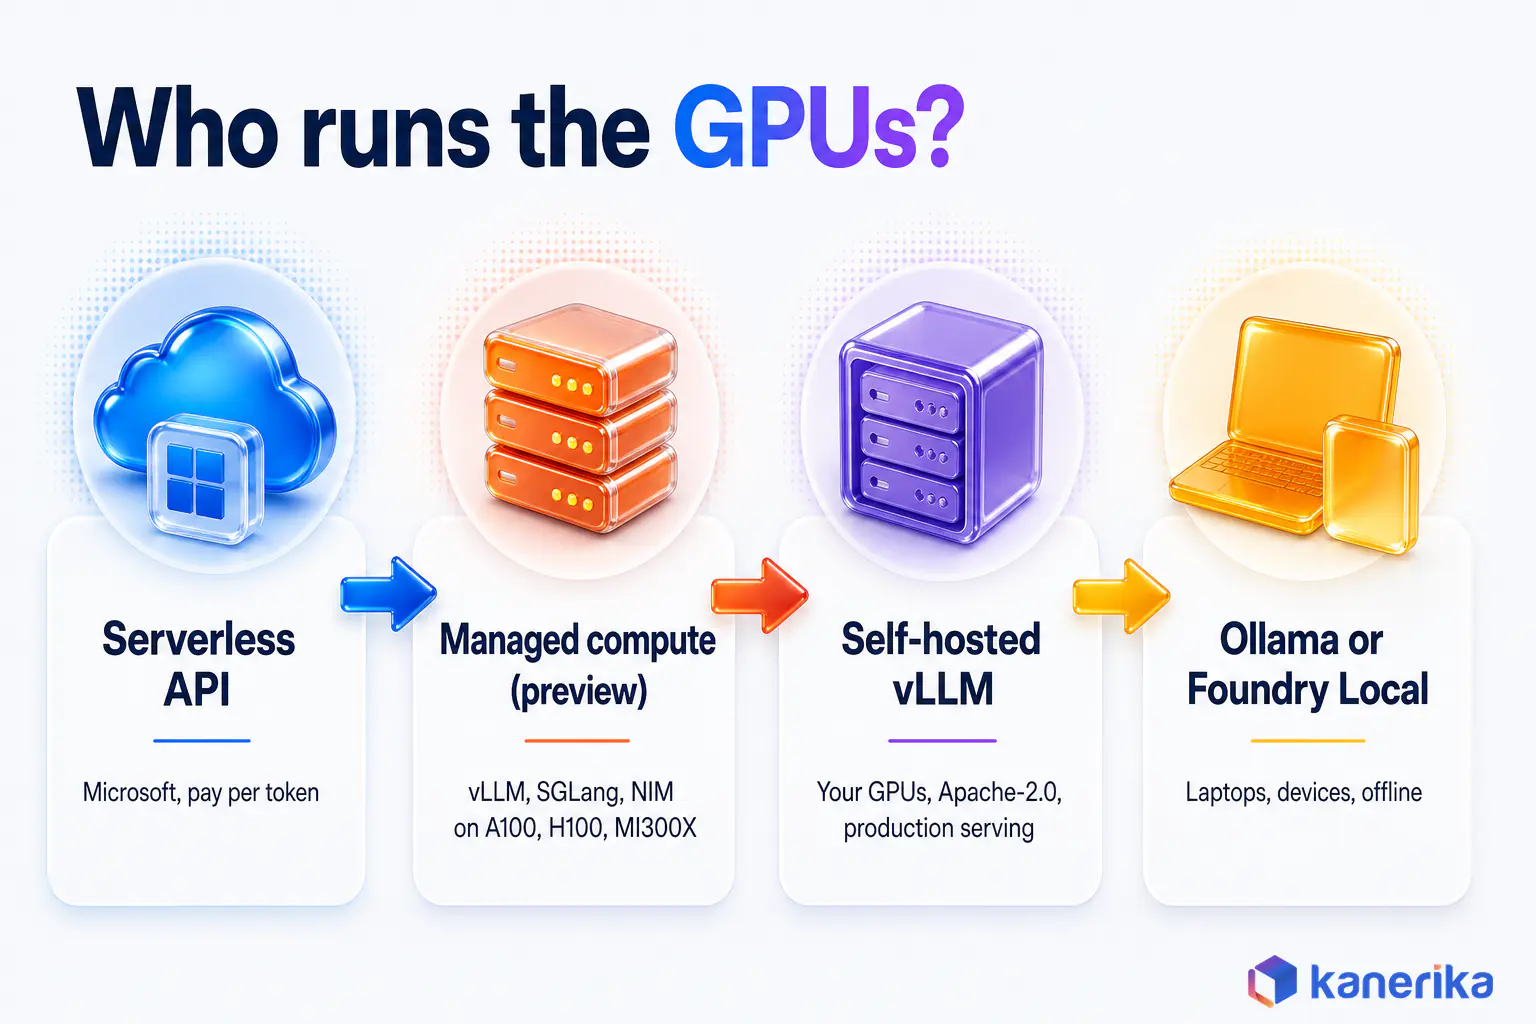
Open-weight models raise a second question after the model choice, which is who runs the GPUs. Foundry gives two managed answers, while vLLM and Ollama give two self-managed ones.
- Serverless API: Foundry Models sold by Azure run on capacity Microsoft manages, and you pay per token. The deployments overview also names this as Microsoft’s preferred option.
- Foundry managed compute (preview): Open-source, partner or custom weights run on dedicated GPUs that Foundry manages. Microsoft-curated vLLM, SGLang and NVIDIA NIM containers run on A100 80 GB, H100 80 GB or MI300X 192 GB.
- Self-hosted vLLM: Your team runs vLLM on its own GPUs. It is Apache-2.0 licensed and uses PagedAttention as well as continuous batching for concurrent serving. The stable release is v0.32.0 from October 18, 2026.
- Ollama or Foundry Local: Ollama is MIT licensed and suits laptops and small team servers, though it handles one request per model at a time by default. Foundry Local instead runs on Windows, macOS on Apple silicon or Linux with no Azure subscription. Microsoft also says it “isn’t designed as a server inference stack.”
Four Questions That Settle the Hosting Choice
Four questions settle most cases, so answer them before picking a path:
- Who should run the GPUs?
- Must prompts and weights stay inside your own boundary?
- Does the license of the weights allow your use?
- Do you need Foundry’s evaluation and governance around the model?
Take a bank that must keep a fine-tuned model in its own data center. It answers yes to the boundary question, so it leans toward self-hosted vLLM.
A product team with no appetite for GPU operations answers the first question the other way. It leans toward managed compute or serverless instead. Self-hosting also means running your own tracing stack, which the guide to LLMOps observability tools compares.
The vLLM vs Ollama comparison covers the self-hosted side. The guide to private LLMs covers the data boundary side.
Foundry Agent Service: Prompt Agents, Hosted Agents and Microsoft-Run Agent Loops
Foundry Agent Service is where models become agents that call tools and take actions. There are two main agent types, prompt agents and hosted agents, plus voice-based prompt agents. A prompt agent can also run on the Microsoft Copilot Harness (preview), where Microsoft runs the agent loop.
A prompt agent is configuration only. You define instructions, a model and tools through the portal, azd, the SDK or REST, and Foundry runs it. Voice-based prompt agents work the same way and run through Voice Live. A hosted agent, by contrast, is your own code in a container that Foundry manages.
Hosted agents can use frameworks such as Microsoft Agent Framework, LangGraph, OpenAI Agents SDK, Anthropic Agent SDK, Copilot SDK or custom code. So Microsoft’s agents overview sums up the advice as “start declarative and move to code.”
| Factor | Prompt agent | Hosted agent | Prompt agent on Copilot Harness (preview) |
|---|---|---|---|
| Authoring surface | Portal, azd, SDK or REST | Your framework in a container | Prompt agent setup, loop run by Microsoft |
| Runtime code | None | Yours | Microsoft’s |
| Compute | Fully managed | Managed container with its own Entra identity | Sandbox run by Microsoft |
| Cost model | Inference plus tool usage | Inference, tools and container compute | Runtime meter plus inference and tools |
| Best for | Most first agents | Custom logic and existing frameworks | Handing the loop to Microsoft |
In code, a prompt agent takes only a few lines of Python. The snippet below is copied from Microsoft’s Foundry SDK quickstart, which installs azure-ai-projects 2.3.0 or later (checked November 3, 2026).
from azure.identity import DefaultAzureCredential
from azure.ai.projects import AIProjectClient
from azure.ai.projects.models import PromptAgentDefinition

# Format: "https://resource_name.services.ai.azure.com/api/projects/project_name"
FOUNDRY_PROJECT_ENDPOINT = "your_project_endpoint"
FOUNDRY_AGENT_NAME = "your-agent-name"

# Create project client to call Foundry API
project = AIProjectClient(
    endpoint=FOUNDRY_PROJECT_ENDPOINT,
    credential=DefaultAzureCredential(),
)

# Create an agent with a model and instructions
agent = project.agents.create_version(
    agent_name=FOUNDRY_AGENT_NAME,
    definition=PromptAgentDefinition(
        model="gpt-5-mini",  # supports all Foundry direct models
        instructions="You are a helpful assistant that answers general questions",
    ),
)
print(f"Agent created (id: {agent.id}, name: {agent.name}, version: {agent.version})")
The sample signs in through DefaultAzureCredential, so run az login first. Its model value is the quickstart’s example, and you replace it with a model deployed in your own project.
Microsoft-Run Agent Loops, Versions and Publishing
The Microsoft Copilot Harness in Foundry entered public preview on October 28, 2026. With this option the resource stays a prompt agent, while Microsoft runs the agent loop as well as the sandbox. Runtime is free before December 1, 2026, and after that it bills $0.0994 per vCPU-hour and $0.0118 per GiB-hour.
Model inference and tools, however, are billed separately on top of that. Every agent also gets automatic version snapshots with rollback. Once published, an agent gets a stable endpoint and can be shared through Microsoft Copilot, Teams and the Entra Agent Registry.
Hosted agents are generally where LLM-powered autonomous agents and their planning loops live. Teams that want graph-style control flow in that code often weigh LangGraph first, especially for branching workflows.
Agent Tools in Foundry: Toolboxes, MCP Servers and Agent-to-Agent (A2A)
Tools let an agent act on systems as well as write text, so tool access is also where most of the risk sits. Foundry groups tools into five families:
- Built-in tools for web search, file search, code interpreter and memory.
- Custom functions that call your own code.
- OpenAPI tools that wrap an existing REST API.
- MCP servers, which use the Model Context Protocol.
- Agent-to-agent calls through A2A, with v1.0 now GA and v0.3 still in preview.
A toolbox puts a curated set of tools behind one managed MCP-compatible endpoint, with central authentication, governance and versioning. So a platform team can approve tools once and let many agents reuse them. MCP connections then authenticate with an API key, an Entra managed identity, OAuth on-behalf-of, or no authentication for public servers.
Routines and Tool Search went GA in September 2026, and then browser automation went GA on October 19, 2026. The guide to MCP vs A2A also explains how the two protocols split the work.
A practical rule is to give each agent the smallest tool set its job needs. For example, an HR agent that reads policy documents has no use for code interpreter or browser automation. Leaving them out also shrinks what a bad prompt can trigger.
Grounding Agents on Enterprise Data with Foundry IQ, Azure AI Search and Microsoft Fabric
Grounding is how an agent answers from your documents instead of from what the model memorized. Retrieval-augmented generation (RAG) fetches relevant passages at question time and then passes them to the model with the prompt.
Foundry IQ is a managed knowledge layer built on Azure AI Search agentic retrieval. It plans subqueries, searches several sources in parallel and enforces the caller’s permissions at query time, which makes it a managed form of agentic RAG.
Azure AI Search still suits teams that want index-level control over chunking, fields and ranking. Fabric IQ, the semantic layer in Microsoft Fabric, connects agents to Fabric data. The overview of Fabric IQ explains that layer in more detail.
The rule that matters most is to keep access control inside the retrieval path. An agent should only retrieve what the person asking may see, so permissions must travel with every query. Good RAG development builds that check into the retrieval layer, as the bank case study later in this post shows.
Cost needs a plan too, because indexing a whole SharePoint estate at launch can make search a large line item. Instead, index by use case and add sources as each agent proves its worth.
Evaluation, Tracing and Monitoring in Microsoft Foundry
Evaluation shows that an agent is good enough to ship, while monitoring shows when that stops being true. Foundry builds both into the platform, as the observability documentation describes. Its evaluators fall into four groups:
- Quality evaluators for coherence, fluency, groundedness and relevance.
- Safety evaluators for hate and unfairness, violence and protected materials.
- Agent evaluators for tool call accuracy and task completion.
- Custom evaluators for rules specific to your domain.
The AI red teaming agent, built on PyRIT, probes an agent with adversarial prompts. It works best with human review, because a person still has to judge which failures matter. The guide to LLM red teaming also covers that process.
Once an agent is live, continuous evaluation scores a sample of production traffic. OpenTelemetry tracing also sends spans into Application Insights, where dashboards show tokens, latency, errors and quality. Alerts then fire when outputs fail their thresholds, which is the core of AI agent observability.
A practical rule is that the team sets pass thresholds per use case and writes them into the release gate. Foundry supplies the measurement, while the threshold stays a business decision. An LLM evaluation framework helps set those numbers before the first release.
Security, Governance and the Foundry Control Plane
Security in Foundry starts with identity. Each new agent gets its own Entra agent identity, so access can be granted, reviewed and revoked per agent, just as it is for people. That identity starts with no resource permissions, and the other controls build on it:
- RBAC at the resource and project level, covered in the guide to Azure identity management.
- Private networking for prompt agents and bring-your-own VNet for hosted agents.
- Customer-managed key encryption.
- Prompt Shields content filters for user prompt attacks and for document attacks hidden in files, emails or web pages.
- Azure Policy, so every new project inherits a security baseline.
The Foundry control plane adds a fleet view of inventory, observability, compliance and security, and it integrates with Microsoft Defender, Purview and Entra. It also tracks agents from Foundry and from non-Microsoft sources, along with their cost and token use.
Picture a security lead asked how many agents exist across the company. With a control plane, that answer comes from one view instead of a survey of every team.
Platform controls still leave work inside each agent. Teams add AI guardrails to agent logic and apply sensitivity labels through data governance with Microsoft Purview. For the policy side, see AI governance services.
On-Demand Webinar
Microsoft Purview for Data and AI
An on-demand session on Purview labels, policies and monitoring for data that AI agents reach.
Watch the Webinar →Azure AI Foundry Pricing: What You Actually Pay For
Azure AI Foundry pricing has no platform charge of its own. Microsoft’s Foundry pricing page says “The Foundry platform is free to use and explore.” Individual features, it also adds, “are billed at their normal rates.”
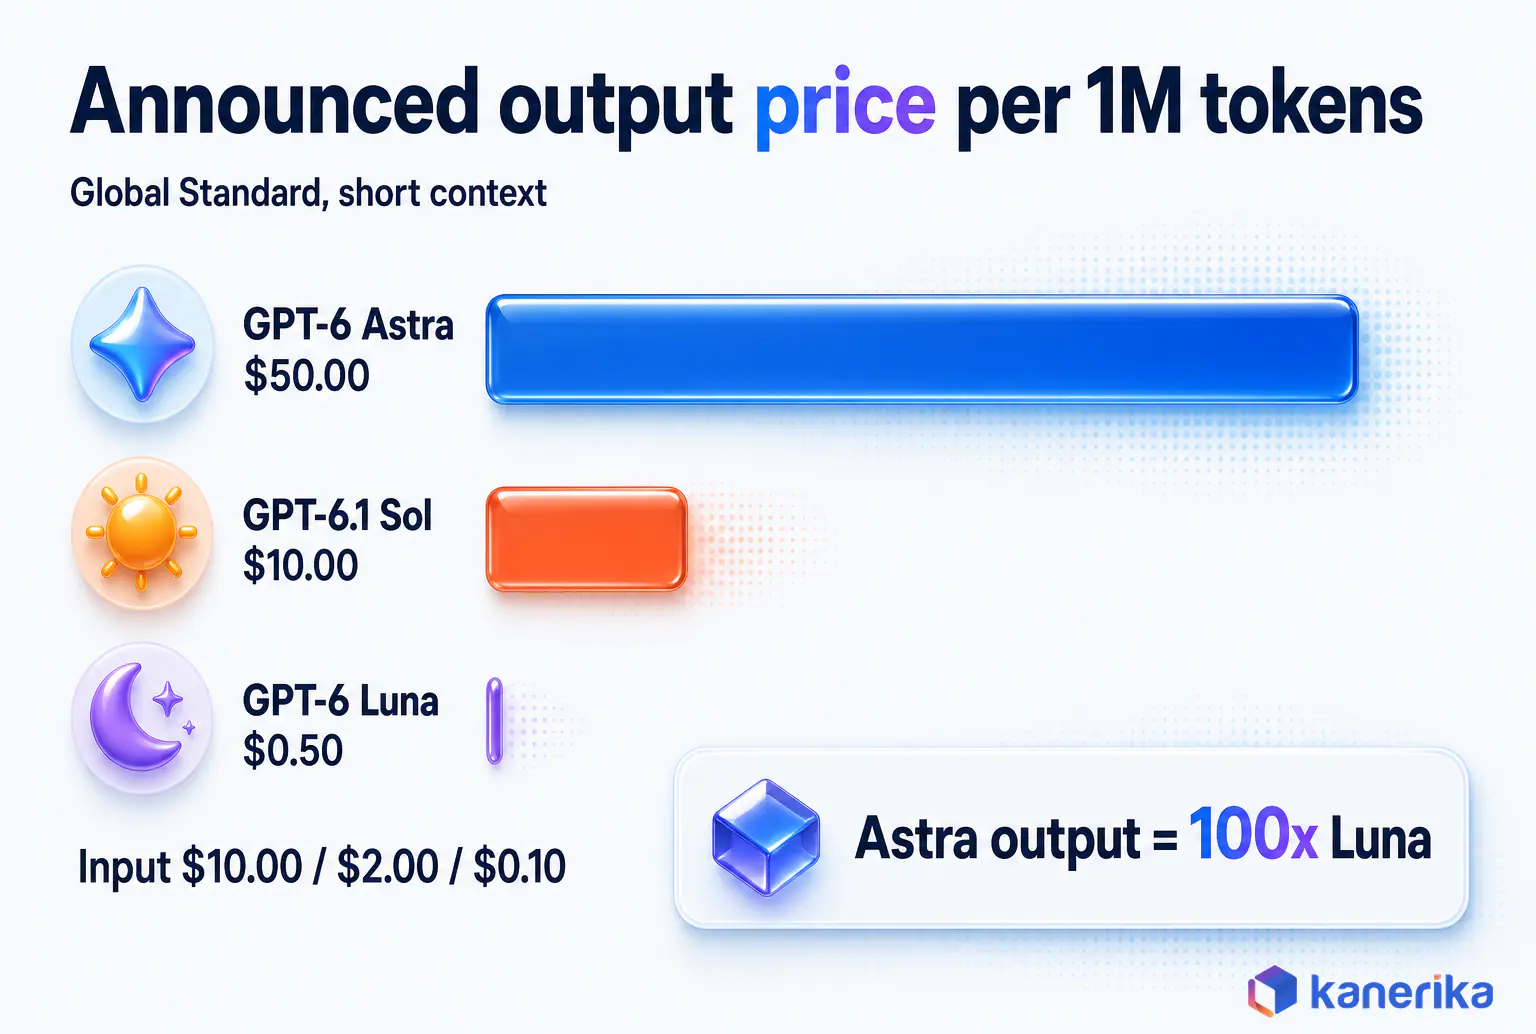
Each service in a project therefore bills on its own meter, and model tokens are usually the largest one. Microsoft announced these GPT-6 family rates in its September 2026 Foundry update, and the table shows them as of November 3, 2026.
| Model (Global Standard, USD per 1M tokens, as of November 3, 2026) | Input | Cached input | Output |
|---|---|---|---|
| GPT-6 Astra | $10.00 | $1.00 | $50.00 |
| GPT-6.1 Sol | $2.00 | $0.10 | $10.00 |
| GPT-6 Luna | $0.10 | $0.01 | $0.50 |
Checked against Microsoft Learn and the Microsoft Foundry Blog on November 3, 2026.
These rates apply to short-context requests, while long-context requests cost more. All three models are GA, with a 1.05M-token context and up to 128K output tokens. The Azure pricing page shows live rates by region, though the numbers above are Microsoft’s September announcement.
Global Batch also cuts token cost by 50% for jobs that can wait up to 24 hours. From December 1, 2026, Copilot Harness sandboxes add $0.0994 per vCPU-hour and $0.0118 per GiB-hour. Overall, a full bill usually draws on eight meters:
- Model inference tokens.
- Azure AI Search or Foundry IQ for retrieval.
- Embeddings for indexing documents.
- Container compute for hosted agents.
- Evaluation runs, which consume tokens as well.
- Storage for files, indexes and traces.
- Networking, such as private endpoints.
- Monitoring in Application Insights.
Budget per Accepted Result
Price per million tokens is a weak budgeting unit, because one user answer may take several model calls. A better unit is therefore the cost of a result a reviewer accepts. It adds up retries, tool calls and evaluation tokens, then divides by the answers that pass review.
Picture an agent that drafts contract summaries. If a cheaper model needs three attempts per accepted summary, it can cost more than a pricier model that gets it right the first time. So track that number per project, together with Azure cost optimization habits such as budgets and cost alerts.
Microsoft Foundry vs Azure OpenAI vs Azure Machine Learning vs Copilot Studio
Four Microsoft products overlap in name, so buyers often mix them up. They differ in who builds with them, and also in how much the platform does.
| Product | What it is | Built for |
|---|---|---|
| Microsoft Foundry | Pro-code platform for models, agents, tools and governance | Developers and AI engineering teams |
| Azure OpenAI | OpenAI models inside Foundry | Teams that need OpenAI models |
| Azure Machine Learning | Model training and MLOps | Data scientists and ML engineers |
| Copilot Studio | Low-code agent builder | Business makers |
Azure OpenAI is no longer a separate platform decision for most teams, since its resources upgrade into Foundry. Azure Machine Learning comes in when a team trains its own models and runs MLOps around them. The comparison of MLflow, Hugging Face Hub and Azure ML model registries covers that side.
For most new projects, then, the real choice is between Foundry and Copilot Studio. For instance, a business analyst who wants an agent over a SharePoint site can start in Copilot Studio. A team that needs custom tools, hosted code or per-agent evaluation will want Foundry instead.
AI Assessment
Check Your AI Readiness Before You Scale Agents
Score your data, governance and infrastructure readiness before funding production agents.
Start Your AI Assessment →How to Choose Between Foundry, Bedrock and Vertex AI
Each major cloud now has its own AI platform, and the right one usually follows where your business already runs. The table gives a fit verdict for each one, drawn from each vendor’s own documentation.
| Platform | Fit verdict | Deciding factor |
|---|---|---|
| Microsoft Foundry | Pick it when Microsoft 365, Entra and Azure already run the business | Each agent gets its own Entra identity and publishes to Teams and Microsoft Copilot, with 10,000+ catalog models |
| Amazon Bedrock | Pick it when workloads, data and IAM policies already live in AWS | Fully managed access to 100+ foundation models, including Amazon Nova, Claude, DeepSeek, OpenAI and xAI |
| Vertex AI | Pick it when data sits in BigQuery and Gemini models lead the shortlist | 200+ models in Model Garden, including Gemini 4 Argon, Claude and Gemma, with notebooks integrated with BigQuery |
Checked against the AWS and Google Cloud documentation on November 3, 2026. Google’s Vertex AI pages now redirect to Gemini Enterprise Agent Platform, so expect that name in its docs.
Feature lists change monthly, so test the verdict against these criteria before committing:
- Where your data and identity already live.
- Which models you need, checked against each vendor’s current catalog.
- Your residency rules and the regions each platform can keep processing inside.
- Existing cloud commitments, which often settle the choice before any feature does.
- Who will operate the agents, and which cloud’s tools they already know.
Teams standardized on AWS or Google Cloud generally start with that cloud’s platform. Teams already on Microsoft 365, Entra and Azure usually start with Foundry, since identity, Purview and Teams publishing are in place. The AWS vs Azure vs Google Cloud comparison also gives a wider view.
Moving a Foundry Pilot to Production: A Release Checklist
A working pilot proves an idea, while production proves it can run safely every day. The gap is mostly operational, so a written list helps.
Before the Pilot: Microsoft’s Five-Step Path
Microsoft Learn lays out a five-step path for new builders:
- Make a first model call.
- Set up the CLI and the azure-ai-projects 2.x SDK.
- Choose a model.
- Build a prompt agent or a hosted agent.
- Add tools, retrieval and memory.
Before Release
Start with four questions, and answer each one in writing before release:
- Who can access which agents, and through which Entra groups?
- What data may each agent retrieve, and is that enforced at retrieval time?
- How are outputs evaluated before users see them, and which thresholds block a release?
- How will problems be caught after go-live, through traces, alerts and continuous evaluation?
Those answers cover the design. Pilots also tend to skip five operational checks:
- Is quota sized for peak load, with retry and backoff handling in the client?
- Is there a model retirement plan? Microsoft keeps a model retirement schedule, so pin versions and test replacements early.
- Can you roll back to a previous agent version quickly?
- Does each project have its own cost alert?
- Is there a named owner for prompts, models and data connections?
Checklist
Agentic AI Checklist
Access, data, evaluation and monitoring checks to clear before an agent goes live.
Get the Checklist →How Kanerika Delivers Microsoft Foundry Projects
Kanerika treats a Foundry project as a governance and data project first, so model choice comes later. Delivery then follows five stages:
- AI tooling assessment and an adoption roadmap, built around use cases with a measurable business result.
- Resource and project planning for structure, networking, identity and policy before any agent is built, with rollout by department.
- Agent design and build with prompt and hosted agents, multi-agent orchestration, memory and retrieval, tested on real business scenarios.
- Model evaluation across the catalog on accuracy, cost and latency, ending in a recommended model mix.
- Identity, access and observability, with Entra ID, RBAC, content filters, network isolation, Azure Policy baselines, tracing and access-log reviews.
Engagements move from consultation to a proof of concept, then to a production rollout with governance in place. When agents touch labeled or regulated data, the same plan also covers Microsoft Purview implementation.
Kanerika’s own agents also plug into this pattern. Karl answers questions over structured data, KlarityIQ works over unstructured documents, and FLIP is Kanerika’s automation platform. Kanerika is also a Microsoft Solutions Partner for Data and AI.
Case Study: Permission-Aware Retrieval for an Investment Bank
Before the project, an investment bank searched its documents and databases through separate interfaces, and its access controls sat outside the retrieval process. Kanerika then deployed KlarityIQ over the bank’s RFI document repositories and Karl over its enterprise databases, behind one chat interface. Role-based access was then enforced at the retrieval layer.
The AI document retrieval project for an investment bank delivered 43% faster information retrieval and 100% role-based compliance at the point of retrieval. It also brought a 35% improvement in workforce efficiency. That is the same permission-aware retrieval pattern Foundry IQ and Entra-scoped agents implement.
Case Study
43% Faster Information Retrieval for an Investment Bank
KlarityIQ and Karl gave bank staff one chat interface over documents and databases, with access enforced at retrieval.
Read the Case Study →Bottom Line: Starting With Microsoft Foundry
Azure AI Foundry, now Microsoft Foundry, gives a team one governed place to pick models, build agents and control what they cost. Each of the four big choices has a sensible default, and each default changes only when a measured need appears.
- Model: shortlist two or three from the catalog, score them with Foundry evaluators, and add model router when task difficulty varies.
- Deployment type: start on Global Standard, then move to Data Zone, Provisioned or Batch for residency, steady volume or async jobs.
- Agent type: start with a prompt agent, and move to a hosted agent once you need your own framework or code.
- Cost unit: budget per accepted result, not per million tokens, and give every project its own cost alert.
Three habits then shorten the path from that first agent to production:
- Fix data access and residency decisions before the first agent is built.
- Start with one prompt agent on Global Standard, then earn the move to hosted agents or provisioned capacity with measured load.
- Write evaluation thresholds into the release gate, so every release meets the same quality bar.
Get those defaults right, and the models, agents, pricing and deployment choices in Azure AI Foundry stay simple to govern as the agent count grows.
Frequently Asked Questions
What is Azure AI Foundry, and is it now called Microsoft Foundry?
Yes. Azure AI Foundry, earlier known as Azure AI Studio, is now called Microsoft Foundry. It is the Azure platform for building and governing AI apps and agents. One Foundry resource holds projects, a catalog of more than 10,000 models, Foundry Agent Service, evaluation and tracing tools, and shared RBAC, networking and policy controls.
Is Azure AI Foundry different from Azure OpenAI?
Yes. Azure OpenAI is one model provider inside Foundry, and Foundry is the wider platform around it. Foundry adds agents, tools, knowledge retrieval, evaluation and governance on top of the models. Existing Azure OpenAI resources can be upgraded in place into Foundry while keeping the same endpoint and API keys, so current apps keep working.
Should I use Azure AI Foundry or Copilot Studio?
Copilot Studio suits business makers who want a low-code agent, for example one that answers questions over a SharePoint site. Foundry suits developers who need custom tools, hosted code, model choice and per-agent evaluation. A team can prototype in Copilot Studio first, then rebuild in Foundry once an agent needs more control or deeper integration.
Can I run Foundry models on my own servers or offline?
Foundry Local runs models on Windows, macOS on Apple silicon and Linux with no Azure subscription, which suits on-device and offline apps. Microsoft says it is not built as a server inference stack. For your own servers, teams usually self-host open weights with vLLM for production serving, or with Ollama for laptops and small team servers.
What should a team fix before moving a Foundry proof of concept to production?
Settle who can access each agent and what data it may retrieve, with permissions enforced at retrieval time. Set evaluation thresholds that block a release, and add tracing and alerts for after launch. Size quota for peak load, plan for model retirement, keep agent versions for rollback, set cost alerts and name an owner for each agent.
Where is my data processed when I deploy a model in Azure AI Foundry?
Data at rest stays in the geography you designate. Processing depends on the deployment type you pick. Global deployments may process inference in any Azure region. Data Zone deployments keep processing within the US, EU or APAC zone, while Standard and Regional Provisioned deployments keep it within your Azure geography for stricter residency needs.
How does Azure AI Foundry work with Microsoft Fabric?
Fabric IQ, which is in preview, connects Foundry agents to data in Microsoft Fabric. That helps teams whose curated data already sits in a Fabric lakehouse. Agents can then answer from governed Fabric data. Foundry IQ and Azure AI Search cover other sources, such as documents and SharePoint content, through the same agent setup.
Which models are available in Azure AI Foundry, including open-source models?
The catalog lists more than 10,000 models from Microsoft, OpenAI, Anthropic, Meta and others. Examples include GPT-6.1 Sol, DeepSeek-V4-Pro, Grok 4.7, Mistral Large 3 (preview), gpt-oss and Claude Opus 5.5, which is GA on both Azure and Anthropic hosting. Open-source and custom weights can also run on Foundry managed compute, which is in preview.
How does Azure AI Foundry compare with AWS Bedrock and Google Vertex AI?
The right platform usually follows where your data, identity and cloud commitments already sit. Compare the models each vendor offers today, its residency options and who will operate the agents. Teams standardized on AWS or Google Cloud usually start with that cloud’s platform. Teams already on Azure, Entra and Microsoft 365 usually start with Foundry.
Does Azure AI Foundry support AI agents?
Yes. Foundry Agent Service has two main agent types: prompt agents with no runtime code, including voice-based prompt agents through Voice Live, and hosted agents that run your own framework in a container. A prompt agent can run on the Copilot Harness (preview), where Microsoft runs the agent loop. Agents get version snapshots and can be published to Teams.
How secure is Azure AI Foundry for enterprise workloads?
Foundry gives each agent its own Entra identity and applies RBAC at resource and project level. It supports private networking, bring-your-own VNet for hosted agents and customer-managed key encryption. Content filters target prompt injection, and Azure Policy sets a baseline for new projects. The control plane integrates with Defender, Purview and Entra for oversight.
Is Azure AI Foundry free, and what does it cost?
The Foundry platform itself is free to use and explore, and each feature bills at its normal rate. Model tokens are usually the largest cost. Microsoft announced GPT-6.1 Sol at $2.00 input and $10.00 output per million tokens on Global Standard. Search, hosted agent compute, evaluation runs, storage and monitoring add their own charges.
Does Azure AI Foundry support MCP and frameworks like LangGraph?
Yes. Agents can connect to MCP servers, and a toolbox can expose curated tools behind one managed MCP-compatible endpoint with central authentication and versioning. Hosted agents can run code written with LangGraph, Microsoft Agent Framework, OpenAI Agents SDK, Anthropic Agent SDK or Copilot SDK. A2A version 1.0 is generally available for agent-to-agent calls.
What is the difference between a prompt agent and a hosted agent in Foundry?
A prompt agent is configuration only. You set instructions, a model and tools, and Foundry runs it, so you pay for inference and tool use. A hosted agent is your own code in a container that Foundry manages, with its own Entra identity. It adds container compute to the bill and suits custom logic.