TL;DR
GPT Codex vs Claude Code is a workflow choice: pick Codex for ChatGPT-centered teams that want cloud tasks, and Claude Code for terminal-first work in large repos. Both agents run locally in a terminal and in IDEs, and both send code context to their vendor’s model API. Codex on ChatGPT Plus uses GPT-6.1 Sol and GPT-6 Luna, while Opus 5.5 and Sonnet 5.5 lead the Anthropic models behind Claude Code. Paid individual plans start at $20 a month on both sides, and team seats cost $20 to $25 per user a month. Their sandbox and permission controls differ more than their benchmark scores, so security teams should compare those first. Settle a close call with a two-week pilot on 20 to 40 real tickets, then choose the agent with the lower cost per merged change.
Key Takeaways
- Both tools are coding agents with a local CLI, IDE support and cloud tasks, so the choice rests on workflow and controls.
- On ChatGPT Plus, Codex runs GPT-6.1 Sol and GPT-6 Luna, while Claude Code runs Opus 5.5, Sonnet 5.5, Haiku 5.5 and Fable 5.1.
- Project rules live in AGENTS.md for Codex and CLAUDE.md for Claude Code, so one set of build, test and no-touch rules can fill both files.
- For safety, Codex uses /permissions for approvals, sandbox and writable roots, while Claude Code adds a read-only Manual mode and /sandbox.
- ChatGPT Plus and Claude Pro both cost $20 a month, while team seats on Codex Business or Claude Team run $20 to $25 per user.
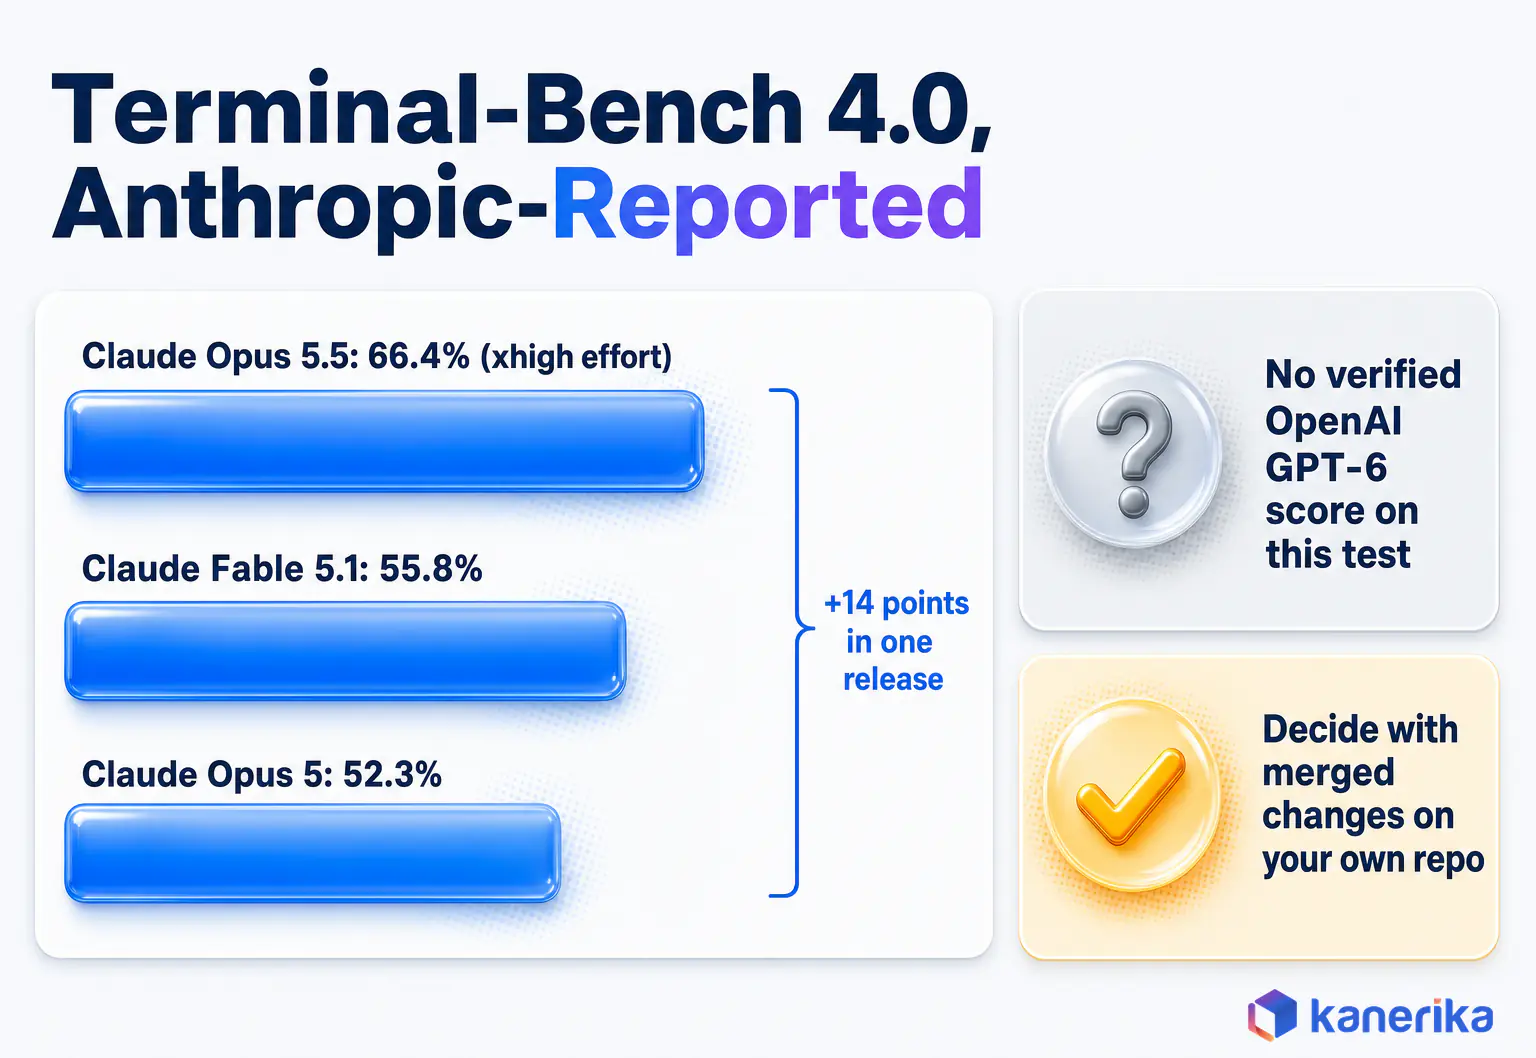
- Anthropic’s own Terminal-Bench 4.0 score rose 14 points from Opus 5 to Opus 5.5, so a pilot that measures cost per merged change beats any leaderboard.
A Migration Sprint, Two Agents, One Failing Test Suite
Picture a platform team two weeks into moving a payments service to a new framework. One engineer runs Codex from the terminal, while another runs Claude Code on the same branch.
Then, on Thursday, the test suite goes red. One session had widened a refactor past the module named in the ticket. The other had stopped to ask before it edited a shared config file.
Neither agent was “smarter” in that moment. Instead, both behaviors came from permission settings, project instructions and how each engineer reviewed the diffs.
That is the real shape of the GPT Codex vs Claude Code question. So this guide compares the two AI coding agents on models, execution, controls and cost. Every price and version was checked against vendor pages on November 3, 2026.
What Are OpenAI Codex and Claude Code in November 2026?
OpenAI Codex and Anthropic Claude Code are coding agents: they read a repository, edit files, run commands and hand the result back for review. Because each comes from a model vendor, it works best with that vendor’s models and accounts.
That vendor link shapes everything from pricing to data terms. Our comparison of OpenAI vs Anthropic also covers the companies behind the two tools.
OpenAI Codex
Codex is OpenAI’s coding agent, and its open-source CLI runs locally on your machine. You install it with npm or Homebrew, then sign in with a ChatGPT account or an API key.
The same agent also reaches past the terminal. An IDE extension covers VS Code, Cursor and Windsurf, while paid ChatGPT plans add web and cloud tasks and iOS. The desktop app also reaches Free and Go accounts as it rolls out.
OpenAI also ships CLI releases often. Version 0.166.0 landed on October 29, 2026, so check the release page before you pin a version for a team.
Anthropic Claude Code
Claude Code is Anthropic’s coding agent, and it started in the terminal. Since then it has spread, and the Claude Code overview lists the terminal, IDEs, a desktop app and the browser.
It also reaches into team tools such as VS Code, JetBrains and Slack. In addition, it runs in the cloud and in CI, and it includes a Code Review feature for pull requests.
Anthropic ships updates often too. For example, version 2.1.317 shipped on November 3, 2026, according to the Claude Code releases page.
Why This Is an Agent Comparison, Not a Model Comparison
In short, a coding agent is a model wrapped in tools, permissions and context management. That wrapper decides which files the model sees, which commands it may run and when it must stop and ask.
As a result, two agents on similar models can behave very differently on the same ticket. That is why this guide spends as much time on sandboxes and project files as on model names.
Vendor support matters too once a rollout reaches the whole company. The video below explains how the OpenAI partner program works for enterprise AI.
Watch on YouTube
OpenAI Partner Network 2026: Tiers, Specializations & Enterprise AI
How OpenAI’s partner program is structured and what it means for enterprise AI rollouts.
GPT Codex vs Claude Code at a Glance
A side-by-side view helps because both products change every few weeks. So the table below fixes the comparison to vendor pages read on November 3, 2026.
Read it row by row with your own constraints in mind. For instance, a team that bans cloud execution can skip the cloud-task row and weigh the permission row twice.
Side-by-Side Comparison
Table 1: GPT Codex vs Claude Code side by side, as of November 3, 2026.
| Area | OpenAI Codex | Anthropic Claude Code |
|---|
| Surfaces | CLI, IDE extension (VS Code, Cursor, Windsurf), web and cloud tasks, desktop app, iOS | Terminal, IDEs (VS Code, JetBrains), desktop app, browser, Slack, CI |
| Models | GPT-6.1 Sol and GPT-6 Luna on ChatGPT Plus; API models in API-key mode | Opus 5.5, Sonnet 5.5, Haiku 5.5, Fable 5.1 |
| Context window | 1,050,000 tokens on GPT-6 models, 128K output | 1M tokens on current Claude models, 128K output |
| Local execution | Yes, the CLI runs on your machine | Yes, the terminal session runs on your machine |
| Cloud tasks | Web and cloud tasks, cloud code review, Slack on paid ChatGPT plans | Claude Code in the cloud, Code Review, CI |
| Project file | AGENTS.md (global plus project layers) | CLAUDE.md |
| Subagents | Yes, delegate focused work and report back | Yes, each with its own context, prompt, tools and permissions |
| Multi-agent teams | Subagents; no separate team mode in the CLI docs | Agent teams, experimental and off by default |
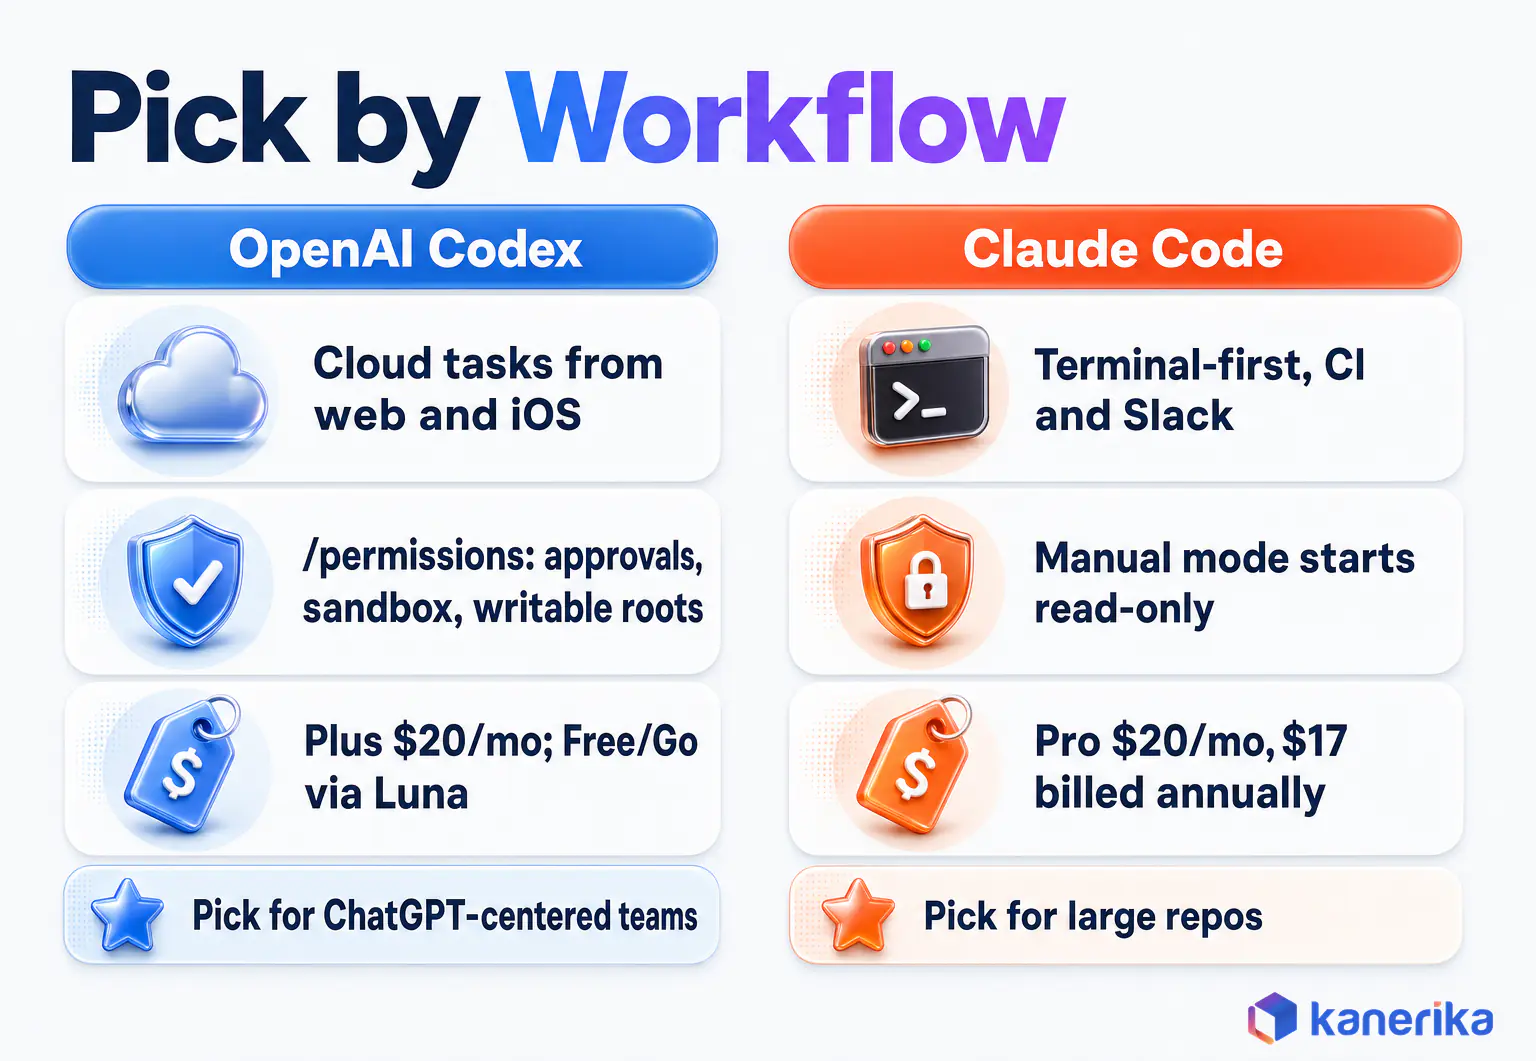
| Permission controls | /permissions for approvals, sandbox and writable roots | Manual mode starts read-only; /sandbox isolates bash |
| Entry price | Free and Go ($8) with GPT-6 Luna as it rolls out; Plus $20 a month | Pro $20 a month, or $17 billed annually; Free has no Claude Code |
| Team plan | Business $20 per user a month annually, $25 monthly | Team standard $20 per user a month annually, $25 monthly |
| Latest release | CLI 0.166.0, October 29, 2026 | 2.1.317, November 3, 2026 |
What the Table Tells You
The table shows two tools with near-identical reach and price. Still, they part ways on where work runs by default and on how each one asks before it changes your code.
Talk to Kanerika
Book a Coding Agent Working Session
Walk through your repos with Kanerika engineers and leave with a risk map, a permission baseline and a pilot ticket list.
Schedule a Session →
Codex leans toward the cloud, so on a paid ChatGPT plan a task can start from the web or a phone. Claude Code leans toward the local terminal, where its permission mode decides whether it asks before each edit. A team that reviews every change by hand should therefore weigh the permission row above the price row.
Which Models Power Codex and Claude Code?
Each agent runs on its own vendor’s model family, and model choice drives both quality and cost. Both vendors now sell a fast, cheap tier as well as one or two flagship tiers.
That spread matters more than any single model. A team can then route planning to a large model and bulk edits to a small one in the same agent.
OpenAI Models in Codex
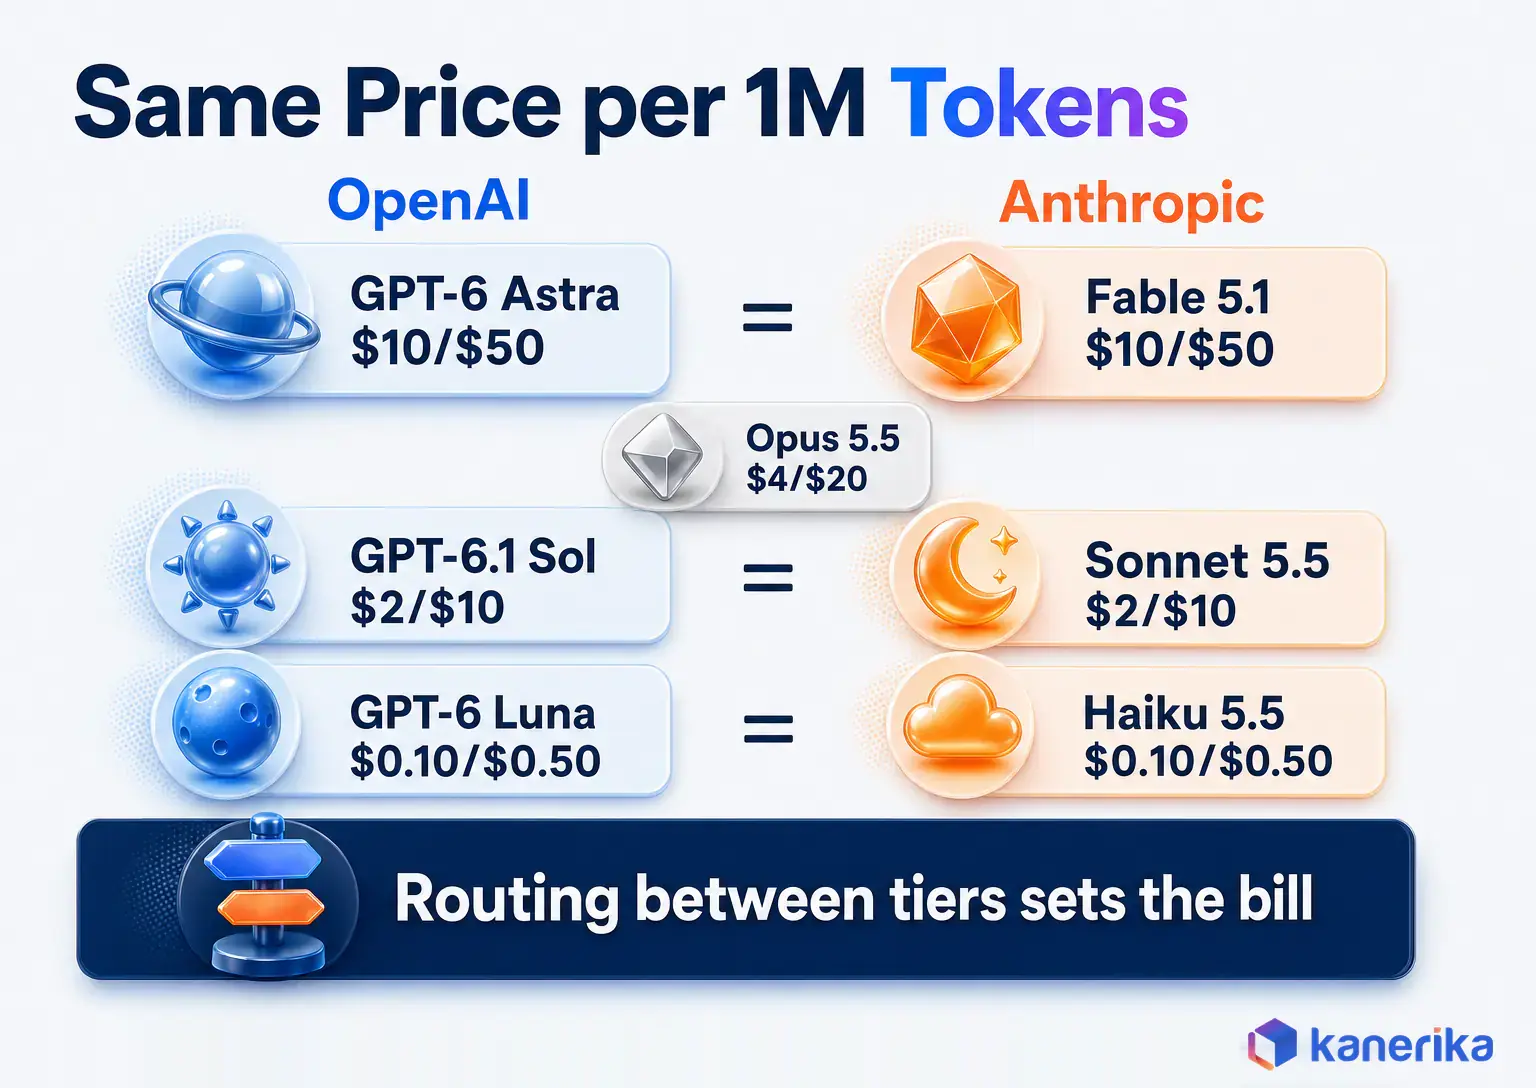
OpenAI’s GPT-6 family covers four price points. GPT-6.1 Sol, published on September 29, 2026, costs $2 per million input tokens and $10 per million output tokens.
Above it sits GPT-6 Astra at $10 and $50. Below it come GPT-6.1 Terra at $1 and $5 and then GPT-6 Luna at $0.10 and $0.50. Our guide to GPT models traces how this lineup grew.
One change matters especially for older setups. GPT-5.5 left Codex for ChatGPT sign-in on October 14, 2026, so any team script that pins it will need an update.
Anthropic Models in Claude Code
Anthropic’s lineup also has four current models. Opus 5.5 arrived on September 22, 2026 at $4 and $20, and then Sonnet 5.5 followed on September 28 at $2 and $10.
Haiku 5.5, released on October 7, 2026, is the cheap tier at $0.10 and $0.50. Fable 5.1 is the premium tier at $10 and $50. Even so, Anthropic’s published benchmarks show Opus 5.5 matching or beating it on most listed tests.
Anthropic’s own docs tell unsure users to start with Opus 5.5, and Claude Code makes it the default model on paid plans. For most coding teams, then, Opus 5.5 does the main work and Haiku 5.5 is the volume tier.
Context Windows and Long Sessions
Both families now hold about a million tokens of context. GPT-6 models take 1,050,000 tokens while Claude models take 1M, and both cap output at 128K tokens.
Long prompts carry a price catch, though. On GPT-6.1 Sol and Terra, prompts over 272K tokens cost 2x on input and 1.5x on output. Similarly, Haiku 5.5 output rises to $2.50 per million above 100K prompt tokens.
Table 2: API list prices per 1M tokens and context limits, as of November 3, 2026.
| Model | Input / output per 1M | Context / max output |
|---|
| GPT-6 Astra | $10 / $50 | 1.05M / 128K |
| GPT-6.1 Sol | $2 / $10 | 1,050,000 / 128K |
| GPT-6.1 Terra | $1 / $5 | 1,050,000 / 128K |
| GPT-6 Luna | $0.10 / $0.50 | 1.05M / 128K |
| Claude Fable 5.1 | $10 / $50 | 1M / 128K |
| Claude Opus 5.5 | $4 / $20 | 1M / 128K |
| Claude Sonnet 5.5 | $2 / $10 | 1M / 128K |
| Claude Haiku 5.5 | $0.10 / $0.50 | 1M / 128K |
A sensible routing rule then follows from the table. Use Opus 5.5 or GPT-6.1 Sol to plan and to refactor across modules, then hand repetitive edits to Haiku 5.5 or GPT-6 Luna.
The same partner question comes up on the Anthropic side. The video below explains how the Claude partner program works for enterprise adoption.
Watch on YouTube
Claude Partner Network 2026: Tiers, Certifications & Enterprise AI
How Anthropic’s Claude partner program works, from tiers to certifications, for enterprise teams.
How Each Agent Runs Your Code: Local, Cloud and IDE
Where an agent executes your code decides what it can touch and what leaves your network. Both tools offer local, IDE and cloud modes, but each mode carries a different risk.
A useful way to think about it is as three rings, from tightest control to widest reach:
- Local CLI: the agent runs in your terminal, inside your repo, under your user account.
- IDE extension: the same agent runs inside the editor, so the open workspace sets its scope.
- Cloud task: the vendor runs the agent in its own environment against a copy of your repo.
Local CLI Sessions
Both CLIs run locally, which makes them easy to start on a single laptop. Local does not mean nothing leaves the machine, though, because each agent sends code context to its vendor’s model API.
So treat a local session as “local execution, remote reasoning”. Files, diffs and command output that the agent reads can all travel to the model as prompt text.
Cloud Tasks and Code Review
Codex adds web and cloud tasks, GitHub code review and Slack once you move to a paid ChatGPT plan. API-key mode keeps the CLI, SDK and IDE, but it drops every cloud feature and bills at API rates.
Claude Code takes a similar path, since it runs in the cloud and in CI. Its Code Review feature comments on pull requests, so a team can gate merges on agent review plus human sign-off.
Data Handling Questions to Ask
Before any rollout, get written answers to three questions. How long does the vendor keep prompts and code, does it train on them, and where does processing happen?
The answers differ by plan. For example, Codex on ChatGPT Business does not train on business data by default. Claude models on Amazon Bedrock, meanwhile, can use regional endpoints that keep data routing inside set regions.
What Do the Benchmarks Actually Show?
Benchmarks give a rough sense of model strength, but they rarely predict how an agent performs in your repo. So treat the numbers below as a starting point rather than a final answer.
Vendor-Reported Numbers
Anthropic reports that Opus 5.5 scores 66.4% on Terminal-Bench 4.0 at xhigh effort. On the same chart, Fable 5.1 scores 55.8% and the earlier Opus 5 scores 52.3%.
However, we found no OpenAI-reported Terminal-Bench 4.0 figure for the GPT-6 models that we could verify. That gap means there is no fair head-to-head number to quote for these two agents.
Why Leaderboard Deltas Mislead
A benchmark score reflects the model, the effort setting, the agent wrapper and the token budget all at once. When any one of them changes, the score moves.
The 14-point jump from Opus 5 to Opus 5.5 shows how fast these numbers shift. Third-party posts also publish conflicting Codex vs Claude Code results.
What Developers Report
Survey data also adds a reality check. In the Stack Overflow 2025 Developer Survey, 84% of respondents used or planned to use AI tools, up from 76% in 2024.
Daily use was common too, with 51% of professional developers using AI tools every day. Still, trust lagged behind use, since 46% distrusted the accuracy of AI output against 33% who trusted it.
Agents, however, were the slowest part of that shift. Some 52% of respondents either did not use agents or stuck to simpler AI tools.
For a team-level view, DORA’s 2025 report, State of AI-assisted Software Development, studies how engineering teams adopt these tools. It is a useful companion read.
Configuration and Extensibility: AGENTS.md, CLAUDE.md, MCP, Skills and Hooks
Project files tell an agent how your repo works before it touches anything. A good one therefore cuts wrong guesses about build commands, test commands and files that must stay untouched.
Codex reads AGENTS.md before any work, layering a global file with project files. Claude Code reads CLAUDE.md in the same spirit, so one set of rules can serve both tools.
A minimal shared file might look like this:
# Project rules for coding agents
## Build
npm ci && npm run build
## Test (run before every commit)
npm test -- --coverage
## Do not edit
- migrations/
- infra/prod/
- any file under .github/workflows/
## Style
- Keep changes inside the module named in the ticket
- Never change a test to make it pass; flag it instead
Beyond the project file, each tool extends in its own way:
- Codex: AGENTS.md layers, MCP servers for outside tools and data, and /permissions settings for approvals and the sandbox.
- Claude Code: CLAUDE.md, MCP servers, subagent definitions, skills for reusable task recipes and hooks that run scripts at set points.
- Both: the Model Context Protocol connects issue trackers, docs and databases without custom glue code.
Still, keep these files short and specific. The ideas behind context engineering apply here, because every line in the file competes for the model’s attention on each task.
Multi-Agent Work: Subagents and Agent Teams
Large tasks go better when an agent splits them into smaller ones. Both tools now support helper agents, although they go about it in different ways.
Codex subagents take a focused piece of work, such as “find every caller of this function”, and then report back. Meanwhile, the main session keeps the plan and merges the results.
Claude Code subagents get their own context window, system prompt, tools and permissions. For instance, a test-writing subagent can hold write access to tests only.
Claude Code also has agent teams, where several sessions work in parallel and coordinate. The feature is experimental and off by default, so you turn it on with the CLAUDE_CODE_EXPERIMENTAL_AGENT_TEAMS=1 environment variable.
Parallel agents also raise the same design questions as any multi-agent AI system. Who owns the plan, how do agents hand off, and who checks the merged result?
Our guide to AI agent orchestration covers those patterns in more detail. In practice, start with one main agent and one or two scoped helpers before trying full teams.
Kanerika Service
Plan Your Multi-Agent Coding Setup
Kanerika designs agent roles, handoffs and permission scopes so Codex or Claude Code subagents work safely on your repos.
Explore Agentic AI Services
Security, Permissions and Enterprise Controls
Permission settings decide what an agent can change without asking, which makes them the most important controls in any rollout. Both tools reach similar outcomes, but through different settings.
Built-In Controls Compared
Codex groups its controls under /permissions: edit approvals, command approvals, sandbox mode and writable roots. On top of that, Codex Business adds SAML SSO, MFA and no training on business data by default.
Claude Code’s manual mode starts read-only and asks before edits or commands. Its /sandbox command also isolates bash, and an organization can disable auto mode for every user.
Claude Code’s starting mode needs a check too. Current terminal and VS Code sessions start in auto mode, where a classifier reviews actions. Admins who want approval prompts can make Manual the default in managed settings.
Table 3: Security controls in Codex and Claude Code, and what to require.
| Control | Codex | Claude Code | What to require |
|---|
| Edit approval | Edit approvals in /permissions | Manual mode asks before edits | Approval on for production repos |
| Command approval | Command approvals in /permissions | Manual mode asks before commands | Approval for network and deploy commands |
| Isolation | Sandbox mode and writable roots | /sandbox bash isolation | Writes limited to the repo working tree |
| Org policy | Check admin settings on your plan | Org can disable auto mode | Auto modes off by default |
| Identity | SAML SSO and MFA on Business | Confirm SSO terms on your plan | SSO for every seat |
| Training on data | Off by default on Business | Check plan terms | Written no-training terms |
A Short Governance Checklist
Controls in the tool are only half of the job, so a short governance checklist covers the rest:
- Secrets: keep keys out of the repo and scan every agent commit for them.
- Audit logs: record which agent ran which command, on which branch, for whom.
- Repo access: name who may run agents on production repos and on which tier.
- Prompt injection: review every MCP server, because tool output can carry hidden instructions.
Our guides on agentic AI security and the LLM security guide go deeper on injection and data leakage. Teams that want a written policy can also start with AI governance services.
Checklist
Download the AI Governance Checklist
A practical list of controls to set before coding agents like Codex or Claude Code work on production code and data.
Get the Checklist →
GPT Codex vs Claude Code Pricing
Pricing comes in two forms for both tools: a monthly seat or pay-per-token API billing. In practice, most teams use seats for people and API keys for automation.
Subscriptions
At first glance, seat prices line up closely at the entry level. However, the real differences show at the top tiers and in how usage limits scale.
Table 4: Subscription plans that include Codex or Claude Code, per Codex pricing and Claude pricing, November 3, 2026.
| Tier | Codex (ChatGPT plans) | Claude Code (Claude plans) |
|---|
| Free | $0, GPT-6 Luna as it rolls out | No Claude Code |
| Low-cost | Go $8, GPT-6 Luna and desktop as it rolls out | None |
| Individual | Plus $20: web, CLI, IDE, iOS, cloud code review, Slack | Pro $20 monthly or $17 billed annually |
| Power user | Pro from $100 ($100, $200 or $500) | Max $100 (5x Pro), Ultra $200 (10x Pro weekly) |
| Team | Business $20 per user annually, $25 monthly, 2+ users | Team standard $20 annually, $25 monthly; premium $100 or $125; 2 to 150 users |
API Rates
API-key mode bills by token, and both vendors discount repeat and batch work. Those discounts often matter more than the headline rate.
- GPT-6.1 Sol: $2 input, $0.10 cached input and $10 output per 1M tokens, with Batch and Flex 50% lower.
- Claude Opus 5.5: $4 input and $20 output, with cache reads at $0.20, cache writes at $5 and Batch at $2 and $10.
- Long prompts: Sol and Terra charge 2x input and 1.5x output above 272K tokens, so trim context before you scale.
The OpenAI API pricing page and Claude API pricing page list every modifier. Our OpenAI API guide also explains how keys, limits and billing work.
Teams that run both vendors often put an LLM gateway in front of the APIs. That way there is one place to route models, cap spend and log usage.
Cost per Merged Change
Seat and token prices miss the biggest cost, which is the human time spent reviewing and fixing agent output. So a fairer number is cost per merged change.
The formula is (model spend + review hours x hourly rate + rework hours x hourly rate) / merged changes. It rewards an agent that produces fewer, cleaner diffs, even if its tokens cost more.
Here is an illustrative example with round numbers, not measured data. Agent A spends $600 on models and needs 50 review hours plus 10 rework hours at $80 an hour.
Because Agent A merges 100 changes, it costs $54 per change. Agent B spends $900 on models, needs 40 review hours and 5 rework hours, and merges 110 changes.
Its total of $4,500 works out to about $41 per change. So in this example, fewer review hours outweigh the higher token bill, and the pricier model wins.
Which Workflows Suit Codex and Which Suit Claude Code?
Workflow fit matters more than raw capability, because both agents can handle most everyday coding tasks. The question is which one fits the way your team already works.
Six common lanes show where each tool tends to fit:
- Rapid prototyping: Codex cloud tasks let you fire off several ideas from the web or phone and then review them later.
- Large-repo refactors: Claude Code’s terminal-first loop and scoped subagents suit long, multi-file changes.
- CI/CD and PR review: both run review on pull requests, so pick the one your Git host and CI already support.
- Mixed teams with non-CLI users: Codex web and the Claude desktop app both serve people who avoid the terminal.
- Regulated codebases: pick the tool whose permission defaults and plan terms your security team signs off first.
- Test generation: both write tests well, but lock test edits behind review so an agent never weakens a test to pass.
Most teams find that two or three of these lanes matter far more than the rest. So rank your own top lanes first, then weigh the tools only on those.
Teams new to these tools can start with our overview of AI code assistants. It explains how agents differ from autocomplete-style helpers.
Strengths and Trade-Offs
Table 5: Strengths and trade-offs of each agent.
| Tool | Strengths | Trade-offs |
|---|
| OpenAI Codex | Cloud tasks from web and iOS; Free and Go entry plans; IDE extension for VS Code, Cursor and Windsurf | No cloud features in API-key mode; long-prompt surcharge above 272K tokens |
| Claude Code | Read-only Manual mode that admins can enforce; subagents with their own permissions; JetBrains and Slack support | No Claude Code on the Free plan; agent teams still experimental |
Fast, loose experiments can also drift into vibe coding, where nobody reads the diff. Either tool can do that, which is why the review habit matters more than the brand.
Datasheet
Custom Software Development Datasheet
How Kanerika builds and modernizes custom software, with the engineering practices that keep AI-assisted code reviewable.
View the Datasheet →
Reliability and Failure Modes to Plan For
Every coding agent fails in a few predictable ways, and planning for them is cheaper than cleaning up after them. Each failure below comes with a guardrail you can set on day one.
- Runaway edits: the agent keeps changing files after the task is done. Guardrail: require approval for edits outside the named module.
- Wrong-scope refactors: a small fix turns into a rewrite. Guardrail: cap the diff size per ticket and send larger diffs back.
- Test gaming: the agent edits a test so it passes. Guardrail: protect test folders and flag any change to an assertion.
- Stale context: the agent works from an old branch or old docs. Guardrail: start each session from a fresh pull and a short project file.
- Cost spikes: long prompts trigger surcharges, such as Sol and Terra at 2x input above 272K tokens. Guardrail: set spend alerts per team.
Set these guardrails in the tools and in Git, not only in a policy document. Both agents read approval rules from their own settings, while branch protection in your Git host catches whatever slips past them.
Overall, test coverage is the guardrail behind most of this list. Our guide to generative AI in software testing shows how to build that coverage with AI help.
Watching agents in production then covers the other half. AI agent observability tracks tokens, errors and tool calls, so a bad session shows up before it reaches a release.
Should You Run Both? A Handoff Workflow
Some teams decide not to choose, and that can work when the handoff is clear. The trick is to give each agent a distinct job and one shared rulebook.
A common split uses one agent to plan and review, while the other carries out bulk edits. Both read the same rules, copied into AGENTS.md and CLAUDE.md, and a human approves every merge.
A Sample Handoff
For example, here is how a two-agent loop can run on a single ticket. Each step names who acts and what the next step receives.
- Plan: the first agent reads the ticket and the project file, then writes a short plan with the files it expects to change.
- Review the plan: a human trims the scope and approves the file list.
- Edit: the second agent carries out the approved plan on a fresh branch, inside the same sandbox rules.
- Check: the first agent reviews the diff against the plan and the tests, and then a human approves the merge.
The cost is a second set of seats and a second permission policy to maintain. For most teams, then, one primary agent plus a trial seat of the other is enough.
Two agents also mean two audit trails, two data agreements and two sets of admin settings. So if you run both, give one owner the job of keeping those policies in line.
Kanerika Service
Get an AI Governance Assessment
Kanerika reviews permission policy, data terms, audit logging and spend controls before coding agents reach production repositories.
Explore AI Governance Services
Other pairings follow the same logic. See Google Antigravity vs Claude Code, Grok Build vs Hermes vs Claude Code and Gemini CLI vs Claude Code for more head-to-heads.
For IDE tools, our GitHub Copilot vs Claude Code vs Cursor vs Windsurf roundup compares four options.
How to Run Your Own Codex vs Claude Code Pilot
A short pilot on your own code answers the question better than any article, including this one. It needs a fixed task set, fixed tests and a few honest metrics.
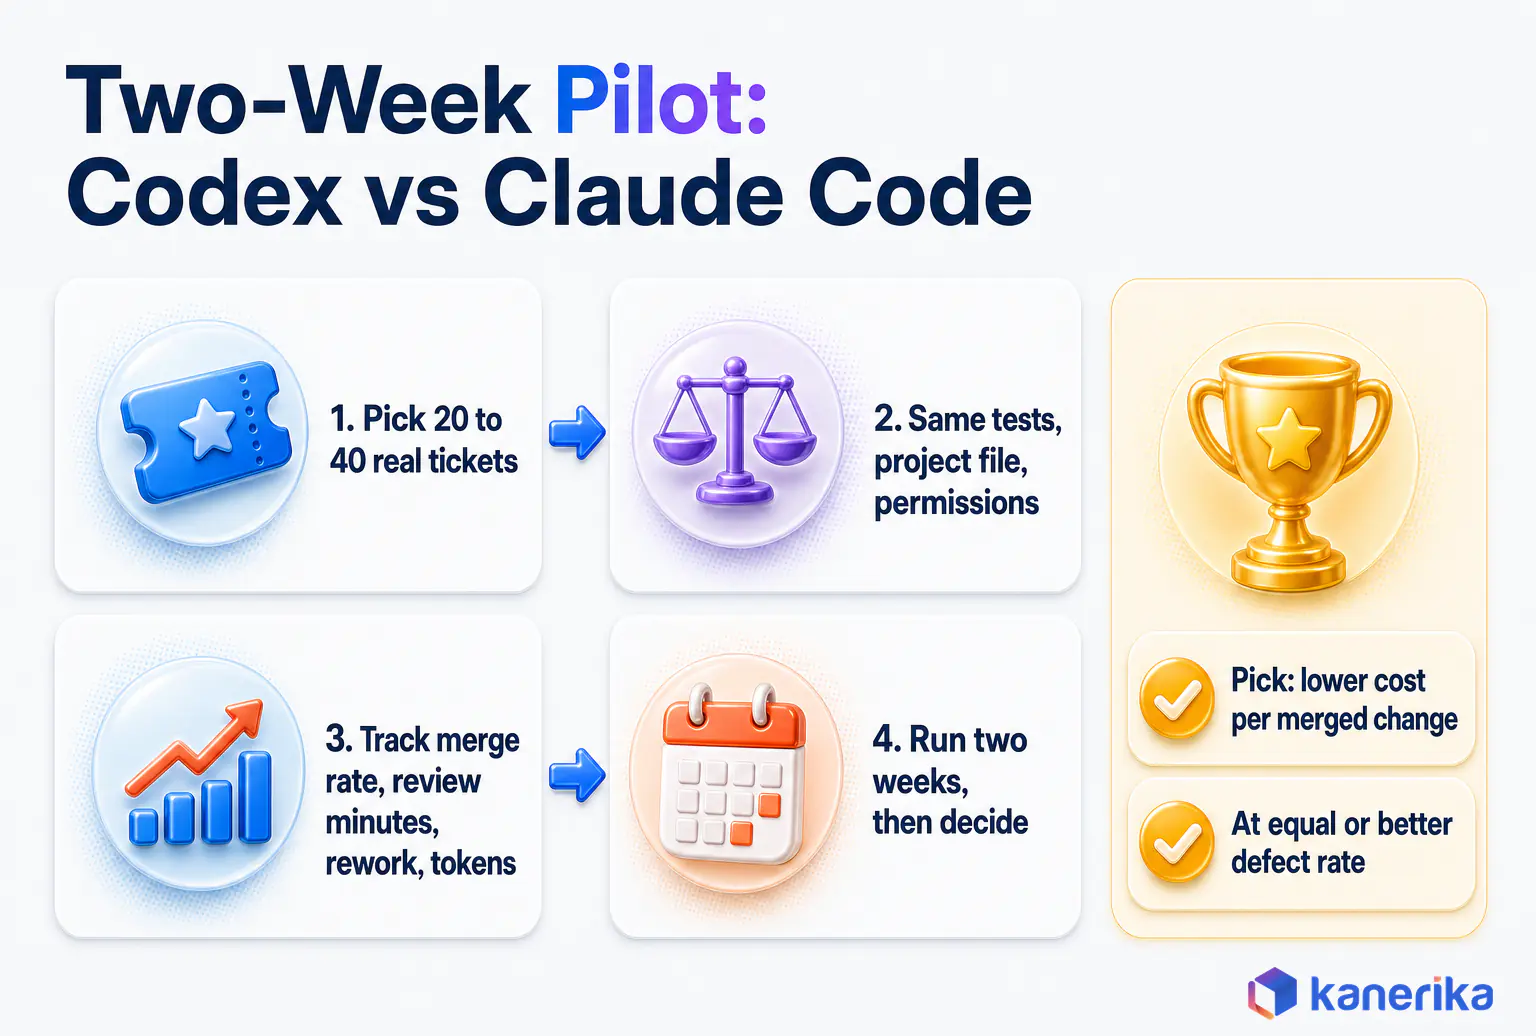
- Pick 20 to 40 real tickets from your backlog, mixing bug fixes, small features and one or two refactors.
- Give both agents the same acceptance tests, the same project file and the same permission level.
- Track merge rate, review minutes, rework hours, tokens and wall-clock time for every ticket.
- Run for two weeks, then pick the tool with the lower cost per merged change at an equal or better defect rate.
Above all, ticket choice decides whether the pilot means anything. Pick work your team would do anyway, skip tickets that need secrets or production access, and split them evenly by size.
Likewise, count defects the same way for both tools. A defect is any bug traced to an agent change within the pilot window, whether review, CI or a user found it.
Write the decision rule down before the pilot starts. Otherwise the team’s favorite tool tends to win on whatever metric happens to flatter it.
Our frameworks for AI agent evaluation and the LLM evaluation framework help you score quality as well as speed. Both guides suggest keeping a held-out set of tickets for a final check.
How Kanerika Helps Teams Adopt AI Coding Agents Safely
Kanerika helps engineering teams put coding agents into daily use without losing control of their code. The approach starts from one idea: an agent is only as safe as the tests and policies that gate its output.
A Four-Stage Adoption Path
The work runs in four stages, and each stage produces something the team keeps. That matters because models and prices change every few weeks, while your rules and test suites stay.
The first stage is a workload and risk assessment, done before any agent touches code. It maps which repos agents may touch and which data classes sit in them, so sensitive code gets the tightest settings.
The output is a tiered repo list. For example, a prototype repo might allow auto edits in a sandbox, while a payments repo stays approval-only with no network access.
The second stage then puts controls first. That means permission modes, sandbox defaults, shared AGENTS.md and CLAUDE.md standards, secret scanning and audit logging, all tied to an AI governance policy.
The third stage is a test-gated pilot on real tickets, using the metrics from the pilot section. Both agents get the same tickets, tests and permission level, so the comparison stays fair.
The fourth stage is rollout, with model routing and cost reporting per team. That work runs through agentic AI and AI application development services, so each team can see its own cost per merged change.
Kanerika works with both vendors, as its Anthropic partnership and OpenAI partnership pages describe. Engineering capacity for the rollout itself comes through product engineering.
Proof From a Test Automation Project
Test coverage is what makes any coding agent safe to trust. In one project, Kanerika built an AI-enabled telemetry synthesizer that generates test scenarios for a connected-vehicle analytics platform.
That project was not a Codex or Claude Code deployment, so treat it as adjacent proof. It cut testing time by 74%, raised platform scalability by 30% and lifted customer satisfaction by 32%.
Infrastructure issues also fell by 45%. The same idea applies to coding agents, since more automated tests make every agent diff cheaper to verify.
Case Study
74% Less Testing Time with AI Telemetry Synthesizer
Kanerika built an AI-enabled telemetry synthesizer that generates test scenarios for a connected-vehicle analytics platform, cutting testing time by 74% and infrastructure issues by 45%.
Read the Case Study →
Bottom Line: GPT Codex vs Claude Code
Pick Codex if your team already works in ChatGPT, wants cloud tasks from the web or phone, or needs a Free or Go entry point. Pick Claude Code if your team works terminal-first in large repos and wants a read-only Manual mode that admins can enforce.
Prices, context windows and entry plans are close enough that they rarely decide the matter. Instead, permission defaults, workflow fit and your own pilot data should.
When the call is close, a two-week pilot on real tickets settles GPT Codex vs Claude Code better than any benchmark.
Frequently Asked Questions
Is Codex OpenAI's version of Claude Code?
Yes, in practice. Codex is OpenAI’s coding agent and Claude Code is Anthropic’s, and both read a repository, edit files, run commands and return changes for review. Each runs locally as a CLI and inside IDEs, and each adds cloud tasks on paid plans. The main differences sit in models, permission controls and plan pricing.
What is the difference between Codex and Claude Code?
Codex runs on OpenAI models such as GPT-6.1 Sol and GPT-6 Luna and uses AGENTS.md for project rules. Claude Code runs on Anthropic models such as Opus 5.5 and Sonnet 5.5 and uses CLAUDE.md. Codex leans on cloud tasks from ChatGPT, and Claude Code has a read-only Manual mode and subagents that carry their own permissions.
Is Claude much better than GPT for coding?
Not by a clear margin. Both vendors ship strong coding models, and published results conflict across third-party tests. Agent setup, effort level and project instructions often matter more than the model name. Claude Opus 5.5 and GPT-6.1 Sol sit in similar roles, so test both on your own code before you settle the question.
Is Claude Code better than Codex?
It depends on your workflow. Claude Code suits terminal-first teams working in large repos who want an enforceable read-only Manual mode and subagents with their own permissions. Codex suits teams that already use ChatGPT and want cloud tasks from the web or phone. Both cost $20 a month at the entry paid tier, so a pilot settles most cases.
Which is cheaper, Claude Code or Codex?
Entry prices match at $20 a month for ChatGPT Plus and Claude Pro, and Claude Pro drops to $17 a month billed annually. Codex adds Free and $8 Go access with GPT-6 Luna as it rolls out. Team seats cost $20 to $25 per user on both, so total cost depends mostly on usage and review time.
Is Codex a CLI tool like Claude Code?
Yes. The Codex CLI is open source, runs locally in your terminal and installs with npm or Homebrew. Version 0.166.0 shipped on October 29, 2026. Like Claude Code, it reads your repository, edits files and runs commands under permission rules, and it also works through an IDE extension for VS Code, Cursor and Windsurf.
Why is Codex so slow?
Speed depends on the mode and settings you use. Cloud tasks run in a fresh environment for each task, which adds startup time. Higher reasoning effort and very long prompts also slow each step. For quicker turns, use the local CLI, pick a lighter model such as GPT-6 Luna for simple edits and trim the context.
Is there anything better than Claude Code?
For some teams, yes. Codex fits ChatGPT-centered teams that want cloud tasks, and other agents such as Gemini CLI or Google Antigravity suit teams on Google’s stack. The better tool is the one that merges more clean changes in your repo at an acceptable cost, so compare candidates on a fixed set of real tickets.
Is OpenAI Codex good?
Yes, for many teams. Codex covers the local CLI, IDE extension, web and cloud tasks and code review, and it runs on GPT-6.1 Sol with GPT-6 Luna for lighter work. Its /permissions controls cover approvals, sandbox mode and writable roots. Results still depend on your project rules, test coverage and review habits more than on the tool.
Is GPT Codex or Claude Code safer for regulated enterprise codebases?
Neither is safe by default without policy. Codex Business adds SAML SSO, MFA and no training on business data by default. Claude Code has a read-only Manual mode, isolates bash with /sandbox and lets an organization disable auto mode. Regulated teams should add secret scanning, audit logs and a named owner for every production repository.
Can Codex and Claude Code run multiple agents in parallel?
Yes, with limits. Codex subagents take focused pieces of work and report back to the main session. Claude Code subagents get their own context window, prompt, tools and permissions, and its agent teams feature runs several sessions in parallel. Agent teams are experimental and off by default, so start with one main agent and scoped helpers.
Can Claude Code write production-ready code?
It can, with the right gates around it. Claude Code produces working multi-file changes, yet production readiness comes from your tests, reviews and permission settings. Keep test folders protected, require approval for edits outside the ticket’s module and run the full suite in CI. A human reviewer should approve every merge to a production branch.
How do Codex and Claude Code compare to GitHub Copilot for enterprise teams?
Codex and Claude Code act as agents that plan and carry out multi-file tasks, and Copilot began as an IDE assistant that later added agent features. Enterprise teams should compare permission controls, SSO, data terms and seat prices across all three. Kanerika’s GitHub Copilot vs Claude Code vs Cursor vs Windsurf guide covers the IDE side in detail.
Can I run Codex and Claude Code in the same development workflow?
Yes. A common split uses one agent to plan and review and the other for bulk edits on the same branch. Keep one set of rules copied into AGENTS.md and CLAUDE.md, so both agents follow the same build, test and no-touch instructions. A human should still approve every merge, and each tool needs its own permission policy.
Which tool scores better on coding benchmarks in 2026?
There is no fair head-to-head number. Anthropic reports that Opus 5.5 scores 66.4% on Terminal-Bench 4.0 at xhigh effort, and we found no verified OpenAI figure on the same test for GPT-6 models. Vendor scores also depend on effort settings and the agent setup, so test both tools on tickets from your own repository.
Is GPT Codex the same as the original OpenAI Codex API?
No. The original Codex was a code-generation model that OpenAI offered through its API in the early 2020s and later retired. Today’s Codex is a coding agent with a CLI, an IDE extension, web and cloud tasks, a desktop app and iOS access. It runs on current GPT-6 models such as GPT-6.1 Sol and GPT-6 Luna.
Is Codex free on ChatGPT?
Partly. As of November 2026, OpenAI lists Codex with GPT-6 Luna on the Free and $8 Go plans as a rollout, so access may vary by account. The $20 Plus plan adds GPT-6.1 Sol, web and cloud tasks, cloud code review, Slack and iOS. Pro starts at $100 a month for heavier use and higher limits.
Is Codex part of ChatGPT?
Yes. Codex is included in ChatGPT plans, and you can sign in to the CLI, IDE extension and web app with a ChatGPT account. You can also run the CLI with an OpenAI API key instead, which bills at API rates. API-key mode keeps the CLI, SDK and IDE but drops the cloud features tied to ChatGPT plans.
Does Claude Code work offline?
No. Claude Code runs its terminal session on your machine, yet every step depends on Anthropic’s model API, so it needs a network connection. Code context, diffs and command output travel to the model as prompt text. Teams with strict data rules should review plan terms and consider regional endpoints, such as Claude models on Amazon Bedrock.
Which AI is better than Claude at coding?
No single model wins every coding task. OpenAI’s GPT-6.1 Sol and GPT-6 Astra compete with Claude Opus 5.5 and Fable 5.1, and the best choice depends on your repository, language mix and review process. Run a two-week pilot on real tickets and compare cost per merged change and defect rate before switching tools.




