TL;DR
In the Databricks vs AWS decision, pick Databricks on AWS when engineers, analysts and data scientists share the same data. Pick AWS’s own services when your team works mostly in SQL and only on AWS. Databricks runs inside your AWS account and reads the same S3 buckets as AWS’s own services.
Both keep data in your S3, so the difference is the layer above it. Databricks charges for its platform on top of your AWS bill, while AWS charges for each service on its own. Compare costs over one and three years on your own workloads, and run both only when one job clearly needs it.
Key Takeaways
- Databricks runs on AWS, so the real choice is Databricks on AWS versus an AWS-native stack.
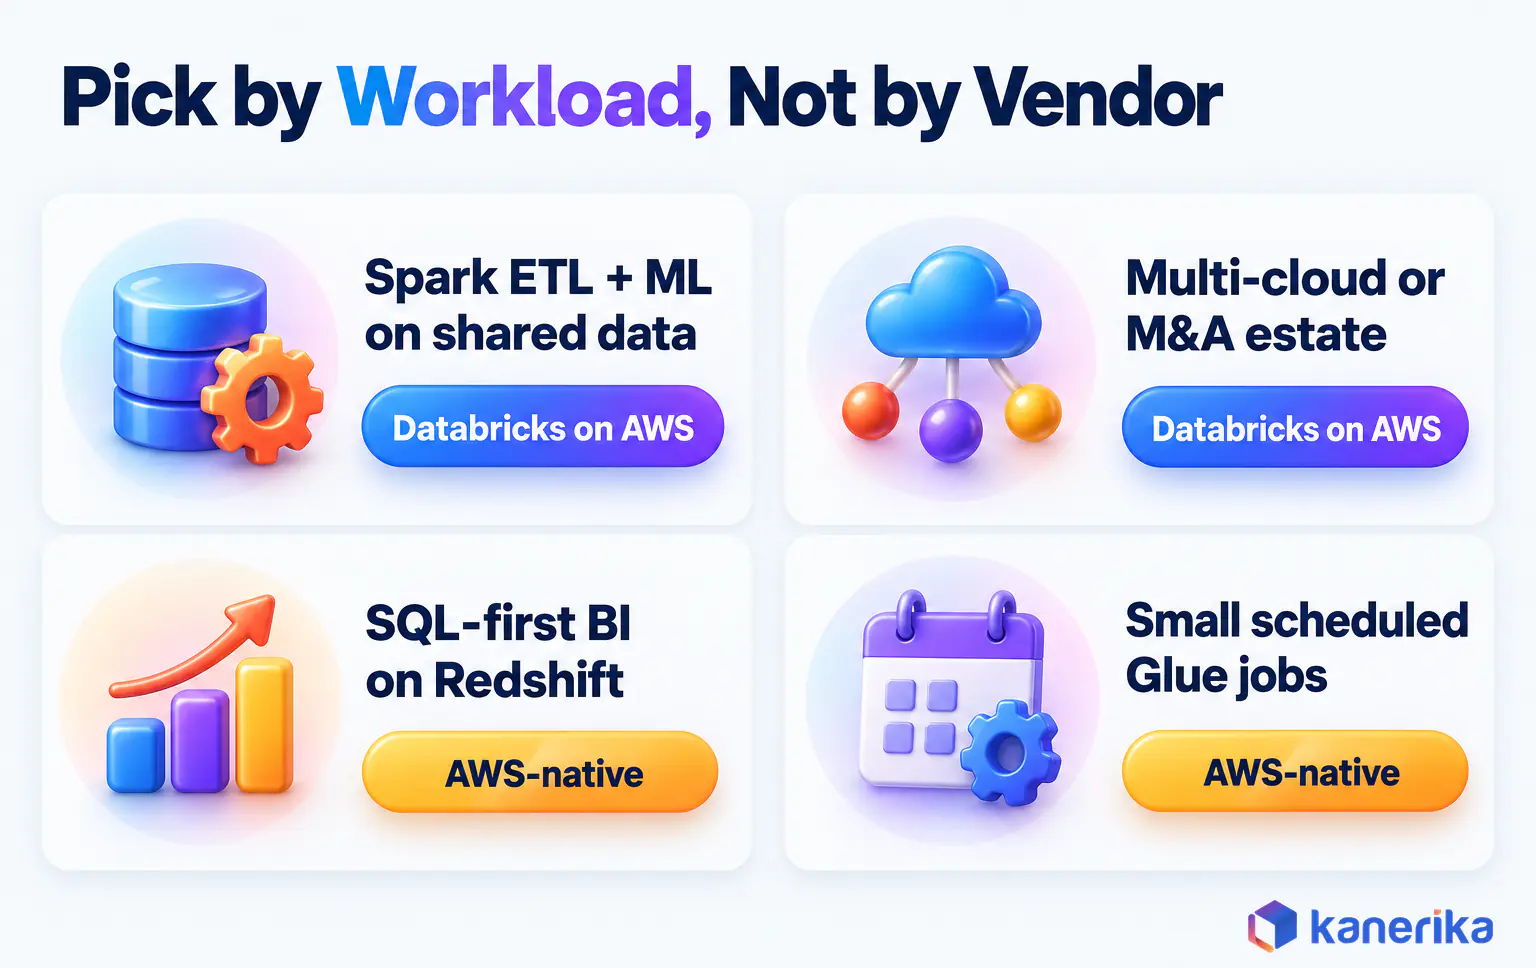
- Pick Databricks on AWS when data engineering, SQL and machine learning teams share the same data and need one catalog.
- Pick AWS-native services when the work is mostly SQL on Redshift or small Glue jobs and the team already knows AWS well.
- As of October 2026, both sides store open table formats on S3, such as Delta Lake with UniForm Iceberg reads or Iceberg in S3 Tables.
- Compare total cost over 12 and 36 months, because the AWS infrastructure under Databricks, egress and engineering time all count.
- A mix works when each tool keeps a named job, such as Redshift for existing BI and SageMaker for model serving.
A Platform Review Where Everything Already Runs on AWS
Imagine a retailer whose data already sits in Amazon S3. The data engineering lead runs nightly Glue jobs, and the analytics team lives in Redshift. A new data science group wants notebooks, feature tables and a model registry.
Then a Databricks quote lands on the table, and the question sounds simple: Databricks or AWS?
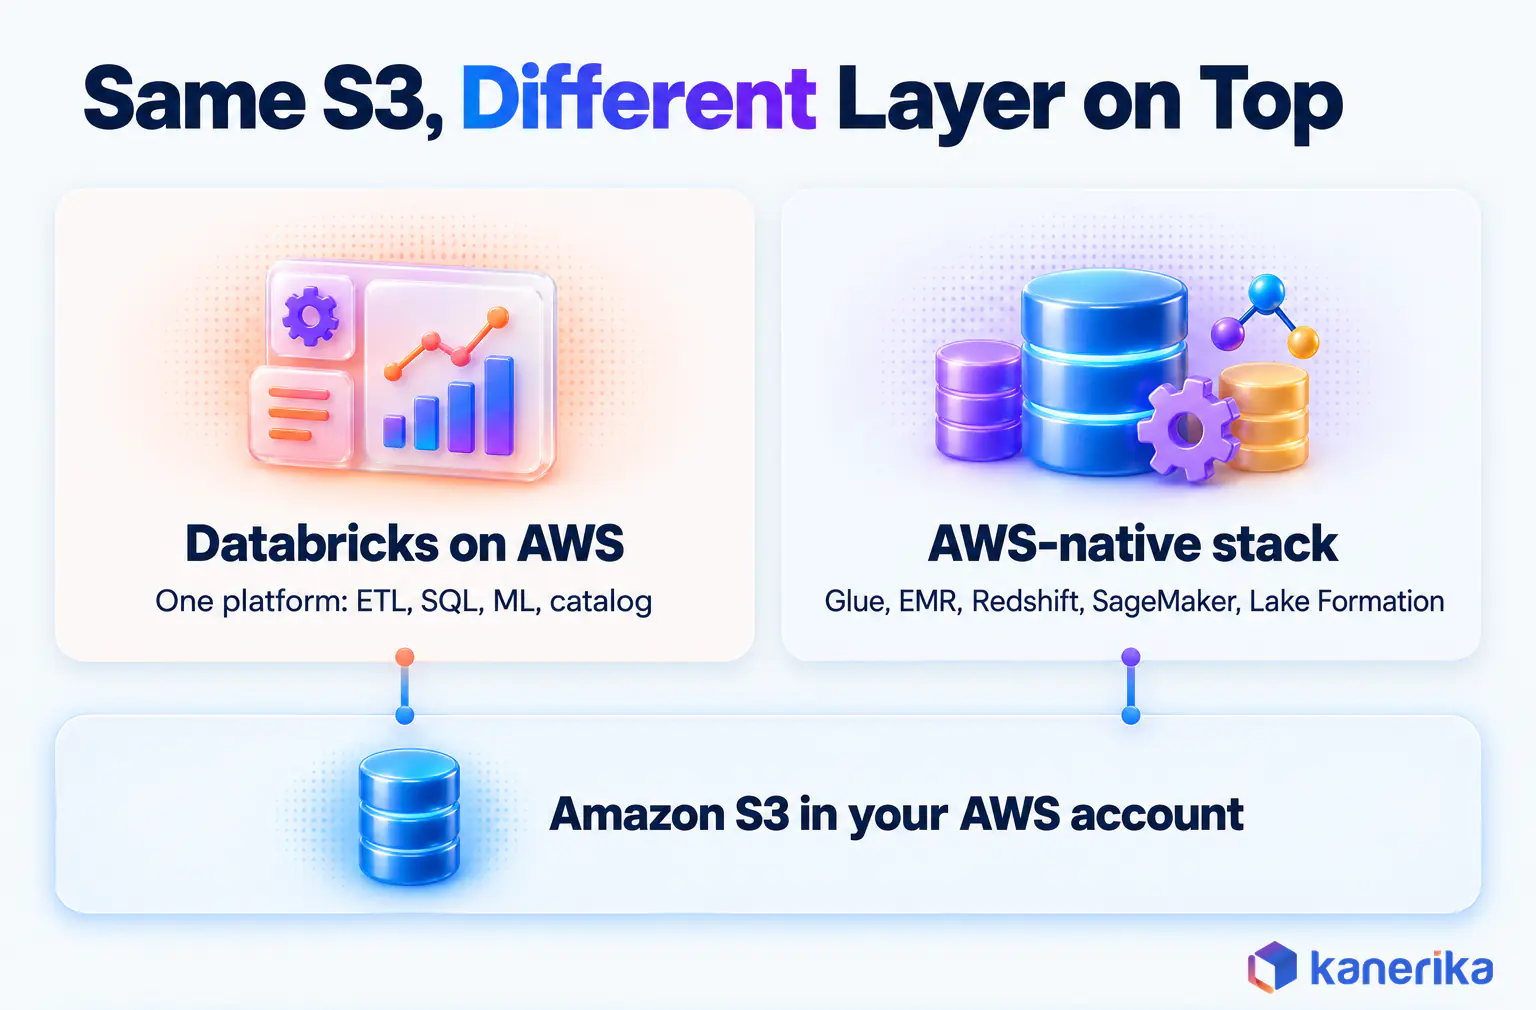
Nobody is proposing to leave AWS. The Databricks workspace would run in the same AWS account, read the same S3 buckets and sit behind the same IAM roles. What is really open is how many tools sit between the data and its users.
This guide compares the Databricks vs AWS choice layer by layer, using vendor prices and product facts. It ends with a scorecard for your own workloads.
Databricks vs AWS Is Really Databricks on AWS vs an AWS-Native Stack
Databricks runs on top of AWS, so the two names describe different layers of the same stack. It is a data and AI platform from the company that created Apache Spark, Delta Lake, MLflow and Unity Catalog. According to its company page, checked in October 2026, more than 20,000 organizations use it, including 70% of the Fortune 500.
What Runs in Your AWS Account
The Databricks architecture documentation splits the product into two planes. The control plane holds the backend services that Databricks manages. Classic compute, by contrast, runs in a compute plane inside your own AWS account, and the workspace storage bucket lives there too.
Serverless compute is the one exception, since it runs in a serverless compute plane inside your Databricks account. With classic compute, both the clusters and the data stay in an account you control. Our guide to Databricks lakehouse architecture explains the two planes in more depth.
An AWS-native stack takes the opposite approach. You assemble managed services instead of one platform, such as Glue or EMR for Spark and Redshift or Athena for SQL. SageMaker then covers machine learning, while Lake Formation and IAM handle access.
Both options keep the data in Amazon S3, so storage is not the battleground. The decision is about the layer above S3, which is either one platform or a set of AWS services you wire together. If the lakehouse idea behind that layer is new, our guide to data lake vs lakehouse explains it before you compare vendors.
Kanerika Service
Databricks Consulting and Implementation
Kanerika plans, builds and migrates Databricks workspaces on AWS, from Unity Catalog design to Spark pipelines and Model Serving, so one platform covers engineering, SQL and ML.
Explore Databricks Services
If your organization has not settled on AWS yet, start a level higher with AWS vs Azure vs Google Cloud. Databricks also runs on Azure and Google Cloud, which matters later when we look at lock-in.
Databricks vs AWS at a Glance
The fastest way to see the gap is to put the same twelve questions to each option. Each row describes what you would actually run, rather than a marketing tier.
| Question | Databricks on AWS | AWS-native stack |
|---|
| Platform shape | One platform for ETL, SQL, ML and governance | Separate managed services joined by S3 and IAM |
| Storage and table format | Delta Lake on S3, with UniForm for Iceberg reads | S3, with S3 Tables for managed Apache Iceberg |
| ETL engine | Apache Spark through Lakeflow and Jobs | AWS Glue (serverless Spark) and Amazon EMR |
| SQL engine | Databricks SQL warehouses | Amazon Redshift (Provisioned or Serverless) and Athena |
| ML and GenAI | MLflow and Model Serving endpoints | SageMaker AI, SageMaker Unified Studio and Amazon Bedrock |
| Governance catalog | Unity Catalog for tables, files and models | IAM, Lake Formation and SageMaker Catalog |
| Open source base | Spark, Delta Lake, MLflow, Unity Catalog | Spark inside Glue and EMR; Iceberg inside S3 Tables |
| Cloud reach | AWS, Azure and Google Cloud | AWS only |
| Billing unit | Databricks DBUs billed per second, plus AWS infrastructure under classic compute | Per service, such as Glue DPU-hours, EMR seconds plus EC2, Redshift hourly rates and S3 |
| Ops burden | One workspace and one catalog to administer | Several services to connect, secure and monitor |
| Best-fit team | Engineers, analysts and data scientists sharing data | SQL-centred teams fluent in AWS services |
| Typical first workload | Spark ETL that feeds ML features | Redshift BI or scheduled Glue jobs |
The pattern is consistent across rows. Databricks on AWS trades service choice for one place to work, while the AWS-native route trades that single place for finer control over each piece.
Talk to Kanerika
Not Sure Which Side Your Workloads Favor?
Bring one pipeline, one BI query set and your current AWS bill. Kanerika will sketch Databricks on AWS and an AWS-native design side by side, with costs and skills for each.
Talk to a Data Expert →
How the Two Approaches Differ, Layer by Layer
A data platform is easier to compare when you break it into the jobs it does. The five layers below follow the path data takes, from files on S3 to governed models in production.
Watch two things as you read: storage is where the two options converge, while governance and ML are where they split most.
Storage and Open Table Formats
Every table in either option ends up as files in S3, so the real question is the table format on top. Databricks writes Delta Lake by default. Its UniForm feature also generates Iceberg metadata alongside the Delta metadata, so Iceberg readers can query the same table.
AWS has moved toward Iceberg as well. Amazon S3 Tables are fully managed Apache Iceberg tables stored in S3, and AWS engines such as Athena can query them directly.
An orders table written by a Databricks pipeline shows how this works. Once UniForm is on, an Iceberg-aware AWS engine can read it without a copy. That is why storage lock-in is lower than it was a few years ago.
| Storage need | Databricks on AWS | AWS-native stack |
|---|
| Default table format | Delta Lake | Apache Iceberg (S3 Tables) or plain Parquet files |
| Reads from other engines | Iceberg readers through UniForm | Any Iceberg-compatible engine |
| Where the files live | S3 bucket in your AWS account | S3 bucket in your AWS account |
Data Engineering and ETL
ETL is where most teams feel the difference first, because it is the work they run every night. On Databricks, pipelines are Spark code or SQL scheduled through Lakeflow and Jobs. Notebooks, tables and job runs sit in one workspace, so an engineer can debug a failed run next to the data it touched. On either side, the data pipeline architecture you choose sets how much of that work runs as batch or streaming.
On AWS, the default Spark service is Glue. You submit a job, then Glue provisions the workers and charges an hourly rate per DPU-hour. AWS Glue pricing bills those hours per second, with a one-minute minimum on Glue 2.0 and later. That model suits small, scheduled jobs because they start, finish and stop paying.
Amazon EMR covers the heavier end. EMR pricing is per second with a one-minute minimum, while clusters run on EC2, EKS, Outposts or EMR Serverless. EMR gives you open-source Spark with full control over versions and instances, but the tuning work stays with your team. When the engine is the whole question, our Databricks vs EMR comparison goes deeper on that head-to-head.
Scale makes the difference concrete. Ten small Glue jobs that each move one table are cheap and easy to own. Two hundred jobs that share feature logic with a data science team are a different matter, because they are easier to run in one workspace.
Kanerika Service
Data Engineering Services
Whether your pipelines run on Glue, EMR or Databricks, Kanerika designs, builds and tunes them, with tested loads, clear ownership and costs you can track per job.
Explore Data Engineering
SQL Analytics and Warehousing
SQL analytics is the layer where AWS has the deepest bench. Amazon Redshift comes in Provisioned and Serverless forms, while Athena runs serverless SQL directly over files in S3. That depth means a team with years of Redshift dashboards, stored procedures and BI tuning has a real asset to protect.
Databricks answers with Databricks SQL warehouses that query Delta tables in place. The selling point is not raw speed on one benchmark. Instead, analysts query the same governed tables the engineers built, with no load into a separate warehouse.
Start with a finance team that has a few hundred Redshift dashboards and the stored procedures behind them. That estate pulls toward staying AWS-native, because moving it means rewriting and retesting reports that already work.
Now add analysts who need the same customer and order tables the ML team trains on. That need pulls toward Databricks SQL, since both groups would query one governed copy instead of keeping two in sync. When both groups exist, ask which one most of the next three years of growth will come from.
The data model matters on either side, because the dimensional design decides join cost on Redshift and Databricks SQL alike. Choosing between a star schema or snowflake schema sets how many joins each dashboard query has to run.
Machine Learning and GenAI
Machine learning is the layer where the two options look most different on paper. Databricks pairs MLflow for tracking and registry with Model Serving, which deploys, governs and queries models for real-time and batch inference. Each served model is then exposed as a REST API.
AWS has rebuilt its ML story around the next generation of Amazon SageMaker. AWS calls it “the center for all your data, analytics, and AI” on its product page. It brings together SageMaker AI for model building, SageMaker Unified Studio as a shared workspace and SageMaker Catalog. For generative AI apps, Amazon Bedrock also gives managed access to foundation models.
The two sides connect, too. The mlflow.sagemaker module deploys MLflow models to SageMaker. Because of that link, a team can train and track in Databricks, then serve on SageMaker endpoints where its apps already run. Our Databricks vs SageMaker comparison goes deeper on the ML layer alone.
In practice, the ML choice usually follows the people. A data science group that wants features, experiments and serving next to its Spark data leans toward Databricks. An app team building on Bedrock with little custom training leans toward AWS.
Watch on YouTube
Databricks Summit 2026 Recap: LTAP, Genie Ontology & Unity AI Gateway
Kanerika walks through what Databricks announced at its 2026 summit, from Genie and LTAP to the Unity AI Gateway, and what it means for teams running ML and GenAI on the platform.
Governance and Security
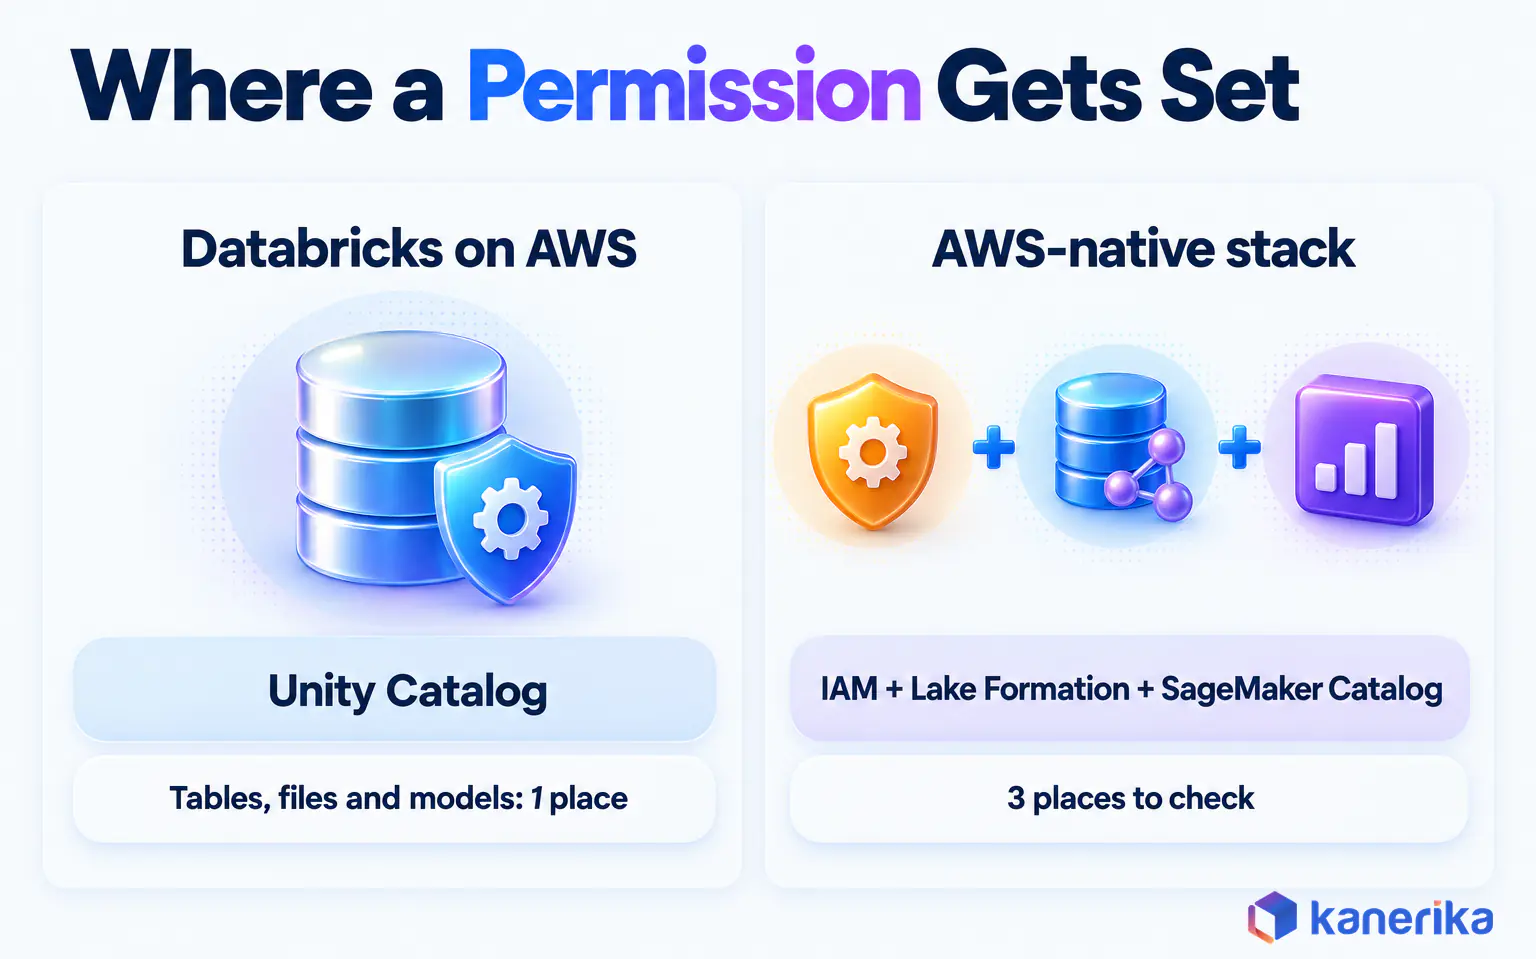
Governance decides how many places a permission has to be set, and that number drives audit effort. Databricks puts tables, files and models under Unity Catalog. It open-sourced Unity Catalog on June 13, 2024 under Apache 2.0. The project is hosted at LF AI & Data and is also compatible with the Iceberg REST catalog API.
On AWS, access starts with IAM. AWS Lake Formation then adds fine-grained access control for data lake data on S3, with a permissions model that augments IAM. SageMaker Catalog, built on Amazon DataZone, also adds business metadata for the SageMaker workspace. For the wider market, see our roundup of data catalog tools.
| Governance need | Databricks on AWS | AWS-native stack |
|---|
| Where policies live | Unity Catalog grants | IAM policies plus Lake Formation permissions |
| What one catalog covers | Tables, files and models | Lake Formation for S3 data, while SageMaker assets sit separately |
| Business catalog | Unity Catalog | SageMaker Catalog on Amazon DataZone |
| Open source status | Unity Catalog OSS, Apache 2.0 | Managed AWS services |
Security and Compliance Controls
Security and compliance follow the same split as governance. On Databricks, regulated workloads run under the compliance security profile, which adds a hardened compute image, monitoring agents and enforced AWS Nitro instance types. Its listed standards include HIPAA, PCI-DSS, HITRUST and FedRAMP Moderate and High. The profile is billed as the Enhanced Security and Compliance add-on, and HIPAA work needs a BAA with Databricks first.
Network isolation works through AWS PrivateLink, so classic compute can reach the Databricks relay and AWS services over private endpoints. On the AWS-native side, compliance is scoped service by service. The Lake Formation security page, for example, points to the AWS Services in Scope by Compliance Program list under the shared responsibility model. An audit therefore checks Glue, Redshift, Lake Formation and SageMaker against the standard one at a time.
Suppose an auditor asks who can read a customer table and the churn model trained on it. In Databricks, both answers come from Unity Catalog. On the AWS-native side, the table answer sits in Lake Formation and IAM while the model answer sits with SageMaker. Our comparison of Unity Catalog, Purview and Collibra covers catalog depth if governance is your main driver.
Databricks vs AWS Pricing: How the Bills Differ
Pricing is where most comparisons go wrong, because the two bills are built from different units. A side-by-side of list prices therefore tells you little until you know which units your workloads consume.
What a Databricks on AWS Bill Contains
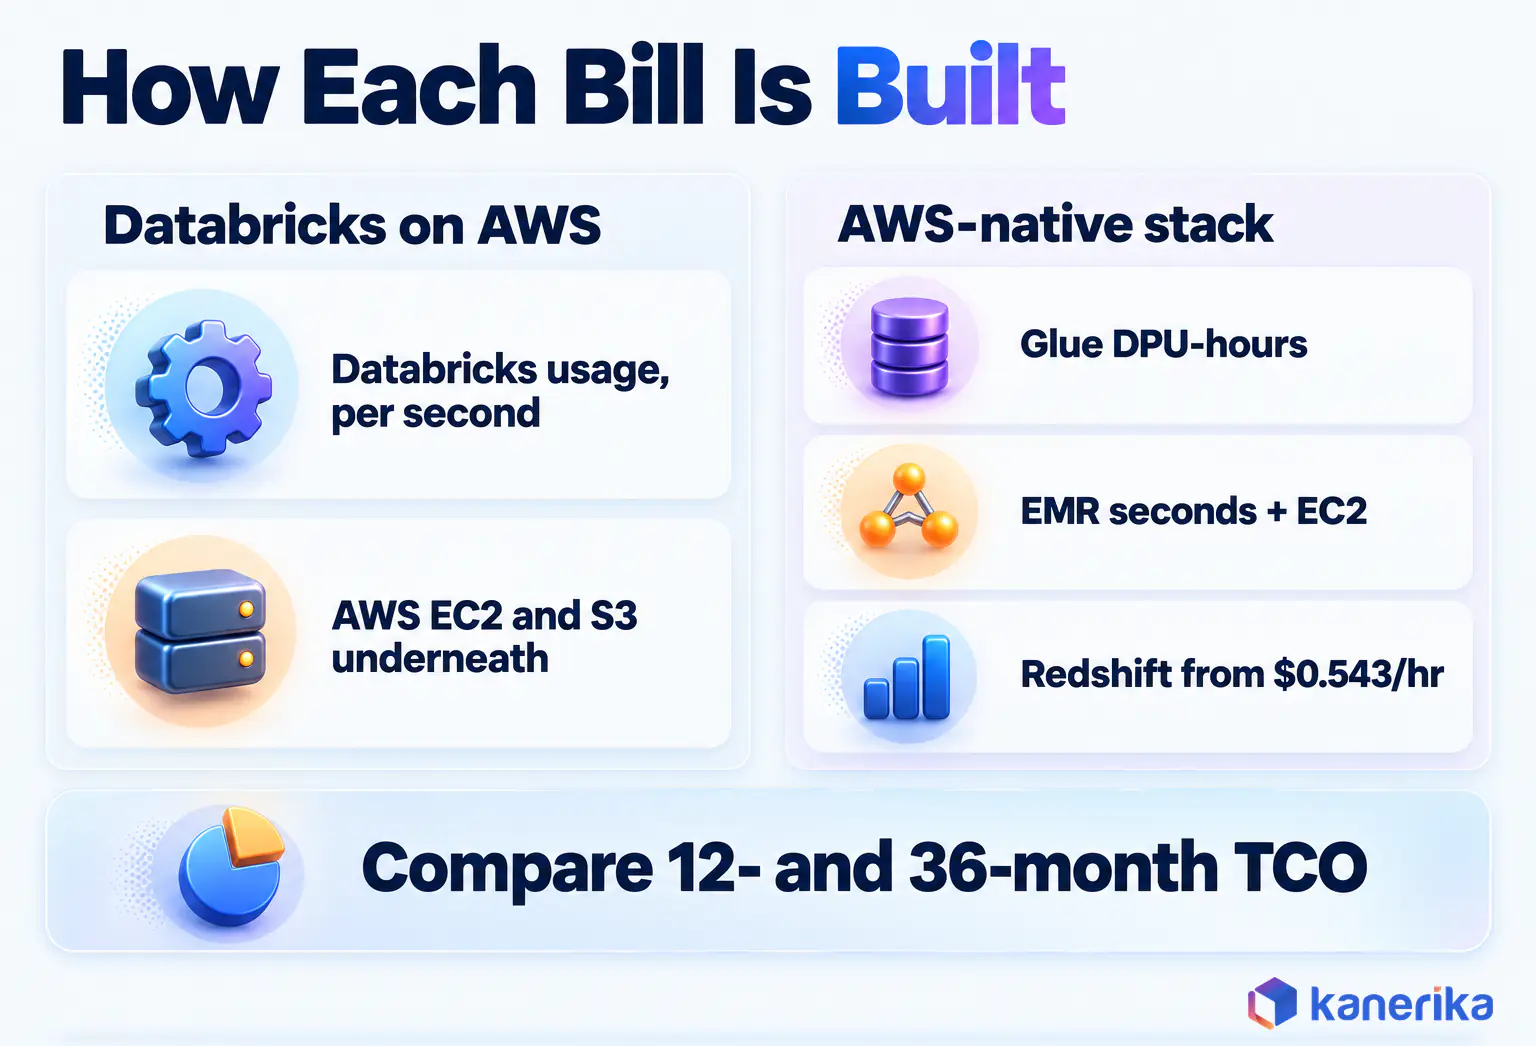
Databricks on AWS pricing is pay-as-you-go per second, with committed-use discounts and no up-front cost. Its billing unit is the DBU, or Databricks Unit, which Databricks defines as a normalized unit of processing power.
Each workload’s DBUs are recorded against a SKU, such as STANDARD_ALL_PURPOSE_COMPUTE, whose name pairs the plan tier with the compute type. The Databricks price list sets an undiscounted price for each SKU, so the DBU rate depends on the tier and compute type behind each workload. With classic compute, you also pay AWS for the EC2 instances and S3 storage underneath, since they run in your account.
Serverless compute runs in the Databricks account, so that part of the infrastructure is not on your AWS bill. An AWS Marketplace account can also serve as a Databricks payment method, which helps teams that buy through committed AWS spend.
What an AWS-Native Bill Contains
The AWS-native bill is a list of separate services. Glue charges per DPU-hour, while EMR charges per second plus the EC2 it runs on. Redshift pricing starts at $0.543 per hour for Provisioned clusters and $1.50 per hour for Serverless. Redshift Serverless bills per second, so you pay nothing while it sits idle.
| Workload | Databricks on AWS bills | AWS-native stack bills |
|---|
| Batch ETL | Databricks usage per second, plus EC2 for classic compute | Glue DPU-hours, or EMR seconds plus EC2 |
| BI and SQL | Databricks SQL warehouse usage | Redshift from $0.543/hr Provisioned or $1.50/hr Serverless |
| ML training and serving | Databricks compute and Model Serving usage | SageMaker instance and endpoint charges |
| Storage | S3 in your account | S3 in your account, or S3 Tables |
A Simple Way to Compare Total Cost
We have not printed a monthly total here on purpose, because any single number depends on job length, cluster size, discounts and data volume. A short total cost of ownership exercise gives a better answer than a borrowed figure.
- Pull 30 to 90 days of real workload data, such as job runtimes, query counts, data volumes and peak concurrency.
- Split the estate into ETL, SQL and ML, because each maps to a different line on each bill.
- Price each slice on both options, using your own discounts and committed-use terms.
- Add storage, data transfer and egress, since list-price comparisons often leave them out.
- Add engineering time for operations, upgrades and integration between services.
- Model the result at 12 months and at 36 months, because migration cost falls in year one.
Once the numbers are in, the decision often rests less on price and more on the operating model and the skills on hand.
Skills, Operations and Lock-In
Every platform asks something of the people who run it, but the two options ask for different things. Databricks on AWS needs Spark, SQL and Python skills, as well as someone who owns workspace setup, compute settings and Unity Catalog. Day-to-day work then happens in one place, which shortens onboarding for new engineers.
An AWS-native stack needs depth across several services instead. Someone has to know Glue job tuning, Redshift workload management, IAM and Lake Formation, and also how they fit together. Teams that already hold AWS certifications and run infrastructure as code often find that natural. Each service also has its own release notes and limits, so upgrades need a plan per service.
Upgrades show the day-two gap most clearly. On Databricks, the main track is one release line, the Databricks Runtime, which clusters and jobs draw from. An AWS-native team follows three tracks instead: Glue versions on each job, EMR release labels on each cluster and Redshift maintenance windows. Cluster sizing is the other recurring Databricks task, which our Databricks performance optimization guide covers.
Where Lock-In Sits on Each Side
Lock-in exists on both sides, just in different places. With AWS-native services, it sits in service-specific APIs, job definitions and Redshift features. Iceberg tables in S3 soften it, since other engines can read them. A later move off Redshift, though, usually means reworking stored procedures and workload settings as well.
With Databricks, you commit to a platform and often a usage contract. Open formats like Delta and Iceberg soften that commitment too, and so does the option to run on Azure or Google Cloud. Paying through an AWS Marketplace account lowers the contract barrier, but it does not reduce the dependence on the platform itself.
When Azure is part of your plans, our Microsoft Fabric vs Databricks guide covers the same decision on the Microsoft side. For a warehouse-first alternative, see Databricks vs Snowflake.
Migration Paths in Each Direction
A migration path matters as much as the destination, because it decides how long two stacks run side by side. Moving toward Databricks usually starts with code you already have. The Databricks migration guide says existing Spark ETL jobs move in a few steps, and SQL or Hive workloads need minimal refactoring.
For legacy SQL in dialects such as T-SQL, Snowflake and Oracle, Databricks points to its agentic code converter. Our guide to legacy systems to Databricks migration covers the sequencing in more detail.
The reverse path runs through AWS tooling. The AWS Schema Conversion Tool converts an existing database or data warehouse schema for targets such as an Amazon Redshift cluster. Either way, move one workload at a time and keep the old path running until the new one matches its outputs.
Datasheet
Databricks Funding Support Through Kanerika
See the funding routes for Databricks projects, such as DCIF and Marketplace transactions, and how Kanerika helps identify eligible projects and structure the proposal.
Get the Datasheet →
When to Choose Databricks on AWS
Databricks on AWS earns its place when the same data feeds several kinds of work at once. In these situations, one platform pays for its extra line on the bill.
- Mixed ETL and ML on shared data. Engineers build tables, and then data scientists train on the same tables without copies or exports.
- Many teams working in notebooks. A shared workspace with one catalog keeps code, data and permissions in step as headcount grows.
- Multi-cloud or merger estates. An acquired business on Azure or Google Cloud can join the same platform pattern and governance model.
- One catalog across data and models. Unity Catalog answers who can see a table and who can call a model, all from one place.
- Streaming plus batch on one engine. Spark handles both, so a team does not maintain two code paths for the same logic.
If several of these describe your estate, Databricks on AWS will usually reduce the number of moving parts. That is the core case for a unified data platform. For a view beyond AWS, our overview of how Databricks compares with other data platforms covers the wider field.
When an AWS-Native Stack Is the Better Fit
An AWS-native stack wins when the work is narrower and the team already knows the services. In those cases, a separate platform adds a contract and a skill set without removing much work.
- SQL-first BI on Redshift. Years of dashboards, stored procedures and workload tuning are hard to justify moving.
- Small, scheduled Glue jobs. Per-second DPU billing suits jobs that start, finish and then stop paying.
- All-in AWS contracts and skills. Committed spend, existing IAM patterns and AWS-certified engineers all point one way.
- Bedrock-centred GenAI apps. Apps that call foundation models with little custom training fit naturally on Bedrock.
Notice what these scenarios share. The data rarely needs to move between engineering, SQL and ML teams, so the cost of stitching services together stays low.
Real-World Databricks vs AWS Use Cases
Use cases make the trade-off concrete, because each one stresses a different layer of the stack. The four below map common workloads to the option that usually fits them.
Fraud and risk reporting. Transaction data often lands in S3 first, and fraud teams need it enriched and access-controlled before it reaches a dashboard. That mix of Spark processing, row-level security and BI tends to favour Databricks on AWS. Our guide to AI in fraud detection covers the modelling side.
Document and unstructured data pipelines. PDFs, scraped pages and metadata need Python processing next to the tables they feed. One workspace keeps that code, its output tables and any downstream ML together.
Dashboards on an established Redshift estate. A BI team with years of Redshift tuning gains little from moving. Redshift Serverless bills per second and costs nothing while idle, so spiky reporting can stay AWS-native. Our cloud data warehouse guide covers that model.
GenAI assistants on foundation models. An app team that calls hosted models through Amazon Bedrock, with little custom training, rarely needs a separate data platform. When the assistant needs retrieval over governed lakehouse tables, our guide to generative AI on Databricks shows the other side.
Most estates hold more than one of these patterns. That is why the scorecard later in this guide scores workloads rather than the company as a whole.
Running Databricks and AWS Together
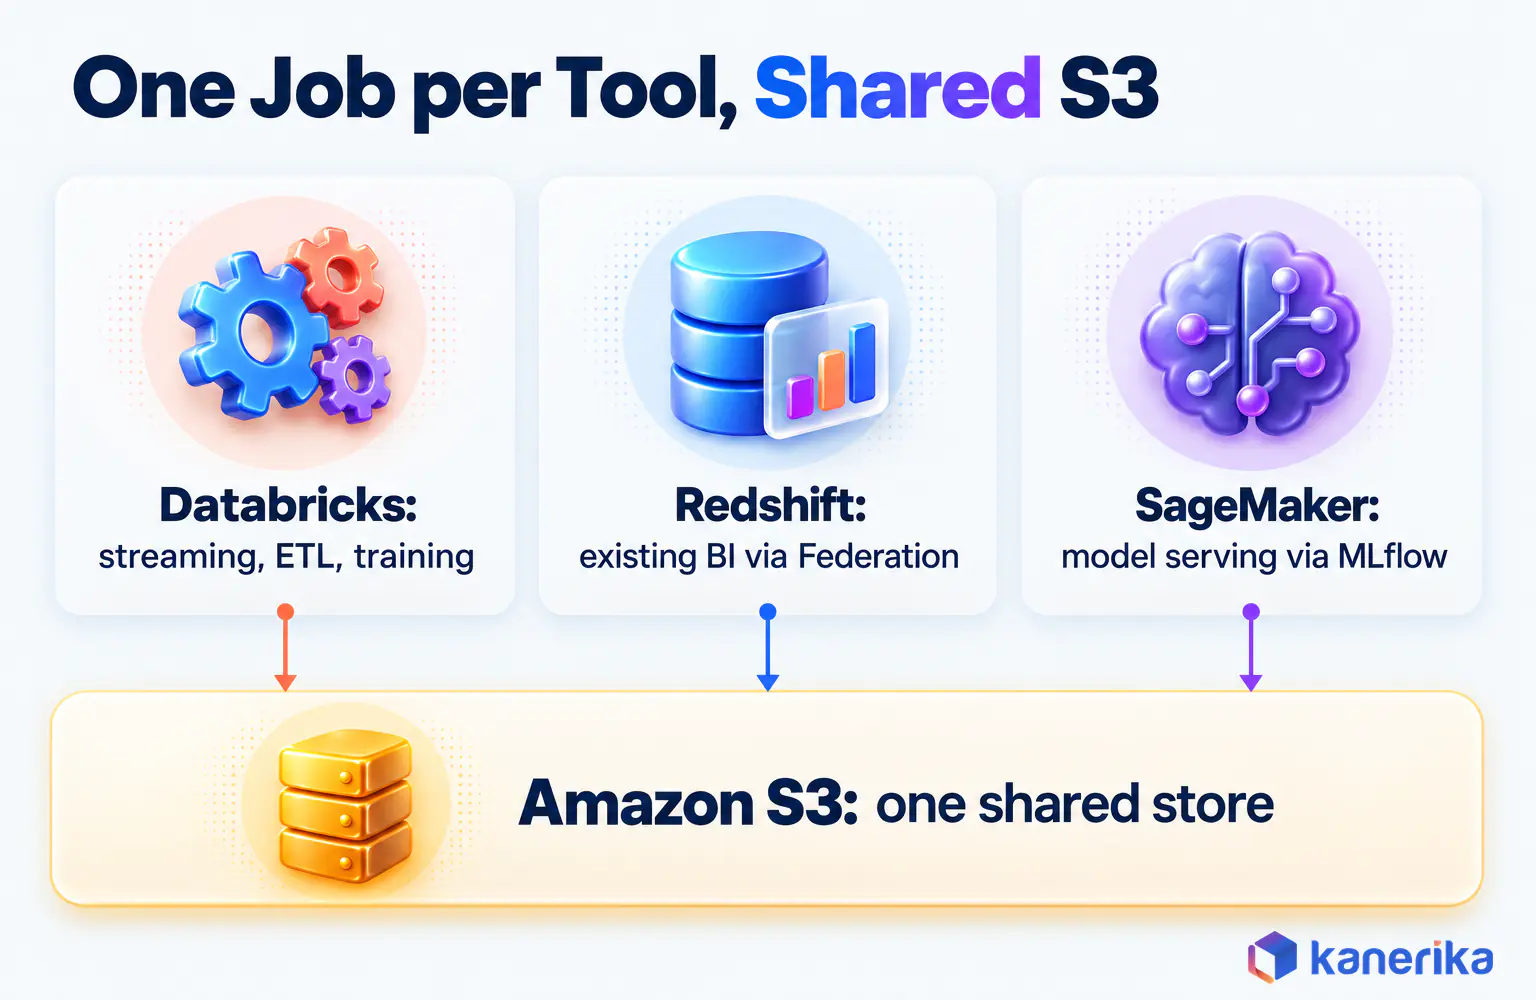
Choosing Databricks on AWS rarely means switching off every AWS data service. The setup holds up when each tool keeps one named job, with S3 as the shared store and workloads drawing the boundaries between tools.
A common pattern looks like this. Kinesis streams events into Databricks streaming jobs, which then write Delta tables in S3. Existing Redshift marts stay where they are for BI, and Databricks queries them through Lakehouse Federation instead of copying the data.
Querying Redshift From Databricks
The older Redshift connector staged data in S3 over JDBC with COPY and UNLOAD. As of October 2026, the Databricks docs list it under external systems (legacy). Databricks recommends Federation wherever it supports the source, and setup takes two SQL statements in Unity Catalog with credentials held in Databricks secrets.
CREATE CONNECTION redshift_bi TYPE redshift
OPTIONS (
  host '<hostname>',
  port '5439',
  user secret('bi-scope', 'redshift-user'),
  password secret('bi-scope', 'redshift-password')
);

-- Needs CREATE CONNECTION on the metastore, plus DBR 13.3 LTS+
-- or a pro/serverless SQL warehouse on 2023.40 or above.
CREATE FOREIGN CATALOG IF NOT EXISTS redshift_sales
USING CONNECTION redshift_bi
OPTIONS (database 'sales');

-- Illustrative query: filters, joins and aggregates push down
-- to Redshift; window functions and OFFSET do not.
SELECT region, SUM(amount) AS revenue
FROM redshift_sales.public.orders
WHERE order_date >= '2026-01-01'
GROUP BY region;
The Federation requirements are where first attempts usually stall. A classic SQL warehouse will not run these statements, since the docs require a pro or serverless warehouse. Pushdown is the second catch. A ranking query with a window function pulls the filtered rows into Databricks before it runs, so filter hard in the same query.
Two more limits are worth knowing before a pilot. Federated queries cannot read Redshift external data, and Redshift timestamps arrive as Spark TimestampType unless infer_timestamp_ntz_type is set to true.
Serving Databricks Models on SageMaker
On the ML side, a model trained and registered with MLflow in Databricks can then be deployed to a SageMaker endpoint. The snippet below follows the mlflow.sagemaker deployment client. The role, image, region and model path are placeholders, and the comments carry the defaults from the MLflow docs.
from mlflow.deployments import get_deploy_client

# One-time step: build the serving image and push it to ECR
#   mlflow sagemaker build-and-push-container
config = dict(
    execution_role_arn="arn:aws:iam::<account-id>:role/<sagemaker-role>",
    image_url="<account-id>.dkr.ecr.us-east-1.amazonaws.com/<image>:<tag>",
    region_name="us-east-1",        # unset falls back to us-west-2
    instance_type="ml.m5.4xlarge",  # default is ml.m4.xlarge
    instance_count=1,
    synchronous=True,
    timeout_seconds=1200,           # default 300 (illustrative value)
    archive=False,                  # needs synchronous=True
)
client = get_deploy_client("sagemaker")
client.create_deployment(
    "churn-model",
    model_uri="models:/churn_model/1",
    flavor="python_function",
    config=config,
)
Two of those defaults cause most surprises, according to the MLflow SageMaker reference. Without a region in the config or the target URI, the client deploys to us-west-2. That can split the endpoint from the apps that call it. A synchronous call also returns after 300 seconds by default while the endpoint may still be creating. Check its status in SageMaker before routing traffic.
Each tool keeps one job in this pattern. Databricks handles streaming, ETL and training, while Redshift keeps the BI it already serves and SageMaker serves models where the apps live. Drift is the main risk, so write down which tool owns each job and review it every quarter.
A Workload-Based Way to Decide
A vendor-neutral way to settle the question is to score each option against your own workloads. The scorecard below uses weights that add up to 100, so you score each option from 1 to 5 on each row.
Agree the weights before anyone scores, since that keeps the result from bending toward a favourite. Then multiply each score by its weight and add the rows for each option.
| Criterion | Weight | Scores high for Databricks on AWS when | Scores high for AWS-native when |
|---|
| Workload mix | 25 | ETL, SQL and ML share the same tables | Work is mostly SQL and scheduled jobs |
| Team skills | 20 | Team writes Spark, Python and SQL in notebooks | Team is fluent in Glue, Redshift and IAM |
| Governance needs | 20 | One catalog must cover data and models | IAM and Lake Formation already meet audit needs |
| Cost over 12 and 36 months | 20 | Consolidation removes services and engineering time | Per-service bills stay small and predictable |
| Cloud strategy | 15 | Multi-cloud or acquisitions are likely | AWS is the only cloud for the foreseeable future |
Confirm the Winner With a Proof of Concept
A score sheet only goes so far, so confirm the winner with a short proof of concept. Pick real workloads rather than a vendor demo, and keep the scope small enough that the same people can build both versions.
- Choose two or three representative workloads, such as one ETL pipeline, one BI query set and, if relevant, one model.
- Build each on both options with the same data in S3 and the same success criteria.
- Measure runtime, cost per run, engineering hours and how long access setup took.
- Run the TCO model from the pricing section, this time with the measured numbers.
- Decide per workload, then check whether the answers point to one platform or a deliberate mix.
Common Mistakes When Choosing Between Them
The same few errors show up in many platform reviews, but each one is cheap to avoid when you name it early.
- Comparing list prices only. Units differ, so a lower hourly rate can still produce a higher monthly bill.
- Ignoring egress and operations time. Data transfer and the hours spent wiring services together are real costs as well.
- Migrating everything at once. Move by workload instead, starting with the one where the gain is clearest.
- Adding governance after go-live. Retrofitting permissions on live tables is slower than designing the catalog first, so start from our data governance best practices.
These mistakes share a root cause, since each treats the choice as a one-time purchase. It is closer to an operating decision that you revisit as workloads change.
How Kanerika Helps You Choose and Deliver
Choosing between Databricks on AWS and an AWS-native stack is easier when your own workload data is on the table. Kanerika is a registered Databricks consulting partner, and our work on this decision follows four stages.
We start with an assessment of your current pipelines, queries, models and costs. From that, we draw two candidate architectures side by side, with the same governance and cost assumptions. A workload proof of concept then tests the shortlist on your data before any wider move begins.
Migration then runs on FLIP, Kanerika’s workflow automation platform. For data integration and ETL, FLIP handles source-to-target mapping and transformation, so pipelines move without a hand rewrite. Warehouse moves to Databricks get automated schema conversion and built-in validation. Its reconciliation checks then compare data across source and target systems and flag mismatches, which gives a cutover sign-off real evidence.
Our Databricks services cover platform setup, Unity Catalog design and pipeline migration. Our data engineering services also cover the AWS-native side when that is the better fit for a workload.
Client Results From Databricks Projects
A financial services client shows the pattern on S3 data. Its core platform data sat in protected S3 with very little metadata, and KPI reporting ran three days behind. Fraud detection and settlement monitoring were working on stale numbers.
Kanerika built Airflow 2.0 pipelines that moved the data from S3 into Databricks for processing and enrichment, then loaded it to Dremio for reporting. Row-level security and automated data quality rules replaced manual Excel transformations. The financial services case study reports a 90% reduction in data lag and a 96% cut in reporting latency.
The raw data stayed in S3 throughout, and the change happened in the layer above it, which is the split this guide describes. Governance moved with the processing instead of being added after go-live.
Another client, an AI-powered sales intelligence platform, saw 80% faster document processing after the same kind of consolidation. Its pipelines had been scattered across MongoDB, Postgres and legacy JavaScript until Kanerika consolidated them in Databricks.
Case Study
80% Faster Document Processing with Databricks Workflows
An AI-powered sales intelligence platform moved scattered MongoDB, Postgres and JavaScript pipelines into Databricks, gaining 80% faster document processing, 95% better metadata accuracy and 45% faster time to insight.
Read the Case Study →
Final Verdict: Databricks or AWS?
Choose Databricks on AWS when engineering, SQL and ML teams share data under one catalog. Choose an AWS-native stack when the work is SQL-first and the team works only on AWS. Because both keep your data in S3, either pick can later borrow one named workload from the other side.
Score two or three workloads on the scorecard above, then run the proof of concept to settle Databricks vs AWS on your own numbers.
Frequently Asked Questions
What is the difference between Databricks and AWS?
Databricks is a data and AI platform, while AWS is a cloud provider with many separate services. Databricks runs on AWS and stores data in your own S3 buckets. The practical choice is between Databricks on AWS as one platform for ETL, SQL and ML, and an AWS-native stack built from Glue, EMR, Redshift and SageMaker.
What is the AWS equivalent of Databricks?
No single AWS service matches Databricks. The closest equivalent is a combination of services, with Glue or EMR for Spark jobs, Redshift or Athena for SQL, SageMaker for machine learning and Lake Formation for access control. The next generation of SageMaker, with Unified Studio, is the AWS move toward one shared workspace for data and AI.
Is Databricks more expensive than AWS?
Not by default, because the bills use different units. Databricks charges per second for platform usage, plus the AWS infrastructure under classic compute. AWS-native services bill separately per DPU-hour, per instance second or per Redshift hour. Compare total cost over 12 and 36 months, including storage, egress and engineering time, before deciding which is cheaper.
Does Databricks use Amazon S3?
Yes. On AWS, Databricks stores table data and workspace files in S3 buckets in your own AWS account. Tables are usually Delta Lake, and UniForm can add Iceberg metadata so Iceberg readers can query them. Because the files stay in your account, other tools in your AWS estate can work with the same data without a separate copy.
How does Unity Catalog compare with AWS Lake Formation?
Unity Catalog governs tables, files and models from one place inside Databricks, and it has been open source under Apache 2.0 since June 2024. Lake Formation adds fine-grained access control for S3 data lake data, augmenting IAM permissions. On the AWS side, models and business metadata sit with SageMaker and SageMaker Catalog instead.
Can you migrate from AWS Glue or EMR to Databricks?
Yes. Glue and EMR jobs are usually Spark code, so much of the logic carries over, and the data can stay in S3. The work is in rewriting job configuration, connectors and scheduling, then setting up Unity Catalog permissions. Migrating one workload at a time, starting with the clearest win, keeps risk and cost under control.
Can Databricks run on AWS?
Yes. Databricks runs on AWS, and classic compute runs in a compute plane inside your own AWS account. The workspace storage bucket also lives in your account, while Databricks manages the control plane. Serverless compute is the exception, because it runs in a serverless compute plane inside your Databricks account rather than your AWS account.
Is Databricks available on Azure and Google Cloud too?
Yes. Databricks runs on AWS, Microsoft Azure and Google Cloud, with the same core platform on each. That reach matters for companies with more than one cloud or with acquisitions on a different provider. AWS-native services such as Glue and Redshift run only on AWS, which is one reason multi-cloud estates often lean toward Databricks.
What is Databricks mainly used for?
Databricks is mainly used for data engineering, SQL analytics and machine learning on shared data. Teams build Spark or SQL pipelines, query Delta tables with Databricks SQL warehouses, and track and serve models with MLflow and Model Serving. Unity Catalog governs access across all of it, so engineers, analysts and data scientists work from the same tables.
Is Databricks a database or an ETL tool?
Databricks is neither a classic database nor only an ETL tool. It is a data platform that stores tables as Delta Lake files in cloud storage, runs ETL with Apache Spark, and serves SQL and machine learning workloads on the same data. Many teams use it for ETL first, then add analytics and ML over time.
What is the difference between AWS Glue and Databricks?
AWS Glue is a serverless Spark service that bills per DPU-hour, charged per second with a one-minute minimum. It suits small, scheduled jobs. Databricks runs Spark inside a full workspace with notebooks, SQL warehouses, MLflow and Unity Catalog. It suits larger estates where engineering and data science teams share pipelines, tables and governance.
Does Databricks replace Amazon EMR?
It can, but it does not have to. EMR gives open-source Spark on EC2, EKS, Outposts or EMR Serverless, billed per second, with tuning left to your team. Databricks adds a managed workspace, catalog and ML tooling on top of Spark. Teams often replace EMR when cluster management and handoffs to data science take too much time.
Is Databricks or SageMaker better for machine learning and GenAI?
Databricks suits teams that want features, experiments and serving next to their Spark data, using MLflow and Model Serving. SageMaker suits teams building inside AWS, especially apps that use Amazon Bedrock for foundation models. The two also connect, because MLflow can deploy models trained in Databricks to SageMaker endpoints where the apps already run.
Is Databricks or Redshift better for analytics?
Redshift is the stronger fit for SQL-first BI teams with years of dashboards and tuning already invested. Databricks SQL fits when analysts need the same governed tables that engineers and data scientists use. You can also keep both, since Lakehouse Federation lets Databricks query Redshift directly without copying the data into Delta tables.














