TL;DR
Databricks Photon pays off for big SQL jobs, heavy writes and BI, but rarely for UDF or stateful streaming code. It is the C++ vectorized engine inside the Databricks Runtime, and it runs Spark code unchanged. SQL warehouses and serverless compute always run it, so the real choice is on classic compute. There, Photon burns DBUs at a higher rate, and Azure lists 2.9x for classic Lakeflow pipelines. It pays only when the runtime it saves outweighs that premium, with VM costs counted. So benchmark each job fairly, check its Photon share, and switch it off where Spark fallback dominates.
Key Takeaways
- Databricks Photon is a native C++ query engine that runs inside the Databricks Runtime, so existing SQL and DataFrame code needs no rewrite.
- Photon is always on for SQL warehouses and serverless compute, while classic compute exposes a checkbox and an API field.
- Photon compute consumes DBUs at a higher rate, so it saves money only when it shortens a job by more than that premium.
- UDFs, RDD code, the Dataset API and stateful streaming fall back to Spark, and you still pay the Photon rate for that time.
- The query profile and the Spark UI show how much of each query ran on Photon, and system.billing.usage also shows what it cost.
- Prove the value job by job with a fair benchmark, then lock the choice in with cluster policies.
The Photon Line on Your Databricks Bill
Picture a finance review in late October. The nightly jobs bill for the data platform has climbed for three straight months. Someone points at a line item that reads “Jobs Compute Photon.” Photon was switched on because the compute defaults said so, and nobody wrote down why.
The data engineering lead is then asked a simple question. What share of those jobs actually ran on Photon, and did the faster runs make up for the higher rate? Nobody in the room can answer, because nobody kept a baseline.
That gap is what this guide closes. It explains what Photon is, where it is on by default and what it cannot accelerate. It then shows the break-even math, a seven-step benchmark and a way to govern the setting. The next finance review then gets a number instead of a shrug.
What Is Databricks Photon?
Databricks Photon is the native vectorized query engine that ships with the Databricks Runtime. It speeds up SQL queries, DataFrame API calls, ETL pipelines and stateless streaming, and it does so without asking you to change your code.
The Databricks Photon documentation says it is compatible with Apache Spark APIs, so existing code runs with no changes. In practice it replaces the part of Spark that executes a query plan. You keep writing Spark SQL or PySpark, and Photon takes over the heavy lifting underneath. On Photon compute, a data engineer sees the same API and the same results. For the right workload, the run is simply much shorter.
Photon matters most on a lakehouse, because large Delta tables are scanned, joined and rewritten there every night. If you are new to that design, Kanerika’s guide to Databricks lakehouse architecture covers the storage and governance layers under Photon. The broader Databricks platform overview explains where the runtime fits.
Kanerika Service
Databricks Consulting and Implementation
Kanerika is a Databricks Consulting Partner that plans, builds and tunes lakehouse platforms, including compute setup, query performance and cost governance.
Explore Databricks ServicesHow Photon Fits Inside the Databricks Runtime
Photon is not a separate product that you buy or install. It is part of the Databricks Runtime (DBR), which also bundles Apache Spark, Delta Lake and the Databricks optimizations. The question “DBR or Photon?” therefore has a simple answer: Photon is one engine inside DBR, and you choose whether to turn it on.
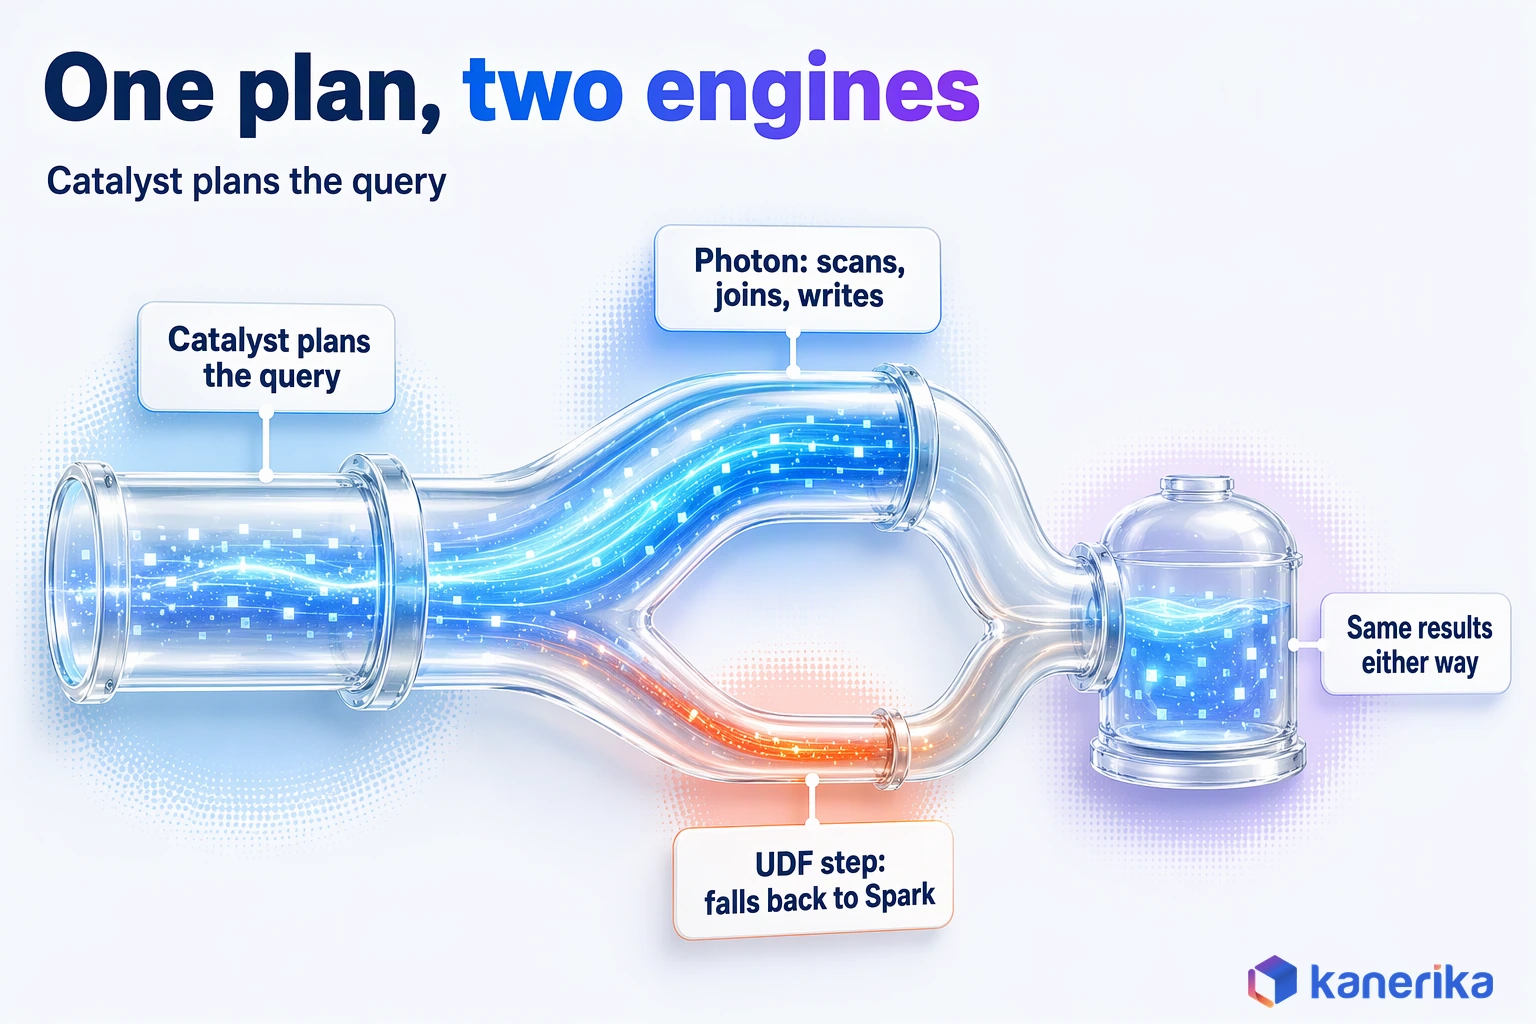
The division of labor is also clean. Spark’s Catalyst optimizer still parses and plans every query, exactly as it does without Photon. When the plan is ready, Photon executes the operators it supports, and the standard Spark engine executes everything else.
That split also explains both Photon’s strength and its blind spots. A query made of scans, filters, joins and aggregations can run almost entirely in Photon. A query that calls a Python UDF in the middle, by contrast, hands that step back to the JVM.
From Preview to Platform Default
Databricks first announced the Photon public preview in 2021. According to the July 2022 release notes, Photon became generally available on July 27, 2022, beginning with Databricks Runtime 11.1.
A week later, on August 3, 2022, Databricks announced general availability across all major clouds. Since then, Photon has gradually moved from an option to the default. The documentation page updated on September 11, 2026 now lists it as always on for SQL warehouses, serverless compute and serverless Lakeflow pipelines.
How Photon Executes a Query
A query engine is the part of a data platform that turns a plan into actual work on actual rows. Photon changes how that work is done, not what the query means, which is why results stay identical while runtimes drop.
For example, take a nightly job that joins a 2-billion-row sales fact table to a customer dimension and writes a summary table. Catalyst produces the same plan either way. With Photon on, the scan, the join, the aggregation and the write all run in native code. Only the steps Photon does not support go back to Spark.
Columnar Batches, SIMD and Native C++
Classic Spark SQL evaluates data inside the Java Virtual Machine. Photon replaces that execution layer with a native C++ runtime that processes data in columnar batches of thousands of rows at a time.
Working in batches lets modern CPUs use SIMD instructions, which evaluate several values in a single CPU cycle. Because the code is native, there are no garbage collection pauses and no JIT warm-up delays. Columnar batches also read memory sequentially, which keeps the CPU pipeline busy instead of waiting on cache misses.
The design choice behind this is worth a short detour. Databricks lists the research paper “Photon: A Fast Query Engine for Lakehouse Systems,” presented at SIGMOD 2022, on its Photon product page. In it, the engineers explain why they chose an interpreted, vectorized design over the code generation that Spark uses. Part of the reason is that vectorized kernels are easier to build, profile and debug.
Joins, Shuffles and the Native Writer
Much of Photon’s gain on real ETL comes from four changes to the heaviest parts of a job. Each one targets work that classic Spark spends a lot of time on.
- Hash joins: Photon replaces sort-merge joins with high-performance hash joins, so large joins skip an expensive sort.
- Columnar shuffle: a redesigned shuffle moves data between nodes in columnar form, which raises throughput for large-scale joins.
- Native Parquet writer: Delta Lake, Apache Iceberg and Parquet writes run natively, including MERGE INTO, UPDATE, DELETE, INSERT and CTAS.
- Scan efficiency: filter pushdown, dictionary pruning and row-group skipping cut the data read from storage, even with many small files.
The documentation singles out wide tables, with thousands of columns, as the biggest winners from the native writer. Two features also require Photon: predictive I/O for reads and writes, and dynamic file pruning in MERGE, UPDATE and DELETE statements.
What Happens at an Unsupported Operator
When Photon meets an operation it does not support, it falls back to the Spark runtime for that part of the query. Fallback is transparent, so the query still finishes and the results are still correct.
The real catch, however, is cost. On classic compute, the whole cluster is billed at the Photon DBU rate while it runs. That includes the minutes spent in the JVM. A job that spends most of its time in a Python UDF pays the premium but gets little of the speed. That is exactly the job our finance review should be asking about.
Where Photon Runs by Default: A Compute-Type Matrix
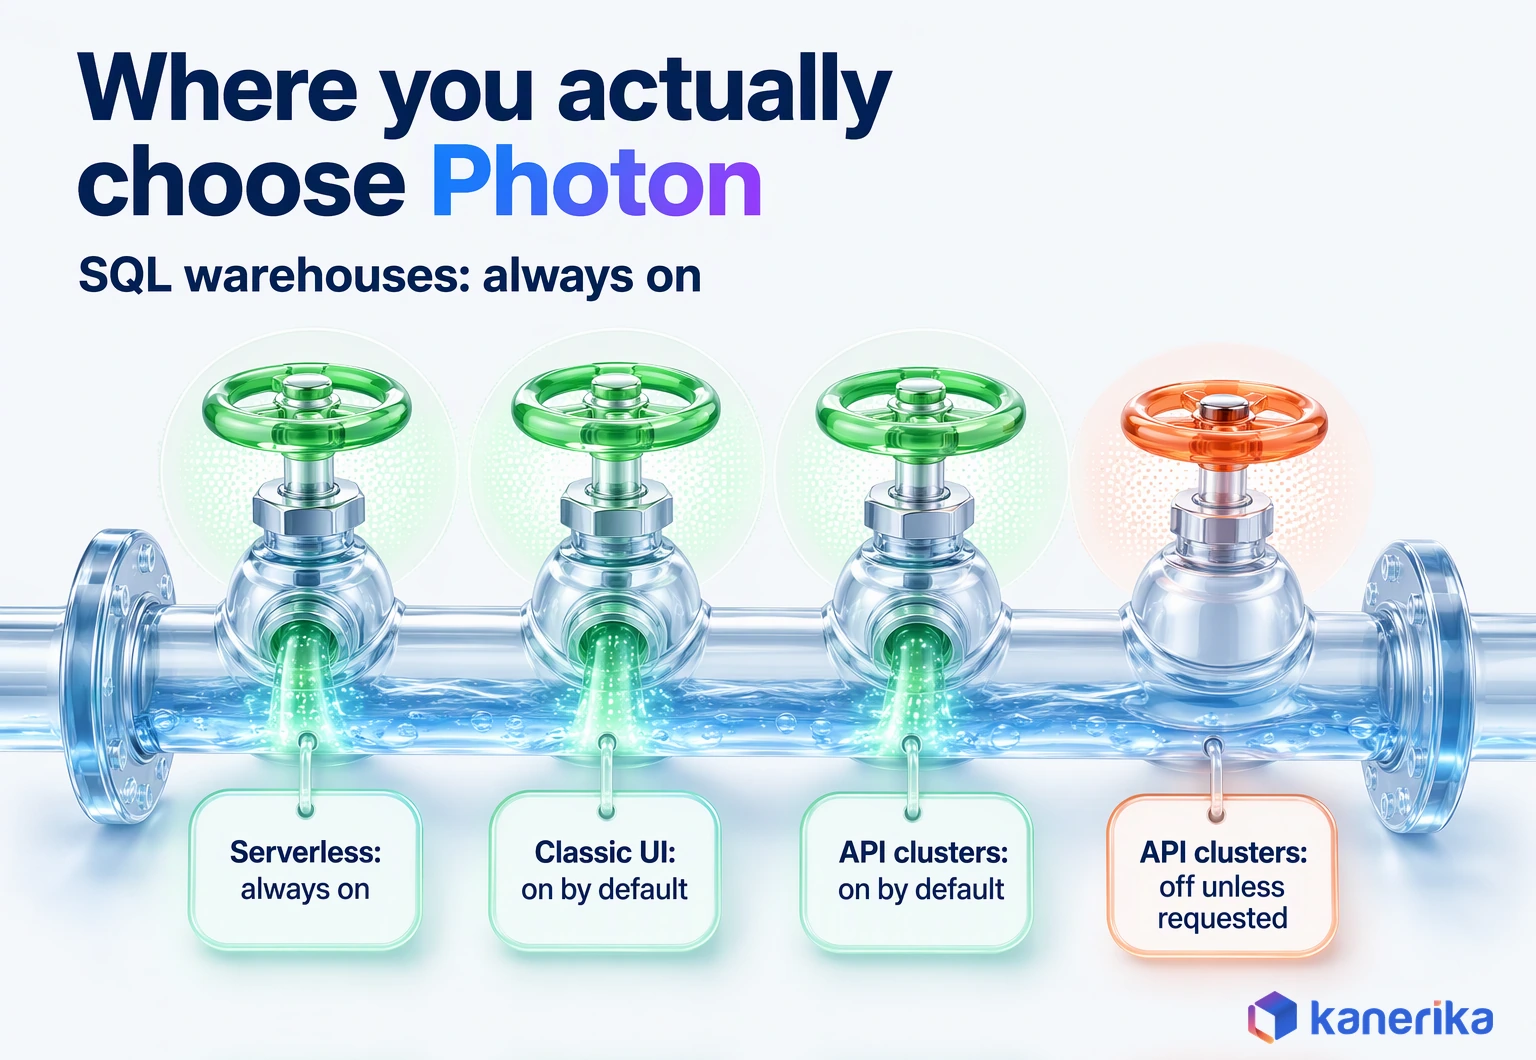
Whether you even get a choice about Photon depends on the type of compute a workload runs on. Serverless products and Databricks SQL warehouses make the decision for you, while classic compute leaves it to whoever creates the cluster or the job.
This is also where many surprises on the bill start. A cluster created in the UI picks up Photon by default. A job created through the Jobs API, however, runs without it unless the request asks for it. Two teams can therefore run the same code on different engines without knowing it.
| Compute type | Photon state | How to change it | Billing note |
|---|---|---|---|
| SQL warehouse | Always on | Not configurable | Billed at the SQL warehouse DBU rate |
| Serverless compute (notebooks, jobs) | Always on | Not configurable | Billed at the serverless DBU rate |
| Serverless Lakeflow pipelines | Always on | Not configurable | Billed at the serverless pipelines rate |
| Classic all-purpose compute | On by default in the UI | “Use Photon Acceleration” checkbox under Performance | Photon SKU, higher DBU count |
| Classic jobs compute | On by default in the UI | Same checkbox on the job cluster | Photon SKU, higher DBU count |
| Classic Lakeflow pipelines | On by default in the UI | Pipeline compute settings | On Azure, 2.9x the non-Photon DBU emission rate |
| Clusters API or Jobs API | Off unless requested | Set runtime_engine to PHOTON | Matches the classic SKU you choose |
| Pipelines API | Off unless requested | Set photon to true | Matches the classic pipeline SKU |
The Azure figure comes from the Azure Databricks pricing page, which states that enabling Photon will increase DBU count. It applies only to classic Lakeflow pipelines on Azure, so treat it as one published data point for that SKU.
Enable or Disable Photon on Classic Compute
On classic compute you control Photon in three places, and a well-run platform uses all three. The three places below run from a single cluster, through automated jobs, to a rule for the whole workspace.
- Open the cluster or job cluster in the compute UI, find Performance and tick or clear “Use Photon Acceleration.”
- Set runtime_engine to PHOTON or STANDARD in the cluster spec of a Clusters API or Jobs API call. For the Pipelines API, set photon to true or false.
- Fix runtime_engine in a cluster policy for each environment so that nobody has to remember the setting.
For example, a job definition sent to the Jobs API looks like this. The runtime version and node type are placeholders for your own values.
"new_cluster": {
  "spark_version": "<your-lts-runtime>",
  "node_type_id": "<your-node-type>",
  "num_workers": 8,
  "runtime_engine": "PHOTON"
}
What Photon Supports and Where It Falls Back
Photon covers the operators that make up the bulk of analytical SQL, plus a wide range of data types. Knowing the list helps you predict, before any benchmark, whether a job will run mostly in Photon or mostly in Spark.
The table below follows the supported operators, expressions and data types in the Databricks documentation. Databricks also notes that the categories are representative rather than exhaustive, and that individual functions inside a category may still have limits.
| Category | What Photon covers |
|---|---|
| Scans and projections | Scan of Parquet, Delta, CSV and JSON, Filter, Project |
| Joins | Hash join, nested-loop join, null-aware anti join, spatial joins such as ST_Intersects and ST_Contains |
| Aggregation and shuffle | Hash aggregate, shuffle, Union, Expand, scalar subqueries |
| Ordering and windows | Sort, TopK, Limit, window functions |
| Writes | Delta and Parquet write sink |
| Expressions | Comparison and logic, arithmetic and math, IF and CASE, strings, casts, aggregates, date and timestamp functions |
| Data types | Integers, Boolean, String, Binary, Decimal, Float, Double, Date, Timestamp, TimestampNTZ, Struct, Array, Map, Variant, Geometry, Geography, collated strings |
The limitations are just as important as the coverage, because each one sends work back to the JVM.
- UDFs: user-defined functions, including Python UDFs, run in Spark rather than Photon.
- RDD and Dataset APIs: code written against RDDs or typed Datasets does not run in Photon.
- Stateful streaming: Photon supports stateless streaming to Delta or Parquet sinks only.
- Short queries: queries that already finish in under about two seconds see no meaningful gain, because planning and scheduling dominate.
- Graviton with Container Services: Graviton instances with Photon do not support Databricks Container Services on dedicated compute or SQL warehouses.
Talk to Kanerika
Not Sure Which Jobs Fall Back to Spark?
Kanerika will review your Databricks jobs, benchmark a few with and without Photon, and show where UDFs or RDD code erase the gain and what each run costs.
Schedule a Demo →Which Workloads Are Good Databricks Photon Candidates?
A good Photon candidate is a job that spends its time doing the things Photon does natively: scanning, joining, aggregating and writing large tables. A poor candidate spends its time in code Photon cannot run, or finishes so fast that there is nothing left to speed up.
For example, consider two jobs on the same cluster. The first rebuilds a 400-column customer table with a MERGE every night. The second loops over rows in a Python UDF to parse free text. Photon will likely transform the first and barely touch the second, although both pay the same higher rate.
| Workload pattern | Expected fit | Why |
|---|---|---|
| Large scans, joins and aggregations in SQL or DataFrames | Strong | Hash joins, columnar shuffle and SIMD kernels do the heavy work |
| Wide-table writes, MERGE, UPDATE and DELETE on Delta | Strong | Native Parquet writer, plus dynamic file pruning that needs Photon |
| BI dashboards with many concurrent users | Strong (always on) | SQL warehouses run Photon and benefit from the disk cache |
| Stateless streaming into Delta | Good | Supported for Delta and Parquet sinks from Kafka, Kinesis and files |
| Feature engineering in SQL or DataFrames | Good | Joins and window functions run natively |
| Python-UDF-heavy transformations | Weak | UDF steps fall back to Spark at the Photon rate |
| RDD or Dataset API code | Poor | Not supported, so the job runs in the JVM |
| Stateful streaming | Poor | Not supported |
| Queries under about two seconds | None | Overhead dominates the runtime |
Ingestion, Transformation and Feature Pipelines
Ingestion jobs often sit in the strong column. Raw files that land through incremental ingestion with Auto Loader are written to Delta by the native writer. The SQL transformations that follow, such as dbt models on Databricks, run on Photon-enabled SQL warehouses by design.
Machine learning pipelines, by contrast, are more mixed. Feature tables built with joins and window functions in the Databricks Feature Store suit Photon well. Custom Python logic for model scoring falls back to Spark and deserves a separate check.
The DBU Cost Question: When Photon Pays for Itself
Photon is not free on classic compute. Databricks bills a Databricks Unit (DBU) for each unit of processing. Photon compute emits more DBUs per hour than the same instance on the standard engine, so the speedup has to cover the higher rate.
Checklist
Databricks Readiness Across Compute, Governance and Cost
Assess your Databricks platform across compute, governance, pipelines, security and AI workloads, then improve performance and control costs.
Get the Checklist →The vendor claims are strong, but they should still be read as claims. The Photon product page says Databricks measured an extra 2x speedup on the TPC-DS 1TB benchmark against the latest Databricks Runtime versions. When we read the page on November 14, 2026, it named no runtime version or test date for that run.
The page adds that customers saw 3x to 8x average speedups on their own workloads, and it cites up to 80% TCO savings. Those are best-case figures for well-suited workloads, so your own jobs remain the only proof that counts. The same page also claims up to 12x better price/performance than other cloud data warehouses, a platform-level question that Kanerika’s Databricks vs Snowflake comparison takes up.
The Break-Even Formula
On classic compute, a run costs its hours multiplied by two hourly rates: the DBU spend and the cloud VM spend. Photon, however, multiplies only the DBU part.
Standard cost = T_std   x (D + V)
Photon cost   = T_photon x (m x D + V)

D = DBU cost per hour on the standard engine
V = VM cost per hour from your cloud provider
m = Photon DBU multiplier for your SKU and cloud

Photon pays when  T_photon / T_std  <  (D + V) / (m x D + V)
The right-hand side is the break-even runtime ratio. Notice that the VM term V appears on both sides, which makes the threshold easier to clear than a DBU-only view suggests.
A Worked Example With Illustrative Numbers
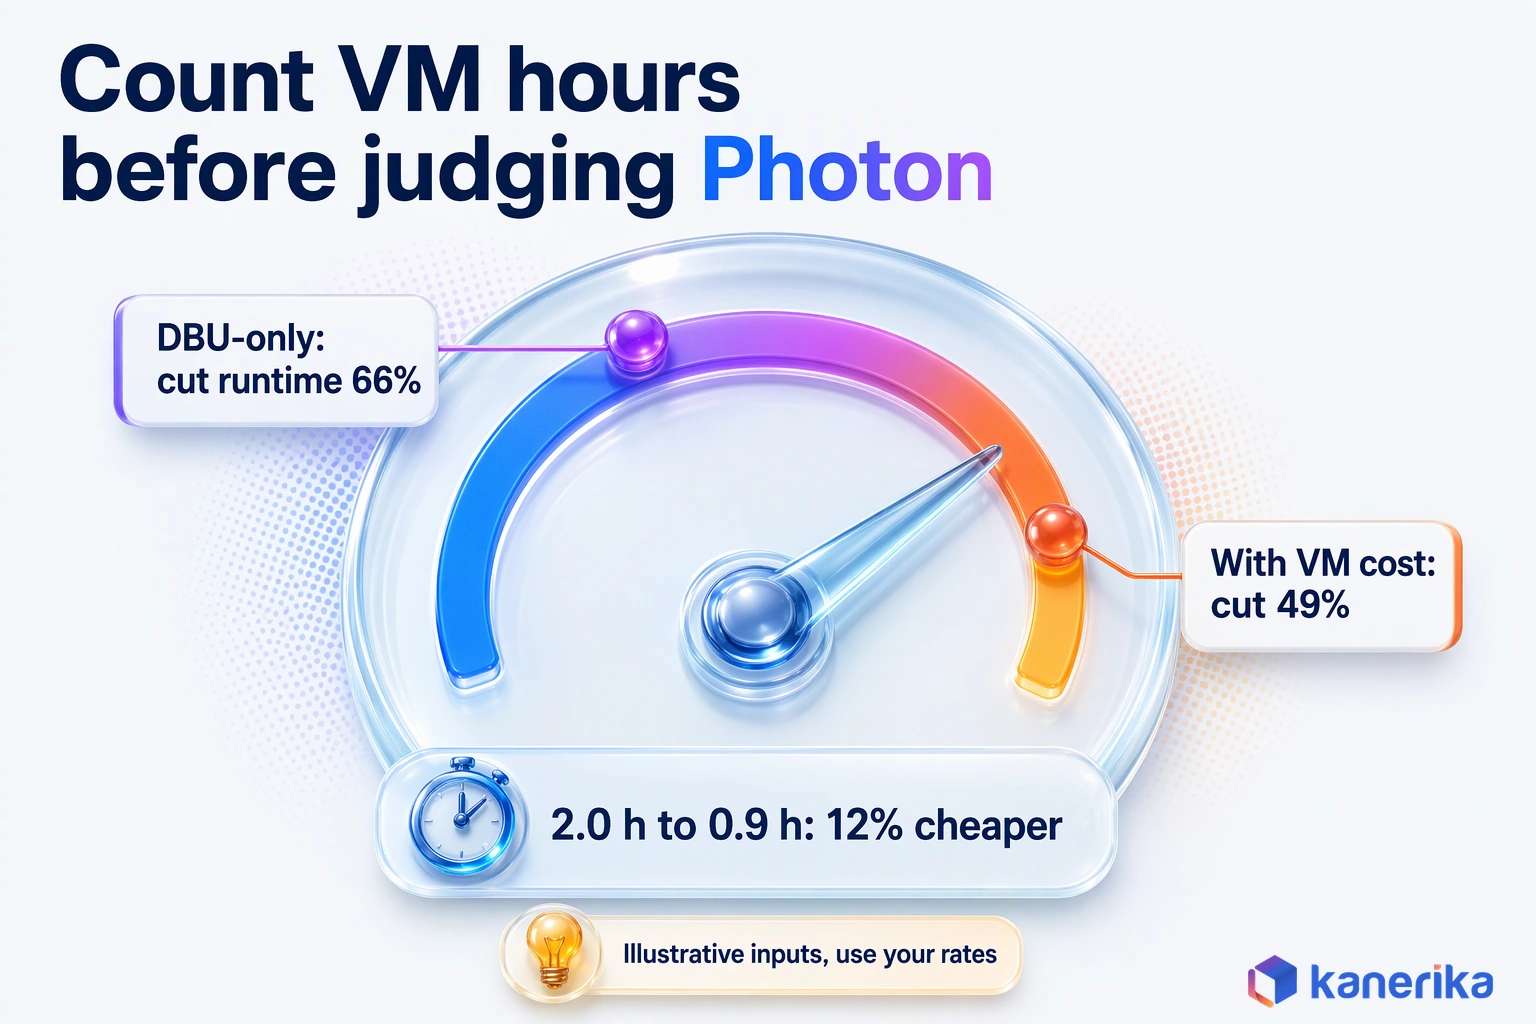
The inputs below are illustrative, so use your own rates and runtimes. Say a standard run takes 2.0 hours and the same job on Photon takes 0.9 hours. That gives a runtime ratio of 0.45. Assume the DBU spend and the VM spend are equal, at one cost unit per hour each. Then take m as 2.9, the published Azure rate for classic Lakeflow pipelines.
- Standard run: 2.0 hours x (1 + 1) = 4.0 cost units.
- Photon run: 0.9 hours x (2.9 + 1) = 3.51 cost units, about 12% cheaper.
- Full break-even ratio: 2 / 3.9 = 0.51, so Photon must cut runtime by about 49%.
- DBU-only view: the ratio would be 1 / 2.9 = 0.34, which demands a runtime cut of about 66%.
On a DBU-only view, this job looks like a loss: 0.9 x 2.9 = 2.61 DBU units against 2.0. Once the VM hours you no longer pay for are counted, the same job saves money. A team that reads only the DBU line on the invoice can therefore switch off Photon on a job where it was paying for itself.
The reverse also holds. If a job only drops from 2.0 to 1.4 hours, the ratio is 0.7, above the 0.51 break-even, and Photon costs more on this SKU. For a wider program that covers instance sizing, autoscaling and idle clusters, see Kanerika’s guide to Databricks cost optimization.
How to Benchmark Photon on Your Own Workloads
A Photon benchmark is a controlled before-and-after test of one job, run twice under identical conditions with only the engine changed. Change anything else, such as the instance size or the data, and the comparison measures cluster luck rather than Photon.
A common failure, for example, is a comparison between a Photon run on a large instance and an old standard run on a smaller one. The seven steps below remove those variables, and they also produce the numbers the break-even formula needs.
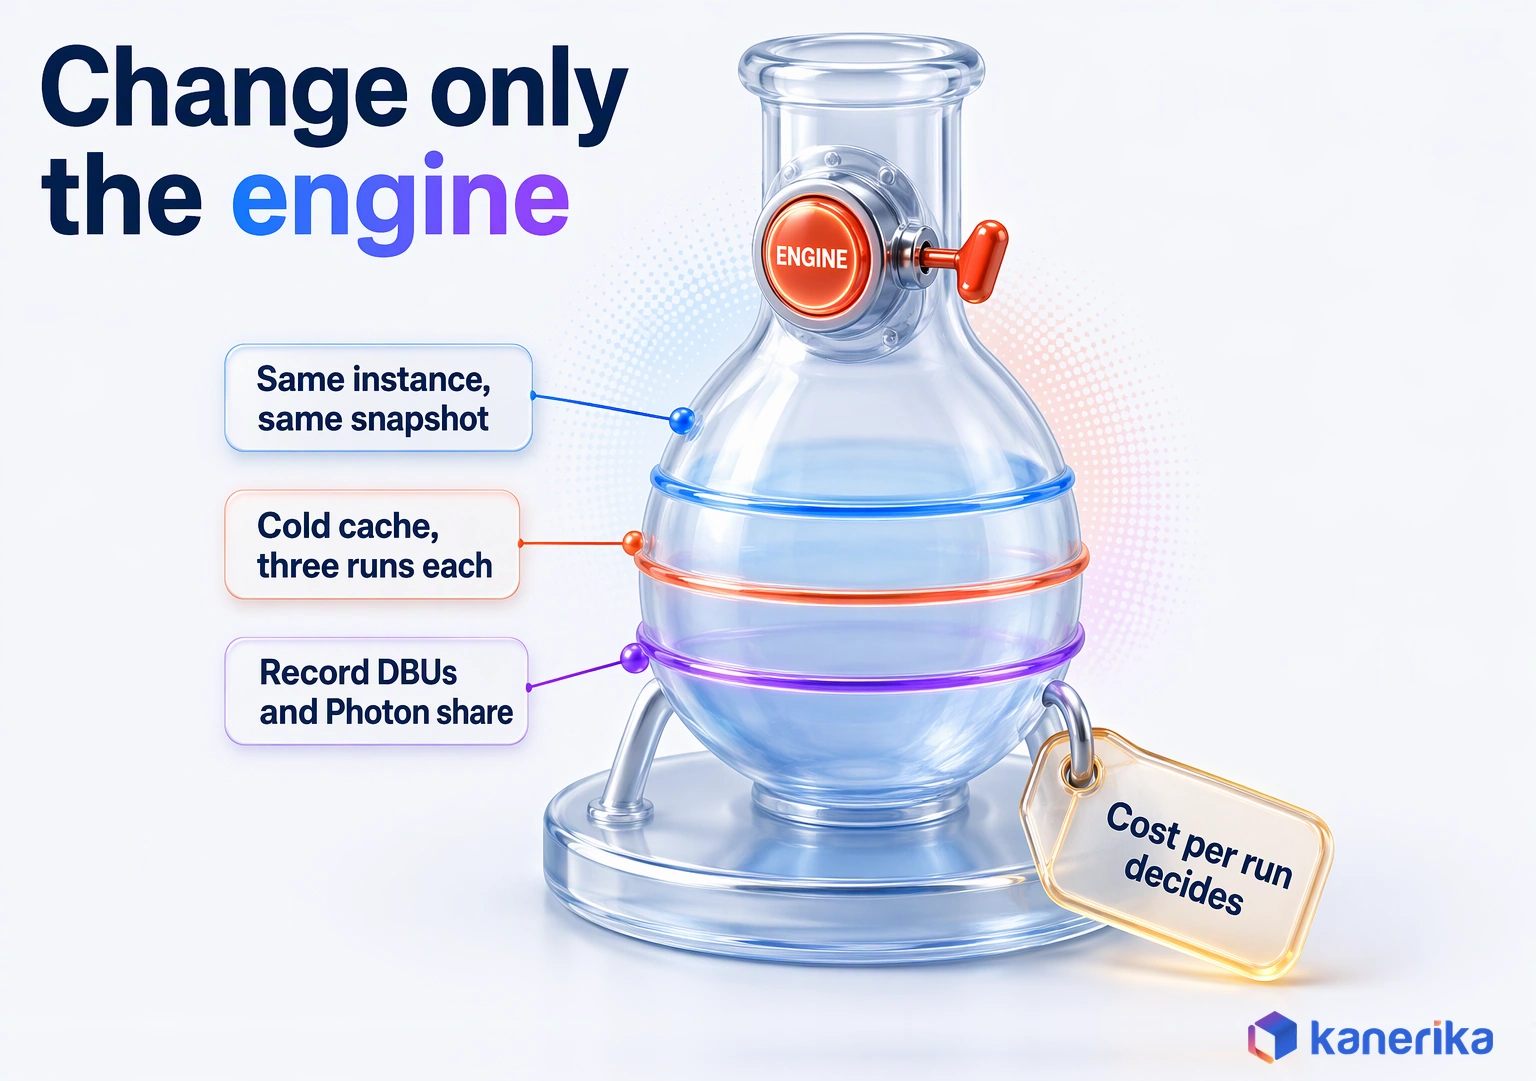
- Use the same instance type and size for both runs, with autoscaling fixed or disabled.
- Run against the same data snapshot, using Delta time travel or a cloned table so both runs read identical rows.
- Disable or equalize the disk cache, because a warm cache flatters whichever run goes second.
- Run each engine three times and take the median, which smooths out cluster start-up and storage noise.
- Record wall-clock time, DBUs and Photon share, using system.billing.usage with the is_photon flag and the Photon task-time percentage from the query profile or Spark UI.
- Compute cost per run with the formula above, including VM cost on classic compute.
- Write down what Photon did not fix, such as UDF stages or skewed joins, because that list drives the next round of tuning.
The billing data lives in the system.billing.usage table, whose product_features.is_photon field marks Photon usage as true or false. A query like this one returns DBUs per job and engine for the last 30 days.
SELECT
  usage_metadata.job_id,
  product_features.is_photon,
  sku_name,
  SUM(usage_quantity) AS dbus
FROM system.billing.usage
WHERE usage_date >= date_sub(current_date(), 30)
  AND usage_metadata.job_id IS NOT NULL
GROUP BY usage_metadata.job_id, product_features.is_photon, sku_name
ORDER BY dbus DESC;
Then keep the results in a small table per job. That record becomes the baseline the finance review was missing.
Reading Photon Coverage in the Query Profile and Spark UI
Two jobs can both say Photon on the cluster page and still spend very different shares of their time in it. Photon coverage is the share of a query’s work that actually ran in Photon rather than falling back to Spark. It is the single most useful number for deciding whether the Photon rate is earning its keep.
Databricks surfaces coverage in two places, depending on the compute type. Both are visual, so an engineer can spot a fallback in seconds once they know the colors.
| Tool | Where it applies | What Photon looks like |
|---|---|---|
| Query profile | SQL warehouses and serverless compute | Execution Details shows the percentage of task time in Photon; Photon operators are purple, standard operators gray |
| Spark UI, SQL/DataFrame tab | Classic all-purpose and jobs compute | Photon operators are orange in the query DAG; standard Spark operators are blue |
A low Photon share usually points to one of a handful of causes, and each one has a known fix. The Databricks performance optimization guide covers the tuning that sits beyond Photon, such as file layout and caching.
- Replace Python UDFs with built-in Spark SQL functions wherever an equivalent exists.
- Rewrite RDD code as DataFrame operations.
- Move typed Dataset API code to untyped DataFrames.
- Run stateful streaming jobs on the standard runtime instead of paying the Photon rate.
Kanerika Service
Data Engineering Services
Kanerika builds and tunes production pipelines on Databricks, from moving legacy Spark code to DataFrames to the monitoring that shows where each job spends its time.
Explore Data EngineeringDecision Framework: Keep, Pilot or Turn Off Photon
The Photon decision is really a set of small decisions, one per workload type. Grouping jobs by pattern keeps the effort manageable and stops one bad benchmark from setting policy for the whole platform.
The table gives a starting position for each scenario. Where it says “high Photon share,” set your own threshold from the Photon share you recorded in step 5 of the benchmark. The right cut-off depends on your SKU and VM costs.
| Scenario | Decision | Reason |
|---|---|---|
| BI and ad hoc SQL on SQL warehouses | Keep (no choice) | Photon is always on and well suited to scans and concurrency |
| Large ETL with a high Photon share and a ratio below break-even | Keep | The runtime cut covers the higher DBU rate |
| Mixed jobs with some Python UDFs | Pilot and measure | Coverage and cost per run decide; fix the UDFs first |
| Short interactive queries on classic clusters | Turn off | Sub-two-second queries gain nothing |
| Stateful streaming | Turn off | Not supported, so the premium buys nothing |
| RDD or Dataset API code | Turn off until rewritten | Runs in the JVM regardless |
Serverless compute also deserves a note of its own. Photon is always on there, but always on does not mean full coverage, since a UDF still falls back. The query profile is still worth reading on serverless jobs, even though there is no switch to flip.
Governing Photon at Scale
On a platform with hundreds of jobs, nobody remembers which ones were meant to run on Photon. Governing Photon means making that engine choice deliberate and visible, instead of an accident of who created the cluster. That takes policy and reporting rather than memory, the same habit that runs through Kanerika’s wider Databricks best practices.
Cluster policies do most of the work. The cluster policy reference lists runtime_engine as an attribute with the values PHOTON or STANDARD, and a policy can fix and hide it. The example below forces Photon on for a production ETL policy.
{
  "runtime_engine": {
    "type": "fixed",
    "value": "PHOTON",
    "hidden": true
  }
}
In practice, a sound governance setup combines a few habits. Each one closes a gap that let the bill in our opening scenario drift.
- Fix runtime_engine per environment with cluster policies, for example PHOTON for production ETL and STANDARD for UDF-heavy data science work.
- Require every job created through the API to set runtime_engine explicitly, since API-created clusters skip the UI default.
- Publish a monthly report from system.billing.usage grouped by is_photon and job, so owners see their own Photon spend.
- Ask a job owner to sign off before Photon is enabled on a classic job, with the benchmark attached.
- Tie the policies to workspace access in Unity Catalog governance so the same teams own both data and compute rules.
The bill in the opening finance review came from a familiar mistake: Photon switched on without a baseline. A written policy with the benchmark attached costs far less than discovering that on an invoice.
Finally, shared data adds one more wrinkle. Tables published through Databricks Delta Sharing are queried on the recipient’s own compute, so the recipient’s engine settings, not the provider’s, apply to those reads.
How Kanerika Rolls Out Photon in Stages
Kanerika treats Photon as a measured rollout rather than a switch. As a certified Databricks partner, Kanerika works through five stages on Photon engagements, so each decision has numbers behind it.
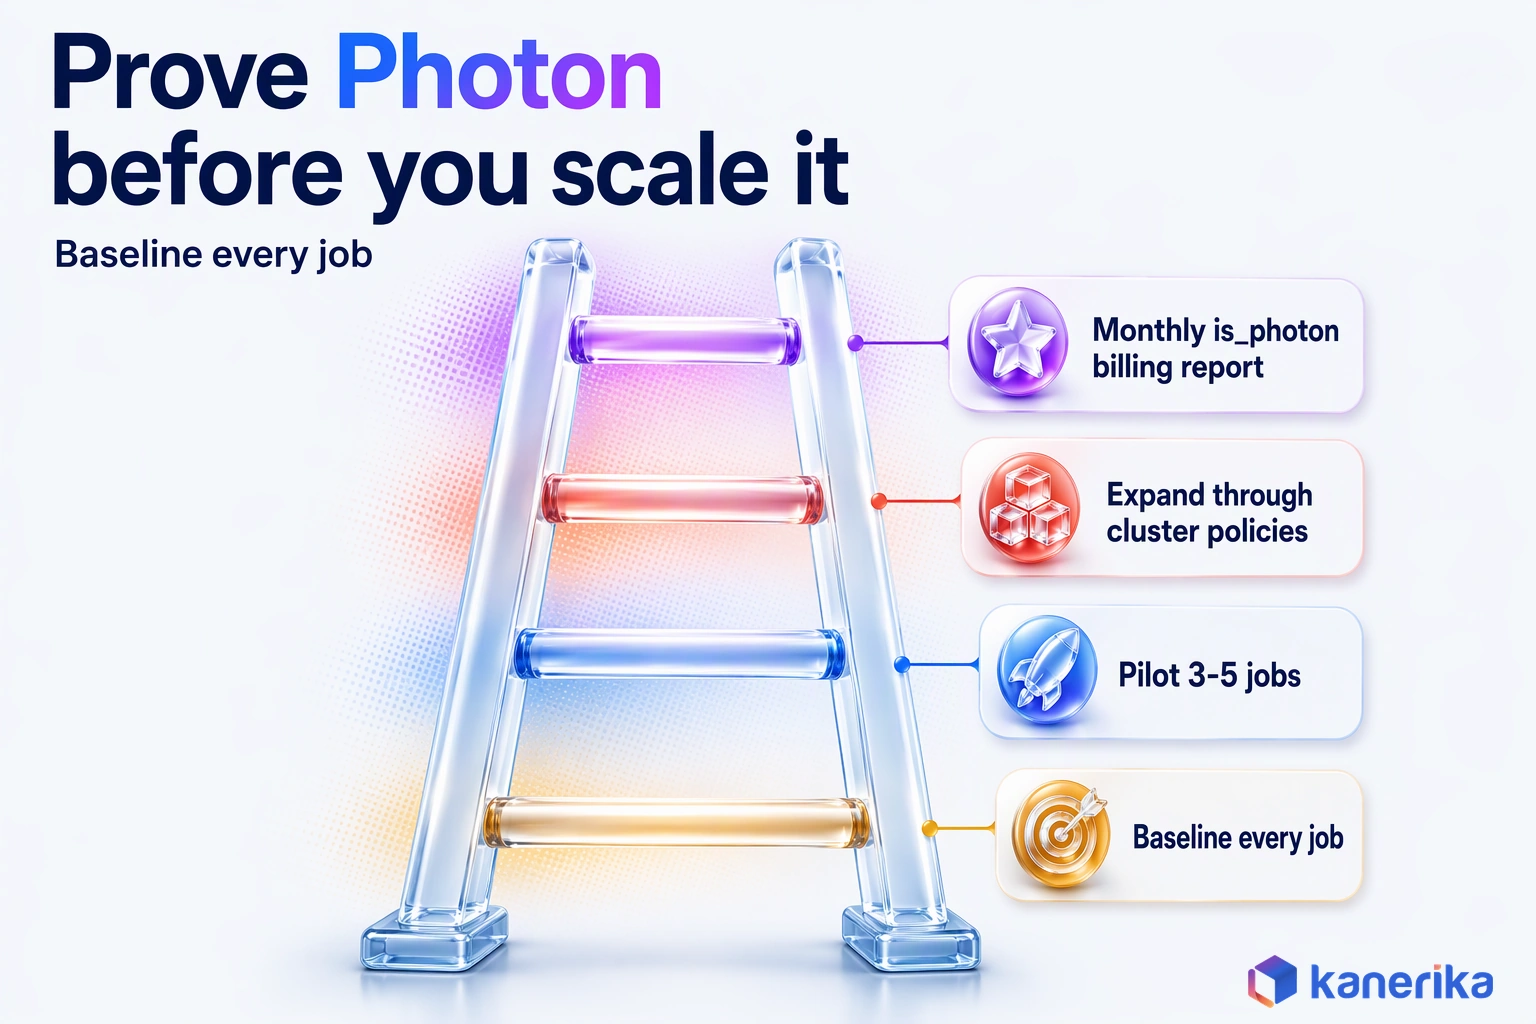
- Workload inventory and baseline: list jobs by compute type, engine and monthly DBUs, and record current runtimes.
- Pilot on three to five jobs: pick a mix of strong and doubtful candidates and run the seven-step benchmark.
- Measure coverage and cost: read the Photon share and compute cost per run with VM cost included.
- Expand with policies: roll the winning setting out through cluster policies per environment.
- Govern with billing reports: track is_photon spend monthly and re-test jobs when code or SKUs change.
Applying the Stages to a Real Kanerika Pipeline
The same measure-first method shaped Kanerika’s work with a leading financial services provider that runs fraud, risk and settlement monitoring. Its KPI reporting ran three days behind, and its data sat in protected S3 storage with little metadata. Analysts patched the gaps by hand in Excel.
Kanerika first built Airflow 2.0 pipelines that moved data out of protected S3 on a fixed schedule. Databricks then processed and enriched the data before it loaded to Dremio. Automated data quality rules, business glossary mappings and row-level security came with it, and pipeline logic replaced the Excel steps.
The client saw a 90% reduction in data lag, a 96% reduction in reporting latency and a 100% increase in BI adoption. Those published results come from the pipeline redesign, not from Photon.
Even so, a pipeline shaped like that one maps cleanly onto the five stages. The scheduled S3 loads and the Databricks enrichment jobs are scan and write work, so the stage-one inventory would list them first. Stage three would then show, through the Photon share and the cost per run, whether the enrichment step earns the higher DBU rate. Migrated warehouse code belongs in the same inventory, including SQL converted with Databricks Lakebridge, because it runs as ordinary Databricks SQL. That method is what turns a Photon line on a bill into a defensible number.
Kanerika’s Databricks consulting and implementation services cover this work end to end, from platform design to cost governance. The team holds ISO 27001, ISO 27701, SOC 2 and CMMI Level 3 credentials. Its data engineering services and data analytics services pick up the pipelines and dashboards that Photon accelerates.
Case Study
90% Less Data Lag with Databricks and Airflow
How Kanerika rebuilt ingestion with Airflow 2.0 and Databricks for a financial services provider, cutting data lag by 90% and reporting latency by 96%.
Read the Case Study →Conclusion: Is Databricks Photon Worth It?
Databricks Photon is worth it for scan, join and write-heavy SQL and DataFrame work. It also suits BI on SQL warehouses, where it is always on anyway. On classic compute, it earns its higher DBU rate only when it cuts runtime by more than the break-even ratio, with VM cost counted.
So prove it per job: benchmark on the same instance type, read the Photon share and compare cost per run. Then switch Photon off where Spark fallback dominates, and lock the result in with cluster policies so that Databricks Photon pays where it runs.
Frequently Asked Questions
What is Databricks Photon?
Databricks Photon is the native vectorized query engine inside the Databricks Runtime. It is written in C++ and processes data in columnar batches of thousands of rows. Spark’s Catalyst optimizer still plans each query, while Photon executes the supported operators. It speeds up SQL, DataFrame, ETL and stateless streaming work without any code changes.
How does Photon differ from Apache Spark?
Photon does not replace Spark as a framework. It replaces the JVM-based execution layer for supported operations, while Spark still handles planning and everything Photon cannot run. Photon uses native C++, SIMD instructions and columnar batches, so it avoids garbage collection pauses and JIT warm-up. Your Spark SQL and DataFrame code stays exactly the same.
When should you turn Photon off?
Turn Photon off on classic compute when a job gains too little to cover the higher DBU rate. Typical cases are Python-UDF-heavy jobs, RDD or Dataset API code, stateful streaming and short interactive queries. Confirm with a fair benchmark on the same instance type, comparing cost per run with VM cost included, before you decide.
Does Photon support streaming workloads?
Photon supports stateless streaming only. It accelerates streams that write to a Delta or Parquet sink from sources such as Delta, Parquet, CSV, JSON, Kafka and Kinesis. Stateful streaming, such as aggregations that keep state across micro-batches, is not supported. Those jobs run on the standard engine, so consider running them without Photon on classic compute.
Does Photon work on serverless compute and SQL warehouses?
Yes. Photon is always on for serverless compute, serverless Lakeflow pipelines and every SQL warehouse, and you cannot switch it off there. Always on does not mean full coverage, though. A query with a UDF still falls back to Spark for that step, so read the Photon share in the query profile when tuning.
Does Photon require code changes to existing workloads?
No. Photon is compatible with Apache Spark APIs, so existing SQL and DataFrame code runs on it unchanged across Python, R, Scala and Java. You only switch the engine on the compute. Some code will not benefit, though, because UDFs, RDD code and the Dataset API fall back to the standard Spark engine during execution.
Why does Photon sometimes show no performance improvement?
The usual cause is low Photon coverage. Python UDFs, RDD code, the Dataset API and stateful streaming all fall back to Spark, so little of the job runs natively. Queries that already finish in under about two seconds also gain nothing, because planning and scheduling dominate. Check the Photon share in the query profile first.
How do I enable Photon on a Databricks cluster?
In the compute UI, tick Use Photon Acceleration under Performance, which is on by default for classic clusters. Clusters and jobs created through the Clusters API or Jobs API need runtime_engine set to PHOTON. For the Pipelines API, set photon to true. A cluster policy can fix the runtime_engine value for a whole environment.
What is the DBU multiplier for Photon-enabled compute?
There is no single multiplier, because it varies by cloud, SKU and compute type. Photon compute consumes DBUs at a higher rate than the same instance without it. On Azure, classic Lakeflow pipelines list a Photon DBU emission rate of 2.9 times the non-Photon rate. Check your cloud’s Databricks pricing page for your SKU.
Do Python UDFs work with Photon?
Yes, they run, but not in Photon. Photon does not support UDFs, so those parts of the query fall back to the Spark runtime. The rest of the query can still use Photon. On classic compute you pay the Photon rate for the UDF time too, so replacing UDFs with built-in functions often pays off.
How do I check what percentage of a query ran on Photon?
On SQL warehouses and serverless compute, open the query profile. The Execution Details view shows the percentage of task time spent in Photon, with Photon operators in purple and standard ones in gray. On classic compute, use the Spark UI SQL/DataFrame tab. There, Photon operators appear orange and standard Spark operators appear blue.
Is Photon enabled by default on Databricks?
Yes, in most places. Photon is always on for SQL warehouses, serverless compute and serverless Lakeflow pipelines. Classic all-purpose compute, jobs compute and classic Lakeflow pipelines enable it by default through a checkbox in the UI. Clusters and jobs created through the API are the exception, since they need runtime_engine set to PHOTON explicitly.
Which workloads benefit most from Databricks Photon?
Photon helps most with long-running SQL and DataFrame work on large datasets. That includes big scans, joins and aggregations, wide-table writes, and MERGE, UPDATE and DELETE on Delta tables. BI dashboards with many concurrent users also benefit on SQL warehouses. Stateless streaming into Delta and feature engineering written in SQL or DataFrames are good candidates too.