TL;DR
Call the Databricks API through the Python SDK or CLI by default, and use raw REST only for the gaps. Authenticate automation with OAuth token federation or M2M OAuth, whose tokens last one hour. Keep personal access tokens for quick tests, never for production. Jobs API 2.2 queues runs by default and pages lists at 100 items. The Supervisor API ended on September 30, 2026. Give AI agents managed MCP servers, Genie Agents or the Agent Bricks CLI instead of raw endpoints.
Key Takeaways
- Databricks API calls split into workspace APIs, which use the workspace URL, and account APIs, which instead add an account ID.
- Databricks recommends its SDKs or CLI over raw REST, because they handle tokens, paging and retries.
- OAuth token federation is the recommended login for automation, and M2M tokens last 3,600 seconds.
- Jobs API 2.2 queues new runs by default, caps list fields at 100 items and also allows 20 run-now requests per second per workspace.
- The Statement Execution API runs SQL over HTTP and waits 10 seconds by default before returning a statement ID.
- Since the Supervisor API ended on September 30, 2026, Databricks now points teams to their own agent loop deployed with the Agent Bricks CLI. Managed MCP servers then supply the governed tools.
A Friday Deploy With Forty Hand-Built Jobs
Picture a platform engineer on a Friday afternoon with forty nightly jobs to copy from development to production. Each was built by clicking through the UI, so each must be rebuilt by hand. One missed parameter means a failed 2 a.m. run and a pager alert.
Done through the Databricks API, the same move is a short script or one bundle deploy. The jobs live as code, a service principal owns them, and the deploy runs the same way every time. Apps are deployed through the same API and bundle route, covered in how to build and deploy Databricks Apps.
Everything below reflects the Databricks docs as of November 3, 2026, and most sections end with a snippet you can run.
What Is the Databricks API?
The Databricks API is a collection of REST endpoints that control a Databricks deployment from code. Almost every action in the workspace UI has an endpoint behind it, from starting a cluster to granting access to a table.
Teams reach for it because clicking does not scale, as the Friday example shows. Code removes the manual cluster and job work, so tools such as Airflow or a CI server can drive the platform. The same script then handles hundreds of jobs with no person in the loop.
New to the platform itself? Start with this overview of the Databricks platform.
| API family | Host you call | What it manages | Example path |
|---|---|---|---|
| Workspace APIs | Your workspace URL | Clusters, jobs, SQL warehouses, Unity Catalog objects | /api/2.0/clusters/list |
| Account APIs | Account console URL plus account ID | Workspaces, users, groups, service principals | /api/2.0/identity/accounts/<id>/users |
Workspace APIs vs Account APIs
Workspace APIs act inside a single workspace, so their host is that workspace’s URL. Account APIs act across the whole account, so they use the account console URL plus your account ID.
Host URLs also differ by cloud, so an AWS script will not reach an Azure or GCP workspace until you change the host. Keep the host in configuration rather than in code, a habit that also pays off in multi-workspace deployments.
How Endpoint Versions Work
Databricks versions each service on its own, not the platform as a whole. For example, Clusters sit at /api/2.0/clusters, Jobs at /api/2.2/jobs and SQL statements at /api/2.0/sql/statements.
So pin the version per service in your client code, and read that service’s release notes before you move to a newer one.
Checklist
Databricks Readiness Checklist
Before you script a workspace through the API, confirm the platform, security and governance foundations are in place. This checklist walks through the items to settle first.
REST, SDK, CLI or MCP: Which Interface Fits Your Team?
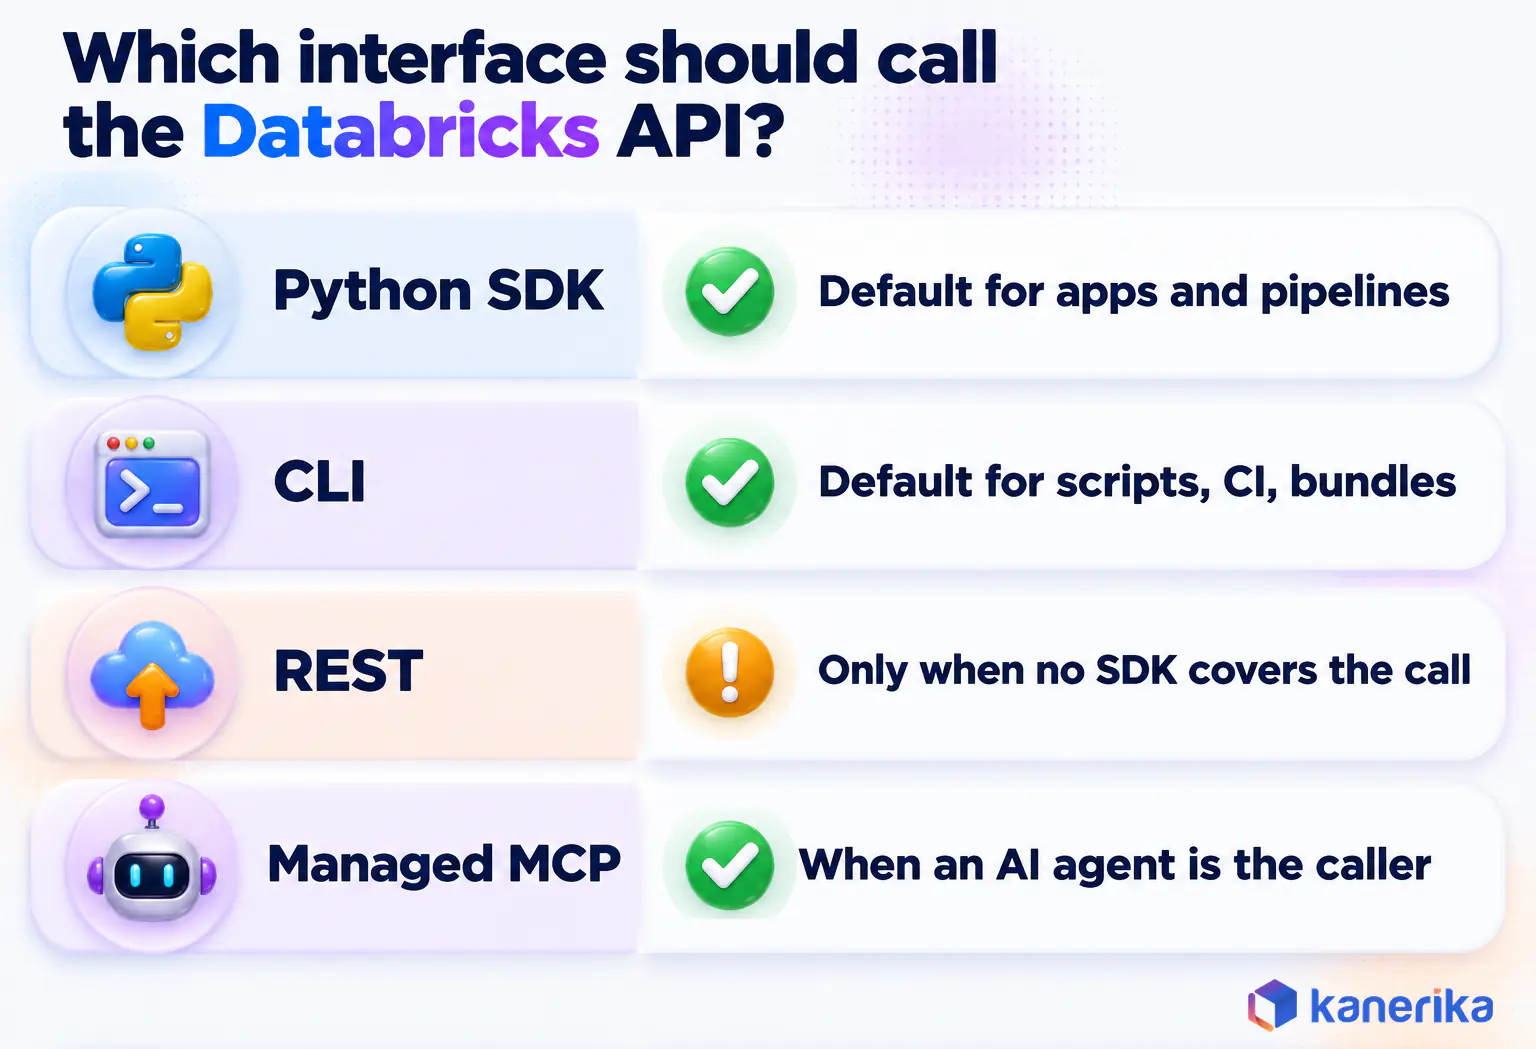
Four interfaces sit on top of the same endpoints, and the right one depends on who or what is making the call. The official Databricks REST API reference recommends the SDKs or CLI for most work and keeps raw REST for advanced cases.
The reason is plumbing. An SDK reads your credentials, refreshes OAuth tokens and follows pagination, while raw HTTP leaves all of that to you.
| Interface | Best for | Auth handling | Example |
|---|---|---|---|
| REST over HTTP | Languages without an SDK, endpoints an SDK lacks | You fetch and refresh tokens yourself | curl GET /api/2.0/clusters/list |
| Python SDK (databricks-sdk) | Applications, pipelines, notebooks | Unified auth with automatic token refresh | WorkspaceClient().clusters.list() |
| Databricks CLI | Shell scripts, CI jobs, bundle deploys | Profiles and environment variables | databricks clusters list |
| Managed MCP servers | AI agents that call tools | OAuth plus Unity Catalog permissions | /api/2.0/mcp/functions/{catalog}/{schema}/{function} |
The Python SDK on PyPI is at version 0.160.0 and still carries a Beta label there. Meanwhile the Databricks CLI has been GA since 1.0.0, and its newest release is v1.23.0 from October 29, 2026.
Versions 0.205 to 0.299 were Public Preview and 0.18 and below are unsupported, so audit shared runners. The CLI also drives bundle deploys, which this bundle walkthrough covers step by step.
How to Authenticate with the Databricks API
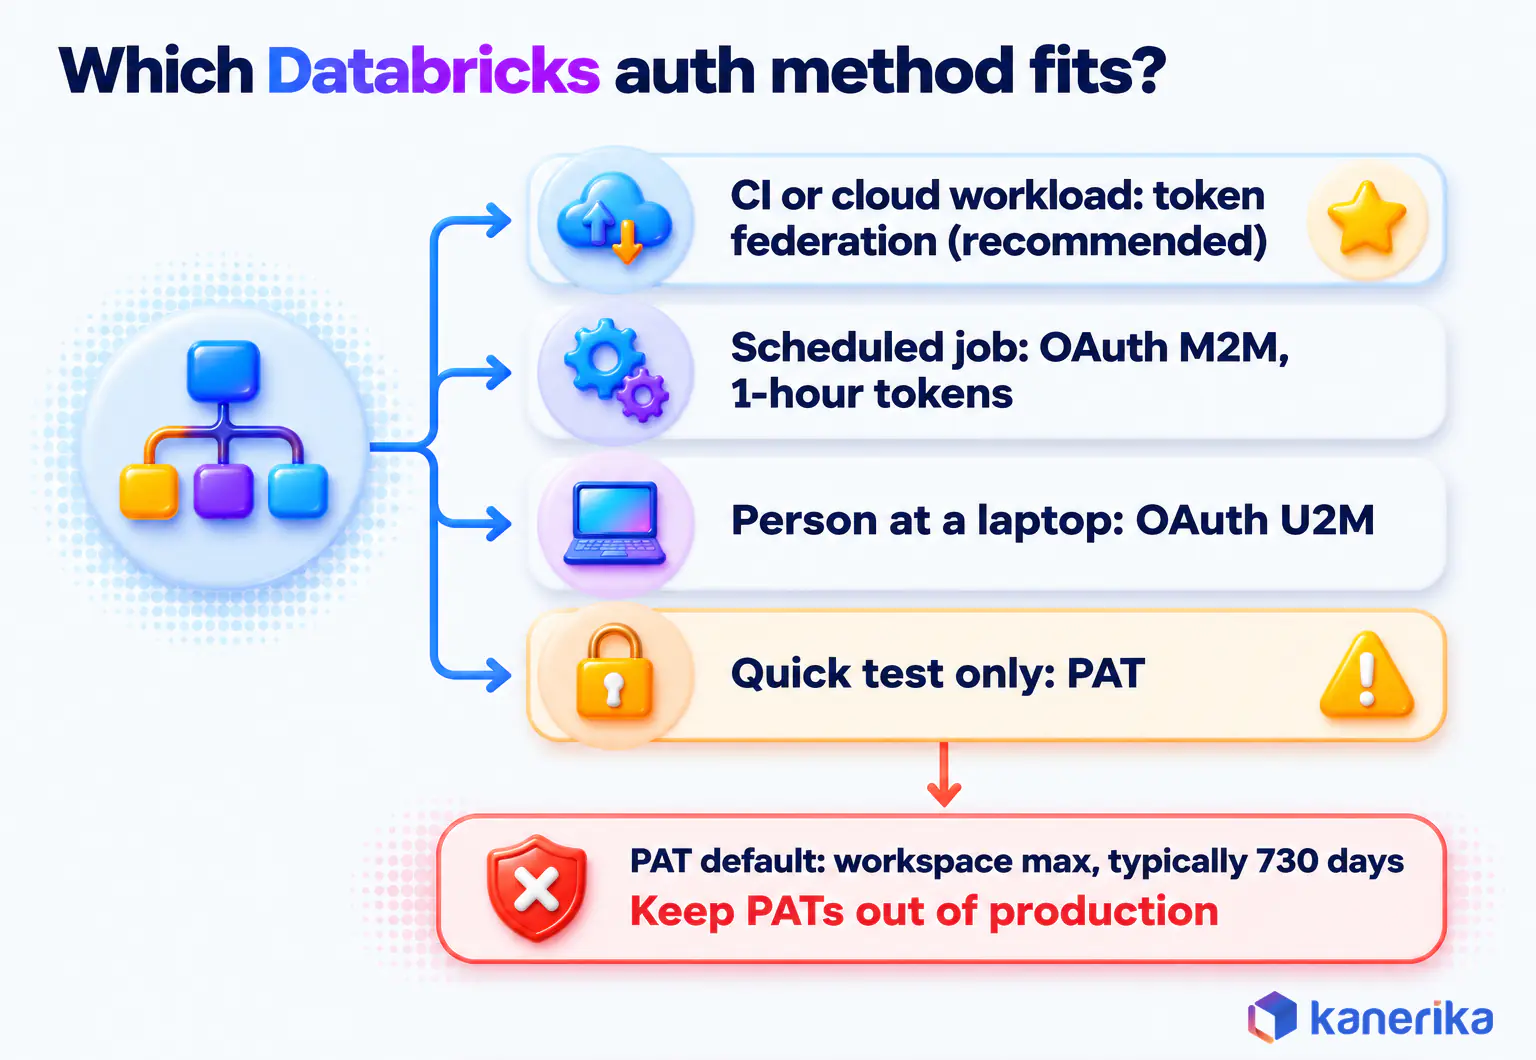
Every call carries a token, and the way you get that token decides how safe the integration is. The Databricks authentication docs list OAuth token federation as recommended, then OAuth for service principals (M2M) and OAuth for users (U2M).
All three rest on the OAuth 2.0 framework in RFC 6749, because it defines the client credentials grant used for machine access. For wider platform controls, see this guide to Databricks security.
OAuth Token Federation (Recommended)
Token federation lets a workload trade a token from your own identity provider for a short-lived Databricks token. A CI system or cloud workload proves its identity, and Databricks then issues an access token.
Because nothing long-lived has to be stored, Databricks recommends it first.
OAuth M2M for Service Principals
Machine-to-machine OAuth is the workhorse for scheduled jobs and back-end services. A service principal holds a client ID and secret, posts them to the workspace token endpoint and then gets an access token back.
curl --request POST \
  --url "https://<workspace-host>/oidc/v1/token" \
  --user "$DATABRICKS_CLIENT_ID:$DATABRICKS_CLIENT_SECRET" \
  --data "grant_type=client_credentials&scope=all-apis"
The response carries an access_token and an expires_in value of 3600, so each token lasts one hour, as the OAuth M2M guide shows. For account-level calls, post to https://accounts.cloud.databricks.com/oidc/accounts/<account-id>/v1/token instead.
The SDKs run this exchange and the hourly refresh for you. On-behalf-of access for service principals is still in Beta, so treat it as a preview.
OAuth U2M for Interactive Users
User-to-machine OAuth, by contrast, is for a person at a keyboard. Running databricks auth login opens a browser, you sign in through your identity provider, and the CLI caches a token it can refresh.
It suits local development, but not a job that runs at 2 a.m.
Personal Access Tokens: When They Still Fit
A personal access token (PAT) is a static bearer string tied to one user and one workspace. Databricks still states its preference for OAuth plainly in the PAT documentation.
The main risk, however, is lifetime. A new PAT defaults to the workspace’s maximum lifetime, typically 730 days, so a leaked token can stay valid for two years. PATs now support scopes too, and Databricks can auto-scope a token after a 30-day observation period.
Use a PAT for a quick test or a tool that cannot speak OAuth. Otherwise, keep it out of production code, notebooks and repositories.
Unified Authentication: Environment Variables and .databrickscfg Profiles
Unified authentication is the shared lookup the SDKs and CLI use to find credentials. They check environment variables first and then a named profile in ~/.databrickscfg, so the same code runs on a laptop and in CI.
# CI runners: environment variables
export DATABRICKS_HOST="https://<workspace-host>"
export DATABRICKS_CLIENT_ID="<service-principal-application-id>"
export DATABRICKS_CLIENT_SECRET="<read-from-your-vault>"

# Laptops: a profile in ~/.databrickscfg
[prod-automation]
host = https://<workspace-host> client_id = <service-principal-application-id> client_secret = <read-from-your-vault>
Switch environments with the DATABRICKS_CONFIG_PROFILE variable or the –profile flag. On shared machines, keep the secret in a vault and inject it at runtime instead.
Your First Databricks API Calls
The fastest way to learn the API is to list something and then run something.
First, the cURL call sends a GET request to the clusters list endpoint. Its host is your workspace URL, and the Authorization header carries a bearer token from any method above.
curl --request GET \
  --url "https://<workspace-host>/api/2.0/clusters/list" \
  --header "Authorization: Bearer $DATABRICKS_TOKEN"
A JSON body then comes back with a clusters array, holding each cluster’s ID, name and state. An HTTP 401 means the token is wrong or expired, while a 403 means it is valid but lacks permission.
Next, the SDK version does the same listing, then triggers an existing job and waits for it. WorkspaceClient() finds credentials through unified authentication, so no token appears in the code.
from databricks.sdk import WorkspaceClient

w = WorkspaceClient()

for cluster in w.clusters.list():
    print(cluster.cluster_name, cluster.state)

run = w.jobs.run_now(job_id=123456).result()  # blocks until the run ends
print(run.run_id, run.state.result_state)
Here run_now returns a waiter, and .result() then blocks until the run reaches a final state. In a real pipeline, also set a timeout and log the run ID, so any failure traces back to the exact run.
Kanerika Service
Databricks Implementation and Automation
Kanerika, a certified Databricks partner, designs workspaces, automates jobs and pipelines through the API, and sets up governance with Unity Catalog.
Automating Workflows with Jobs API 2.2
The Jobs API turns notebooks, scripts and SQL into scheduled, repeatable runs. When Airflow, Azure Data Factory or a CI pipeline “runs the Databricks job,” this is the API it calls. For the concepts behind it, see this guide to Databricks workflows as well.
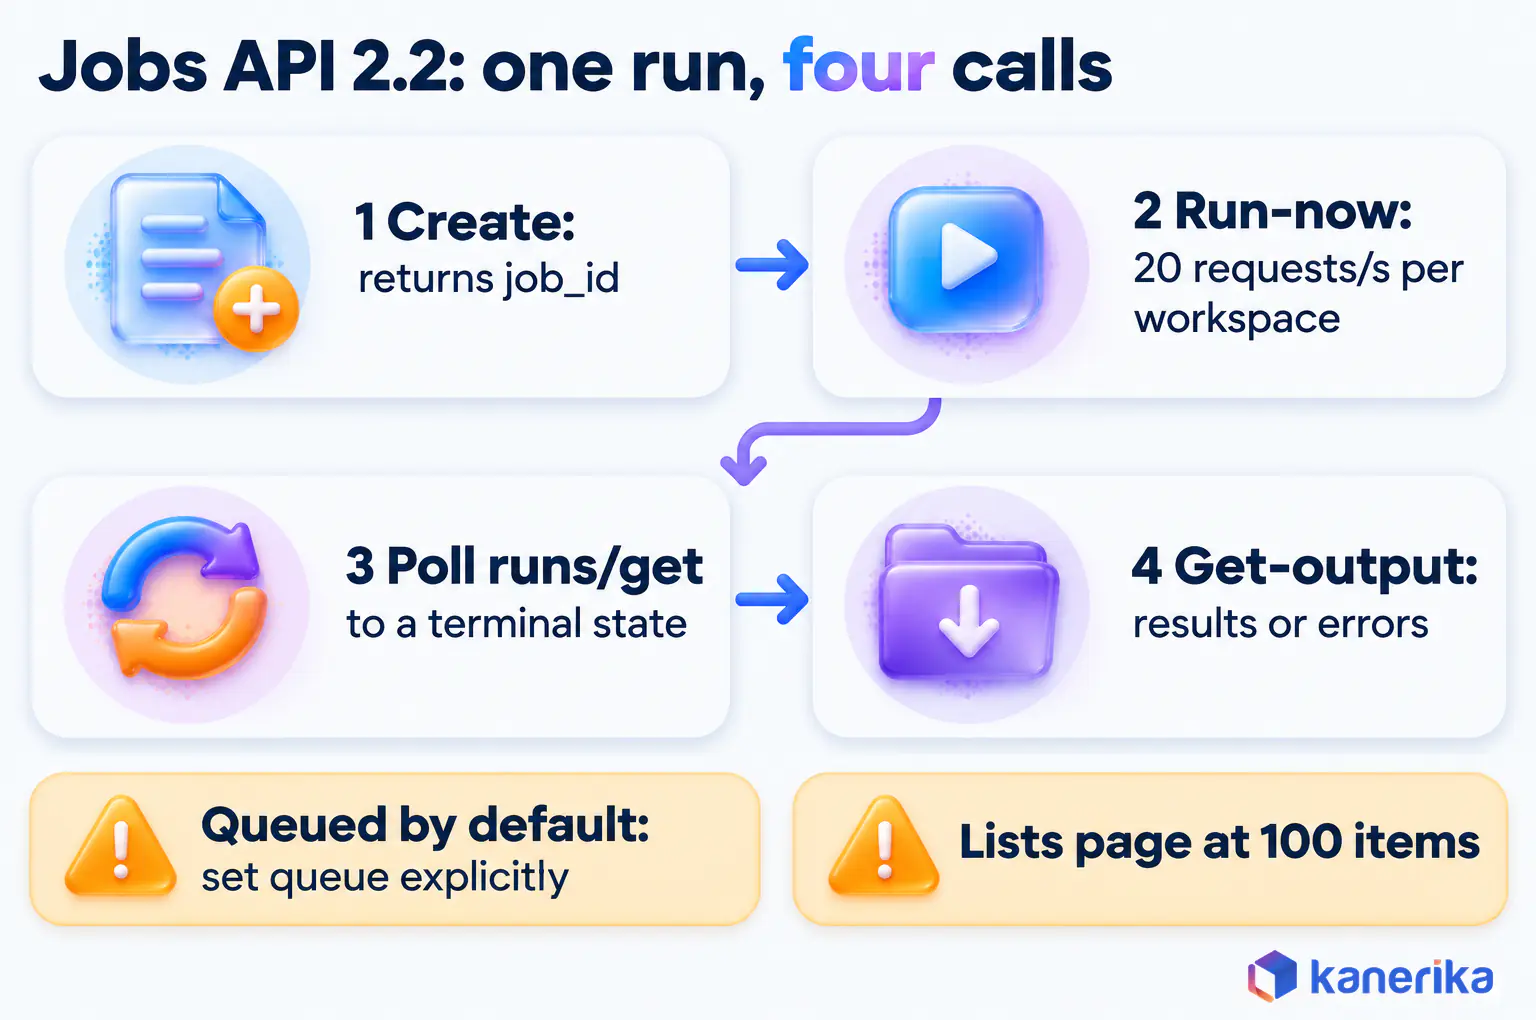
A job’s life comes down to four calls.
- Create: POST /api/2.2/jobs/create with tasks, compute and a schedule, and the response returns a job_id.
- Trigger: POST /api/2.2/jobs/run-now with the job_id and any parameters, and the response returns a run_id.
- Poll: GET /api/2.2/jobs/runs/get with the run_id until the run reaches a terminal state.
- Read output: GET /api/2.2/jobs/runs/get-output for a task run to fetch its output or error message.
Version 2.2 changed two defaults that catch teams moving from 2.1, according to the Jobs API 2.2 update notes. New jobs are queued by default, so a run waits for capacity instead of being skipped. Set queue to false for the old behavior. Jobs created through 2.0 or 2.1, by contrast, need queue set to true to get queueing.
Then there is paging. List fields such as tasks and job clusters now stop at 100 elements per response, and the rest arrive through next_page_token. So code that assumed one response held every task will quietly skip work on large jobs.
Pipelines built with Databricks Lakeflow run on the same job machinery, so the same rules apply there too.
Running SQL with the Statement Execution API
The Statement Execution API runs SQL on a SQL warehouse over plain HTTP, with no JDBC or ODBC driver. It suits small services and scripts that need a result without a full client library.
The core flow takes three calls, as the Statement Execution API tutorial shows. A fourth call, POST …/cancel, stops a statement you no longer need.
- Submit: POST the statement and a warehouse_id to /api/2.0/sql/statements.
- Wait or poll: the call waits 10 seconds by default, and a slower query returns a statement_id you poll with GET /api/2.0/sql/statements/{statement_id}.
- Fetch: read the result inline from the response, or download it through external links when it is large.
{
  "warehouse_id": "<warehouse-id>",
  "statement": "SELECT region, SUM(amount) AS revenue FROM sales.orders GROUP BY region",
  "wait_timeout": "30s",
  "on_wait_timeout": "CANCEL",
  "disposition": "INLINE",
  "format": "JSON_ARRAY"
}
First, wait_timeout sets how long the call blocks. Then, with on_wait_timeout set to CANCEL, the query stops when that window passes instead of running on in the background.
| Disposition | Formats | Best for | Watch out for |
|---|---|---|---|
| INLINE (default) | JSON_ARRAY | Small results returned in the response | Results over 25 MiB fail and cancel the statement |
| EXTERNAL_LINKS | JSON, CSV, ARROW_STREAM | Large extracts and downstream loads | Links grant direct download access |
A serverless SQL warehouse starts quickly, typically in 2 to 6 seconds, which suits this request-and-response traffic.
Managing Clusters and SQL Warehouses Through the API
Compute is where Databricks API automation saves the most money, because an idle cluster bills whether anyone uses it or not. The Clusters API and the SQL Warehouses API cover the full lifecycle, from create and start to resize and terminate.
Even so, the bigger decision is cluster type. A job cluster is created for one run and shuts down when the run ends, while an all-purpose cluster stays up for interactive work. Scheduled jobs therefore belong on job clusters, a point this Databricks cost optimization guide expands on.
Talk to Kanerika
Want a Second Look at Your Databricks Automation?
Kanerika reviews how your jobs, clusters and credentials are wired through the API, then maps the changes that cut idle compute and remove long-lived tokens.
Avoid hardcoding a runtime version string, too. Instead, query GET /api/2.0/clusters/spark-versions and pick from that list, so a retired version never breaks a deploy. For training and inference compute, see Databricks AI Runtime, and for tuning, the performance optimization guide.
Unity Catalog APIs for Governance
Unity Catalog is the governance layer of Databricks, and its APIs manage catalogs, schemas, tables and grants as code instead of clicks. That matters when a new team needs identical permissions in three workspaces by Monday morning.
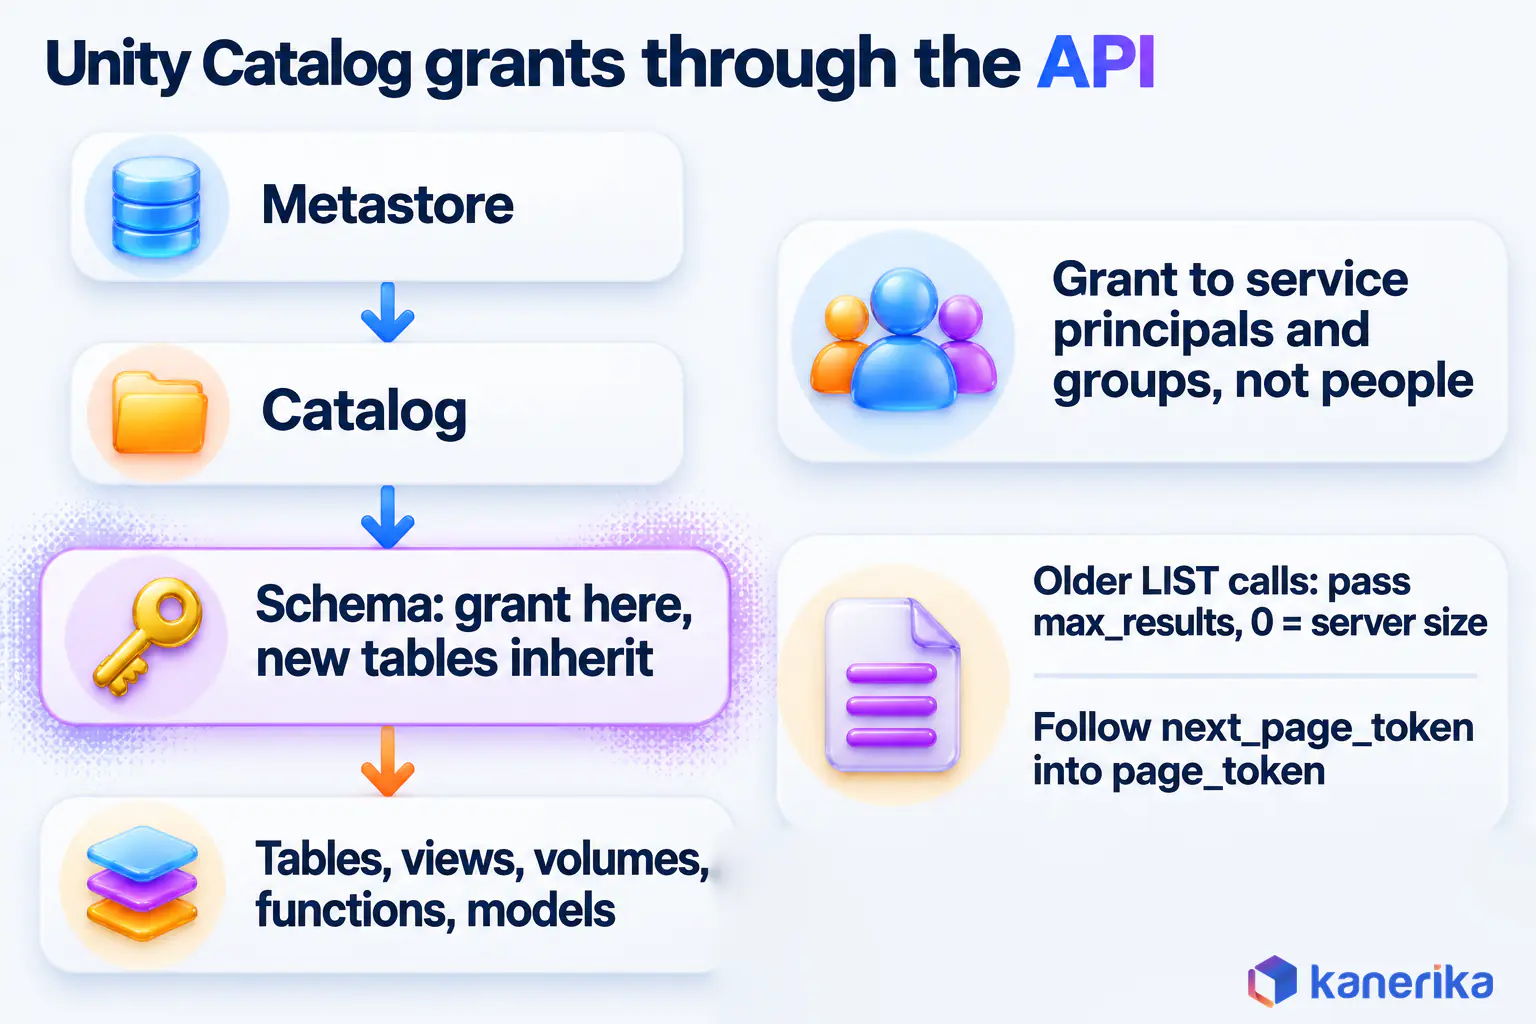
Objects also nest in a fixed order. A metastore holds catalogs, catalogs hold schemas, and schemas hold tables, views, volumes, functions and models. Because grants follow that tree, a privilege on a schema reaches the tables inside it.
The Unity Catalog guide explains the model in full, while the API simply exposes it. Grants can also run as SQL GRANT statements through the Statement Execution API, which is easier to review in a pull request.
Two habits also keep this manageable. Grant to service principals and groups rather than to people, and grant at schema level where you can, so new tables inherit access.
Some older Unity Catalog LIST calls only page when you pass max_results, and a value of 0 lets the server pick the page size. For the program around these controls, see Kanerika’s data governance services.
Model Serving and Foundation Model APIs
Model Serving exposes models as REST endpoints inside your workspace, and Foundation Model APIs also add hosted models from several providers. You call a serving endpoint with a workspace token, just like any other Databricks API endpoint.
As of November 3, 2026, the supported models page lists endpoints such as these, but names change as models arrive and retire.
| Model | Endpoint name |
|---|---|
| Claude Opus 5.5 | databricks-claude-opus-5-5 |
| Claude Sonnet 5.5 | databricks-claude-sonnet-5-5 |
| GPT-6.1 Sol | databricks-gpt-6-1-sol |
| Gemini 4 Argon | databricks-gemini-4-argon |
| Gemini 3.8 Flash | databricks-gemini-3-8-flash |
| Grok 4.7 | databricks-grok-4-7 |
| gpt-oss-120b | databricks-gpt-oss-120b |
Still, the list moves quickly in both directions. Claude Opus 5.5 was announced on September 22, Claude Sonnet 5.5 on September 28 and GPT-6.1 Sol on September 29, 2026.
On the way out, DeepSeek V4 Flash (0731) is scheduled to retire on November 5, 2026. DeepSeek V4.1 Flash is set to follow on November 19. For a wider view, see this roundup of generative AI models.
Billing Modes and Cost Math
Billing comes in four modes, per the Foundation Model APIs documentation.
- Pay-per-token: shared capacity, billed on the tokens you send and receive.
- Priority pay-per-token: the same billing unit with higher priority on capacity.
- Provisioned throughput: dedicated capacity, on demand or reserved for one or three months.
- Batch inference: large offline jobs run through AI Functions.
The cost math is simple, though, once you know the unit. Price equals the dollar rate per DBU times the DBU rate a model consumes. The foundation model serving pricing page uses $0.07 per DBU in AWS US East as its example. So, as an illustration only, a model rated at 100 DBUs per million tokens would cost $7.00 per million tokens.
For model calls written directly in SQL, by contrast, see Databricks AI Functions. The wider training and serving stack is covered in this guide to Mosaic AI.
Building AI Agents on Databricks APIs in Late 2026
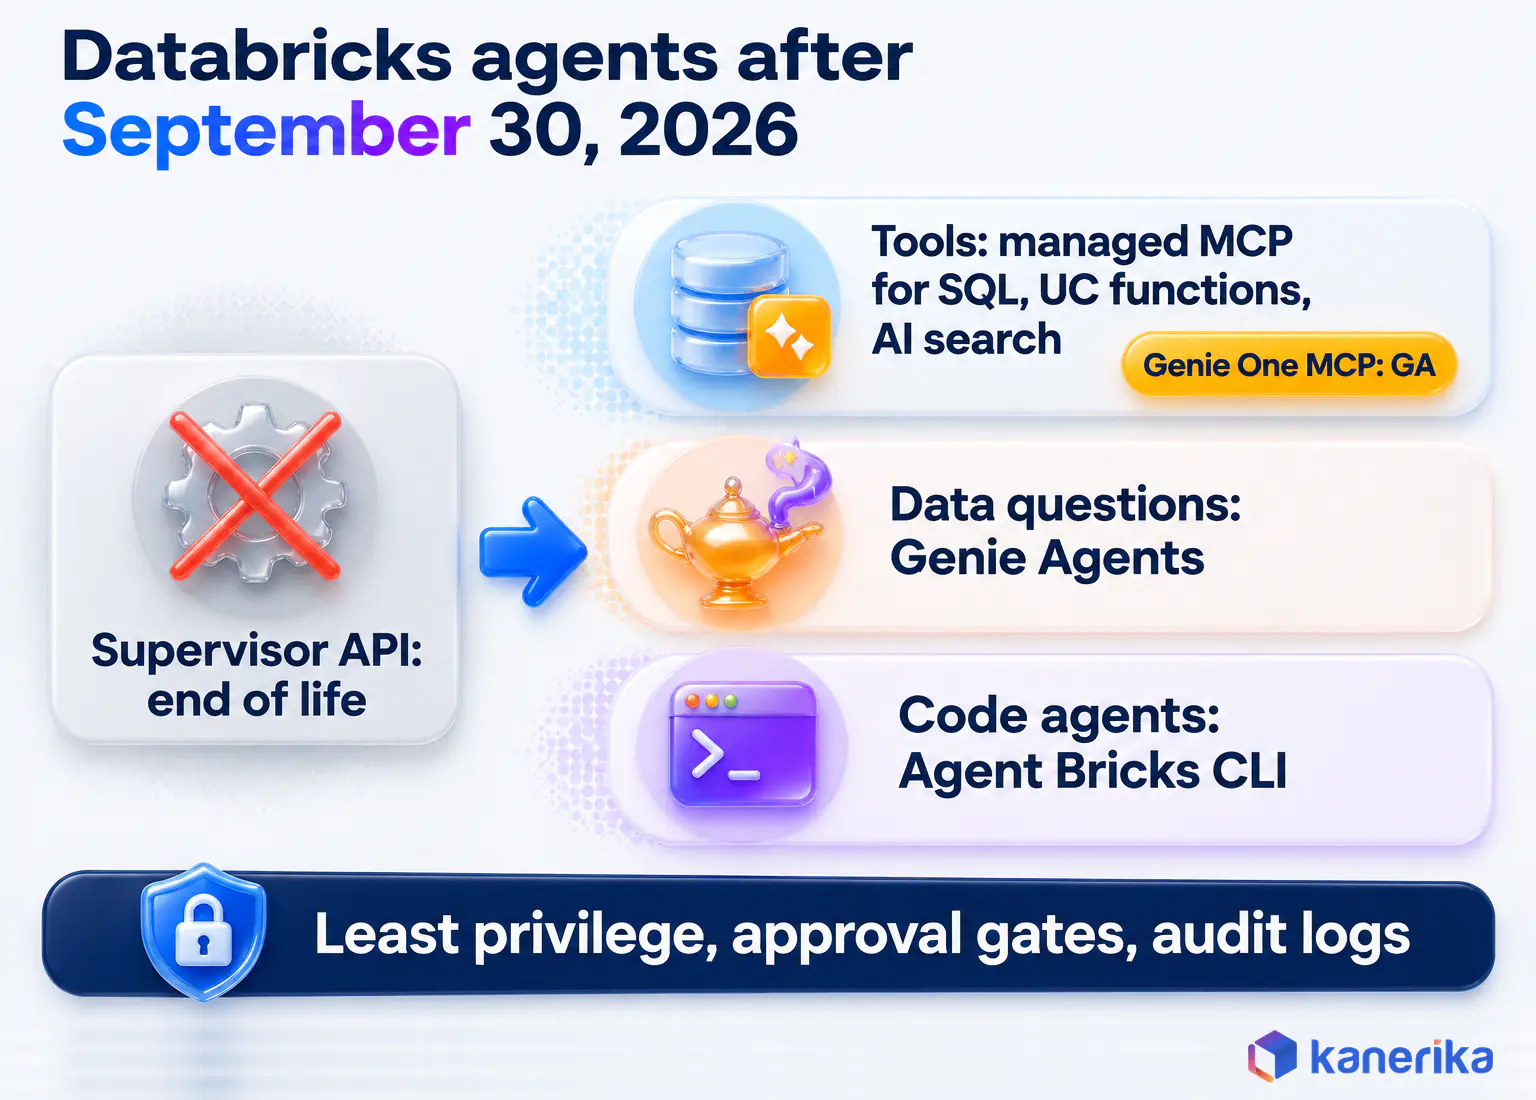
Agent work on Databricks changed shape on September 30, 2026, when the Supervisor API reached end of life. It is no longer available, and the Supervisor API page now points teams to their own agent loop plus the Agent Bricks CLI. The older Supervisor Agent is also labeled legacy and is not recommended for new systems.
What comes next splits by job, because each piece serves a different caller. Managed MCP servers give an agent governed tools, Genie Agents answer questions over your data, and the Agent Bricks CLI scaffolds and deploys code agents. Read more in this Agent Bricks guide and also the Databricks Genie overview.
Managed MCP Servers and Guardrails
Managed MCP servers run on Model Context Protocol, so any MCP-aware client can call them. The managed MCP documentation lists these endpoints.
| Managed MCP server | Path | What the agent gets | Status |
|---|---|---|---|
| Databricks SQL (existing integrations) | /api/2.0/mcp/sql | Governed SQL queries on your warehouse | Public Preview |
| Unity Catalog functions | /api/2.0/mcp/functions/{catalog}/{schema}/{function} | A registered function exposed as a tool | Public Preview |
| AI search | /api/2.0/mcp/ai-search/{catalog}/{schema}/{index} | Retrieval from a search index | Public Preview |
Genie One MCP is generally available, per the same page. For new SQL integrations, however, Databricks says to use system.ai.dbsql, which needs an account admin to enable the Unity Gateway beta. Every one of these runs under Unity Catalog permissions, so an agent sees only what its identity can see. To govern model and tool traffic in one place, read about the Unity AI Gateway.
Above all, treat each agent as a production identity. Give it a service principal with least privilege, and put an approval gate in front of any tool that writes or deletes. Then keep audit logs of every tool call.
Teams picking assistant products face a similar trade-off between reach and control, as Microsoft Copilot vs ChatGPT shows. For multi-agent designs, see these AI agent orchestration patterns and Kanerika’s agentic AI services.
Rate Limits, Pagination and Error Handling
Every endpoint enforces rate limits, set per endpoint and per workspace, and a busy pipeline will hit them. When it does, the server answers with HTTP 429 Too Many Requests, a status code defined in RFC 6585 that may carry a Retry-After header.
Databricks asks clients to back off with jitter and to wait at least as long as Retry-After says. Its resource limits page lists the numbers, and two of them in particular shape most orchestration designs.
| Endpoint | Limit | What it means for you |
|---|---|---|
| /jobs/run-now | 20 requests per second per workspace | Throttle fan-out triggers from schedulers |
| /jobs/runs/submit | 35 requests per second per workspace | One-off runs get a little more headroom |
For example, the retry wrapper below covers the common case. It retries 429 and 503 responses, honors Retry-After and adds random jitter, so parallel workers do not retry in lockstep.
import random
import time
import requests

def call_with_retry(method, url, headers, max_attempts=6, **kwargs):
    for attempt in range(max_attempts):
        resp = requests.request(method, url, headers=headers, timeout=60, **kwargs)
        if resp.status_code not in (429, 503):
            resp.raise_for_status()
            return resp
        retry_after = float(resp.headers.get("Retry-After", 0))
        backoff = min(60, 2 ** attempt) + random.uniform(0, 1)
        time.sleep(max(retry_after, backoff))
    raise RuntimeError(f"Gave up after {max_attempts} attempts: {url}")
Pagination, by contrast, follows one pattern across most list calls. Read next_page_token from each response and send it back as page_token until it comes back empty.
Other errors need a fix rather than a retry. A 400 means fix the request, a 401 means refresh the token, and a 403 means fix the permission. When a failure fits none of these, the Databricks troubleshooting guide covers the usual suspects.
Kanerika Service
Build Pipelines That Survive Limits and Failures
Kanerika’s data engineering team designs monitored, retry-safe pipelines on Databricks, from ingestion and orchestration to data-quality checks.
Production Patterns: CI/CD, Terraform and Orchestration
In production, teams rarely write HTTP calls by hand. Instead they use four layers of tooling, and each layer calls the Databricks API on their behalf.
- Declarative Automation Bundles in CI: jobs, pipelines and their settings live in YAML, and CI runs databricks bundle validate, deploy and run, per the bundles documentation.
- The Terraform provider for infrastructure: workspaces, Unity Catalog objects, cluster policies and permissions become reviewed code.
- Airflow or Azure Data Factory for orchestration: the scheduler calls run-now and polls the run, so Databricks work slots into a wider pipeline.
- Event-driven agent calls: a queue message or webhook triggers a serving endpoint or job, and the result flows back.
This split also keeps ownership clear. Platform teams own the Terraform, data teams own the bundles, and the orchestrator only triggers and watches. Model lifecycle work follows the same logic, for example in this Databricks MLOps guide.
Many teams build these layers during a migration off a legacy scheduler or ETL tool. Writing the new jobs as code from the first week avoids rebuilding them twice. This Databricks ETL guide shows how those pipelines usually take shape.
Security Checklist for Databricks API Integrations
API incidents usually trace back to a credential that lived too long or could do too much. The checklist below therefore closes the common gaps.
- Run automation as service principals, never as a named user.
- Prefer OAuth token federation, then M2M OAuth, so no long-lived secret exists.
- Keep PATs out of code and repositories.
- Store client secrets in a vault or in Databricks secrets, and then read them at runtime.
- Scope tokens and grants to what each job needs.
- Rotate client secrets and any remaining PATs on a fixed schedule.
- Turn on audit logs and review API activity by service principal.
- Treat EXTERNAL_LINKS result URLs as secrets and never log them.
Run the list before each integration reaches production.
How Kanerika Builds on the Databricks API
Kanerika is a certified Databricks partner, and its delivery work uses the API to enforce platform standards. Engagements follow four stages.
- Assess the workspace and auth model: move PAT-based automation to service principals and OAuth.
- Codify the platform: express jobs, clusters and permissions in Declarative Automation Bundles and Terraform.
- Wire orchestration: connect Airflow or Azure Data Factory to Jobs API runs, with retry logic and monitoring from the data engineering practice.
- Add governed AI access: expose data to agents through Unity Catalog permissions and managed MCP servers.
For teams moving onto Databricks, FLIP, Kanerika’s migration accelerator platform, automates paths such as Informatica, Alteryx and DataStage to Databricks. The migrated jobs then go through the same bundle and Terraform setup as new work. The DataStage to Databricks datasheet summarizes how FLIP handles that migration.
In one engagement, a financial services provider had KPI reporting running three days behind, with source data held in protected S3 storage. Kanerika built Airflow 2.0 ingestion pipelines, processed the data in Databricks and loaded it into Dremio, adding row-level security and automated data-quality rules.
The client reported a “90% reduction in data lag from source to consumption” as a result. Reporting sped up too, with a “96% reduction in reporting latency, down from a three-day cycle.” BI usage grew as well, with a “100% increase in BI adoption across reporting teams.” That is the pattern from the Jobs API section, where Airflow orchestrates and Databricks runs the processing.
Case Study
90% Less Data Lag with Databricks and Airflow
A financial services provider cut data lag by 90% and reporting latency by 96% with Airflow ingestion, Databricks processing and automated data-quality rules.
Overall, the practical lessons carry over. Start every integration with a read-only service principal and widen access only when a job needs it. Store secrets outside code from the first commit, and set the queue field explicitly when you move jobs to Jobs API 2.2.
Wrapping Up
One set of endpoints sits behind several front doors. The SDK and CLI fit most work, raw REST fills the gaps, and managed MCP servers give agents a governed way in. Meanwhile OAuth, through federation or M2M, keeps every caller on short-lived tokens.
Start small with one service principal, one job and one retry wrapper, and only then grow into bundles and Terraform. Pick one nightly job this week, move it to a service principal with M2M OAuth, and deploy it from a bundle.
Frequently Asked Questions
What is the Databricks API and what does it cover?
The Databricks API is a set of REST endpoints that control a Databricks deployment from code. Workspace APIs manage clusters, jobs, SQL warehouses and Unity Catalog objects, while account APIs manage workspaces, users and groups. Model serving, SQL statements and managed MCP servers for AI agents run through the same authenticated surface, so one token model covers everything.
Should I use the Databricks SDK, CLI or REST API?
Databricks recommends its SDKs or CLI for most work, because they handle authentication, token refresh and pagination for you. Use the Python SDK inside applications and pipelines and the CLI in scripts, CI jobs and bundle deploys. Keep raw REST calls for languages without an SDK or for endpoints an SDK does not cover yet.
How do I run SQL queries through the Databricks API?
Use the Statement Execution API. Send the SQL statement and a warehouse_id to /api/2.0/sql/statements. The call waits 10 seconds by default, and a slower query returns a statement ID that you poll. Small results come back inline as a JSON array, while large results arrive through external links in JSON, CSV or Arrow format.
Can I call Claude or GPT models through the Databricks API?
Yes. Foundation Model APIs host models such as Claude Opus 5.5, Claude Sonnet 5.5 and GPT-6.1 Sol as serving endpoints, for example databricks-claude-opus-5-5. You query them with a workspace token and choose pay-per-token, priority pay-per-token or provisioned throughput billing. Read endpoint names from the supported models page, because models arrive and retire often.
What is the difference between workspace and account APIs?
Workspace APIs manage resources inside one workspace, such as clusters, jobs, SQL warehouses and Unity Catalog objects, and they use the workspace URL as the host. Account APIs manage resources across the whole account, such as workspaces, users, groups and service principals, and they use the account console URL plus your account ID in the request path.
How does authentication work with the Databricks API?
Every call carries a bearer token. Databricks recommends OAuth token federation, which exchanges a token from your identity provider, followed by OAuth M2M for service principals and OAuth U2M for interactive users. M2M access tokens last one hour. Personal access tokens still work, but they default to long lifetimes and belong only in quick tests.
What replaced the Databricks Supervisor API?
The Supervisor API reached end of life on September 30, 2026, and is no longer available. Databricks now points teams to their own agent loop built with the Agent Bricks CLI, to Genie Agents for questions over data, and to managed MCP servers for governed tools. The older Supervisor Agent is labeled legacy and not recommended for new systems.
How should teams handle Databricks API rate limits?
Limits apply per endpoint and per workspace, and an exceeded limit returns HTTP 429. Retry with exponential backoff plus random jitter, and always wait at least as long as the Retry-After header says. Throttle fan-out on busy endpoints such as jobs run-now, which allows 20 requests per second per workspace, and do not retry 400, 401 or 403 errors.
How do I use the Unity Catalog API?
Call the Unity Catalog endpoints with a token for an identity that holds the right privileges, then create or list catalogs, schemas and tables and update grants. Grant to service principals and groups at schema level so new tables inherit access. On some older LIST calls, pass max_results to enable paging and follow next_page_token until it is empty.
Can the Databricks API connect to external systems?
Yes. Airflow and Azure Data Factory trigger Databricks jobs through the run-now endpoint and poll for results, CI servers deploy bundles through the CLI, and Terraform manages workspaces and permissions. AI agents built on any MCP-aware client can reach governed SQL, Unity Catalog functions and search indexes through managed MCP servers that respect Unity Catalog permissions.
What changed in the Databricks API in 2026?
Three changes matter most. Jobs API 2.2 queues new runs by default and pages long lists at 100 items. The Supervisor API reached end of life on September 30, 2026, and Databricks now points teams to their own agent loop deployed with the Agent Bricks CLI. The Databricks CLI is GA from version 1.0.0, and v1.23.0 shipped on October 29.
How do I trigger a Databricks job using the REST API?
Send a POST request to /api/2.2/jobs/run-now with a bearer token and a JSON body holding the job_id plus any job parameters. The response returns a run_id. Poll /api/2.2/jobs/runs/get with that ID until the run reaches a terminal state, then call runs/get-output for a task run to read its output or error message.
What is the difference between Jobs API 2.1 and 2.2?
Jobs API 2.2 queues new runs by default, so a run waits for capacity instead of being skipped, and you set queue to false to opt out. Jobs created through 2.0 or 2.1 need queue set to true to get queueing. Version 2.2 also caps list fields such as tasks at 100 items and pages the rest with next_page_token.