TL;DR
The top data migration challenges are hidden dependencies, bad source data, semantic mismatch, live-source sync and risky cutover, and each one is fixed by an evidence gate. Score every challenge on impact, likelihood and detectability, then fix first the ones you would only find after cutover. For a live transactional source, use a bulk load plus change data capture and a short write freeze; for small, static data, a single big-bang cutover is simpler. Validate in three layers, because matching row counts can still hide wrong values. Keep a rehearsed rollback path until the target runs cleanly, and retire the old system only after operational acceptance. Kanerika runs migrations through five gated stages, and its zero-downtime Databricks migration for a large US retailer decommissioned 100% of the legacy infrastructure.
Key Takeaways
- Copying the data is the easy part, while discovery, meaning, sync, validation, cutover and handover are where migrations slip.
- Twelve challenges recur on enterprise programs, and each needs an early warning sign, a fix and evidence before the team moves on.
- A simple impact x likelihood x detectability score tells you which challenges to fix in the first wave.
- Big-bang, phased, CDC and parallel run answer different questions, so pick the cutover, movement and validation pattern separately.
- Row counts are a structural check only; business reconciliation with control totals is what finance and auditors accept.
- Security, rollback and decommissioning need proof on paper, from least-privilege access to NIST-aligned media sanitization.
The Load Finished. The Totals Did Not Match.
The migration team ran the final load on a Friday night. By Saturday morning every table had landed, and the row counts matched to the last record. The cutover call ended early, and the old database was scheduled for shutdown.
On Monday, finance ran its month-end control totals. The general ledger was off in one currency by a small but stubborn amount.
It took two days to find the cause. The legacy system rounded tax at the line level, and the new pipeline rounded it at the invoice level. Nothing was lost, yet nobody could sign the close until the rule was traced, fixed and replayed.
That is what data migration challenges look like in practice. They rarely show up as failed jobs. They show up as numbers the business no longer trusts, usually after the old system is gone. Twelve of them recur on almost every program. Each one has an early warning sign, a fix and a piece of evidence that proves it closed before the old system goes dark.
What Data Migration Challenges Are, and Why They Surface Late
A data migration challenge is anything that stops the business from trusting the target system once it goes live. That includes missing data, but it also covers changed meanings, broken reports, slow cutovers and unowned alerts. If a finance analyst cannot tie a report back to the old system, the migration has a challenge, whatever the job logs say.
It helps to separate challenges from risks. A risk is something that could happen, such as a vendor delay or a failed disk. A challenge is something the plan must solve on every program, such as mapping a legacy date field into a new type. Risks go into a register; challenges go into the work breakdown.
Data migration challenges surface late for a simple reason. Most of them are invisible to the tools that move data, and they only appear when people start using the target. For the basics of how a move is structured, see this guide on what data migration involves.
Moving the Data Is the Smallest Part of the Job
Copying tables from one platform to another is a well-solved problem. Cloud vendors, ETL tools and replication products all do it reliably at scale.
The hard work sits around the copy instead. First, teams have to discover what exists, agree what each field means and keep a live source in sync. They also have to validate results, cut over without losing writes and hand the new system to people who will run it. Each of those steps has its own failure modes, and they explain most of the overruns described in Kanerika’s look at data migration trends.
That gives a simple budgeting rule. Plan the migration around discovery, meaning, sync, validation, cutover and handover, and treat the copy itself as the easy part.
The 12 Data Migration Challenges and How to Fix Each One
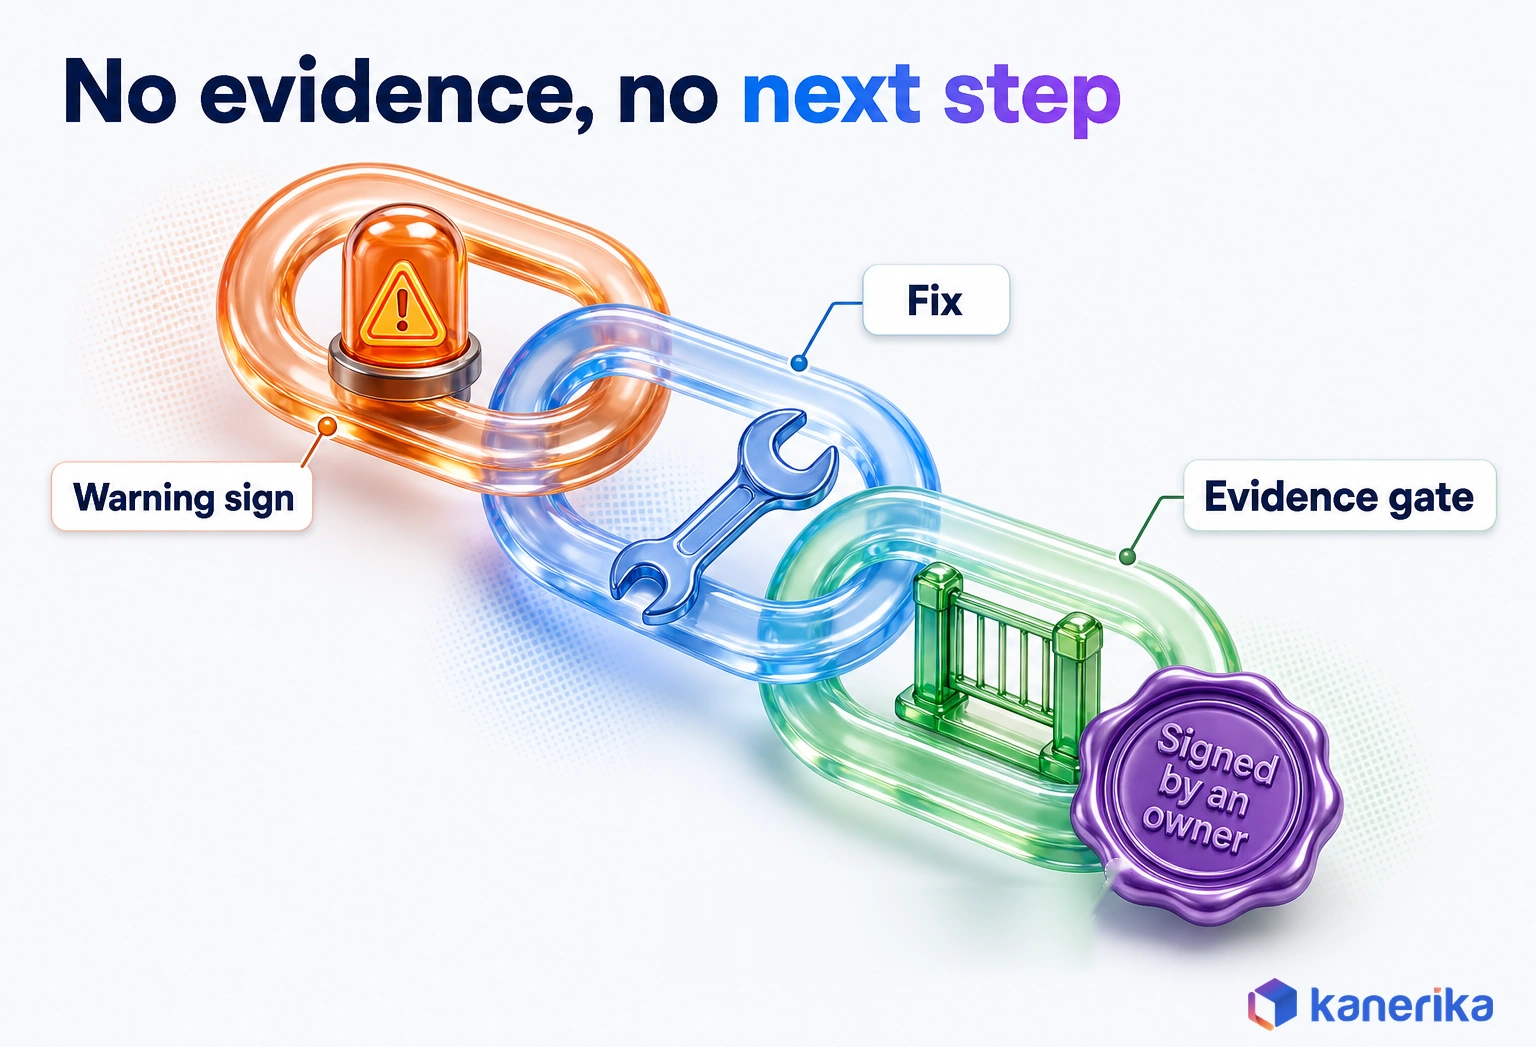
Every enterprise migration meets some version of the same twelve problems, whatever the source and target platforms are. The table below is the master reference. For each challenge it lists the earliest warning sign, the fix and the evidence a team should hold before it moves on.
The last column matters most. A fix that cannot be shown to a reviewer is only a promise. For that reason, each row ends in something you can hand over, such as a signed report or a test result.
The Twelve Challenges at a Glance
| Challenge | Early warning sign | Fix | Evidence before moving on |
|---|---|---|---|
| Hidden scope and dependencies | Reports or extracts with no known owner | Dependency map built from query logs and job schedules | Every consumer listed and signed by an owner |
| Poor source data quality | Duplicates, nulls and orphan keys in profiling | Profile, classify, then fix or quarantine | Quality report with agreed dispositions |
| Schema and semantic mismatch | Same field name, different meaning | Versioned mapping contract and boundary tests | Signed mapping with edge-value tests |
| Legacy extraction and source load | Exports that time out or slow production | Throttled, off-peak extraction with restart points | Timed extraction run on production-size data |
| Keeping a live source in sync | Deletes and late updates missing in the target | CDC with checkpoints, ordering and replay | Lag and replay test under real write volume |
| Downtime and cutover | No agreed write freeze or switch sequence | Rehearsed runbook with an abort rule | Timed dress rehearsal inside the business window |
| Rollback gaps | No plan for writes made on the target | Reverse sync or a defined point of no return | Rollback rehearsed end to end |
| Security and compliance | Broad service accounts and open staging areas | Least privilege, encrypted staging, access mapping | Access review and audit log sample |
| Validation limited to row counts | Counts match but reports disagree | Structural, record-level and business checks | Control totals signed by a business owner |
| Tooling that fails on edge cases | Demos only on clean, small datasets | Test tools on real workloads and failure cases | Proof-of-concept results on your own data |
| Change management and handover | Alerts and runbooks with no named owner | Training, on-call ownership and hypercare | Operational acceptance signed by the run team |
| Unstructured and AI-dependent data | Search or chatbot answers change | Copy content and permissions, rebuild indexes | Retrieval tests matched against old answers |
Hidden Scope and Undocumented Dependencies
Hidden scope is the challenge that causes the most rework, because everything downstream depends on it. A finance team’s monthly extract, a partner’s nightly file and a forgotten dashboard all read from the source. Yet none of them appears in the project charter.
The fix is a dependency map built from evidence rather than interviews. Pull query logs, scheduler definitions and connection lists from the source, then trace each consumer to a person. A report that nobody claims within a set period goes on a retire list, with sign-off from its business area.
When the map is done, every consumer has an owner, a target equivalent and a test. Kanerika’s data integration services team builds this inventory before any pipeline design starts, since the integration points are where most surprises hide.
Checklist
Data Migration Checklist
Work through discovery, mapping, sync, validation and cutover tasks in order, so every challenge has an owner and a test before go-live.
Get the Checklist →Poor Source Data Quality
Legacy systems hold years of duplicates, free-text codes and orphan records, and a migration exposes all of it at once. The temptation is to clean everything on the way in. But that turns a migration into an open-ended quality program and changes values the business may rely on.
A better approach is to profile, classify and decide. Profiling tells you what is wrong, while classification tells you how much it matters. Each issue then gets one of three dispositions:
- Fix in the source, when the business owns the error and can correct it there.
- Fix in the pipeline instead, with a documented and tested rule.
- Quarantine, when the record cannot be trusted and needs a human decision.
The rule that matters is never to rewrite a business value silently. Suppose a pipeline changes a customer’s region or an invoice’s currency. That change needs a rule, a log entry and an owner who agreed to it. The same discipline sits behind most big data challenges, where volume makes silent fixes impossible to audit.
Schema and Semantic Mismatch
Schema mismatch is the visible part of this problem: types, lengths and precision that differ between platforms. Semantic mismatch is the dangerous part, because the field names stay the same while their meanings change.
For example, take a legacy DATETIME column stored without a time zone. The old application assumed local server time, while the new platform stores everything in UTC. If the pipeline copies the value as it is, every timestamp shifts by several hours. Daily sales then land on the wrong date near midnight, and nobody notices until a regional report disagrees.
The fix is a versioned mapping contract. Each target field records its source field, type, unit, time zone and transformation rule. Boundary tests then check the edges, such as midnight, month end, daylight saving changes, maximum precision and null handling. Finally, any change to the contract gets a new version and a rerun of the tests.
Legacy Extraction and Source-System Load
Old systems were not built to be read in bulk. Full-table exports can time out, lock rows that production still needs or slow the application for its users. Some tables lack primary keys, so restarting a failed extract from the middle is not possible.
So plan extraction like a production change. Run it off-peak, throttle it, split large tables by key range or date and record restart points. Time one full run on production-size data before you commit to a cutover window.
It’s also worth testing what happens on the source side. A lot of legacy databases still sit on old RAID arrays, and a full data extraction puts a heavy load on those disks. If one fails and the array goes down before the data is moved, you’ll need RAID recovery software to get it back.
Keeping a Live Source in Sync
Most enterprise sources keep taking writes while the migration runs, often for weeks. The initial bulk load is only a snapshot, and the target starts to drift as soon as it finishes.
Change data capture closes the gap by reading inserts, updates and deletes from the source log and applying them to the target. The common failures are quiet ones. Deletes get dropped, updates arrive out of order or a replay after a failure applies the same change twice.
Three controls keep sync honest. First, checkpoints record exactly which log position has been applied. Second, ordering by commit sequence keeps late updates from overwriting newer ones. Third, idempotent writes, such as a keyed merge, make a replay safe to run again. The test that proves it is a replay drill under real write volume, with lag measured throughout.
Downtime, Cutover and Rollback Gaps
Cutover is where the other challenges come due at once. A team without an agreed write freeze, switch sequence and abort rule is improvising in the most expensive hour of the program.
Rollback is harder than it looks, because the target starts accepting writes the moment users switch. An order placed on the new system at 9:05 does not exist on the old one. Switching back an hour later loses it unless something copies it back. The cutover section below covers the go/no-go list and the two ways to handle that divergence: reverse sync or a fixed point of no return.
Security, Validation and Tooling Gaps
Security tends to loosen during a migration. Service accounts get broad rights to save time, and staging areas hold full copies of sensitive tables. A staging bucket that holds last year’s customer table with no deletion date is a production-grade risk with none of production’s controls. The fix is to apply production controls to every temporary copy; the governance section lists what to prove.
Validation is often reduced to row counts because counts are easy to automate. Matching counts prove only that the right number of rows arrived, so the validation section sets out the two further layers that catch wrong values.
Tooling fails in a quieter way. A tool chosen from a feature list handles the demo schema, then breaks on the first packed decimal or source table without a primary key. The rework then lands in a budget that never counted it. The planning section lists the failure cases to test before you buy and the cost lines that absorb the rework.
Change Management and Operational Handover
A migration can pass every technical test and still fail in its first month of operation. For instance, analysts keep exporting from the old system out of habit. Alerts fire with no owner, and the support team learns the new platform during an incident.
That is why handover needs the same rigor as cutover. Train users on the reports they will actually open, not on the platform in general. Name an on-call owner for every pipeline and alert, and run a hypercare period with a daily review of incidents.
Above all, do not retire the old system the day after cutover. Keep it read-only until the run team signs operational acceptance.
Unstructured and AI-Dependent Data
Documents, emails and wiki pages often feed enterprise search tools and AI assistants, which adds a new class of migration problem. Copying the files is easy, but their permissions, metadata and the derived artifacts built on them are much harder to carry across.
Copy the canonical content with its access control lists intact. Treat embeddings, vector stores and search indexes as derived data to rebuild on the target. Then run a set of known questions against both the old and new systems and compare the answers. If a chatbot answers differently, or shows a document a user should not see, the migration is not finished.
Which Challenges to Tackle First: A Severity Scoring Model
A long list of data migration challenges is only useful once you know which ones to fix first. A simple score, built from three factors, turns the list into an ordered plan that the steering group can approve.
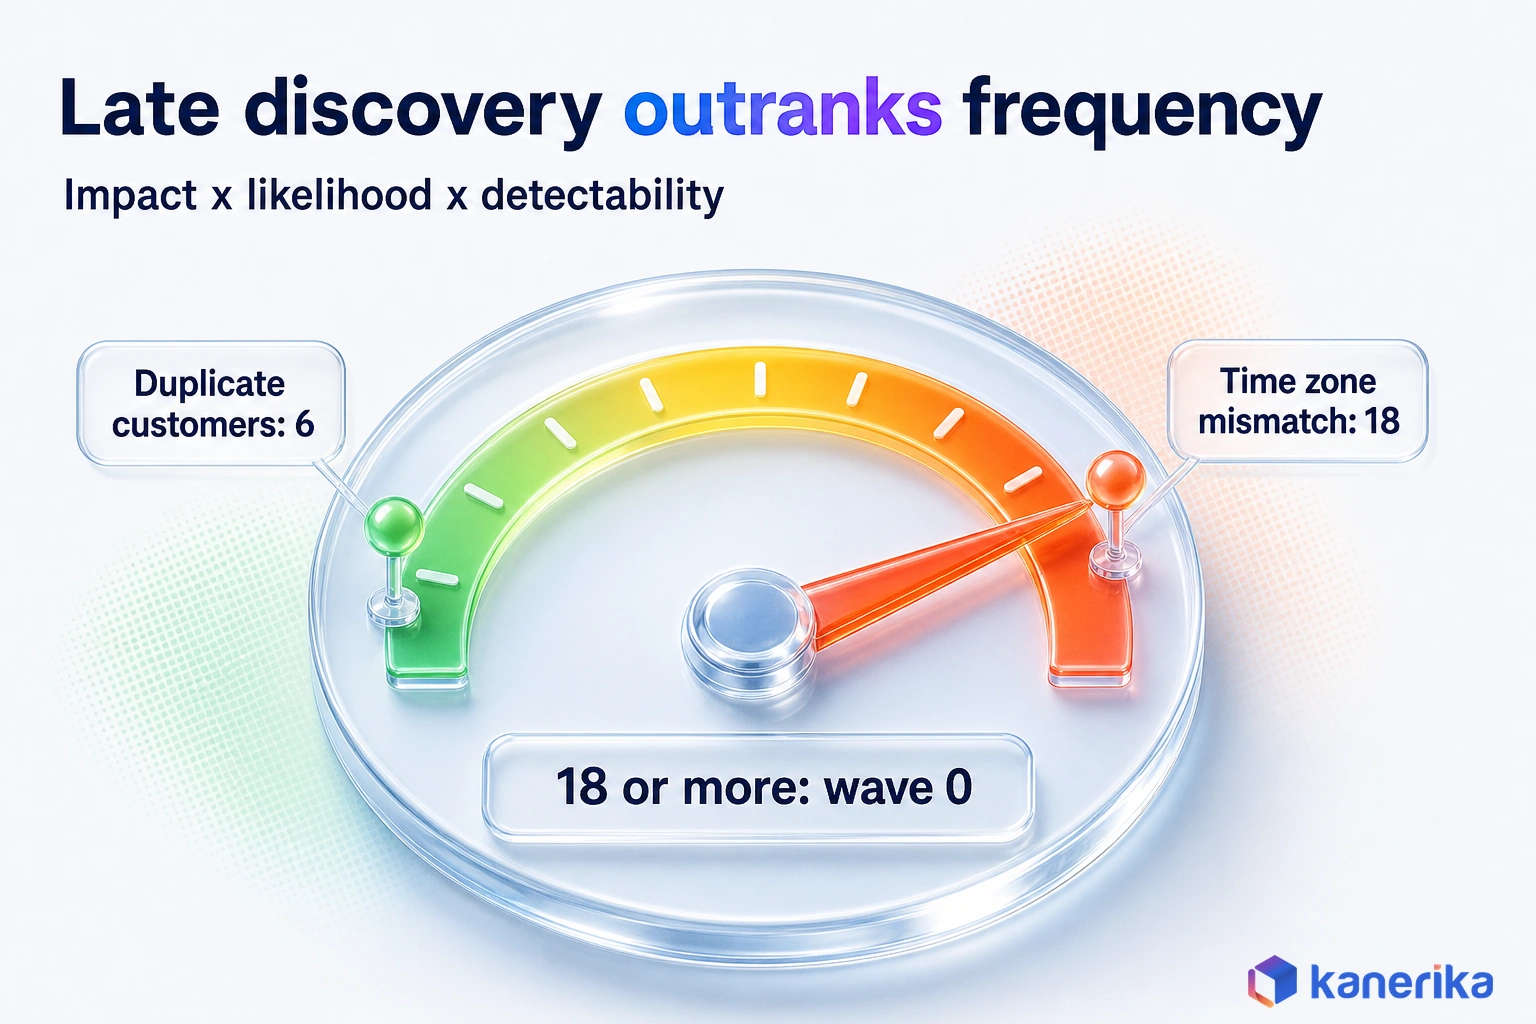
Rate each challenge from 1 to 3 on three scales. Impact measures how much damage it would do to the business. Likelihood then measures how probable it is on this program. Detectability measures how late you would find it, where 3 means it would only surface after cutover. Multiply the three, so scores run from 1 to 27.
Detectability is the factor most teams leave out, even though it changes the order. A medium-impact problem that would hide until month-end close is more dangerous than a frequent one that profiling catches in the first week.
A Worked Scoring Example
The table below scores four challenges for one illustrative program, a move of order and finance data from an on-premises database to a cloud lakehouse. The scores show the method; your own program will score differently.
| Challenge (illustrative program) | Impact | Likelihood | Detectability | Score | Wave |
|---|---|---|---|---|---|
| Time zone mismatch on order timestamps | 3 | 2 | 3 | 18 | Wave 0 |
| Live order source drifting during sync | 3 | 3 | 2 | 18 | Wave 0 |
| Change management and handover | 2 | 2 | 2 | 8 | Later wave |
| Duplicate customer records | 2 | 3 | 1 | 6 | Fix during build |
Use 18 as the line for wave 0. Anything at or above it gets a proof before the main build starts, such as a boundary test suite or a replay drill. Lower scores still get fixed, just inside the normal build and test cycle.
Notice how the duplicate customers score lowest despite being the most likely problem. Profiling finds them on day one, so they are cheap to manage. The time zone issue scores far higher because it would pass every row count and surface only in a regional report weeks later.
Choosing a Migration Approach: Big-Bang, Phased, CDC or Parallel Run
Teams often argue about big-bang versus phased versus CDC as if they were three options for one decision. They are answers to three different questions, and a sound plan picks one of each.
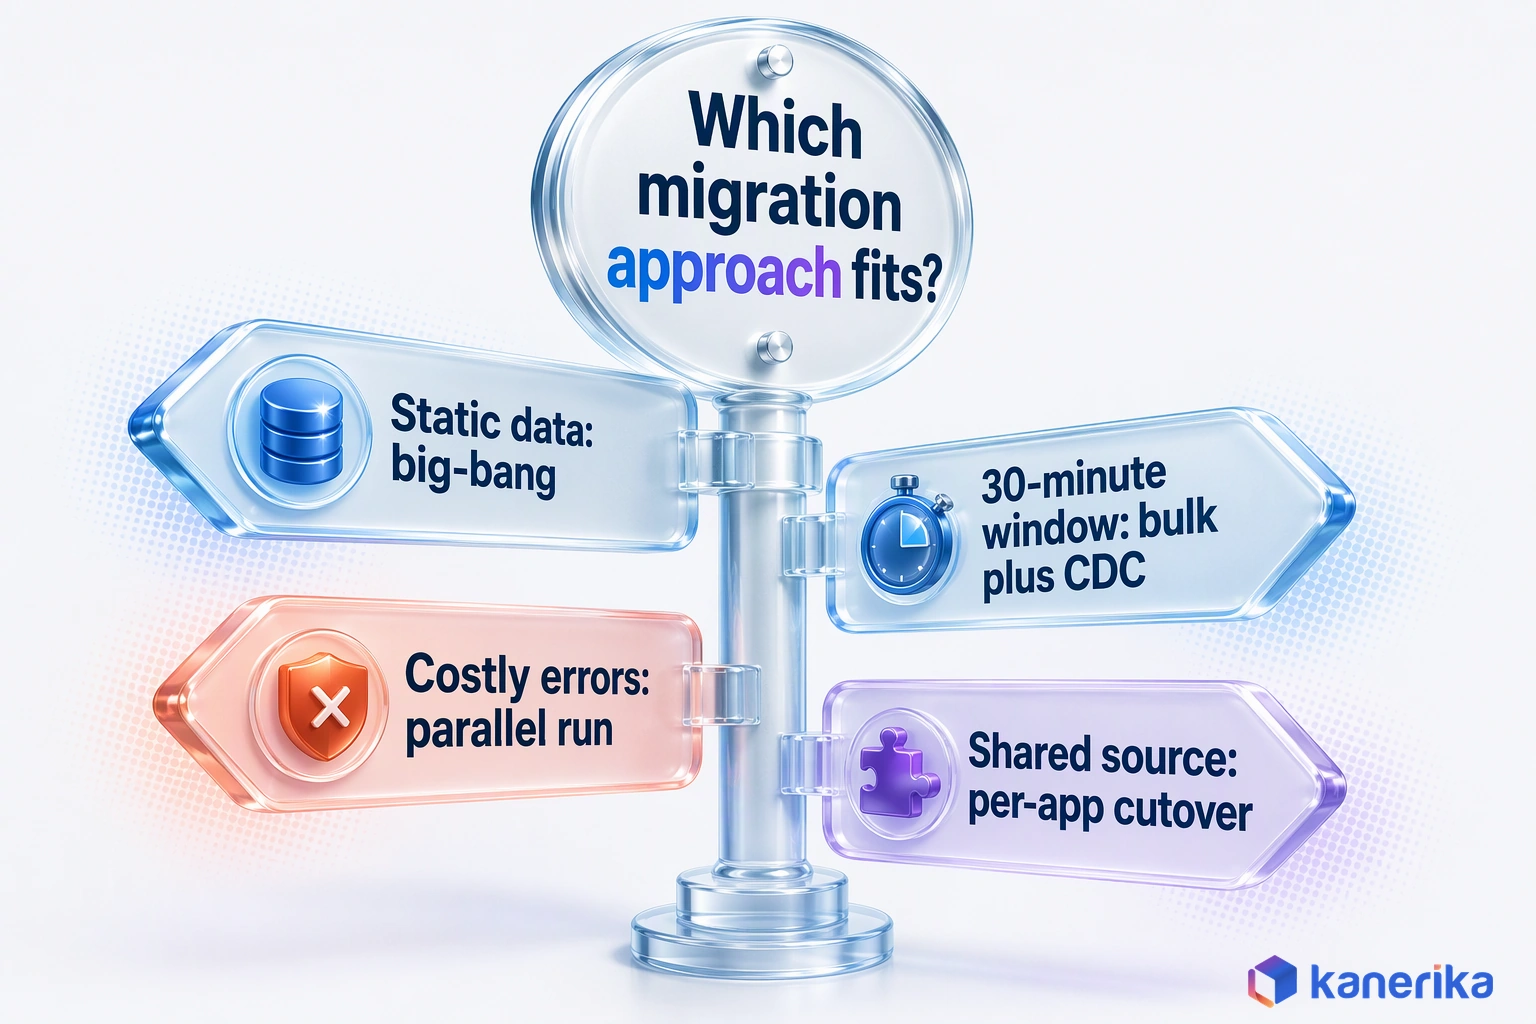
Big-bang and phased describe the cutover strategy, meaning whether everything switches at once or in waves. Bulk load and CDC, by contrast, describe data movement, meaning a one-time copy or a continuous stream of changes. A parallel run is a validation pattern in which both systems run side by side until their outputs agree. The graphic below shows the four most common picks. The table after it also adds phased cutover for loosely coupled domains and a one-time load for frozen history.
Six Scenarios and the Pick for Each
The right mix depends on the source’s write volume, the downtime the business accepts and the cost of an error. The table gives a stated pick for six common scenarios.
| Scenario | Pick | Why |
|---|---|---|
| Small, static dataset with a weekend outage allowed | Big-bang cutover with a bulk load | Nothing changes during the copy, so sync adds cost without value |
| Large estate split into loosely coupled domains | Phased cutover by domain | Each wave is smaller, and lessons carry into the next one |
| Live transactional source with a short downtime window | Bulk load plus CDC and a brief write freeze | The freeze only has to cover the final delta |
| Finance or regulated reporting where errors are costly | Parallel run before the switch | Outputs are compared on real periods before anyone relies on them |
| Many applications sharing one source database | CDC sync with per-application cutover | Each application moves after its own validation |
| Historical data that no longer changes | One bulk load, then archive | No sync needed; validate once and lock it |
Most enterprise programs end up combining rows, such as CDC for the live order tables and a one-time bulk load for ten years of history. For the planning steps around this choice, Kanerika’s data migration framework covers phases and roles in more depth.
Worked Example: Live Order Data With a 30-Minute Write Pause
Suppose an order system takes writes around the clock, and the business allows a 30-minute pause in writes on a Sunday morning. A bulk load alone cannot fit that window, but bulk plus CDC can. The sequence looks like this:
- Record the source log position, then take a consistent snapshot and bulk-load it into the target.
- Start CDC from the recorded position and apply changes until lag stays low and stable.
- Reconcile the bulk baseline with counts, key checks and control totals while CDC keeps running.
- At minute 0, freeze writes on the source and announce the freeze to users.
- Drain the final delta and confirm that applied lag is zero.
- Run a fast reconciliation on the day’s orders, open order counts and order value totals.
- Switch application connections to the target and reopen writes there.
- Apply the abort rule. If reconciliation is not green by minute 20, reopen writes on the source and keep the target for analysis.
The abort rule at minute 20 leaves 10 minutes to reopen the source inside the agreed window. Agree that deadline with the business before the weekend, not during the call.
Kanerika Service
Data Migration Services
Kanerika plans and runs enterprise migrations from discovery and mapping to CDC sync, rehearsed cutover, hypercare and retirement of the old system.
Explore Migration ServicesValidation Beyond Row Counts
Validation answers one question: can the business rely on the target the way it relied on the source? Row counts cannot answer that alone, which is why the hook’s ledger matched on rows and failed on money.
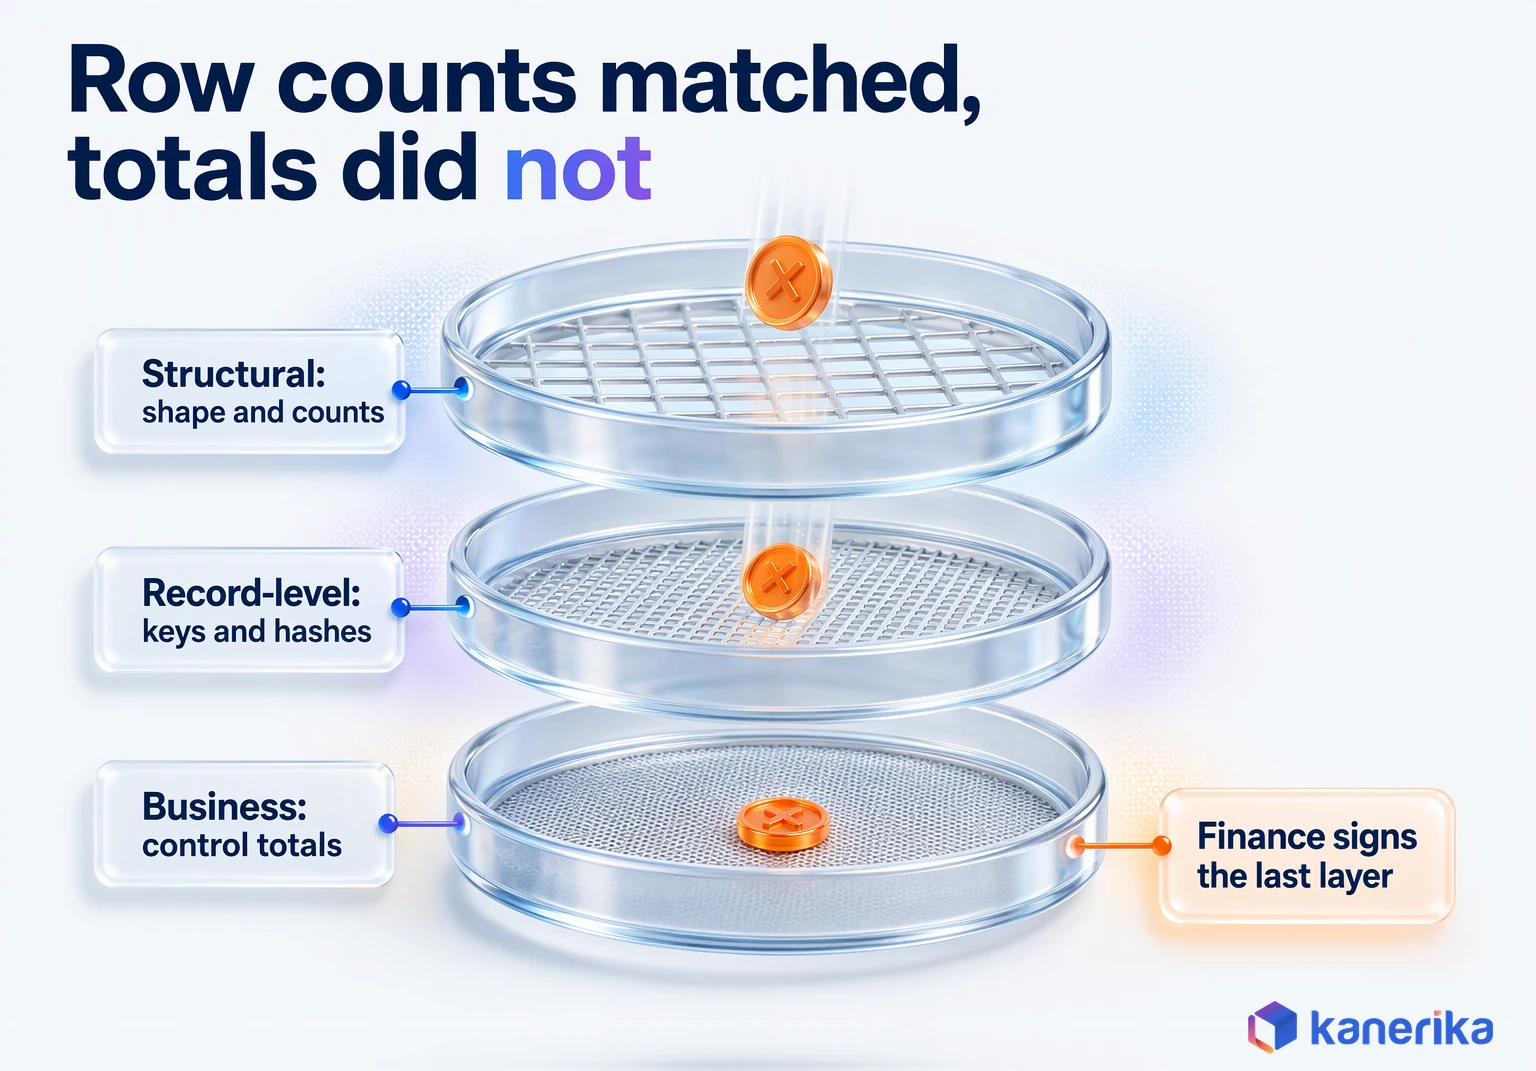
Think of validation in three layers. Each layer catches errors the one before it misses, and each has a different person who signs it off.
Structural checks confirm the shape of the data, such as tables, columns, types, nullability and row counts per partition. Record-level checks confirm the values, usually by matching keys and comparing column hashes or sampled fields. Business reconciliation confirms the meaning, by comparing the numbers people actually report on.
| Layer | Typical tests | Who signs |
|---|---|---|
| Structural | Schema match, types, nullability, row counts per table and partition | Data engineering lead |
| Record-level | Key matching, column hash comparison, sampled field diffs, orphan checks | QA or test lead |
| Business reconciliation | Control totals, aging buckets, open balances, report tie-outs by period | Business data owner, often finance |
Business reconciliation is easiest to run as grouped totals compared side by side. The query below lands both extracts in one engine and lists every posting date and currency where counts or amounts differ.
-- Control totals by posting date and currency, legacy vs target
SELECT COALESCE(s.posting_date, t.posting_date) AS posting_date,
       COALESCE(s.currency, t.currency)         AS currency,
       s.row_cnt AS src_rows,   t.row_cnt AS tgt_rows,
       s.amount  AS src_amount, t.amount  AS tgt_amount
FROM (SELECT posting_date, currency, COUNT(*) AS row_cnt, SUM(amount) AS amount
      FROM legacy_gl_entries GROUP BY posting_date, currency) s
FULL OUTER JOIN
     (SELECT posting_date, currency, COUNT(*) AS row_cnt, SUM(amount) AS amount
      FROM target_gl_entries GROUP BY posting_date, currency) t
  ON s.posting_date = t.posting_date AND s.currency = t.currency
WHERE COALESCE(s.row_cnt, 0) <> COALESCE(t.row_cnt, 0)
   OR COALESCE(s.amount, 0)  <> COALESCE(t.amount, 0);
An empty result is the evidence. A row like the hook’s currency gap points straight at the period and currency to investigate, which turns a two-day hunt into a short one.
Run aging buckets and open balances the same way, and keep every signed result with the cutover record. Auditors will ask for it, and so will the next team that changes the pipeline.
Cutover, Rollback and Retiring the Old System
Cutover is the moment users stop relying on the old system and start relying on the new one. It should be a rehearsed, timed event with clear criteria. The decision to proceed then becomes a check against a list, not a judgment call at midnight.
Before the night, rehearse at least once on production-size data, with the same people and runbook you will use on the night. Time every step, then compare the total against the business window with some margin to spare.
A go/no-go list keeps the decision honest:
- All wave 0 challenges closed, with their evidence filed.
- A full dress rehearsal completed inside the agreed window.
- Structural, record-level and business reconciliation green and signed.
- CDC lag stable and a replay drill passed.
- Rollback path rehearsed, with a named person who can trigger it.
- Access reviewed on the target and staging areas locked down.
- On-call owners named for every pipeline, job and alert.
- Business owners available during the cutover and the first close.
Rollback and Retirement
Rollback gets harder once the target accepts writes, because the two systems begin to diverge. So decide in advance how long you keep a way back. Either run reverse sync from target to source for a fixed period, or define a point of no return after which you fix forward. Write that point into the runbook so nobody debates it under pressure.
Retire the old system only after operational acceptance, ideally after at least one full business cycle such as a month-end close. Keep it read-only in that period, then archive what regulation requires you to retain. When storage media are disposed of, follow NIST SP 800-88 Rev. 2, the media sanitization guideline published in September 2025 that supersedes the 2014 revision.
Security, Compliance and Governance During Migration
A migration creates more copies of sensitive data than the business normally holds. There is the source, the staging area, the target and often an extract on someone’s laptop. Each copy needs the same protection as production, and governance is how you prove it.
The stakes are also concrete. IBM’s Cost of a Data Breach Report 2026 puts the global average cost of a breach at USD 4.99 million. That is a 12% increase on the prior year’s figure. A loosely secured staging bucket during a migration is exactly the kind of gap that report counts.
Regulation also adds specific duties. Personal data moving from the EU to a US platform falls under GDPR’s international transfer rules. The European Commission’s EU-US Data Privacy Framework adequacy decision lets that data flow to certified US companies. Confirm the target vendor’s certification before the first copy.
For US health data, the HIPAA Security Rule at 45 CFR 164.312 requires audit controls and lists encryption as an addressable specification. Addressable means you must assess it and document your decision, which is easier to defend if staging is encrypted anyway.
Controls to Prove Before Go-Live
Each control below needs an owner and a piece of evidence before cutover, because auditors ask for proof, not intent.
| Control | What to prove | Owner |
|---|---|---|
| Least-privilege service accounts | Each migration account reads or writes only what its job needs | Platform security |
| Secured staging | Encryption at rest, network isolation and a deletion date | Data engineering lead |
| Access mapping | Source roles mapped to target roles, then reviewed before go-live | Data owner |
| Audit evidence | Logs of who accessed which data, kept for the required period | Compliance |
| Transfer basis | Legal basis for any cross-border movement on file | Privacy officer |
Access mapping deserves extra care. Legacy systems often grant rights through application logic, while cloud targets enforce them in the data layer, so a one-to-one copy of roles rarely works. Tools such as Microsoft Purview help classify sensitive columns before you decide who sees them on the target.
For a wider view of ownership and policy, the pillars of data governance apply directly to migration work. Kanerika’s data governance consulting team often sets these controls up before the first extract runs.
Teams in the US can see how we run these projects on our data migration services in the USA page, or on the New York data migration services page.
Target-Platform Traps: Microsoft Fabric, Databricks and Snowflake
Each target platform solves some migration problems for you and introduces a few of its own. Knowing them early saves a redesign halfway through the build. For the business case behind a platform move, see this guide to data platform migration.
Microsoft Fabric
Fabric mirroring continuously replicates data from Azure databases and external sources into OneLake in near real time. For a supported source, mirroring can replace a hand-built CDC pipeline during coexistence. Changes can be published as fast as every 15 seconds, and a replicator merges them into Delta tables. Background replication compute is also free, and each purchased capacity unit includes one free terabyte of mirroring storage, so an F64 capacity carries 64 TB.
The trap is assuming every source qualifies. Microsoft Learn’s source list, last updated in August 2026, includes Azure SQL Database, SQL Server, Oracle, Snowflake and Google BigQuery. Some sources are still in preview. Check yours and keep a CDC fallback for anything outside it.
One setting also matters during coexistence. Mirrored databases created after mid-June 2025 keep one day of Delta history by default. If reconciliation needs time travel over a longer window, raise the retention under Delta table management in the mirrored database settings. Kanerika’s guide to Azure to Microsoft Fabric migration walks through these choices, and the Microsoft Fabric practice page lists the related services.
Talk to Kanerika
Planning a Move to Fabric, Databricks or Snowflake?
Kanerika maps your sources against the target platform’s sync, merge and mapping limits, then scores the challenges that would surface after cutover. A short working session turns that into a wave plan.
Book a Working Session →Databricks
On Databricks, Delta Lake’s MERGE statement handles the upserts that CDC sync depends on. Its WHEN NOT MATCHED BY SOURCE clause lets you handle rows deleted at the source. The clause is available in Databricks SQL and in Databricks Runtime 12.2 LTS and above. Lakeflow pipelines also provide native SCD Type 1 and Type 2 and CDC support through AUTO CDC.
For an incremental change feed, the usual pattern carries an operation flag on each change row. The example below is illustrative, with sample table and column names.
-- Illustrative: apply one deduplicated CDC batch (sample names)
MERGE INTO sales.orders AS t
USING orders_changes_latest AS s
  ON t.order_id = s.order_id
WHEN MATCHED AND s.op = 'DELETE' THEN DELETE
WHEN MATCHED THEN UPDATE SET
  t.status = s.status, t.amount = s.amount, t.updated_at = s.updated_at
WHEN NOT MATCHED AND s.op <> 'DELETE' THEN INSERT
  (order_id, status, amount, updated_at)
  VALUES (s.order_id, s.status, s.amount, s.updated_at);
Two details decide whether this runs cleanly. Databricks documents that a merge can fail when several source rows match the same target row. To avoid that, reduce each batch to the latest change per key first. WHEN NOT MATCHED BY SOURCE THEN DELETE suits a different case, where the source is a full snapshot rather than a batch of changes.
The real trap here is older runtimes and hand-written merge logic that silently ignores deletes. So pin a runtime that supports the clauses you need and test delete handling in the replay drill. Teams moving ETL estates should also read this account of Informatica to Databricks migration, or see the Informatica to Databricks migration service.
Snowflake
Snowflake moves tend to trip on semantics rather than mechanics, and the time zone trap from the mapping section shows up here first. A column declared as plain TIMESTAMP becomes TIMESTAMP_NTZ, because the TIMESTAMP_TYPE_MAPPING parameter defaults to that type. NTZ stores wall-clock time and ignores zones.
The two alternatives behave differently. TIMESTAMP_LTZ stores UTC and displays it in the session time zone, while TIMESTAMP_TZ stores UTC with an offset. Pick the type per source column in the mapping contract, or regional reports drift near midnight. Record numeric precision and identifier case there as well.
Snowflake’s MERGE also guards against messy change batches. With ERROR_ON_NONDETERMINISTIC_MERGE at its default of TRUE, a merge fails when several source rows would update or delete one target row. Deduplicate each batch to one row per key first, as the Snowflake docs suggest, rather than switching the check off.
Also watch compute spend during validation, since repeated full-table comparisons on large warehouses add up. Sample at the record level and reserve full comparisons for business reconciliation. The Snowflake services page covers Kanerika’s work on that platform.
How to Plan Effort, Cost and Tooling Before You Commit
Migration budgets usually fail on items nobody wrote down, rather than on the line items they did include. A cost model that lists every activity, even roughly, is more accurate than a precise estimate of the copy alone.
Estimate each of these lines separately, with its own owner and assumptions:
- Discovery and dependency mapping.
- Field mapping and the mapping contract.
- Data quality remediation and quarantine handling.
- Pipeline build and conversion of legacy logic.
- Rehearsals, including at least one full dress rehearsal.
- Coexistence, meaning double running of both platforms during sync and parallel runs.
- Validation labor, including business time for reconciliation sign-off.
- Cutover staffing across all teams on the night.
- Hypercare after go-live.
- Decommissioning, archiving and media sanitization.
Coexistence and validation labor are the two lines most often missing. Both platforms run and bill at once during sync, and finance staff time for sign-off is real cost even when it sits in another budget.
Migration ROI Calculator
Estimate Your Migration ROI
Use Kanerika’s migration ROI calculator to size coexistence, validation and conversion effort before you commit a budget.
Calculate Migration ROI →Choosing Tools Against Failure Cases
Every migration tool looks good on a clean demo table. The useful test is how it behaves on your worst data and your worst day.
First, give shortlisted tools a real workload with odd types, wide tables and a source without primary keys. Then break things on purpose: kill a job halfway, replay a CDC window and change a column type. Then score each tool on how it recovers. For a ranked view of the market, see Kanerika’s list of data migration tools. For ETL platform choices, read this comparison of Talend vs Informatica PowerCenter.
Where AI Helps
AI can speed up the analysis-heavy work of profiling, mapping suggestions and validation sampling. A model can read a legacy column called CUST_RGN, its sample values and its downstream reports. It can then propose that the column maps to customer_region and flag the codes it cannot place. It drafts quickly, but an analyst still approves each mapping rule, and a business owner still signs the reconciliation. The guide to AI-powered data migration shows where it pays off and where it does not.
How Kanerika Delivers Migrations in Five Gated Stages
Kanerika runs every migration as a sequence of stages, and each stage closes only when its evidence exists. That maps directly to the evidence column in the challenge table above, so a sponsor can see what has been proven at any point.
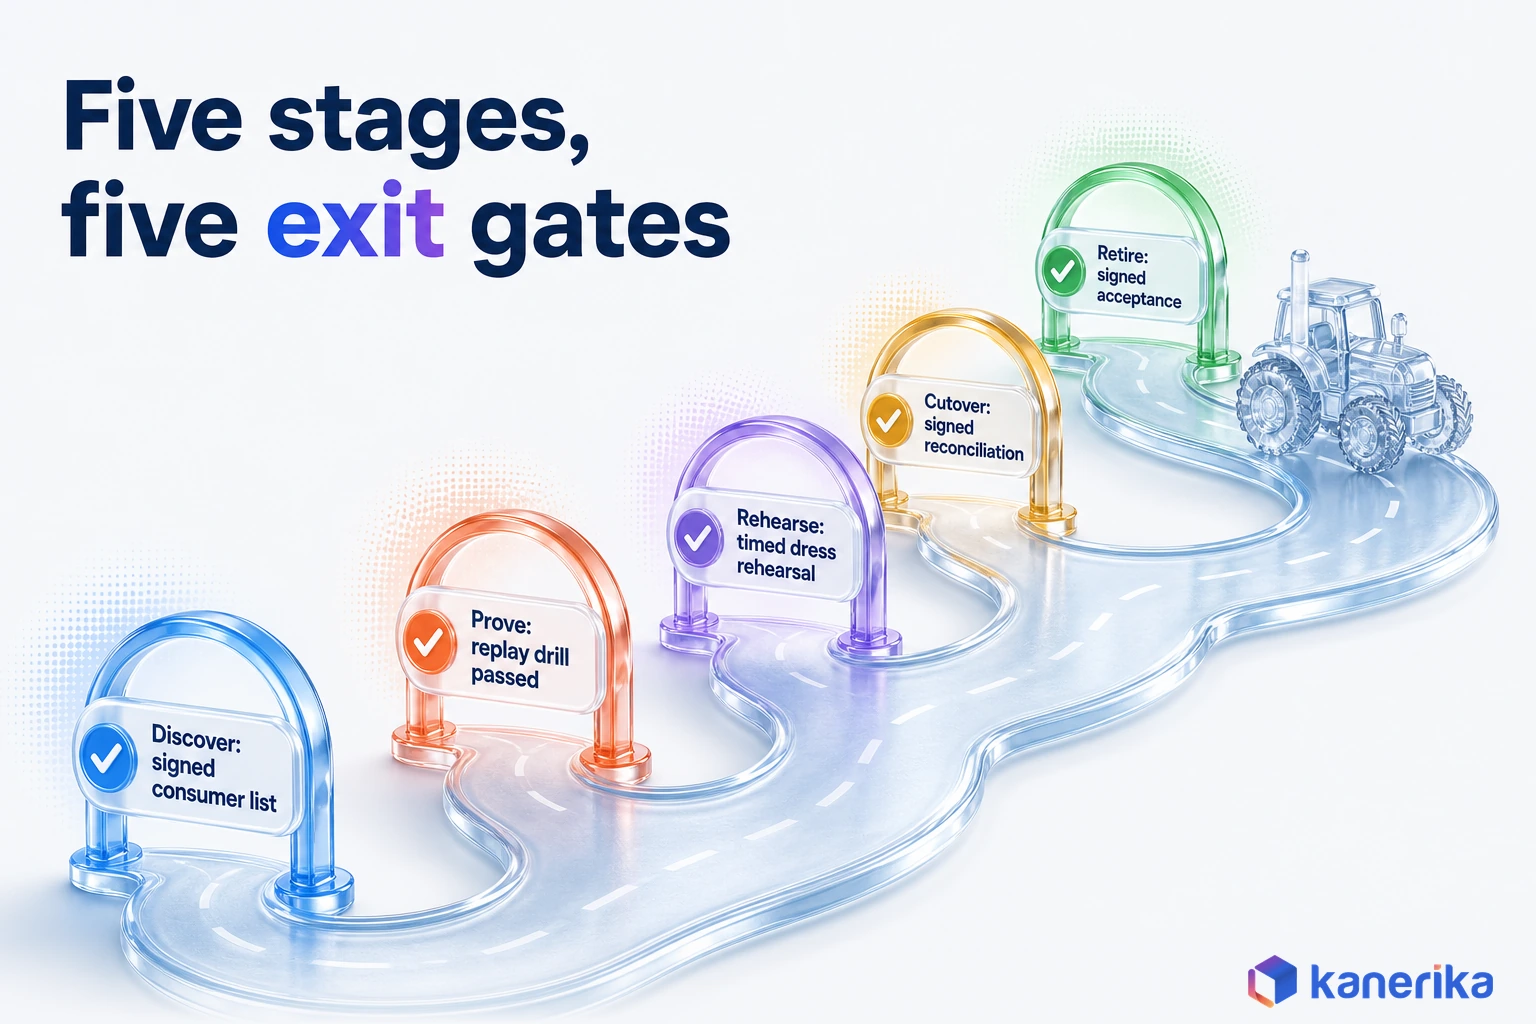
- Discover. Build the dependency map, profile the source and score each challenge. The exit gate is a signed consumer list and a scored challenge register.
- Design and prove. Write the mapping contract, choose the cutover, movement and validation pattern and prove every wave 0 item. The exit gate is passing boundary tests and a replay drill.
- Build and rehearse waves. Build pipelines wave by wave, with all three validation layers running on each one. The exit gate is a timed dress rehearsal inside the business window.
- Controlled cutover. Execute the runbook against the go/no-go list, with the abort rule agreed. The exit gate is signed business reconciliation on live data.
- Stabilize and retire. Run hypercare, hand over to named owners and retire the source after operational acceptance. The exit gate is a signed acceptance and a sanitization record.
Kanerika’s FLIP migration accelerator automates much of the conversion work across 24 supported migration paths and is listed on Microsoft Marketplace. The broader data migration services cover the full sequence, from discovery to retirement.
The firm is a Microsoft Fabric Featured Partner with the Data Warehouse Migration to Azure specialization. Kanerika also has more than 10 years of enterprise delivery, over 130 enterprise clients and a 98% client retention rate.
Case Study: Zero-Downtime Databricks Migration for a US Retailer
The client is one of the largest retail corporations in the United States. Its business applications ran on distributed on-premises PostgreSQL and Cassandra databases, with no central lineage or governance. Production dependencies made a standard cutover too risky, so the move had to run with zero downtime.
To solve this, Kanerika designed a three-phase migration. PySpark notebooks and Spark connectors moved the full history into Delta Lake tables under Unity Catalog. Timestamp-based, CDC-style incremental sync with Delta MERGE kept the source databases live and current throughout.
Each application was then redirected to Databricks individually, only after its own validation. The on-premises infrastructure was decommissioned only after full confirmation. The retail Databricks migration case study reports three results:
- Zero downtime, with no production interruption.
- 100% of legacy infrastructure decommissioned.
- 100% centralized governance, lineage and data access.
The pattern matches the scenario table above: CDC sync with per-application cutover, gated by validation and followed by a late, confirmed retirement. To plan the same gates on your own estate, talk to Kanerika’s migration team.
Case Study
Zero-Downtime Databricks Migration for Retail Analytics
One of the largest US retail corporations moved off distributed PostgreSQL and Cassandra to Databricks with zero downtime, 100% of legacy infrastructure decommissioned and 100% centralized governance and lineage.
Read the Case Study →Migration Readiness Checklist
Before you approve a cutover date, answer each question below with a yes and a piece of evidence. Any no is a gap to close first. A fuller task list is in Kanerika’s downloadable data migration checklist.
- Does every report, extract and job reading the source have a named owner?
- Has every data quality issue been fixed, quarantined or accepted in writing?
- Is the mapping contract versioned and signed, with boundary tests passing?
- Has a full extraction run on production-size data finished inside its window?
- Has CDC passed a replay drill, including deletes, under real write volume?
- Are all challenges scoring 18 or above closed with evidence?
- Have structural, record-level and business reconciliation all passed and been signed?
- Has a timed dress rehearsal fit inside the business window?
- Is the rollback path rehearsed, with a defined point of no return?
- Are access, staging and audit logging reviewed and approved?
- Does every pipeline and alert have an on-call owner after go-live?
- Is the old system staying read-only until operational acceptance is signed?
Twelve yeses mean every challenge on the list has been found and fixed with proof. So how do you fix the top data migration challenges? Find each one early, rank it by how late it would surface and close it with evidence the business signs.
Frequently Asked Questions
What are the most common data migration challenges?
The most common data migration challenges are hidden dependencies, poor source data quality, schema and semantic mismatch, slow legacy extraction and keeping a live source in sync. Cutover, rollback, security, validation, tooling, handover and AI-dependent content complete the usual list of twelve. Each one needs an early warning sign, a planned fix and evidence before the team moves on.
What causes data migration projects to fail?
Projects usually fail because problems surface after cutover, when the old system is already gone. Typical causes are undocumented reports and jobs, field meanings that changed between platforms, validation that stopped at row counts and cutovers with no rehearsed rollback. Ranking challenges by how late they would appear, and fixing those first, prevents most of these failures.
Are matching row counts enough to validate a migration?
Matching row counts prove only that the right number of records arrived. They miss wrong values, shifted time zones, rounding changes and broken relationships. A complete validation adds record-level checks, such as key matching and column hash comparison, and business reconciliation of control totals, aging buckets and open balances, signed by the business data owner.
How do you migrate sensitive or regulated data securely?
Classify sensitive columns before the first extract and give migration service accounts only the access their jobs need. Encrypt and isolate staging areas, set deletion dates for temporary copies and keep audit logs. Confirm the legal basis for any cross-border transfer, map source roles to target roles and review access before go-live.
What should a rollback plan include, and when is it safe to retire the old system?
A rollback plan names who can trigger it, the abort deadline, how writes made on the target are handled and a defined point of no return. Rehearse it end to end. Retire the old system only after operational acceptance, ideally after a full business cycle, and sanitize its media following NIST SP 800-88 guidance.
What data should you migrate and what should you archive?
Migrate data that active processes, reports and models still read, plus anything the business must query often. Archive historical data that no longer changes and is needed only for retention or occasional lookups. Base the split on the dependency map and retention rules, and validate archived data once before you lock it.
How do you handle data quality in a migration?
Start by profiling the source to find duplicates, nulls, orphan keys and inconsistent codes. Classify each issue by business impact, then fix it in the source, fix it in the pipeline with a documented rule or quarantine it for a human decision. Never change a business value silently, and keep a signed quality report as evidence.
What is the role of governance in data migration?
Governance makes sure every copy of the data stays protected and accountable during the move. It covers least-privilege service accounts, encrypted staging, mapping source roles to target roles and keeping audit logs. It also assigns owners who sign off mappings, quality decisions and reconciliation results, so auditors can trace who approved each change and when.
How long does an enterprise data migration take?
Duration depends on the number of sources and consumers, data quality, how much legacy logic needs conversion, the write volume on live sources and how many waves the cutover needs. Rehearsals, parallel runs and hypercare also add time. The most reliable estimate comes from a discovery phase that maps dependencies and scores challenges before the plan is fixed.
How do you choose the right data migration partner?
Ask each partner to show evidence gates for every stage, a sample mapping contract and a rehearsed rollback plan from a past program. Check certifications with the target platform vendor and read case studies that name real outcomes. A strong partner will also test its tooling on your own data and failure cases before you commit.
What are the risks of delaying a legacy data migration?
Delay raises the cost of keeping old hardware, licenses and scarce skills alive. Legacy systems also become harder to secure as vendor support ends, and their data grows harder to extract as volumes increase. Analytics and AI projects that need modern platforms wait too, so the business carries both the old costs and the missed value.
What is the difference between data migration and data integration?
Data migration is a one-time move of data from a source system to a target, ending with the source retired or archived. Data integration is an ongoing process that keeps several live systems connected and consistent. A migration often uses integration techniques such as change data capture while both systems run side by side during coexistence.
How do you migrate data without losing it?
Map every source table and consumer first, then move data with restart points and change data capture checkpoints. Make writes idempotent so replays are safe, and handle deletes explicitly. Validate in three layers covering structure, record values and business totals, and keep the old system read-only until operational acceptance, so nothing is lost if a gap appears.
How do you minimize downtime during data migration?
Load a consistent snapshot in bulk while the source stays live, then stream changes with change data capture until lag is low and stable. Freeze writes only for the final delta, run a fast reconciliation and switch connections. Rehearse the sequence on production-size data and agree an abort deadline that leaves time to reopen the source.