TL;DR
In RAG vs LLM, use a standalone LLM for drafting and general questions, and add RAG when answers depend on private, changing or auditable information. An LLM generates text from what it learned in training, while RAG retrieves relevant documents and hands them to that LLM before it answers. Every RAG system still runs on an LLM, so the real decision is whether to add a retrieval layer. Million-token context windows on models such as Claude Opus 5.5 and GPT-6.1 Sol do not remove retrieval, because company knowledge is larger, changes daily and needs per-document permissions. In a worked example at November 3, 2026 list prices, sending 200K tokens per question costs about 30 times more each month than retrieving five relevant chunks. Test retrieval quality on a fixed question set first, then choose the model.
Key Takeaways
- An LLM answers from its training data, while RAG retrieves your documents at question time and passes them to the same kind of model.
- A standalone LLM fits drafting, summarizing text you paste in, code help, translation and general questions.
- RAG fits private, frequently updated, permission-sensitive or auditable knowledge, where each answer needs a source.
- Context windows of about 1M tokens make small, stable knowledge easy to load, but resending a large prompt per question cost about 30 times more than retrieval in our worked example.
- Six questions on unseen data, update frequency, citations, permissions, corpus size and format settle the choice, and a standalone LLM fits when none of the first four applies.
- Most RAG failures start in retrieval, so measure context precision, recall and faithfulness before you upgrade the model.
Your Model Is Fluent. It Has Never Read Your Policy Manual.
Picture an employee asking the company assistant a simple question: how much can I spend on a hotel during this quarter’s client visits? A standalone LLM answers at once, in clear and confident prose. Yet the nightly limit it quotes, though sensible, appears nowhere in your travel policy.
Still, the model is not broken. It has simply never seen the policy, which HR revised in the spring and stored in a folder the model cannot reach.
A RAG system handles the same question in a different order. It searches the policy library first, finds the current lodging section, and hands that passage to the model along with the question. The answer quotes the real limit and links to the page it came from, so the employee can check it in seconds.
That gap between a fluent answer and a sourced answer sits at the center of the RAG vs LLM question. This guide explains what each approach does and what it costs at November 3, 2026 list prices. It then shows how to decide which one a use case needs.
RAG vs LLM: The Short Answer
An LLM is a model, and RAG is an architecture built around one. A large language model generates text from patterns it learned during training. Retrieval-augmented generation adds a search step that finds relevant documents and places them in the prompt before the model writes its answer.
The term comes from a research paper by Lewis et al., submitted on May 22, 2020 and published at NeurIPS 2020. It paired a document retriever with a generator model so that answers could draw on text outside the model’s weights. The tooling has changed a great deal since then, yet the core idea holds: look things up first, then generate.
For a team comparing the two, the practical version is short. Use an LLM on its own when the task depends on general knowledge or on text you supply. Add retrieval instead when the answer must come from your own documents, stay current or show its source.
This post therefore focuses on that architecture decision. For the wider topic of how these systems are designed and governed, see our guide to retrieval-augmented generation.
Is RAG a Replacement for an LLM?
No. Every RAG system still needs an LLM to read the retrieved passages and write the reply, so retrieval sits in front of the model. Remove the model and you are left with a search engine that returns a ranked list of documents.
The useful question is whether a given use case needs that retrieval layer at all. Many tasks do not, and adding RAG to them only adds cost, latency and moving parts. Others fail without it, however capable the model is.
What an LLM Does on Its Own, and Where Its Knowledge Stops
A standalone LLM is a very capable writer with a fixed memory. It learned language, facts and reasoning patterns from a large training set, then stopped learning when training ended. Everything it knows at answer time comes from those weights plus whatever you type into the prompt.
That design is why LLMs are so good at general tasks, and the amount they can read in one prompt keeps growing. Anthropic announced Claude Opus 5.5 on September 22, 2026. OpenAI followed with GPT-6.1 Sol on September 29, 2026, and both accept prompts of about one million tokens. That leaves room to paste in several long reports at once.
Google’s Gemini 4 Argon, whose model card was published on October 13, 2026, supports up to 1M tokens of combined context. For background, see how LLMs fit within generative AI, or read how an LLM works under the hood.
Four Limits of a Standalone LLM
Even so, size and speed do not change the basic limits. Four of them show up as soon as a standalone LLM meets company work:
- A training cutoff. The model knows nothing that happened after its training data was collected, which is how training data sets a knowledge cutoff. A pricing change or a new regulation published later is invisible to it.
- No access to private data. Contracts, tickets, policies and product specs were never in the training set. So the model can only guess at them.
- No source citations. A standalone model cannot point to the document behind a claim, because it never retrieved one. Reviewers therefore have nothing to check.
- Confident errors. When the model lacks a fact, it often produces a plausible one instead. This is the core of LLM hallucination, and it reads exactly like a correct answer.
None of these limits matter much for a marketing draft or a code explanation. All four matter when a customer, an auditor or an employee relies on the answer to act. That second group of tasks is where retrieval earns its place.
Kanerika Service
LLM Development Services
Kanerika designs and builds LLM applications for drafting, summarization and analysis, with evaluation and guardrails set before launch.
Explore LLM DevelopmentHow RAG Works, Step by Step
RAG works like an open-book exam for the model. Before answering, the system finds the pages most likely to contain the answer and puts them on the desk. The model then writes its reply from those pages instead of from memory alone.
Take the travel-policy question from the opening, for example. The policy PDF was split into short sections and indexed when it was published. When the employee asks about hotel limits, the system finds the two sections on lodging, passes them to the model, and the answer cites both.
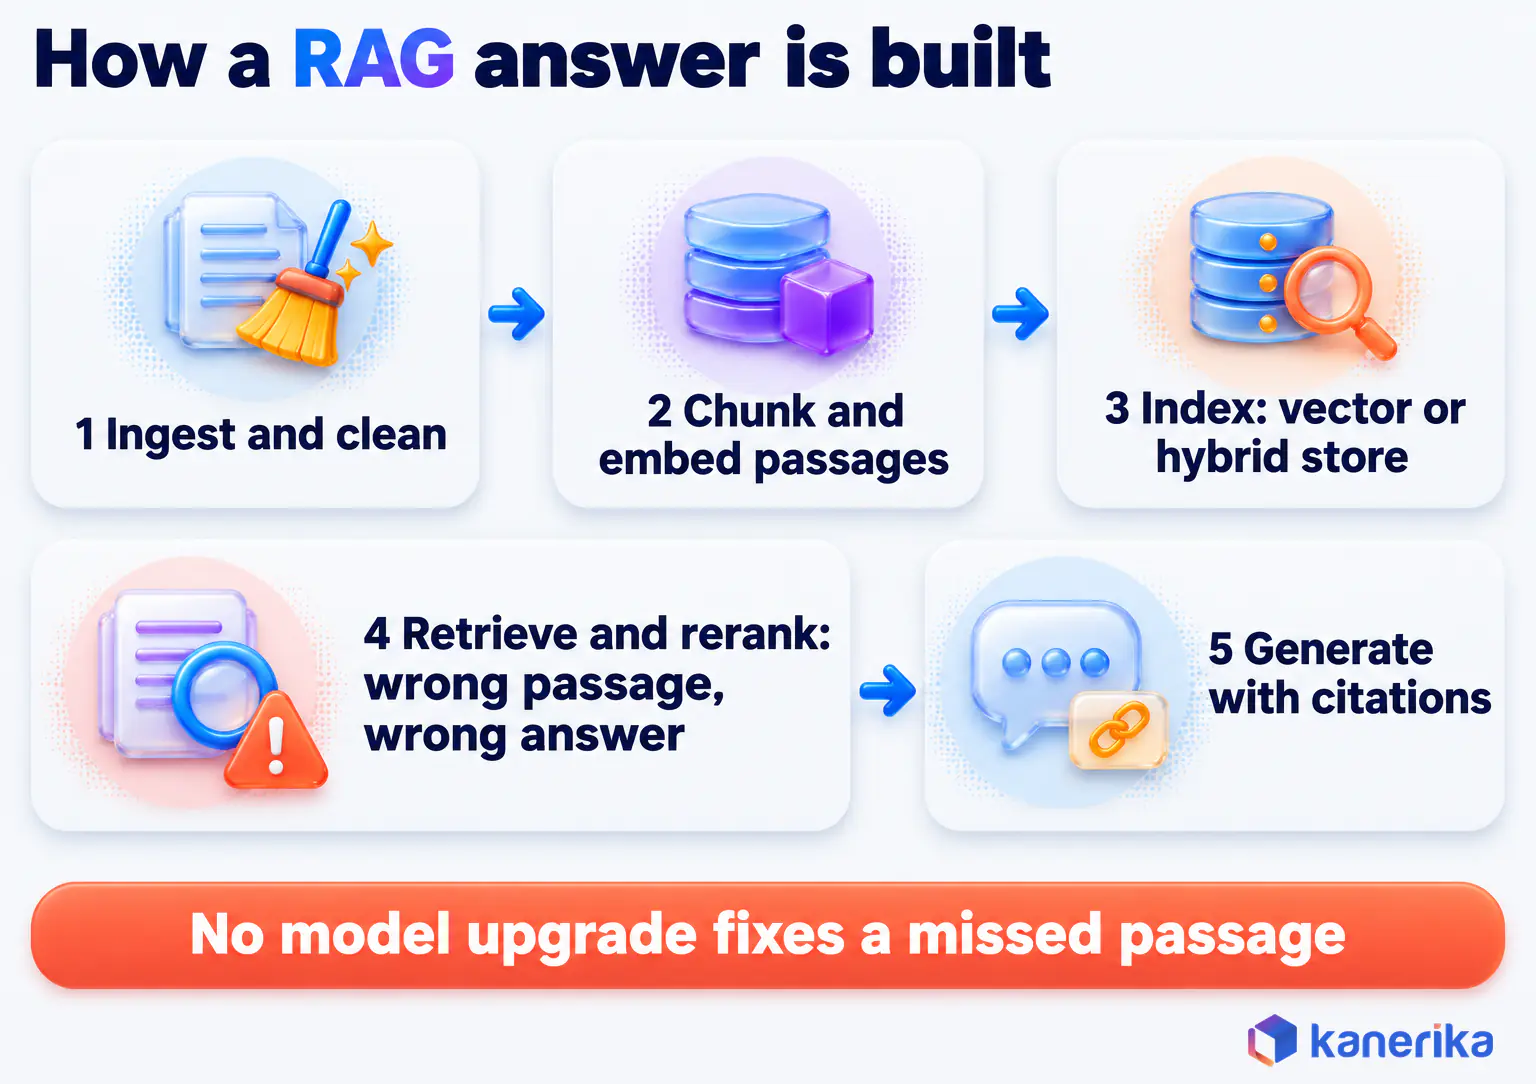
Each stage of that flow carries its own design choices, covered in our guide to each stage of a RAG pipeline. At a high level, a production system runs five stages:
- Ingest and clean. Connectors pull documents from file shares, wikis, ticket systems and databases. Document preprocessing removes headers, duplicates and broken tables that would confuse search.
- Chunk and embed. Each document is split into passages, and an embedding model turns every passage into a vector that captures its meaning.
- Index. The vectors and their metadata go into a vector database or a hybrid store that also supports keyword search.
- Retrieve and rerank. The question is embedded the same way, the closest passages are fetched, and a reranker orders them by relevance.
- Generate with citations. The top passages and the question go to the LLM, which writes an answer and cites the passages it used.
Why Chunking Matters
Chunking deserves more attention than it usually gets. Passages that are too long dilute the match, and passages that are too short lose the sentence that explains a number. Metadata such as document owner, date and access group travels with each chunk, which later makes filtering and freshness checks possible.
The order of the stages matters more than it looks. If step four returns the wrong passage, the model has nothing correct to work from. For that reason, most tuning effort goes into search and ranking.
RAG Patterns in 2026: Hybrid Search, Agentic RAG, GraphRAG and CAG
The basic five-stage design has grown several variants, each aimed at a specific weakness. Teams usually start simple and add a pattern only when evaluation shows the gap it closes. Comparing the RAG tools and frameworks that implement them is also a separate exercise.
| Pattern | What it adds | Worth it when |
|---|---|---|
| Hybrid search | Keyword matching alongside vector search, so exact terms such as product codes are found | Queries mix names, codes and natural language |
| Agentic RAG | The model plans several retrieval steps and checks what each one returns | One search cannot answer the question |
| GraphRAG | A graph of entities and relationships, with summaries of related groups | Questions ask about themes across a whole corpus |
| CAG (cache-augmented generation) | Preloads a small, stable knowledge set into the context and reuses the cache | The knowledge fits in the window and rarely changes |
In agentic RAG, the model decides what to search next, which helps when an answer needs several lookups. GraphRAG comes from Edge et al. (2024), and our guide to knowledge graph RAG shows where entity links help. CAG, described by Chan et al. (2024), skips retrieval for small, stable knowledge and preloads it instead.
RAG vs LLM: Differences at a Glance
The cleanest way to compare the two is dimension by dimension, holding the model constant. In the table, “RAG” means the same LLM with a retrieval layer in front of it. That framing keeps the comparison fair, since the generator can be identical on both sides.
| Dimension | Standalone LLM | RAG (the same LLM plus retrieval) |
|---|---|---|
| Knowledge source | Training data, fixed when training ended | Training data plus documents retrieved for each question |
| Freshness | Stops at the training cutoff | As current as the last index update |
| Private data | None, unless you paste it into the prompt | Indexed company sources, searched on demand |
| Citations | Cannot point to a source document | Can cite the passage behind each claim |
| Hallucination risk | Higher on company-specific facts | Lower when retrieval finds the right passage, though never zero |
| Context limits | About 1M tokens on leading models as of November 3, 2026 | The same window, filled with the passages retrieval selects |
| Cost per query | Grows with every token sent in the prompt | Small prompts, plus embedding and vector search charges |
| Latency | One model call | Adds a search and rerank step before generation |
| Access control | The model sees whatever is in the prompt | Documents filtered by user permissions at retrieval time |
Reading the Table
Three rows decide most projects: freshness, private data and access control. If a use case touches any of them, a standalone model will struggle however good it is. The other rows mostly shape cost and speed once the architecture is chosen.
The context row needs a closer look, because it moved the most during 2026. As of November 3, 2026, Claude Sonnet 5.5, GPT-6.1 Sol and Gemini 4 Argon all accept about a million tokens. The difference between the two approaches lies in cost, corpus size and permissions, and the long-context section below works through the numbers.
The way each side gets its information is the root of every other row:
- RAG:
Actively uses external sources of information, such as search indexes, APIs, or document repositories. This real-time external querying illustrates the core operational mechanism of how does rag work in modern enterprise architectures. This allows it to deliver factually accurate and updated information in real-time or on-demand. - LLM:
Relies on what it absorbed during training and on the text placed in its prompt. It cannot query an index, an API or a document store by itself, so its knowledge ends at its training cutoff.
Simplicity Versus Control
In practice, these differences show up as a set of trade-offs. A standalone LLM is simpler to run, with one model call, no index to maintain and no ingestion pipeline. A RAG system adds a search step before generation, along with storage and query charges that vary by vendor.
What you get in return, though, is control. You decide which documents the model may see, you can correct an answer by correcting a document, and every reply can carry a citation.
For regulated or customer-facing work, that control is usually the reason the project exists. It is also what lets a compliance team sign off on an assistant before it reaches customers.
Checklist
Generative AI Checklist
Work through the data, security, evaluation and ownership checks to settle before a generative AI or RAG system goes into production.
Get the Checklist →When an LLM Alone Is Enough
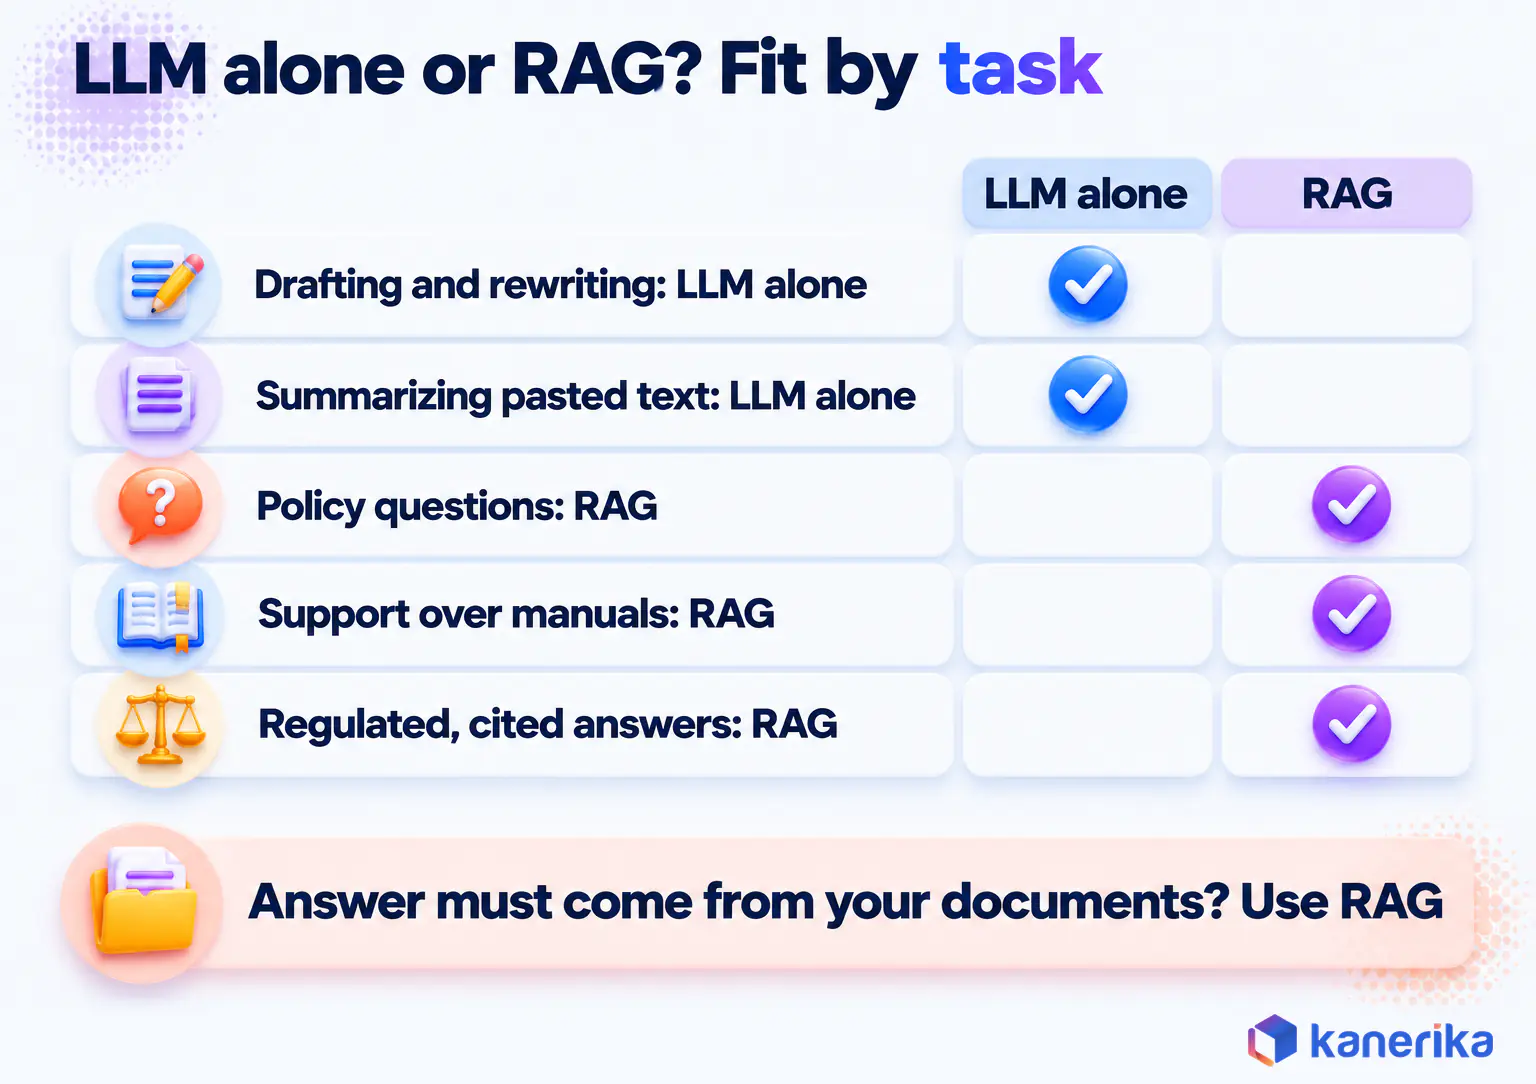
A standalone LLM is the right tool whenever the knowledge a task needs is general, or you hand it over in the prompt. In those cases retrieval only adds cost and complexity, because the answer stays the same. A good test is whether a capable new hire could do the task without opening any company system.
Consider a product manager who pastes a long research report into a chat and asks for a one-page summary. Everything the model needs is already in the prompt, so there is nothing to retrieve. The same also holds for rewriting an email, explaining a regular expression or brainstorming launch names.
Common tasks where a standalone LLM is enough include:
- Drafting and rewriting. Emails, job descriptions, marketing copy and first drafts of reports.
- Summarizing pasted text. Meeting notes, articles or documents you supply in the prompt.
- Code help. Explaining, reviewing or generating code that uses public languages and libraries.
- Brainstorming. Names, outlines, test cases and alternative approaches to a problem.
- Translation. Converting text between languages while keeping its tone and meaning.
- Education and training content. Lessons, quizzes and explanations of general concepts.
Education and Training Content
Educational Support LLMs can also generate personalized learning materials, explain difficult concepts, offer interactive tutoring, and develop adaptive learning experiences, the kind of pacing the best language learning website options use for one subject, extended here across any domain a learner needs.
Training teams also use the same strength for onboarding material and practice questions. Once a course must quote the company’s own procedures, though, the task crosses into retrieval territory.
Cost is another reason to stay simple. For high-volume, low-risk tasks such as classification or short rewrites, small language models and low-cost hosted tiers often do the job well.
As of November 3, 2026, Claude Haiku 5.5 lists $0.10 per million input tokens and $0.50 per million output, for prompts up to 100K. GPT-6 Luna lists the same two rates, a twentieth of the Claude Sonnet 5.5 input price.
The line moves the moment a task needs facts the model has never seen. A policy question, a contract clause or a customer’s ticket history all fall outside training data, however the prompt is worded.
When You Need RAG Instead of a Standalone LLM
RAG becomes necessary when the answer lives in your documents and nowhere else. Fluency does not help if the source fact is missing from the model. Five situations make retrieval close to mandatory:
- Private company data. Policies, contracts, product specs and internal wikis were never in any training set. Retrieval is the only way the model can read them at question time.
- Frequently updated data. Price lists, inventory, support articles and regulations change weekly or daily. Re-indexing a changed document is a routine job, while retraining a model is a project that goes stale again.
- Answers that need citations or an audit trail. Legal, finance and healthcare teams must show where an answer came from. RAG returns the passage behind each claim.
- Permission-sensitive data. HR files, deal documents and patient records must only reach people allowed to see them. Retrieval can filter by user permissions before any text reaches the model.
- Corpora too large for any window. A knowledge base spanning tens of thousands of documents will not fit in a one-million-token prompt. Retrieval selects the few passages that matter for each question.
Where These Conditions Show Up
These conditions show up across industries. In customer support, customer support agents answer from the current help center and product manuals, so a changed return policy reaches customers the same day.
In legal document review and compliance work, retrieval lets a reviewer jump from each answer straight to the clause behind it. Healthcare guidance follows the same logic, since clinical protocols change and every recommendation needs a traceable source.
Research teams use RAG to search large internal libraries and cite findings across many reports. Much of that groundwork depends on document processing that turns scanned files and forms into clean, searchable text.
A useful sign that a project needs RAG is the follow-up question users ask most. If it is “where did that come from?”, the system needs citations, and citations need retrieval.
Once retrieval is reliable, many teams start asking analytical questions of the same enterprise data, such as trends across tickets or contracts. The Kanerika podcast episode below looks at the AI analytics tools and strategies teams are weighing for 2026.
Long Context vs RAG: Does a 1M-Token Window Replace Retrieval?
Long context means the model can read a very large prompt in one pass. As of November 3, 2026, leading models accept about a million tokens. That is enough room for a large document set, which raises a fair question. If everything fits, why build a retrieval layer at all?
The answer comes down to cost, corpus size and permissions. Every token you send is billed on every question, so a large prompt multiplies spend. Most company knowledge is also far larger than one window and changes daily, and one shared prompt cannot respect per-document access rights.
Cost Arithmetic at List Prices
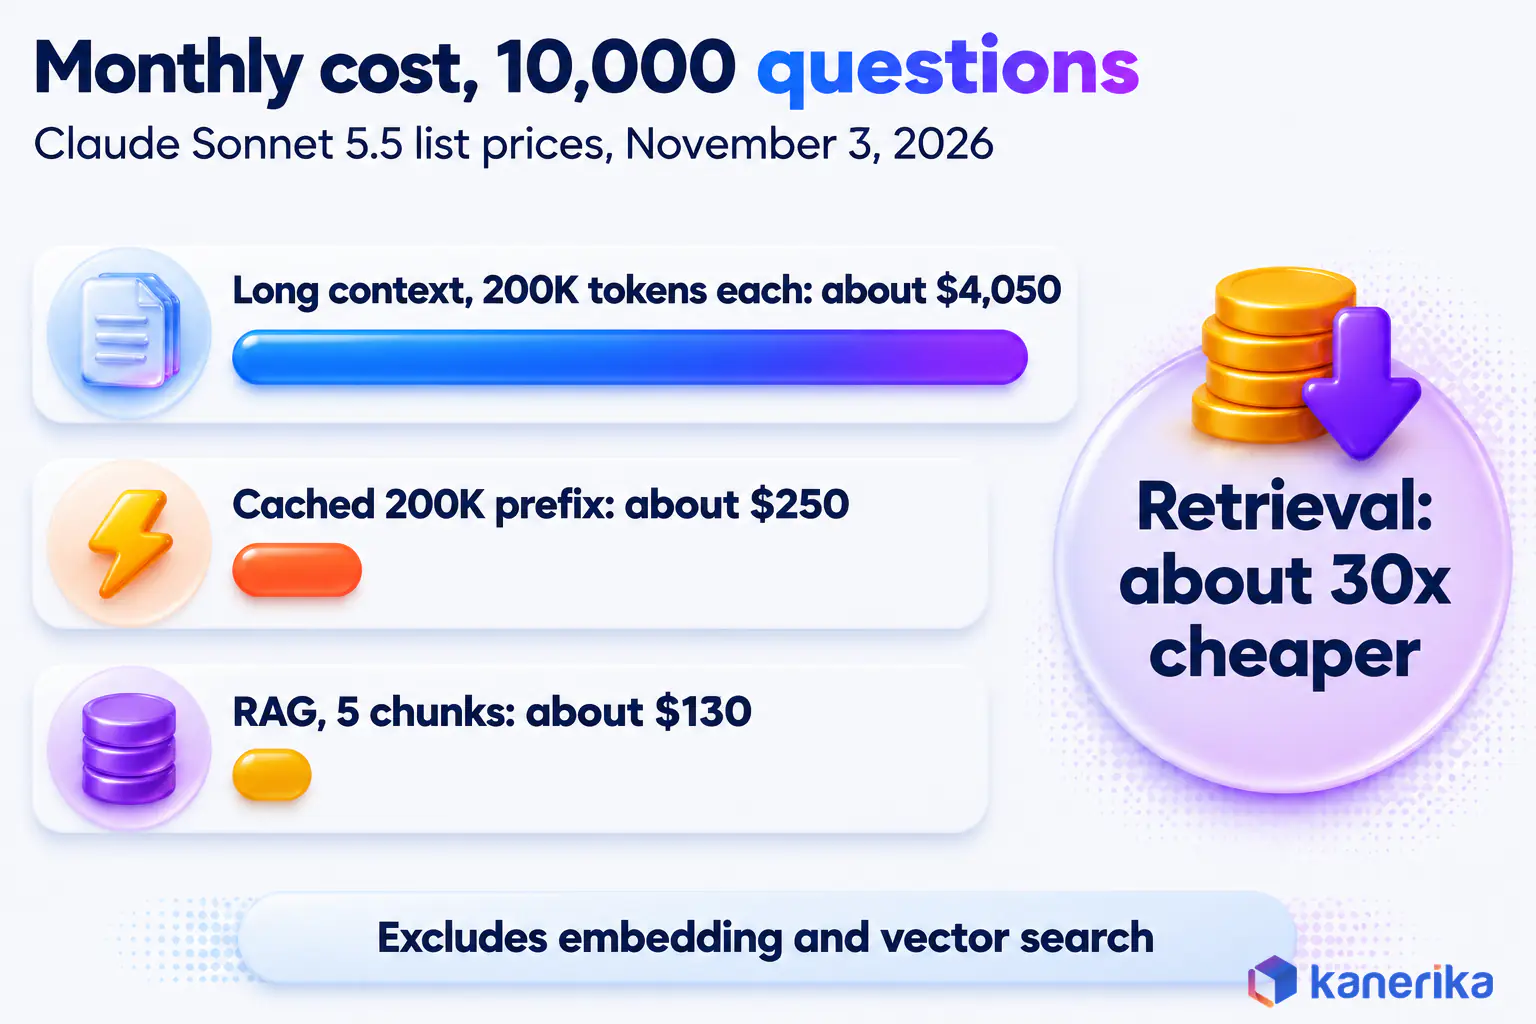
The cost gap is easy to estimate, because list prices are public. The table below uses Claude Sonnet 5.5 list prices of $2 per million input tokens and $10 per million output tokens. It also assumes 10,000 questions a month and 500 output tokens per answer.
| Setup (10,000 questions a month) | Input tokens per question | Input cost per month | Output cost per month | Total per month |
|---|---|---|---|---|
| Long context, full prompt every time | 200,000 | $4,000 | $50 | About $4,050 |
| Long context, same prefix served from prompt cache | 200,000 (cached reads) | $200 | $50 | About $250, plus small cache-write charges |
| RAG with 5 retrieved chunks | About 4,000 | $80 | $50 | About $130, plus embedding and vector search |
This is illustrative arithmetic from list prices on November 3, 2026. Embedding and vector search costs are excluded and vary by vendor, so the RAG figure is a floor for that row. Even so, $4,050 against $130 is a gap of about 31 times.
The cached row explains why cache-augmented generation works in some cases. Sonnet 5.5 bills cached input reads at $0.10 per million tokens. A fixed 200K prefix served from cache drops to about $250 a month, plus small cache-write charges at $2.50 per million.
That saving holds only while the knowledge is small and stable. Each edit to the cached text means writing the cache again, and a corpus that changes daily keeps paying that charge.
Price Tiers and Speed
Pricing tiers can also punish very long prompts. GPT-6.1 Sol bills prompts over 272K tokens at twice the input rate and 1.5 times the output rate. A 500K-token prompt therefore costs $4 per million input tokens, or about $2 per question in input alone.
Gemini 4 Argon shows a different risk, a scheduled price change. Its list price is $2 input and $10 output per million tokens through November 30, 2026, rising to $4 and $20 from December 1, 2026. Run on Gemini 4 Argon, the RAG workload above would see its monthly input bill move from $80 to $160.
Speed follows the same pattern as cost. A model has to read every token you send before it answers. So a very large prompt tends to slow the reply, while a short retrieved prompt keeps it quick.
The practical rule is to retrieve to select and use long context to reason. Retrieval first picks the passages that matter, and a large window then lets the model reason across all of them at once. Good context engineering is mostly about deciding what earns a place in that window.
RAG vs Fine-Tuning vs Long Context
Fine-tuning is the third option teams weigh, and it solves a different problem. It changes the model’s weights by training on examples, which makes it good at teaching format, tone and task behavior. It is a poor way to add facts, because each new fact means another training run.
Long context sits between the two, giving the model more to read without changing it. Many production systems combine all three, with retrieval for knowledge, a light fine-tune for output format and a large window for reasoning. For the full trade-off, read our guide to RAG vs fine-tuning, and see parameter-efficient fine-tuning for lower-cost training methods.
| Approach | What it changes | Keeps knowledge current? | Best for |
|---|---|---|---|
| RAG | What the model sees for each question | Yes, with each index update | Private, changing or cited facts |
| Fine-tuning | The model’s weights and default behavior | No, each change needs retraining | Fixed formats, tone and label sets |
| Long context | How much the model reads at once | Only if you resend fresh text | Reasoning over one bounded document set |
The table points to a simple order of work. First, fix knowledge gaps with retrieval, then fix behavior gaps with tuning. Use long context when one large but bounded document set needs reasoning across it.
Kanerika Service
RAG Development Services
Kanerika builds permission-aware RAG systems with hybrid search, source citations and an evaluation set that proves each change.
Explore RAG DevelopmentA Decision Framework: RAG, LLM or Both
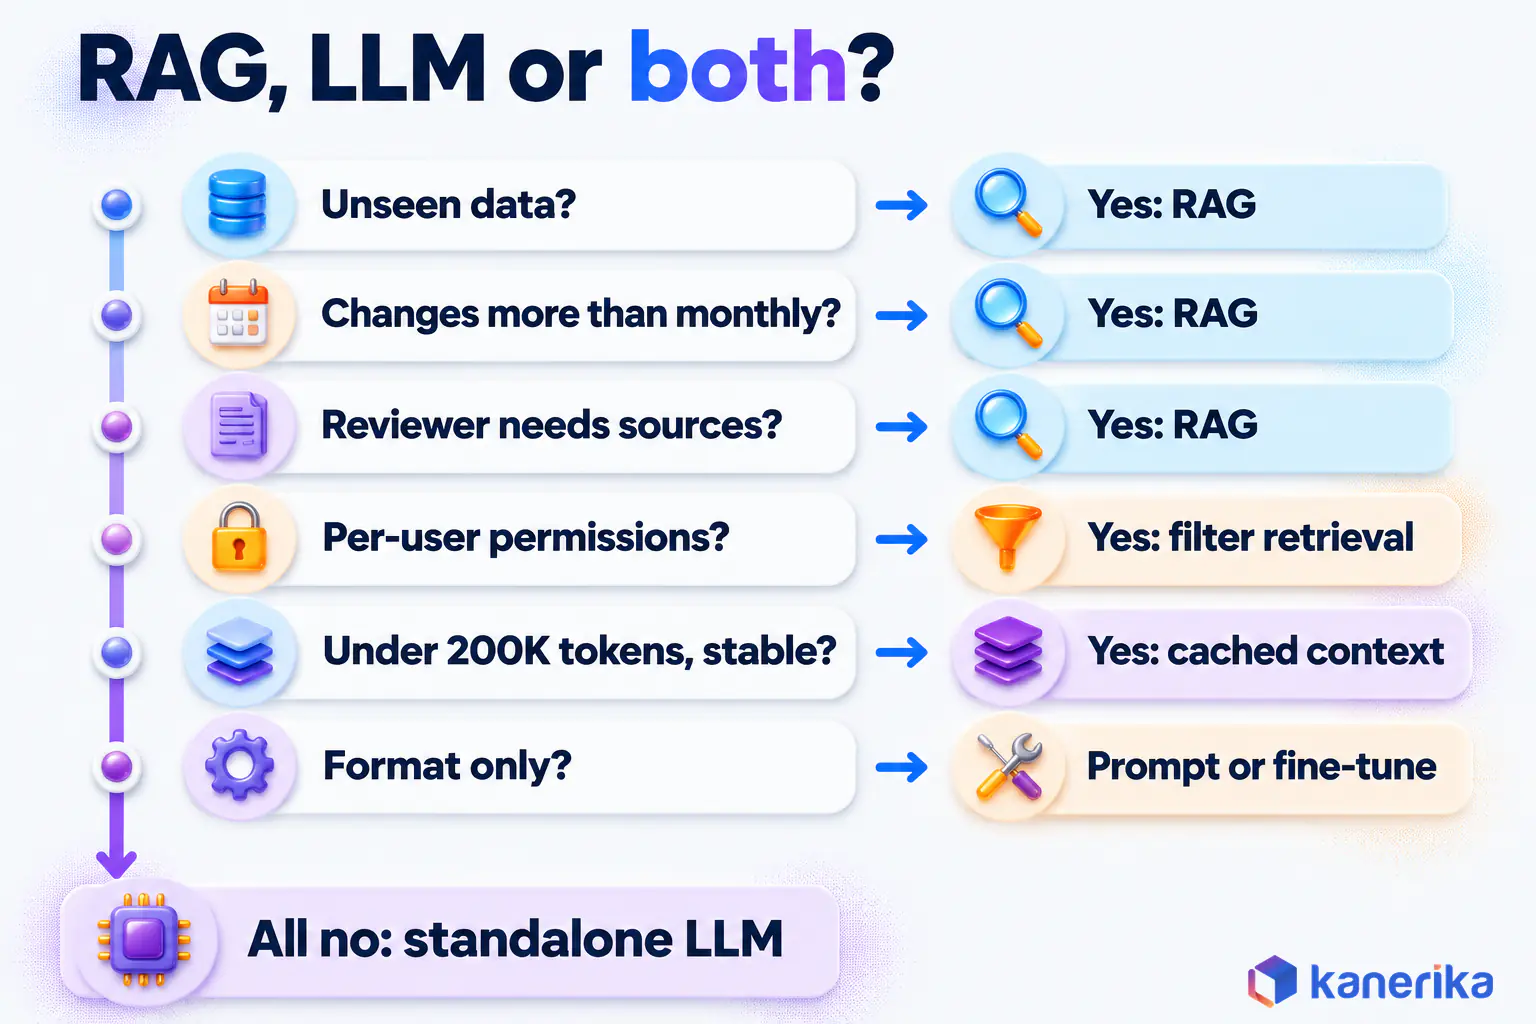
Most RAG vs LLM decisions can be settled with six questions, asked in order. Each one either points toward retrieval or clears the way for a simpler design. Work through them for each use case separately, since one assistant can mix both kinds of task.
- Does the answer depend on data the model never saw? If yes, add retrieval, because no prompt wording can supply facts the model lacks.
- Does that data change more than monthly? If yes, retrieval keeps answers current, since re-indexing is cheap and retraining is slow.
- Must a reviewer see the source? If yes, use RAG with citations, so every claim links to a passage.
- Do different users have different permissions? If yes, enforce those permissions inside retrieval, before any text reaches the model.
- Does the source fit in under about 200K tokens and stay stable? If yes, long context with prompt caching may be enough, which is the CAG pattern.
- Is the need style or format rather than facts? If yes, start with prompting, consider fine-tuning later, and skip retrieval.
A yes on any of the first four questions puts a retrieval layer in the design. The one exception is a yes on question five without a yes on question four, where a small, stable source can be cached instead. A yes on question six alone points to prompting or tuning, and if every answer is no, a standalone LLM with good prompts is the right call.
Applying the Framework to Two Requests
First, run the travel-policy assistant through the list. The policy is private, employees want to see the clause, and some sections differ by region and grade. That is three yeses, on questions one, three and four, so the assistant needs RAG with permission filters.
Then take a request to draft a product launch email from notes the marketer pastes in. Nothing is private beyond the notes, nothing needs a citation, and the need is tone and structure. Every answer is no, so a standalone LLM handles it well.
Many teams, however, find both kinds of request in the same tool. In that case, route each request to the right path, and keep the retrieval layer for the questions that need it. Teams with strict data residency rules should also consider private LLM deployment, so the model and the index stay inside their own environment.
Where RAG Fails and How to Evaluate It
RAG reduces errors without removing them, and its failures look different from a standalone model’s. Most problems start before generation, in what the system retrieved or failed to retrieve. That makes them fixable, as long as you can see where the chain broke.
A support team might find its assistant quoting a return window that changed two weeks earlier. The model did nothing wrong, because it faithfully summarized an outdated article that was never re-indexed. So the fix sits in the pipeline, which is why the table below starts from symptoms.
| Failure | Likely cause | Fix |
|---|---|---|
| Wrong passage retrieved | Chunks too long or short, or embeddings missing exact terms | Hybrid search, better chunk boundaries and a reranker |
| Outdated answer | The index was not refreshed after a source changed | Scheduled re-indexing and stale-index alerts |
| Unauthorized content returned | Permissions checked after generation, or not at all | Filter by user permissions at query time |
| Unsupported answer | The model filled gaps beyond the retrieved text | Require citations and score faithfulness |
| Cost creep | Too many or too large chunks per question | Cap the chunk count and track cost per answer |
The unsupported-answer row sits closest to classic hallucination. Understanding why models produce unsupported answers helps teams write prompts that keep the model inside the retrieved text.
Datasheet
KlarityIQ: Your Document Intelligence Agent
See how KlarityIQ turns enterprise documents into structured, searchable content that a RAG system can retrieve with permissions intact.
View the Datasheet →Measuring Retrieval and Answer Quality
Evaluation should score retrieval and generation separately, on a fixed set of real questions with known answers. The Ragas metrics documentation names the measures most teams start with:
- Context Precision. How much of the retrieved text is relevant to the question.
- Context Recall. Whether retrieval found everything needed to answer.
- Faithfulness. Whether each claim in the answer is supported by the retrieved context.
- Response Relevancy. Whether the answer addresses the question that was asked.
- Factual Correctness. How closely the answer matches a reference answer.
One rule, in particular, saves a lot of wasted effort. If the right passage is not in the top results, no model upgrade fixes the answer, so check retrieval metrics before you change the model.
An LLM evaluation framework keeps these scores comparable across releases. Once the system is live, AI observability tools track the same signals on real traffic.
Security: Permission-Aware Retrieval
Retrieval also opens a new path for data to leak. The OWASP entry LLM08:2025 Vector and Embedding Weaknesses names unauthorized access and data leakage from misaligned access controls as risks. A vector store that ignores document permissions will hand an intern the board minutes.
The fix is to filter by user permissions at retrieval time, before any text reaches the model. Screening the output afterward comes too late, because restricted text that reaches the model can surface in the reply.
Teams should also treat retrieved text as untrusted input, since a planted instruction inside a document can steer the model. These checks belong alongside the wider LLM security controls a team already runs, such as logging, rate limits and output review.
How Kanerika Builds RAG and LLM Systems
Kanerika treats the RAG vs LLM question as a data question first and a model question second. Most of the work on a production assistant goes into knowing what the documents are, who owns them and who may read them. Model choice comes later, once retrieval can be measured. Kanerika’s RAG development and LLM development services both start from that inventory.
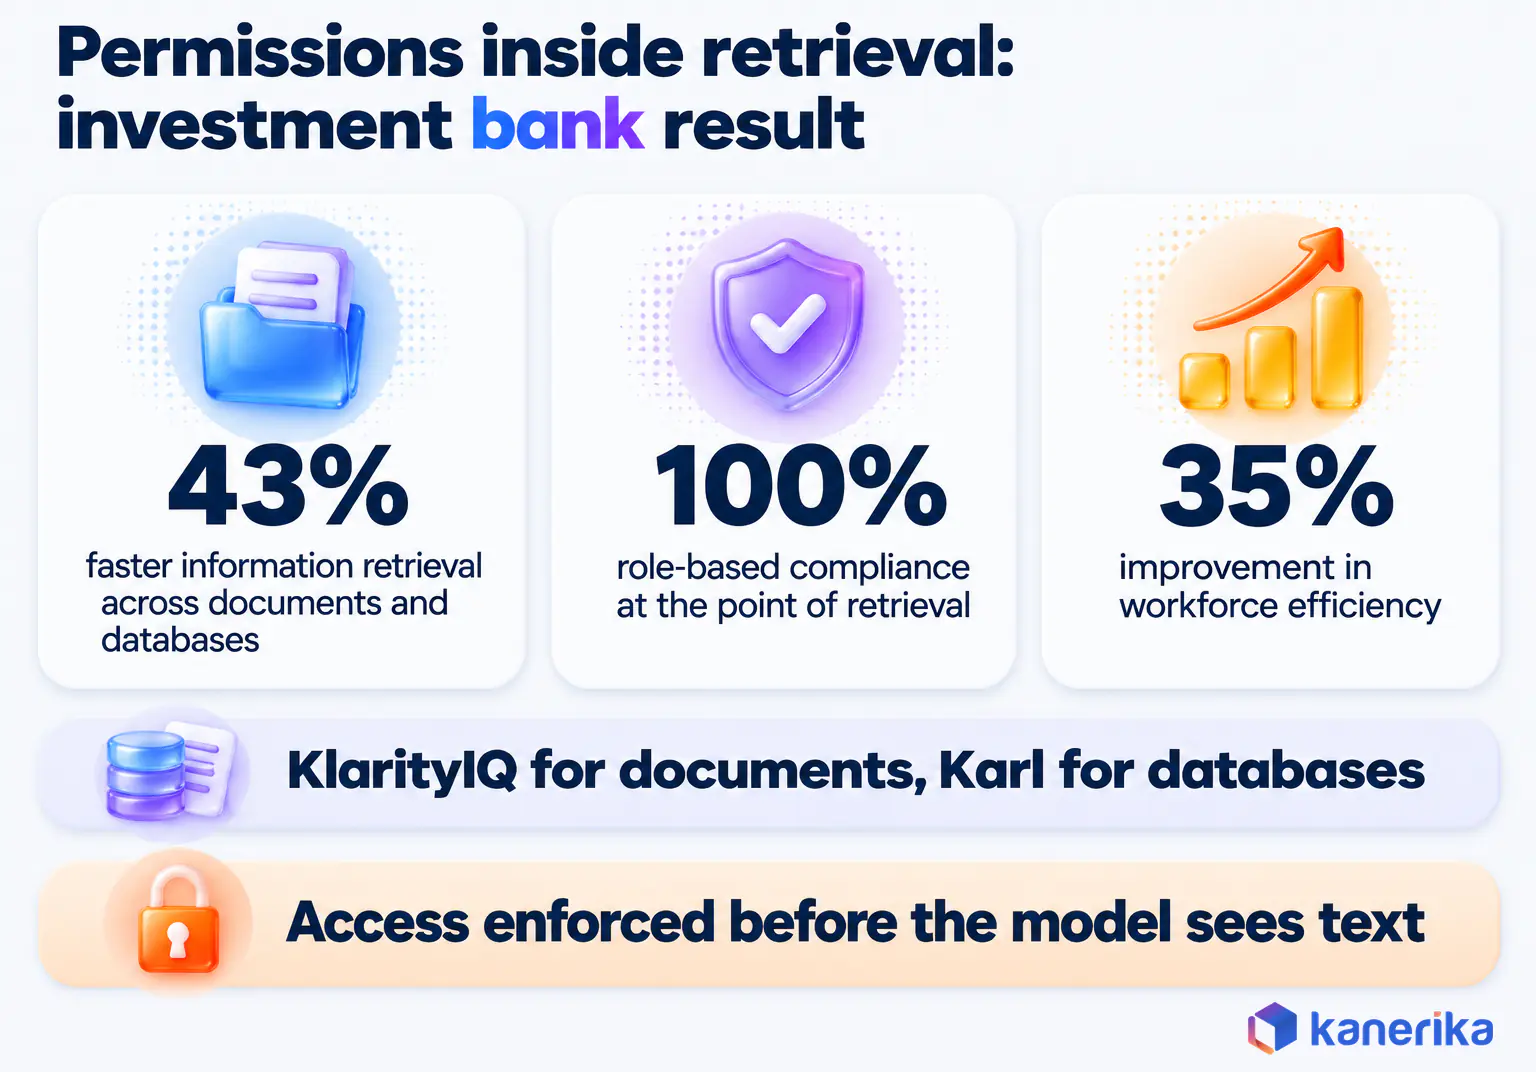
Two parts of Kanerika’s FLIP platform do much of this work. KlarityIQ is a document intelligence agent that turns unstructured files into searchable, structured content. Karl answers natural-language questions over structured data, so one assistant can query databases as well as documents.
Four Stages, in Order
Projects then follow four stages:
- Assess data and access. Inventory sources, owners, refresh cadence and who may see what, before any index is built.
- Build retrieval with permissions inside it. Chunking, metadata, hybrid search and role filters applied at query time.
- Evaluate on a fixed question set before choosing the model. Retrieval metrics come first, then the faithfulness of the answers.
- Operate. Monitor retrieval hit rate, cost per answer and stale-index alerts once the system is live.
The order reflects where projects tend to go wrong. A model swap is easy to make later, while a permission model added after launch usually means rebuilding the index.
The same stages apply whether the final design is a standalone LLM, a RAG system or a mix. Stage one often shows that some requests need no retrieval at all, which keeps the build smaller.
Evaluation is where the RAG vs LLM choice gets settled with evidence. A fixed set of real questions, scored on retrieval and faithfulness, shows whether a standalone model already answers well enough. If it does not, the same set shows how much retrieval closes the gap.
Case Study: 43% Faster Document Retrieval for an Investment Bank
A leading investment bank searched its document repositories and databases through separate interfaces. Access controls sat outside the retrieval process.
Kanerika deployed KlarityIQ for unstructured RFI documents and Karl for database queries, both behind chat interfaces. Role-based access control was applied at the retrieval layer, so each user could only retrieve content they were cleared to see. The investment bank case study reports three results:
- “43% faster information retrieval across documents and databases”
- “100% role-based compliance achieved at the point of retrieval”
- “35% improvement in workforce efficiency”
In other words, this is the permissions-inside-retrieval argument in practice. A long-context LLM given every document in one prompt would have struggled to meet that compliance result, because it reads everything regardless of who asked. Building a separate prompt for each user’s permissions is, in effect, retrieval under another name. Filtering at retrieval meant each answer was built only from content the asking user was cleared to see.
Talk to Kanerika
Planning a RAG or LLM Assistant?
Bring one use case and a sample of real questions. Kanerika’s team will help you decide whether it needs retrieval and how to test it.
Book a Consultation →Wrapping Up
RAG and LLMs work as two layers of one system. The model supplies language and reasoning, and retrieval supplies current, private and permitted facts with a source attached.
Use a standalone LLM when the knowledge is general or already in the prompt. Add RAG when answers must come from your own changing, permissioned documents. That is how to choose in RAG vs LLM for 2026: test retrieval on real questions first, then pick the model.
Frequently Asked Questions
What is the difference between RAG and LLM?
An LLM is a language model that answers from patterns it learned during training. RAG is an architecture that first retrieves relevant documents from your own sources and passes them to an LLM with the question. The LLM still writes the reply, while retrieval grounds it in current, private and citable information the model never saw in training.
When should I use RAG instead of a standalone LLM?
Use RAG when answers depend on private company data, information that changes more than monthly, or sources a reviewer must be able to check. It also fits when different users have different access rights. A standalone LLM is enough for drafting, summarizing text you paste in, code help, translation and general questions that need no company knowledge.
Does RAG slow down response time?
RAG adds a search step, and often a rerank step, before the model starts writing, so it adds some latency to each answer. The prompt is usually much shorter than a long-context prompt, which can offset part of that delay. Caching frequent queries, limiting chunk counts and choosing a fast reranker keep the extra time small.
Should I choose RAG or fine-tuning?
Choose RAG when the model lacks facts, such as private, current or citable knowledge. Choose fine-tuning when the model knows enough and needs to follow a fixed format, tone or label set. Many teams start with RAG and good prompts, then add a small fine-tune only when evaluation shows a remaining behavior gap.
How do you evaluate a RAG system?
Build a fixed set of real questions with known answers, then score retrieval and generation separately. Ragas metrics such as Context Precision, Context Recall, Faithfulness, Response Relevancy and Factual Correctness cover both halves. Check retrieval first, because a model upgrade cannot fix an answer when the right passage never reached it. Rerun the set after every change.
Is RAG secure for confidential company data?
It can be, when permissions are enforced inside retrieval. Filter documents by each user’s access rights at query time, so restricted text never reaches the model. OWASP lists vector and embedding weaknesses, including data leakage from misaligned access controls, as LLM08 in its 2025 list. Also treat retrieved text as untrusted input and log every query.
Can RAG and LLM be used together?
Yes, and every RAG system already does. The retrieval layer finds the most relevant passages in your documents, and the LLM reads them and writes the answer with citations. Many production systems also add prompt caching for small, stable reference text and a light fine-tune for output format, so all three methods work as layers of one design.
Can LLMs still hallucinate even with RAG?
Yes. RAG lowers the risk without removing it. Errors usually come from retrieval, when the system fetches the wrong passage, an outdated version or too little context. The model can also add claims the passages do not support. Scoring faithfulness and context recall on a fixed question set shows which part of the pipeline causes each error.
What is the difference between RAG and CAG?
RAG searches an index for each question and sends only the relevant passages to the model. CAG, or cache-augmented generation, loads a small and stable knowledge set into the prompt once and reuses it through the provider’s prompt cache. CAG suits a short policy handbook or product sheet. RAG suits large, changing or permission-controlled document collections.
Is ChatGPT a RAG-based LLM?
ChatGPT is an application built on OpenAI’s language models, such as GPT-6.1 Sol. When web search or file search is switched on, it retrieves pages or uploaded files and answers from them, which is a form of RAG. Without those tools, it answers from the model’s training data and the text in the conversation, like any standalone LLM.
Are RAG systems more expensive to run than a standalone LLM?
Per question, RAG often costs less than sending a large document set every time. In a worked example at Claude Sonnet 5.5 list prices on November 3, 2026, RAG cost about $130 a month for 10,000 questions, against about $4,050 for 200K-token prompts. RAG does add embedding, storage and vector search costs, which vary by vendor.
Which industries benefit most from RAG and LLM?
Industries with large, changing and regulated document sets gain the most. Banking and insurance teams use RAG for policy, contract and research questions. Healthcare teams use it for clinical guidance that needs a traceable source. Legal and compliance teams use it for clause lookup and review. Customer support teams use it to answer from current help articles and manuals.
Will long-context LLMs replace RAG?
Long context reduces the need for retrieval on small, stable document sets, and it helps models reason across many passages at once. Retrieval still matters for large corpora, daily updates and per-user permissions. Sending a full 200K-token prompt for every question also costs far more, so most teams use retrieval to select and long context to reason.
Can RAG work without an LLM?
The retrieval half can run alone as a semantic search engine that returns ranked passages and links. It cannot write an answer, summarize several sources or explain a finding in plain language without a generator model. In practice, RAG means retrieval plus generation, so a language model of some size is always part of the system.