TL;DR
In Manus AI vs Genspark vs Gemma vs Gemini, pick Manus for delegated tasks, Genspark for research deliverables, Gemma for regulated data and Gemini for hosted reasoning. The four are different purchases: two agent products billed in credits, one hosted model family billed per token and one open-weight family you run yourself. As of November 2026, Manus Pro starts at $20 a month and Genspark Plus at $24.99 a month. Gemini 4 Argon costs $2 per million input tokens and $10 per million output tokens, then doubles on December 1, 2026. Gemma’s open weights cost nothing to license, but you carry the GPUs, the security work and the evaluation. Compare the options on cost per completed task and on where your data goes, then test each shortlisted tool on the same three tasks.
Key Takeaways
- Manus AI and Genspark are agent products you subscribe to, while Gemini is a hosted model family and Gemma is a set of open weights.
- Manus fits delegated, multi-step execution, while Genspark fits research that ends in slides, sheets or documents.
- Gemma costs nothing to license, and 4-bit quantization cuts its memory needs to about a quarter of the BF16 figure.
- Gemini 4 Argon handles up to 1M tokens of combined context, but its API price doubles on December 1, 2026.
- Gemini 3.8 Flash costs $0.75 per million input tokens until December 31, 2026, then rises to $1.50.
- Choose by data sensitivity first, then autonomy, then cost per completed task, and prove the choice with a three-task pilot.
Four Names, Two Kinds of Product
Picture an operations lead with one AI budget line and a shortlist of four names. A colleague swears by Manus. Another team already pays for Genspark, while IT keeps mentioning Gemma and Gemini.
The obvious plan is to pick the cheapest one that works. Then the lead opens the pages and finds credits on two, tokens on the third and no price on the fourth.
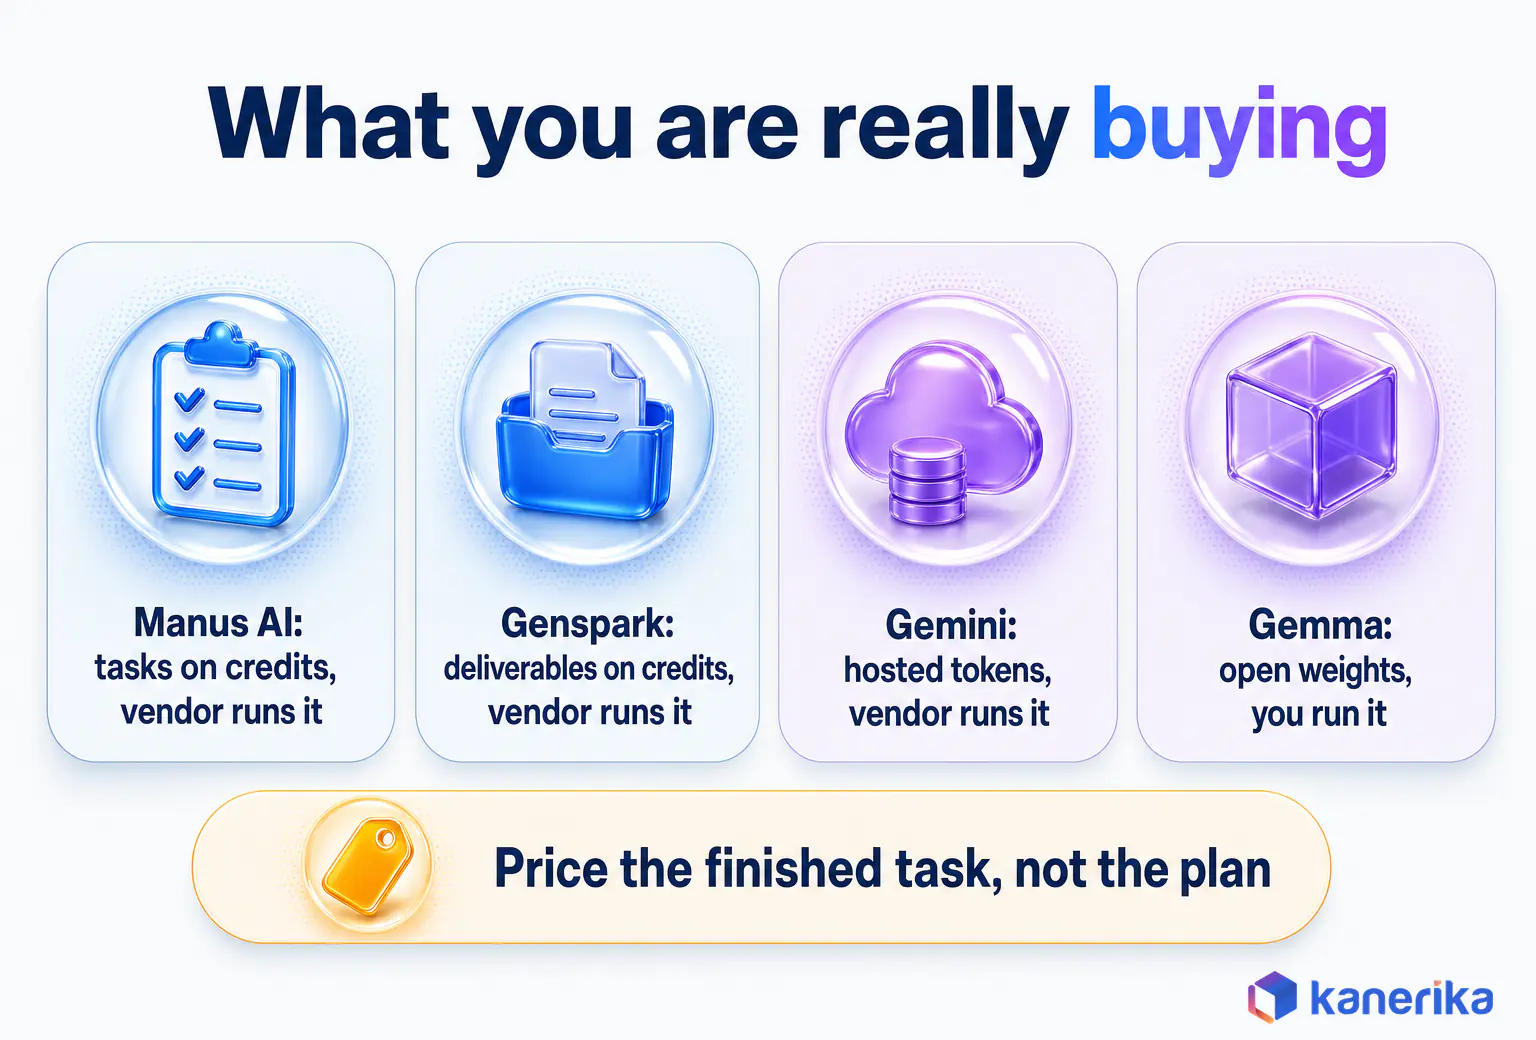
That mismatch is the real story behind Manus AI vs Genspark vs Gemma vs Gemini. Two of the names are finished agent products, while the other two are model families. This guide sorts them by what you are buying, then matches each one to a business job, with prices dated November 2026.
What You Are Actually Buying: Agent Platforms, a Hosted Model Family and Open Weights
Each of these four names sells a different thing, so the first step is to sort them into classes. An agent product gives you finished work. A model family, by contrast, gives you raw capability that someone still has to wrap in an application.
Manus and Genspark sit in the first class. You describe an outcome, such as a competitor brief or a cleaned spreadsheet, and the product plans the steps and hands back the result. Both bill in credits, so the cost of a task depends on how much work it takes. Our guide to agentic AI covers the wider idea.
Gemini and Gemma sit in the second class. Gemini is Google’s hosted model family, reached through the Gemini API, Google AI Studio or Google Cloud, and billed per token. Gemma is Google’s open-weight family, which you download and run on your own hardware, so the bill is GPUs and staff time.
Who Runs It and Who Carries the Risk
The class you buy also decides who carries the risk. With an agent product, the vendor runs the workspace while you govern what you feed it. With open weights, you run everything, which is why teams building an enterprise LLM stack often start there. The split between AI agents and LLMs works the same way, since one acts while the other answers.
| Product | Class | What you get | Who runs it | Pricing unit |
|---|---|---|---|---|
| Manus AI | Agent product | A delegated agent that plans, browses and runs code, then returns a finished output | Manus, in its cloud workspace | Monthly plan with credits |
| Genspark | Agent workspace | Research, as well as AI Slides, AI Sheets, AI Docs and Genspark Code | Genspark | Credits, or per seat once a team joins |
| Gemini 4 Argon and 3.8 Flash | Hosted model family | Model calls when your app or a Google app sends a request | Per million tokens, or a subscription | |
| Gemma | Open-weight model family | Weights you download, then run under the license on the model card | You | Your own GPUs and staff time |
Read the table as four different contracts rather than four versions of one product. For example, a $20 agent plan and a $2 token price only become comparable once you convert both into the cost of one finished task. Readers comparing assistants can also see Manus versus ChatGPT and Claude.
The category map also explains why vendor demos rarely settle the question. Each demo shows its own class at its best, so an agent demo looks effortless and a model benchmark looks precise.
Manus AI: A Delegated Agent for Multi-Step Work
Manus is built for handing off a whole task, not a single question. You give it an objective, and it works through the steps in its own cloud workspace until it has something to hand back.
For a primer on the product itself, start with what Manus AI is. This section focuses instead on how it behaves inside a business, where the questions are cost, control and approvals.
What Manus Does in Practice
A typical request reads like a brief to a junior analyst. For example, you might ask Manus to find the ten largest logistics software vendors in Europe and compare their prices. Manus then breaks that into steps, browses, runs code where needed and returns the finished file.
The Manus pricing page now promotes Manus 2.0. Its documentation describes connectors, including MCP connectors, that let the agent reach other tools. That reach makes Manus useful, but it also makes governance harder.
According to the Manus help center, Pro starts at $20 a month with 4,000 credits. A second Pro tier starts at $40 a month with 8,000 credits and a 7-day trial, while Team starts at $20 per seat a month with SSO. Annual billing also takes 17% off.
Where Manus Gets Complicated
Credits are the first complication. One plan can cover many short tasks or a few long ones. A task that browses twenty sites burns more than one that edits a file, so usage varies widely. Budget owners therefore need a few weeks of real usage before the monthly number means much.
Approvals are the second. When an agent acts on external sites, such as submitting a form, someone has to decide which actions need a human click first. Credentials are the third, since every connector you authorize is a door the agent can open.
On the vendor side, the Manus security page lists SOC 2 Type 1 and Type 2, ISO 27001:2022 and ISO 27701:2019. Those certificates describe the vendor’s controls. Your own controls, such as which data you allow into a task, still sit with you.
Teams weighing Manus against other computer-use agents can read our desktop agent comparison.
Genspark: An AI Workspace for Research and Deliverables
Genspark is closer to a research desk than a general-purpose agent. Most work starts with a question and ends with a document, a slide deck or a spreadsheet that someone will present.
Think of a strategy team that needs a market overview by Friday. In Genspark, an analyst can research the topic, turn the findings into AI Slides and push the numbers into AI Sheets without leaving the workspace. The product line also includes AI Docs and Genspark Code.
Where Genspark Fits
Genspark fits jobs where the output is a deliverable that a person will read. Research summaries, briefing decks, first-draft reports and comparison sheets are the natural cases.
The plans scale by credits and seats. The Genspark membership plans page lists Free at 100 credits a day and Plus at $24.99 a month, or $19.99 billed annually, with 10,000 credits. Pro costs $249.99 a month, or $199.99 annually, with 125,000 credits. Team costs $40 per seat a month, or $35 annually, while Enterprise is custom.
Limitations and Enterprise Controls
The enterprise controls are where Genspark separates its plans. Its Team and Enterprise page says those plans are opted out of model training and that data is encrypted at rest and in transit. Admins also choose which connectors the workspace may use.
The same page says the SOC 2 Type II and ISO 27001 badges are public on Genspark’s Trust Center. The SOC 2 report itself is available under NDA. It mentions SAML SSO and SCIM provisioning without tying them to a plan. Configurable data residency in the US, EU or Japan and a custom DPA, by contrast, come only with Enterprise. A regulated buyer should therefore treat residency as a contract item, not a toggle.
Genspark is also a workspace rather than a BI or data platform. Metric definitions, row-level security and audited dashboards still belong in your data stack, so the workspace should consume governed data instead of replacing it.
Before you roll out either agent product, check whether your data, processes and owners are ready for autonomous work. A short readiness review now saves a stalled rollout later.
Checklist
Agentic AI Readiness Checklist
Check your data, processes, owners and controls before you hand real work to an agent product.
Get the Checklist →Gemma: Google’s Open-Weight Models for Private Deployment
Gemma is the option for teams that want the model inside their own walls. You download the weights, run them on hardware you control and decide exactly where every prompt and output goes.
Google ships Gemma in several sizes and lists each release in the Gemma release notes. Before you plan a deployment, read the model card for the exact size you intend to run. It states the license terms, the context length and the input types, and those details decide whether that size fits your use case.
Open weights are the reason regulated teams look at Gemma first. For instance, a hospital network or an insurer can keep patient or policy data on its own servers. That removes a third-party processor from the data path. Our guides to private LLMs and sovereign AI cover the wider pattern.
Gemma Sizes, Precision and the Hardware They Need
Each Gemma size trades capability for hardware. The smallest variants suit phones and laptops, while the largest need a serious GPU.
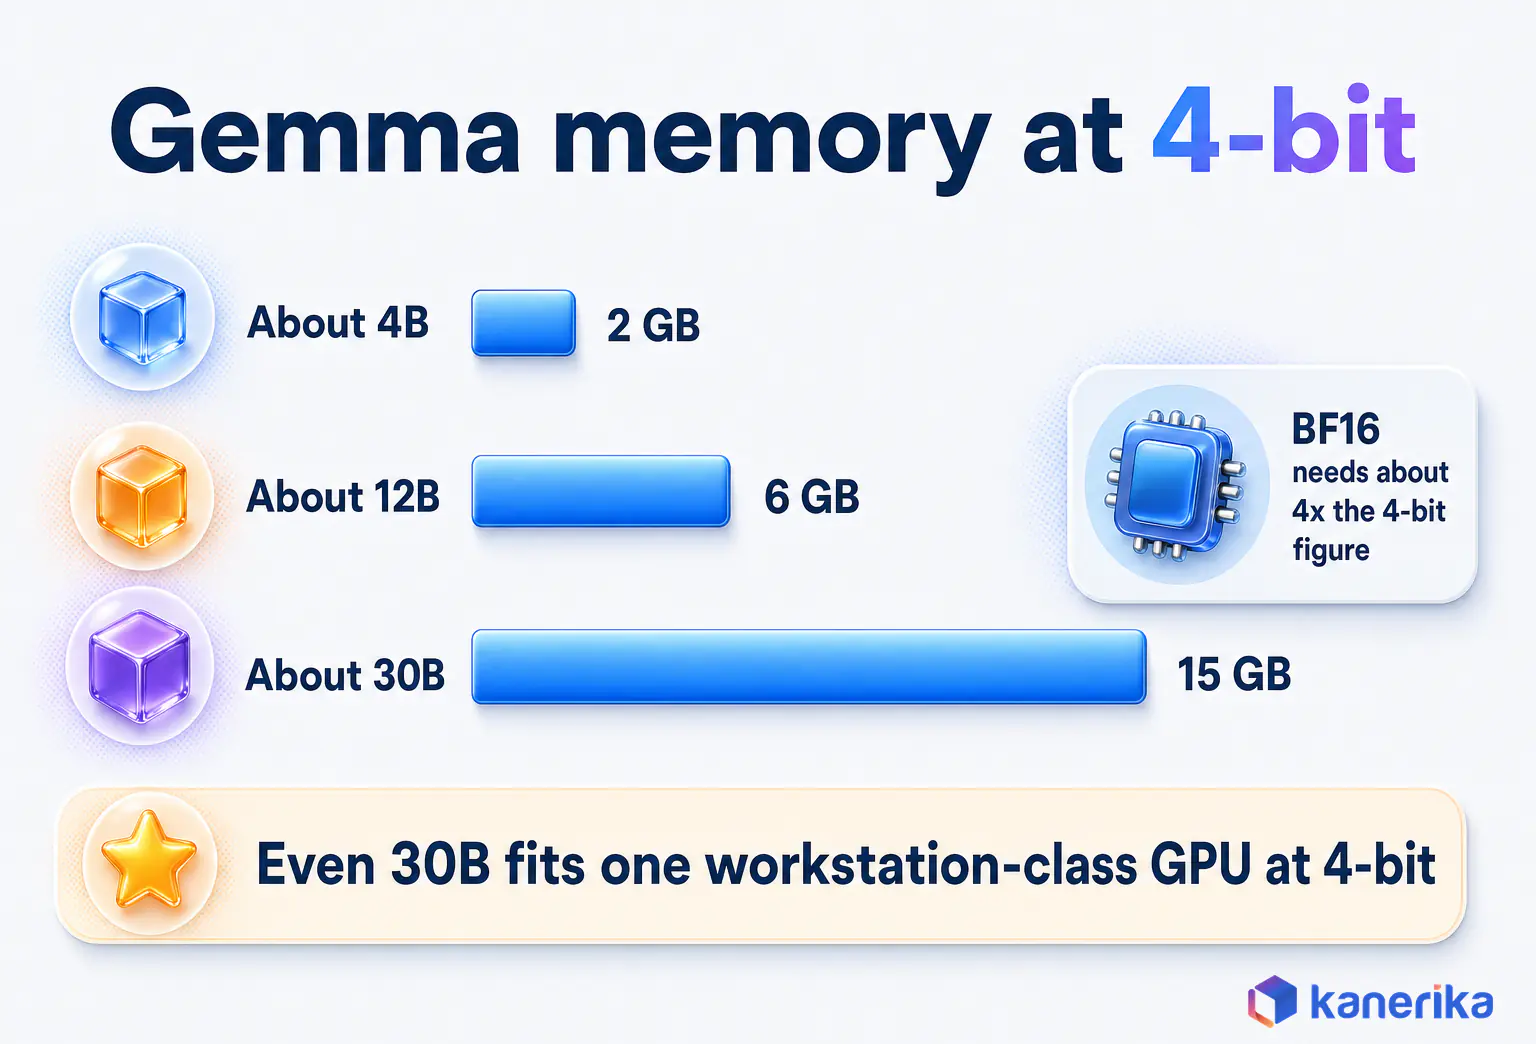
Memory depends mostly on precision. A useful rule of thumb is two bytes per parameter at BF16, one byte at 8-bit and half a byte at 4-bit. The context cache and runtime overhead come on top. Google’s Gemma core documentation gives approximate figures per size, though it notes that real use varies by tool.
| Model size (parameters) | BF16 weights | 8-bit weights | 4-bit weights | Typical hardware at 4-bit |
|---|---|---|---|---|
| About 4B | About 8 GB | About 4 GB | About 2 GB | Laptop or phone |
| About 12B | About 24 GB | About 12 GB | About 6 GB | Consumer GPU |
| About 30B | About 60 GB | About 30 GB | About 15 GB | One workstation-class GPU |
In practice, 4-bit quantization brings even a 30B-parameter model down to roughly 15 GB of weights. That puts a private deployment within reach of a single workstation-class GPU, which changes the cost conversation for a pilot. Plan extra headroom for long prompts, since the context cache grows with every token you keep in memory.
What Gemma Cannot Do for You
Gemma gives you weights, not a service. You own security patching, access control, logging, scaling and evaluation, as well as the people who run them. There is no built-in agent, so any multi-step behavior is something your team builds around the model.
That trade suits teams with platform engineers and a clear reason to keep data in-house. It suits a five-person marketing team far less. For the build-versus-buy view, see our pieces on open-source LLMs and small language models.
Gemini 4 Argon and Gemini 3.8 Flash: Google’s Hosted Models
Gemini is the option for teams that want Google’s strongest models without running any hardware. You send a request to Google’s API or use Gemini inside Google’s apps, and then you pay for what you use.
Two models matter for this comparison as of November 2026. Gemini 4 Argon is the newer of the two, and its model card is dated October 13, 2026, without a GA or Preview label. Gemini 3.8 Flash is the lower-cost option, priced at well under half of Argon per token. Our guide to Google Gemini AI covers the full family.
What Gemini Does Well
Long context is Argon’s headline strength. It handles up to 1M tokens of context, with input and output combined. That is enough to read a full contract archive or a large codebase in one request.
Input types are the second thing to check. Google lists the accepted inputs on Argon’s model card, so confirm your file types there before you design a workflow around multimodal models. A claims team, for example, may want to send a scanned form and a photo of the damage in the same request.
Individuals can also reach Gemini through the Google AI Pro plan at $19.99 a month. Teams choosing between chat assistants can compare ChatGPT vs Gemini vs Claude.
Pricing Reality
Gemini’s API prices are low in November 2026, but both models are already scheduled to rise. Anyone budgeting for 2027 should therefore plan on the later numbers.
- Gemini 4 Argon costs $2 per million input tokens and $10 per million output tokens through November 30, 2026.
- From December 1, 2026, Argon costs $4 per million input tokens and $20 per million output tokens.
- Gemini 3.8 Flash costs $0.75 per million input tokens and $3.75 per million output tokens through December 31, 2026.
- After that date, Flash costs $1.50 per million input tokens and $7.50 per million output tokens.
Both changes double the per-token rate. So a workload that looks cheap on a November invoice will cost twice as much by January, even if usage stays flat.
Where Gemini Falls Short
Lock-in is the first limit. Prompts, tooling and evaluation sets tuned to Gemini take work to move, and the price changes above show that the vendor sets the terms.
Agreement scope is the second, and it matters most for healthcare. Google’s HIPAA compliance page lists Gemini Enterprise and Gemini Enterprise Agent Platform among the products its BAA covers. Google AI Studio is not on that list, so a prototype built there should not touch patient data.
The third limit is uncertainty about what comes next. Google announced Gemini 4 Carbon in October 2026 with no price, model ID or availability date, so it cannot be planned around yet.
Teams that want hosted and private models side by side need one deployment plan that covers both. That plan decides which data each model may see before any code ships.
Kanerika Service
LLM Development and Private Model Deployment
Kanerika deploys and evaluates open-weight and hosted language models in your environment, under the right controls.
Explore LLM DevelopmentManus AI vs Genspark vs Gemma vs Gemini: Head-to-Head Comparison
A side-by-side view helps once you accept that the four tools are different classes. The tables below compare what each one does, how each handles compliance and how each one bills.
Core Capabilities
Capabilities split along the agent-versus-model line. Agents act, while models answer, so the first row is where the classes separate most clearly.
| Capability | Manus AI | Genspark | Gemma | Gemini 4 Argon |
|---|---|---|---|---|
| Executes multi-step tasks | Yes, delegated | Yes, inside the workspace | Only if you build it | When your app or a Google tool calls it |
| Research deliverables | Yes | Yes, such as slides, sheets and docs | Only if you build it | Only if your app adds it |
| Context window | Less relevant, since you buy tasks | Less relevant, since you buy tasks | Varies by size, so check the model card | 1M tokens |
| Runs offline | No | No | Yes | No |
| Input types | Web and files, as well as connectors | Web and files, as well as connectors | Text; check the model card for each size | As listed on Google’s model card |
The capability rows already hint at a build-versus-buy split. If they point you toward running models in your own environment, the next questions are architecture, hosting and evaluation.
Talk to Kanerika
Choosing Between Agents and Models?
Talk to Kanerika about routing each workflow by data sensitivity and proving the choice with a pilot.
Contact Us →Compliance and Security
Compliance depends on who runs the stack. With Manus, Genspark and Gemini, you rely on the vendor’s certificates and contract. With Gemma, the controls are whatever your own environment holds.
| Control | Manus AI | Genspark | Gemma | Gemini |
|---|---|---|---|---|
| Certifications | SOC 2 Type 1 and Type 2, ISO 27001:2022, ISO 27701:2019 | SOC 2 Type II, ISO 27001 badges (report under NDA) | Yours | Check the specific product |
| Training on your data | Check terms before you upload data | Team and Enterprise opted out | Stays with you unless you move it | Depends on the product, so check the tier |
| Identity | SSO on Team | SAML SSO and SCIM supported, so confirm the plan | Yours | Varies, since it depends on the product |
| HIPAA path | Review the contract before use | Review the contract before use | Your environment | BAA covers Gemini Enterprise, but not AI Studio |
| Data residency | Review the contract before use | Enterprise only: US, EU or Japan | Wherever you deploy | Set in the contract, so check per product |
Certificates and agreements describe the vendor’s controls. What an agent does inside your own compliance workflow is a separate question, and that is where most of the review effort goes.
Kanerika’s video below shows one answer in practice. It covers a custom AI agent built for compliance vetting, which gathers records and drafts cited reports for analysts to check.
Cost Structure
The cost rows show why a direct price comparison misleads. Each tool charges for a different unit, so the cheapest entry price says little about the cheapest finished task.
| Item | Manus AI | Genspark | Gemma | Gemini |
|---|---|---|---|---|
| Entry price | Pro from $20 a month | Free, or Plus at $24.99 a month | $0 license | Argon $2 / $10 per 1M tokens |
| Team price | From $20 per seat a month | $40 per seat a month | Staff and GPUs | Usage-based, so it scales with tokens |
| Billing unit | Credits | Credits | Hardware hours | Tokens |
| Discounts and changes | 17% off annual billing | Lower rates when billed annually | None, since the license is free | Argon doubles December 1, 2026 |
Tables like these narrow the field to two or three candidates. Still, only a pilot on your own tasks, with pass bars set in advance, settles which one earns the budget.
Talk to Kanerika
Planning a Three-Task AI Pilot?
Kanerika helps you pick the tasks, set the pass bars and measure cost per completed task.
Schedule a Demo →What a Task Really Costs: Credits vs Tokens vs GPUs
The fairest way to compare these tools is to price one finished task in each. A plan price or a token rate on its own tells you very little.
Start with a simple, document-heavy job. Say your team processes 1,000 documents a month, and each one needs 20,000 input tokens and 2,000 output tokens. That totals 20 million input tokens and 2 million output tokens a month.
On Gemini 4 Argon, that workload costs $60 a month through November, then $120 from December 1, 2026. On Gemini 3.8 Flash, it costs $22.50 a month, rising to $45 from January 1, 2027. Per document, Argon moves from six cents to twelve cents.
At scale, a pipeline that reads 1 billion input tokens a day for 30 days runs about $22,500 a month on Flash before January 1, 2027. On Argon, the same input volume costs about $60,000 in November and $120,000 from December 1.
| Workload | Gemini 3.8 Flash | Gemini 4 Argon | Assumption |
|---|---|---|---|
| 1,000 documents a month (20M in, 2M out) | $22.50, then $45 from January 1, 2027 | $60, then $120 from December 1, 2026 | List prices, before caching or discounts |
| 1B input tokens a day for 30 days | About $22,500 a month | About $60,000, then $120,000 | Input tokens only |
Agent Plans and Open Weights
Agent plans need a different calculation. On Manus Pro, $20 for 4,000 credits works out to half a cent per credit. On Genspark Plus, $24.99 for 10,000 credits is about a quarter of a cent per credit. Even so, the unknown is how many credits your task burns, and only a pilot answers that.
Gemma moves the cost into hardware and people. Its license is free, but GPU hours, monitoring and the engineers who maintain the stack are not. Since most Gemma budgets go to serving rather than training, the split between inference versus training costs matters here.
So never put a $20 plan beside a per-token rate and call it a comparison. Convert both into the cost of one completed task first.
Manus AI vs Genspark vs Gemma vs Gemini: How to Choose for Each Job
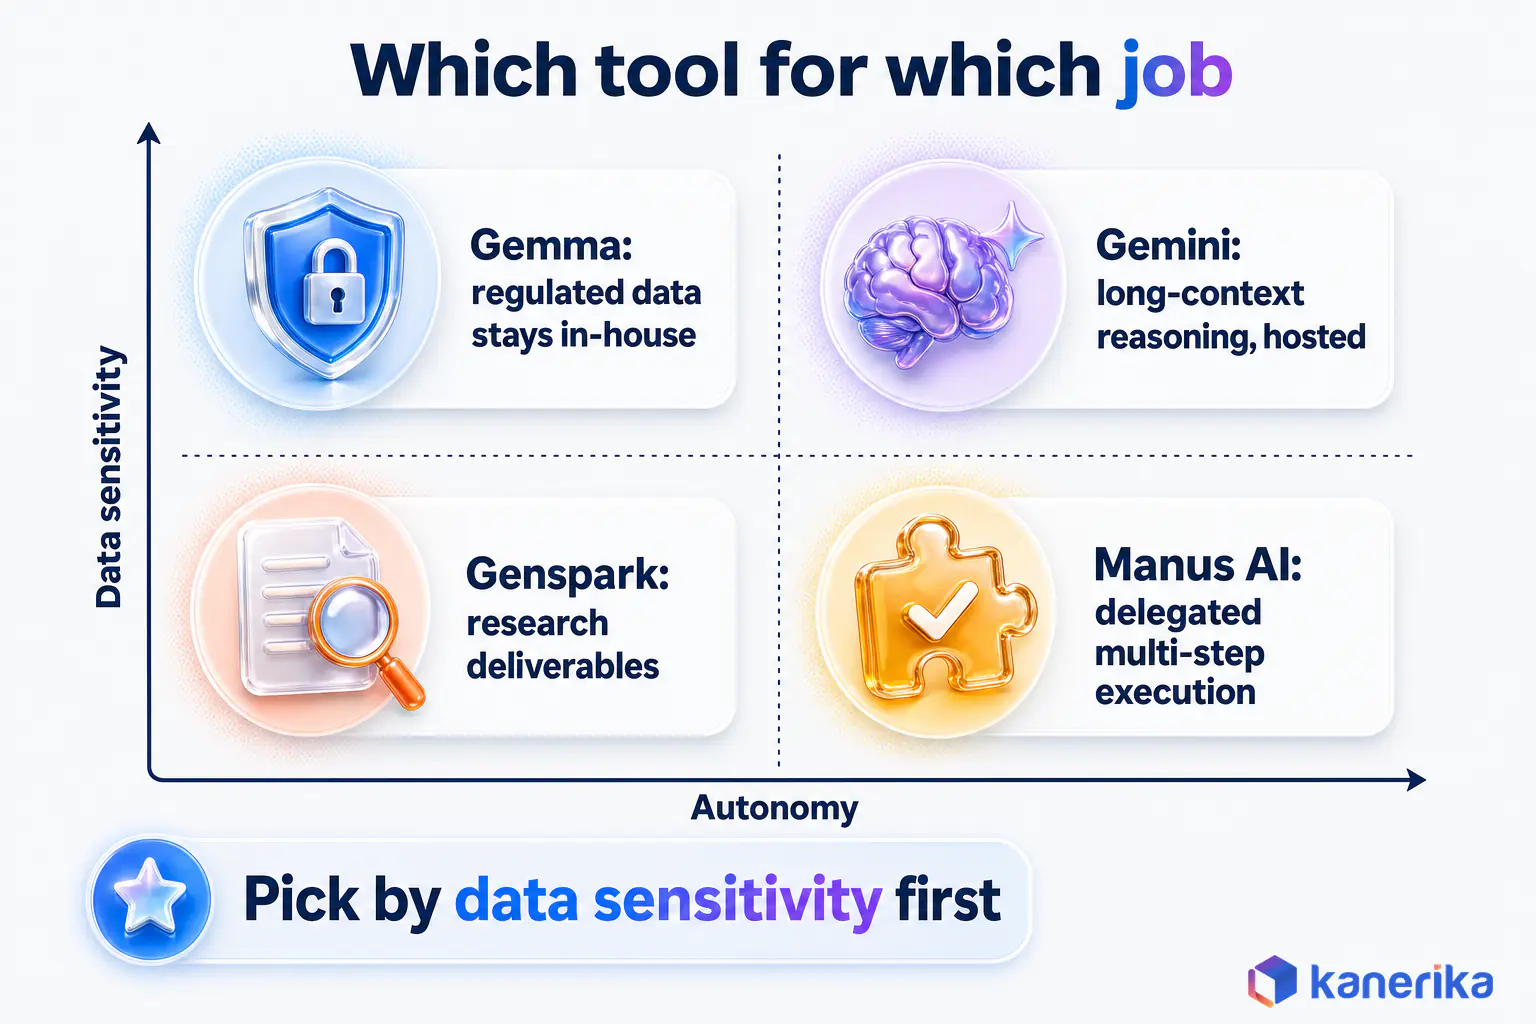
The right choice depends on the job, not on which tool scores highest overall. Four questions settle most cases. How sensitive is the data, how much autonomy does the task need, what unit will you pay in, and who will operate the tool?
Choose Manus When the Work Is Delegated Execution
Pick Manus when you want to hand off a multi-step task and get a finished output back. Vendor research, list building and multi-site data gathering are good fits.
Keep the data low-risk and the approvals tight. Manus works best on public or internal-but-not-regulated inputs, with a person approving any action on an external site.
Choose Genspark When the Output Is a Research Deliverable
Pick Genspark when the end product is a deck, a sheet or a document that a person will read. Strategy, sales enablement and marketing teams get the most from it.
Use the Team or Enterprise plan for company work, since those plans are opted out of model training. If you need data residency, raise it with Enterprise sales before rollout.
Choose Gemma When the Data Cannot Leave Your Environment
Pick Gemma when regulated or confidential data must stay on infrastructure you control. Healthcare records, financial data and internal legal documents are the usual cases.
Gemma also suits high-volume, narrow tasks where per-token API costs would add up. It needs engineers who can run, patch and evaluate a model, so staff the project before you buy the GPUs.
Choose Gemini When You Need Hosted Long-Context Reasoning
Pick Gemini 4 Argon when a task needs heavy reasoning across very long inputs, such as a full contract archive. Pick Gemini 3.8 Flash instead when speed and cost matter more than peak reasoning.
For regulated data, use a product covered by Google’s agreement, such as Gemini Enterprise. Then budget on the December 2026 and January 2027 prices.
| Factor | Manus AI | Genspark | Gemma | Gemini 4 Argon |
|---|---|---|---|---|
| Data sensitivity | Low to moderate | Low to moderate, especially on Team or Enterprise | High, regulated | Higher, once the right agreement is in place |
| Autonomy | High, delegated | Medium, workspace | Only if you build it | Only if you build it |
| Cost unit | Credits | Credits or seats | GPUs and staff | Tokens |
| Who operates it | Manus | Genspark | Your team | Google, while your team runs the app |
| Best first job | Multi-site research and data gathering | Briefing decks and reports | Private document processing | Long-context analysis |
Many teams end up with two of the four, not one. A common pairing is Genspark for the research desk and Gemma or Gemini for the applications IT builds. If Manus is close but not right, our list of Manus AI alternatives covers other agent options in the same class.
Security, Privacy and Governance Checklist
Every one of these tools touches company data, so the security review should come before the pilot, not after it. The checklist below works for all four, though the answers will differ by class.
The NIST AI Risk Management Framework is a useful anchor. It is voluntary, and on April 7, 2026, NIST published a concept note for a critical-infrastructure profile. For agent-specific risks, see our guide to agentic AI security.
Eight Checks to Run on Every Tool
- Retention and deletion: find out how long prompts and outputs are kept, and how to delete them on request.
- Data residency: confirm where data is stored and processed, then get it in the contract if it matters.
- Encryption: check encryption at rest and in transit, as well as who holds the keys.
- SSO and role-based access: tie every seat to your identity provider and limit who can use which connector.
- Audit logs: make sure you can see who ran what, with which data, and when.
- Connector permissions: grant the narrowest scope each connector needs, then review the list every quarter.
- Human approval for external actions: require a person to approve anything an agent sends, submits or buys.
- HIPAA and GDPR scope: confirm which product and tier sit under your BAA or data processing agreement.
Point eight trips up more teams than any other. A vendor can hold every certificate on the list while the specific product you use sits outside the agreement. Our AI governance framework and our guide to HIPAA-compliant software development go deeper on both sides.
Write the answers down per tool and keep them with the pilot results. When procurement or audit asks why a tool was approved, that record is the answer.
Checklist
AI Governance Checklist
Work through retention, residency, access, logging and human approval before any tool touches company data.
Get the Checklist →Run a Same-Three-Tasks Pilot Before You Commit
The fastest way to choose is to give each shortlisted tool the same three real tasks and score the results. A two-week pilot on your own work beats any amount of reading vendor pages.
Pick tasks that represent your actual demand. For example, choose one research brief, one document-processing job and one multi-step workflow that touches another system. Then run each through every tool on the shortlist, with the same inputs and the same reviewer.
| Task | What to measure | Pass bar to set before you start |
|---|---|---|
| Research brief | Accuracy of facts and sources | Every source checks out when verified |
| Document processing | Extraction accuracy and cost per document | Errors and cost stay below the agreed limit |
| Multi-step workflow | Completion without a human rescue | Finishes while approvals stay in place |
| All three | Cost per completed task | Lower than doing it by hand |
Set the pass bars before anyone sees a result. Otherwise, the most impressive demo tends to win, even when it fails the task that matters.
Benchmarks vs Your Own Pilot
Public benchmarks measure different things for models and agents. Model benchmarks test reasoning or coding on fixed questions, while agent benchmarks test whether a system finishes a task end to end.
Open-weight model cards, Gemma’s included, report scores on fixed academic benchmarks such as coding and math tests. Those numbers help compare models with each other, yet none of them tells you how a tool handles your invoices. Our AI agent evaluation guide and LLM evaluation framework show how to build your own test set.
Four Deployment Mistakes That Sink Pilots
- Comparing plan prices instead of cost per completed task, which hides the real bill.
- Testing on demo data, so the pilot passes and production fails on messy inputs.
- Skipping approvals on external actions, then pausing the pilot after the first wrong email.
- Using an agent where a deterministic script would do, when RPA tools already handle stable, rule-based steps well.
A pilot that dodges all four produces numbers you can take to a budget meeting.
How Kanerika Combines Agents, Hosted Models and Open Models in Regulated Industries
Regulated clients rarely need one of these four tools. Instead, they need a rule for which work goes where, so Kanerika starts every engagement by sorting workflows before choosing any product.
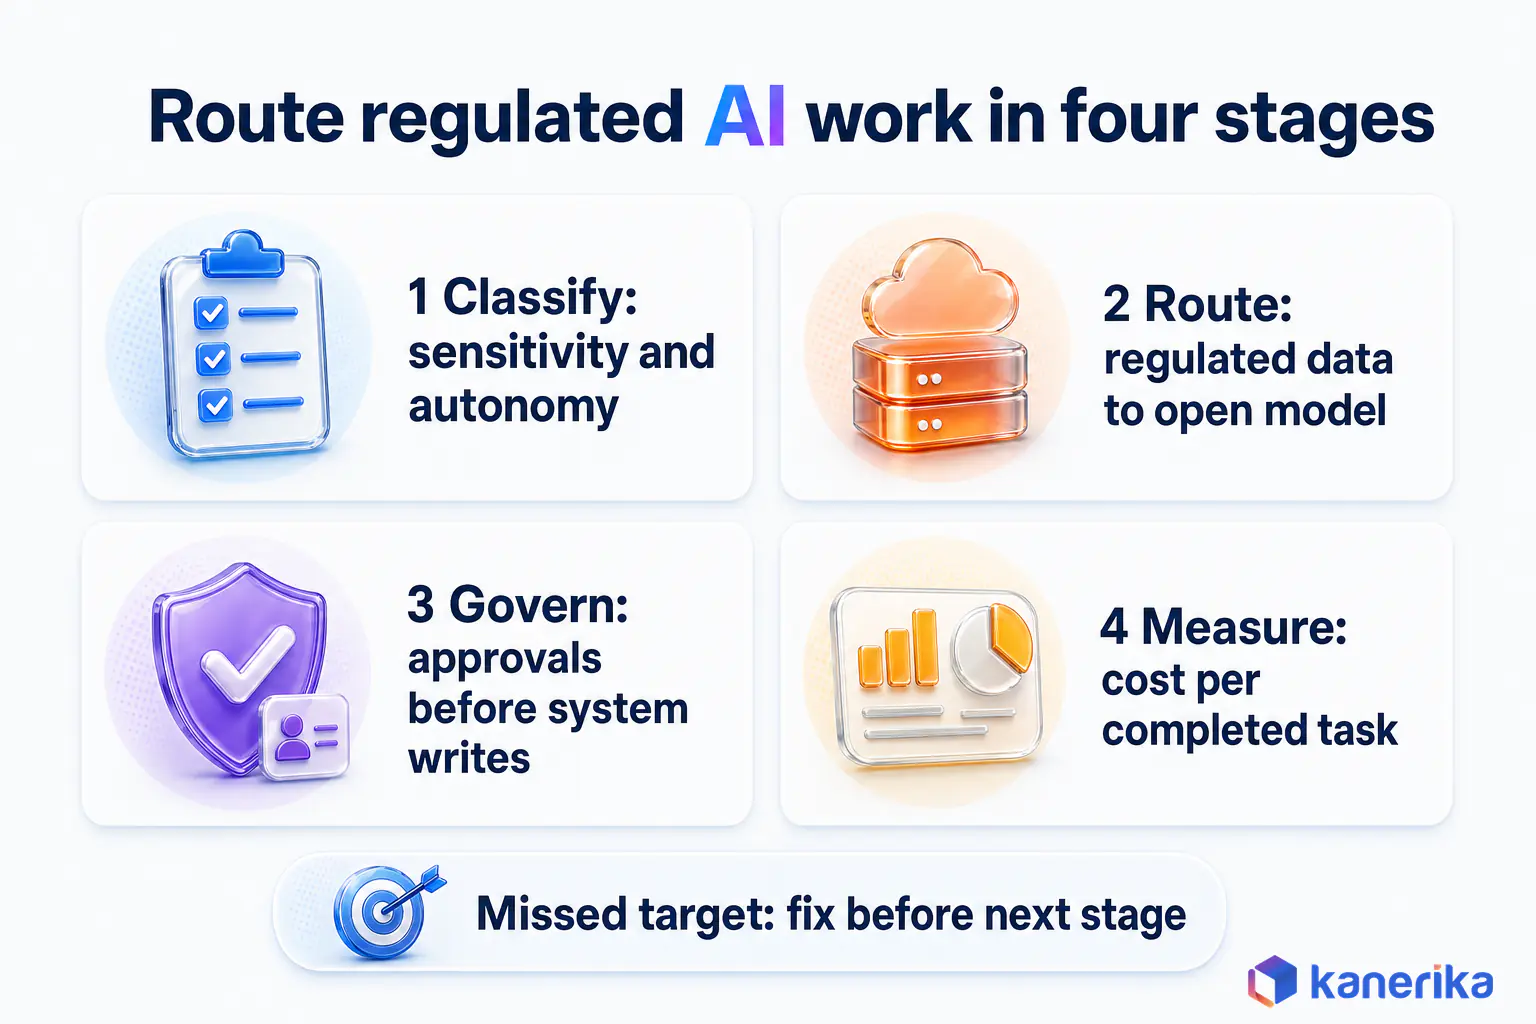
The method has four stages. First, classify each workflow by data sensitivity and the autonomy it needs.
Second, route each workflow to its tool. Regulated data goes to an open model such as Gemma inside the client’s environment. Heavy reasoning on public data goes to a hosted model under the right agreement, while research gathering goes to an agent. Third, add approvals, logging and evaluation before anything writes to a system of record.
Fourth, measure cost per completed task every month, so the routing rule stays honest as prices change. A stage that misses its target gets fixed before the next one starts.
Each stage maps to a practice area. Agent builds run through Kanerika’s agentic AI services, alongside FLIP, Kanerika’s automation platform. Private model deployment runs through LLM development services, while the controls come from AI governance services.
The classify step usually surprises clients. Workflows that felt sensitive often turn out to use public data, while a few that felt routine carry personal records. That inventory alone tends to change the shortlist.
The routing rule is written down rather than left to habit. Each workflow gets an owner, a data class, an approved tool and a monthly cost-per-task target. When a vendor changes a price or a plan, the team then rechecks only the workflows that tool serves.
Case Study: 3x Faster Expert Vetting with an AI Compliance Agent
A global expert network faced backlogs because negative news screening of experts was manual. Analysts spent their time gathering records instead of judging them.
Kanerika built an AI compliance agent that gathers vetting data, searches news and professional records, and produces cited reports mapped to compliance rules. As a result, analysts review the findings instead of researching from scratch.
Expert vetting became 3x faster, and backlog cases fell by 70%. Event delays dropped by 40%, while negative news screening time fell by 60%. The full story is in the AI compliance agent case study.
For a team weighing the four tools in this guide, the lesson is about design before vendor. Decide who gathers, who decides and what gets logged, and then the tool choice gets much easier to defend.
The pattern carries over to most regulated research work. An agent gathers and drafts, a person decides, and every step leaves a record. For document-heavy compliance, the Klara document intelligence and compliance agent datasheet shows a related approach.
Case Study
3x Faster Expert Vetting with an AI Compliance Agent
A global expert network replaced manual negative news screening with an AI compliance agent, cutting backlog cases by 70% and screening time by 60%.
Read the Case Study →Wrapping Up
These four tools answer different questions. Manus delegates execution, Genspark produces research deliverables, Gemma keeps data in your environment and Gemini supplies hosted reasoning at scale.
Pick by data sensitivity first, autonomy second and cost per completed task third. Then prove the pick with a same-three-tasks pilot before you sign anything annual.
What to Watch Next
Two price dates and one announcement will shape this comparison over the next few months. Track them alongside other recent AI developments.
- Gemini 4 Argon’s price rises to $4 and $20 per million tokens on December 1, 2026.
- Flash moves to $1.50 and $7.50 per million tokens after December 31, 2026.
- Google announced Gemini 4 Carbon in October 2026, but it has no price, model ID or availability date yet.
So, Manus AI vs Genspark vs Gemma vs Gemini comes down to one question per job. Who should do the work, and where should the data live? A workflow that gathers public facts can go to an agent, while patient records stay on Gemma or a covered Gemini product. Answer that for each workflow, and the right tool usually picks itself.
Frequently Asked Questions
What Is the Difference Between Gemma and Gemini?
Gemma is Google’s family of open-weight models that you download and run on your own hardware. Gemini is Google’s hosted model family that you reach through the Gemini API, Google AI Studio or Google Cloud. Gemma gives you control of the weights and the data path. Gemini gives you larger hosted models without running GPUs.
Can I Use Gemma and Gemini Together in the Same Architecture?
Yes. A common pattern sends regulated or confidential data to Gemma inside your own environment. Public or low-risk work goes to Gemini through a governed cloud account. A routing layer decides which path each request takes. The design adds operational work, so plan monitoring, logging and access control for both paths from the start.
Does Fine-tuning Gemma Require a Large Dataset?
Not always. Parameter-efficient methods such as LoRA can adapt a model with a few thousand high-quality examples for narrow tasks like classification or extraction. Retrieval often solves knowledge gaps without any fine-tuning. Start with retrieval and prompt design, measure the gap, and fine-tune only when the evaluation set shows it is needed.
How Should I Think About RPA Alongside These AI Tools?
RPA still fits stable, rule-based steps in systems with predictable screens. Agents such as Manus fit tasks that need judgment, research or changing paths. Many teams pair them, with RPA running deterministic steps and an agent or model handling the unstructured part. Keep human approval on any step that writes to a system of record.
Can GenSpark Replace a Research Team?
No. Genspark can compress the gathering and first-draft stage of research, which frees analysts for judgment work. It does not replace domain expertise, source validation or accountability for conclusions. Treat its output as a draft with citations to check, and keep a named owner for every research deliverable that reaches a client or executive.
Which Is Best for Secure, Production-Ready Enterprise AI Applications?
For applications you build and own, Gemma or Gemini is the usual base. Gemma suits data that must stay in your environment. Gemini suits hosted workloads under the right agreement, such as Gemini Enterprise. Manus and Genspark fit knowledge-worker productivity more than embedded applications. Data sensitivity and who operates the stack decide it.
What Is the Difference Between Manus AI and Genspark?
Manus is a delegated agent. You hand it an objective and it plans, browses, runs code and returns a finished output from its own cloud workspace. Genspark is an AI workspace built around research and deliverables such as slides, sheets and documents, with agents and connectors inside it. Manus suits execution, Genspark suits research output.
Are Manus AI, Genspark, Gemma and Gemini Direct Competitors?
Only partly. Manus and Genspark are agent products you subscribe to. Gemini is a hosted model family you call or use through Google apps. Gemma is a set of open-weight models you deploy yourself. They overlap on some tasks, but each one is a different purchase with a different cost, risk and ownership model.
Can Gemma Run Locally Without an Internet Connection?
Yes. Once you download the Gemma weights, the model runs offline on hardware you control, with no calls to Google. Memory is the main limit. As a rule of thumb, weights need about half a byte per parameter at 4-bit, so a 12B-parameter model needs roughly 6 GB before overhead. Smaller sizes fit laptops.
Is GenSpark Suitable for Internal Business Intelligence?
For light internal research, it can help. Genspark gives admins control over connectors on its Team and Enterprise plans. Those plans are also opted out of model training. Genspark is still a workspace, not a governed BI platform. Metric definitions, row-level security and audited dashboards belong in your BI and data stack.
How Does Manus AI Handle Compliance Requirements?
Manus lists SOC 2 Type 1 and Type 2, ISO 27001:2022 and ISO 27701:2019 on its security page, and its Team plan adds SSO. Certifications cover the vendor’s controls, not your use case. Regulated data still needs a contract review, data-flow mapping and human approval before an agent acts on external systems.
How Much Do Manus AI and Genspark Cost in November 2026?
As of November 2026, Manus Pro starts at $20 a month with 4,000 credits. A second Pro tier starts at $40, and Team starts at $20 per seat. Genspark Plus costs $24.99 a month, Pro costs $249.99 and Team costs $40 per seat. Credits burn at different rates per task, so price the work.
Is Gemini 4 Argon Better Than Gemma for Coding and Reasoning?
For hard reasoning over long inputs, Gemini 4 Argon usually has the edge. It handles up to 1M tokens of combined context on Google’s hosted infrastructure. Gemma wins when data cannot leave your environment, and it can cost less at high volume. Test both on your own coding and reasoning tasks before you decide.
What's the Realistic Timeline for Deploying Gemma in a Regulated Environment?
Plan in weeks, not days. A pilot on existing GPU capacity can run in two to four weeks. Production adds security review, access control, logging, evaluation sets and change management, which often takes two to three months in regulated firms. Fine-tuning and validation add more time if the use case needs them.