TL;DR
For RAG vs agentic RAG, pick standard RAG for one-source questions and agentic RAG for questions that span several systems. Standard RAG searches once and answers once, so it stays fast and cheap. Agentic RAG lets an AI agent plan, search again and check its own work. Those extra steps add cost and delay. Many teams use a router that sends easy questions to RAG and hard ones to the agent. Either way, cap the agent’s loops and keep a person in charge of any change to data.
Key Takeaways
- Standard RAG runs a fixed retrieve-then-generate path, while agentic RAG lets an agent decide what to retrieve next and when to stop.
- Agentic RAG earns its cost on multi-hop, ambiguous and cross-system questions, and adds little on single-fact lookups.
- Cost per query scales with the number of LLM calls, so loop caps and stop rules belong in the design from day one.
- A hybrid router that tries cheap RAG first and escalates on low confidence is the practical default for mixed workloads.
- Agentic retrieval widens the attack surface, so map OWASP LLM risks to controls and trace every agent step.
- Move in stages: ship standard RAG, log its failures, then add one agentic pattern for the failing slice only.
One Assistant, Two Questions, Two Very Different Answers
Picture a finance analyst testing the new internal assistant before its rollout. She asks for the refund policy, and the bot finds the policy page, quotes the right clause and cites it. So far, standard RAG did exactly what it was built to do.
Then she asks a harder one: why did supplier X’s last three invoices fail the three-way match? This time the bot returns one half-relevant paragraph from a procurement guide and a confident summary that explains nothing.
That answer lives in three places: the ERP invoice table, the purchase orders and the supplier contract. A single search cannot join them. This scenario is illustrative, though it captures the real choice between the two designs.
RAG vs Agentic RAG at a Glance
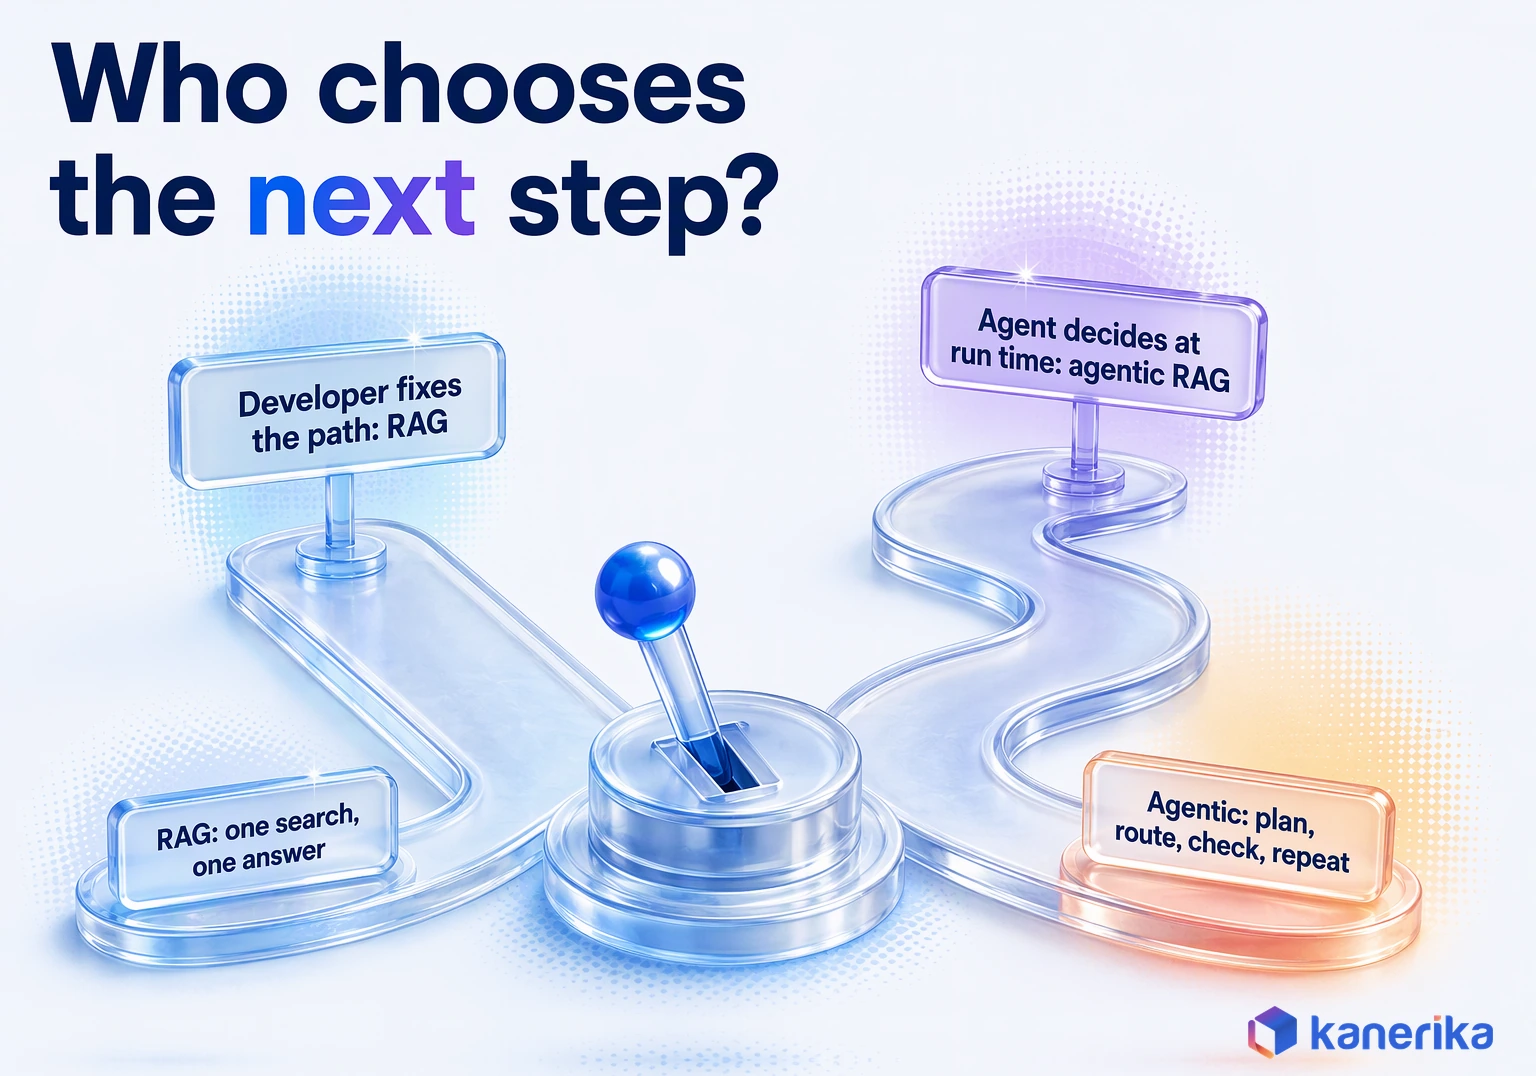
The plain-English difference comes down to who decides the path. Standard RAG follows a fixed recipe: search once, hand the results to the model, write the answer. Agentic RAG puts an LLM agent in charge of the recipe, so it can plan, choose a source, check what came back and search again.
That one design change shifts cost, speed, predictability and the governance load. The table below compares the two across the dimensions that decide real projects.
| Dimension | Standard RAG | Agentic RAG |
|---|---|---|
| Control flow | Fixed pipeline set by the developer | Agent chooses the next step at run time |
| Retrieval passes | Usually one, so it stays fast | One to many, until a stop rule fires |
| Sources | Typically one index | Several indexes, databases and APIs |
| Tool use | None beyond search | SQL, APIs, calculators, web search |
| Latency | Low and stable | Higher and variable |
| Cost per query driver | One generation call plus retrieval | Number of LLM calls and tool calls |
| Predictability | Same input, same path | Path can differ between runs |
| Debugging | Inspect one retrieval and one prompt | Trace every plan, call and check |
| Typical failure | Wrong or missing chunk, confident answer | Loops, wrong tool, runaway cost |
| Governance load | Access control on one index | Access control on every tool, plus action limits |
| Best fit | Policy Q&A, product docs, FAQs | Multi-hop research, cross-system analysis |
| Build effort (relative) | Lower, since the path is fixed | Higher, mostly in evaluation and controls |
Read the table as a trade. Agentic RAG buys reach and adaptability, and you pay for it in latency, cost and oversight. The rest of this guide shows where that trade is worth making.
Benefits and Limitations: RAG vs Agentic RAG
Each design has a short list of things it does well and a matching list of things it does badly. Seen side by side, the two lists are close to mirror images.
| Approach | Benefits | Limitations |
|---|---|---|
| Standard RAG | Fast, low cost per query, same path every time, easy to audit and replay, quick to build | Misses when the first search misses, weak on multi-hop and ambiguous questions, reaches one index, no check that the evidence answers |
| Agentic RAG | Chains lookups, reaches databases and APIs, re-searches on weak evidence, can ask back or say it found nothing | Several times the model calls, variable latency, paths differ between runs, wider attack surface, heavier testing and tracing |
Notice that every agentic benefit has a cost attached. So the useful question is never which list looks longer, but which limitation your workload can live with.
How Standard RAG Works and Where It Breaks
Standard RAG is the baseline every comparison starts from, so it helps to see its moving parts before judging its limits. The pattern was introduced by Lewis et al. in the 2020 paper Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks. It pairs a language model with a search step so answers draw on your documents instead of the model’s memory alone.
The Retrieve-Then-Generate Pipeline
The pipeline has five stages. Documents are split into chunks, each chunk is turned into an embedding, and the embeddings go into an index. At question time, the system retrieves the top-k closest chunks and passes them to the model, which writes the answer.
The k value is a real tuning knob. LlamaIndex, for example, sets similarity_top_k to 2 by default in its core constants, which suits short factual answers. Questions whose evidence spans several chunks usually need a larger k, set and tested on your own question log.
Every query takes the same path. That is the strength. You can log the retrieved chunks, replay the prompt and see exactly why an answer came out the way it did. If the real question is whether to retrain the model instead, the trade-offs differ, and our guide to RAG vs fine-tuning covers that choice.
Kanerika Service
RAG Development Services
Kanerika designs and builds retrieval-augmented generation systems with permission-aware retrieval, evaluation sets and citations, starting from the simplest design that answers your questions.
Explore RAG DevelopmentFive Places Standard RAG Fails
The fixed path is also the weakness. When the first search misses, nothing in the pipeline notices. Five failure patterns, in particular, show up again and again in enterprise deployments.
- A bad first search. The user writes “PTO carryover” and the policy says “unused leave.” The retriever misses, so the model answers from whatever it found.
- Multi-hop questions. “Which contracts signed by our largest customer expire this quarter?” needs one lookup to find the customer and a second to find the contracts.
- Ambiguous questions. “What were Q3 numbers?” could mean revenue, headcount or tickets. A fixed pipeline guesses instead of asking or exploring.
- Answers split across SQL and documents. Invoice amounts sit in a database while payment terms sit in a PDF. One vector search reaches only one of them.
- No check on relevance. Nothing verifies that the retrieved text actually answers the question, so a near miss becomes a fluent wrong answer.
Teams have patched these gaps with better chunking, hybrid search and re-ranking. Those fixes help, but they still keep the path fixed. Agentic RAG goes a step further and changes who controls the path.
What Makes RAG Agentic
RAG becomes agentic when a language model, acting as an agent, controls the retrieval loop instead of following a script. The survey by Singh et al., Agentic Retrieval-Augmented Generation: A Survey on Agentic RAG, describes this as embedding autonomous agents in the RAG pipeline. In practice, four capabilities do the work. For the full architecture, see our deep dive on agentic RAG.
Planning and Query Decomposition
To start, the agent breaks a complex question into smaller ones.
Take a request to compare churn in the two regions with the highest support volume. The agent splits it into three sub-questions. It finds support volume by region, picks the top two, then pulls churn for each. Each sub-question gets its own retrieval, and the agent then assembles the parts.
Routing Across Sources and Tools
Next, the agent decides where each sub-question should go. For instance, a number belongs in the data warehouse, a clause belongs in the contract index and a fresh event may need web search. Frameworks such as LangGraph make these routes explicit, and our comparison of LangChain vs LangGraph shows how. Standards like MCP then give the agent a uniform way to call tools, covered in our guide to MCP vs A2A.
Even so, a wrong route costs more than a slow one, since the answer then comes from the wrong system. At a leading investment bank, Kanerika paired KlarityIQ for documents with Karl for databases, and the case study reports 43% faster information retrieval.
Self-Checking and Corrective Retrieval
An agentic system also checks its own evidence before answering. Self-RAG (Asai et al., 2023) trains a model to retrieve on demand and then critique its output through self-reflection. Corrective RAG (Yan et al., 2024) grades retrieved documents and triggers a fresh search when they look weak.
In other words, both catch the near miss that a fixed pipeline lets through.
The One Test: Who Chooses the Next Step?
One test classifies any system. If the developer fixed the sequence in code, it is standard or advanced RAG, however clever each step is. If the model decides at run time whether to retrieve again, which tool to call or when to stop, it is agentic RAG.
At the simplest, a single agent can run the whole loop. Multi-agent designs split it, with one agent planning and others retrieving or checking, as described in our guide to AI agent architecture. Either way, a person can stay in the loop for judgment calls, much like AI augmentation of analyst work. This retrieval loop is also only one use of an agent, and our guide to agentic AI vs AI agents covers the wider picture.
AI Assessment
Is Your Data Ready for Agentic Retrieval?
Take Kanerika’s AI maturity assessment to see where your sources, access controls and governance stand before you add agents to your RAG stack.
Start Your AI Assessment →Agentic RAG Design Patterns Compared
Agentic RAG covers a family of patterns, and each one adds a specific capability at a specific cost. Picking a pattern is easier when you see what it adds and how many extra model calls it tends to need. The table uses relative costs, since real counts depend on your prompts and data.
| Pattern | What it adds | Extra LLM calls per query (relative) | When to use it | Source |
|---|---|---|---|---|
| ReAct | Interleaves reasoning steps with tool actions | High: one call per think-act step | Open-ended research across tools | Yao et al., 2022 |
| Router RAG | Sends each question to the right index or tool | Low: one routing call | Several sources with clear boundaries | Design pattern |
| Corrective RAG | Grades retrieval and re-searches when weak | Low to medium: a grading call, sometimes a retry | Noisy corpora with frequent misses | Yan et al., 2024 |
| Adaptive RAG | Picks no, single or multi-step retrieval by question complexity | Varies: low for simple, high for complex | Mixed traffic of easy and hard questions | Jeong et al., 2024 |
| Multi-agent RAG | Separate planner, retriever and checker agents | Highest: calls per agent per step | Long tasks that need specialist roles | Singh et al., 2025 |
| GraphRAG | Retrieves over entities and relationships, not just text chunks | Medium: graph queries plus generation | Questions about connections between entities | Design pattern |
Combining Patterns and Where GraphRAG Fits
In practice, most production systems combine two or three of these patterns. For example, a router in front, corrective checks on retrieval and a loop cap on the agent make a common stack.
GraphRAG, in particular, deserves a note of its own. Some questions are about relationships, such as which suppliers share a parent company. In that case a knowledge graph gives the agent structure that text chunks lack. Classic variants such as iterative, conversational and hybrid-search RAG are covered in our guide to advanced RAG techniques. Retrieval over images and tables has its own patterns, explained in multimodal RAG.
The graph pattern also changes how you model the data upfront. Entities and links must be extracted and kept current, which is real engineering work before the first query runs.
One Question Through Both Pipelines: A Worked Example
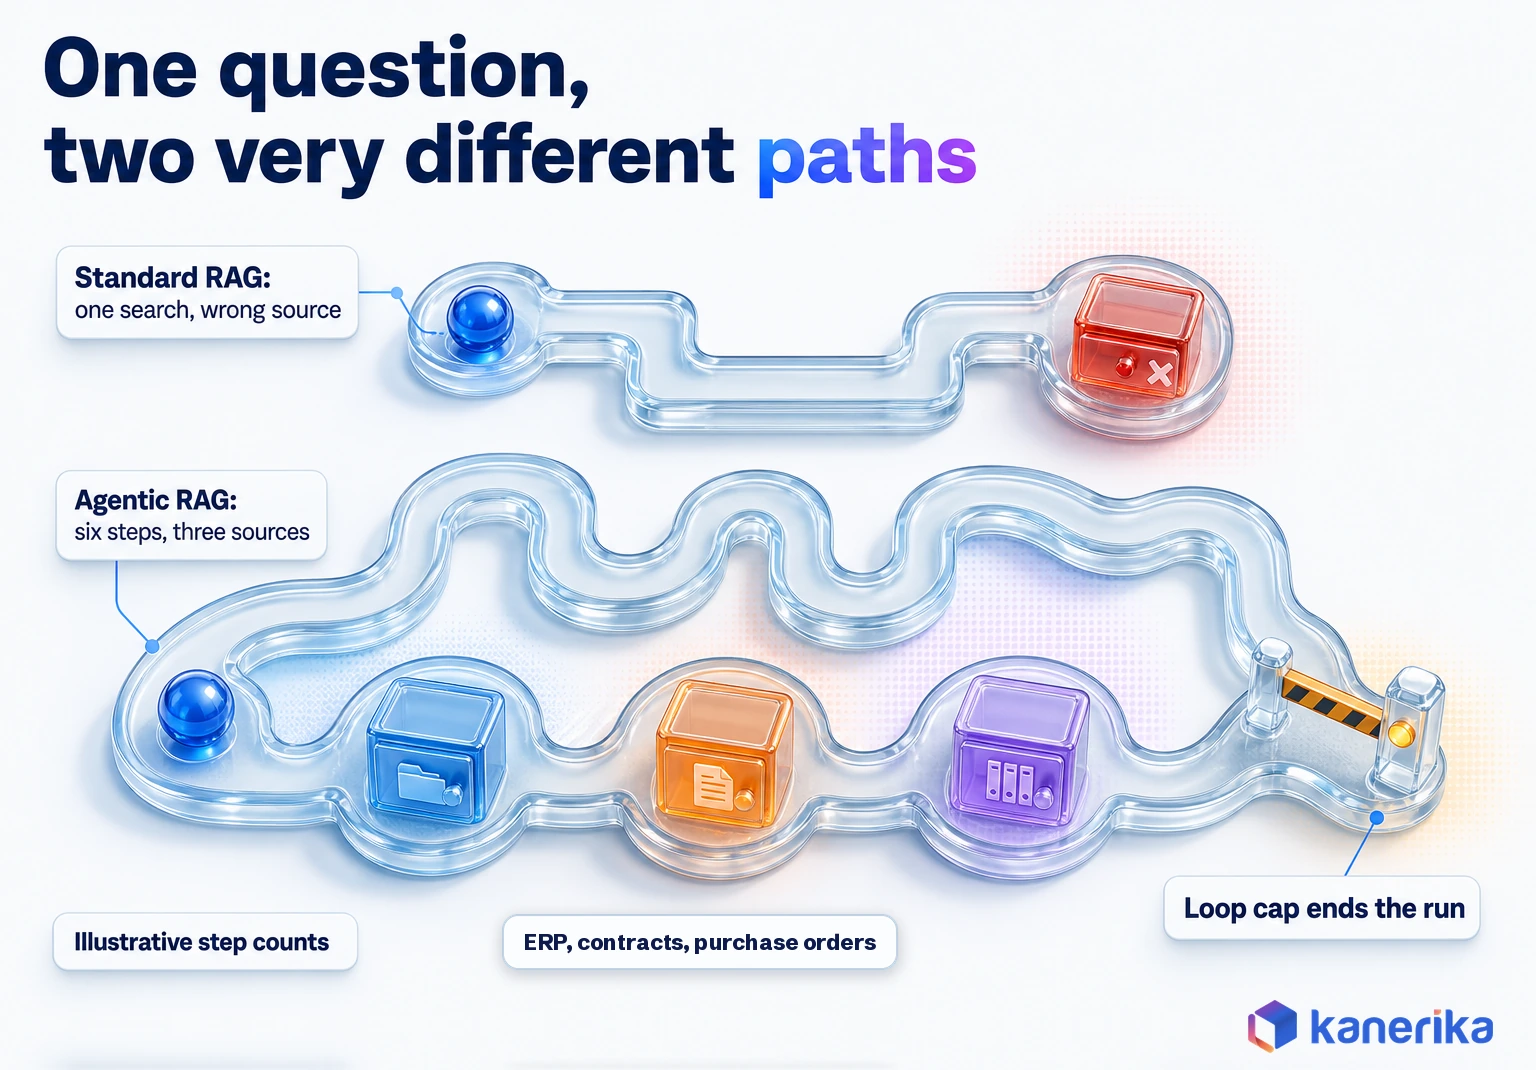
A concrete trace makes the difference easier to see than any definition. So take the supplier question from the opening and send it through both designs. The step counts below are illustrative, chosen to show the shape of each path rather than to measure a specific system.
| Step | Standard RAG path | Agentic RAG path |
|---|---|---|
| 1 | Embed the question and search the document index | Plan: split into invoice status, PO match and contract terms |
| 2 | Generate an answer from the top chunks | Query the ERP invoice table for supplier X’s last three invoices |
| 3 | Done | Search contract PDFs for the supplier’s price and quantity terms |
| 4 | Check: do the results explain the mismatch? Partly, a PO is missing | |
| 5 | Re-query purchase orders for the missing PO number | |
| 6 | Answer with citations to each invoice, PO and clause, then stop |
The standard path makes one retrieval and one generation call. It finishes fast, and it returns the half-relevant guide paragraph, because the real answer was never in the document index.
The agentic path, by comparison, makes several model calls and three tool calls. As a result, it reaches the database, the contracts and the missing purchase order. It also stops on purpose, because a loop cap ends the run if the evidence never lines up. That cap matters as much as the extra reach, since an agent without one can keep searching and billing.
The example also shows where agentic RAG adds nothing. Had the analyst asked for the refund policy, the agent would plan, route to the policy index and answer. That is the same result as standard RAG at a higher cost.
Cost, Latency and Accuracy Trade-offs
Few comparison pages put numbers to the trade, yet cost is usually the first question a budget owner asks. The good news is that the math is simple once you count model calls. Latency and accuracy also follow from the same count.
A Simple Per-Query Cost Model
Model the cost of one answered question with two terms, where the first covers language model calls and the second covers everything else the system touches.
cost per query = (LLM calls x average tokens per call x price per token)
               + retrieval calls + tool and API calls

standard RAG : LLM calls = 1
agentic RAG  : LLM calls = planning + routing + checks + final answer
               (for example, 4 to 8 for a multi-step question)
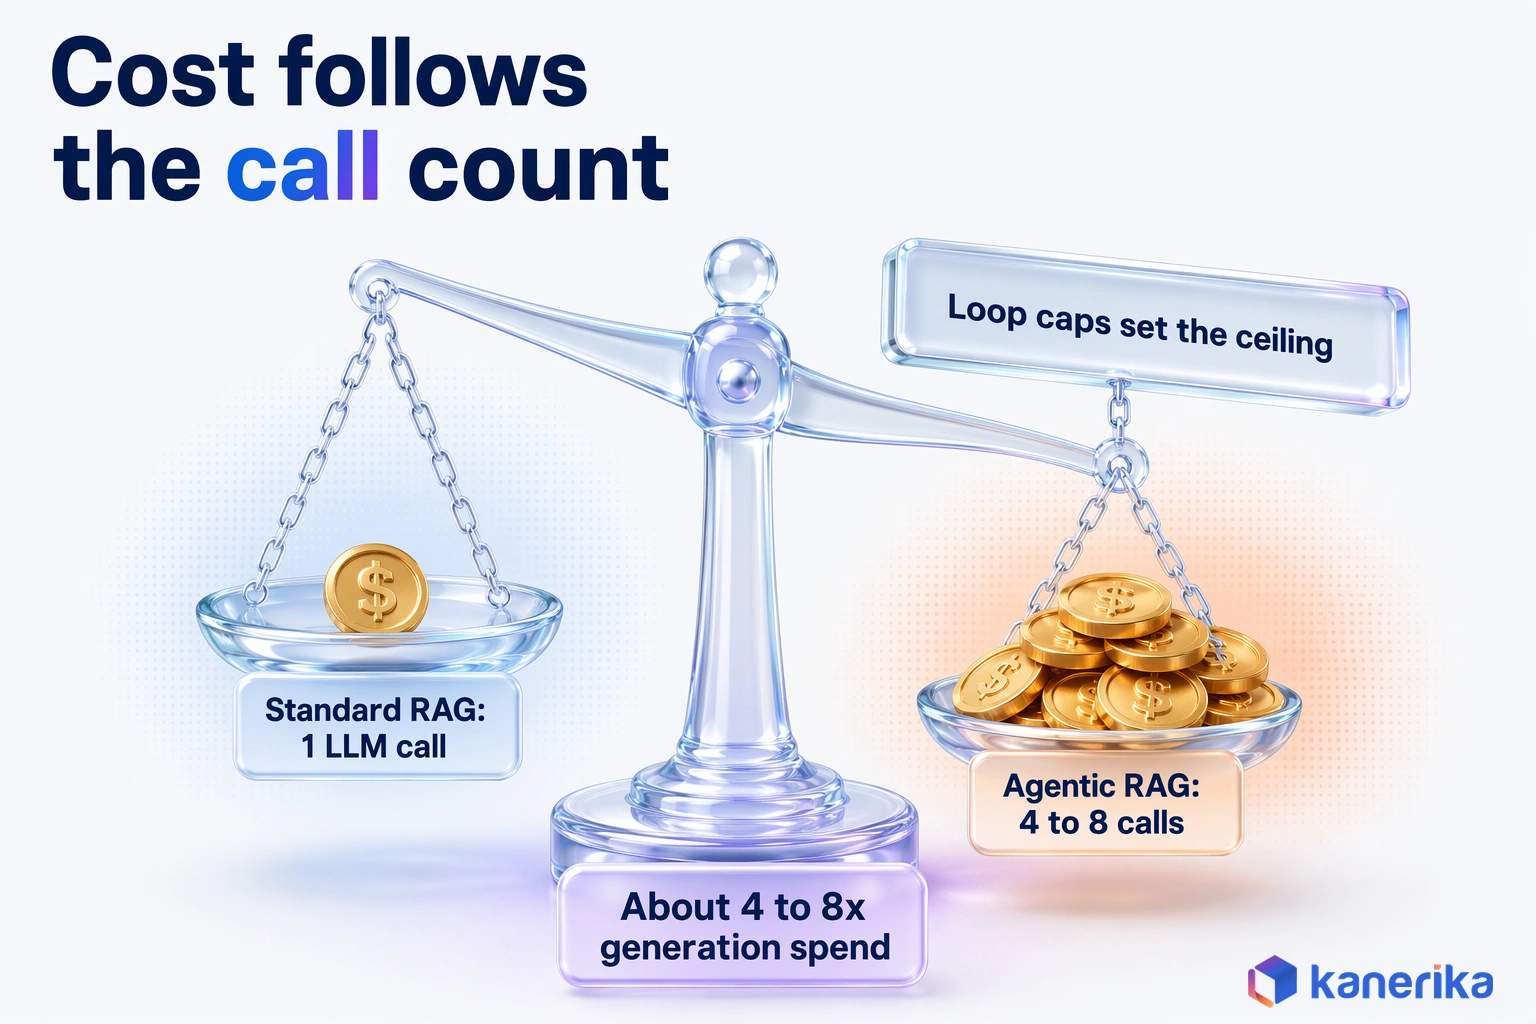
Plug in your own token prices, since they change often. The structure matters more than the price. So an agentic query with 4 to 8 LLM calls costs roughly 4 to 8 times the generation spend of a one-call RAG query. That assumes similar token counts per call, and tool calls and longer prompts add more on top.
Latency follows the same logic. Calls that run in sequence add up, so a six-step agent run takes several times longer than one generation. Parallel retrieval narrows the gap, and the planning calls still sit in sequence.
Loop Budgets and Stop Rules
An agent with no limits can loop until the budget runs out. Stop rules therefore turn that open-ended risk into a known ceiling. Set these before the first pilot user arrives.
- Maximum iterations: cap planning and re-retrieval rounds per question.
- Maximum tool calls: cap database, API and search calls separately from model calls.
- Timeout: end the run after a fixed wall-clock budget that matches the user’s patience.
- Token budget: stop when total tokens for the query pass a set limit.
- Honest fallback: when a cap fires, answer “I could not confirm this” and show the sources found so far.
Framework defaults will not set these caps for you. In LangGraph, for instance, the documented default recursion_limit from version 1.1.4 is 10,007 super-steps, and exceeding it raises a GraphRecursionError. That ceiling is far above what a retrieval loop needs, so pass a small limit per run and catch the error as your fallback trigger.
The fallback is the part teams forget. A clear “not found” with sources builds more trust than a confident guess produced on the last allowed step. Kanerika’s support agent for a global expert network hands low-confidence cases to live staff; its case study reports 65% self-service resolution.
Where Accuracy Actually Improves
Accuracy gains from agentic retrieval cluster in specific question types, such as the three below. Multi-hop questions improve because the agent can chain lookups. Ambiguous questions improve because the agent can explore readings or ask back. Cross-system questions improve because the agent can reach both the table and the document.
Single-fact lookups gain little, since one good search already finds the answer. That is the reasoning behind Adaptive-RAG (Jeong et al., 2024), which picks a retrieval strategy based on question complexity. So spend agent steps only where the question needs them.
Decision Framework: When to Choose RAG or Agentic RAG
The choice between the two designs is a per-workload decision, not a company-wide one. For instance, a support team and a finance team can rightly land on different answers. The scenario picks, five questions and router design below then make the call repeatable.
Scenario Picks
Start by matching the workload to a pattern. The table covers ten common enterprise scenarios and the reasoning behind each pick.
| Scenario | Pick | Why |
|---|---|---|
| Policy Q&A for employees | Standard RAG | One source, predictable questions, fast answers needed |
| Product documentation support | Standard RAG | Single index, answers live in one or two chunks |
| HR self-service | RAG first, agentic on escalation | Most questions are policy lookups, a few need employee records |
| Contract review across clauses | Agentic RAG | Clauses cross-reference each other, as in document-heavy legal workflows |
| Financial variance analysis | Agentic RAG | Needs SQL figures plus commentary from reports |
| Regulatory research | Agentic RAG | Multi-hop across rules, guidance and internal policy |
| IT incident triage | RAG first, agentic on escalation | Runbook lookups first, logs and tickets when the runbook falls short |
| Sales account research | Agentic RAG | Combines CRM data, contracts and public news |
| Customer support with order lookup | RAG first, agentic on escalation | FAQs via RAG, order status via a tool call, as with AI agents for customer support |
| Compliance vetting | Agentic RAG | Checks many sources against fixed disqualification rules |
Five Questions That Decide It
When a workload does not match a row above, these five questions settle it. In general, two or more answers on the agentic side justify the extra cost.
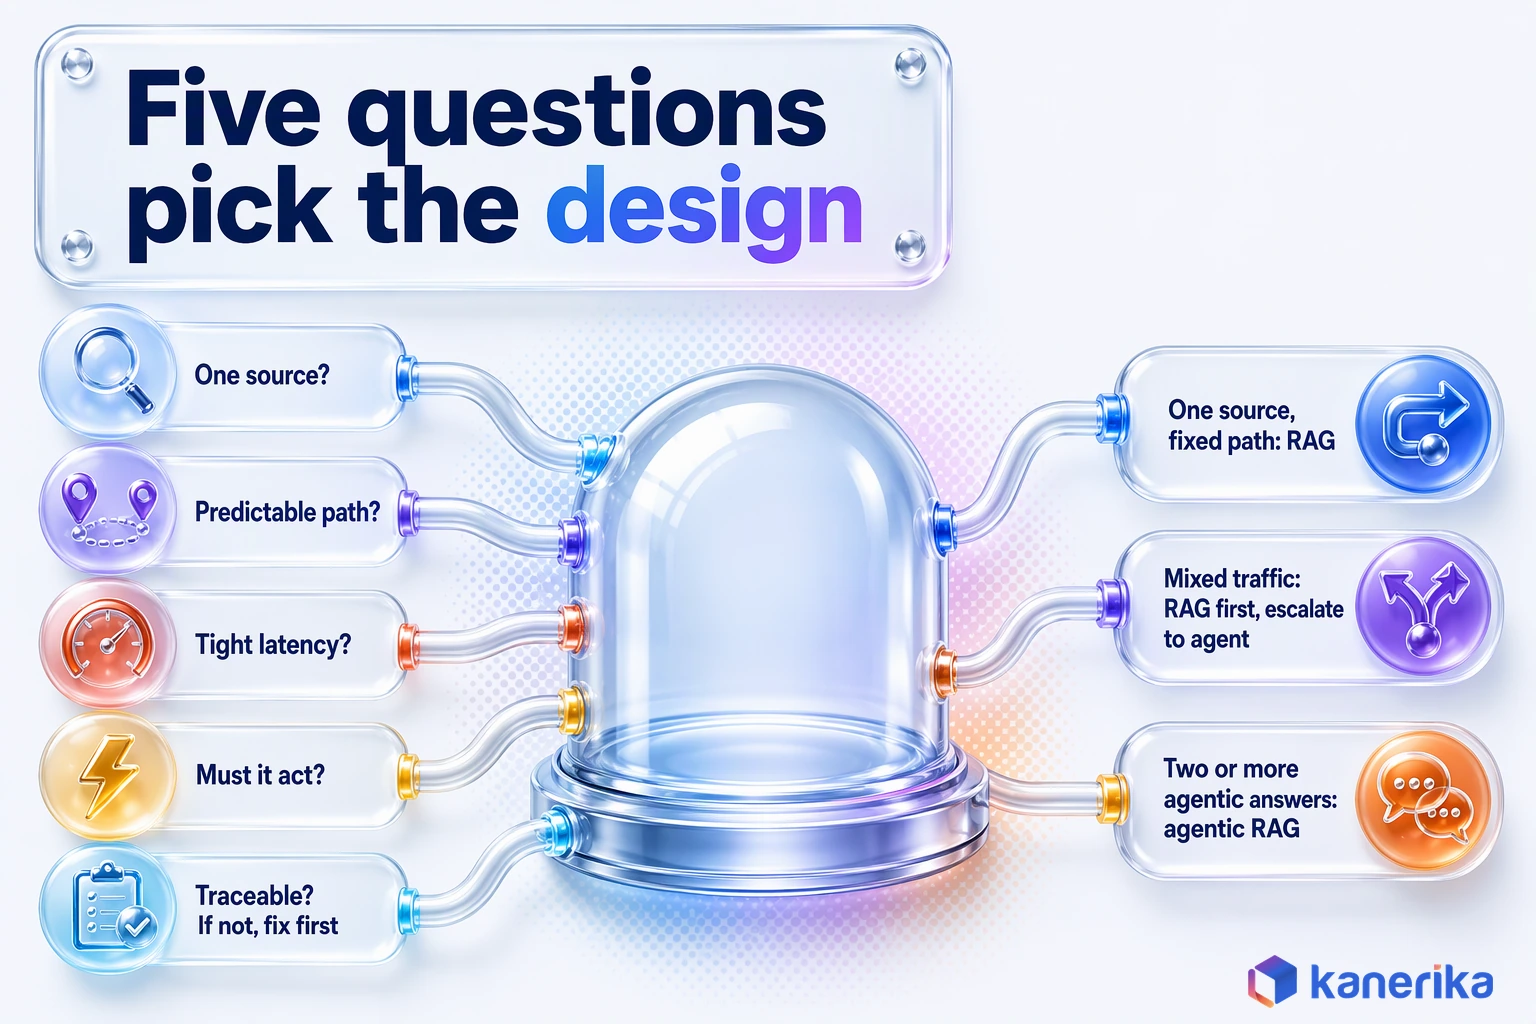
- Does the answer live in one source? Yes points to RAG. No points to agentic RAG.
- Is the path predictable? If you can write the steps down in advance, code them as a fixed pipeline.
- Is the latency budget a few seconds or less? If yes, favor standard RAG, or a router that rarely escalates to the agent.
- Does the system need to act, or only read? If it must act, that points to agentic RAG with much stricter controls.
- Can you trace every step? If not, fix observability before you add autonomy.
The Hybrid Router
Mixed workloads rarely need a pure choice. Instead, a hybrid router sends every question down the cheap RAG path first. It escalates to the agent only when retrieval confidence is low or the question has several parts.
The router can be something small, such as a classifier or a single LLM call. Adaptive-RAG formalizes the same idea by routing on question complexity. The payoff is that simple questions keep RAG speed and cost, while hard ones get agent reach. Escalation rate becomes the number to watch, because it tells you what share of traffic pays the agentic premium.
Retrieval confidence needs a concrete score to act on. Azure AI Search semantic ranker, for example, reranks the top 50 results. It gives each one a @search.rerankerScore from 0 to 4, where 2.0 means somewhat relevant and 4.0 means a complete answer. Microsoft also warns against overly granular thresholds, because score distributions shift slightly between runs. The settings below are illustrative starting points, not benchmarks.
# Illustrative hybrid router settings: tune on your own evaluation set
retrieval_top_k            = 5     # LlamaIndex default similarity_top_k is 2
escalate_if_top_score      < 2.0   # Azure rerankerScore scale, 0 to 4
escalate_if_sub_questions  >= 2    # multi-part question detected
agent_recursion_limit      = 12    # LangGraph super-steps per run
max_tool_calls             = 8
timeout_seconds            = 20
In short, start strict, then loosen one setting at a time while you watch escalation rate and cost per resolved query.
Risks and Governance for Agentic Retrieval
Giving a model the power to choose sources and call tools also gives attackers and mistakes more room to work. Security teams raise this objection first, so plan the controls alongside the design. In the investment bank project, Kanerika enforced role-based access at the retrieval layer, and the case study reports 100% role-based compliance. The OWASP Top 10 for LLM Applications names the main risks.
“An agent with access to a provider credential can expose it or misuse its authority if its environment is compromised or its behavior is manipulated.”
Amit Kumar Jena, Head of AI Development, Kanerika
From his byline in Cybersecurity Insiders, October 18, 2026
Risk-to-Control Matrix
Each risk below also gets worse as the agent gains reach. At the same time, each control limits the damage without removing the agent’s usefulness.
| Risk | Why agentic RAG raises it | Control |
|---|---|---|
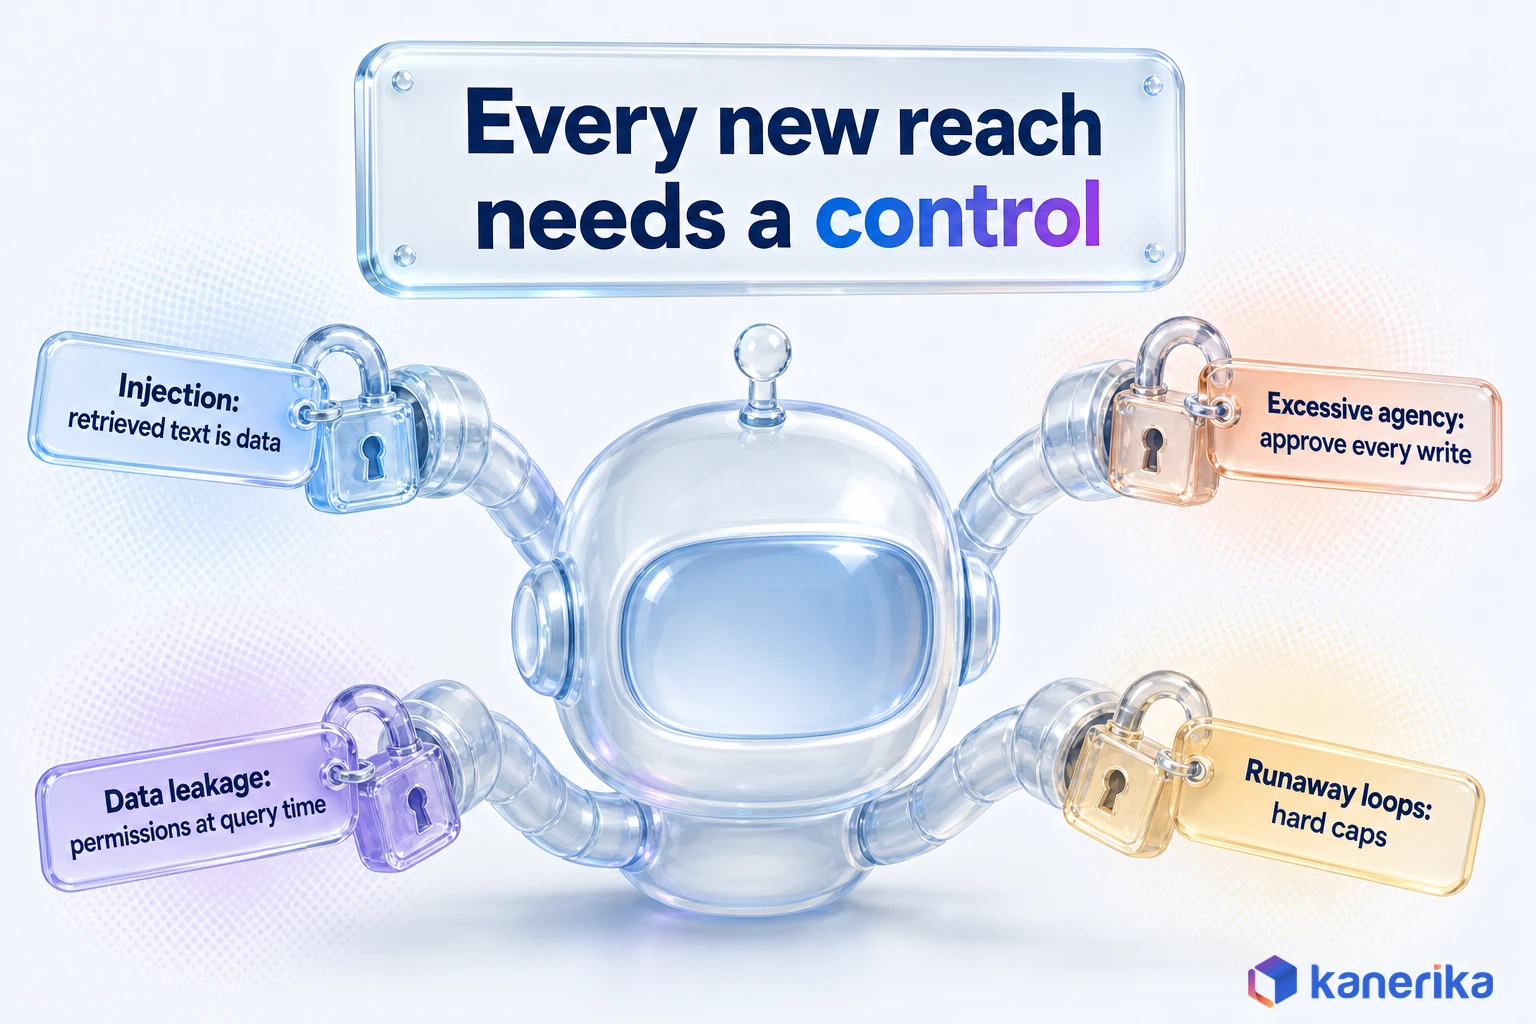
| Indirect prompt injection (OWASP LLM01) | The agent reads external files and pages that can carry hidden instructions | Treat retrieved text as data, never as instructions; filter sources |
| Excessive agency (OWASP LLM06) | Too much functionality, permission or autonomy in the agent’s tools | Read-only tools by default; human approval for any write |
| Vector and embedding weaknesses (OWASP LLM08) | Misaligned access controls can leak data across users | Permission-aware retrieval enforced at query time |
| Runaway loops | No fixed end to the reasoning cycle | Iteration, tool-call, time and token caps |
| Non-determinism | The same question can take different paths | Fixed evaluation sets and regression tests per release |
| Missing audit trail | Decisions happen inside many hidden steps | Step-level tracing of plans, calls, sources and outputs |
Access control deserves the most attention. In standard RAG, for example, you secure one index. In agentic RAG every tool the agent can call needs the same user-level permission check, or the agent becomes a way around it.
Governance Checklist for US Enterprises
US teams, in particular, often anchor their program to the NIST AI Risk Management Framework. NIST published its Generative AI Profile (NIST AI 600-1) on July 26, 2024, and it maps well to agentic retrieval. A practical checklist looks like this, and our guide to AI governance best practices covers the wider program around it.
- Name an owner for each source the agent can reach.
- Inventory every tool and record whether it reads or writes.
- Enforce the user’s own permissions on every retrieval and tool call.
- Require human approval before any action that changes a record.
- Log each step with enough detail so that anyone can replay the run.
- Run red-team tests for injection through retrieved content.
- Review loop caps and cost per query every month.
- Define how users report a wrong answer and who fixes it.
These controls also build on ordinary data governance, so our guide to data governance principles covers the ownership and access basics they rely on.
How to Evaluate RAG and Agentic RAG Side by Side
A fair comparison runs both designs against the same question set and then scores them on the same metrics. Otherwise, teams compare a polished demo against a rough prototype and learn nothing. To that end, build the set from real user questions, including the ones the current system fails.
Group the metrics in three layers so you can see where a gain or loss comes from. Set your own pass marks per use case before the pilot starts.
Kanerika Service
Agentic AI Services
Kanerika builds governed AI agents with routing, loop caps, step-level tracing and human approval on write actions, so agentic retrieval stays auditable in production.
Explore Agentic AI| Layer | Metric | What it tells you |
|---|---|---|
| Retrieval | Recall@k | Did the right evidence appear in the top results? |
| Retrieval | Context precision | How much of the retrieved text was relevant? |
| Answer | Faithfulness | Is every claim supported by the retrieved evidence? |
| Answer | Citation accuracy | Do the cited sources actually say what the answer claims? |
| System | Steps per query | How much work the agent did, and whether it is creeping up |
| System | Latency p95 | What the slowest typical user experiences |
| System | Cost per resolved query | Spend divided by questions actually answered |
| System | Escalation rate | Share of traffic a router sends to the agent |
Overall, cost per resolved query is the fairest single number. An agent that costs more per call but resolves far more questions can still win, while one that only adds steps cannot. For the full production test setup, see our guide to building a RAG application.
Moving From RAG to Agentic RAG in Stages
Teams rarely need to rebuild from scratch in order to get agentic behavior. Instead, the safer path adds autonomy only where the logs show the fixed pipeline failing. Five stages keep each change small and measurable.
- Baseline standard RAG and log failures. Ship the simple pipeline first, then record every question it misses or answers poorly.
- Classify the failure modes. Sort misses into bad search, multi-hop, ambiguity, split sources and unchecked relevance.
- Add one pattern for the failing slice. Put a router or a corrective check in front of only those questions.
- Cap loops and add tracing. Set iteration, tool and time limits, and log every step before widening use.
- Widen scope once evaluation holds. Expand to more question types only when faithfulness and cost per resolved query stay within your marks.
Each stage has a clear exit test, so a stakeholder can see why the next one is justified. The approach also keeps a working fallback in place the whole time.
When a stage stalls, the logs show why. Often the fix is better chunking or a cleaner source rather than more autonomy.
How Kanerika Builds RAG and Agentic RAG Systems
Kanerika treats the RAG-versus-agent decision as an outcome of evidence rather than a starting assumption. Our RAG development services start with the simplest design that answers the questions, and our agentic AI services add agent control where the logs prove it is needed. Delivery follows four stages.
- Scope and baseline. Collect a real question log, then inventory the sources and map who may see what.
- Standard RAG with permission-aware retrieval. Build the pipeline with access checks at query time and a fixed evaluation set.
- Agentic retrieval on the failing slice. Add routing or corrective loops for the questions that fail, with loop caps and step tracing.
- Harden and release. Red-team, tune cost and require human approval on any write action.
In practice, two Kanerika agents often sit behind such a router. Karl answers questions over structured data, and its product page reports 62% time saved on data analysis, 5x faster decisions and 78% team efficiency. KlarityIQ, by contrast, is a document agent for natural-language retrieval from enterprise knowledge.
Take the supplier question from earlier. A router would send the invoice and purchase-order lookups to Karl and the contract clause search to KlarityIQ. The agent then joins both answers and cites each source.
Case Study: An AI Compliance Agent for Expert Vetting
The pattern holds up in production. A global leader in knowledge-sharing between industry experts and decision-makers, with a network of over one million experts, needed faster expert vetting. Kanerika built an AI compliance agent that pulls from internal databases and crawls news, social and professional records. After that, it maps findings against disqualification criteria and reports them with citations.
That is multi-source retrieval plus rule checks, an agentic RAG design in practice. The client saw 3x faster expert vetting and 60% less time on negative-news screening. It also recorded a 70% decrease in backlog cases and a 40% reduction in event delays.
Case Study
3x Faster Expert Vetting with an AI Compliance Agent
Kanerika built an AI compliance agent for a global expert network. It retrieves from internal databases and public records, maps findings to disqualification rules, and cut backlog cases by 70% and event delays by 40%.
Read the Case Study →RAG vs Agentic RAG: The Verdict
The answer to RAG vs agentic RAG depends on the question, not the trend. Standard RAG wins when the answer lives in one source and the path is predictable. It is faster, cheaper and easier to audit, and it covers policy, product and FAQ workloads well.
Agentic RAG wins on the slice of questions that need several lookups, several systems or a check before answering. Earn it with evidence, so log where standard RAG fails, then add agent control only there.
When both kinds of questions arrive at the same front door, run a hybrid router. That way, simple answers stay cheap while hard ones go to the agent. Cap the loops, trace the steps and keep a person on any write action. Start with RAG, and let your failure logs decide when agentic RAG has earned its place.
Frequently Asked Questions
What is the difference between RAG and agentic RAG?
Standard RAG follows a fixed path. It searches an index once, passes the top results to a language model and writes an answer. Agentic RAG puts an LLM agent in charge of that path. The agent can plan, choose sources and tools, check the evidence and search again before it answers or stops.
Is agentic RAG better than standard RAG, and is it worth it?
Agentic RAG is better only for certain questions. It pays off on multi-hop, ambiguous and cross-system questions where one search cannot find the answer. For single-source lookups it adds cost and latency with little gain. The best test is to log where standard RAG fails and add agent control only for that slice.
What are the levels of RAG?
A widely cited survey by Gao et al. groups RAG into three paradigms. Naive RAG retrieves and generates in one pass. Advanced RAG adds steps before and after retrieval, such as query rewriting and re-ranking. Modular RAG makes those parts swappable. Agentic RAG is often treated as the next level, where an agent controls the flow.
Is ChatGPT a RAG system?
A chat assistant is a RAG system only when it retrieves outside content and grounds its answer in that content. A model answering from its training data alone is not RAG. Many assistants add search or file retrieval as an option, so whether a given answer used RAG depends on how that session was set up.
Does agentic AI require RAG?
No. Agentic AI means a model that plans and takes actions with tools, and many agents never retrieve documents. An agent that books meetings or updates tickets may only call APIs. Agents need RAG when their decisions depend on company knowledge, such as policies, contracts or records, that the model has not seen in training.
Does agentic RAG reduce hallucinations?
It can, on the right questions. An agent that checks whether retrieved text answers the question, and searches again when it does not, avoids many confident wrong answers. Corrective RAG and Self-RAG were designed for this. It does not remove hallucination, so faithfulness checks, citations and an honest not-found fallback are still needed.
How much more does agentic RAG cost than standard RAG?
Cost scales with the number of model calls per question. Standard RAG makes one generation call, while an agentic run might make four to eight for planning, routing, checks and the answer. With similar token counts per call, generation spend rises by about that multiple. Tool calls and longer prompts add more on top.
Can you combine standard RAG and agentic RAG?
Yes, and many teams should. A hybrid router sends every question down the cheap standard RAG path first. It escalates to the agent only when retrieval confidence is low or the question has several parts. Simple questions keep RAG speed and cost, while hard ones get agent reach. Track the escalation rate to manage spend.
How do you evaluate an agentic RAG system?
Run it against a fixed set of real user questions and score three layers. Retrieval metrics include recall at k and context precision. Answer metrics include faithfulness and citation accuracy. System metrics include steps per query, p95 latency, cost per resolved query and escalation rate. Set pass marks per use case before the pilot starts.
What are the security risks of agentic RAG?
The OWASP Top 10 for LLM Applications names the main ones. Indirect prompt injection can hide instructions in retrieved files. Excessive agency gives tools too much permission or autonomy. Weak access controls on vector stores can leak data across users. Runaway loops and missing audit trails add operational risk, so caps and step-level tracing matter.
How do you move from RAG to agentic RAG?
Move in stages. Ship standard RAG first and log every question it misses. Sort the misses into failure types such as multi-hop or split sources. Add one agentic pattern, like a router or corrective check, for that slice only. Then cap loops, add tracing and widen scope once evaluation results hold steady.
What is the difference between agentic RAG and AI agents?
AI agents are the broad category of models that plan and act with tools toward a goal. Agentic RAG is one use of an agent, focused on retrieval. The agent decides what to search, where and when to stop, so its answer rests on company knowledge. Many AI agents do other work, such as updating records.
How can you tell if a system is agentic RAG?
Ask who chooses the next step. If a developer fixed the sequence of retrieval and generation in code, the system is standard or advanced RAG. If the model decides at run time whether to search again, which tool to call or when to stop, it is agentic RAG. That holds even with a single agent.
Is RAG an agentic workflow?
Standard RAG is not an agentic workflow. It runs the same retrieve-then-generate steps for every question, with no decision made by the model about what to do next. RAG becomes agentic once an LLM agent controls the loop by planning sub-questions, routing to sources, checking results and deciding when the answer is complete.
What is the difference between Self-RAG and agentic RAG?
Self-RAG is one specific technique, published by Asai et al. in 2023. It trains a model to decide when to retrieve and to critique its own output through reflection. Agentic RAG is the broader family. It also covers planning, routing across many sources, tool calls and multi-agent designs, with Self-RAG as one possible building block.
What are the benefits of agentic RAG?
Agentic RAG can break a complex question into parts, reach several sources, including databases and APIs, and check evidence before answering. That improves results on multi-hop and ambiguous questions. It also makes it possible to answer questions whose facts sit partly in tables and partly in documents, which a single vector search cannot join.
Which is faster, RAG or agentic RAG?
Standard RAG is faster. It makes one retrieval and one generation call, so response time stays low and stable. Agentic RAG makes several model and tool calls, often in sequence, so each answer takes longer and timing varies by question. Parallel retrieval and a router that escalates only hard questions help close the gap.
Which applications are best suited for agentic RAG?
Agentic RAG suits work that spans several sources or steps. Good examples include contract review across clauses, financial variance analysis, regulatory research, sales account research and compliance vetting against fixed rules. Simple policy questions, product documentation and FAQ bots usually run better on standard RAG, which stays faster, cheaper and easier to audit.
Can agentic RAG work without internet or API access?
Yes. Agentic RAG needs a model and the sources it is allowed to reach, not the public internet. A fully private setup can run a self-hosted model against internal indexes, databases and tools on your own network. The agent then plans and routes across those internal sources only, which suits regulated or air-gapped environments.
What are the main types of RAG?
Common types include naive or standard RAG, advanced RAG with re-ranking and query rewriting, and modular RAG built from swappable parts. Agentic patterns add router RAG, corrective RAG, adaptive RAG, multi-agent RAG and GraphRAG. Multimodal RAG retrieves images and tables as well as text. There is no fixed official count of types.