TL;DR
LangGraph MCP integration lets a LangGraph agent call tools on MCP servers, and new builds should use langchain.mcp’s MCPAdapter over Streamable HTTP. LangGraph owns the workflow and state, the MCP servers expose the tools, and the adapter turns each MCP tool into a LangChain tool. Keep the legacy MultiServerMCPClient only on code you cannot migrate yet, since langchain-mcp-adapters is no longer actively maintained. Pick stdio for a prototype, remote MCP once several teams share tools, and a plain API tool when only one agent needs it. Start read-only, then gate every write behind a LangGraph interrupt with an idempotency key. Checkpoint state in Postgres so an approval can pause for hours and resume exactly where it stopped.
Key Takeaways
- A LangGraph MCP integration has four parts: the graph, the MCP servers, the adapter between them and the control layer around writes.
- MCP support moved into LangChain as langchain.mcp (MCPAdapter, beta), and the standalone langchain-mcp-adapters package is no longer actively maintained.
- Streamable HTTP is the production transport, stdio suits local development and HTTP+SSE is deprecated.
- LangGraph v1 deprecated create_react_agent in favor of create_agent, so old tutorials need new imports.
- Put an interrupt before every write tool and persist state with PostgresSaver, never InMemorySaver.
- Choose MCP when tools are shared across agents or teams, and a direct API tool when one agent uses one system.
A Support Agent That Can Read Every Invoice, and Should Not Issue the Refund
A customer writes in on a Monday morning. Their card shows two charges of $249 for October, and they want the money back today.
The support agent you built answers in seconds, so the customer barely waits. First it pulls both invoices, then it reads the ticket history and confirms the duplicate. Then it reaches for the credit tool, because nothing in the code told it to stop.
That last step is where most of the engineering in this guide lives. Reading invoices is low risk. Moving money is not, so the agent needs a pause, a reviewer and a key that stops the same credit from landing twice.
This guide builds that agent end to end with current code. You get two MCP servers, a LangGraph state graph with an approval interrupt and a Postgres checkpointer. You also get the controls that make a LangGraph MCP integration safe for enterprise use.
What LangGraph MCP Integration Means in 2026
In plain terms, LangGraph decides what the agent does next, and MCP gives it a standard way to reach the tools that do the work. The two solve different problems, which is why they fit together so well.
LangGraph is a framework for stateful agentic workflows, such as approvals that span days. You describe the agent as a graph of nodes and edges, and it keeps the conversation state, retries and pauses. If you want the longer split between the two LangChain projects, our guide on where LangChain ends and LangGraph begins covers it.
The Model Context Protocol is an open standard that Anthropic open-sourced on November 25, 2024. An MCP server publishes tools with names, descriptions and input schemas, so any compliant client can discover and call them. Our explainer on the Model Context Protocol covers the protocol internals in depth.
Adoption is no longer a bet. Anthropic donated MCP to the Agentic AI Foundation under the Linux Foundation on December 9, 2025. At that point it reported more than 10,000 active public servers and over 97 million monthly SDK downloads across Python and TypeScript. Gartner also predicted in August 2025 that 40% of enterprise apps will feature task-specific AI agents by 2026, up from less than 5% in 2025. Our analysis of agentic AI enterprise adoption tracks how that shift is landing.
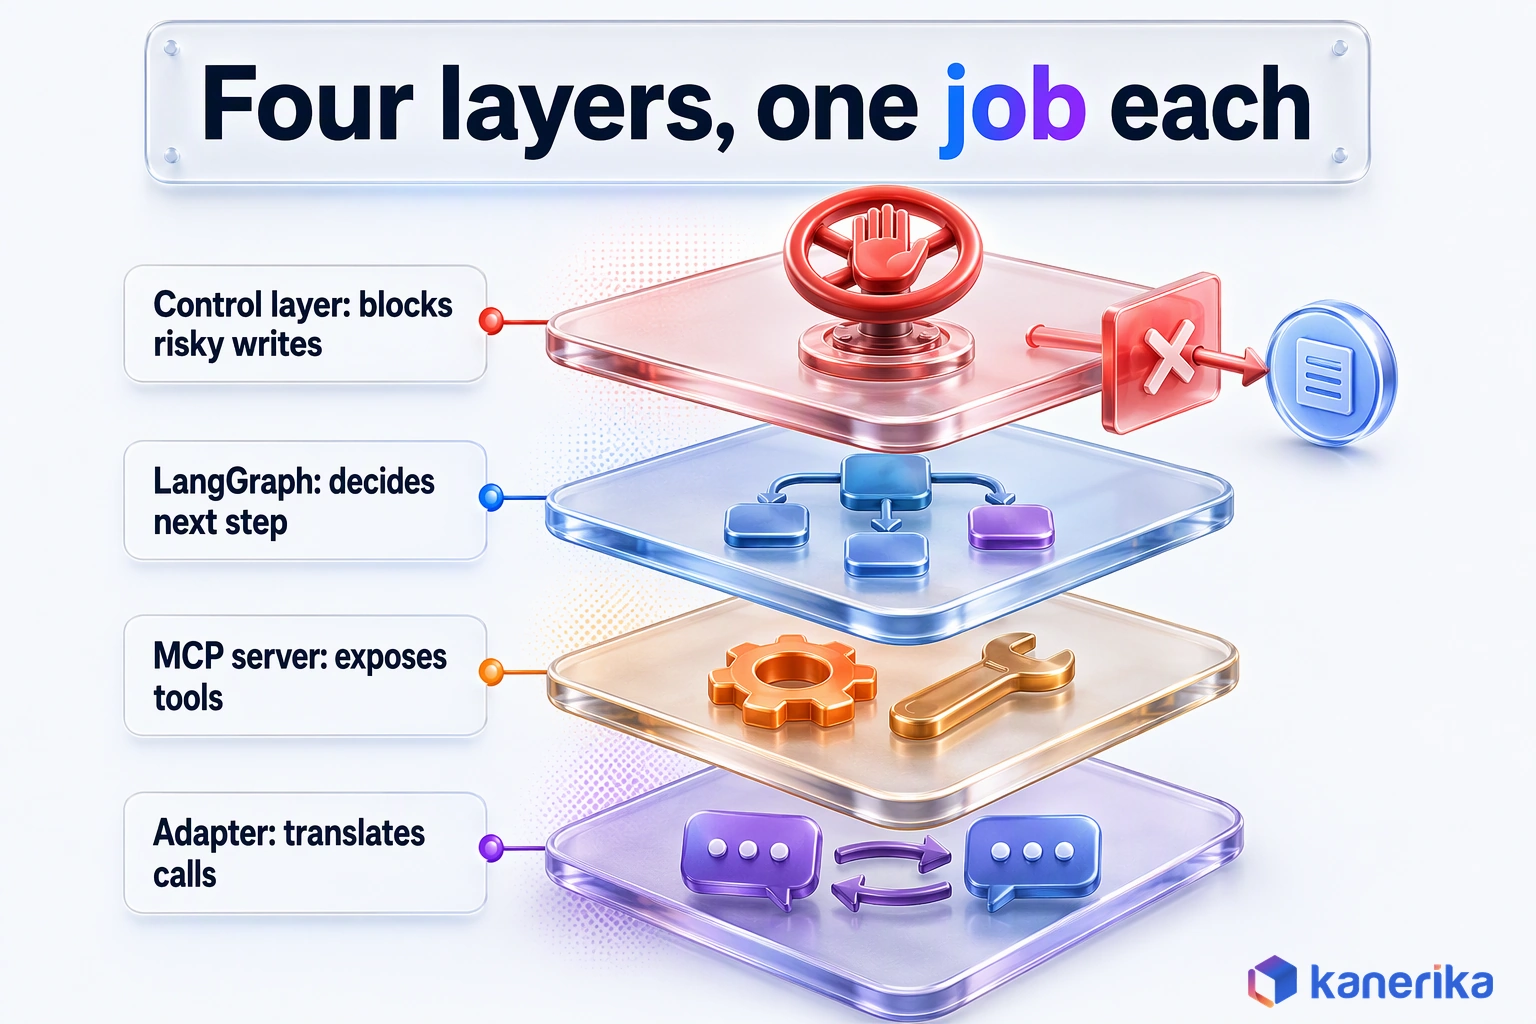
The Four Layers of a LangGraph MCP Integration
An integration has four layers. Each has one job, so confusing them is the source of most design mistakes.
| Layer | Its job | What it is not |
|---|---|---|
| LangGraph | Runs the workflow: state, routing, retries, pauses and resumes | A tool catalog, and not a security boundary either |
| MCP server | Exposes tools with schemas over a standard protocol | An orchestrator; it does not decide when a tool runs |
| Adapter (langchain.mcp) | Turns MCP tools into LangChain tools the graph can bind | A policy engine; it passes calls through |
| Enterprise control layer | Allowlists, approvals, idempotency, audit traces and identity | Optional; without it the demo is the product |
The fourth row is the one most tutorials skip, even though auditors ask about it first. It is the layer that decides which writes an agent may make, under whose identity, and what trail each call leaves behind. For why context alone is not control, see how MCP makes agents context-aware; for where MCP stops and A2A starts, see how MCP and A2A divide the work.
What Changed Since Early 2026
If you followed a LangGraph MCP tutorial written before September 2026, parts of it no longer run as written. Five changes matter, because each one touches code you may already have in production.
The biggest, by far, is the move to langchain.mcp, since it changes every import. LangChain announced MCP support inside LangChain on September 3, 2026, and the langchain-mcp-adapters repository now states it is no longer actively maintained.
| Change | Date | What to do in your code | Source |
|---|---|---|---|
| MCP spec 2026-07-28: stateless, self-contained requests with per-request capability negotiation | July 28, 2026 | Stop relying on long-lived sessions; keep conversation state in the LangGraph checkpointer | MCP specification |
| MCP support moved to langchain.mcp (MCPAdapter, beta); adapters package unmaintained | September 3, 2026 | Install langchain[mcp] 1.4.0 or later and swap MultiServerMCPClient for MCPAdapter | LangChain migration guide |
| create_react_agent deprecated in LangGraph v1 | LangGraph v1 | Use create_agent from langchain.agents, or an explicit StateGraph | LangGraph v1 migration guide |
| HTTP+SSE transport deprecated in favor of Streamable HTTP | MCP spec 2025-03-26 | Move servers to Streamable HTTP; use SSETransport only for back-compat | MCP 2025-03-26 transports spec |
| Agent Server /mcp supports revisions 2024-11-05 through 2026-07-28 | langgraph-api 0.18.0 | Upgrade langgraph-api before exposing graphs to new MCP clients | Agent Server MCP docs |
A note on Python: langchain 1.5.0 needs 3.11, while langgraph 1.2.22 and mcp 2.3.0 still accept 3.10. Every LangChain package dropped Python 3.9 with v1.
How the Integration Works: One Request, End to End
The easiest way to understand the integration is to follow one user message through it. Most of the steps are checks, while the model itself appears in only two of the ten.
Take the billing question from the opening, for example. The user asks why they were charged twice. Before it answers, the graph has to decide which tools it may touch, call them safely and save its place.
The Ten Steps of One Request
- Authenticate. The request arrives with the user’s identity, and the graph loads the scopes that identity holds.
- Discover. MCPAdapter lists the tools each configured server publishes, with their schemas.
- Filter. An allowlist drops every tool this agent is not approved to use before the model ever sees it.
- Route. The model reads the conversation and proposes zero or more tool calls.
- Validate arguments. Arguments are checked against the schema and against business limits, such as a maximum credit.
- Approve. Any write tool triggers a LangGraph interrupt, and a person approves, edits or rejects it.
- Execute with a timeout. The tool runs on its MCP server, and a slow or failed call returns an error instead of hanging.
- Minimize output. Only the fields the next step needs go back into the state, with sensitive values redacted.
- Checkpoint. The checkpointer saves the full state, so a crash or a long approval loses nothing.
- Return. The model writes the final answer from the verified tool results, with a trace id for audit.
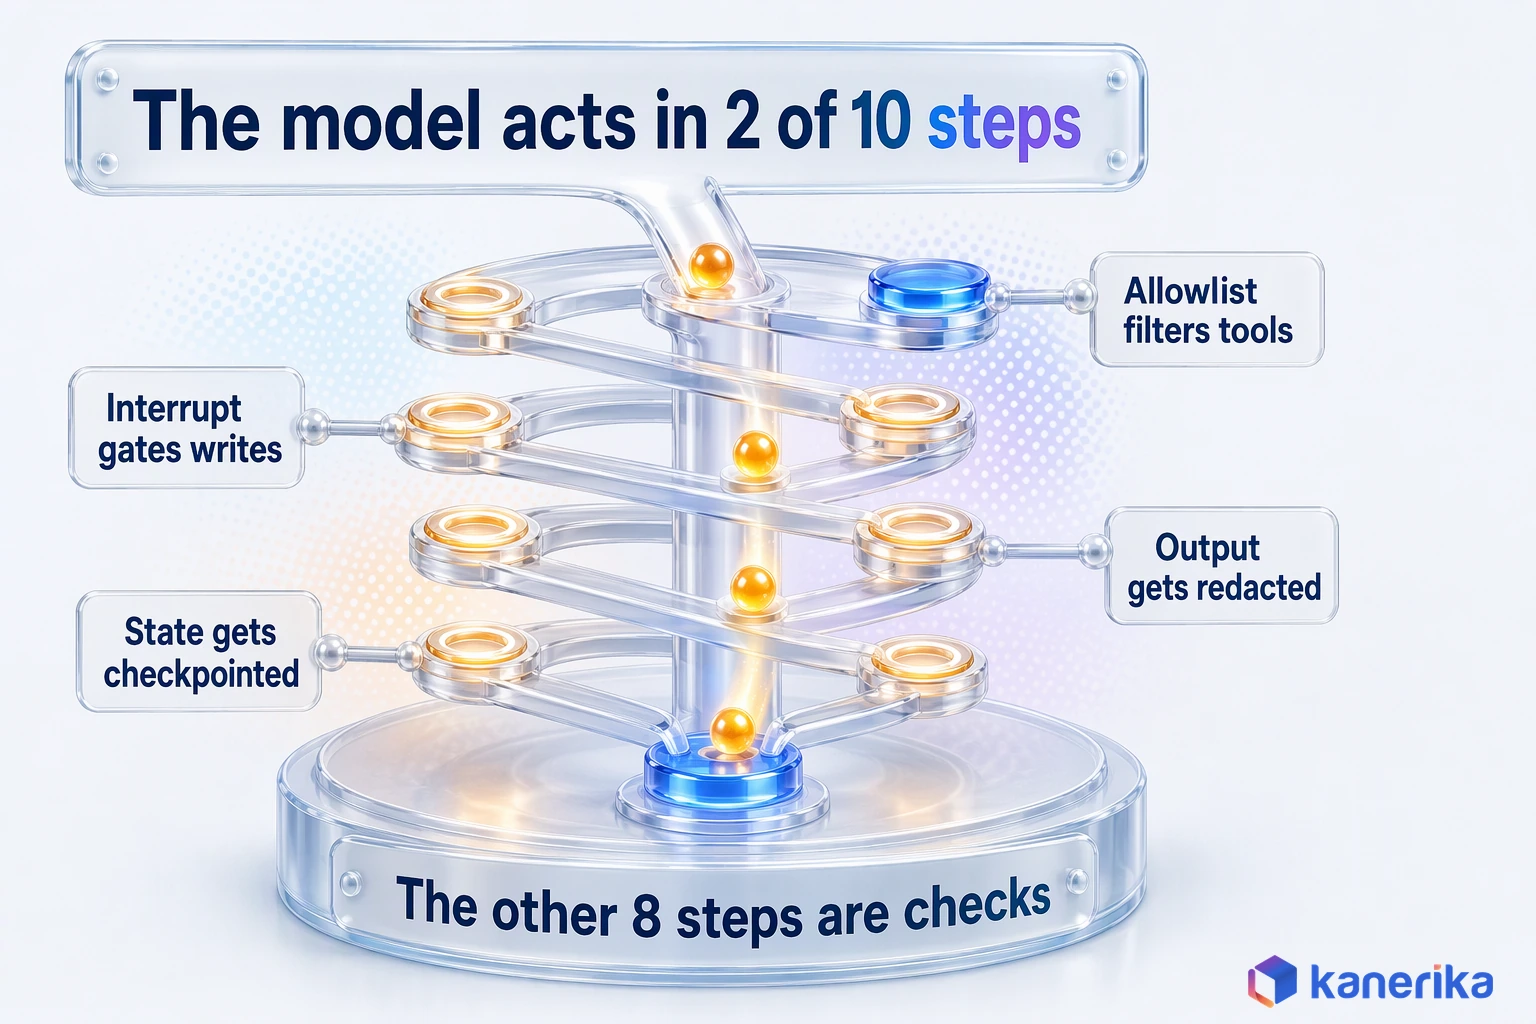
Steps 3, 6 and 8 are the ones teams leave out when they rush a prototype. Step 8 in particular decides what lands in graph state and what stays in the tool output, the core question of agentic context engineering (and the reason context engineering, not prompt wording, is where agent quality is won).
Notice that the protocol itself only covers steps 2 and 7, rather than the whole trace. Everything else is your graph’s responsibility, which is good news, because LangGraph gives you a node for each of them.
Choose Your Adapter and Transport Before Writing Code
Two choices shape every line that follows: which library connects LangGraph to MCP, and how the bytes travel between them. Getting them right first saves a migration later.
For new code, the answer is MCPAdapter from langchain.mcp, unless a legacy constraint blocks it. It is an async context manager, and it infers the transport from each server entry. It also prefixes tool names with the server name when you connect several servers. The catch is that it is labeled beta and raises a LangChainBetaWarning on import, so pin the version.
| Option | Status | Pick it when |
|---|---|---|
| langchain.mcp MCPAdapter | New, beta; needs langchain[mcp] 1.4.0 or later | Any new build, and any codebase you can migrate |
| langchain-mcp-adapters MultiServerMCPClient | Legacy; still installable at 0.3.2 but no longer actively maintained | Existing production code that you cannot migrate this quarter |
| Raw mcp SDK ClientSession plus load_mcp_tools from the adapters package | Low level; full control of the session | Custom transports or debugging a single server |
The transport choice is simpler, because the specification has already made it for production. Streamable HTTP is the standard for anything shared or remote. By comparison, a stdio server runs as a local subprocess, which is ideal while you develop but cannot be shared.
| Transport | Use for | Avoid when |
|---|---|---|
| stdio | Local development, a single user, tools on the same machine | Several users or agents need the same server |
| Streamable HTTP | Shared, remote and production servers behind a gateway | Purely local, single-user tools, where stdio is simpler |
| HTTP+SSE | Back-compat with an old server you do not control | Any new server; it is deprecated |
WebSocket servers have no FastMCP transport at all, so they need to move to Streamable HTTP before they can join a langchain.mcp build.
Build a LangGraph MCP Integration Step by Step
This section builds the billing agent from the opening, one file at a time, so you can test each piece before the next. You will end with two MCP servers and a graph that reads freely but asks before it writes. Finally, you add durable state and an endpoint that other MCP clients can call.
Each code block also names the versions it was written against. The libraries move quickly, so treat those labels as the first thing to check when something fails.
Prerequisites and Version Pinning
Start with a clean environment and pinned versions before you write any code. Pin the versions this guide was written against: langchain 1.5.0, langgraph 1.2.22 and the mcp SDK 2.3.0, per the PyPI release data.
- Python 3.11 or later, so one interpreter satisfies every package.
- Pinned langchain, langgraph and the mcp SDK, together with a lock file from pip freeze.
- A Postgres database for checkpoints, or SQLite on a laptop.
- Non-production credentials with least privilege: read-only for billing data, a capped test account for the CRM.
- An API key for the chat model you plan to use, such as an Anthropic model.
# Written against langchain 1.5.0, langgraph 1.2.22, mcp 2.3.0 (PyPI, November 2026)
python3.11 -m venv .venv
source .venv/bin/activate

pip uninstall -y langchain-mcp-adapters        # only if an older build installed it
pip install "langchain[mcp]==1.5.0" "langgraph==1.2.22" \
            langchain-anthropic langgraph-checkpoint-postgres langgraph-checkpoint-sqlite

# Freeze what pip resolved (mcp, fastmcp and friends) so every environment matches
pip freeze > requirements.lock
The uninstall line matters on older projects. Having both MCP packages installed is a common cause of confusing import errors, because tutorials mix the two.
Checklist
Agentic AI Readiness Checklist
Check data access, tool ownership, approval rules and monitoring before your first agent touches a production system.
Get the Checklist →Build Two MCP Servers With FastMCP
The agent needs one server for reads and another for writes. Splitting them is a governance decision first. As a result, the read server can have broad access while the write server stays narrow, logged and capped.
The read server below exposes invoices and ticket history over Streamable HTTP. In a real deployment it would query a read-only database view, but stand-in rows keep the example runnable.
# billing_read_server.py
# Written against fastmcp as installed by langchain[mcp] 1.5.0 (November 2026)
from fastmcp import FastMCP

mcp = FastMCP("billing")

# Stand-in rows. In production this reads a read-only database view.
INVOICES = [
    {"customer_id": "C-1042", "invoice_id": "INV-7781", "amount": 249.00, "date": "2026-10-01"},
    {"customer_id": "C-1042", "invoice_id": "INV-7790", "amount": 249.00, "date": "2026-10-01"},
]
TICKETS = [
    {"customer_id": "C-1042", "ticket_id": "T-48213", "summary": "Charged twice for October"},
]

@mcp.tool()
def get_invoices(customer_id: str, limit: int = 10) -> list[dict]:
    """Return recent invoices for one customer. Read-only."""
    rows = [r for r in INVOICES if r["customer_id"] == customer_id]
    return rows[: min(limit, 50)]          # hard cap, whatever the model asks for

@mcp.tool()
def get_ticket_history(customer_id: str) -> list[dict]:
    """Return support tickets for one customer. Read-only."""
    return [t for t in TICKETS if t["customer_id"] == customer_id]

if __name__ == "__main__":
    mcp.run(transport="http", host="127.0.0.1", port=8001)   # Streamable HTTP at /mcp
Note the hard cap on limit. The model can ask for a thousand rows, but the server decides what it returns, which is the right place for that rule.
The write server is smaller on purpose. It has one tool, a ceiling on the amount and an idempotency key. So a retried call returns the first result instead of issuing a second credit.
# crm_write_server.py
# Written against fastmcp as installed by langchain[mcp] 1.5.0 (November 2026)
from fastmcp import FastMCP

mcp = FastMCP("crm")
_applied: dict[str, dict] = {}             # use a database table with a unique key in production

@mcp.tool()
def issue_credit(customer_id: str, invoice_id: str, amount: float,
                 idempotency_key: str) -> dict:
    """Apply a credit note to one invoice. Repeating a key returns the first result."""
    if idempotency_key in _applied:
        return _applied[idempotency_key]
    if not 0 < amount <= 500:
        raise ValueError("Agent-initiated credits must be between 0 and 500.")
    result = {"credit_id": f"CR-{len(_applied) + 1:05d}", "customer_id": customer_id,
              "invoice_id": invoice_id, "amount": amount, "status": "applied"}
    _applied[idempotency_key] = result
    return result

if __name__ == "__main__":
    mcp.run(transport="http", host="127.0.0.1", port=8002)
Raising ValueError is deliberate. MCPAdapter turns a tool error into a ToolMessage with status error, so the model sees a clear refusal rather than a crash.
Connect LangGraph to the Servers
Once both servers are running, the graph needs their tools as LangChain tools. MCPAdapter does that in a few lines, using the standard mcpServers config shape, and it infers Streamable HTTP from each url entry.
# connect.py: the current path (langchain.mcp, beta)
# Written against langchain[mcp] 1.5.0 (November 2026)
import asyncio
from langchain.mcp import MCPAdapter

MCP_CONFIG = {
    "mcpServers": {
        "billing": {"url": "http://127.0.0.1:8001/mcp"},   # url entry: Streamable HTTP
        "crm": {"url": "http://127.0.0.1:8002/mcp"},
        # a stdio entry would be {"command": "python", "args": ["/abs/path/server.py"]}
    }
}

async def main():
    async with MCPAdapter(MCP_CONFIG) as adapter:
        tools = await adapter.list_tools()
        print(sorted(t.name for t in tools))
        # ['billing_get_invoices', 'billing_get_ticket_history', 'crm_issue_credit']

asyncio.run(main())
The printed names carry the server prefix, as shown in the comment. That is automatic for a multi-server config, and it prevents two servers that both expose a tool called search from colliding.
If you maintain an older codebase, the legacy client still installs. The one thing to change is the call pattern, because MultiServerMCPClient stopped being a context manager at 0.1.0.
# Legacy path: langchain-mcp-adapters 0.3.2 (no longer actively maintained)
import asyncio
from langchain_mcp_adapters.client import MultiServerMCPClient

client = MultiServerMCPClient({
    "billing": {"transport": "http", "url": "http://127.0.0.1:8001/mcp"},
    "crm": {"transport": "http", "url": "http://127.0.0.1:8002/mcp"},
})

async def main():
    tools = await client.get_tools()      # plain call: no "async with" on 0.1.0 and later
    print([t.name for t in tools])

asyncio.run(main())
When you are ready to migrate, the import changes are small. The LangChain migration guide lists them in full.
| Old import (langchain_mcp_adapters) | New import (langchain.mcp) |
|---|---|
| client.MultiServerMCPClient | MCPAdapter, used with async with |
| tools.load_mcp_tools | MCPAdapter(…).list_tools() |
| tools.convert_mcp_tool_to_langchain_tool | as_langchain_tool, now a coroutine |
| tools.MCPToolArtifact | MCPToolArtifact |
| tool_interceptors | @wrap_tool_call middleware on the agent |
Kanerika Service
Agentic AI Consulting and AI Agent Development
Kanerika designs and builds governed AI agents, from tool inventory and MCP servers to approval workflows, evals and production monitoring.
Explore Agentic AI ServicesWire the StateGraph: Router, Tool Node, Approval Interrupt, Fallback
This is the heart of the build, so it is worth reading slowly. The graph has four nodes, and each one maps to a step from the request trace. First the agent proposes, then the router sorts reads from writes. After that, the approval node pauses for a person, and the fallback hands off when tools keep failing.
You could use create_agent from langchain.agents for a quick start, of course. Multi-agent designs build on the same nodes, and our guide to AI agent orchestration covers those patterns. An explicit StateGraph is worth the extra lines here, because the approval rule has to sit in the graph, where nobody can prompt it away.
# graph.py
# Written against langchain 1.5.0 and langgraph 1.2.22 (November 2026)
from typing import Literal

from langchain.chat_models import init_chat_model
from langchain.messages import AIMessage, ToolMessage
from langchain_core.runnables import RunnableConfig
from langgraph.graph import END, START, MessagesState, StateGraph
from langgraph.prebuilt import ToolNode
from langgraph.types import Command, interrupt

READ_TOOLS = {"billing_get_invoices", "billing_get_ticket_history"}
WRITE_TOOLS = {"crm_issue_credit"}

def build_graph(all_tools, checkpointer=None):
    # 1. Allowlist BEFORE binding: the model never sees a tool you did not approve.
    tools = [t for t in all_tools if t.name in READ_TOOLS | WRITE_TOOLS]
    model = init_chat_model("anthropic:claude-sonnet-5-5").bind_tools(tools)

    async def agent(state: MessagesState):
        return {"messages": [await model.ainvoke(state["messages"])]}

    # 2. Router: no tool call ends the turn, any write goes to approval first.
    def route(state: MessagesState) -> Literal["approve", "tools", "__end__"]:
        calls = getattr(state["messages"][-1], "tool_calls", None) or []
        if not calls:
            return END
        return "approve" if any(c["name"] in WRITE_TOOLS for c in calls) else "tools"

    # 3. Approval: pause the run, wait for a person, stamp an idempotency key.
    def approve(state: MessagesState, config: RunnableConfig) -> Command[Literal["tools", "agent"]]:
        last = state["messages"][-1]
        writes = [c for c in last.tool_calls if c["name"] in WRITE_TOOLS]
        decision = interrupt({"action": "approve_write", "calls": writes})
        if not decision.get("approved"):
            reason = decision.get("reason", "no reason given")
            rejected = [ToolMessage(content=f"Rejected by reviewer: {reason}",
                                    tool_call_id=c["id"], status="error")
                        for c in last.tool_calls]
            return Command(goto="agent", update={"messages": rejected})
        thread = config["configurable"]["thread_id"]
        stamped = [
            {**c, "args": {**c["args"], "idempotency_key": f"{thread}:{c['args']['invoice_id']}"}}
            if c["name"] in WRITE_TOOLS else c
            for c in last.tool_calls
        ]
        # Same message id, so the add_messages reducer replaces the call in place.
        return Command(goto="tools",
                       update={"messages": [last.model_copy(update={"tool_calls": stamped})]})

    # 4. Fallback: two tool errors in a row hand the case to a person.
    def after_tools(state: MessagesState) -> Literal["agent", "fallback"]:
        recent = [m for m in state["messages"][-4:] if isinstance(m, ToolMessage)]
        errors = sum(1 for m in recent if m.status == "error")
        return "fallback" if errors >= 2 else "agent"

    def fallback(state: MessagesState):
        return {"messages": [AIMessage(content="I could not finish this safely. "
                                              "A billing specialist will follow up.")]}

    g = StateGraph(MessagesState)
    g.add_node("agent", agent)
    g.add_node("tools", ToolNode(tools, handle_tool_errors=True))
    g.add_node("approve", approve)
    g.add_node("fallback", fallback)
    g.add_edge(START, "agent")
    g.add_conditional_edges("agent", route)
    g.add_conditional_edges("tools", after_tools)
    g.add_edge("fallback", END)
    return g.compile(checkpointer=checkpointer)
Three details carry the governance. First, the allowlist runs before bind_tools, so an unapproved tool never reaches the prompt. Second, the interrupt saves the state through the checkpointer and waits until someone resumes it with Command(resume=...). That wait can last seconds or days, as the LangGraph interrupts documentation describes. Third, the approval node stamps the idempotency key from the thread id and invoice, instead of trusting the model to invent one.
A rejected write goes back to the agent as an error ToolMessage for every pending call. The model then explains the refusal to the user rather than retrying blindly.
Talk to Kanerika
Designing Approval Rules for Your Agents?
Walk through your workflow with Kanerika engineers and leave with a tool allowlist, an approval design and a read-only pilot scope.
Schedule a Demo →Persist State With a Checkpointer
Interrupts only work when the paused state survives. That makes the checkpointer a production requirement from day one.
The LangGraph persistence guide notes that InMemorySaver keeps checkpoints in RAM and loses them on restart. So use PostgresSaver in production, SqliteSaver on a laptop and InMemorySaver only in tests.
# run.py: production-style run with a Postgres checkpointer
# Written against langgraph 1.2.22 and langgraph-checkpoint-postgres (November 2026)
import asyncio
from langchain.mcp import MCPAdapter
from langgraph.checkpoint.postgres.aio import AsyncPostgresSaver
from langgraph.types import Command

from connect import MCP_CONFIG
from graph import build_graph

DB_URI = "postgresql://agent:***@db.internal:5432/agent_state"

async def main():
    async with MCPAdapter(MCP_CONFIG) as adapter, \
               AsyncPostgresSaver.from_conn_string(DB_URI) as saver:
        await saver.setup()                                  # creates tables on first run
        graph = build_graph(await adapter.list_tools(), saver)
        cfg = {"configurable": {"thread_id": "ticket-T-48213"}}   # one thread per conversation

        result = await graph.ainvoke(
            {"messages": [("user", "Why was customer C-1042 charged twice in October?")]}, cfg)

        if "__interrupt__" in result:                        # paused for approval
            print(result["__interrupt__"][0].value)          # show the reviewer the proposed write
            result = await graph.ainvoke(Command(resume={"approved": True}), cfg)

        print(result["messages"][-1].content)

asyncio.run(main())

# Local development: same code, different saver.
#   from langgraph.checkpoint.sqlite.aio import AsyncSqliteSaver
#   async with AsyncSqliteSaver.from_conn_string("checkpoints.db") as saver: ...
# Unit tests only: from langgraph.checkpoint.memory import InMemorySaver (gone on restart)
Give every conversation its own thread_id. Otherwise, reusing one id across customers mixes their histories, which is both a bug and a data leak.
The __interrupt__ key can also carry an elicitation request from an MCP server. In that case MCPAdapter drives the same interrupt loop, so one resume path handles both approvals and server questions.
Expose Your Graph as an MCP Server
The integration also runs in the other direction. Once the billing agent works, other teams may want to call it from their own agents or IDEs. In that case, MCP is the cleanest way to offer it.
LangSmith Agent Server exposes every deployed graph as an MCP tool at the /mcp endpoint over Streamable HTTP. Per the Agent Server MCP documentation, it supports protocol revisions 2024-11-05 through 2026-07-28, and the newest revision needs langgraph-api 0.18.0 or later.
{
  "dependencies": ["."],
  "graphs": {
    "billing_dispute_agent": {
      "path": "./agent.py:graph",
      "description": "Investigates duplicate charges and proposes credits for human approval"
    }
  },
  "env": ".env"
}
The description becomes the tool description that MCP clients see, so write it for the model that will choose the tool. Run the server locally with langgraph dev, and the endpoint answers at port 2024.
# Any MCP client can now call the agent. From another LangGraph app:
# Written against langchain[mcp] 1.5.0 (November 2026)
import asyncio
from langchain.mcp import MCPAdapter

async def main():
    async with MCPAdapter("http://localhost:2024/mcp") as adapter:   # single URL target
        agent_tools = await adapter.list_tools()
        print(agent_tools)

asyncio.run(main())
If a graph should never be callable this way, set disable_mcp to true in the http section of langgraph.json.
Worked Example: A Billing-Dispute Agent
Here is the same graph handling one real-looking case, step by step, from question to credit. The customer, amounts and ids are illustrative, but every step maps to code you have already seen.
The input is one question from a support ticket, asking why this customer was charged twice. Below is the path the graph takes, including the moment it stops and waits.
- Scope check. The agent node sees only three allowlisted tools, so the question cannot wander into payroll or HR systems.
- Read invoices. The model calls
billing_get_invoicesfor customer C-1042 and gets two $249 invoices dated October 1, 2026. - Read history. It calls
billing_get_ticket_historyand finds ticket T-48213 reporting the double charge. - Reconcile. Same customer, amount and date with two invoice ids points to a duplicate, and the model says so with both ids.
- Propose a credit. The model asks for
crm_issue_crediton INV-7790 for $249. - Pause for approval. The router sends the write to the approval node, the interrupt fires and the state is saved to Postgres.
- Idempotent write. A billing lead approves an hour later, the node stamps the key
ticket-T-48213:INV-7790, and the credit is applied once even if the call retries. - Trace and reply. The agent answers the customer, and the trace id ties the reads, the approval and the write together for audit.
Two things did not happen, and they matter more than the eight that did. The agent never moved money on its own, and a network retry could not double the refund.
The same pattern also fits any support case that ends in a write, such as a plan change, a shipping reissue or a password reset. More patterns like it appear in our collection of AI agent examples.
AI Assessment
Which of Your Workflows Are Ready for an Agent?
Score your data access, governance and team skills in a few minutes, and see which support or billing workflows you can automate safely first.
Start Your AI Assessment →Decision Framework: Direct API, Local MCP, Remote MCP or Hybrid
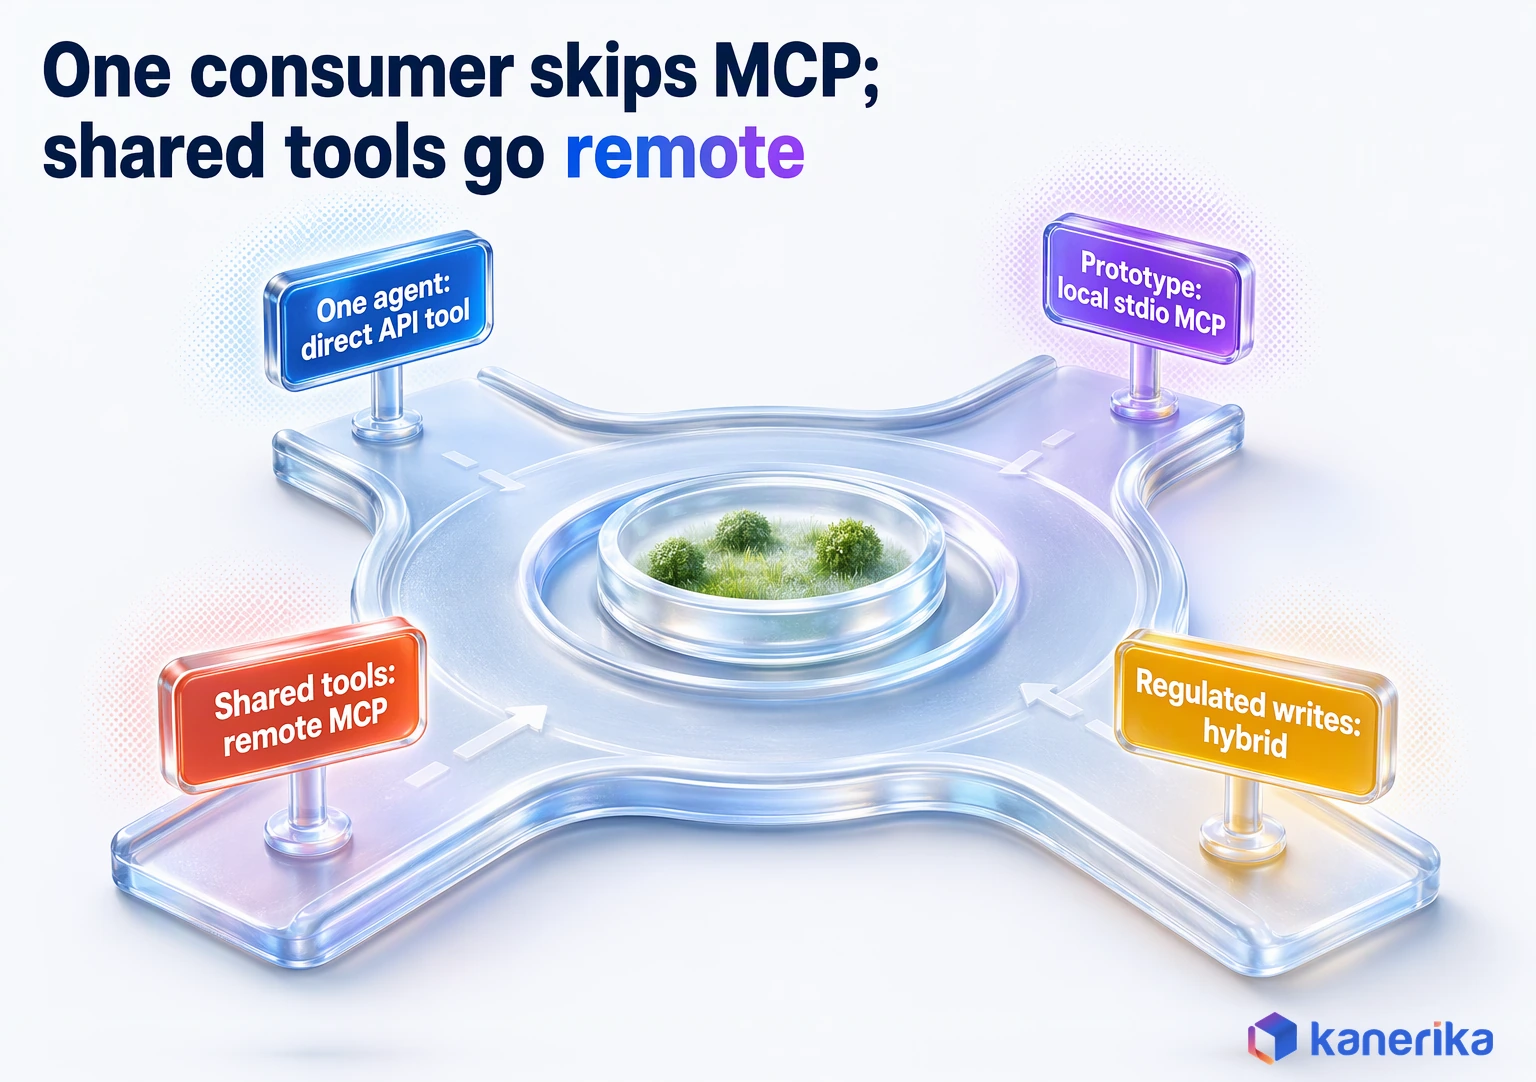
MCP is a good default for shared tools, but it is not free. Every server is one more service to run, secure and version, so the honest question is whether the sharing pays for that overhead.
A useful rule, then, is to count consumers and weigh risk. If one agent calls one internal system, a plain LangChain tool that wraps the API is simpler and faster to ship. Once several agents or teams need the same tools, however, a shared MCP server saves each of them from rebuilding the same connector.
| Scenario | Pick | Why |
|---|---|---|
| One internal tool used by one agent | Direct API tool | No server to run, because the tool lives in the graph’s code |
| Prototype or proof of concept | Local stdio MCP | Fast to start and easy to swap later, since nothing is deployed |
| Tools shared by several teams or agents | Remote Streamable HTTP MCP behind a gateway | One governed connector, one audit point, many consumers |
| Regulated writes such as payments or record changes | Hybrid: remote MCP for reads, a controlled direct write path with approval | Reads scale through MCP while writes keep a narrow, audited path |
Worked Decision: A Billing Agent Shared by Three Teams
Consider how that plays out when three support teams share one billing agent.
- Three teams need invoice and ticket reads, so a single remote MCP server avoids three copies of the same connector.
- The reads carry customer data, so the server sits behind a gateway that checks each caller’s identity.
- Credits move money, so they stay on a separate write server with a cap and an idempotency key.
- Every write passes through the LangGraph approval interrupt, whichever team’s agent proposed it.
- The verdict is hybrid: remote MCP for reads and a narrow, approved write path, which is exactly the build above.
When is MCP not worth it? If the tool has one consumer, no plans to share and a stable API, wrap the API directly. Then revisit the choice when a second team asks for it. Simple AI assistants for business that only answer questions rarely need MCP at all. Vendor-neutral patterns beyond LangGraph are covered in our guide to AI agent integration.
Common LangGraph MCP Errors and Fixes
Most failures in a LangGraph MCP integration come from version drift rather than from logic bugs. Old tutorials, two adapter packages and a fast-moving spec make it easy to copy code that no longer matches what is installed.
The table below collects the errors teams hit most often, especially the ones that come from outdated examples.
| Symptom | Cause | Fix |
|---|---|---|
Error when entering async with MultiServerMCPClient(...) | The client stopped being a context manager at 0.1.0 | Call await client.get_tools() directly, or move to MCPAdapter, which is a context manager |
| Deprecation warning on create_react_agent | LangGraph v1 deprecated it | Import create_agent from langchain.agents, or build an explicit StateGraph |
| An SSE server stops connecting | HTTP+SSE is deprecated and a url entry is treated as Streamable HTTP | Migrate the server, or pass Client(SSETransport(url)) to MCPAdapter for back-compat |
| Tool names do not match your allowlist | Multi-server configs prefix names as {server}_{tool} | Update allowlists and prompts to the prefixed names |
| A stdio server fails to start | Relative paths or a missing environment in the subprocess | Use absolute paths to the interpreter and the script, and pass the needed variables |
| The model sees a failed tool as a normal result | Tool errors arrive as data, while transport failures raise | Check ToolMessage status, and catch transport errors in the tool node or a fallback |
| Approvals vanish after a restart | InMemorySaver keeps state in process memory | Switch to PostgresSaver in production |
| pip install fails on Python 3.9 or 3.10 | LangChain packages need 3.10 or later, and langchain 1.5.0 needs 3.11 | Upgrade to Python 3.11 or later |
| LangChainBetaWarning on import | langchain.mcp is in beta | Expected; pin the version and test before each upgrade |
When the Error Is Not in the Table
When an error is not in the table, check versions first. Print the installed versions of langchain, langgraph, mcp and fastmcp and compare them with the labels on the code you copied.
If versions match and a tool still misbehaves, take the model out of the loop. Call the tool directly through MCPAdapter with the same arguments the agent sent. A failure there is a server problem, so no prompt change will fix it.
Governance, Security and Risk Controls
An agent with tools is a new kind of user in your systems. For that reason, it needs the controls you would give a new hire with billing access. The difference is speed: an agent can make a hundred bad calls before anyone notices one. Everything learned from machine learning governance still applies, with tools in place of models.
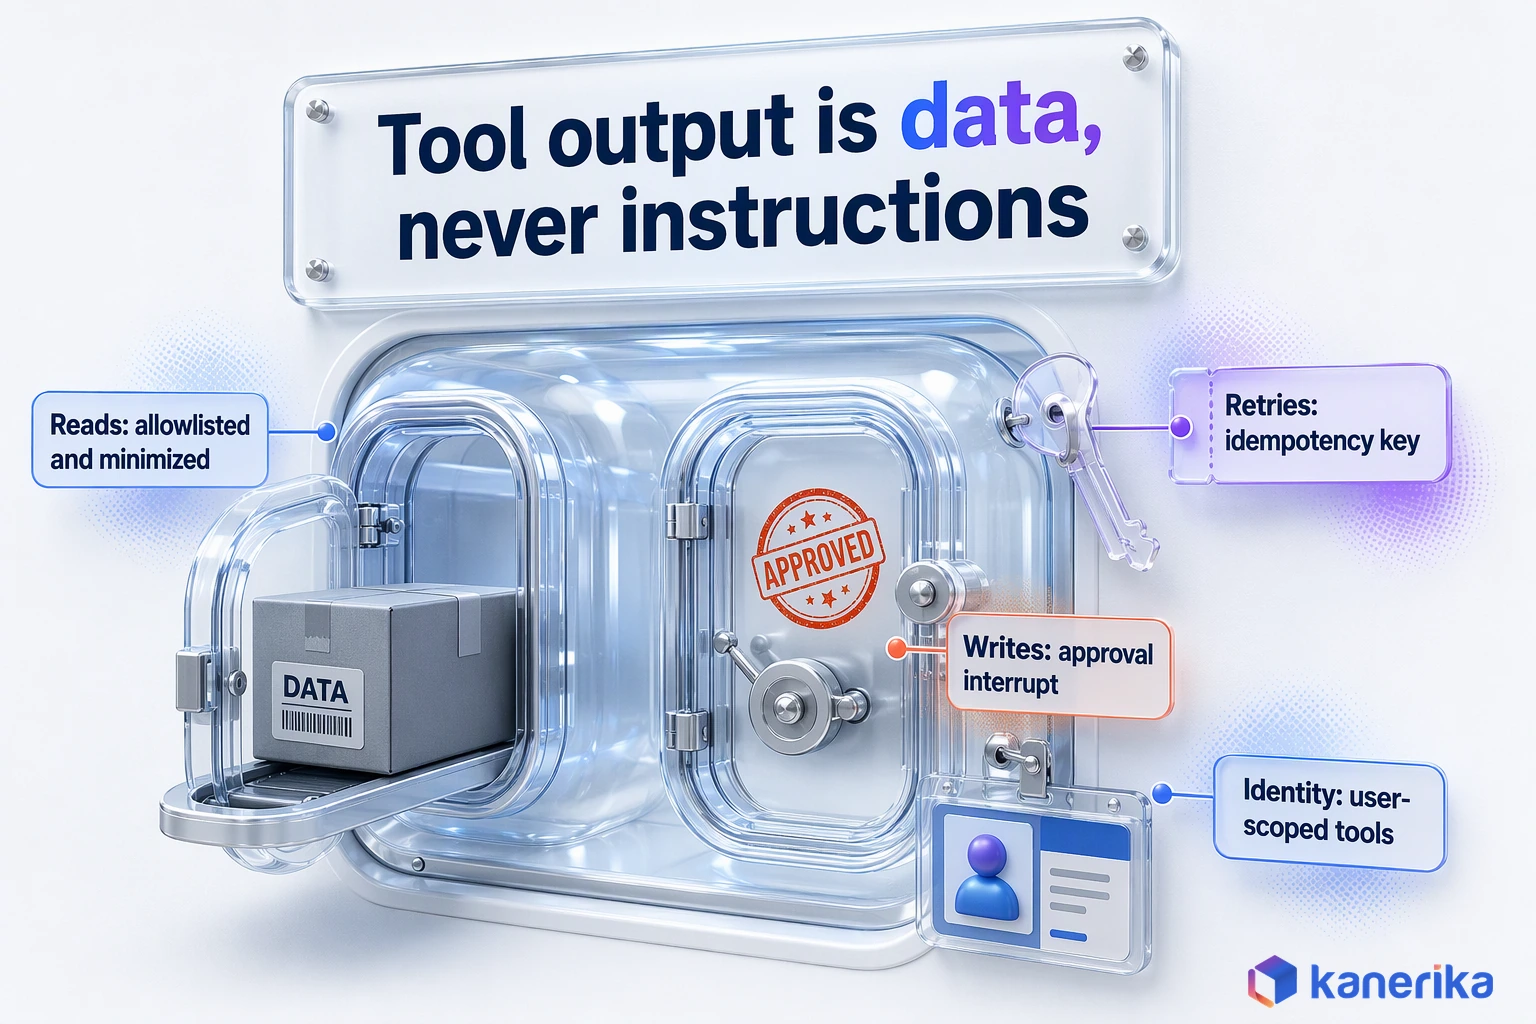
The central risk is that tool output flows straight back into the prompt, so it can steer the model. A ticket, an email or a web page returned by a tool can carry text that reads like an instruction. Therefore, treat every tool result as untrusted data and never as a command. The broader list of challenges that stall AI agents in production starts with this one for good reason.
| Risk | Control | Where it lives |
|---|---|---|
| Prompt injection through tool output | Treat results as data, strip instructions, keep writes behind approval | Output-minimizing step and approval node |
| Over-broad scopes | Per-agent tool allowlist and least-privilege credentials per server | Graph allowlist and MCP server config |
| Write replay and duplicate charges | Idempotency keys on every write tool | Approval node and write server |
| Schema drift between servers and agents | Contract tests and pinned server versions | CI pipeline |
| Missing audit trail | Redacted traces that link reads, approvals and writes | Tracing and observability layer |
| Lost user identity | Propagate the end user’s identity and use user-scoped MCP tools | Gateway and Agent Server |
Schema Drift, Traces and Identity
Schema drift is the quiet risk on this list, because nothing breaks loudly. A server team renames a field or tightens a type, and an agent that worked on Friday starts failing on Monday. Contract tests that call every tool with known inputs catch the change in CI, while pinned server versions stop it from reaching production unannounced.
Traces need the same care, but in the other direction. They should link each read, approval and write under one id. Even so, they must not copy full customer records into a log store with wider access than the CRM.
Identity deserves a closer look as well. If every call reaches the CRM as one service account, the audit log cannot tell which customer request caused which change. To fix that, the new adapter moved authentication onto the FastMCP client, which supports both per-server and per-user auth. Agent Server also supports user-scoped MCP tools.
A gateway in front of the remote servers is the natural place to enforce all of this. It can check the caller, apply rate limits and log every tool call in one format. As a result, each MCP server does not need its own copy of the same rules. Platform gateways follow the same idea, as our look at the Databricks Unity AI Gateway shows.
Five Mistakes That Turn a Demo Into a Liability
Each mistake below is the absence of one control from the table above, which is why none is hard to fix before launch. Every one of them is expensive to fix after an incident.
- Binding every tool a server exposes, instead of an allowlist per agent.
- Letting the model decide when a write is safe, instead of an interrupt.
- Retrying writes without an idempotency key.
- Logging full tool payloads, customer data included, into traces.
- Running production on InMemorySaver, so a restart drops every pending approval.
On-Demand Webinar
The Real Cost of LLM Security Risks and How to Reduce Them
A recorded Kanerika session on the security risks that LLM applications create and the controls that reduce them, from data exposure to misuse.
Watch the Webinar →Deployment Options
Where you run the graph decides how much of the plumbing you own, so decide it early. The three common choices trade convenience for control, and the right one depends on where your data and security team already live.
LangSmith Agent Server is the shortest path if you want the /mcp endpoint and managed checkpointing out of the box. AWS Bedrock AgentCore suits teams that have standardized on AWS. According to the AgentCore developer guide, it works with any framework, LangGraph included, and its Gateway supports remote MCP servers. Self-hosting gives full control, at the cost of running Postgres, scaling and tracing yourself.
| Option | What you get | What you own |
|---|---|---|
| LangSmith Agent Server | /mcp endpoint, checkpointing, user-scoped MCP tools | Graph code, server configs, approvals |
| AWS Bedrock AgentCore | Framework-agnostic runtime with LangGraph support; Gateway for remote MCP servers | Graph code, IAM design, MCP server hosting |
| Self-hosted containers | Docker Compose for development, Kubernetes for production | Everything: checkpointer database, scaling, tracing, upgrades |
Whichever you pick, keep the MCP servers deployable on their own. That way the same billing server can serve a LangGraph agent today and a different framework tomorrow. For a wider view of the surrounding stack, see our roundup of agentic AI tools. Framework trade-offs beyond LangGraph are in our guide to AI agent frameworks.
How Kanerika Delivers LangGraph MCP Agents in Stages
Kanerika builds agents the way this guide does: read first, write later, and only after each stage passes a gate. The staging is what keeps a pilot from turning into an incident.
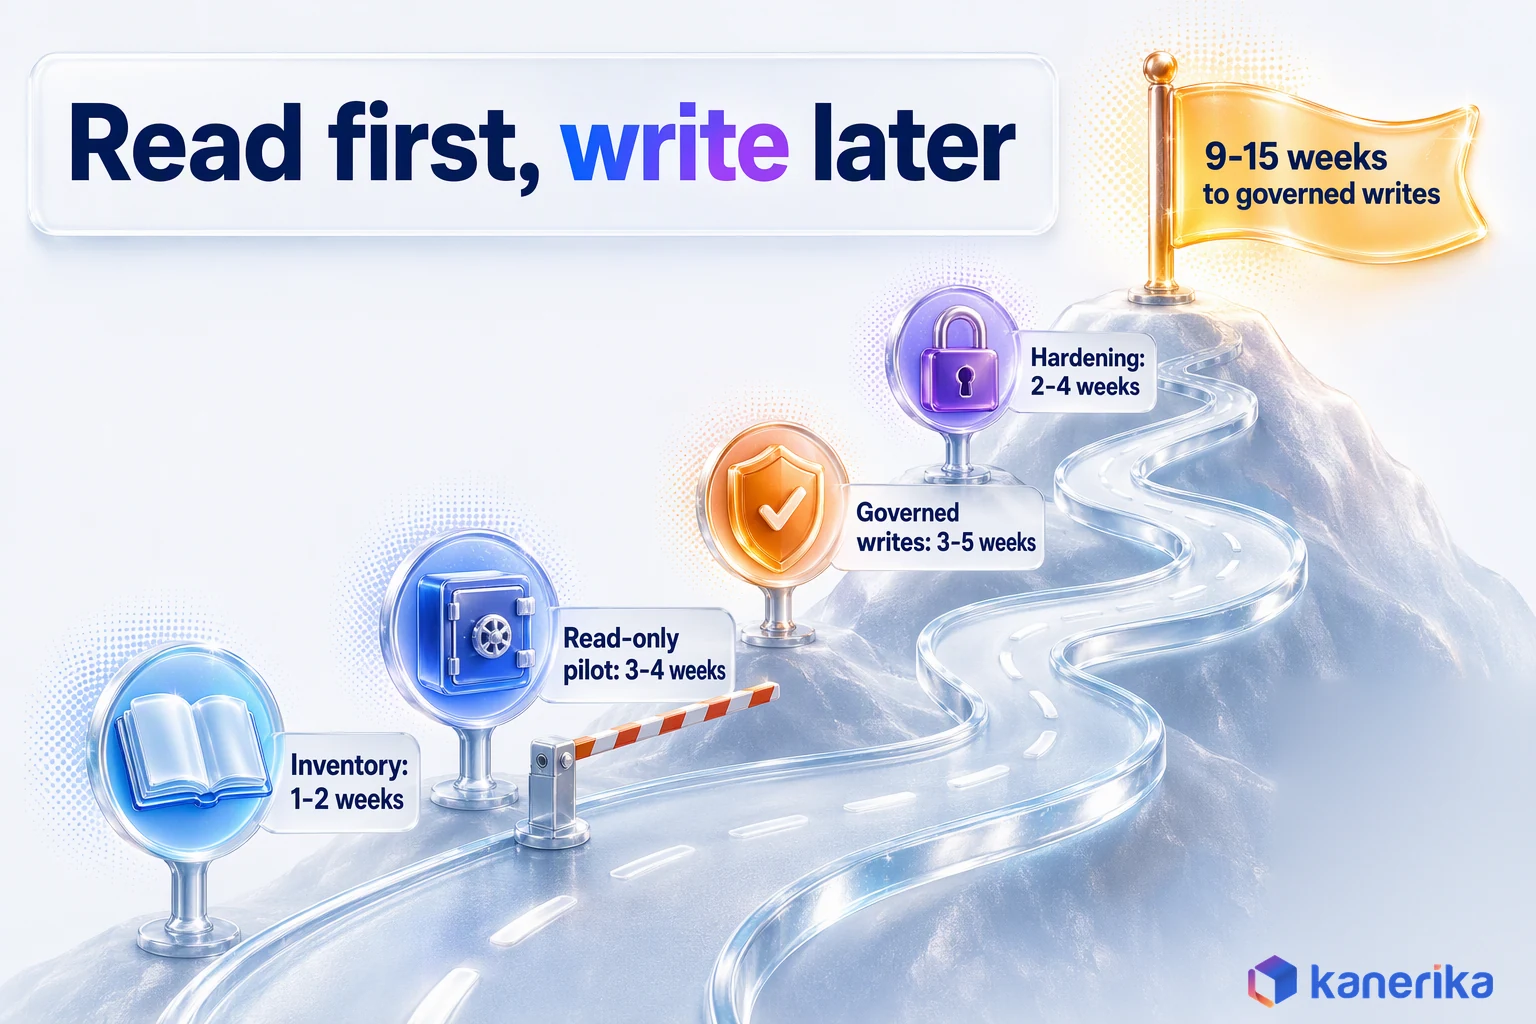
The first conversation is about the workflow rather than the framework. We map which systems the agent must read, which actions it may take and who approves them. Then we pick the types of AI agents that fit each workflow. The agentic AI consulting and development team then delivers in five stages.
| Stage | Output | Gate to the next stage |
|---|---|---|
| 1. Use case and tool inventory | Workflow map, tool list, risk class per tool | Owners sign off on scopes and approvers |
| 2. Read-only pilot | MCP read servers, graph, checkpointer, evals | Answer quality meets the agreed target on real tickets |
| 3. Governed writes | Write servers, approval interrupts, idempotency | No duplicate or unapproved writes in testing |
| 4. Hardening | Evals in CI, observability, redacted tracing | Security review passed before launch |
| 5. Scale | More servers, more teams, user-scoped tools | Each new tool repeats stages 1 to 3 |
Effort by Stage
Teams always ask how long this takes before they commit. The ranges below are planning ranges from Kanerika delivery practice, scoped per project, and they assume the source systems already have usable APIs.
| Stage | Typical range | What moves it |
|---|---|---|
| Use case and tool inventory | 1 to 2 weeks | Number of systems as well as approvers |
| Read-only pilot | 3 to 4 weeks | Data access and eval set quality |
| Governed writes | 3 to 5 weeks | Number of write tools and approval rules |
| Hardening | 2 to 4 weeks | Security review depth |
| Scale | 1 to 2 weeks per new server | Reuse of existing patterns, such as approval nodes |
Adding the first four stages gives 9 to 15 weeks to governed writes in production. The read-only pilot often shows value well before that, which is why it comes first.
Case Study: 80% Ticket Auto-Response With an LLM Support Agent
The billing example generalizes a pattern Kanerika has delivered in support automation. The client, a B2B SaaS company, serves SMB clients in more than 40 countries. It faced rising support costs, trouble retaining skilled staff and a flood of repetitive tickets.
Kanerika first built a knowledge base from historical tickets, then an LLM-based ticket resolution system on top of it. The client reached 80% auto-response on tickets, cut staffing costs by 70%, halved ticket resolution time and saw a 30% rise in customer satisfaction.
That project predates the build in this guide and did not use LangGraph or MCP. It shows the same principle, though: automate the reads and answers first, and add actions once the answers are trusted.
Case Study
80% Ticket Auto-Response With an LLM Support Agent
A B2B SaaS company serving SMB clients in 40+ countries reached 80% ticket auto-response, 70% lower staffing costs and 50% faster resolution with an LLM ticket-resolution system.
Read the Case Study →Final Recommendation: Build the Smallest Governed Integration That Proves Value
The fastest route to a production agent is a small one. Pick one workflow, connect it read-only and add a single approved write only when the reads have earned trust.
- Pick one workflow with a clear owner, such as billing disputes.
- Build read-only MCP servers and connect them with MCPAdapter over Streamable HTTP.
- Wire an explicit StateGraph with an allowlist and a PostgresSaver checkpointer.
- Add one write tool behind an interrupt, with a cap and an idempotency key.
- Measure answer quality on real cases, then expand server by server.
So, how do you build a LangGraph MCP integration in 2026? Use langchain.mcp’s MCPAdapter over Streamable HTTP, keep state in a checkpointer, and put every write behind an approval interrupt.
Frequently Asked Questions
What are LangChain MCP adapters?
LangChain MCP adapters convert tools published by MCP servers into LangChain tools that a LangGraph agent can bind and call. The standalone langchain-mcp-adapters package with MultiServerMCPClient is no longer actively maintained. New code should install langchain[mcp] 1.4.0 or later and use MCPAdapter from langchain.mcp, which is in beta, so pin the version.
What is a LangGraph MCP server?
A LangGraph MCP server is any MCP server whose tools your graph consumes, such as a billing database reader or a CRM writer. It publishes tool names, descriptions and input schemas over stdio or Streamable HTTP. The graph discovers those tools through MCPAdapter, filters them with an allowlist and decides when each one runs.
How do I test LangGraph MCP integration before production?
Run the MCP servers locally with stand-in data and test each tool on its own first. Then run the graph against a set of real past cases and score the answers. Add contract tests for every tool schema, test the approval interrupt and resume path, and confirm that retried writes stay idempotent.
How do I prevent prompt injection from MCP tool responses?
Treat every tool result as untrusted data, never as an instruction. Return only the fields the next step needs, strip or flag instruction-like text, and keep the allowlist tight so a hijacked prompt cannot reach new tools. Most important, put every write behind an approval interrupt, so injected text cannot move money or change records.
How do I authenticate users across LangGraph and MCP servers?
Propagate the end user’s identity from the request into the graph instead of sending every call through one service account. With langchain.mcp, authentication lives on the FastMCP client, which supports per-server and per-user auth. Agent Server supports user-scoped MCP tools, so audit logs can show which person triggered each tool call.
Can a LangGraph agent itself be exposed as an MCP server?
Yes. LangSmith Agent Server exposes each deployed graph as an MCP tool at the /mcp endpoint over Streamable HTTP. It supports protocol revisions from 2024-11-05 through 2026-07-28, and the newest revision needs langgraph-api 0.18.0 or later. The graph’s description field in langgraph.json becomes the tool description that MCP clients see. Disable it with disable_mcp when needed.
How do you add a human-in-the-loop checkpoint in LangGraph?
Call interrupt() inside a node, usually an approval node placed before any write tool. LangGraph saves the state through the checkpointer and pauses the run. A reviewer then resumes it with Command(resume=…), passing approval, edits or a rejection. Use PostgresSaver in production so a pending approval survives restarts and can wait for hours or days.
How does Kanerika use LangGraph and MCP in enterprise deployments?
Kanerika delivers agents in stages. Teams start with a use case and tool inventory, then build a read-only pilot on MCP servers. Governed writes come next, with approval interrupts and idempotency keys, followed by hardening through evals, observability and redacted tracing. Each new server or team repeats the same gates before it reaches production.
How do I connect LangGraph to an MCP server?
Install langchain[mcp], then open MCPAdapter with an mcpServers config that lists each server by URL or command. Inside the async with block, await adapter.list_tools() to get LangChain tools. Filter them with an allowlist, bind them to your model and add a ToolNode to the StateGraph. The transport is inferred from each entry.
Does LangGraph support MCP directly, or do I need an adapter?
LangGraph itself does not speak MCP, so you need an adapter between the graph and the servers. The supported option is MCPAdapter in langchain.mcp, which ships with LangChain under the mcp extra. The older langchain-mcp-adapters package still installs at version 0.3.2, but it is no longer actively maintained and should be migrated.
Should I use MCP or connect LangGraph directly to APIs?
Use a direct API tool when one agent calls one internal system and nobody else needs it. Choose MCP when several agents or teams share the same tools, because one governed server replaces many copies of a connector. For regulated writes, a hybrid works well, with MCP for reads and a narrow approved write path.
Which MCP transport should I use with LangGraph?
Use Streamable HTTP for anything shared, remote or in production, ideally behind a gateway that checks identity. Use stdio for local development, where the server runs as a subprocess on your own machine. Avoid HTTP+SSE for new servers, since the specification deprecated it, and move WebSocket servers to Streamable HTTP before migrating.
Can LangGraph connect to multiple MCP servers?
Yes. List each server under mcpServers in one MCPAdapter config, mixing local stdio and remote Streamable HTTP entries as needed. MCPAdapter prefixes every tool name with its server name, such as billing_get_invoices, so tools with the same name never collide. Update your allowlists and prompts to use those prefixed names consistently.