TL;DR
In LLM vs vLLM, pick a hosted LLM API for low or spiky traffic and vLLM for steady, high-volume open-weight serving. The LLM is the model that writes the answer, while vLLM is open-source software from UC Berkeley that runs open-weight models on your own servers. Its PagedAttention design cuts KV cache waste to near zero and gave 2-4x the throughput of FasterTransformer and Orca at the same latency. The famous 24x figure comes from a June 2023 test against Hugging Face Transformers, so treat it as history rather than a promise. The engine has no license fee, but you still pay for hardware, operations staff and idle capacity. Self-host only when your measured cost per 1M tokens beats the cheapest hosted model that meets your quality bar.
Key Takeaways
- An LLM is the model that writes answers, while vLLM is open-source software that serves open-weight models.
- PagedAttention and continuous batching cut KV cache waste to near zero, so GPUs stay busy.
- The 24x figure is a June 2023 test against Hugging Face Transformers, while 2.7x compares vLLM v0.6.0 with v0.5.3.
- Closed models such as GPT-6.1 Sol or Claude Opus 5.5 cannot run on vLLM, because their weights are private.
- The cheapest hosted models priced in this guide charge $0.50 per 1M output tokens, so self-hosting must beat that.
- Before production, vLLM needs a gateway, pinned versions and a team that owns uptime.
Fifty Users, One GPU and a Chatbot That Crawled
Picture a product team that ships an internal chatbot on one rented GPU. Ten testers love it, but on launch morning 50 colleagues log in at once and every answer stalls. Beyond engine choice, LLM inference optimization covers how to cut that latency and cost without losing quality.
Nobody changed the model, the prompts or the GPU. What changed is how many requests the serving software must juggle at the same time, and a plain generate loop juggles them badly.
That gap is the real subject of LLM vs vLLM. This guide separates the model from the engine, then shows when vLLM pays off and when a hosted API wins.
LLM vs vLLM: The Short Answer
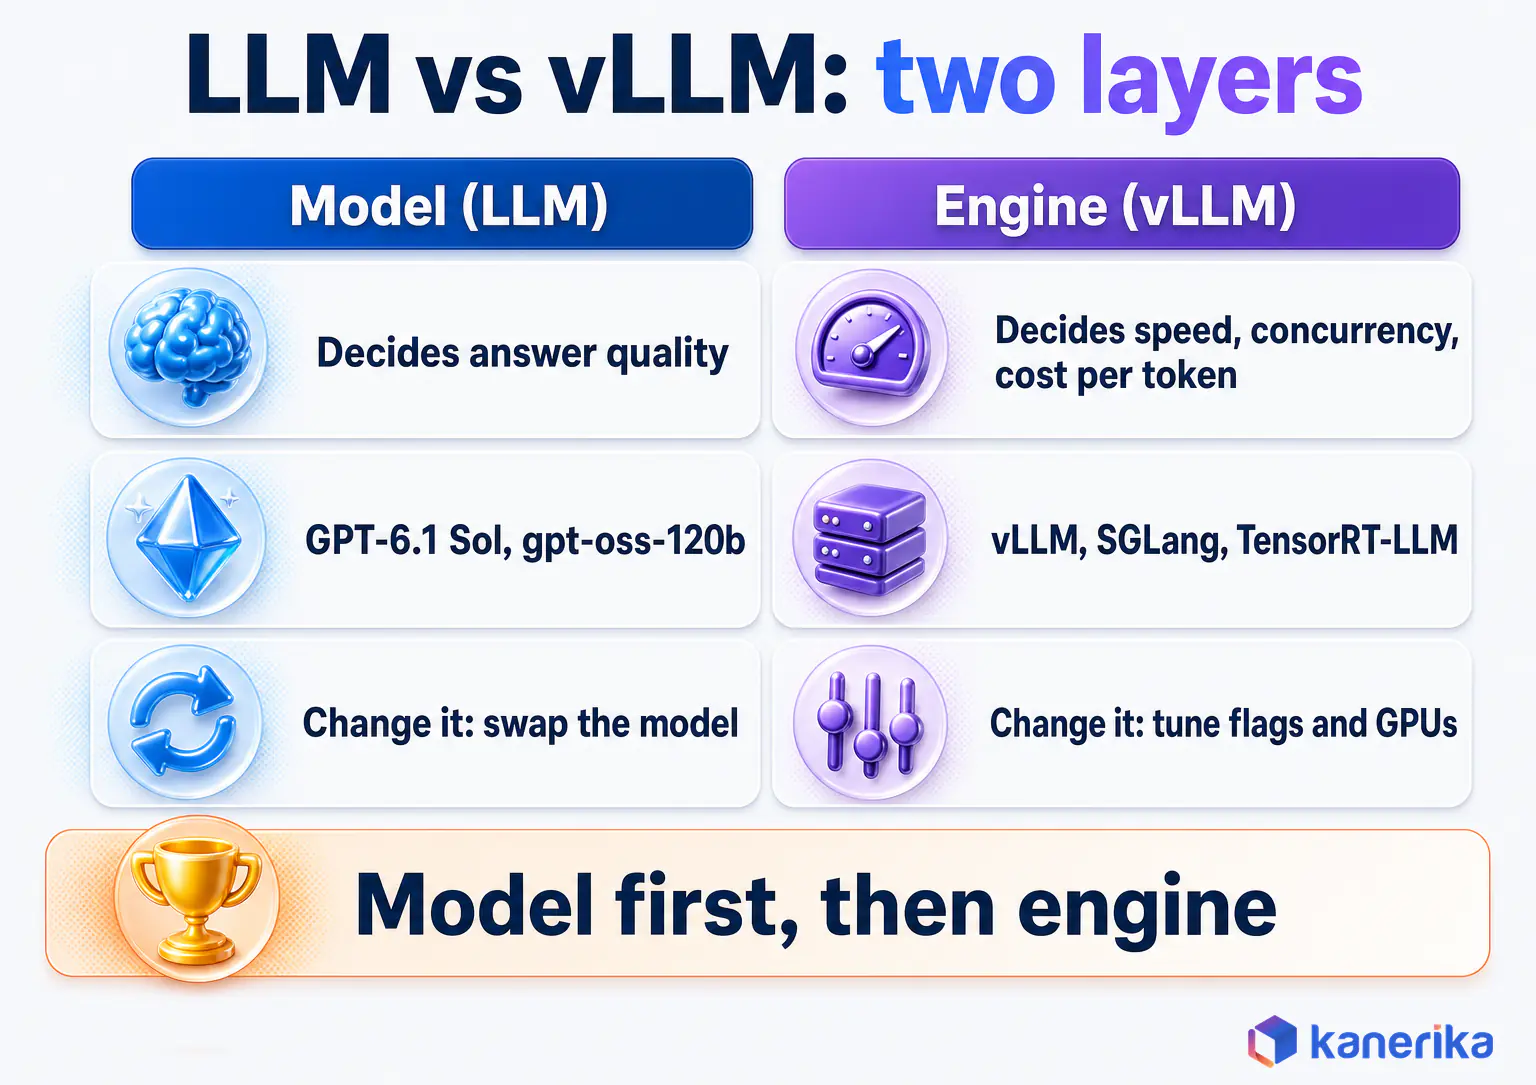
An LLM and vLLM sit on different layers of the same stack, so you usually need both. The LLM is the trained model, while vLLM is the software that serves an open-weight model to many users at once.
Think of a restaurant. The LLM is the recipe, so it decides how good the dish tastes, while vLLM is the kitchen that cooks it for 500 diners without long waits.
| Layer | What it is | Examples | What it decides |
|---|---|---|---|
| Model (LLM) | Trained weights that predict the next token | GPT-6.1 Sol, gpt-oss-120b, Qwen3.8-27B | Answer quality and reasoning |
| Serving engine | Software that runs the weights for many users | vLLM, SGLang, TensorRT-LLM | Speed, concurrency, cost per token |
| Hardware | The chips that do the math | NVIDIA H100, A100, L4; AMD and Intel GPUs | Capacity and memory ceiling |
| Interface | The API your app calls | OpenAI-compatible endpoint | How much app code changes |
So you cannot swap a model for an engine. Pick the model first for quality, then pick the engine that serves it at the speed and price you need.
What an LLM Is
A large language model is a set of trained weights. During inference it reads your prompt and predicts one token at a time, while training builds those weights once. Our guides to AI inference vs training and how LLM training works cover both halves.
Hosted models such as GPT-6.1 Sol and Claude Opus 5.5 run only behind their vendors’ APIs. Open-weight models such as gpt-oss-120b, Mistral Large 4 and Qwen3.8-27B publish their weights, so you can run them yourself on vLLM.
What Is vLLM?
vLLM is an open-source inference and serving engine for large language models. It writes no answers itself; instead, it makes an open-weight model respond faster and serve more people per GPU.
The project started at UC Berkeley and launched on June 20, 2023, with a launch post on the vLLM blog. Because it ships under the Apache 2.0 license, companies can use it commercially without a fee.
No official expansion of the name could be verified, but the “v” is widely read as “virtual”. That points to the virtual-memory idea behind PagedAttention, described in the SOSP 2023 PagedAttention paper and in our explainer on what virtual large language models are.
The project at a glance, from its GitHub repository and releases page on November 3, 2026:
- License: Apache 2.0, free for commercial use.
- Community: more than 2,000 contributors and over 96,000 GitHub stars.
- Latest release: v0.33.0, published November 2, 2026.
- Coverage: more than 200 model architectures, GPT-OSS among them.
- Interfaces: OpenAI-compatible server, Anthropic Messages API and gRPC.
Since the server speaks OpenAI’s API format, most apps can switch to a self-hosted model by changing a base URL and a key.
Kanerika Service
LLM Development Services
Kanerika builds LLM applications, including models deployed on your own infrastructure.
Explore LLM DevelopmentStandard LLM Inference vs vLLM: Comparison Table
The fair baseline for vLLM is a plain Hugging Face Transformers generate loop. That loop suits one user in a notebook, but it was never built to share a GPU among dozens of requests.
The differences below grow as traffic rises, so a quiet demo rarely exposes them.
| Aspect | Standard inference (Transformers loop) | vLLM |
|---|---|---|
| KV cache memory | Large reserved block, much of it unused | Small pages with near-zero waste |
| Batching | Static batches wait for their slowest request | Continuous: requests join as others finish |
| Throughput under load | Falls as users queue | Up to 24x Transformers in the June 2023 launch test |
| Latency under load | Climbs once the batch is full | Steadier, since nobody waits for a full batch |
| API | Your own wrapper code | OpenAI-compatible server built in |
| Hardware | Any PyTorch device | NVIDIA, AMD and Intel GPUs, CPUs, plus TPU and other chips via plugins |
| Setup effort | A few lines of Python | One install and serve command, then operations |
| Best for | Research and single-user tools | Shared, multi-user production serving |
How vLLM Makes LLM Inference Faster
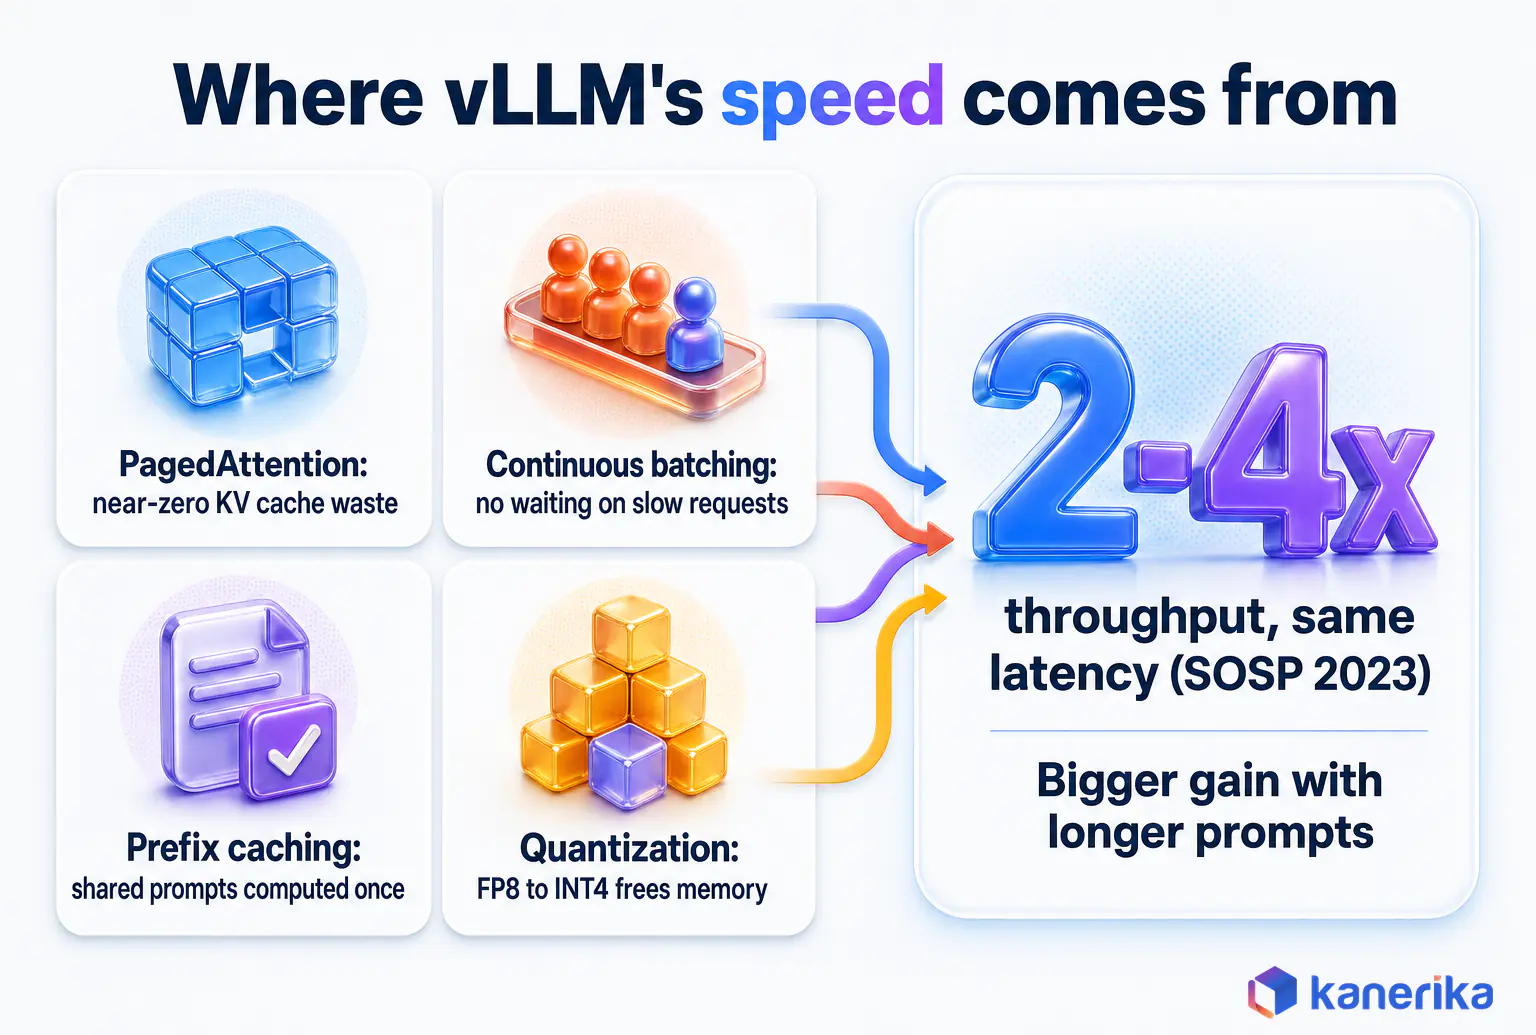
vLLM gets its speed from a few ideas that attack wasted GPU memory and idle compute rather than changing what the model says. Most target the KV cache, the attention data each request stores while generating, which our guide on how the KV cache works explains.
PagedAttention
PagedAttention splits each request’s KV cache into small fixed-size blocks, much as an operating system pages memory. A block table tracks them, so almost nothing sits reserved and idle.
The numbers show why this matters. The vLLM launch post found that older systems wasted 60% to 80% of KV cache memory through fragmentation and over-reservation. With PagedAttention, waste falls under 4%, so one GPU can batch many more requests.
Continuous Batching
New requests join the running batch as soon as another one finishes, instead of waiting for the whole batch to end. Picture one user asking for a long report while another wants a one-word label.
With static batching, the label waits for the report. With continuous batching it returns at once, a queued request takes its slot, and the GPU stays busy.
Prefix Caching and Chunked Prefill
Prefix caching reuses work for a shared prompt start, such as a long system prompt. Chunked prefill splits a huge prompt into pieces, so it does not stall other users.
Quantization and Speculative Decoding
Quantization stores weights in fewer bits, with FP8, MXFP4, NVFP4, INT8, INT4, GPTQ, AWQ and GGUF supported, so more users fit in memory. Speculative decoding drafts tokens cheaply and then checks them in one pass. The engine also serves many LoRA adapters on one base model, which suits teams using parameter-efficient fine-tuning.
Multi-GPU Parallelism
When a model outgrows one GPU, vLLM splits it. The vLLM parallelism guide shows --tensor-parallel-size 4 splitting each layer across four GPUs. Adding --pipeline-parallel-size 2 also cuts the layer stack into two stages, for eight GPUs in all. Larger models can span several nodes.
For the full mechanism, see how PagedAttention and virtual LLM serving work, since this post asks whether that speed justifies your own servers.
LLM vs vLLM Performance: What the Benchmarks Actually Show
Every vLLM speed claim traces back to a test with a specific model, GPU and baseline. Quote a number without its setup, and teams end up expecting gains they never see.
The three most repeated numbers come from three different experiments:
| Result | Compared against | Model and GPU | Date | Source |
|---|---|---|---|---|
| Up to 24x throughput (up to 3.5x vs TGI) | Hugging Face Transformers; TGI | LLaMA-7B on A10G, LLaMA-13B on A100 40GB, ShareGPT lengths | June 20, 2023 | vLLM launch blog |
| 2-4x throughput at the same latency | FasterTransformer and Orca | Paper’s test models; gain grows with longer sequences and larger models | SOSP 2023 | PagedAttention paper |
| 2.7x throughput, 5x faster TPOT | vLLM v0.5.3 | Llama 3 8B on one H100 | September 5, 2024 | vLLM v0.6.0 update |
In the last row, 2.7x is vLLM against an older vLLM, not against a plain LLM setup. So it measures progress between releases.
The paper also says gains grow with longer sequences and bigger models, so a light, short-prompt workload will see less. To get your own number, measure four metrics at production concurrency:
- TTFT (time to first token): the wait before an answer starts.
- TPOT (time per output token): the average gap between streamed tokens.
- ITL (inter-token latency): the delay between tokens, felt as stutter when it spikes.
- Throughput: total tokens per second.
The vllm bench serve command reports all four, per its benchmark CLI docs. Since repeated runs can reuse the prefix cache and flatter results, vary prompts between runs, and check quality with an LLM evaluation framework.
Which LLMs Can You Run on vLLM in 2026?
vLLM can only serve models whose weights you can download. GPT-6.1 Sol, Claude Opus 5.5 and Gemini 4 Argon keep theirs private, so they stay API-only.
Open-weight models fill the rest of the menu, so licenses matter as much as size. Here are widely used options as of November 3, 2026:
| Model | Weights license | Size note |
|---|---|---|
| gpt-oss-120b | Apache 2.0 | 117B (5.1B active); fits one 80GB GPU such as an H100 |
| gpt-oss-20b | Apache 2.0 | 21B (3.6B active); runs within 16GB of memory |
| Mistral Large 4 | Mistral Ecosystem Open-Weight License; model-as-a-service operators need a commercial license | Hugging Face card recommends vLLM |
| Mistral Small 4 | Apache 2.0 | 119B (6.5B active) |
| Qwen3.8-27B | Apache 2.0 | 262,144-token native context |
| DeepSeek V4.1-Flash-1017 | MIT | Also sold as a low-cost API |
| GLM-5.3 | Custom license | Check terms before commercial use |
Support changes with each release, so check vLLM’s supported-models list before you buy hardware. The README names GPT-OSS and the Mistral Large 4 card names vLLM, but test the rest yourself.
For a wider survey, see our roundups of open-source LLMs and small language models, while Opus vs Mistral walks through the closed-versus-open trade in detail.
Checklist
Generative AI Checklist
Check data readiness, model choice, security and governance before you commit budget.
Get the Checklist →Cost: Hosted LLM API vs Self-Hosted vLLM
vLLM itself is free, but serving a model with it is not. You pay for GPUs, storage, networking and staff, whereas a hosted API folds all of that into one price per token.
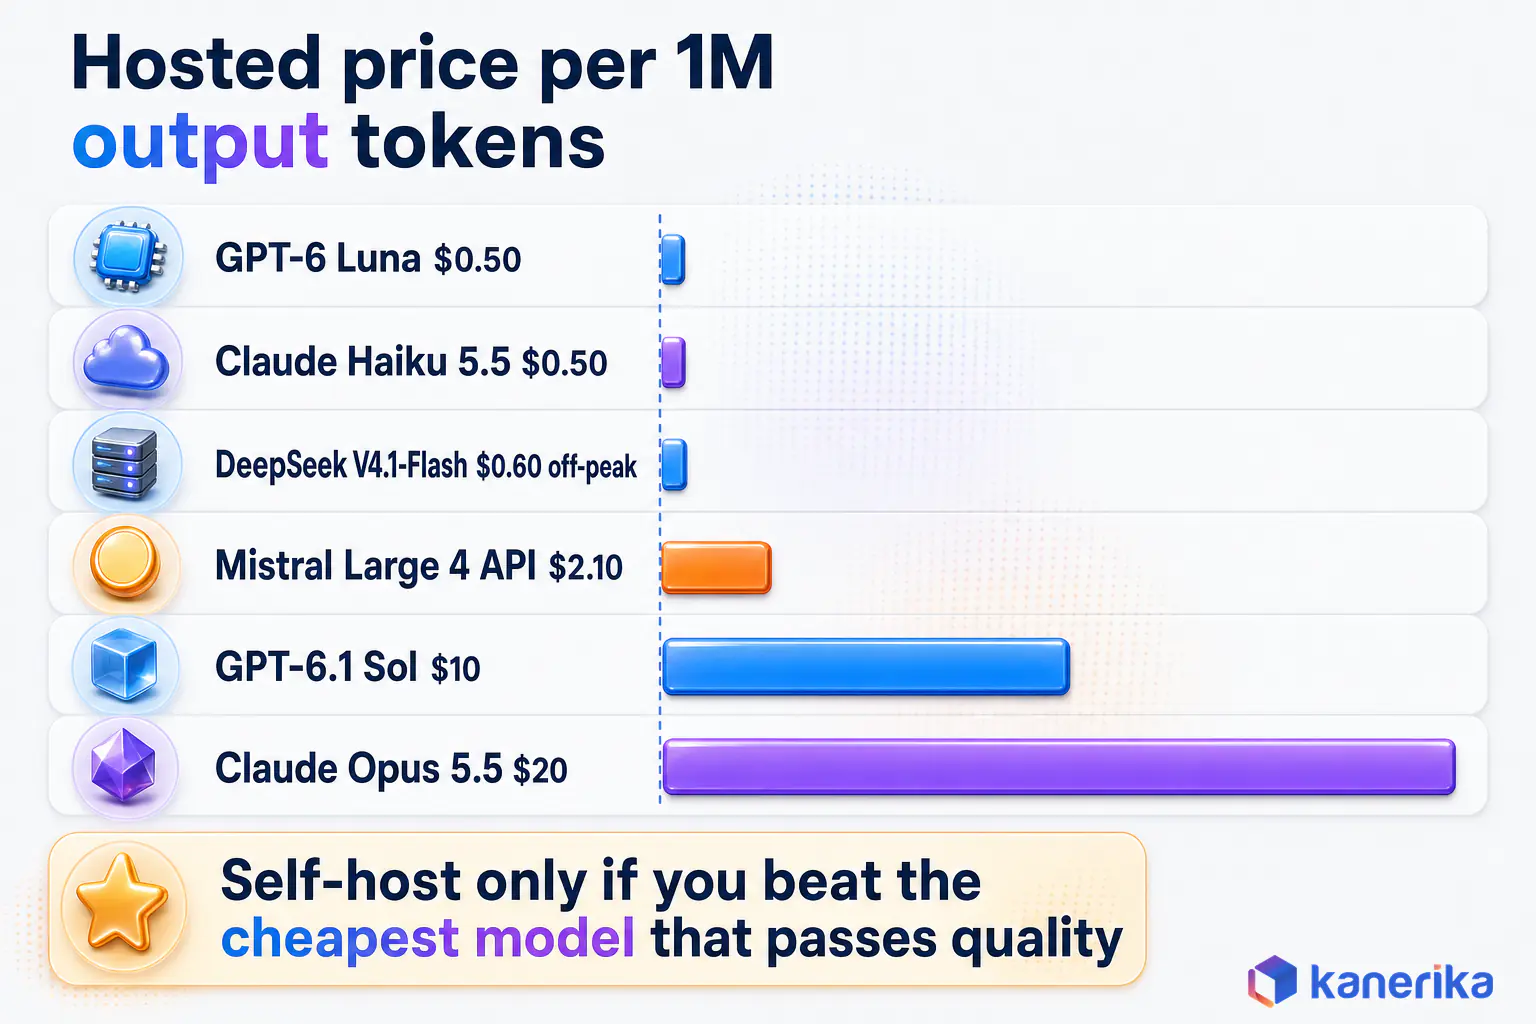
Hosted prices set a hard bar for self-hosting, so start there. Here are list prices per 1M tokens, read from vendor pages on November 2-3, 2026:
| Hosted model | Input per 1M | Output per 1M | Note |
|---|---|---|---|
| GPT-6 Luna | $0.10 | $0.50 | Lowest listed output price |
| Claude Haiku 5.5 | $0.10 | $0.50 | Prompts up to 100K tokens |
| DeepSeek V4.1-Flash | $0.15 | $0.60 | Off-peak rate |
| Mistral Large 4 (API) | $0.70 | $2.10 | Same model is open-weight |
| GPT-6.1 Sol | $2 | $10 | Closed weights |
| Gemini 4 Argon | $2 | $10 | $4 and $20 from December 1, 2026 |
| Claude Opus 5.5 | $4 | $20 | Closed weights |
For example, at list output prices, one billion output tokens a month costs $500 on GPT-6 Luna but $10,000 on GPT-6.1 Sol. The bar to beat is therefore the cheapest model that meets your quality needs.
A Four-Step Method to Compare Costs
GPU hourly prices swing too widely by cloud, region and commitment to quote here, so work from your own numbers:
- Log real monthly token volume, split into input and output, over several weeks.
- Then price that volume on the cheapest hosted model that passes your quality tests.
- Measure your own vLLM tokens per second at target concurrency, especially at real GPU utilization.
- Finally, compare cost per 1M tokens, including idle hours, redundancy, storage and staff time.
Self-hosting tends to win under steady, high volume or when rules call for a private LLM deployment. For spiky loads, though, the OpenAI API and its peers usually stay cheaper. In any case, review GPU spend in your cloud cost management process like any other line item.
vLLM vs SGLang, TensorRT-LLM, TGI, Ollama and llama.cpp
vLLM is one of several serving engines, and the right one depends on your hardware and user count. Some rivals chase peak speed on one vendor’s GPUs, while others target a laptop.
Status comes from each project’s GitHub page on November 3, 2026, because an engine that stops shipping is a risk you inherit.
| Engine | Best for | Status (November 3, 2026) |
|---|---|---|
| vLLM | Multi-user serving on many GPU types | v0.33.0, November 2, 2026 |
| SGLang | High-throughput serving | v0.5.23, November 2, 2026 |
| TensorRT-LLM | Peak performance on NVIDIA GPUs only | v1.4.0rc2 pre-release, October 28, 2026 |
| Hugging Face TGI | Existing deployments only | Archived, maintenance mode; recommends vLLM and SGLang |
| Ollama | Local, single-machine use | v0.40.14, November 3, 2026 |
| llama.cpp | C/C++ inference on CPUs and laptops | Open-source project |
| llm-d | Orchestrating many vLLM replicas | v1.0.0, October 20, 2026; runs vLLM |
Ollama or llama.cpp suit one developer on one machine, while TensorRT-LLM fits teams all-in on NVIDIA. For shared serving across many users, pick vLLM or SGLang instead.
Our deeper comparisons also cover SGLang vs vLLM, vLLM vs Ollama and other vLLM alternatives. Since TGI’s repository is archived, teams still running it should plan a move.
Talk to Kanerika
Not Sure Which Serving Engine Fits?
Get an LLM serving assessment: hosted API, vLLM or hybrid, sized to your workload.
Get an LLM Serving Assessment →When to Use vLLM, a Hosted LLM API, or Both
The choice between vLLM and a hosted LLM API comes down to volume, data rules and your team. It is rarely permanent, though, and a mix of both often fits best.
Choose vLLM when:
- Traffic is steady and high, so GPUs stay busy.
- Data residency or privacy rules keep the model inside your network.
- An open-weight model already meets your quality bar.
- Your team can run GPUs, patch software and carry on-call duty.
Choose a hosted LLM API when:
- Volume is low or spiky, so owned GPUs would sit idle.
- You need the strongest closed model, such as GPT-6.1 Sol or Claude Opus 5.5.
- Nobody on the team wants to own GPU infrastructure.
A hybrid splits work by difficulty. Hard reasoning goes to a hosted frontier model, while routine, high-volume calls such as classification, extraction and RAG pipeline answers go to vLLM. A gateway in front decides where each request goes.
Model size also matters, as our comparison of SLMs vs LLMs shows. For the quality side, see choosing an enterprise LLM, and for retrieval-heavy designs, RAG development works on either route.
From Prototype to Production with vLLM, Step by Step
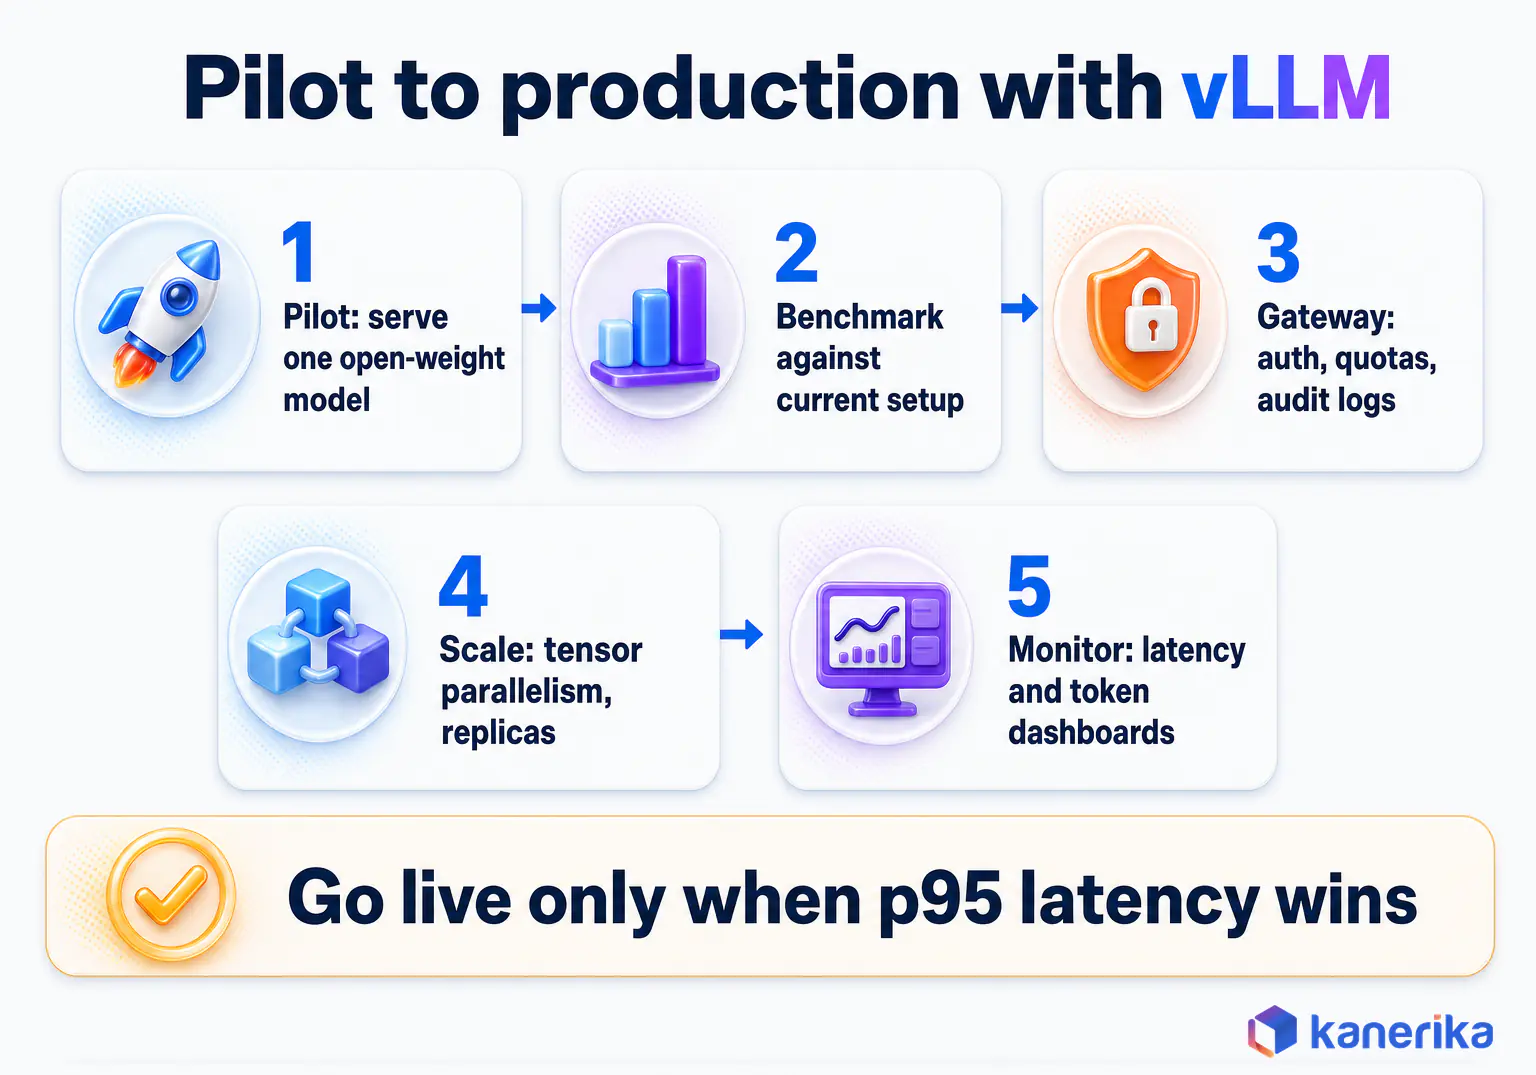
Taking vLLM to production is mostly about wrapping the engine in the controls any shared service needs. In practice, six steps cover it, using commands from the GPU installation guide and quickstart, read on November 3, 2026.
- Check the hardware: vLLM needs Linux, Python 3.11 to 3.14 and an NVIDIA GPU with compute capability 7.5 or higher, such as a T4, A100, L4, H100 or B200.
- Install and serve: run
uv pip install vllm --torch-backend=auto, thenvllm serve <model>on port 8000 with--api-keyset. - Repoint your code: OpenAI SDK apps only need a new base URL and API secret, so nothing else changes.
- Benchmark: run
vllm bench servewith real prompts before any traffic moves, comparing TTFT, TPOT, p95 latency and throughput with your current setup. Go live only when p95 latency wins. - Add a gateway: use authentication, rate limits and per-user quotas, which OWASP LLM10:2025 lists against unbounded consumption, as well as audit logs and a risk register based on NIST AI 600-1 (published July 26, 2024).
- Scale and monitor: add tensor parallelism or replicas on Kubernetes, watch latency and token dashboards, and pin versions so upgrades happen on your schedule.
Steps 2 to 4 on a single Linux GPU host look like this, using gpt-oss-20b because it fits within 16GB of memory:
# Step 2: install, then serve on port 8000
uv pip install vllm --torch-backend=auto
vllm serve openai/gpt-oss-20b --api-key "$VLLM_API_KEY"

# Step 3: point OpenAI SDK code at the server
export OPENAI_BASE_URL="http://localhost:8000/v1"
export OPENAI_API_KEY="$VLLM_API_KEY"

# Step 4: benchmark before traffic moves
vllm bench serve --model openai/gpt-oss-20b
Skipping the gateway is the riskiest shortcut, because an open endpoint invites runaway cost and data leaks. Our guides to the LLM gateway, LLM observability and LLM security cover each control, while AI governance ties them to policy.
Limitations and Trade-Offs of Running vLLM
vLLM solves serving, but it hands you jobs a hosted API used to carry. Weigh these five before you commit hardware and headcount.
- Linux only: Windows teams need WSL or a Linux server, while laptop work usually suits Ollama or llama.cpp better.
- A GPU floor: NVIDIA cards need compute capability 7.5 or higher, while large models also need enough GPU memory or several GPUs.
- Fast, breaking releases: v0.32.0 shipped on October 18, 2026, then v0.33.0 on November 2, 2026, with PyTorch 2.14.0 and CUDA 13.0-only wheels that can break older driver stacks.
- You own uptime: patching, capacity, failover and on-call duty move to your team instead of a vendor.
- Smaller gains at low load: because gains grow with longer sequences and larger models, a light workload may see far less than the headline numbers.
Each risk is manageable with owners, runbooks and version pinning. Treat the engine as a production service with its own budget, and then it behaves like one.
Kanerika Service
MLOps Consulting
Scale inference with confidence and monitor usage and latency in production.
Explore MLOps ConsultingHow Kanerika Helps Teams Serve LLMs in Production
Kanerika builds and runs LLM systems for enterprises, and the serving engine is one decision inside that work. As a Microsoft Solutions Partner for Data and AI, we start from the workload before choosing hosted or self-hosted serving.
Our LLM development services cover models deployed on your own infrastructure, while generative AI projects bring them into business workflows. Each serving project runs in four stages:
- Workload assessment: we measure token volume, latency targets and data residency, then decide whether a hosted API or self-hosting comes first.
- Model and engine selection: we review open-weight licenses, trial vLLM or SGLang on your prompts, then confirm quantization keeps quality.
- Secure serving layer: a gateway adds role-based access, quotas and audit logs, while kanGuard from Kanerika’s kanSuite adds unauthorized-access prevention and data security.
- Integration and operations: FLIP connects RAG and agent workflows to the model, while MLOps practice covers monitoring, scaling and upgrades.
The working rule is simple: run a hosted API for the first month, log real token volumes, then decide.
For a B2B SaaS company serving SMB clients in more than 40 countries, Kanerika built an LLM-driven ticket response system. It auto-responds to 80% of tickets, cut staffing costs by 70% and resolves tickets 50% faster, with a 30% rise in customer satisfaction.
Case Study
80% Ticket Auto-Resolution with LLM-Driven AI
A B2B SaaS company auto-responds to 80% of tickets and cut staffing costs by 70%.
Read the Case Study →LLM vs vLLM: The Bottom Line
The answer to LLM vs vLLM is both, in order. Pick the LLM that meets your quality bar first, because no serving engine can fix a weak model. Then serve it with vLLM only when your benchmark and cost math beat a hosted API.
Frequently Asked Questions
What is the difference between LLM and vLLM?
An LLM is a trained language model that reads a prompt and writes an answer. vLLM is open-source software that runs open-weight LLMs on GPUs and serves many users at once. The model decides answer quality. vLLM decides speed, concurrency and cost per token. Most production stacks that self-host need both layers working together.
What does vLLM stand for?
We could not verify an official expansion of the name from the project. The “v” is widely read as “virtual”, after the operating-system virtual-memory idea behind its PagedAttention method. PagedAttention stores each request’s KV cache in small pages, the way an operating system pages memory. That design is the main source of its speed.
Is TensorRT-LLM faster than vLLM?
It depends on your hardware and model, so test both. TensorRT-LLM targets NVIDIA GPUs only and aims for peak performance there, with more setup work. vLLM runs on NVIDIA, AMD and Intel GPUs and starts with one serve command. As of November 3, 2026, the newest TensorRT-LLM build, v1.4.0rc2, is still a pre-release.
What is the difference between vLLM and Ollama?
Ollama is built for running models locally on one machine, such as a developer laptop, with a very simple setup. vLLM is built for serving many users at once on GPU servers, using paged memory and continuous batching. Use Ollama to test and prototype. Use vLLM when a shared service needs throughput and an OpenAI-compatible API.
Is vLLM faster than llama.cpp?
On GPU servers with many users, vLLM is usually the stronger choice because of continuous batching and paged KV cache memory. llama.cpp is a C/C++ engine designed for CPUs and laptops, where vLLM does not fit well. The right pick depends on your hardware and traffic. Benchmark both with your own prompts before you decide.
Is self-hosting with vLLM cheaper than an LLM API?
Only at steady, high volume. vLLM has no license fee, but you pay for GPUs, storage, networking, idle time and staff. In this guide, GPT-6 Luna and Claude Haiku 5.5 are the cheapest hosted models, at $0.50 per 1M output tokens. Self-host only when your measured cost per 1M tokens beats the cheapest model that meets your quality bar.
How do you benchmark vLLM against your current setup?
Run the vllm bench serve command with real prompts at the concurrency you expect in production. Track time to first token, time per output token, inter-token latency and total throughput. Repeated runs can reuse the prefix cache and flatter results, so vary prompts or restart between runs. Then compare the same metrics against your current setup.
Who built vLLM?
vLLM started as a research project at UC Berkeley and launched publicly in June 2023. It is now an open-source project with more than 2,000 contributors and over 96,000 GitHub stars as of November 3, 2026. The code ships under the Apache 2.0 license, and version v0.33.0 was released on November 2, 2026.
Why is vLLM faster than standard LLM inference?
vLLM wastes far less GPU memory and keeps the GPU busier. PagedAttention stores the KV cache in small blocks with near-zero waste, so more requests fit on the card at once. Continuous batching adds new requests as others finish. The SOSP 2023 paper reports 2-4x the throughput of FasterTransformer and Orca at the same latency.
Why and when should you use vLLM?
Use vLLM when traffic is steady and high, when data must stay inside your own network, and when an open-weight model already meets your quality bar. You also need a team that can run GPUs and handle upgrades. For low or spiky volume, or when you need the strongest closed model, a hosted API usually fits better.
Can vLLM handle long prompts and many users at once?
Yes. Chunked prefill splits very long prompts into pieces so they do not stall other users. Prefix caching reuses work for shared prompt starts such as system prompts. Continuous batching serves many users on the same GPU without waiting for a full batch. The PagedAttention paper notes that its gains grow with longer sequences and larger models.
Does vLLM support multiple GPUs and AMD hardware?
Yes. vLLM splits large models across GPUs with tensor parallelism and pipeline parallelism, for example with the tensor-parallel-size 4 flag, and it can span several nodes. Beyond NVIDIA, the project supports AMD and Intel GPUs, CPUs, TPU and other hardware through plugins. Check the installation docs for the exact versions your hardware needs.
Is vLLM free for commercial use?
Yes. vLLM uses the Apache 2.0 license, which allows commercial use, changes and redistribution without a fee. The model you serve has its own license, though. gpt-oss-120b uses Apache 2.0, while Mistral Large 4 uses the Mistral Ecosystem Open-Weight License, which requires a commercial license for model-as-a-service operators. Read both before launch.
Can vLLM run closed models like GPT-6.1 Sol or Claude Opus 5.5?
No. vLLM can only serve models whose weights you can download. GPT-6.1 Sol, Claude Opus 5.5 and Gemini 4 Argon keep their weights private, so they run only through their vendors’ APIs. For self-hosting, pick an open-weight model such as gpt-oss-120b, Qwen3.8-27B or Mistral Small 4 and test it on your prompts.
Is vLLM faster than Hugging Face Transformers?
For multi-user serving, yes. vLLM’s June 2023 launch test reported up to 24x the throughput of Hugging Face Transformers on LLaMA-7B and LLaMA-13B with ShareGPT request lengths. That gap comes from paged memory and continuous batching. For a single user in a notebook the difference is much smaller, so benchmark your own workload first.