TL;DR
Pick data integration tools by where your data lands: Fabric Data Factory on Fabric, Lakeflow Connect on Databricks, AWS Glue on AWS. Choose Informatica IDMC when a regulated estate spans several clouds and on-premises systems. Fivetran suits a small team that must load many SaaS apps, and Airbyte suits teams that need to self-host. Boomi is the pick when business apps must stay in sync with each other. Coupler.io lets marketers and finance analysts load SaaS data into sheets and BI without code. Before you sign, test your messiest source for two weeks and compare the full 12-month cost.
Key Takeaways
- Choosing a data integration tool is choosing an architecture, so start with the platform where your data will land.
- Platform-native tools (Fabric Data Factory, Lakeflow Connect, AWS Glue) win when one cloud or lakehouse is home; independent tools win across several.
- Pricing models differ more than prices: monthly active rows, DPU-hours, credits and capacity units each reward a different usage pattern.
- Data integration tools also differ in who runs them: engineers for Glue and Airbyte, analysts for Matillion, business teams for Coupler.io.
- A two-week proof of concept with a schema change, a failure test and a lineage check exposes more than any feature matrix.
- Legacy ETL has a deadline: Talend Open Studio was retired in January 2024, and SSIS and PowerCenter estates need a planned exit.
Watch on YouTube
Migrating Data Pipelines from SSIS to Microsoft Fabric for SSMH | Case Study
See how Kanerika moved a legacy SSIS pipeline estate into Microsoft Fabric, and what changed for the teams that depend on that data every day.
The Month-End Close Where Three Systems Disagree
It is the third working day of the month, and the finance team has three revenue numbers. The ERP shows one total, while the CRM and the billing platform each show another.
The CFO’s dashboard was supposed to settle it. Instead, it reads from a nightly export that broke when someone renamed a CRM field, so it is two days stale.
Nobody made a bad purchase here. Each system was bought for a good reason, and every export script worked on the day it was written. What the company never chose was an integration architecture, so data moved, landed and changed in a different way for every system.
That choice is the real job of data integration tools. This guide reviews 11 of them and places each one by where your data lands and how it moves. It then covers pricing models, a two-week proof of concept and the exit from legacy ETL.
What Data Integration Tools Do in 2026
A data integration tool moves data from the systems that create it to the places that use it, and keeps the two in step. That sounds simple until you count the sources, such as an ERP database, a CRM, ad accounts and partner files.
The work breaks into four jobs. First, the tool connects to each source and moves the data on a schedule or as changes happen. Then it reshapes the data, so a customer in the CRM matches the same customer in billing. Finally, it lands the result in an analytics platform, a warehouse or another application.
The fourth job is where the architecture gets decided. A tool built for Microsoft Fabric writes naturally into OneLake, whereas a tool built for AWS writes into S3 and the Glue Data Catalog. Pick one of these tools and you have quietly picked the platform too.
Integration also overlaps with two neighbouring ideas. Ingestion is only the first step of moving raw data in, and data ingestion vs data integration lays out the difference. Scheduling, retries and alerting, on the other hand, are covered in the guide to automated data integration.
ETL, ELT, CDC, iPaaS and Data Virtualization Compared
Every tool on this list implements one or more of five movement patterns. Knowing the pattern tells you more about fit than any connector count, because it fixes latency, cost and where transformation logic lives.
| Pattern | How data moves | Typical latency | Typical tools | When it fits |
|---|
| ETL | Extract, transform on a separate engine, then load | Hours (batch) | Informatica IDMC, AWS Glue, Qlik Talend Cloud | When data needs heavy cleansing before it lands |
| ELT | Load raw data, then transform inside the warehouse | Minutes to hours | Fivetran, Airbyte, Matillion | When the warehouse or lakehouse has spare compute |
| CDC | Read the database change log and copy only changed rows | Seconds to minutes | Fabric Copy job and Mirroring, Lakeflow Connect, Fivetran | When databases feed near real-time reports |
| iPaaS | Event or API calls between applications | Per event | Boomi | When apps must share orders, customers or employees |
| Data virtualization | Query sources in place without copying | Query time | Denodo | When copying data is not allowed |
Many teams end up with two patterns rather than one. ELT or CDC feeds the analytics platform, while an iPaaS keeps operational apps in step. If the terms still blur, the guide on data integration vs ETL also separates the process from the pattern.
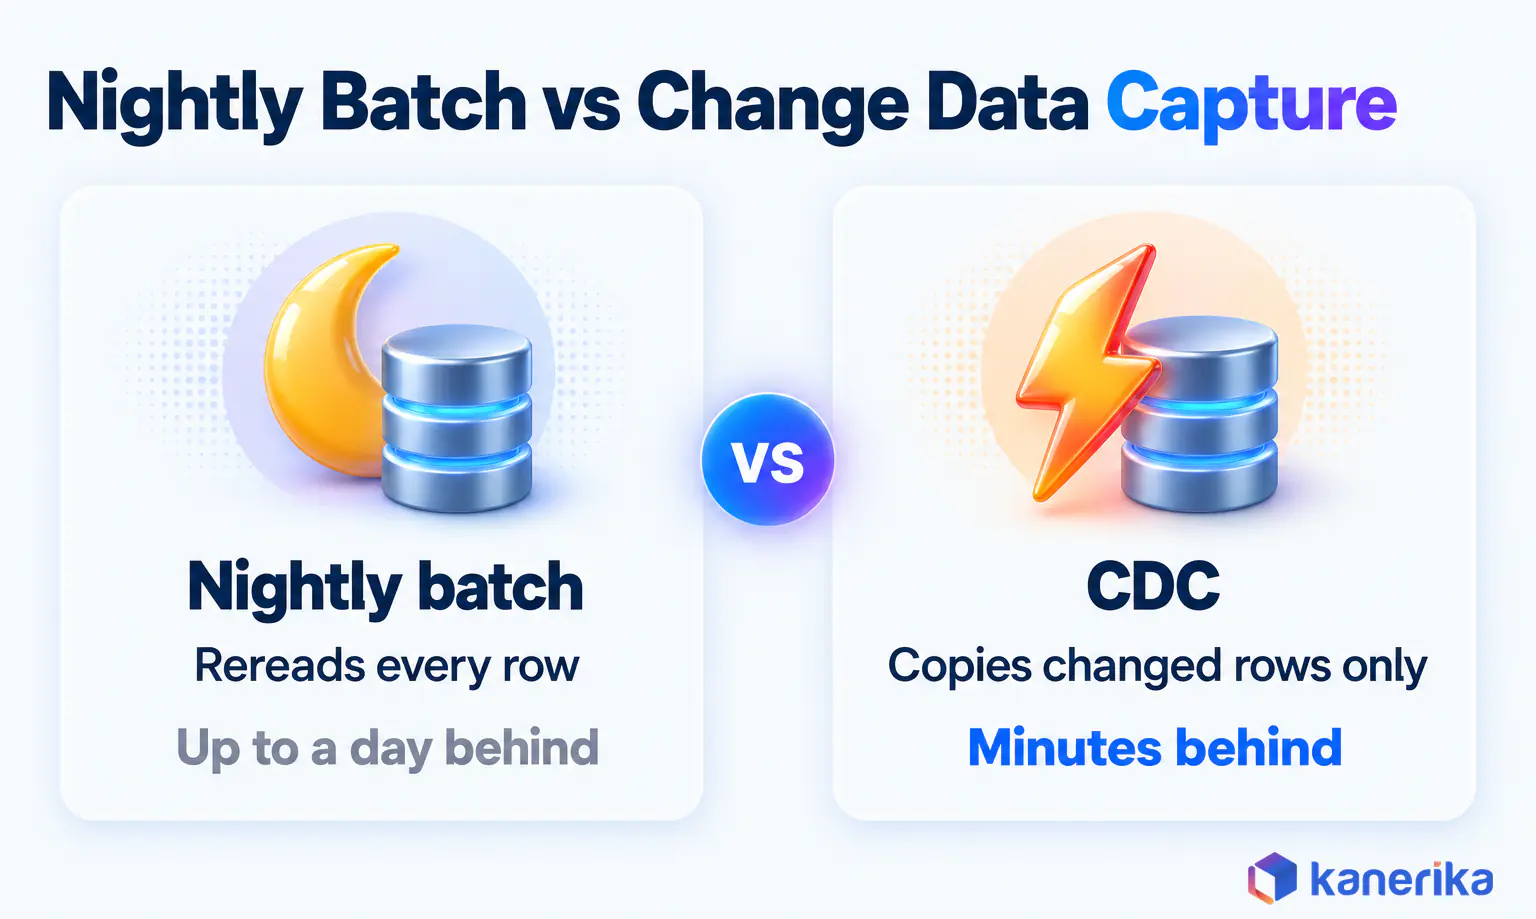
The biggest practical jump is from nightly batch to change data capture. A nightly full load rereads every row, so reports can run up to a day behind. CDC, by contrast, reads only what changed, so the same report runs minutes behind while moving far less data.
How We Selected These 11 Tools
Vendor pages rank their own product first, so this list uses criteria from delivery work instead. Each tool earned its place because it is the strongest answer to one recurring situation.
- Connector depth over connector count. We looked at how well a tool handles hard sources, such as ERP databases, SaaS APIs with rate limits and files whose layout changes.
- CDC and schema drift. A good tool notices a new or renamed column, then either adapts or stops loudly instead of loading broken data.
- Governance and lineage. Pipelines should register in the catalog you already use, such as Unity Catalog or Microsoft Purview. Our guide to data governance tools compares those catalogs.
- Deployment model. Fully managed SaaS, self-hosted, or hybrid, so an agent runs inside your network.
- Pricing model. Whether cost tracks rows, compute hours, credits or capacity, and therefore how predictable it is.
- Migration path off legacy ETL. How easily SSIS, PowerCenter or Talend Open Studio jobs move onto the tool.
Two tools in this list are close siblings: Azure Data Factory and Fabric Data Factory. Both are included because many estates run the first while deciding when to move to the second.
The 11 Best Data Integration Tools at a Glance
The table below is the short version of these data integration tools. Read the “where data lands” column first, because it usually narrows the field to two or three candidates before any demo.
| Tool | Category | Best for | Where data lands | Pricing model |
|---|
| Informatica IDMC | Enterprise ETL/ELT suite | Complex, governed hybrid estates | Any major cloud or on-premises target | Enterprise subscription, quoted |
| Qlik Talend Cloud | Integration plus data quality | Integration and data quality in one platform | Major warehouses and lakes | Tiered subscription |
| Fabric Data Factory | Platform-native | Analytics that lands in Microsoft Fabric | OneLake | Fabric capacity units |
| Azure Data Factory | Platform-native | Existing Azure and hybrid pipelines | Azure data stores | Per 1,000 runs plus DIU-hours |
| Databricks Lakeflow Connect | Platform-native | Lakehouses on Databricks | Unity Catalog tables | Databricks serverless compute |
| AWS Glue | Platform-native | Serverless Spark ETL on AWS | S3, Redshift, Glue Data Catalog | Per DPU-hour |
| Fivetran | Managed ELT | Low connector upkeep | Most cloud warehouses and lakes | Monthly active rows |
| Airbyte | Source-available ELT | Deployment control and custom sources | Most warehouses and lakes | Self-host Core or paid managed plans |
| Matillion | Warehouse ELT | Warehouse-centred ELT teams | Cloud warehouses | Consumption credits |
| Boomi | iPaaS | Application and API integration | Operational apps and APIs | Tiered subscription |
| Coupler.io | No-code SaaS loader | Business teams and SaaS reporting | Sheets, BI tools, BigQuery, Snowflake | Tiered subscription |
Notice that four of the 11 are tied to one platform. That is not a weakness, since a native tool usually has the deepest hooks into its own catalog, security and billing. It only becomes a problem when your data has more than one home.
Kanerika Service
Data Integration Services
Kanerika assesses your sources and destination, recommends the integration architecture and builds governed pipelines that keep ERP, CRM and SaaS data in step.
Explore Data Integration Services
The 11 Best Data Integration Tools in 2026, Reviewed
Each review below follows the same order: what the tool does well, the trade-off you accept, how it is priced and when to skip it. The first two are broad enterprise suites, the next four are platform-native, and the last five are independent specialists.
1. Informatica IDMC: Best for Complex, Governed Hybrid Estates
Informatica Intelligent Data Management Cloud (IDMC) is the broadest suite here. It covers integration, data quality, master data and cataloguing in one place. Ownership has also changed, since Salesforce completed its acquisition of Informatica on 18 November 2025.
Its strength shows in regulated, mixed estates. For example, a bank with mainframe extracts, an on-premises Oracle warehouse and three clouds can run everything under one set of policies. Few independent tools cover that spread.
PowerCenter, the older on-premises product, is now the legacy line. Informatica markets a PowerCenter cloud modernization path to IDMC, including a PowerCenter Cloud Edition. Still, plan it as a migration project with its own testing and cutover.
Trade-off and pricing: breadth brings a learning curve and a quoted enterprise subscription. Skip it if your sources are mostly SaaS apps feeding one warehouse, because a lighter ELT tool will cost less.
2. Qlik Talend Cloud: Best for Integration Plus Data Quality
Talend is now part of Qlik, and its current platform is Qlik Talend Cloud. Its appeal is that profiling, cleansing and validation sit next to the pipelines instead of in a separate product.
That matters most when the data itself is the problem, such as duplicate customers or inconsistent addresses. For instance, a distributor merging three customer masters can deduplicate addresses inside the same job that loads the warehouse.
One change catches many teams out. The free Talend Open Studio was retired on 31 January 2024, so jobs built on it now run on software that gets no updates.
Trade-off and pricing: a tiered subscription, and the strongest value comes when you use the quality features. Skip it if you only need simple SaaS-to-warehouse replication.
3. Microsoft Fabric Data Factory: Best When Analytics Lands in Fabric
If your reports, lakehouse and semantic models live in Microsoft Fabric, its own Data Factory is the natural first pick. Microsoft’s Fabric Data Factory overview groups the work into three jobs: Copy job moves data (bulk, incremental and CDC), Dataflow Gen2 transforms it with low code, and pipelines orchestrate it.
Mirroring keeps a near real-time replica of a supported operational database in OneLake. A Power BI report can then read fresh ERP data without a hand-built pipeline.
Mirroring also changes the cost picture, because Microsoft documents that the background compute for mirroring replication is free and does not consume capacity. Each capacity unit also includes 1 TB of free mirroring storage, so an F64 capacity gets 64 TB.
Everything lands in OneLake and is billed against Fabric capacity units. That keeps cost in one place, but a heavy integration job also competes with your reports for the same capacity.
Trade-off and pricing: capacity-based billing and a strong Microsoft bias. Skip it if most of your analytics run on Databricks, Snowflake or AWS, since you would be copying data into a platform nobody queries.
Case Study
40% Lower Costs: SSIS to Microsoft Fabric Migration
Kanerika automated the move of a large enterprise’s SSIS pipelines to Microsoft Fabric, delivering 30% faster processing, 40% lower operational costs and 99.9% data integrity during migration.
Read the Case Study →
4. Azure Data Factory: Best for Existing Azure and Hybrid Pipelines
Azure Data Factory (ADF) remains the workhorse for many Azure estates. Its self-hosted integration runtime reaches databases behind the firewall. That is why it became the default bridge from on-premises SQL Server to Azure.
Microsoft’s own comparison page calls Fabric Data Factory “the next generation of Azure Data Factory”. It also says about 90% of ADF activities are already available there. So ADF is safe to keep running, but new analytics work should be weighed against Fabric first.
Trade-off and pricing: ADF pricing charges orchestration per 1,000 runs, data movement per DIU-hour and pipeline activity per hour. Skip it for greenfield Fabric projects. For a vendor-by-vendor view, see Informatica vs Azure Data Factory vs Talend.
5. Databricks Lakeflow Connect: Best When the Lakehouse Is Databricks
Lakeflow Connect is the built-in ingestion layer in Databricks. The Databricks documentation lists managed connectors for SaaS apps such as Salesforce, Workday, HubSpot and Jira. It also covers CDC from SQL Server, MySQL and PostgreSQL.
The advantage is governance by default. Because ingested tables are governed by Unity Catalog on serverless compute, access rules and lineage apply from the first load instead of being added later.
Trade-off and pricing: billed as Databricks serverless compute, while the connector list is shorter than an independent ELT vendor’s. Skip it if your lakehouse is not Databricks, or if you need a long tail of niche SaaS sources.
Watch on YouTube
Databricks Migration: Moving Enterprise Data Off Legacy ETL
A walkthrough of how enterprises move data and pipelines off legacy ETL onto Databricks, and where governance fits in the move.
6. AWS Glue: Best for AWS-Native Serverless Spark ETL
AWS Glue runs Spark ETL jobs without clusters to manage, and it keeps metadata in the Glue Data Catalog. For a team whose lake sits in S3 and whose warehouse is Redshift, that makes it the shortest path.
Billing is per DPU-hour, so cost tracks how long jobs run and how many workers they use. The AWS Glue pricing example (checked 23 October 2026) puts a Spark ETL job at $0.44 per DPU-hour, although rates vary by region.
Trade-off: Glue suits engineers who write Spark rather than analysts who want a visual designer. Skip it if most of your data and people sit outside AWS.
7. Fivetran: Best for Managed ELT With Low Connector Upkeep
Fivetran’s promise is that you stop maintaining connectors. It builds and patches source connectors and handles API changes. Then it loads raw tables into your warehouse, so transformation can run there.
That transformation step now sits under the same roof, because Fivetran and dbt Labs completed their merger on 1 June 2026. The deal joins managed loading with dbt’s in-warehouse modelling.
Trade-off and pricing: Fivetran is priced on Monthly Active Rows. MAR counts each distinct row once a month, however often it changes. A table whose rows nearly all change each month costs close to its full row count. A large table that rarely changes costs little. Skip it if a few very large tables rewrite most of their rows every month.
8. Airbyte: Best for Deployment Control and Custom Sources
Airbyte suits teams that want to run integration inside their own environment. Airbyte Core is source-available under the Elastic License 2.0. So you can self-host it, but you cannot resell it as a managed service.
The other draw is custom sources. When an internal API or a niche SaaS tool has no ready-made connector, engineers can build one rather than wait for a vendor roadmap.
Trade-off and pricing: self-hosting Core carries no licence fee, yet you still pay for infrastructure and the engineers who run it. Managed plans are priced separately. Skip self-hosting if nobody on the team wants to own upgrades and on-call.
Talk to Kanerika
Not Sure Which Tool Fits Your Estate?
Bring your source list and target platform. Kanerika will help you narrow the 11 tools to a tested shortlist and plan a proof of concept on your hardest source.
Schedule a Demo →
9. Matillion: Best for Warehouse-Centred ELT Teams
Matillion’s Data Productivity Cloud is built for teams that transform data inside the warehouse. It pushes the work down to the warehouse engine, while giving analysts a visual designer alongside SQL.
Picture an analytics team on Snowflake that models its data in SQL but wants a visual designer for its pipelines. Matillion fits that team well, because each job is pushed down and runs on Snowflake compute rather than a separate engine.
It also ships Maia, an agentic assistant that helps build and document pipelines. Even so, treat its output like any generated code and review it before production.
Trade-off and pricing: Matillion pricing uses consumption credits, which pay for Task Hours billed only while a pipeline runs. Every plan comes with a free trial. Skip it if your transformation runs in Spark notebooks rather than warehouse SQL.
10. Boomi: Best for Application and API Integration
Boomi is an iPaaS, so its centre of gravity is operational systems rather than analytics. The Boomi Enterprise Platform connects applications through APIs and events. For example, it can create a customer in the ERP the moment a deal closes in the CRM.
That makes it a complement to an ELT tool, not a replacement. Use Boomi when a person or process waits on the data, but use ELT or CDC when a report does.
Trade-off and pricing: a tiered subscription, although bulk analytical loads are not its strength. Skip it if all you need is data in a warehouse.
11. Coupler.io: Best for Business Teams Loading SaaS Data
Coupler.io is the no-code option on this list. It connects to 400+ data sources across ads, CRM, ecommerce and finance. It then loads them into spreadsheets, BI tools and warehouses such as BigQuery and Snowflake.
Its users are usually marketers and finance analysts rather than data engineers. A marketing lead can, for example, schedule ad spend from several platforms into Power BI or Looker Studio without filing a ticket. Typical use cases include:
- Using BigQuery for data analytics across CRM and ecommerce data.
- Refreshing a cross-channel marketing dashboard on a schedule.
- Pulling finance and sales exports into one shared spreadsheet.
Trade-off and pricing: a tiered subscription, built for reporting rather than heavy transformation or CDC. Skip it for core ERP replication.
Four more tools are worth a look as honourable mentions, since each fits a narrower situation than the 11 above. MuleSoft suits API-led integration between applications, while Hevo Data gives a small team no-code ELT. Estuary covers streaming CDC alongside batch loads, and Denodo queries sources in place, the virtualization pattern for when copying is not allowed.
How to Choose a Data Integration Tool: Start With Where the Data Lands
The fastest way to a shortlist is to answer five questions in order. Each answer removes candidates, so by the third you are usually down to two or three tools.
- Destination platform. Fabric, Databricks, AWS, Snowflake and BigQuery each have a natural first pick.
- Latency need. Daily batch, hourly refresh and near real-time CDC each narrow the field differently.
- Source mix. Mostly databases point to CDC tools, whereas mostly SaaS apps point to managed ELT.
- Team skills. Spark engineers, SQL analysts and business users need different interfaces, so match the tool to the people.
- Governance. Decide which catalog owns lineage and access before you compare features.
First Pick and Runner-Up by Scenario
The destination question carries the most weight, because it settles security, billing and lineage in one go. Once it is answered, the scenario table below gives a first pick and a fallback.
| Scenario | First pick | Runner-up | Why |
|---|
| Analytics lands in Microsoft Fabric | Fabric Data Factory | Fivetran | Because Mirroring and Copy job write straight to OneLake |
| Lakehouse on Databricks | Lakeflow Connect | Fivetran | Because Unity Catalog governs from the first load |
| Data and team on AWS | AWS Glue | Airbyte | Because serverless Spark sits next to S3 and Redshift |
| Regulated hybrid estate | Informatica IDMC | Qlik Talend Cloud | Since one policy and lineage layer spans every cloud |
| Many SaaS sources, small data team | Fivetran | Airbyte | Because it needs the least connector upkeep |
| Warehouse on Snowflake or BigQuery, SQL-first team | Matillion | Fivetran | Because the work runs as SQL inside the warehouse |
| Apps must stay in sync | Boomi | MuleSoft (see the four further tools) | Because the job is event and API flows, not bulk loads |
| Business users need SaaS data in BI | Coupler.io | Fivetran | Because business users can schedule loads without code |
The runner-up column is there for a reason. If your first pick fails the proof of concept below, the runner-up is the tool to test next, rather than a fresh long list.
Worked Example: A Mid-Size Retailer on Fabric
Consider a retailer whose analytics platform is Microsoft Fabric. Its ERP runs on SQL Server, its online store is Shopify, and its sales team works in Salesforce.
The ERP matters most for daily trading, so Fabric Mirroring keeps a near real-time copy of it in OneLake. Shopify and Salesforce are SaaS sources, which a Fabric Copy job can load where a connector exists. For any source Copy job cannot reach, the candidate is Fivetran. Marketing also wants ad spend next to sales, so the team uses Coupler.io to schedule those feeds into Power BI itself.
The open question is whether to add Fivetran at all. A second tool means a second bill, a second monitoring console and a second set of credentials to rotate. So it is worth adding only if Copy job cannot cover a source the business needs every day. Otherwise, one tool is cheaper to run, even if a few connectors take more setup.
What Data Integration Tools Cost
List prices tell you little, because each vendor meters a different thing. The useful question is which usage pattern each model rewards and which one it punishes.
| Pricing model | Example tools | Cost grows with | Watch for |
|---|
| Monthly active rows | Fivetran | Rows inserted, updated or deleted each month | Tables where most rows change each month |
| DPU-hour or DIU-hour, plus per 1,000 runs | AWS Glue, Azure Data Factory | Job duration, workers and run count | Jobs that run long or often, since both multiply the bill |
| Consumption credits | Matillion | Pipeline compute used | Job growth, so set credit alerts |
| Capacity units | Fabric Data Factory | Size of the Fabric capacity | Integration jobs, because they compete with reports |
| Subscription tiers or connectors | Boomi, Coupler.io, Qlik Talend Cloud | Tier, connectors and users | Unused connectors, so audit them yearly |
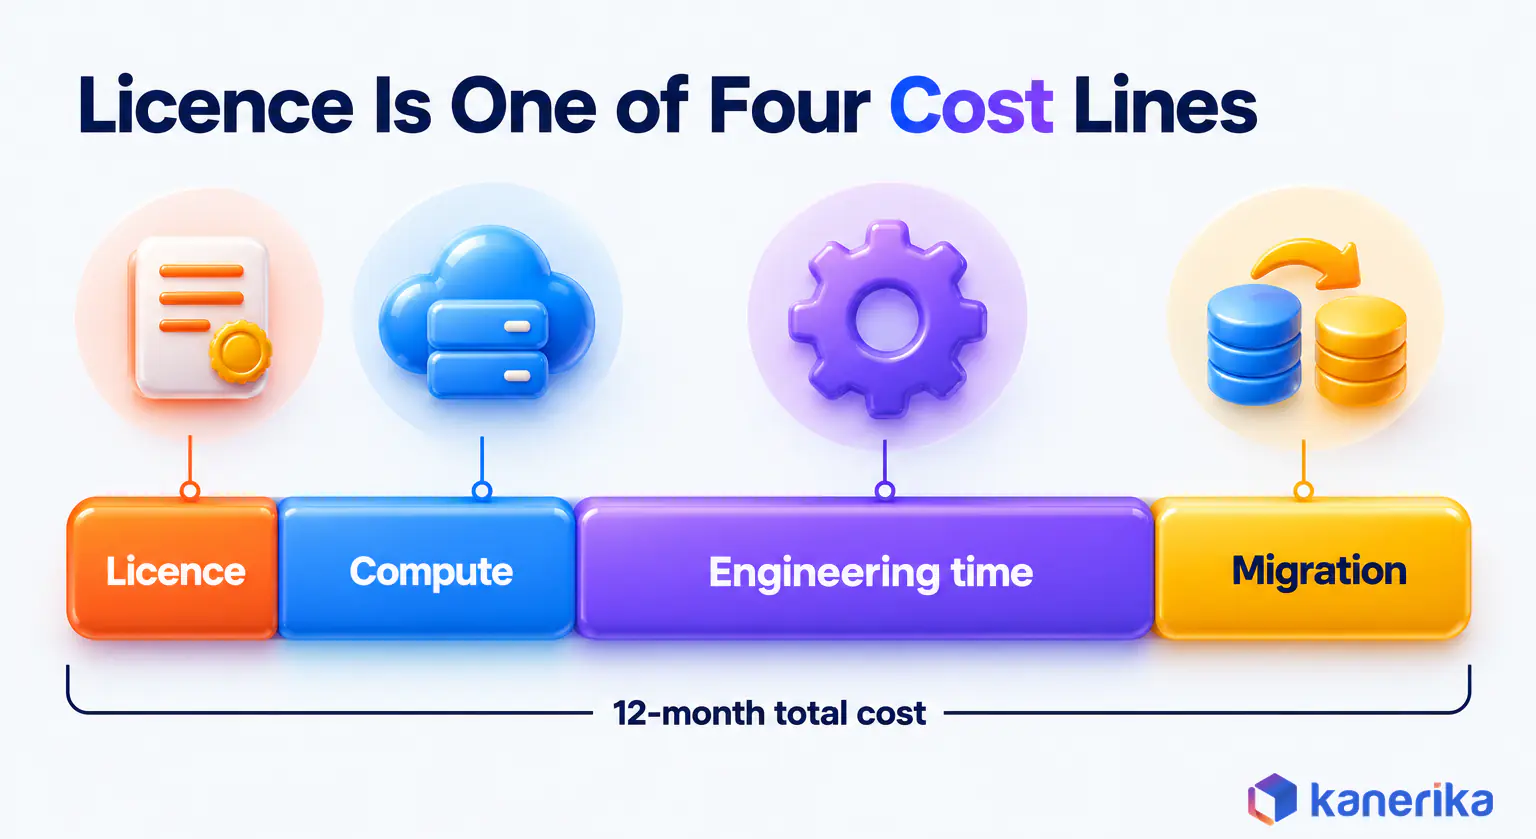
Licence is also only one line of the 12-month total cost of ownership. Add the compute the tool triggers in your warehouse and the engineering time to build and watch pipelines. Then add the one-off cost of migrating old jobs. The engineering line often surprises teams, and our breakdown of enterprise data integration costs covers it in more depth.
The AWS example of $0.44 per DPU-hour is the only published rate quoted here. It shows why the model matters as much as the rate. A Glue job that uses 10 DPUs for 15 minutes consumes 2.5 DPU-hours, or about $1.10 per run. So if it runs every hour, the same job costs roughly $26 a day before storage and catalog charges.
Run a Two-Week Proof of Concept Before You Sign
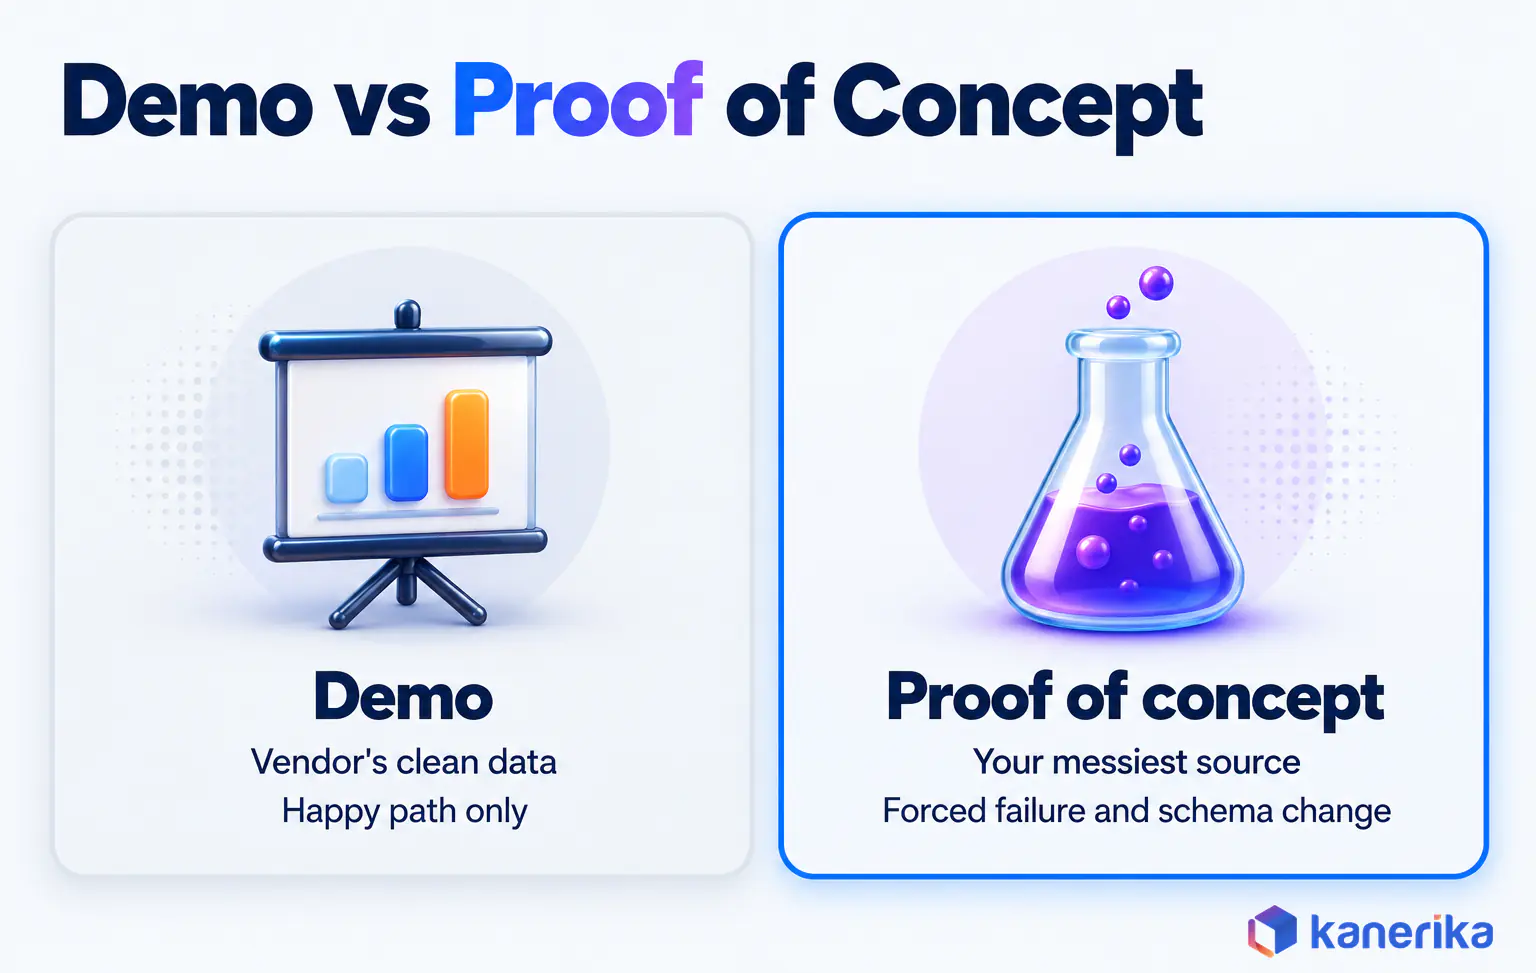
A demo shows a tool on the vendor’s data, whereas a proof of concept shows it on yours. Two weeks is usually enough to see the difference.
- Pick three real sources, including one ugly one, such as the legacy database or the SaaS app with the strictest API limits.
- Change a schema on purpose. Add and rename a column mid-test, then record what the tool does.
- Measure CDC lag between a change in the source and its arrival in the target.
- Break it. Kill a run halfway, then check whether the retry duplicates or drops rows.
- Check lineage in your own catalog, since the vendor console alone proves little.
- Read the cost meter daily and project it to a full month.
Write the pass criteria down before the test starts, so the result cannot be argued afterwards. The table below is a starting point.
| Test | Pass | Fail |
|---|
| Schema change | New column appears or the pipeline stops with a clear alert | Silent load of nulls or misaligned data |
| CDC lag | Within the freshness your reports need | Lag grows through the day |
| Failure and retry | Row counts match after the rerun | Duplicates or gaps |
| Lineage | Source-to-report lineage visible in your catalog | Lineage only inside the vendor tool |
| Cost | Monthly projection within budget | Projection depends on guesses about volume |
The ugly source is the one that decides most evaluations. A tool can handle a clean SaaS API well and still struggle with a twenty-year-old ERP schema. Yet that ERP is often the source your finance team depends on.
Mistakes That Sink Data Integration Tool Rollouts
Failed rollouts of data integration tools usually come down to a handful of avoidable decisions. They trace back to how the tool was bought and run in the first month, and those decisions matter more than which vendor won.
Buying for connector count. A catalogue of hundreds of connectors means little if the three you depend on are shallow. Test the three you need before counting the rest.
Ignoring schema drift. Source teams rename fields without warning. When the tool loads bad data silently, the first person to notice is usually an executive reading a wrong number. Ask each vendor how the tool reports a changed column before you sign.
No owner for pipeline health. Because pipelines fail at night and at month end, someone has to own alerts and freshness checks, which is the discipline of data observability.
Governance bolted on later. Adding access rules and lineage after hundreds of pipelines exist is slow and expensive. Instead, wire the tool into the catalog and lineage tools you already run from day one.
Two overlapping tools. Teams often buy a second tool for one awkward source and end up paying twice for the rest. Decide which tool owns which pattern, and then write it down. One owner per pattern also keeps the bill and the on-call rota simple.
Glue scripts instead of orchestration. Cron jobs and shell scripts that chain pipelines together become the next legacy problem. Scheduling and dependencies belong to a separate category of data automation tools. The wider habits are also collected in our data integration best practices.
Moving Off Legacy ETL: SSIS, Informatica PowerCenter and Talend Open Studio
Many teams evaluating new integration tools are really planning an exit from an old one. Three legacy products come up again and again, and each has a different reason to move.
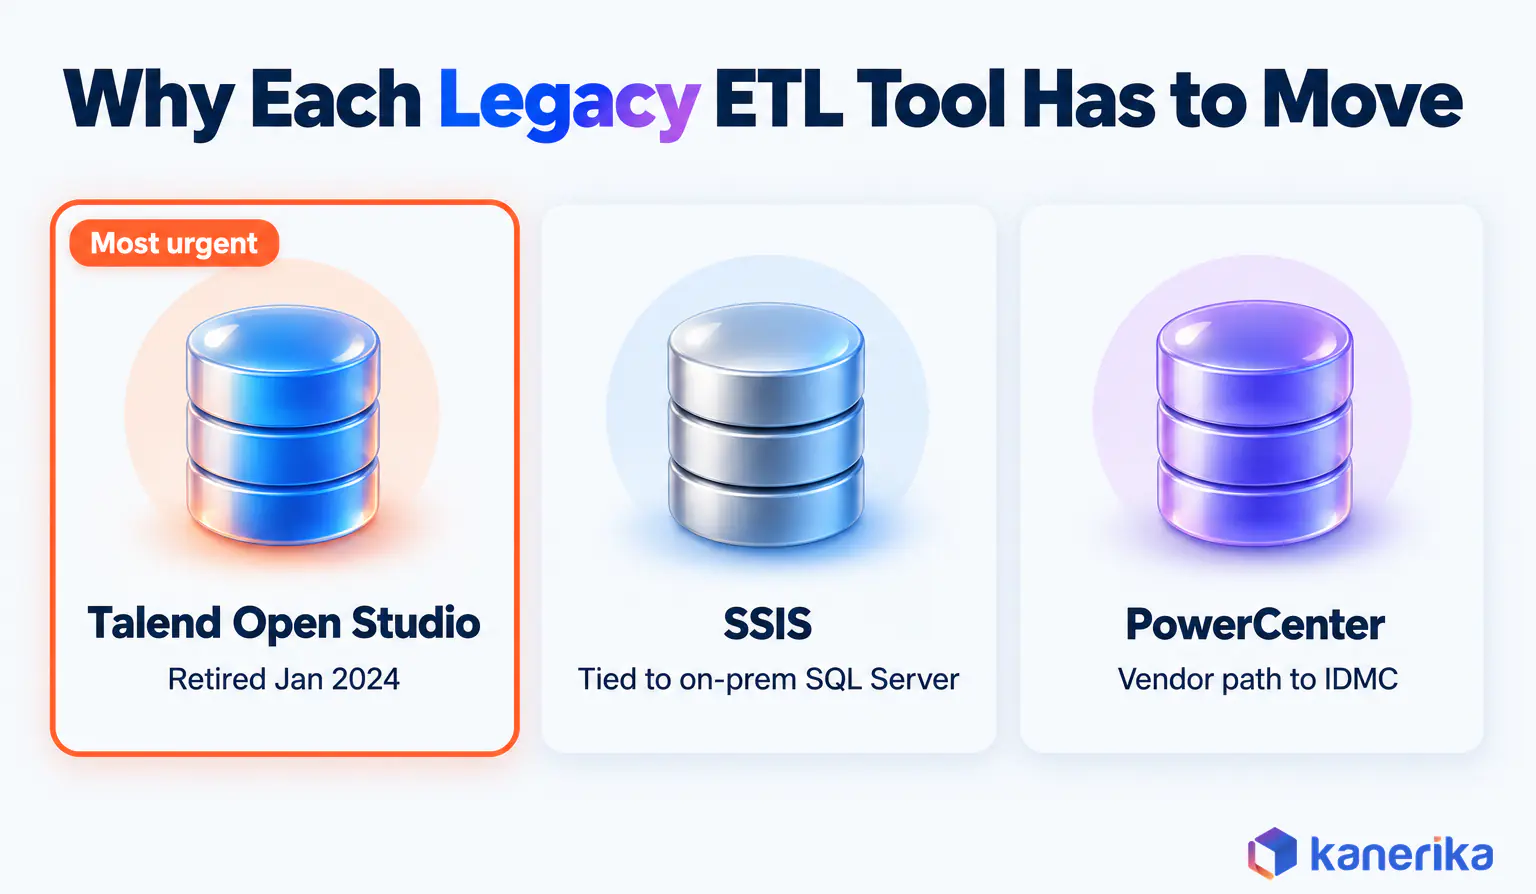
As noted in the Qlik review, Talend Open Studio has the clearest deadline because it is already retired. PowerCenter estates have a vendor path to IDMC, so the question is when rather than whether. SSIS still runs, but it ties pipelines to on-premises SQL Server and its upkeep.
The target usually follows the destination platform you chose earlier. SSIS estates heading for Microsoft Fabric tend to land in Fabric Data Factory. PowerCenter estates choose between IDMC and a lakehouse rebuild, while Talend Open Studio users move to Qlik Talend Cloud or a managed ELT tool.
| Legacy tool | Common target | What to watch |
|---|
| SSIS | Fabric Data Factory or Azure Data Factory | Script tasks and custom components, since they have no direct equivalent |
| Informatica PowerCenter | Informatica IDMC, or Fabric or Databricks | Mapping logic, because it hides in reusable transformations |
| Talend Open Studio | Qlik Talend Cloud, or a managed ELT tool | Hand-written Java routines, so inventory them first |
Migrate in Waves, Not All at Once
Whatever the target, migrate in waves rather than all at once. Start with a low-risk domain, then run old and new pipelines in parallel and reconcile row counts before switching off the original. Our guides to SSIS to Fabric migration and ETL migration cover the steps in detail.
Each row also hides a skills question. SSIS teams know SQL Server well but may be new to Spark notebooks or Dataflow Gen2, so training belongs in the migration plan. PowerCenter and Talend teams face a similar shift when they move to a tool that transforms inside the warehouse.
Parallel runs cost money, so agree up front how long both pipelines will run. Two full month-end closes, for example, give finance enough evidence to trust the new numbers.
The hardest part of most migrations is the undocumented logic inside old jobs. Script tasks, custom components and hand-written routines are where the surprises hide. So inventory that logic first, and the tool choice becomes much easier to defend.
How Kanerika Helps You Choose and Implement Data Integration Tools
Kanerika’s data team works through the same sequence this guide describes, starting from your sources and destination rather than a preferred vendor. The first step is an assessment of where data lives, where it needs to land and which pipelines carry the most business risk.
That assessment produces a source inventory, a target architecture and a ranked list of pipelines to move first. Kanerika’s data integration services team then runs a two-week pilot on the riskiest source rather than the easiest one.
The pilot also answers the cost question early, since it shows what compute, licence and support will look like at full scale. The business case then rests on measured numbers rather than vendor estimates.
Migration then happens in waves, using the FLIP migration accelerators to automate moves off SSIS, Informatica, DataStage and Alteryx. Governance and monitoring are set up as part of the build, so they are never left until after it.
What an SSIS to Fabric Migration Delivered
One engagement shows the pattern. A large enterprise needed to move its SSIS pipelines to Microsoft Fabric without losing data or rewriting everything by hand.
Kanerika built an automated framework to extract, analyse and migrate the SSIS packages. It then rebuilt the transformations as PySpark notebooks and Power Query (M), with role-based access, encryption and monitoring in place.
Processing ran 30% faster, operational costs fell 40% and manual maintenance dropped 25%. Data integrity also held at 99.9% during migration. The full write-up is in the SSIS to Microsoft Fabric case study.
That sequence holds whichever tool wins your evaluation, whether the estate is Fabric-first, a Databricks lakehouse or a mix of platforms. It also runs before any large licence is signed, so the spend follows the evidence from the pilot.
If you would rather compare implementation partners than products, our review of data integration companies covers that side of the decision.
Kanerika Service
FLIP: Automated Migration From Legacy ETL
FLIP automates migrations from SSIS, Informatica, DataStage and Alteryx toward Microsoft Fabric, Databricks or Talend, so pipelines move in tested waves instead of hand rewrites.
Explore FLIP
Final Shortlist: The Best Data Integration Tool for Each Scenario
Every tool on this list is the right answer somewhere and the wrong answer somewhere else. This shortlist pairs each common situation with the tool to test first.
| If your situation is | Test this tool first |
|---|
| Analytics in Microsoft Fabric (Azure Data Factory for existing Azure pipelines) | Fabric Data Factory |
| Lakehouse on Databricks | Databricks Lakeflow Connect |
| Data and engineers on AWS | AWS Glue |
| Regulated, hybrid, many platforms | Informatica IDMC |
| Many SaaS sources, small team | Fivetran (Airbyte if you need to self-host) |
| Warehouse on Snowflake or BigQuery, SQL-first team | Matillion (Fivetran as runner-up) |
| Applications that must stay in sync | Boomi |
| Business users need SaaS data in BI | Coupler.io |
Which of these data integration tools is best, then? The one built for the platform where your data lands, proven on your messiest source in a two-week test.
Frequently Asked Questions
What is a data integration tool?
A data integration tool is software that moves data from source systems such as ERP databases, CRMs and SaaS apps into a destination such as a warehouse, lakehouse or another application. It connects to each source, copies data on a schedule or as changes happen, reshapes it so records match, and keeps the destination in step with the sources.
Which is the best data integration tool?
There is no single best tool, because the right choice depends on where your data lands. Fabric Data Factory leads for Microsoft Fabric, Lakeflow Connect for Databricks and AWS Glue for AWS. Informatica IDMC suits governed hybrid estates, Fivetran suits low-upkeep managed ELT, and Boomi suits application-to-application integration across operational systems.
Can dbt replace Informatica?
Only in part. dbt can replace Informatica’s in-warehouse transformation logic when data already lands in a cloud warehouse, but it does not extract or load data, manage data quality or provide a full catalog. Teams replacing Informatica usually pair dbt with a loading tool such as Fivetran or Airbyte, plus separate governance and data quality tooling.
Is dbt the same as Databricks?
No. dbt is a transformation framework that runs SQL models on top of a data platform. Databricks is the data platform itself, providing storage, compute, Unity Catalog governance and ingestion through Lakeflow Connect. Many teams use the two together, running dbt models on Databricks compute, but neither one replaces the other in a modern data stack.
Is Talend a data integration tool?
Yes. Talend is now part of Qlik, and its current product is Qlik Talend Cloud, which combines data integration with profiling, cleansing and validation in one platform. The free Talend Open Studio was retired on 31 January 2024 and no longer receives updates, so teams still running it should plan a move to a supported platform.
Is Tableau a data integration tool?
No. Tableau is a business intelligence and visualisation tool. It connects to many data sources and includes Tableau Prep for light data preparation, but it is not built to move, replicate or govern data between systems at scale. Teams usually feed Tableau from a warehouse or lakehouse that a dedicated integration tool keeps loaded and current.
Is SQL a data integration tool?
SQL is a query language, not a tool. It is used heavily inside data integration, though: ELT tools and dbt express transformations in SQL, and CDC tools read changes from SQL databases. Hand-written SQL scripts can integrate small datasets, but they lack the scheduling, monitoring, retries and lineage that a dedicated integration tool provides.
Is Excel an ETL tool?
Excel is a spreadsheet, not an ETL tool, but its Power Query feature can extract, transform and load data from files, databases and web sources into a workbook. That works well for personal analysis. For shared, scheduled or governed reporting, a no-code loader such as Coupler.io or a full integration tool is far more reliable and easier to audit.
Will ETL be replaced by AI?
AI is changing how pipelines are built rather than removing the need for them. Assistants such as Matillion’s Maia help generate and document pipelines, and tools increasingly suggest field mappings. Data still has to move, be checked and be governed, so AI is better seen as speeding up integration work while engineers review what it produces.
Which data integration tool is best for Microsoft Fabric?
Fabric Data Factory is the natural first pick, because it writes straight into OneLake through pipelines, Dataflow Gen2, Copy job and Mirroring. Microsoft calls it the next generation of Azure Data Factory, with about 90% of ADF activities already available. Existing ADF pipelines can keep running, but new Fabric analytics work should start in Fabric Data Factory.
What is the difference between Airbyte and Fivetran?
Fivetran is a fully managed ELT service priced on Monthly Active Rows, built so teams spend little time maintaining connectors. Airbyte gives more deployment control: Airbyte Core is source-available under Elastic License 2.0, so it can be self-hosted, and teams can build custom sources. Choose Fivetran for low upkeep and Airbyte for control over deployment.
Which data integration tools support change data capture?
Several tools in this guide support change data capture. Fabric Data Factory offers CDC through Copy job and near real-time replicas through Mirroring. Databricks Lakeflow Connect captures changes from SQL Server, MySQL and PostgreSQL, and Fivetran also replicates database changes. Always test CDC lag on your own databases, because it depends on source load and configuration.
What are examples of data integration tools?
Common examples include Informatica IDMC, Qlik Talend Cloud, Microsoft Fabric Data Factory, Azure Data Factory, Databricks Lakeflow Connect, AWS Glue, Fivetran, Airbyte, Matillion, Boomi and Coupler.io. They range from enterprise suites and platform-native services to managed ELT tools, iPaaS products and no-code loaders. MuleSoft, Hevo Data, Estuary and Denodo also appear on many shortlists.
What are the best open-source data integration tools?
Fully open-source options are fewer than they were, because Talend Open Studio was retired in January 2024. Airbyte Core is often called open source, but it is source-available under Elastic License 2.0, which allows self-hosting and blocks reselling it as a managed service. Check each licence before you build on it, especially if you offer data services.
How much does a data integration tool cost?
Cost depends on the pricing model more than the list price. Fivetran charges by Monthly Active Rows, Matillion by consumption credits, Fabric by capacity units and Azure Data Factory per 1,000 runs plus DIU-hours. The AWS Glue pricing example shows $0.44 per DPU-hour. Budget for compute, engineering time and migration as well as the licence.
How do you test a data integration tool before buying it?
Run a two-week proof of concept on three real sources, including your messiest one. Change a schema mid-test, measure CDC lag, kill a run to check retries, confirm lineage in your own catalog and project the cost meter to a full month. Write pass and fail criteria before starting, so the result is clear to everyone involved.
What security features should a data integration tool have?
Look for encryption in transit and at rest, role-based access control, single sign-on and secure credential storage for every source. For on-premises sources, a self-hosted agent or runtime avoids opening inbound firewall ports. Lineage and audit logs that feed your catalog, such as Unity Catalog or Microsoft Purview, help prove who accessed or changed data.
How do you migrate from SSIS or Informatica PowerCenter to a modern tool?
Start with an inventory of packages or mappings and the hidden logic inside them, such as script tasks and reusable transformations. Pick the target by destination platform: Fabric or Azure Data Factory for SSIS, and IDMC, Fabric or Databricks for PowerCenter. Then migrate in waves, run old and new pipelines in parallel and reconcile row counts before cutover.
Which is the most popular ETL tool?
No neutral ranking measures popularity reliably, and vendor pages rank themselves first. In enterprise estates, Informatica, Azure Data Factory and SSIS remain widely deployed, while Fivetran and Airbyte are common choices for cloud ELT. A better question is which tool fits your destination platform, latency needs and team skills, proven on your own data.
What is the difference between ETL and ELT?
ETL transforms data on a separate engine before loading it into the target, so only cleaned data arrives. ELT loads raw data first and transforms it inside the warehouse or lakehouse, using that platform’s compute. ELT suits cloud platforms with elastic compute, while ETL still fits cases where data must be cleansed or masked before it lands.
Is ETL a data integration?
Yes. ETL is one method of data integration, alongside ELT, change data capture, application integration through iPaaS and data virtualization. In ETL, data is extracted from sources, transformed on a separate engine and loaded into a target. Data integration is the broader goal of combining data from many systems so people and applications see one consistent view.
What are the 5 steps of ETL?
A common five-step breakdown is extract, clean, transform, load and analyse. Data is pulled from source systems, checked for errors and duplicates, reshaped to match the target model, loaded into a warehouse or lakehouse, and then used for reporting. Some teams describe ETL as three steps; the extra two simply separate quality checks and consumption.
What are the types of data integration?
The main types are ETL, ELT, change data capture, application integration and data virtualization. ETL and ELT move data in batches and differ in where transformation happens. CDC copies only changed rows for low latency. Application integration, usually through an iPaaS, syncs operational apps through APIs, and virtualization queries sources in place without copying them.
Is ETL the same as API?
No. ETL is a process for moving and reshaping data in bulk between systems, while an API is an interface that lets one application request data or actions from another. ETL tools often use APIs to read from SaaS sources, and iPaaS products such as Boomi build integrations around APIs, but the two terms describe different things.
Is dbt an ETL tool?
dbt handles only the transform step. It runs SQL models inside a warehouse or lakehouse after another tool has loaded the data, which makes it part of an ELT stack rather than a complete ETL tool. dbt Labs completed its merger with Fivetran on 1 June 2026, pairing dbt modelling with Fivetran’s managed loading under one company.




