TL;DR
In the machine learning vs AI choice, pick machine learning when past data can teach the system and rule-based AI when the logic is fixed. AI is the whole field of computers doing tasks that need judgment. Machine learning is one part of AI that learns from data. So every machine learning system is AI, but not every AI system learns. Tools like ChatGPT use generative AI, a branch of machine learning that writes text. Many real systems mix both, and a person makes the final call.
Key Takeaways
- AI is the field and the goal. Machine learning is one way to reach it, learning patterns from data instead of following written rules.
- The terms nest: AI contains machine learning, which contains deep learning, which contains generative AI and large language models.
- Rules engines, search and planning are AI without machine learning, and they still run many tax, credit and routing decisions.
- Choose by the problem: stable logic suits rules, labeled history suits predictive ML, and language output suits generative AI.
- Governance differs too: the NIST AI RMF and the EU AI Act focus on risk, and learned models take more work to explain.
- Production systems often mix approaches, with a rules gate, a model score and a person who signs off.
One Claims Queue, Three Different Systems
Picture a health insurer’s claims queue on a busy Monday morning. A rules engine checks each new claim for a policy number, a valid date of service and a signed form. Anything incomplete then goes straight back to the sender.
The claims that pass move on to a machine learning model, which scores each one for fraud risk using patterns from years of past claims. A large language model then drafts a plain-English summary for the adjuster, who makes the final decision.
All three systems are artificial intelligence. Only two of them are machine learning, because the rules engine never learned anything; a person wrote its logic. That split is the whole machine learning vs AI question in one workflow.
It matters most when a team must choose, explain or fix a system. This guide covers how the two terms differ and how each one works in practice. It also shows how to pick the right approach for a given problem, and which risk rules treat them differently.
What Is the Difference Between AI and Machine Learning?
Artificial intelligence is the broad field of building systems that handle tasks needing human-like judgment, such as recognizing images, planning routes or answering questions. Machine learning is one method within AI that learns patterns from data instead of following rules a person wrote. All machine learning is AI, but not all AI is machine learning.
The practical difference is where a system gets its logic. In classic AI a person writes the rules, while in machine learning the data shapes them. That one change decides what data you need, how you test the system and how easily you can explain a decision.
What Artificial Intelligence Means
AI names a goal more than a single technology. A system counts as AI when it handles a task that would normally need human judgment. It may do so with written rules, search, planning or learned models. Chess engines, credit policy engines and voice assistants all sit under the same label.
Policy bodies take the same broad view. The OECD definition of an AI system, updated in November 2023, covers any machine-based system that infers from its input how to generate predictions, content, recommendations or decisions. Every system in this guide is narrow AI, built for one task. General intelligence is a separate debate, covered in AI vs AGI vs ASI.
The field is old and wide, which explains much of the confusion. Early AI was mostly symbolic, built from logic and hand-coded knowledge, and those methods never went away. A modern enterprise artificial intelligence program usually runs rules, optimization and learned models side by side.
Scope also covers how people and machines share the work. When the aim is to support a human decision instead of replacing it, the topic becomes augmented intelligence vs artificial intelligence. That is a related but separate question.
What Machine Learning Means
In the 1950s, AI pioneer Arthur Samuel gave machine learning a definition that still holds. As MIT Sloan notes, he called it “the field of study that gives computers the ability to learn without explicitly being programmed.”
In practice, a team feeds a model many examples, and the model adjusts its internal parameters until its predictions match the known answers. Show it thousands of past claims marked fraud or genuine, and it learns which patterns tend to come before fraud. It then applies those patterns to claims it has never seen.
There are three main styles. Supervised learning trains on labeled examples, unsupervised learning finds structure in unlabeled data, and reinforcement learning improves through trial, error and reward. Many teams add a fourth, semi-supervised learning, which mixes a small labeled set with a large unlabeled one.
Learning from data sounds simple, yet the algorithm is the small part. The bulk of the effort goes into gathering data, testing results and watching the model after launch, which is where real projects succeed or stall.
Case Study
36% Cost Savings with AI/ML-Powered RPA in Insurance
Kanerika paired rules-based automation (RPA) with machine learning anomaly detection, NLP and image recognition for a health, travel and accident insurer. It cut claim processing time by 20%.
Read the Case Study →Where Deep Learning and Generative AI Fit
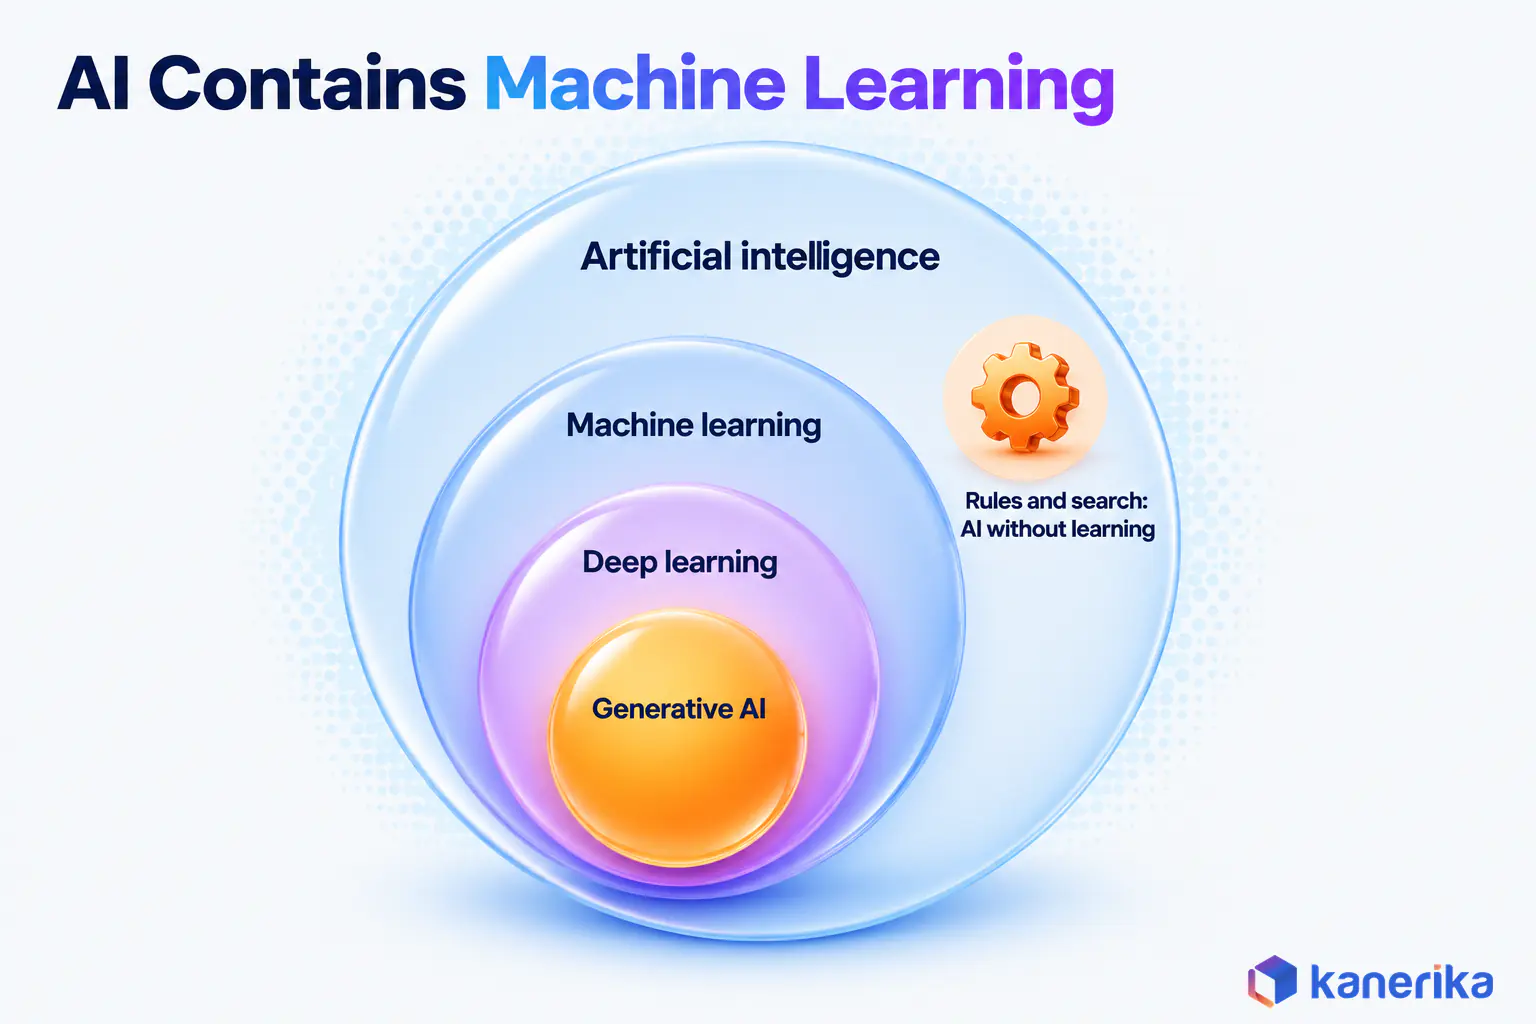
The cleanest way to hold these terms in your head is a set of nested circles. AI is the outer circle, machine learning sits inside it, and deep learning sits inside machine learning. Finally, generative AI, including large language models, forms the innermost ring.
Deep learning is machine learning built on neural networks with many layers, so it can learn straight from raw images, audio and text. Generative AI applies deep learning to create new content, such as text, images or code. A large language model is a deep learning model trained on huge amounts of text to predict the next word.
So is ChatGPT AI or machine learning? It is both, an AI product built on a machine learning model, and the circles show why both labels fit. The same logic covers image generators, coding assistants and voice cloning tools. Each inner ring adds capability, but it also adds data needs, compute cost and difficulty in explaining results.
What AI and Machine Learning Have in Common
The two terms differ in scope, yet they share more than the debate suggests. Both automate decisions that people used to make by hand, and both fail quietly when the inputs are wrong. A rules engine fed a stale policy table and a model trained on skewed history make the same kind of mistake, confident and wrong.
Both also need testing before launch and, just as much, monitoring after it, including data observability checks on the inputs they read. Neither one removes the need for clean data, clear ownership and a person who can overrule the output. Those three habits sit at the heart of responsible AI practice, whichever technique runs underneath.
Machine Learning vs AI: Side-by-Side Comparison
A side-by-side machine learning vs AI view helps because the two terms sit at different levels. One names a field and the other names a method, so the table sets AI as a whole against the machine learning part of it.
Read it with one question in mind: where does the system’s logic come from? Nearly every other row follows from that answer.
| Dimension | Artificial intelligence (the field) | Machine learning (a method inside AI) |
|---|---|---|
| Scope | Any system that performs tasks needing judgment | Systems that learn patterns from data |
| Goal | Act sensibly on a task, the way a skilled person would | Predict, classify or generate accurately from examples |
| How it works | Rules, search, planning, optimization or learned models | Trains a model on examples, then applies it to new inputs |
| Data needs | Can run on written logic with little data | Needs large volumes of relevant, often labeled data |
| Typical output | Decisions, plans, answers and actions | Scores, classes, forecasts and generated content |
| Examples | Tax-rule engine, route planner, chess engine | Spam filter, demand forecast, fraud score |
| Explainability | High for rules, lower once learned models are involved | Simple models are readable; deep networks are hard to read |
| Running cost | Low for rules, higher once models are added | Training, retraining, monitoring and compute |
| Typical failure | Rules go stale when policy or the world changes | Drift, skewed training data and overconfident errors |
The last two rows are where projects get surprised. A rules system costs little to run but needs people to update it, while a model only improves when someone retrains it on fresh data.
How Each One Learns
Machine learning learns in one way, from examples. A model sees inputs paired with outcomes, measures its own error and adjusts until that error shrinks. Its knowledge lives in numbers called weights rather than in sentences a person can read.
That has practical effects on where training can happen. For example, hospitals or banks often cannot pool their data. In that case teams can train a shared model with federated learning, which keeps raw records where they are.
AI’s learning process can be more diverse and complex. It may involve not just learning from data, but also from experiences, reasoning, and even from abstract concepts. AI systems might use a combination of approaches, including rule-based systems, expert systems, and machine learning – similar to how students often combine lectures, research, and paper writer service in USA to strengthen their academic work.
In plain terms, AI as a field can get its logic from people, search or data, while machine learning gets it from data alone. A rule written by an analyst can be read line by line, while the weights inside a neural network are much harder to read.
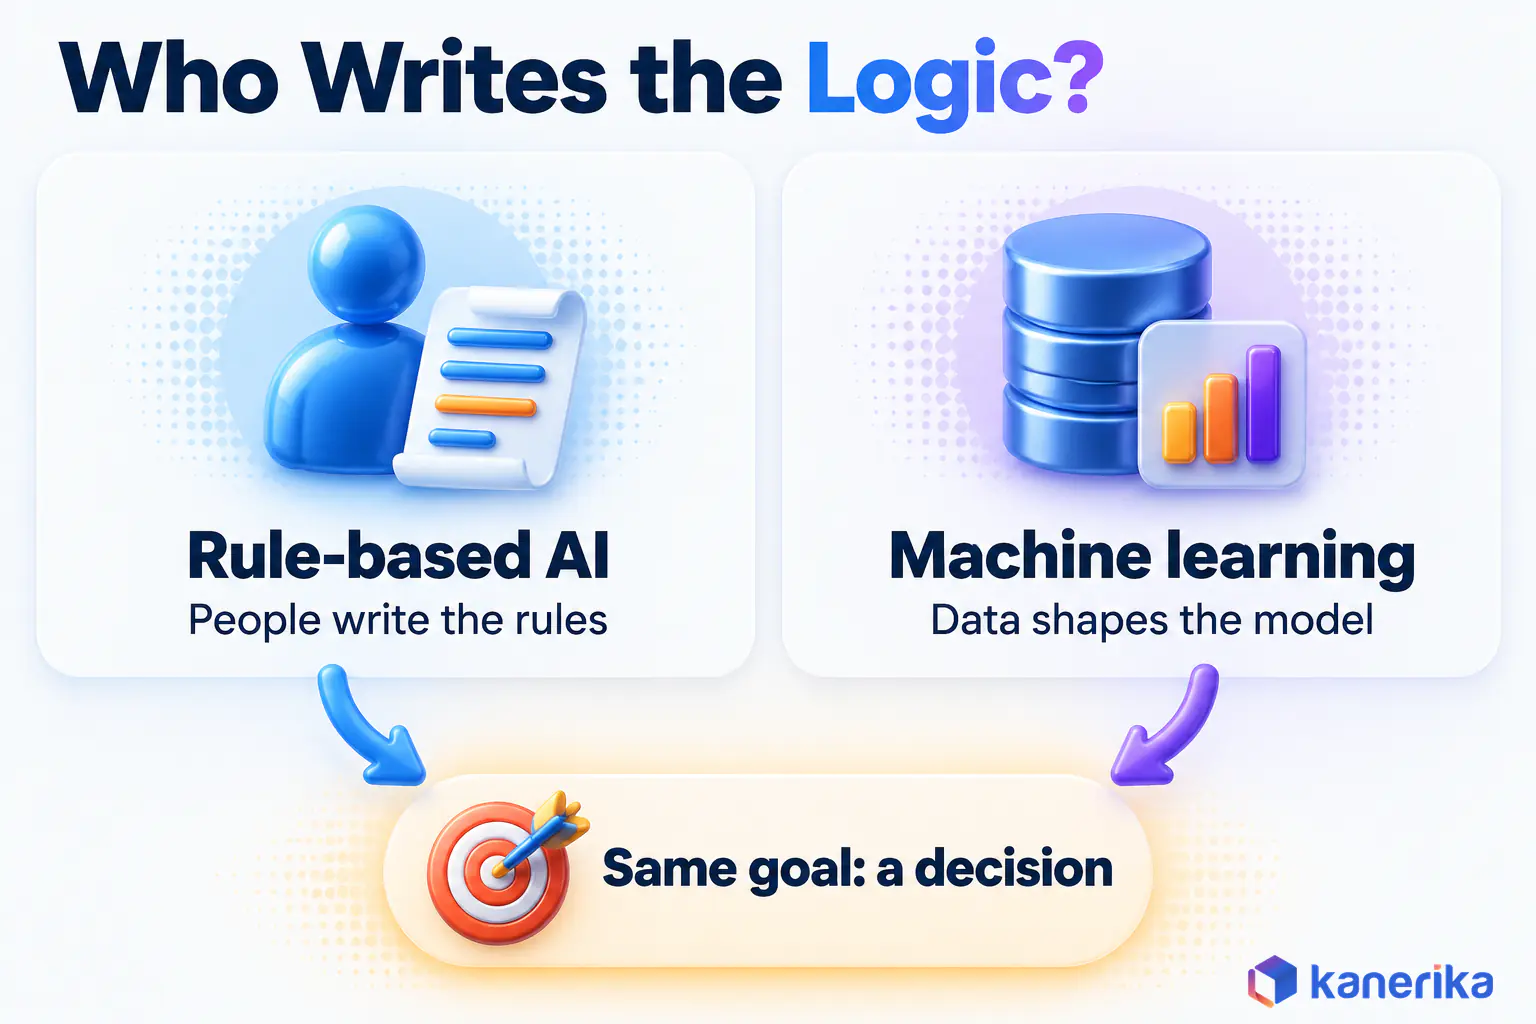
The difference shows up the first time an auditor asks why. A rule points to the line that fired, while a model needs explanation tools to show which inputs mattered.
Can AI Work Without Machine Learning?
Yes, and a lot of dependable AI still does. Rules engines and expert systems encode what specialists know as if-then logic. A tax engine that applies filing thresholds, or a credit policy that declines applicants below a set score, follows written rules every time.
Search and planning form the other large family. A route planner explores a road network to find the shortest path. A classic chess engine searches ahead through possible moves to pick the strongest one. Neither needs training data, because each relies on a clear model of the problem and a way to score each option.
These systems are cheap to run and easy to audit, which is why regulated teams keep them. Their weakness is change, since every new policy, product or exception means someone must edit the rules by hand. Where rules drive workflow tools, the line between AI and plain automation also blurs, a question covered in AI vs automation intelligence.
How AI and Machine Learning Work in Practice
Definitions only go so far, so it helps to see how each kind of system gets built and run. Three patterns cover nearly every enterprise project: a trained model, a rule-based system and a generative AI application.
How a Machine Learning Model Is Built
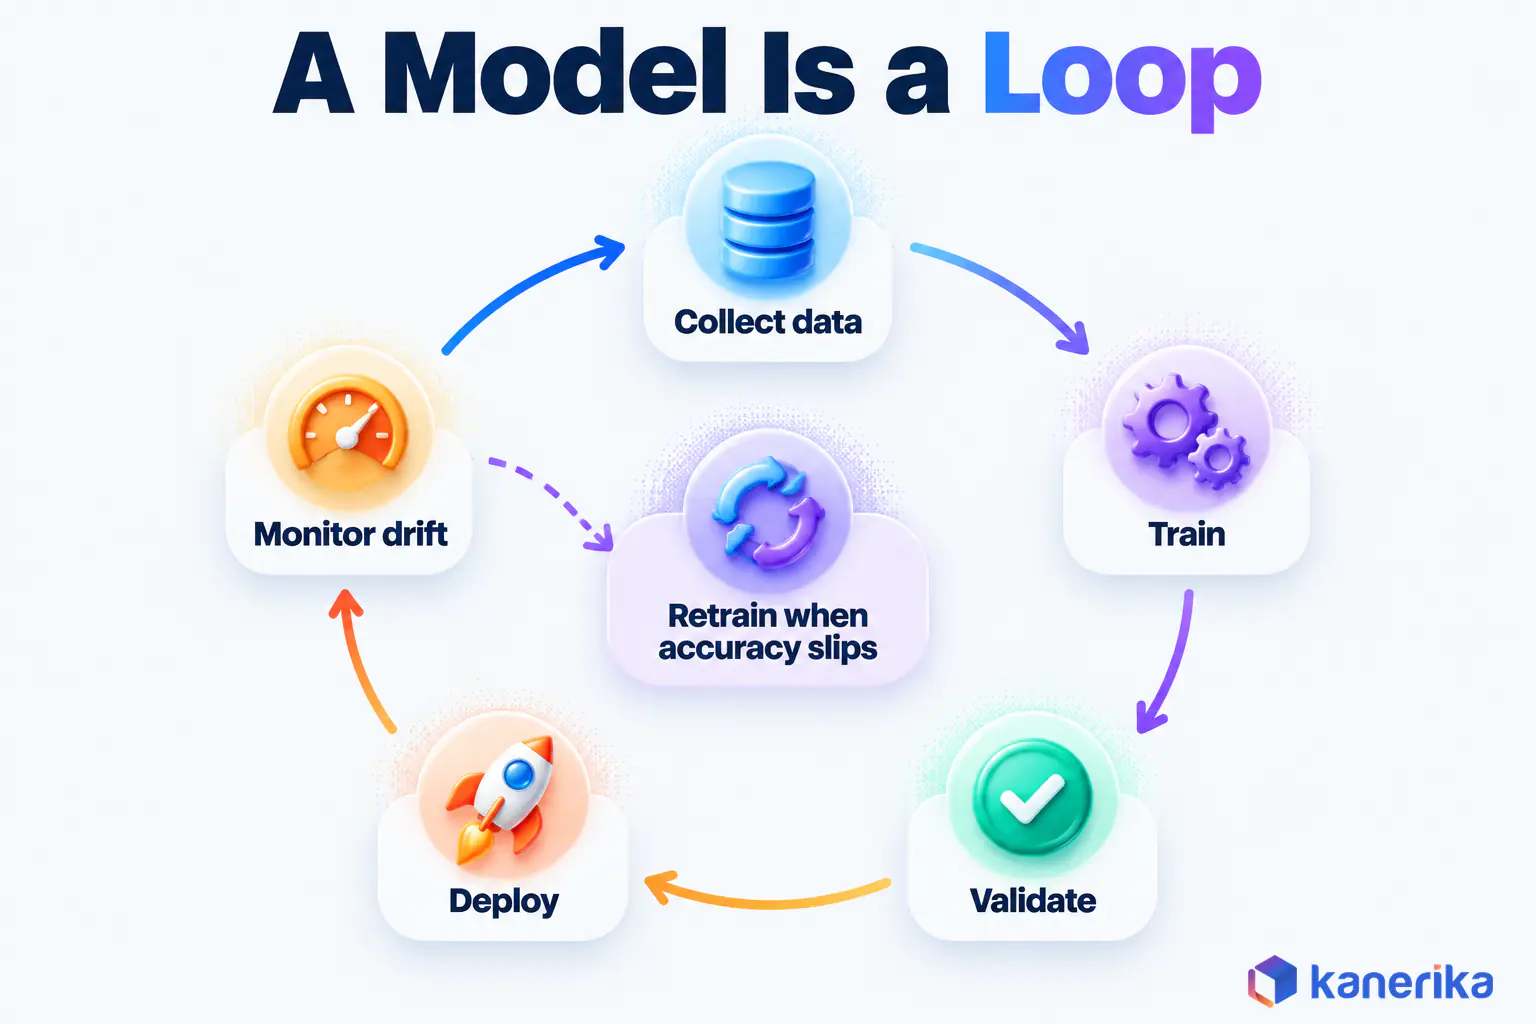
A model is less a product than a loop. The steps below repeat for as long as the model stays in use.
- Collect data. Gather historical records that include the outcome you want to predict, such as past claims marked fraud or genuine.
- Prepare features. Clean the data and turn raw fields into signals a model can use, such as claim amount relative to the policy limit.
- Train. Fit one or more algorithms to the training set and tune their settings.
- Validate. Test the model on data it never saw, and compare it with a simple baseline.
- Deploy. Put the model behind an application or workflow, with logging on every prediction.
- Monitor and retrain. Watch for drift as real-world data moves away from the training data, and retrain when accuracy slips.
The last step is where many models fail without anyone noticing. A fraud model trained on 2024 claims can lose accuracy by 2026 as fraud patterns change, even though no code has changed. The discipline that runs this loop at scale is called machine learning operations, or MLOps.
MLOps covers versioning data and models, automating retraining and recording which version made which decision. Good machine learning model management means anyone can answer, months later, why a model scored a claim the way it did.
When the model predicts a number such as next quarter’s demand, the same loop applies. The guide to machine learning in predictive analytics covers that forecasting side in depth.
In the claims queue, good MLOps means logging which model version scored each claim, so a disputed denial can be traced months later.
How a Rule-Based AI System Works
A rule-based system starts with people instead of data. Domain experts and analysts write the logic as explicit conditions, and an engine applies them in order. A claims rule might read: if the date of service falls after the policy end date, reject the claim.
Building one means interviewing experts, writing and testing the rules, and setting up a safe way to change them. The output is fully predictable, so it is easy to audit.
The trade-off is reach. Rules handle the cases someone foresaw and little else, so a new fraud trick sails through until an analyst writes a rule for it.
The contrast is clearest when the same claims decision is written both ways. In the Python sketch below, an analyst types the rule, while the model learns its logic from closed claims using scikit-learn’s HistGradientBoostingClassifier. The column names, the 10,000 limit and the 0.7 cut-off are illustrative, not industry values.
import pandas as pd
from sklearn.ensemble import HistGradientBoostingClassifier
from sklearn.metrics import average_precision_score
from sklearn.model_selection import train_test_split

# Rule-based AI: an analyst writes every condition
def route_by_rule(claim: dict) -> str:
    if claim["service_date"] > claim["policy_end_date"]:
        return "reject"
    if claim["amount"] > 10_000 or claim["prior_claims_12m"] >= 3:
        return "investigate"
    return "fast_track"

# Machine learning: the conditions are learned from labeled history
FEATURES = ["amount", "prior_claims_12m", "days_since_policy_start"]
history = pd.read_csv("closed_claims.csv")  # one row per closed claim
X_train, X_test, y_train, y_test = train_test_split(
    history[FEATURES], history["confirmed_fraud"],
    test_size=0.2, stratify=history["confirmed_fraud"], random_state=42,
)
model = HistGradientBoostingClassifier().fit(X_train, y_train)

# Fraud is rare, so check ranking quality, not plain accuracy
risk = model.predict_proba(X_test)[:, 1]
print("average precision:", round(average_precision_score(y_test, risk), 3))

# Runs only on claims that already passed the rules gate
def route_by_model(claim: dict, threshold: float = 0.7) -> str:
    score = model.predict_proba(pd.DataFrame([claim])[FEATURES])[0, 1]
    return "investigate" if score >= threshold else "fast_track"
Both functions return a routing decision, yet only the rule reads like policy. The model’s behavior moves every time it is retrained, so it needs version logging and drift checks.
The evaluation line matters too. Google’s machine learning course advises against accuracy on imbalanced datasets, and fraud is rare, so the sketch reports average precision instead.
How a Generative AI Application Works
A generative AI application is usually built around a large language model that someone else trained. The model learned from text through machine learning, but a business team uses it through prompts rather than by training it. That is why an LLM project often feels more like software integration than data science.
Enterprise builds usually add two layers around the model. Retrieval pulls approved documents, such as policy wording, into the prompt so answers rest on company facts. Guardrails then check inputs and outputs for sensitive data, off-topic requests and claims the sources do not support.
Testing changes too. Instead of one accuracy score, teams review samples of answers for correctness, tone and grounding. For a closer look at chat-style assistants versus content generation, see conversational AI vs generative AI.
Kanerika Service
AI Consulting Services
Kanerika designs and builds AI systems, from business rules and predictive models to generative AI applications with retrieval and guardrails. Each one runs on the data platform you already use.
Explore AI ServicesAI vs ML Examples in Everyday Business
The quickest test for any product is to ask where its logic comes from. Here is how six common business systems sort out once you ask that question.
| Example | Technique | Is it machine learning? |
|---|---|---|
| Email spam filter | Classifier trained on labeled messages | Yes, supervised learning |
| Retail demand forecast | Time-series model trained on sales history | Yes, predictive ML |
| Customer chatbot on an LLM | Language model plus document retrieval | Yes, the generative branch of ML |
| Credit policy rules engine | Written if-then rules | No, rule-based AI |
| Delivery route planner | Search over a road network | No, search and optimization |
| Visual quality check on a production line | Computer vision model trained on images | Yes, deep learning |
Four of the six learn from data, while two run on logic that people wrote. Even so, all six are fair to call AI.
Kanerika Service
Machine Learning Consulting Services
Kanerika builds and runs predictive and deep learning models, from data preparation and feature design to deployment, drift monitoring and retraining.
Explore ML ServicesRule-Based AI or Machine Learning: Which Fits Which Problem
Choosing well starts with the problem rather than the tool. The shape of the output and the data you already hold usually point to one side of the AI and machine learning split within minutes.
On the machine learning side there are two branches. Predictive ML returns a number or a class, such as a risk score, while generative AI returns language, images or code. The table treats generative AI as that second branch of machine learning, not as a separate camp.
| Problem | Pick | Data needed | Explainability | Main risk |
|---|---|---|---|---|
| Stable policy logic, such as eligibility checks | Rule-based AI | Little beyond the rules themselves | High, every decision traces to a rule | Rules go stale as policy changes |
| A score, class or forecast from past outcomes | Machine learning (predictive) | Labeled history with enough examples of each outcome | Medium, depending on model type | Drift and skewed history |
| Patterns in images, audio or sensor streams | Machine learning (deep learning) | Large labeled sets of images or signals | Low without added tools | Errors on unfamiliar inputs |
| Drafting, summarizing or answering in language | Machine learning (generative branch) | Approved documents for retrieval, plus test questions | Low, needs grounding checks | Fluent answers that are wrong |
| Scheduling or routing under fixed constraints | Rule-based AI (search and optimization) | A clear model of the constraints | High | Poor plans if the constraints are wrong |
Start With the Output
A useful shortcut is to look at the output first. If it is a yes or no under known policy, rules usually win. If it is a number learned from history, predictive ML wins. When the answer has to be written in words, the generative branch of machine learning takes over.
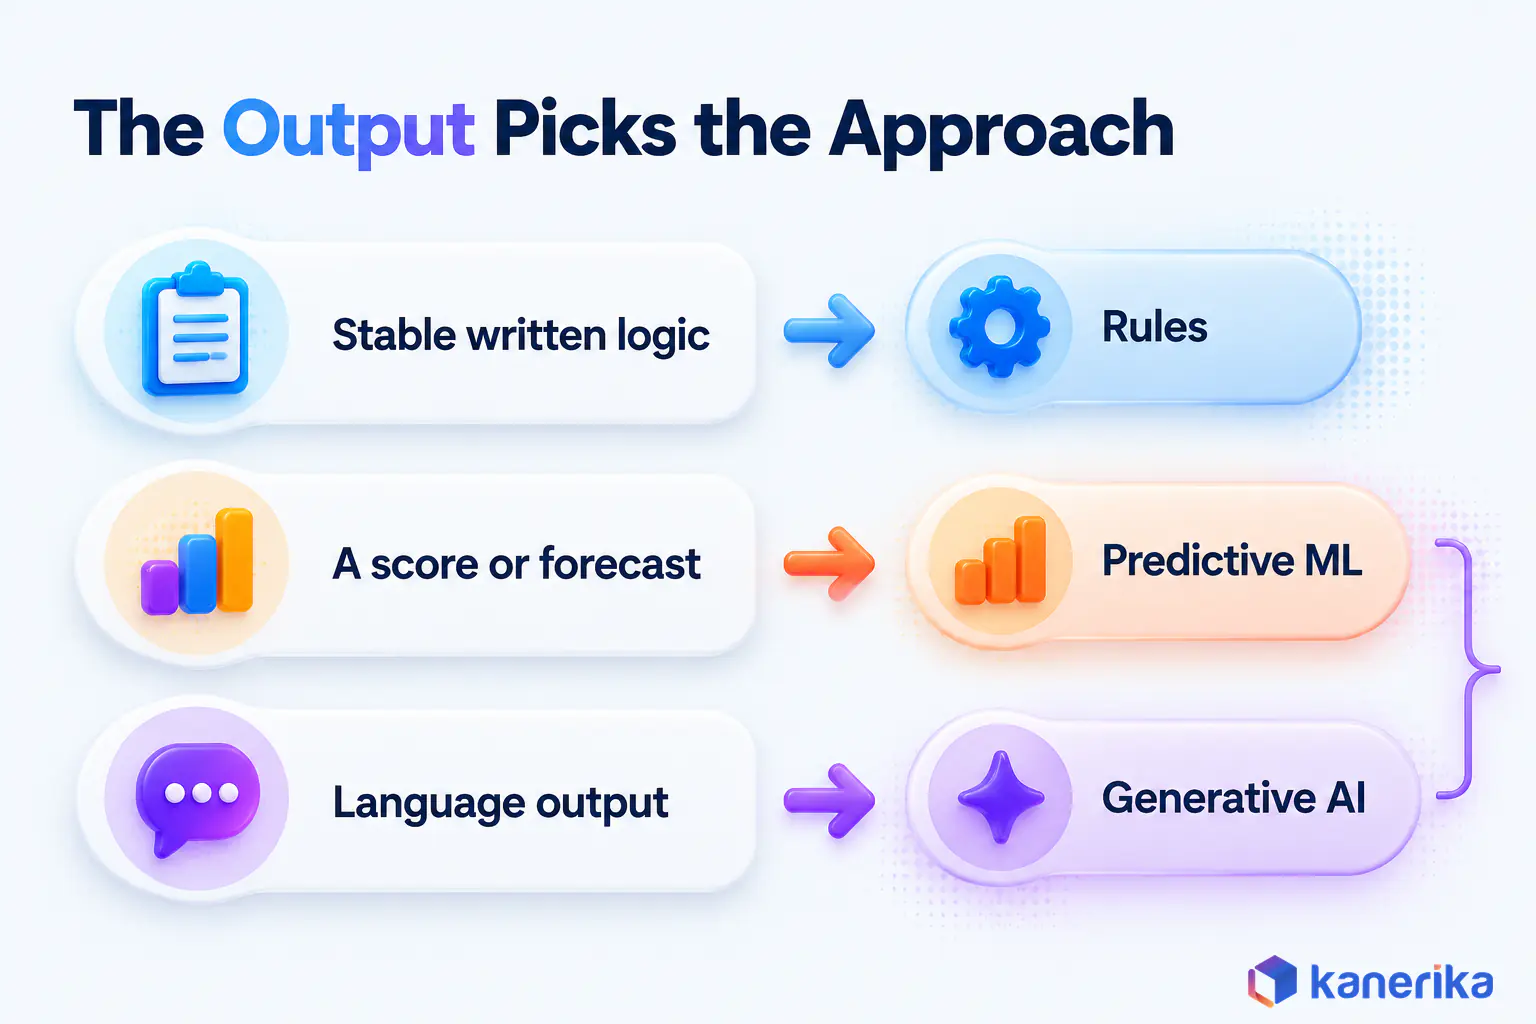
Running cost follows the same order, because rules are cheapest, predictive models add retraining and generative AI adds a charge per model call.
Five Questions to Ask Before You Choose
Five questions settle most choices before anyone writes code. Answer them with the people who own the process, and bring the data team in early.
- Is the logic stable and writable as rules? If experts can state it in a page of conditions that rarely change, start with rules.
- Do you have labeled history? Predictive ML needs past examples with known outcomes, in enough volume to cover the cases that matter.
- Is the output a number, a class or language? Numbers and classes point to predictive ML, while free text points to generative AI.
- How much error can you tolerate? A product suggestion can miss often, while a claim denial needs a far lower error rate and a human check.
- Who must explain the decision? If a regulator, auditor or customer can ask why, favor rules or simpler models, or plan explanation tools from day one.
Google’s engineers reach the same order from the build side. The first of Google’s Rules of Machine Learning is “Don’t be afraid to launch a product without machine learning,” because machine learning requires data. Its third rule is “Choose machine learning over a complex heuristic.” So start with rules, and switch to a model once the rule set grows too tangled to test or keeps missing new cases.
The same thinking helps when a vendor calls its product “AI-powered.” Ask three things before you trust the label.
- What sits underneath: written rules, a trained model or a third-party LLM?
- What data was it trained or configured on, and does that data look like yours?
- How was it evaluated, on which test set, and how often is it checked after launch?
A vendor that cannot answer those plainly is probably selling the label more than the capability.
AI Assessment
Not Sure Which Approach Your Use Case Needs?
Take Kanerika’s AI Maturity Assessment to see how ready your data, skills and governance are for rules, predictive models or generative AI.
Start Your AI Assessment →What Each Approach Needs in Data, Skills and Cost
Budgets differ less in the build than in the years after it. The table below is directional, since real costs depend on scale, vendor and how much data work is already done.
| Approach | Data | Skills | Cost profile |
|---|---|---|---|
| Rule-based AI | Policy documents and expert knowledge | Business analysts, domain experts, rules developers | Low build and run cost, with steady effort to keep rules current |
| Predictive ML | Clean, labeled historical data | Data engineers, data scientists, MLOps engineers | Higher build cost, then ongoing retraining and monitoring |
| Generative AI (ML branch) | Approved documents for retrieval and evaluation sets | Software engineers, evaluation skills, security review | Lower build cost on a hosted model, with usage-based run cost that grows with traffic |
Data work is the line item teams most often underestimate. Rules need little of it, while predictive models depend on careful data preparation before any training starts. Poor data quality is also among the most common AI adoption challenges.
Worked Example: Routing Insurance Claims
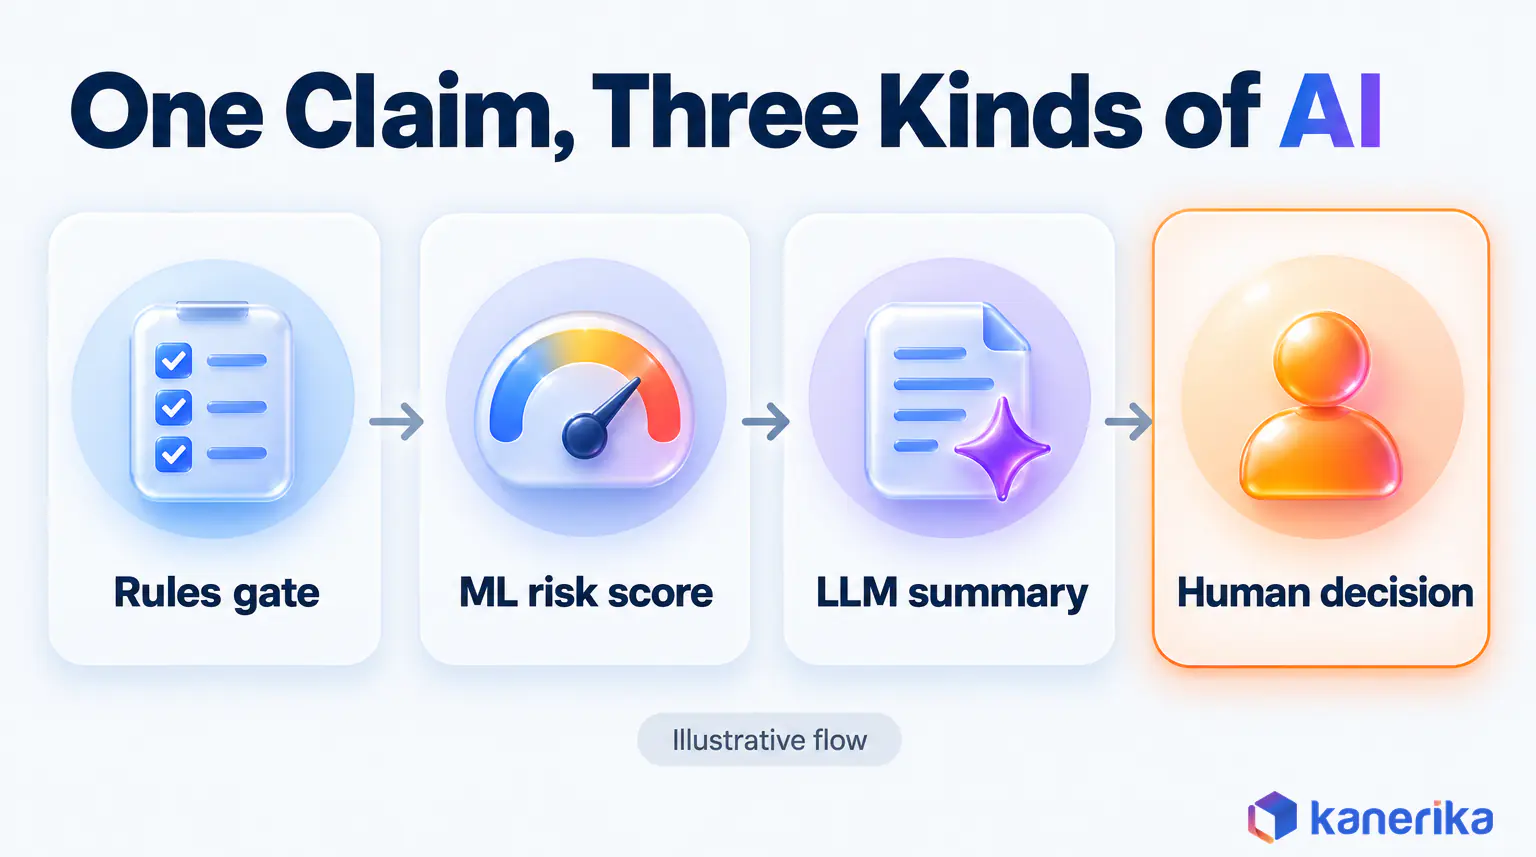
Back to the claims queue from the opening, this time as a design. The flow below is illustrative, and its stages are generic rather than taken from any one insurer.
First, a rules gate checks completeness and policy validity. These checks are fixed and auditable, so rules are the right tool, and nothing that fails them reaches a model.
Second, a predictive model scores each remaining claim for fraud risk, trained on past claims with known outcomes. Low-risk claims move toward fast payment, while high-risk ones go to a specialist investigator.
Third, a large language model drafts a short summary of the claim file and cites the documents it used. The adjuster reads the summary, checks the flagged items and makes the call.
Each stage uses the approach that fits its job, and a person owns the result. For how fraud models are built and tuned, see this guide to AI in fraud detection.
The design also makes failures easier to trace. If paid claims later prove fraudulent, the team can check whether the rules, the score or the human review let them through. Then it fixes that one stage.
Strengths, Limits and Risks of AI and Machine Learning
Every approach buys something and gives something up. The table sets out the main trade-off for each one, which is often the fastest way to rule an option out.
| Approach | Main strength | Main limit |
|---|---|---|
| Rule-based AI | Predictable, cheap to run and easy to audit | Brittle when cases fall outside the rules |
| Predictive ML | Finds patterns people miss and adapts through retraining | Needs good labeled data, and can drift or inherit bias |
| Deep learning | Handles images, audio and text at scale | Hard to explain, and needs large data and compute |
| Generative AI (ML branch) | Produces fluent language and code from prompts | Can state wrong answers with confidence, so needs grounding and review |
Those limits also shape risk. A rules error repeats the same way every time, which makes it easy to spot and fix. A model error can be subtle and uneven, hitting one customer group harder than another.
Risk and Governance Differences
Regulators and standards bodies mostly govern AI by what a system does and how much harm it could cause, whether or not it learns. Machine learning still draws extra scrutiny, because learned behavior is harder to predict and explain.
In the United States, NIST released the AI Risk Management Framework 1.0 on January 26, 2023. Its core organizes the work into four functions: govern, map, measure and manage. On July 26, 2024, NIST added a Generative AI Profile, NIST AI 600-1, for risks specific to generative models.
In Europe, the EU AI Act entered into force on August 1, 2024. Its obligations arrive in phases, and the AI Omnibus, in force since July 27, 2026, pushed back the high-risk dates.
| Date | What applies under the EU AI Act |
|---|---|
| February 2, 2025 | Prohibited AI practices and AI literacy duties |
| August 2, 2025 | Obligations for general-purpose AI models |
| August 2, 2026 | The Act becomes generally applicable |
| December 2, 2027 | High-risk rules for Annex III systems (as amended by the AI Omnibus) |
| August 2, 2028 | High-risk rules for Annex I systems (as amended by the AI Omnibus) |
Many organizations also adopt ISO/IEC 42001, the international standard for AI management systems. Whatever the framework, models that affect people need decisions you can explain, and explainable AI techniques help show which inputs drove a prediction.
Rule-based systems pass this test almost by default. Learned models need it designed in, with documented training data, test results and a named owner who can answer for each version. That record is the backbone of any AI governance program.
Build, Fine-Tune or Buy
Once the approach is clear, the next choice is how to get it, so cost and speed come into play. Buying a packaged tool is fastest when the problem is common, such as invoice capture or email triage, and your data looks like everyone else’s.
Fine-tuning, by contrast, sits in the middle. A team takes an existing model, often a language model, and adapts it with its own examples so it uses the right terms and formats. If the gap is missing company facts rather than style, retrieval is often the cheaper fix, a trade-off covered in RAG vs fine-tuning.
Building a custom model makes sense when the data or the decision is your edge, as with fraud patterns specific to your book of business. It costs more and takes longer, so it should be reserved for the problems where a generic tool would leave money on the table.
Many enterprises end up with a mix, buying the commodity pieces and building the few models that set them apart.
How Kanerika Helps Enterprises Choose and Ship the Right Approach
Kanerika starts with the problem and the data, then picks the technique, which is the order this guide argues for. The work runs in four stages, each with a clear exit test.
- Assess. Map the decision, its owner, the cost of an error and the data that exists for it.
- Select. Choose rules, predictive ML, generative AI or a mix, using the five questions above.
- Pilot with evaluation. Test against a baseline on real data before anyone scales it.
- Deploy and monitor. Ship with logging, drift checks and a named owner for each model.
The insurance work shows the mix in action. For a health, travel and accident insurer, Kanerika combined rules-based automation (RPA) with machine learning anomaly detection, NLP and image recognition. The program cut claim processing time by 20%, improved operational efficiency by 25% and delivered a 36% increase in cost savings.
Teams that need predictive models can start with machine learning consulting services, while programs that mix rules, models and LLMs fit AI consulting services. Either way, the first deliverable is a clear choice of approach, backed by a measured pilot.
Case Study
80% Ticket Auto-Resolution with LLM-Driven AI
Kanerika built LLM-driven ticket response for a B2B SaaS company with SMB clients in 40+ countries. It auto-responded to 80% of tickets and cut staffing cost by 70%.
Read the Case Study →Machine Learning vs AI: The Bottom Line
AI is the field and the goal, meaning systems that handle tasks needing judgment. Machine learning is the method inside it that learns from data, and deep learning and generative AI are deeper rings of the same circle. So the machine learning vs AI choice is never abstract. It is about which kind of AI fits the job in front of you.
Use rule-based AI when the logic is stable, written down and must be explained line by line. Predictive machine learning is the better pick when you hold labeled history and need a score, class or forecast. Its generative branch fits when the output must be language, and in every case a person should stay on the decisions that matter.
Strong systems often chain rules with both branches of machine learning, as the claims example shows. AI names the goal, and machine learning is the right tool when your data can teach the system better than your rules can.
Frequently Asked Questions
Are machine learning and AI the same thing?
No. Artificial intelligence is the broad field of building systems that handle tasks needing human judgment. Machine learning is one method inside that field, where a system learns patterns from data instead of following rules a person wrote. Every machine learning system counts as AI, while plenty of AI, such as rules engines, involves no learning.
What are the 4 types of AI?
A common textbook grouping lists four types by capability. Reactive machines respond to the present input only, and limited memory systems use recent data. Theory of mind AI would understand beliefs and intentions, and self-aware AI would have its own consciousness. Only the first two exist in practice, and every business system in use belongs to them.
Is ChatGPT AI or ML?
ChatGPT is both. It is an AI product built on a large language model. That model was trained with machine learning, specifically deep learning on large amounts of text. Users interact with it through prompts, without training it themselves, which is why it feels like software rather than a machine learning project.
What are the basics of AI and ML?
AI is the goal of getting computers to handle tasks that need judgment, using rules, search or learned models. Machine learning is the data-driven route, where a model trains on examples, gets tested on new data and is monitored once deployed. Deep learning and generative AI are more advanced forms of machine learning.
Does machine learning create AI?
Machine learning is one of the main ways to build AI, though it is not the only one. When a model learns to spot fraud or recognize images from examples, the result is an AI system. Rules engines and planning algorithms create AI too, using logic that people write instead of patterns learned from data.
Is NLP AI or ML?
Natural language processing is a branch of AI focused on understanding and producing human language. Early NLP relied on grammar rules and dictionaries, while modern NLP relies mainly on machine learning and deep learning models. Large language models are the latest step, so NLP today sits where AI, machine learning and linguistics overlap.
Is generative AI the same as machine learning?
Generative AI is a subset of machine learning. It uses deep learning models, such as large language models and image generators, to create new text, images or code. Machine learning is much broader and also covers predictive models that return scores, classes or forecasts. All generative AI is machine learning, while much of machine learning only predicts.
How is deep learning different from AI and machine learning?
Deep learning is a type of machine learning that uses neural networks with many layers. It learns directly from raw images, audio and text, so it handles tasks like speech recognition and image inspection well. It needs more data and compute than other machine learning methods, and its decisions are harder to explain.
When should a company use machine learning instead of generative AI?
Use predictive machine learning when you hold labeled history and the output is a number or a category. Examples include a fraud score, churn risk or demand forecast. Choose generative AI when the output is language, such as summaries or answers. Many workflows use both, with a model scoring a case and an LLM explaining it.
Is AI better than machine learning?
Neither is better, because machine learning is a part of AI and the question is which approach fits a problem. Written rules suit stable, explainable logic. Predictive machine learning suits scoring and forecasting from history, and generative AI suits language tasks. The right choice depends on your data, your error tolerance and who must explain each decision.
Is AI a machine or software?
AI is software. It runs as code and models on ordinary hardware, from phones to cloud servers, sometimes with specialized chips such as GPUs to speed up training. A robot or a self-driving car is a machine that uses AI software for perception and decisions, so the intelligence lives in the software layer.
What is the most common type of AI used today?
Every AI system in business use today is narrow AI, and machine learning powers much of it. It covers systems trained for one job, such as spam filtering, product recommendations, fraud scoring and demand forecasting. Generative AI assistants built on large language models are also narrow AI, because each one handles a defined range of language tasks.
What are the 4 types of machine learning?
The four usual types are supervised, unsupervised, semi-supervised and reinforcement learning. Supervised learning trains on labeled examples, and unsupervised learning finds structure in unlabeled data. Semi-supervised learning mixes a small labeled set with a large unlabeled one, and reinforcement learning improves through trial, error and reward. Supervised learning powers most predictive business models.
Why do so many AI projects fail?
AI projects usually stall for reasons unrelated to the algorithm. Common causes are unclear business goals, poor or unlabeled data, no baseline to measure against, weak ownership after launch and models that drift without monitoring. Picking the wrong approach also hurts, such as training a model where a few written rules would have worked better.
Can AI exist without machine learning?
Yes. Rules engines, expert systems, search and planning algorithms are all AI that never learn from data. A tax engine applying filing thresholds or a route planner finding the shortest path works from logic people defined. These systems need little or no training data, which makes them cheaper to run and easier to audit.
What comes first, AI or ML?
AI came first, both as an idea and as a field. Early AI systems relied on logic and hand-written rules. Machine learning grew inside the field as a way to let computers learn from examples, and AI pioneer Arthur Samuel defined it in the 1950s. Deep learning and generative AI came later still, as deeper branches of machine learning.
Does AI replace machine learning?
No, because machine learning is part of AI and powers most modern AI products. Generative AI, for example, runs on deep learning models trained through machine learning. In real systems the approaches work together, with rules for fixed policy checks, predictive models for scores and generative models for language. A person still approves important decisions.
What is an example of AI that is not machine learning?
A credit policy rules engine is a clear example. It approves or declines applications using if-then rules that analysts wrote, and it never learns from data. Other examples include delivery route planners, classic chess engines that search possible moves and scheduling optimizers. Expert systems that encode a specialist’s knowledge as written logic count too.