TL;DR
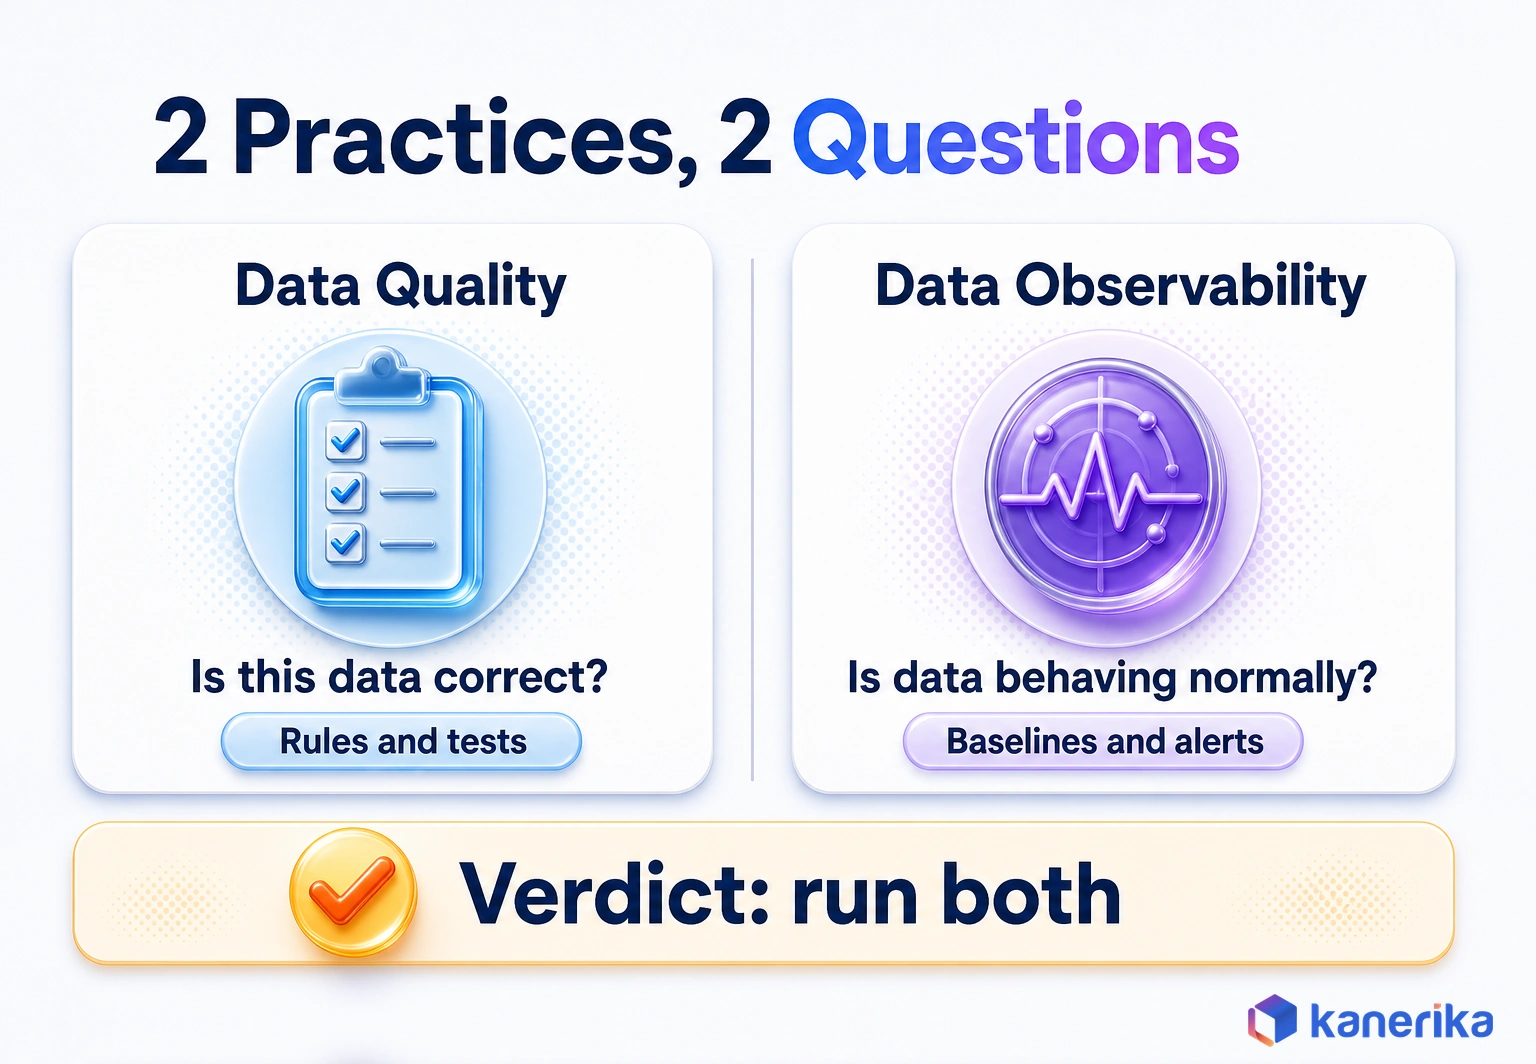
In data observability vs data quality, fund quality first when no one has defined good data, and fund observability first when rules exist but users still find breaks before your team does. Data quality sets the standard, so it defines the rules for accuracy, completeness, validity and timeliness that a dataset must meet. Data observability then watches production pipelines for changes in freshness, volume, schema, value distribution and lineage. Quality tests catch the known problems someone wrote rules for, while observability catches silent breaks nobody predicted, such as a feed that stops updating. Mature teams therefore run both in one pipeline, with contracts at ingestion, tests in transformation, monitors in production and lineage for impact. Neither replaces the other, so the real decision is which gap is costing you more right now.
Key Takeaways
- Data quality defines what fit-for-purpose data looks like and then tests records against that definition.
- Data observability watches production data for changes in freshness, volume, schema, distribution and lineage, even when no rule exists.
- Quality catches failures of meaning, such as duplicates and impossible values, while observability catches failures of movement, such as stale or shrinking loads.
- Fund quality first when definitions and owners are missing, and fund observability first when users spot broken data before engineers do.
- Platforms such as Purview, Databricks and Snowflake now ship native quality and monitoring features, so start there before buying a separate tool.
- Data contracts connect the two, because one agreement states the rules a test enforces and the freshness a monitor watches.
The Quality Checks Passed. The Data Was Three Days Old.
Picture a retail replenishment table that feeds next week’s store orders. Every morning, a suite of tests runs against it before the orders go out. Product IDs are never null, each SKU and store pair is unique, and on-hand quantities fall inside a valid range. All of it passes, so the dashboard shows green.
Then a regional manager calls about empty shelves. The team digs in and finds that an upstream inventory feed stopped sending files three days earlier. The table never broke. Instead, it kept serving Monday’s stock counts on Thursday, and every row was still valid.
Nothing in the test suite was wrong, because a stale row can be complete, unique and valid all at once. What the team lacked was a signal that said when the data had stopped moving.
That gap is the data observability vs data quality question in a single incident. The scene is a composite, but plenty of data teams have lived some version of it. This guide explains what each practice does, which failures each one catches and misses, and how the two fit into one pipeline. It then ends with a decision matrix for which one to fund first.
Data Observability vs Data Quality: The Short Answer
The simplest way to separate the two is to ask which question each one answers, because their goals overlap more than their methods do.
Data quality asks whether a dataset is fit for its purpose. It first defines the standard through dimensions such as accuracy, completeness and validity, then checks data against rules that encode it. For example, a quality rule might say that every invoice needs a customer ID, or that a discount can never exceed 40%. When a record breaks a rule, the check fails and someone fixes the record or its source.
Data observability asks whether production data is behaving the way it normally does. It watches pipelines and tables continuously for signals such as freshness, row volume, schema changes and shifts in value distribution. It does not need a rule for every failure, because it learns a baseline and flags departures from it. Say a table usually lands 2 million rows by 6 a.m. but arrives with 200,000 at noon. A monitor raises an alert, even though every one of those rows passes its tests.
| Practice | Question it answers | Works by | Catches best |
|---|---|---|---|
| Data quality | Is this data correct and fit for use? | Explicit rules and tests | Known problems, such as nulls and duplicates |
| Data observability | Is production data behaving normally? | Learned baselines and anomaly alerts | Silent breaks that no rule anticipated |
Put simply, quality defines what good looks like, while observability tells you when production stops looking like it. You need the first to know what to protect and the second to know when that protection has failed.
Kanerika Service
Data Engineering Services From Kanerika
Kanerika builds data platforms with quality checks on every pipeline and lineage tracked from source to report, so problems surface before users find them.
Explore Data Engineering ServicesWhat Is Data Quality?
Data quality is the degree to which data is fit for the job someone needs it to do. A customer address that works for a marketing segment may still be useless for a delivery route, so quality always depends on use. That is why quality work starts with a definition before any tool gets involved.
Teams first agree on what accurate, complete and timely mean for a given dataset. They then write those definitions down as rules and test against them. Skipping that step shows up later as wrong forecasts, failed audits and weeks of rework. Kanerika’s breakdown of the cost of bad data quality shows how those losses build up across a business.
The Six Dimensions of Data Quality
Quality is usually measured across a short list of dimensions. The UK Government Data Quality Framework, for example, uses the six core dimensions published by DAMA UK, shown in the table below. Lists still vary between frameworks, and some teams add a seventh dimension that matters to their own data.
| Dimension | Plain meaning | Example check |
|---|---|---|
| Accuracy | Values match the real-world fact | Ship-to ZIP code matches the carrier’s address file |
| Completeness | Required values are present before data is used | Every order has a customer ID |
| Consistency | The same fact agrees across systems, such as CRM and billing | Customer status is active in both systems |
| Timeliness | Data is available when needed and recent enough to use | Inventory snapshot is less than 24 hours old |
| Uniqueness | Each real-world entity appears once, so nothing is double counted | One row per SKU and store pair |
| Validity | Values follow the required format and allowed range | Order date is a real date rather than a future one |
For a stricter model, ISO/IEC 25012 defines 15 characteristics. It also splits them into those inherent to the data itself and those that depend on the system holding it.
Notice that timeliness sits on the quality list too. A quality team can write a freshness rule, but only for the tables it knows to watch. The replenishment failure above slipped through because nobody had written that rule for that feed.
How Data Quality Is Enforced
Quality is enforced through a loop of work rather than a single tool. Five activities carry most of the load.
- Profiling: scan the data to learn its real shape, null rates and value ranges before writing any rules. Kanerika’s guide to data profiling covers the techniques.
- Rules and tests: encode expectations as checks that run on load or during transformation, such as not-null, unique and accepted-value tests.
- Cleansing: correct, standardize or quarantine the records that fail, then trace each one back to its source.
- Stewardship: give each critical dataset a named owner who decides what its rules should be, as set out in a data governance framework.
- Issue tracking: log every failure with a cause and a fix, so recurring problems get solved at the source.
This loop is precise, because every check states exactly what good means. Still, it is limited to what someone thought to write down. That limit is where observability comes in.
What Is Data Observability?
Data observability is the ability to understand the health of data in production from the signals it gives off. The idea comes from software engineering, where teams track systems through metrics, logs and traces instead of waiting for users to report outages. Applied to data, it means watching tables and pipelines continuously so that teams notice when their behavior changes.
The payoff is coverage. A team might write careful tests for 50 critical tables, while an observability tool can baseline every table in the warehouse without hand-written rules. It therefore catches the failures nobody predicted, and those are often the ones that hurt.
The Five Pillars of Data Observability
Monte Carlo, the vendor that popularized the term, groups observability signals into five pillars. Its newer list says quality, whereas older versions said distribution. Both names still describe the same idea, which is values drifting away from their normal pattern.
| Pillar | What it watches | Example alert |
|---|---|---|
| Freshness | When a table last updated | Inventory feed has not landed in 72 hours |
| Quality (distribution) | The shape of values, such as null rates, ranges and averages | Null rate on a discount column jumps from 1% to 30% |
| Volume | Row counts and file sizes compared to normal | Daily orders load arrives with 90% fewer rows than usual |
| Schema | Columns, types and structure | A source renames customer_id to cust_id without warning |
| Lineage | Upstream sources and downstream consumers | Shows which dashboards break when the table fails |
For a deeper look at each pillar, as well as how teams roll the practice out, see Kanerika’s guide to data observability.
What Observability Cannot Tell You
Observability sees change, but not correctness. Suppose a pipeline has applied the wrong currency rate every day for a year. To a monitor, those values look normal, because wrong has become the baseline. Only a rule that knows the correct rate can catch it, so this is quality territory.
The same limit applies to business logic. A monitor will not know that a refund should never exceed the original order. Nor will it know that a policy start date must come before its end date. Those are statements about meaning, so they live in quality rules written by people who understand the business.
Checklist
Data Engineering Checklist
Work through the pipeline, testing and monitoring checks that keep data accurate and on time, from ingestion rules to production alerts.
Get the Checklist →Data Observability vs Data Quality: Side-by-Side Comparison
Seen side by side, the two practices differ less in goal than in method. Both exist so that people can trust the numbers in front of them. Quality gets there by checking data against a definition, while observability gets there by watching data for change.
| Factor | Data quality | Data observability |
|---|---|---|
| Question it answers | Is this data correct and fit for use? | Is production data behaving normally? |
| What it examines | Values in records and columns | Pipelines, tables and their metadata over time |
| Method | Explicit rules and tests | Learned baselines, anomaly detection and lineage |
| Timing | At load, during transformation or in scheduled audits | Continuously, while data runs in production |
| Typical owner | Data stewards and domain owners | Data engineering and platform teams |
| Output | Pass or fail results and quality scores | Alerts, incidents and impact maps |
| Scale | Grows with every rule people write, so coverage stays narrow | Covers many tables with little setup per table |
| Strength | Precise on known, defined problems | Finds silent breaks before users do |
| Failure it misses | Problems nobody wrote a rule for | Data that is wrong in a steady, consistent way |
The last row matters most, because each practice is blind exactly where the other one sees. That is why this comparison ends in a pairing rather than a winner.
Which Failures Each One Catches (and Misses)
A comparison of methods helps, but data teams think in incidents. The clearer test is to take real failure types and ask which practice would raise the flag first. The eight below show up often in enterprise pipelines, so they make a fair test.
| Incident | Caught by quality tests? | Caught by observability? | Best first line of defense |
|---|---|---|---|
| Upstream feed stops and the table goes stale | Only if a freshness rule exists for that table | Yes, through a freshness monitor | Observability |
| Source renames or drops a column | Often, when a test or load fails | Yes, through a schema change alert | Observability, backed by a data contract |
| Row count drops by half overnight | Only if a volume rule exists | Yes, through a volume anomaly | Observability |
| Duplicate customer records after a merge | Yes, through a uniqueness test | Sometimes, when counts spike | Quality |
| Discount stored as 50 instead of 0.50 | Yes, through a valid-range test | Yes, through a distribution shift | Quality |
| Wrong currency rate applied for months | Yes, once a reference check exists | No, because the error is the baseline | Quality |
| Refund larger than its original order | Yes, through a business rule | No, since nothing about the pattern changes | Quality |
| Null spike in an optional field nobody tests | No | Yes, through a null-rate anomaly | Observability |
What the Pattern Shows
Read the right-hand column and the split comes out even, four and four. Observability leads on failures of movement, such as staleness, schema drift and volume swings. Quality leads on failures of meaning, such as duplicates, impossible values and broken business logic.
Neither column is empty, so a stack built on one practice alone leaves about half of these incidents for a user to find. Try the same exercise on your own incident log from the past quarter. Tag each incident by the practice that would have caught it first, and then the gap in your stack becomes obvious.
Talk to Kanerika
Find the Failures Your Stack Misses
Bring a few recent data incidents. Kanerika’s team will map which ones quality rules or monitors would have caught and show where your coverage stops.
Book a Data Quality Review →Do You Need Both, or Do They Compete?
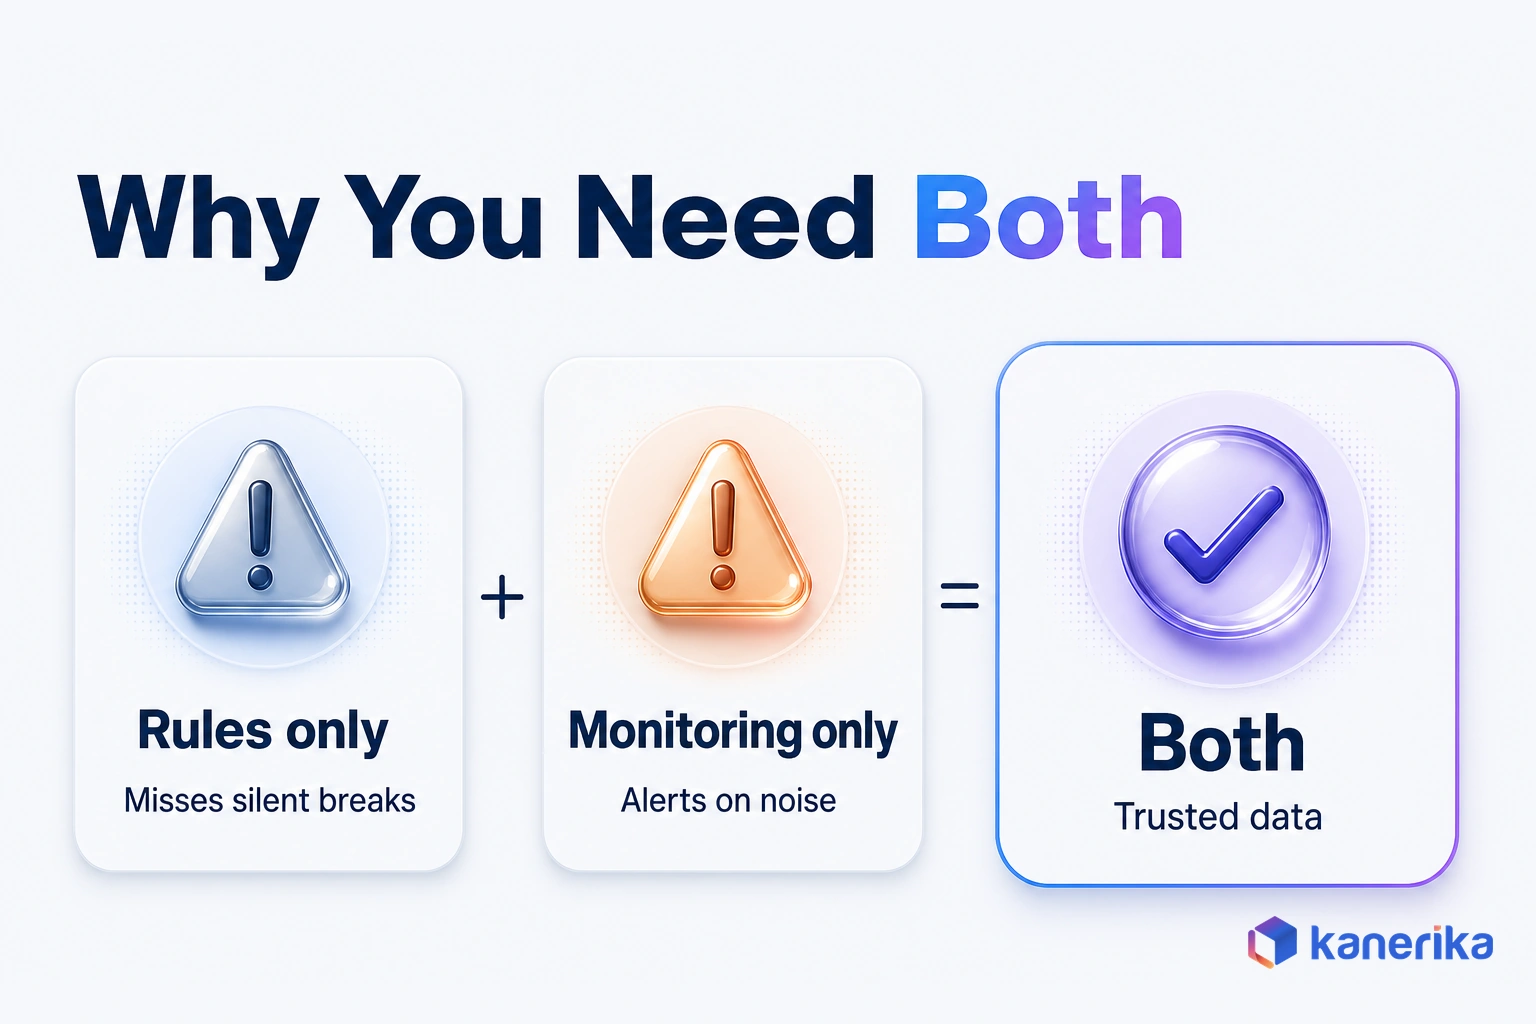
They do not compete, because each one fixes the other’s weakness. Run either one alone, though, and a predictable gap opens up.
Observability without rules tends to drown in noise. A monitor might flag that a table’s null rate rose from 2% to 4%. Nobody can say whether that matters, so the alert gets muted.
After a few weeks of muted alerts, the team stops trusting the tool at all. Rules supply the missing context, because a rule tied to a business owner tells you which changes are worth a call.
Rules without monitoring miss the silent breaks. Tests only run on the tables and conditions someone thought of, so a stale feed or a quietly shrinking load slips straight past them. Monitoring supplies the coverage that hand-written rules never reach. In dbt projects, dbt data quality tests and freshness checks are one way to write those rules.
The people reading the results matter as well, since a score nobody understands changes nothing. A dashboard that shows a 92% completeness score only helps when the finance or operations user knows what that number means for their report. Investing in data literacy turns quality scores and freshness flags into signals the business acts on.
Data Monitoring vs Data Observability vs Data Quality vs Data Reliability
Four terms get used almost interchangeably in vendor pitches, so the overlap causes real confusion when teams set budgets. Each one still names a different layer. Monitoring is the narrowest, observability widens it, quality sets the standard, and reliability is the outcome all three serve.
| Term | What it means | Question it answers | Example |
|---|---|---|---|
| Data monitoring | Checks known metrics against fixed thresholds | Did this metric cross its limit? | Alert when a scheduled load fails |
| Data observability | Infers health from many signals, including ones nobody defined in advance | Is something wrong that we did not anticipate? | Flag a drop in row volume before users notice |
| Data quality | Defines and tests what fit-for-purpose data looks like | Does this data meet our standard? | Test that every order has a customer ID |
| Data reliability | Trusted data available on time, measured over weeks and months | Can people depend on this data? | Hit a freshness target for a core table, then report it monthly |
Reliability is the result, usually expressed as service levels for freshness and availability. Kanerika’s guide to data reliability covers how to set those targets. Integrity, which asks whether data stays unaltered in motion and at rest, sits beside quality rather than inside it. The guide to data integrity vs data quality draws that line.
How They Work Together in One Pipeline
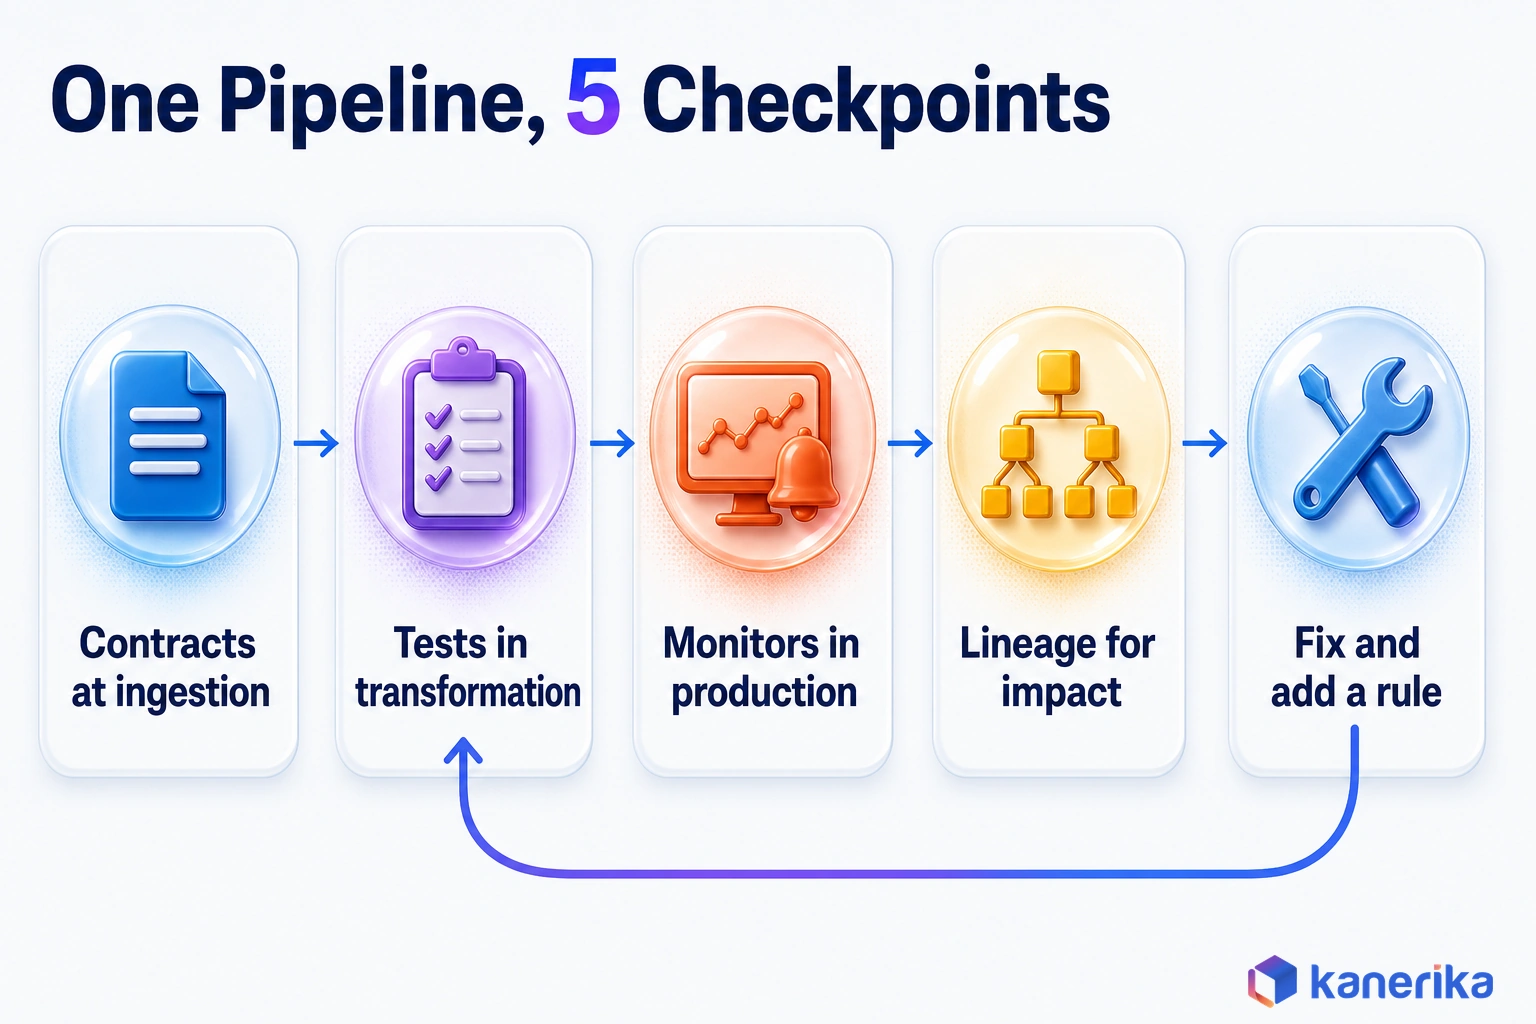
The cleanest way to run both is to give each one a stage in the pipeline instead of treating them as rival tools. Quality rules sit where data is defined and transformed, while observability sits where data runs in production. Lineage then connects the two when something breaks.
- Set contracts at ingestion: agree with each source team on the fields, types and freshness a feed must deliver, then quarantine loads that break the agreement.
- Test during transformation: in dbt, the built-in data tests cover not_null, unique, accepted_values and relationships, and teams also add custom tests for business rules.
- Monitor in production: turn on platform monitors for freshness, volume and anomalies. Snowflake data metric functions measure quality on a schedule and send notifications, while Databricks data quality monitoring detects freshness and completeness anomalies across a schema.
- Trace impact with lineage: when an alert fires, use data lineage to find the upstream cause. It also shows which reports and models read the broken table.
- Fix, assign and update the rule: route the incident to the domain that owns the data and fix the cause. Then turn the lesson into a new test. In a data mesh, each domain owns its quality rules, so that routing stays clear.
Each trip through step 5 also moves a failure from the observability column into the quality column. Over time, monitors spend less effort on known problems and more on the truly unexpected ones.
Data Contracts: Where the Two Meet
A data contract is a written agreement between the team that produces a dataset and the teams that consume it. It is also the one place where quality and observability share a single definition. The contract states the rules a quality test enforces, as well as the freshness and volume targets a monitor watches.
For example, a small contract for the replenishment feed from the opening might look like this.
dataset: store_inventory_daily
owner: supply-chain-data-team
freshness_sla: "lands by 06:00 UTC every day"
unique_key: [sku_id, store_id]
fields:
  - name: sku_id
    type: string
    rules: [not_null]
  - name: store_id
    type: string
    rules: [not_null]
  - name: on_hand_qty
    type: integer
    rules: [not_null, ">= 0"]
volume: "alert if rows fall more than 30% below the 7-day average"
on_breach: "quarantine the load and notify the owner"
With that contract in place, the three-day-old table from the opening could not have stayed quiet. The freshness target would have failed on the first missed morning, so the owner would have known by 6 a.m.
Which Should You Fund First? A Decision Matrix
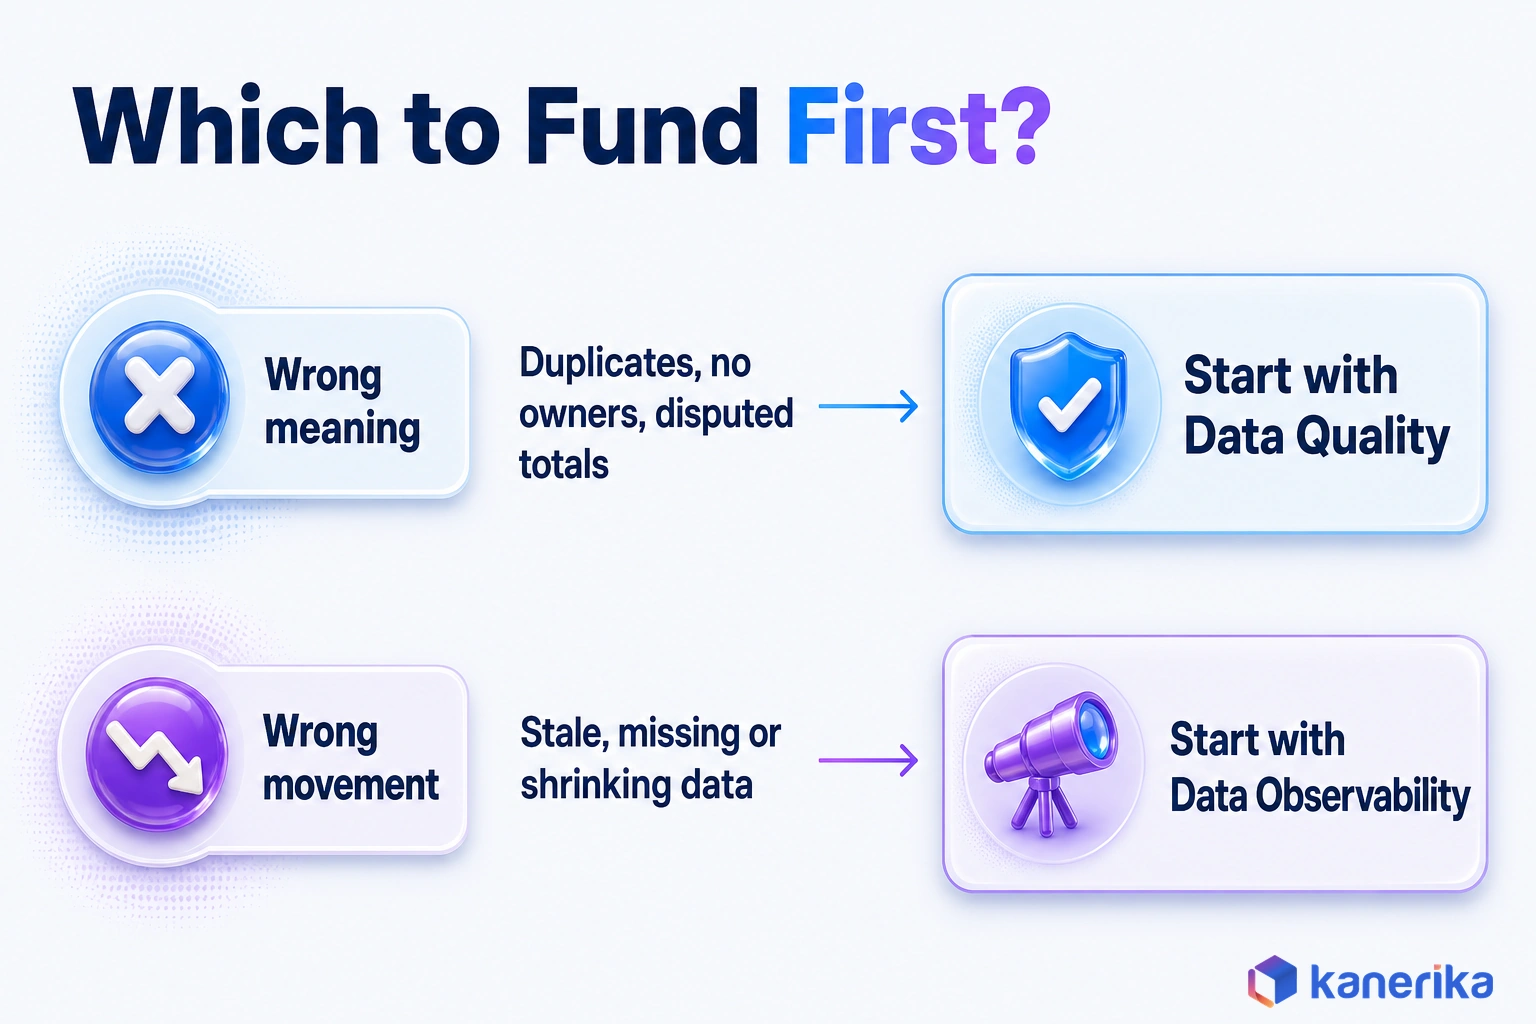
The practical question is sequence: which gap do you close first with the budget you have? The right first move depends on where your failures come from, rather than on which category sounds more modern. Match your situation to the rows below.
| Your situation | Start with | Why |
|---|---|---|
| No agreed definitions or owners for critical data | Data quality | Monitors need a standard before they can alert |
| Users report wrong numbers, such as duplicates or bad totals | Data quality | These are failures of meaning, so rules catch them |
| Regulated reporting or audits need documented controls | Data quality | Auditors ask for rules, owners and evidence |
| Users find stale or missing data before your team does | Data observability | Freshness and volume monitors close that gap fast |
| Hundreds of tables, but only a few have tests | Data observability | Baselines cover breadth that rules cannot reach |
| Upstream schema changes keep breaking pipelines | Data observability, plus contracts | Schema alerts and contracts stop silent drift |
| Tests exist, but incidents still take days to trace | Data observability | Lineage and alerting cut detection and resolution time |
The pattern behind the matrix is simple. When your problems are about what the data means, start with quality. When they are about whether data arrived, changed or stopped, start with observability instead.
Start With Data Quality When…
- Nobody can say who owns your revenue, customer or product tables.
- Business users regularly dispute totals, counts or definitions.
- An audit, regulator or customer contract requires documented data controls.
- You are migrating to a new platform and want clean rules in place before go-live.
Start With Data Observability When…
- Late or missing data is the most common complaint you hear.
- Your estate has grown faster than anyone could write tests for it.
- Source systems change without warning and then break downstream jobs.
- Incidents take days to trace because nobody can see what depends on what.
In either case, the first practice is a starting point rather than the destination. Plan the second one within the next one or two budget cycles, because the failures it catches will not wait for you.
Worked Example: A Retail Replenishment Pipeline
Return to the replenishment table from the opening. The sketch below is illustrative rather than a client case, but it shows how controls split by stage once both practices are in place.
| Stage | Quality control | Observability control |
|---|---|---|
| Source feed (store inventory files) | Contract sets required fields and types | Freshness alert when no file lands by 6 a.m. |
| Ingestion to the raw layer | Reject rows with a null SKU or store | Volume anomaly compared to the 7-day average |
| Transformation (dbt models) | Unique SKU and store pair, on-hand quantity of zero or more | Schema change alert on source columns |
| Replenishment table | Order quantity within the allowed range for each store | Distribution shift in order quantities |
| Dashboards and store orders | Totals reconciled against the ERP before release | Lineage shows which reports read the table |
In this setup, the stale feed fails its freshness check on the first morning. Lineage then shows which store order reports read the table, so the team pauses automated orders before a shelf runs empty. Meanwhile, the tests in transformation still catch the duplicate and range problems that monitors miss.
Tools: Native Platform Features, Quality Tools and Observability Platforms
Buying decisions get easier once you sort tools by category instead of comparing logos. Many teams already own more than they realize, because the major data platforms now ship quality and monitoring features of their own. Start there, then add specialist tools where native features run out.
| Category | What it does | Examples | When it is enough |
|---|---|---|---|
| Native platform features | Rules, profiling and monitors inside your data platform | Purview Unified Catalog, Databricks data quality monitoring, Snowflake data metric functions | When one main platform holds most of your data |
| Open-source testing | Code-based tests that run in pipelines | dbt tests, GX Core, Soda Core | When engineers want checks in version control |
| Commercial quality suites | Profiling, cleansing, matching and stewardship workflows | Informatica, Qlik Talend Cloud, Ataccama | When master data and regulated reporting involve many stewards |
| Observability platforms | Automated monitors, lineage and incident workflows across tools | Monte Carlo, IBM watsonx.data integration (data observability), Bigeye | When many platforms feed many tables and silent failures are costly |
Native Features in Microsoft, Databricks and Snowflake
On Microsoft’s stack, Purview Unified Catalog data quality supports out-of-the-box and AI-generated rules at column level. It then rolls the resulting scores up to data assets, data products and governance domains. Purview data quality is billed on pay-as-you-go Data Governance Processing Unit (DGPU) meters, so cost follows usage rather than a fixed license.
Snowflake’s data quality monitoring needs Enterprise Edition, which matters if your account runs on Standard. On Databricks, the data profiling feature was formerly called Lakehouse Monitoring, so older guides may use that name. Native tooling is usually enough when most critical tables live on one platform, while a cross-tool platform earns its cost once failures start in the hand-offs.
Open-Source Tools and Commercial Suites
GX Core is open source under the Apache 2.0 license, and Fivetran announced in May 2026 that it will become the project’s steward. Soda Core also ships as open-source packages, while Soda Cloud adds anomaly detection on top.
Ownership on the commercial side has shifted, so check a vendor’s roadmap before you sign. Salesforce completed its acquisition of Informatica on November 18, 2025. Earlier, IBM bought Databand.ai in a deal that closed in June 2022, adding data observability to its portfolio. Talend’s data quality tooling now ships inside Qlik Talend Cloud.
Pricing models differ by category too. Observability platforms often price by usage or by the number of tables monitored, while commercial quality suites tend to be quote-led. For a ranked list with strengths as well as trade-offs, see Kanerika’s roundup of data observability tools.
Metrics to Track for Both
What you measure decides what improves, so each practice needs its own scorecard. Quality metrics describe the state of the data itself. Observability metrics, by comparison, describe how fast the team finds and fixes problems, which is where alert fatigue shows up first.
| Metric | Belongs to | How to compute | Target direction |
|---|---|---|---|
| Dimension scores | Quality | Share of records passing each dimension’s rules | Up |
| Test coverage of critical tables | Quality | Critical tables with at least one test, divided by all critical tables | Up |
| Incidents per month | Both | Count of data incidents logged, such as stale loads or failed tests | Down |
| Time to detect | Observability | Average time from failure until the first alert | Down |
| Time to resolve | Observability | Average time from alert until the fix ships | Down |
| Data downtime | Observability | Incidents multiplied by the sum of detection and resolution time | Down |
| Alert precision | Observability | Alerts that led to action, divided by all alerts | Up |
Data downtime combines how often data breaks with how long it stays broken, so leadership can follow one figure. Alert precision is the early warning for fatigue. When most alerts lead nowhere, engineers start muting them, and then the next real incident slips past.
The approach borrows from site reliability engineering. Google’s four golden signals of latency, traffic, errors and saturation, for instance, play the same role for software systems.
Use Cases by Industry
Each industry splits rules and signals differently, but the pattern holds. A quality rule protects meaning that regulators or customers care about. An observability signal protects the flow of data that operations depend on.
| Industry | Quality rule example | Observability signal example |
|---|---|---|
| Financial services | Every transaction carries a valid account and currency code | The overnight trade feed arrives late or with fewer rows than usual |
| Retail | One price per SKU, store and date | A region’s point-of-sale feed goes stale before stores open |
| Healthcare | Patient records carry required identifiers and valid codes | A lab results feed drops a column after a vendor update |
| Manufacturing | Sensor readings stay within the machine’s physical range | Sensor values shift suddenly on one line, even though nothing failed |
In each row, the rule would pass the observability failure, while the monitor would miss the rule failure. That is the pairing argument again, seen through an industry lens.
Data Quality and Observability for AI and GenAI
AI raises the stakes for both practices, because models repeat whatever their data teaches them. A dashboard with bad data misleads a few readers. A model trained on the same data, however, repeats the error in every prediction it makes.
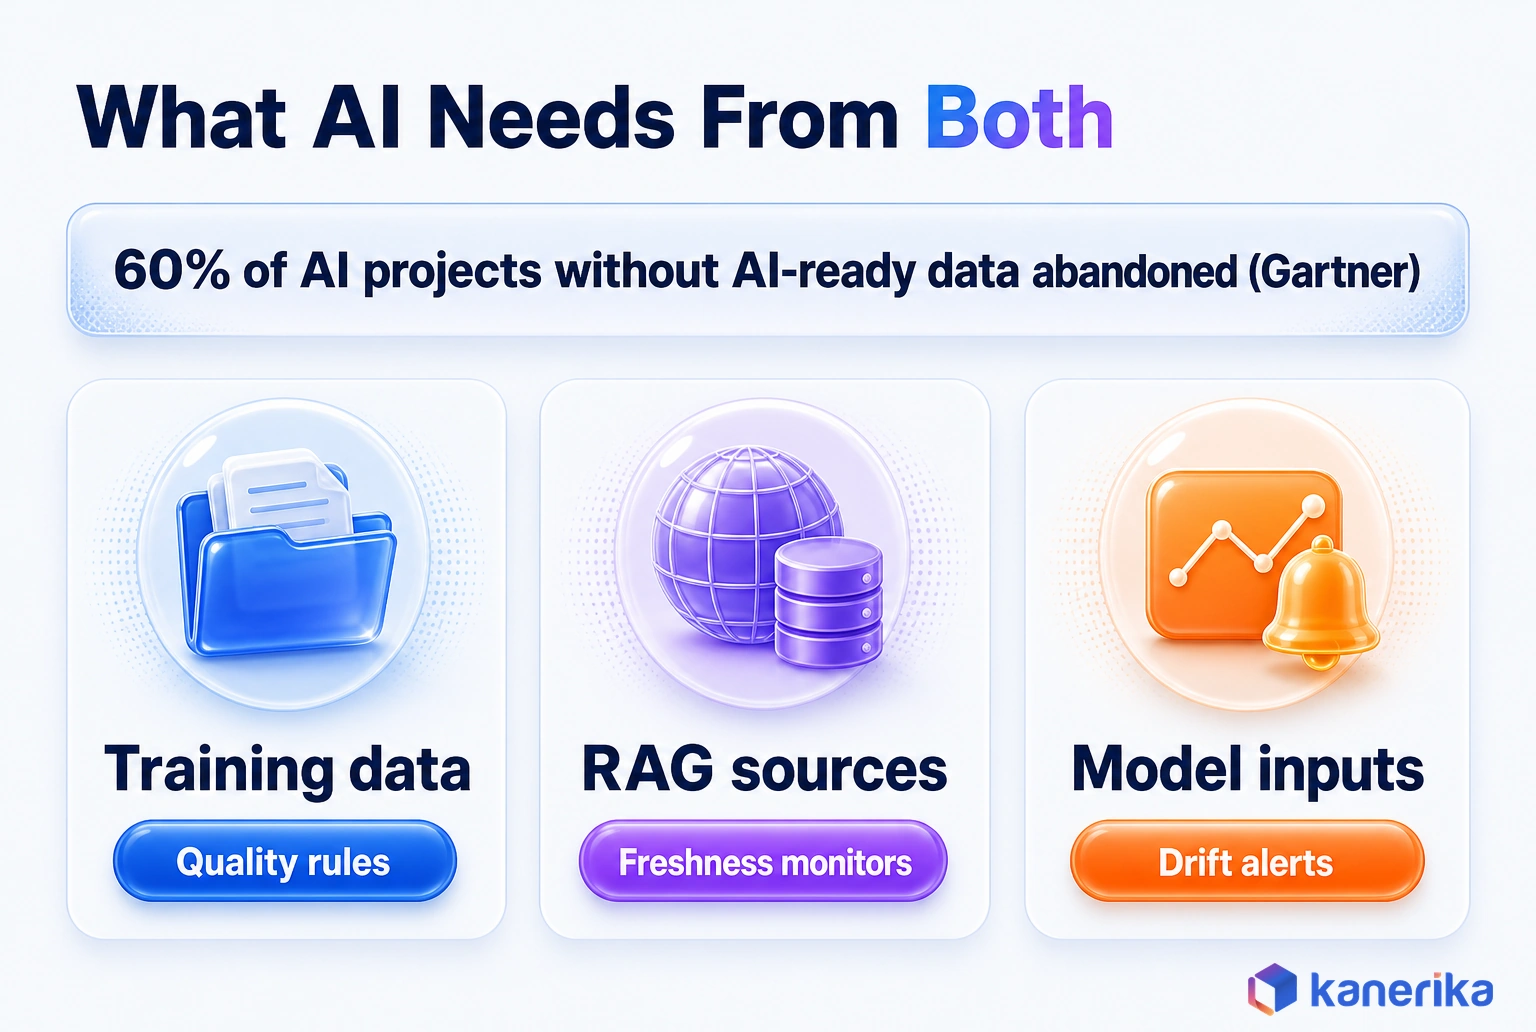
Gartner warned in February 2025 that through 2026, organizations will abandon 60% of AI projects unsupported by AI-ready data. The same release found that 63% of organizations either lack, or are unsure they have, the right data management practices for AI. Both gaps sit squarely in the territory this guide covers.
Where AI Needs Both Practices
Three areas of an AI system need both practices at once.
- Training data: quality rules check labels, duplicates and representativeness before a model ever sees the data. A mislabeled or duplicated example teaches the model a wrong pattern as if it were true.
- RAG sources: a retrieval system answers from whatever documents it indexes, so a stale knowledge base produces confident, outdated answers. Freshness monitors on source collections catch an outdated index before a user acts on an old policy or price.
- Model inputs after launch: observability tracks drift in input distributions, which is often the first sign that a model’s accuracy is slipping.
What Regulation Asks For
Regulation points the same way. The EU AI Act’s Article 10 covers data for high-risk AI systems. It asks that training, validation and testing data be relevant and sufficiently representative. It also asks that the data be, as far as possible, free of errors and complete.
Those requirements are quality rules by another name, but meeting them month after month takes monitoring. A dataset that passed its checks at training time can drift or go stale a quarter later, and only a monitor will notice. That is the case for building both into the platform from the start, not after an audit asks.
How Kanerika Builds Data Quality and Observability Into Data Platforms
Kanerika treats quality and observability as parts of the platform build rather than tools bolted on after go-live. Its data engineering services include a Data Quality and Observability offering, with quality checks on every pipeline and lineage tracked end to end. Ownership models and policies come from the data governance practice, so every rule has a named owner.
Allen Distribution shows the approach in practice. The company’s warehouse management and HR data sat across on-premises SQL servers, so reporting was largely manual. Kanerika consolidated the data into a Microsoft Fabric lakehouse, rebuilt reporting in Power BI with row-level security, and then automated the refreshes.
The results map onto both sides of this guide. Moving the data into one Fabric lakehouse resolved the blanks and nulls and delivered a 54% improvement in data accuracy, which is the quality side. Automated refreshes cut report generation time by 95%, and a single scheduled refresh is also the point where a freshness monitor belongs.
For a SaaS client building an AI DataOps platform, where schema drift kept breaking pipelines, Kanerika’s product engineering team added correlation-ID tracing across the platform. The result was 65% faster customer onboarding and 37% lower operational costs.
Case Study
65% Faster Onboarding for an AI DataOps Platform
For a SaaS client’s AI DataOps platform hit by schema drift, Kanerika’s product engineering team added correlation-ID tracing, with 65% faster onboarding and 37% lower operational costs.
Read the Case Study →Conclusion: Set the Standard, Then Watch It
Data quality and data observability answer different questions. Quality defines what good data means and then tests against it. Observability, on the other hand, watches production for the moment data stops behaving, including the failures nobody wrote a rule for.
Each one is blind where the other sees, so the long-term answer is both, joined by contracts, lineage and clear owners. The short-term answer, however, depends on your incident log.
If users dispute what the numbers mean, or nobody owns the definitions, start with data quality. If users find stale, missing or shrinking data before your team does, start with data observability. That is the practical resolution of data observability vs data quality: fund the side that closes your most expensive gap first, then add the other.
Frequently Asked Questions
What is the difference between data quality and data observability?
Data quality defines what fit-for-purpose data looks like and tests records against rules for accuracy, completeness, validity and timeliness. Data observability watches production pipelines for changes in freshness, volume, schema, distribution and lineage. Quality catches known problems someone wrote a rule for, while observability catches silent breaks nobody predicted, so mature teams usually run both together.
What is data observability?
Data observability is the ability to understand the health of data in production from the signals it gives off. Tools learn a normal baseline for each table, covering freshness, row volume, schema and value distribution, then alert when behavior changes. Lineage shows which source caused a problem and which reports depend on the affected data, which speeds up every fix.
What are the 4 pillars of observability?
In software observability, the four pillars are usually given as metrics, events, logs and traces, often shortened to MELT. Metrics are numeric measurements over time, events record discrete changes, logs capture detailed messages, and traces follow a request across services. Data observability adapts the same thinking to tables and pipelines through freshness, volume, schema and lineage signals.
What are the 3 C's and 5 C's of data quality?
No single standard defines the 3 C’s or 5 C’s of data quality, so the lists vary by author. One common version of the 3 C’s is completeness, consistency and correctness. Five-C lists often add currency, meaning timeliness, and conformity to required formats. Both overlap heavily with the six DAMA UK dimensions, which are more widely cited.
What are the six dimensions of data quality, and is there a seventh?
The six core dimensions used by DAMA UK and the UK Government Data Quality Framework are accuracy, completeness, consistency, timeliness, uniqueness and validity. Some frameworks add a seventh dimension to fit their own data and use cases. ISO/IEC 25012 goes further with 15 characteristics, so the right list depends on how formal your quality program needs to be.
Can data observability replace data quality testing?
No. Observability spots changes in how data behaves, but it cannot judge whether a value is correct. A wrong currency rate applied every day becomes the normal baseline, so a monitor never flags it. Only a rule that knows the correct rate catches that error. Observability widens coverage, and quality testing supplies the business meaning behind every check.
Which should organizations implement first, data quality or data observability?
Start with data quality when critical data has no agreed definitions or owners, or when users dispute what the numbers mean. Start with data observability when users find stale, missing or shrinking data before your team does, or when hundreds of tables have no tests at all. Either way, plan the second practice within a budget cycle or two.
How do data quality and data observability work together?
They work as stages of one pipeline. Data contracts set expectations at ingestion, quality tests run during transformation, and observability monitors watch freshness, volume and schema in production. When an alert fires, lineage shows the cause and the affected reports. The fix then becomes a new quality rule, so the same failure gets caught earlier the next time.
What is the difference between data monitoring and data observability?
Data monitoring checks metrics you already know to watch against fixed thresholds, such as a failed load or a row count limit. Data observability goes further by learning normal behavior across many signals and flagging changes nobody defined in advance. Monitoring answers whether a known metric crossed its limit, while observability answers whether something unexpected has gone wrong.
How does data observability help AI and machine learning systems?
AI systems repeat whatever their data teaches them, so silent data problems turn into wrong predictions. Observability tracks drift in model inputs, the freshness of documents behind retrieval systems, and volume or schema changes in training pipelines. Catching these early protects model accuracy. Gartner expects organizations to abandon 60% of AI projects unsupported by AI-ready data through 2026.
Can Microsoft, Databricks or Snowflake handle data quality monitoring natively?
Yes, each platform ships native features. On Microsoft’s stack, Purview Unified Catalog adds column-level quality rules and rolls scores up to data products and governance domains. Databricks data quality monitoring detects freshness and completeness anomalies, and Snowflake data metric functions run scheduled checks with notifications. Estates spread across several platforms often add a dedicated observability tool.
How do you monitor data quality?
Start by profiling critical tables to learn their real null rates, ranges and patterns. Turn that knowledge into tests for completeness, uniqueness, validity and freshness that run on every load. Then add production monitors for volume, schema changes and anomalies, track dimension scores over time, and route every failure to a named owner who fixes the cause.
What is a KPI in observability?
A KPI in observability is a measurable indicator of how healthy a system or data pipeline is. For data teams, common KPIs include time to detect an incident, time to resolve it, incidents per month, data downtime and alert precision. Each one needs a target direction and an owner, so the numbers drive action instead of sitting in reports.
What are the popular data observability tools?
Data observability tools fall into a few categories. Dedicated platforms such as Monte Carlo, IBM watsonx.data integration and Bigeye monitor many systems at once. Native features in Microsoft Purview, Databricks and Snowflake cover a single platform well. Open-source options like dbt tests, GX Core and Soda Core add code-based checks. The right mix depends on how many platforms you run.
What are the five pillars of data observability?
The five pillars are freshness, quality, volume, schema and lineage. Freshness tracks when data last updated, and quality covers the shape of values, which older lists called distribution. Volume watches row counts, schema catches structural changes such as renamed columns, and lineage maps upstream sources and downstream consumers so teams can see what an incident affects.
What is the ISO standard for data quality?
ISO/IEC 25012 is the main international model for data quality. It defines 15 characteristics and splits them between those inherent to the data itself and those that depend on the system that holds and serves it. Teams often pair it with simpler frameworks, such as the six DAMA UK dimensions, when they design their own quality rules and scorecards.
What is the difference between data quality and data monitoring?
Data quality defines the standard data must meet and tests records against it, such as requiring every order to carry a customer ID. Data monitoring checks known metrics against fixed thresholds, such as alerting when a scheduled load fails or a row count falls below a set limit. Quality decides what correct means, while monitoring watches for predefined failures.
What are the main observability metrics?
For data pipelines, the main observability metrics are freshness, row volume, schema changes, null rates and value distribution for each table. At the team level, track time to detect, time to resolve, incidents per month, data downtime and alert precision. Together these show whether data is healthy and how quickly the team finds and fixes problems when they happen.
What are the 4 golden signals for observability?
The four golden signals come from Google’s Site Reliability Engineering book. They are latency, traffic, errors and saturation. Latency measures how long requests take, traffic measures demand, errors count failed requests, and saturation shows how close a system is to its capacity. Data teams borrow the idea by tracking freshness, volume, failed loads and pipeline load.