TL;DR
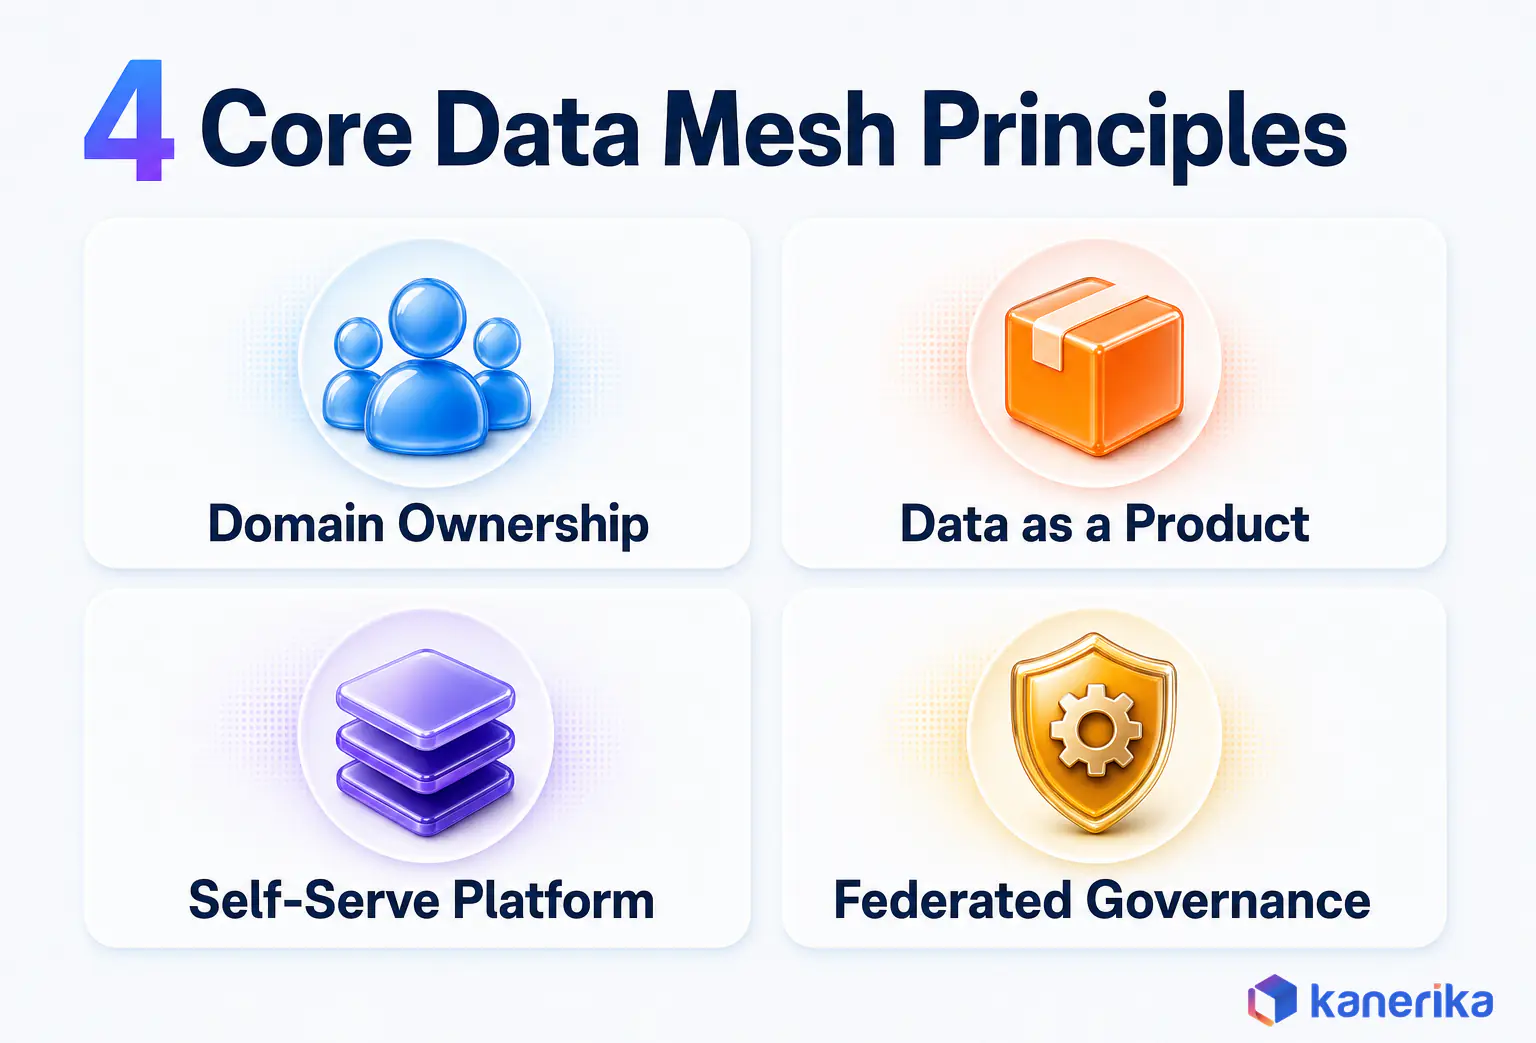
There are four data mesh principles, not six: domain ownership, data as a product, a self-serve platform and federated governance. In plain terms, business teams own their data and share it as ready-to-use products. A shared platform and common, automated rules keep those teams working together. Zhamak Dehghani, who created data mesh, says the four only work as a set. Lists of six usually count governance twice or treat a practice as a principle. Fabric, Databricks and Snowflake help, but data leaders should still pilot all four on one or two domains first.
Key Takeaways
- Data mesh rests on four principles, namely domain ownership, data as a product, a self-serve platform and federated computational governance.
- The four work only as a set, because each one fixes a problem that the others create on their own.
- A data product bundles code, data with its metadata, and the infrastructure it runs on into one deployable unit.
- Governance becomes computational when global rules run as platform checks instead of living in a policy document.
- Fabric domains, Unity Catalog and Snowflake Secure Data Sharing support the principles, yet ownership and product habits still need people.
- A phased pilot on one or two domains, measured against a backlog baseline, is the safest way to start.
When Every Report Waits on One Team
Picture a Monday leadership meeting at a growing manufacturer. Sales reports one revenue number, finance reports another, and the supply chain dashboard shows a third. Each team pulled its figure from the same central data platform, but at different times and through different filters.
Behind those numbers sits a central data team of capable engineers with a request queue that never shrinks. Every new source, report and model change lands on their desk. Because they know the order system less well than the order team does, each fix starts with a round of questions.
Nobody in that room is doing a bad job. The structure is the problem, and data mesh was proposed for exactly this situation. This guide explains the four principles in plain terms and why they only work as a set. It also maps them to modern platforms and shows what a data leader should do about each one.
What Are Data Mesh Principles?
Data mesh principles are the four rules that define how a data mesh organizes the ownership, architecture and governance of analytical data. A data mesh does not funnel every dataset into one central platform run by one team. Instead, each business domain owns its data and publishes it as a product that other teams can use.
A shared platform and a shared set of rules then keep those domains connected, so decentralization does not turn into chaos. In short, the principles describe the whole arrangement, from who owns a table to how access rules get enforced. For the wider picture, including benefits and use cases, see our guide to what data mesh is and how teams set it up.
Where the Four Principles Came From
Zhamak Dehghani, then at Thoughtworks, first described the idea on martinfowler.com. Her article was titled How to Move Beyond a Monolithic Data Lake to a Distributed Data Mesh. Its final installment appeared on 20 May 2019.
She followed it on 03 December 2020 with Data Mesh Principles and Logical Architecture, which states that data mesh is founded in four principles. She also wrote that she intended the four to be “collectively necessary and sufficient”. That phrase matters for anyone planning an adoption, so we return to it below.
The approach has a commercial market around it too: a MarketsandMarkets report published in January 2024 projects the data mesh market to reach USD 2.5 billion by 2028, a 16.4% CAGR.
The Problem They Solve
Centralized data teams work well when a company has a handful of sources and a handful of reports. Yet they struggle as both multiply. Every new source adds a pipeline the central team must build and maintain, while every new use case joins the same queue.
Three symptoms usually show up together, especially as the company grows:
- The backlog grows faster than the team can hire, so business teams wait weeks for simple changes.
- Engineers who never work in the source systems end up interpreting their data, which causes quiet errors in meaning.
- Ownership blurs, so when a number is wrong, nobody is sure who should fix it.
The four principles attack these symptoms from different angles, starting with who owns the data.
The Four Principles at a Glance
Each principle answers a different question about your data. Who owns it, what do they deliver, what do they build on, and which rules does everyone follow? The table below shows what each principle changes, who carries it, and what tends to break when it is missing.
| Principle | What changes | Who owns it | What breaks without it |
|---|---|---|---|
| Domain-oriented data ownership | Analytical data is owned by the business domain that produces or best understands it | Domain teams, each with a data product owner and engineers | The central team stays a bottleneck, so meaning gets lost in handoffs |
| Data as a product | Domains publish data for known consumers with documentation, quality targets and an owner | Data product owners inside each domain | Datasets get dumped and orphaned, so nobody trusts them |
| Self-serve data infrastructure as a platform | Shared tools let domains build products instead of rebuilding pipelines | A central platform team | Every domain builds its own stack, so costs and skills spread thin |
| Federated computational governance | Global rules are agreed jointly and then enforced automatically by the platform | A federated group of domain and platform representatives | Domains drift into new silos because formats and access rules no longer match |
Read the rows as one system rather than four separate projects. The first two principles decentralize the work. The last two, by contrast, keep that decentralized work coherent, cheap to run and safe.
Principle 1: Domain-Oriented Data Ownership
The first principle moves accountability for analytical data to the teams closest to it. Dehghani’s full name for it is domain-oriented decentralized data ownership and architecture. In plain terms, the team that runs the order process also owns the order data that analysts use.
That is a bigger change than it sounds, because ownership here means decision rights as well as blame. For example, the order domain decides how its data is modeled, when its schema changes and what quality it guarantees.
Consider an online retailer. Under a central model, the data team pulls raw order events, guesses what a “cancelled” status means and then builds a revenue table. Under domain ownership, however, the orders team publishes that table itself, with cancellation logic written by the people who designed the order system.
It also needs people who can act on those decisions. In practice, that means a named owner plus at least one data engineer embedded in the domain. Our guide to data stewardship roles and models shows how stewards fit alongside these owners.
Talk to Kanerika
Mapping Your First Data Domains?
Bring your current request backlog and a list of candidate domains. Kanerika will help you pick a pilot domain, name its owners and scope a first data product.
Book a Working Session →How to Draw Domain Boundaries
Domain boundaries decide whether ownership works, so draw them with care. Dehghani’s 2019 article separates source-oriented domain data, which reflects facts from operational systems such as orders or shipments, from consumer-oriented data. The second kind is shaped for a specific use, such as demand forecasting.
A few practical rules help when you draw them:
- Align domains with business capabilities such as ordering, billing or fulfilment, rather than with the org chart, which changes more often.
- Give each domain a team that can actually act, with an owner and real engineering capacity.
- Keep source-oriented products close to the system of record, and build consumer-oriented products only when a real consumer asks.
- Start with domains whose data other teams already request, since demand proves the value early.
Getting this wrong is expensive to undo. Boundaries drawn around reporting lines tend to dissolve at the next reorganization, and the data products go with them.
Principle 2: Data as a Product
The second principle changes what a domain delivers. Instead of dumping tables into a lake and walking away, a domain publishes data the way a product team ships software. That means known users and a quality promise.
Every data product has a named owner, a defined set of consumers and targets it is measured against. Accountability for quality shifts upstream, as close to the source as possible. When a downstream report breaks, the question becomes which product missed its promise, and that product’s owner can answer it. For a plan that prices and sells a data product externally, see this data monetization strategy guide.
What a Data Product Contains
Dehghani calls the data product the architectural quantum of a mesh, meaning the smallest unit you can deploy on its own. It bundles three parts. The code covers pipelines, APIs and access policies, while the data comes with its metadata, such as schema, documentation and quality measures. Finally, the infrastructure is what the product runs on.
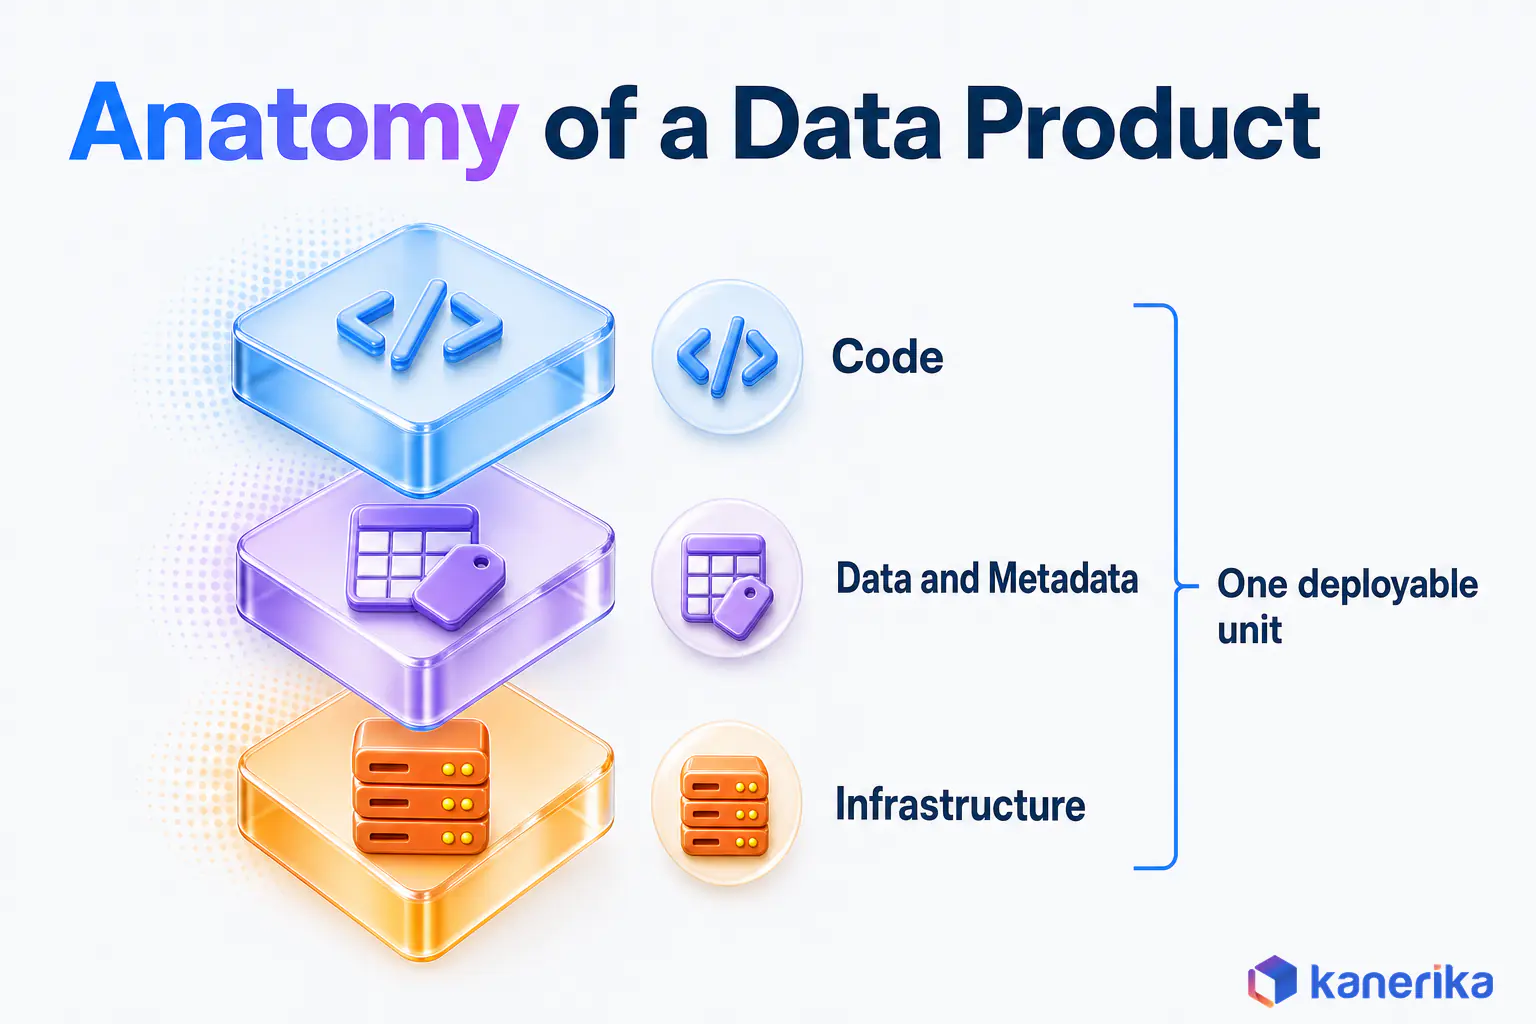
Packaging all three together is what makes a product independently deployable. A team can change its transformation logic without filing a ticket with anyone else, because the code ships with the data it produces.
The Six Qualities of a Usable Data Product
Dehghani’s 2019 article lists six qualities a data product needs before others can rely on it. They are a checklist for a single data product, not a second set of principles, even though some lists blur the two. The table turns each quality into a check you can run.
| Quality | What it means | How to check it |
|---|---|---|
| Discoverable | Consumers can find it without asking around | A catalog entry with an owner and a plain description |
| Addressable | It has a stable, unique address | A fixed path or endpoint that survives internal changes |
| Trustworthy and truthful | Its owner commits to measurable quality | Published SLOs for freshness and completeness, plus lineage |
| Self-describing | Its meaning and structure are documented | Schema, field definitions and sample data travel with it |
| Interoperable and governed by global standards | It can be joined with other products | Shared identifiers, formats and naming set by governance |
| Secure and governed by global access control | Access follows company-wide policy | Access rules enforced by the platform rather than by manual grants |
Where Data Contracts Fit
This is also where API-first design and data contracts belong. A data contract writes down the schema, quality targets and access rules a product promises. As a result, consumers can depend on it, and the platform can test it automatically. The example below is illustrative and not tied to any one tool.
data_product: orders.daily_order_status
owner: order-management-domain
consumers:
  - logistics.on_time_delivery
  - finance.revenue_reporting
schema:
  order_id: string        # shared global identifier
  customer_id: string     # classified as pii
  promised_date: date
  status: [open, shipped, delivered, cancelled]
slo:
  freshness: "refreshed by 06:00 UTC daily"
  completeness: "99.5% of orders present"
access:
  default: internal
  pii_fields: masked_unless_role(finance_analyst)
Notice that the contract mixes two kinds of rule. The owner sets the schema and the targets, whereas the PII classification and the masking rule come from global policy. That split is the subject of the fourth principle. Contracts and catalog entries also tend to live together, and our review of data catalog tools shows where.
Principle 3: Self-Serve Data Infrastructure as a Platform
The third principle stops decentralization from turning into duplication. If ten domains each build their own ingestion, storage, scheduling and monitoring, the company pays for ten stacks and needs ten sets of scarce skills. A self-serve platform instead gives every domain the same paved road.
A platform team owns that road, and its customers are the domain teams. Its job is to make building, publishing and running a data product routine. So the test is simple: can a domain engineer create a new product without opening a ticket with the platform team?
Kanerika Service
Data Engineering Services
Kanerika builds the shared platforms, pipelines and data product templates that let domain teams publish trusted data without waiting on a central queue.
Explore Data EngineeringA self-serve data platform is different from self-service business intelligence, which serves report users rather than the engineers who build data products. Both matter, but they solve different problems for different people.
The Three Platform Planes
Dehghani describes the platform as three planes, although she offers them as an example split rather than a fixed design.
- Infrastructure provisioning plane. Storage, compute, identity and networking, provisioned on request.
- Data product developer experience plane. Templates and tools to build, test, deploy and version a data product in one workflow.
- Mesh supervision plane. Capabilities that span all products, such as discovery, lineage, policy enforcement and quality monitoring.
Many teams build the bottom plane and stop there, which leaves domains with raw infrastructure and no product tooling. The middle plane is where the effort pays off, since it turns good engineering habits into defaults. Our data engineering best practices cover the habits worth encoding.
Principle 4: Federated Computational Governance
The fourth principle answers an obvious worry. If every domain owns its data, who keeps the whole thing consistent? Data mesh answers with a federated group of domain and platform representatives instead of a central governance office. That group then sets a small number of global rules.
The word computational does the heavy lifting. Rules are not published as a document and checked by people later. Instead, they are written as policies that the platform enforces whenever a product is built, published or queried. A domain cannot publish a product with an unclassified personal field, for example.
This model builds on the fundamentals rather than replacing them. Our guides to data governance principles and to building an enterprise data governance framework cover ownership, stewardship and policy design in more depth.
Checklist
Data Governance Checklist
A practical checklist for setting ownership, classification, access and quality rules, the same decisions a federated governance group has to make.
Get the Checklist →What Gets Decided Centrally, Locally and Automatically
The hardest design work is choosing which decisions stay global. Too many global rules recreate the central bottleneck, while too few let the mesh fragment. For most enterprises, the split below is a reasonable starting point.
| Decision | Federated group | Domain | Enforced by the platform |
|---|---|---|---|
| Access policy | Defines roles and default access levels | Approves access requests for its products | Applies the policy on every query |
| PII classification | Defines sensitive data categories | Tags its own fields | Blocks publishing when a field is unclassified |
| Schema standards | Sets shared identifiers and naming rules | Models its own products within them | Validates schemas at publish time |
| Quality SLOs | Sets the minimum SLO every product must declare | Sets and meets targets for its products | Monitors and alerts when targets are breached |
| Retention | Sets retention periods by data category | Applies them to its products | Archives or deletes on schedule |
Regulatory checks such as privacy and retention sit here too. The federated group translates each regulation into a policy once, and then the platform applies it everywhere. That is far cheaper than auditing every domain by hand.
Why the Four Principles Only Work Together
Dehghani’s phrase “collectively necessary and sufficient” is easy to read past, yet it is the most practical idea in the framework. Each principle solves a problem that another one creates. So if you adopt one in isolation, you usually trade the old problem for a new one.
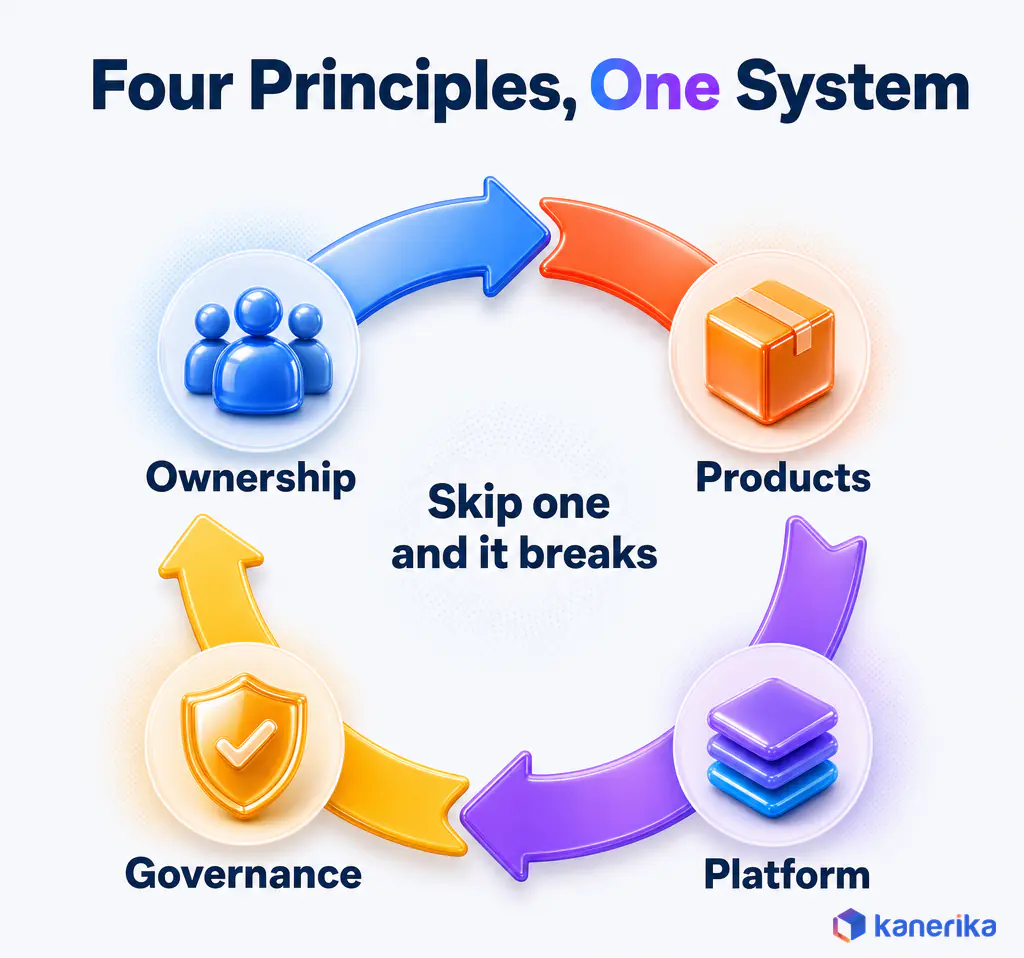
Domain ownership creates independent teams, so you need a platform to stop them from duplicating each other’s work. The platform makes publishing easy, so you also need governance to keep what gets published consistent. Product thinking, in turn, gives each dataset a reason to exist and someone to answer for it.
| If you adopt | Without | You usually get |
|---|---|---|
| Domain ownership | A self-serve platform | Duplicated pipelines and rising costs, because every domain builds its own stack |
| Domain ownership | Federated governance | New silos with incompatible formats and access rules |
| Data as a product | Domain ownership | Orphaned datasets with no team accountable for quality |
| A self-serve platform | Data as a product | The central bottleneck, relocated to the platform team |
The last row is the failure that shows up most in practice. A company buys a modern platform, renames its central team and then keeps working the old way. Because ownership never moves, the queue simply moves with the team.
Four Data Mesh Principles or Six? Principles Versus Practices
Search for data mesh principles and you will find lists of four, five and six. In fact, an earlier version of this article listed six. Dehghani’s 2019 article introduced the ideas without numbering them, and her December 2020 follow-up set them down as four principles. The extra items in longer lists are useful practices that belong under one of them.
The confusion is understandable. Practices such as data contracts and API-first access are concrete, so they feel like principles. Mapping each one back to its parent keeps your adoption plan simple, as the table shows.
| Commonly listed item | Canonical principle it belongs to |
|---|---|
| Decentralized data governance | Federated computational governance, as a duplicate of principle 4 |
| API-first architecture | Data as a product, through the addressable and interoperable qualities |
| Interoperability and global standards | Federated computational governance |
| Data contracts | Data as a product, with checks enforced by governance |
| Discoverability and cataloging | Data as a product, delivered through the platform’s supervision plane |
| Platform thinking or a platform team | Self-serve data infrastructure as a platform |
The same discipline helps when data mesh is compared with other approaches. A data fabric is mainly a technology layer that connects data where it sits, whereas a mesh is mainly an operating model. Our comparison of data fabric vs data mesh explains where the two overlap and where they part ways.
How the Principles Work in a Real Enterprise: A Worked Example
Abstract principles get clearer when you follow one concrete flow. The example below is illustrative. A mid-sized manufacturer with three operational domains wants one trusted on-time delivery KPI, and today it spends days reconciling three versions of it.
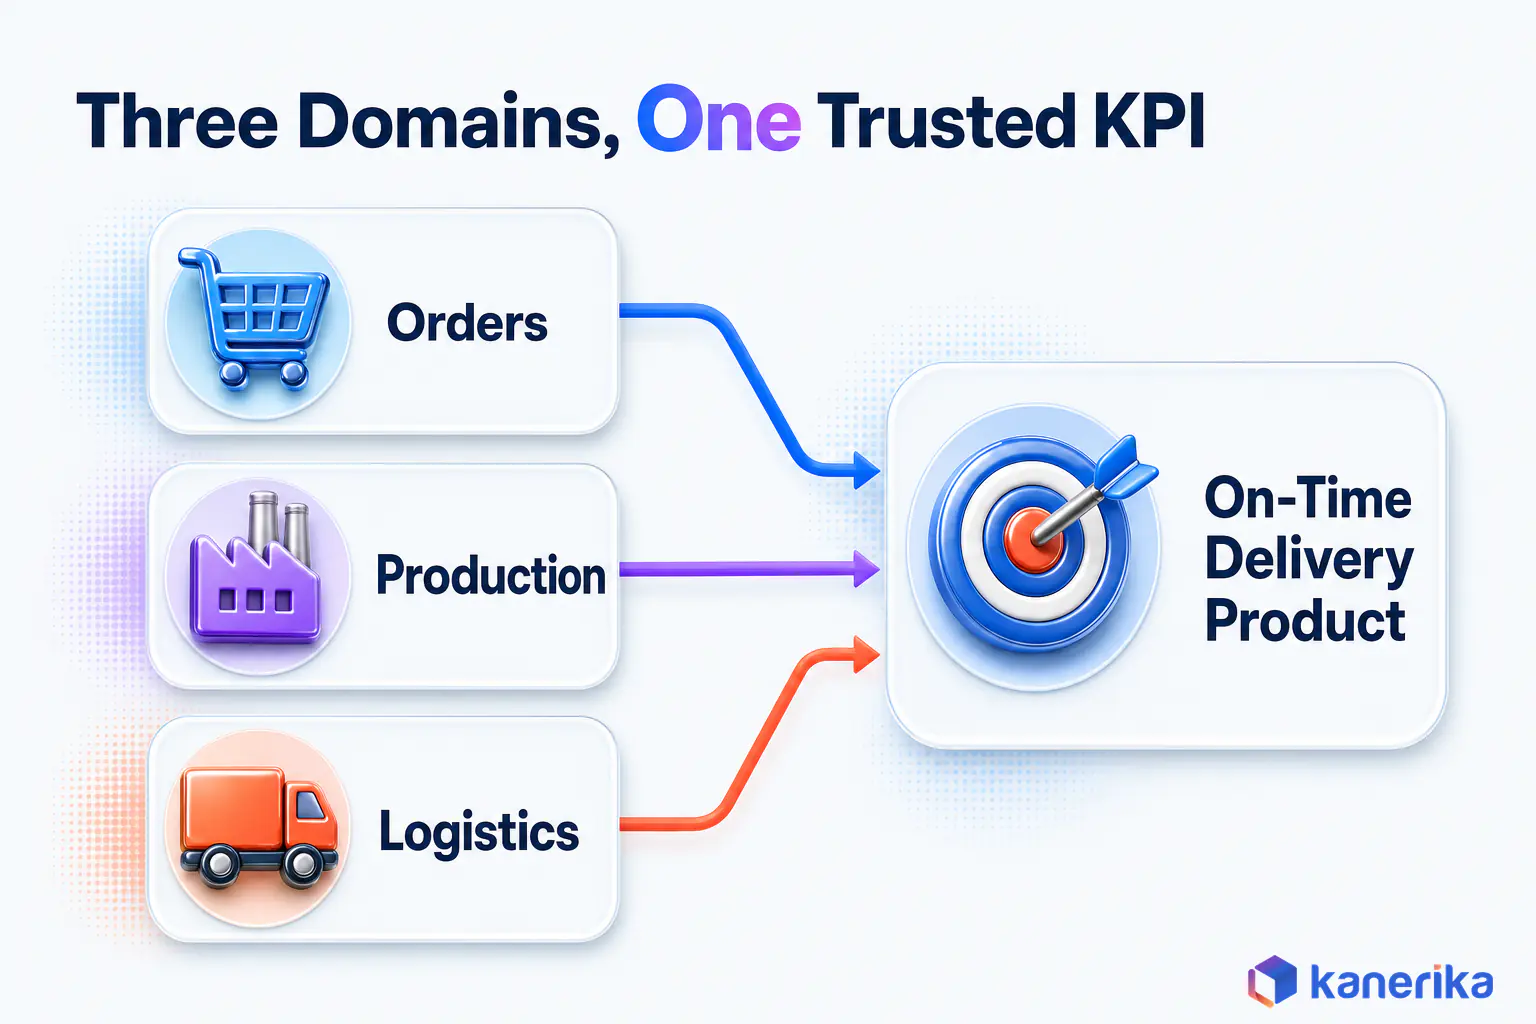
- Ownership. First, the order, production and logistics teams each take ownership of their source data. Each names a data product owner and embeds one data engineer.
- Products. Each domain then publishes one source-oriented product: confirmed orders with promised dates, production completions, and shipment events with delivery timestamps.
- Platform. All three products start from the same platform templates, so each gets storage, a pipeline scaffold, tests and a catalog entry without bespoke work.
- Governance. The federated group sets one rule that matters here. Every product uses the shared order identifier and a common time zone, and the platform rejects any version that breaks it.
- Consumer product. Finally, the logistics domain, as the main user, builds a consumer-oriented on-time delivery product that joins the three and publishes a freshness target.
Look at what changed. The definition of “on time” now lives in one owned product rather than in three spreadsheets. So when the number looks wrong, data lineage points to a specific product and its owner.
The central team changes role too. It now spends its time improving the platform instead of fielding report requests, which is the shift the four principles were designed to produce.
Data Mesh Principles on Microsoft Fabric, Databricks and Snowflake
Modern platforms can support the four principles, but none of them installs the operating model for you. Each one covers parts of the platform and governance work. The ownership and product habits, however, still have to be built by people, so the map below lists documented capabilities only.
| Principle | Microsoft Fabric | Databricks | Snowflake |
|---|---|---|---|
| Domain ownership | Domains and subdomains group data by business area | Set by your catalog and workspace design | Set by your account and database design |
| Data as a product | Not built in; owners and contracts are set by your teams | Products governed as Unity Catalog objects | Products shared through Secure Data Sharing without copying data |
| Self-serve platform | One SaaS platform shared by all domains | A shared lakehouse, with templates built by your platform team | A shared platform, with templates built by your platform team |
| Federated computational governance | Some tenant-level settings can be delegated to domains | Unity Catalog centralizes access control, lineage and audit logging | Providers choose which objects each consumer account can see |
Microsoft is candid about the limits. In its Fabric domains documentation, last updated in May 2025, it says Fabric’s data mesh architecture “primarily supports organizing data into domains,” with some governance settings delegated to them. Domains are a container, so product owners, contracts and federated rules remain your work. For the governance layer on that stack, see our guide to data governance with Microsoft Purview and our Microsoft Fabric practice.
Databricks and Snowflake
On Databricks, Unity Catalog is described as “the unified governance layer for data and AI built into Databricks”. That makes it the natural home for computational policies, and our Databricks Unity Catalog guide goes deeper.
On Snowflake, Secure Data Sharing lets a domain share selected objects with another account. Snowflake also notes that “no actual data is copied or transferred between accounts,” which suits the data-as-a-product idea well. Our walkthrough of Snowflake data sharing covers the setup.
Is Data Mesh Right for Your Organization?
Data mesh is an operating model change, so it pays off only where the central model is genuinely failing. Before you commit budget, answer five questions honestly.
- Can you measure the central backlog? If request wait times are not tracked, you cannot show that a mesh improved them.
- Do you have named domain owners with engineers? Ownership needs engineering capacity behind it to mean anything.
- Is there real demand for cross-domain reuse? A mesh earns its cost when many teams need each other’s data.
- Can you fund a platform team? Without one, every domain rebuilds the same tooling.
- Is there an executive sponsor? Moving decision rights between teams needs someone who can settle disputes.
As a rule of thumb, three or more yes answers justify a pilot. Fewer suggest fixing the central model first and then revisiting the question in a year.
When Not to Adopt Data Mesh
Data mesh is a poor fit when a company has only a few domains, a small data team or one dominant source system. In those cases, a well-run central platform gives most of the benefit at a fraction of the coordination cost. A lakehouse built on a medallion architecture is one common example.
A mesh also does not settle storage decisions for you. Our explainer on data mesh vs data lake covers how the operating model and the storage layer relate.
How to Apply the Four Principles: A Phased Roadmap
A data mesh is adopted in slices rather than in one big program. The roadmap below ties each stage to a principle, so you always know which one you are strengthening. For the broader rollout, our article on setting up a data mesh fills in the surrounding detail.
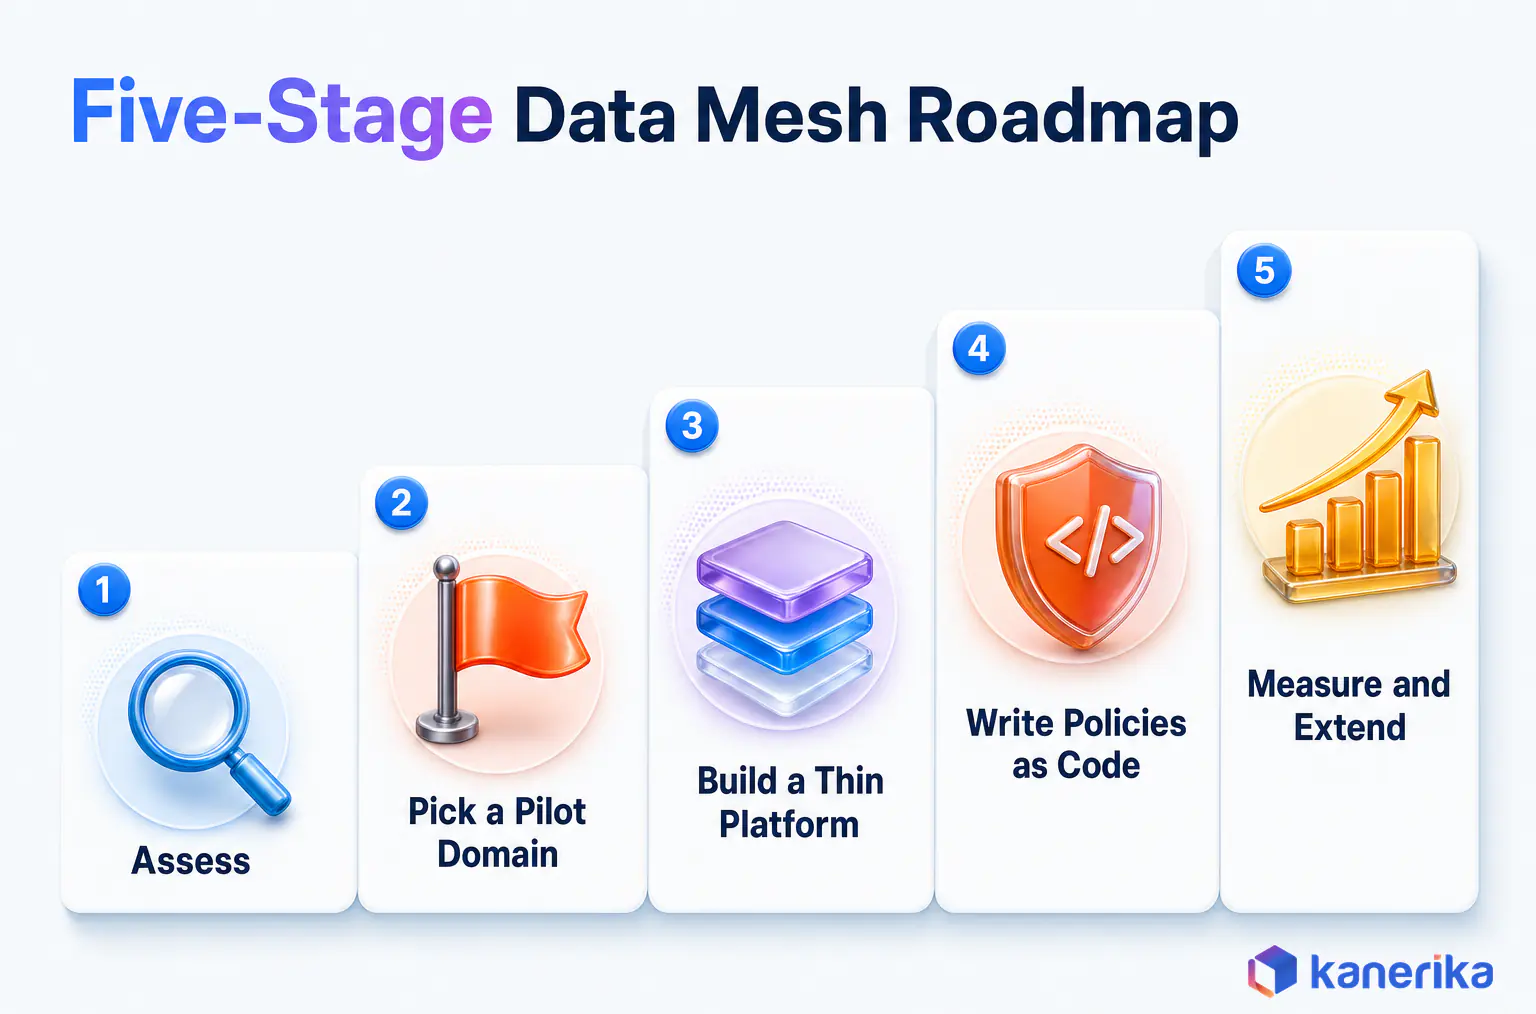
- Assess. Score the current state against each of the four principles, and record the central backlog as a baseline.
- Pick one or two domains and one product. Choose domains with motivated owners and data that others already request, which exercises principles 1 and 2.
- Build a thin platform slice. Provide just enough templates, storage and catalog support for the pilot products, so principle 3 starts in miniature.
- Write the first policies as code. Start with classification, access and schema checks enforced at publish time, under principle 4.
- Measure and extend. Compare results with the baseline, and only then add domains in waves.
Resist adding domains before the first product has real consumers. A mesh with ten unused products is harder to fix than a mesh with one well-used product.
KPIs That Show the Principles Are Working
Pick a few measures that map to the principles and track them from the first stage. Observability tooling can collect several of them automatically, and our data observability guide covers the options.
| KPI | Principle | How it is measured |
|---|---|---|
| Time to publish a new data product | Self-serve platform | Days from request to the first consumer query |
| Products with a named owner and SLO | Data as a product | Share of catalog products with both fields filled |
| Reuse count | Data as a product | Distinct consuming teams or products per data product |
| Policies enforced automatically | Federated governance | Share of global rules checked by the platform rather than by people |
| Central backlog age | Domain ownership | Median age of open requests to the central team |
Set your own targets from the baseline rather than borrowing benchmarks, since the direction of travel matters more than any single number.
Checklist
Data Engineering Checklist
Use this checklist to scope the platform slice for a data mesh pilot, from pipelines and testing to monitoring and documentation.
Get the Checklist →Common Mistakes When Applying the Four Principles
Failed adoptions tend to break one principle while claiming to follow it. Four patterns come up again and again, and each has a straightforward fix.
- Renaming the central team as the platform team. If it still builds every pipeline, nothing has changed. Instead, move pipeline work into domains and give the platform team a product backlog of its own.
- Domains without data engineers. Owners without builders become reviewers of someone else’s work. So embed at least one engineer in every pilot domain.
- Products with no consumer. Publishing everything creates clutter rather than value. Require a named consumer before anyone builds a product.
- Governance as a PDF. Rules that live in a document get checked late or never. Turn each global rule into a platform check, starting with classification and access.
Each fix maps back to one of the four principles. For the governance mistake in particular, our data governance best practices show how teams turn policy into routine checks.
How Kanerika Helps Put Data Mesh Principles Into Practice
Kanerika is a data and AI consulting firm that helps enterprises move from central data bottlenecks toward owned, governed data products. We start with a principle-by-principle readiness assessment. That way, the gaps in ownership, product practice, platform and governance are visible before any build begins.
From there, the work is concrete. For example, we help teams define a first data product with a contract and an SLO. We also set up Fabric domains or Unity Catalog policies and write governance policies as code. Our data engineering services cover the platform and product work, while our data governance services cover the federated rules.
A typical first engagement stays small on purpose. It covers one or two domains, one or two data products with real consumers, and the first set of policies as code. Leaders then judge the model on evidence from their own data before funding the next wave.
Client Example: One Governed KPI Layer Across Three SAP Systems
One engagement shows the pattern. A global leader in thermal management and heat transfer solutions had its order journey spread across three SAP systems. Kanerika connected 35+ source tables across the order lifecycle into one Microsoft Fabric platform and built 50+ governed KPIs to standardize lead-time reporting. The Microsoft Fabric order visibility case study explains how that manufacturer now tracks order lead times from lead to delivery across the three SAP systems.
The result was a 60% reduction in time spent per reporting cycle. It was not a full data mesh. Still, it shows two of the principles at small scale: data from three systems shaped into reusable, governed datasets, and one governed KPI layer that every team now works from. The case study on unifying order data across three SAP systems has the details.
Case Study
60% Less Reporting Effort Across 3 SAP Systems on Fabric
A global thermal management leader unified 35+ source tables from three SAP systems into one Microsoft Fabric platform, with 50+ governed KPIs and a 60% reduction in time spent per reporting cycle.
Read the Case Study →If you are weighing where to start, you can book a working session with our team. Whatever platform you choose, adopt the principles together, because none of them works alone. Those are the four core data mesh principles every data leader should know: domain ownership, data as a product, a self-serve platform and federated governance.
Frequently Asked Questions
What are the four principles of data mesh?
The four principles of data mesh are domain-oriented data ownership, data as a product, self-serve data infrastructure as a platform, and federated computational governance. Zhamak Dehghani set them out in 2020 and described them as collectively necessary and sufficient. In practice that means adopting all four together, because each one covers a gap the others leave open.
Are there four or six data mesh principles?
There are four. Lists of six usually split governance into two items, such as decentralized governance and federated governance, or promote a practice like API-first design to a principle. Those extras are useful, but they belong under the original four. Dehghani’s six data product qualities are a separate list that describes what a good data product looks like.
What is an example of data mesh in a company?
Picture a manufacturer whose order, production and logistics teams each publish one data product with a named owner. A shared platform gives all three the same templates and checks. A governance rule requires a common order identifier. The logistics team then builds an on-time delivery product from all three, replacing several conflicting spreadsheet versions of that KPI.
What is the difference between data mesh and data fabric?
Data mesh is mainly an operating model that decentralizes data ownership to business domains. Data fabric is mainly a technology layer that connects and manages data across systems, often using metadata and automation. They can work together, with a fabric providing integration capabilities inside a mesh platform. Our data fabric vs data mesh comparison explains the trade-offs.
Can data mesh work with a central data warehouse or lakehouse?
Yes. Data mesh decides who owns and publishes data, not where it is stored. Many companies run a mesh on one shared lakehouse or warehouse, with each domain owning its own schemas, products and pipelines inside it. The platform team runs the shared storage, while governance rules keep the domains compatible. Our data mesh vs data lake article explains more.
What are the biggest challenges in implementing data mesh?
The hardest parts are organizational. Domains often lack data engineers, central teams get renamed without changing how they work, and governance stays a document instead of becoming automated checks. Drawing domain boundaries around the org chart instead of business capabilities causes problems later. Funding a platform team before value is proven is another common hurdle for leadership to plan around.
How do you start a data mesh strategy?
Start by assessing your current state against the four principles and recording the central backlog as a baseline. Pick one or two domains with motivated owners and data others already request. Build a thin platform slice, write the first governance rules as code, publish one product with real consumers, and measure results before adding more domains.
Can you implement data mesh on Microsoft Fabric?
Yes, partly. Fabric supports domains and subdomains, and some tenant-level governance settings can be delegated to domains. Microsoft’s documentation, last updated in May 2025, says Fabric’s data mesh support mainly covers organizing data into domains. Data product ownership, contracts and federated rules still have to be designed and run by your teams, often alongside Microsoft Purview for governance.
What are the main components of a data mesh?
A data mesh has four working parts. Domain teams own and publish data products, and each product bundles code, data with metadata, and infrastructure. A self-serve platform gives every domain the same tooling for storage, pipelines and discovery. A federated governance group sets global rules, which the platform then enforces automatically across every product in the mesh.
What is a data product in data mesh?
A data product is a dataset published by a domain for known consumers, with a named owner and a quality promise. Dehghani calls it the architectural quantum of a mesh, meaning the smallest unit you can deploy on its own. It carries its code, its data and metadata, and the infrastructure it needs, so it can change independently.
What is federated computational governance?
Federated computational governance is the fourth data mesh principle. A group of domain and platform representatives agrees on a small set of global rules, such as access, classification and schema standards. The platform then enforces those rules as code every time a product is built, published or queried, instead of relying on people to check documents after the fact.
What is a self-serve data platform in data mesh?
A self-serve data platform is shared infrastructure that lets domain teams build, publish and run data products without filing tickets. A platform team owns it and treats the domains as its customers. Dehghani describes three planes, covering infrastructure provisioning, data product developer experience and mesh supervision, which spans discovery, lineage, policy enforcement and quality monitoring across products.
What is data mesh in simple terms?
Data mesh is a way of organizing analytical data so that the teams who know the data best also own it. Each business domain publishes its data as a product for others to use. A shared platform keeps the tooling consistent, and shared rules keep the products compatible, so the company avoids one central team becoming a bottleneck.
What are the benefits of data mesh?
The main benefits are shorter wait times for new data, clearer ownership when numbers are wrong, and data that reflects the business meaning its domain intended. Reuse also improves because products are documented and discoverable. These gains appear only when all four principles are in place. Our broader data mesh guide covers benefits and use cases in more detail.
What prerequisites and skills does data mesh need?
Data mesh needs domain owners who can make decisions about their data, data engineers embedded in those domains, and a platform team that builds shared tooling. It also needs an executive sponsor to move decision rights between teams. Useful skills include data modeling, pipeline engineering, writing data contracts, catalog management and expressing governance rules as automated checks.
Is data mesh obsolete in 2026?
No. The four principles still describe how large organizations can scale analytical data without one central bottleneck. What has changed is the tooling, since platforms such as Microsoft Fabric, Databricks and Snowflake now ship domain and governance features. AI work also raises the value of owned, governed and well-documented data, which is exactly what a mesh produces.