TL;DR
The best RAG tools for enterprise AI applications depend on the layer you are missing, so pick a framework to orchestrate, a vector database to store and an evaluator to score. LangChain, LlamaIndex and Haystack are the leading frameworks, while Pinecone, Weaviate and Qdrant lead on vector storage and Ragas handles evaluation. When your data already sits in one cloud and the team is small, a managed service such as Azure AI Search or Amazon Bedrock Knowledge Bases can replace the build. Choose on security and permission-aware retrieval first, then retrieval quality, then cost. LLM tokens, not vector storage, usually dominate the monthly bill, so retrieval precision is the main cost lever. Kanerika takes RAG from a one-source pilot to production with permission-aware retrieval, citations and evaluation on every change.
Key Takeaways
- RAG tools cover four layers, so most teams need one tool per missing layer: framework, vector database, evaluator or managed cloud service.
- LangChain suits agent-heavy workflows, while LlamaIndex suits document-heavy ingestion and Haystack suits explicit, testable pipelines.
- Pinecone is fully managed, Weaviate pairs open source with a cloud service, and Qdrant also adds Hybrid Cloud for data residency.
- Score retrieval and generation separately with Ragas metrics such as Context Recall and Faithfulness, then pin the Ragas version.
- Enforce access control at retrieval time, before any answer is generated, in line with OWASP LLM08:2025 and the NIST AI RMF.
- In our illustrative model, trimming retrieved context from 5 chunks to 3 cuts a Claude Sonnet 5.5 bill from $7,200 to $5,760 a month.
When the Pilot Meets SharePoint
Picture a RAG pilot that answers questions from 40 curated PDFs. The answers are quick, cited and correct, so the steering group signs off on a wider rollout.
Then the same pilot is pointed at the full SharePoint estate. Soon it starts quoting a superseded policy, and one answer cites a document the user was never allowed to open.
Nothing broke in the model. Instead, the gap sat in the tooling around it: connectors, permission checks, retrieval quality and evaluation. This guide compares the best RAG tools for enterprise AI applications by the layer each one fills, so you can close those gaps before rollout.
What RAG Tools Are, and the Four Layers They Cover
RAG tools are the software that lets a language model answer from your documents instead of from memory alone. In retrieval-augmented generation, the system first finds relevant passages, then passes them to the model as context for the answer.
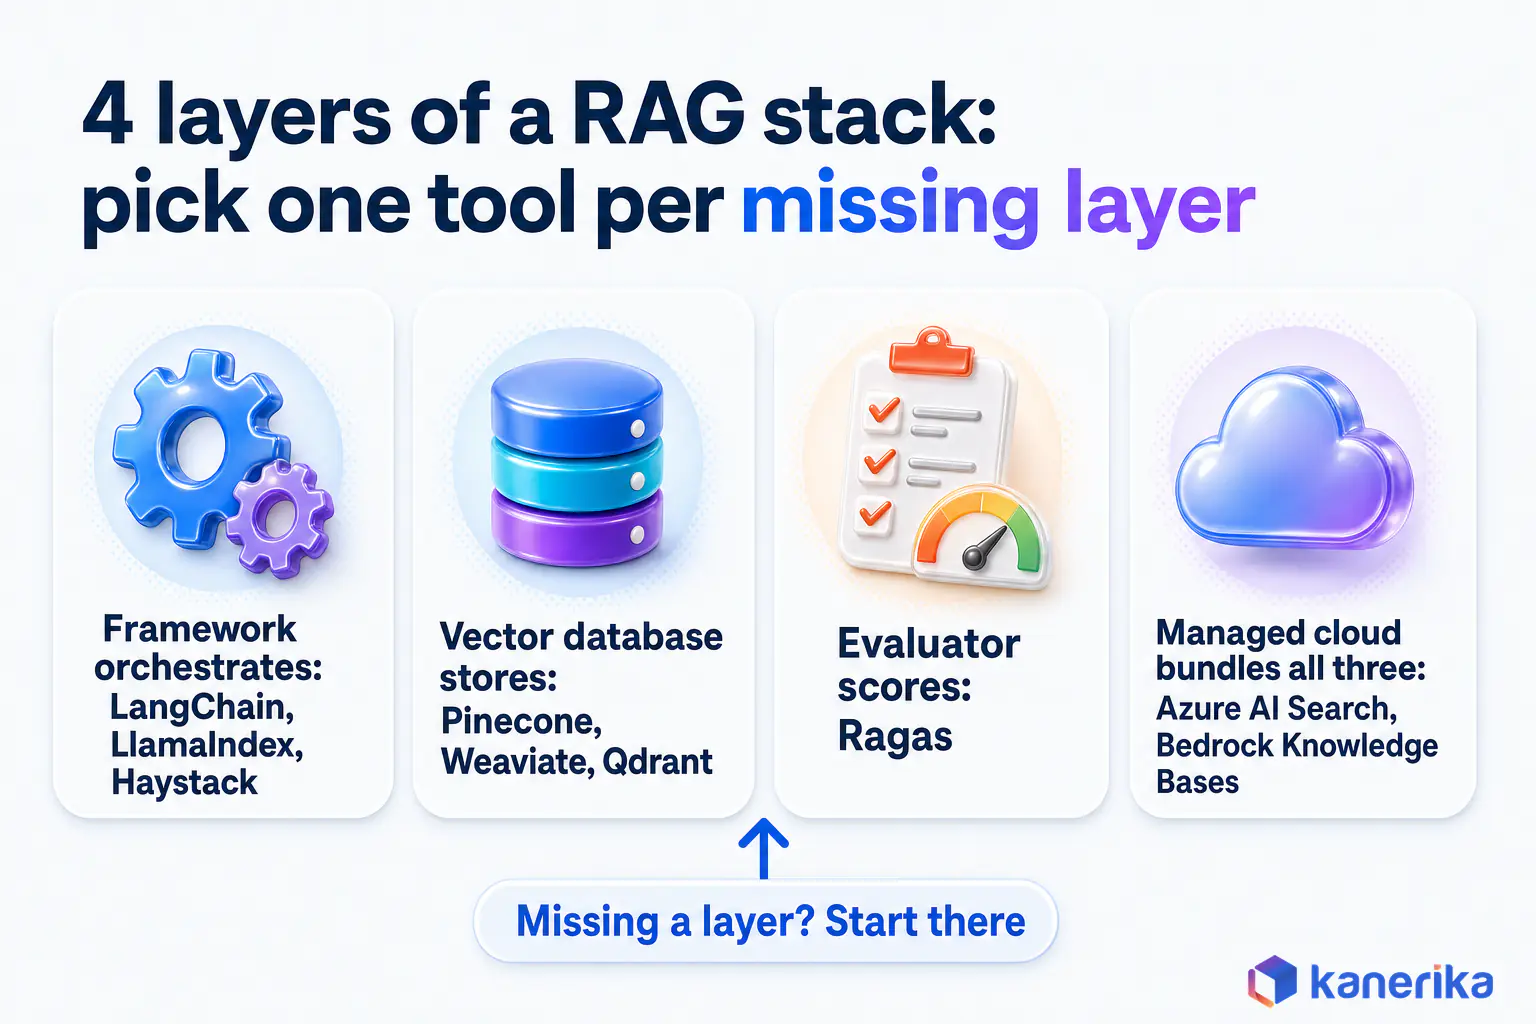
No single product does all of that well. So an enterprise RAG stack splits into four layers, and each tool in this guide lives mainly in one of them.
- Orchestration framework. Code that connects loaders, retrievers, prompts and models into one flow. LangChain, LlamaIndex and Haystack sit here.
- Vector database. Storage that indexes embeddings and returns the nearest passages, together with filters on metadata. Pinecone, Weaviate and Qdrant sit here.
- Evaluator. A test layer that scores retrieval and answers against a fixed question set before each release. Ragas sits here.
- Managed cloud service. A hosted service that bundles ingestion, indexing and retrieval inside one cloud, such as Azure AI Search or Amazon Bedrock Knowledge Bases.
The benefits come from that split. Answers stay grounded in a controlled source set, and each one can carry a citation back to the passage it used. You can also update sources without retraining a model.
A useful way to read the rest of this guide is to ask which layer you are missing. For example, a team with a strong data platform may only need a framework and an evaluator. A small team, by contrast, may buy the whole stack as a managed service.
How RAG Differs from a Standalone LLM
A standalone LLM answers from what it learned in training, so it cannot see your contracts, tickets or policies. It also has no way to show where an answer came from.
RAG adds a retrieval step before generation. The model then reads the passages you supply, cites them and stays inside the boundary of your sources. For a deeper look, see our guide to RAG vs a standalone LLM.
Where Enterprises Use RAG Tools
Five patterns account for most enterprise RAG work, and each one puts weight on a different layer of the stack. For a fuller catalog, see our guide to types of RAG applications.
- Internal knowledge management. Employees ask questions across wikis, policies and project files, which is the core of AI knowledge management.
- Domain expert assistants. Legal, finance or engineering teams query contracts, filings or manuals, then get cited answers.
- Research tools. Analysts search long reports, so they get summaries that link back to the source pages.
- Learning platforms. Training content becomes a tutor that answers from approved course material only.
- Regulatory and compliance support. Teams check a question against current regulations as well as internal controls, with every claim traceable to a source.
How a Production RAG Pipeline Works
A production RAG pipeline is a chain of steps, and a weak link anywhere shows up as a bad answer at the end. Take an engineer who asks about one exact part number: if retrieval misses it, no model can recover the answer.
The eight steps below are the standard shape. Tools differ, though, in how much of each step they handle for you.
- Parse and ingest. Pull files from SharePoint, file shares and databases, then extract clean text from PDFs, scans and tables through document parsing.
- Chunk. Split documents into passages. Test two or three chunk sizes against the same question set instead of trusting a default.
- Embed. Convert each chunk into a vector with an embedding model, and keep that model fixed so old and new vectors stay comparable.
- Index with metadata. Store vectors with source, date, owner and access-control fields, so that filters can run at query time.
- Hybrid retrieve. Combine keyword and vector search, so part numbers and clause IDs still match exactly while paraphrased questions still find their meaning.
- Rerank. Pass the top candidates through a reranker that orders them by relevance before the model sees them.
- Generate with citations. Send the best passages to the LLM with instructions to answer only from them, then cite each source.
- Evaluate. Score retrieval and answers on a fixed question set, and rerun the scores whenever something changes.
Agentic RAG adds a planning step on top: the system splits a question into sub-queries, retrieves for each and then combines the results. Our guides to agentic RAG, knowledge graph RAG and advanced RAG techniques cover those patterns.
This guide stays at the tool level. To build and debug each pipeline stage, use our step-by-step pipeline guide.
How to Evaluate the Best RAG Tools for Enterprise AI Applications
Evaluating RAG tools starts with your constraints, and feature lists come later. A bank with strict data residency rules and a startup with one public knowledge base can reach opposite answers from the same shortlist.
Use the seven criteria below as a scoring sheet. Weight security and permissions first, then retrieval quality, then cost, because a cheap tool that leaks a restricted document is never cheap.
Seven Criteria to Score Before You Shortlist
| Criterion | What to check | Why it matters |
|---|---|---|
| Ingestion and connectors | Native loaders for SharePoint, file shares, PDFs, databases and scanned documents | Most answer problems start earlier, with bad or missing source text |
| Retrieval quality | Hybrid keyword and vector search, plus reranking and metadata filters | Users ask with exact IDs as well as loose paraphrases |
| Permission-aware retrieval and SSO | Document-level access filters that run during the query, plus SSO | Users must never retrieve passages they cannot open, even if those passages are relevant |
| Deployment and data residency | Managed, self-hosted or hybrid, plus region choice and private networking | Regulated data often must stay in one region, so this row can rule a tool out |
| Observability and evaluation | Tracing of each retrieval and model call, plus evaluation | You cannot fix a wrong answer until you can trace it |
| Cost model | Flat tier, usage-based or minimum spend, plus per-request fees | Pilot pricing rarely holds once query volume grows |
| License | MIT, Apache 2.0 or commercial terms | Decides whether you can fork and self-host, so check it before any build |
Score each candidate from 1 to 3 on every row, then run the top two through a bake-off on your own questions. The rollout section later in this guide explains how to run that test.
Two rows deserve extra weight in regulated industries. Permission-aware retrieval and data residency are hard to retrofit, so a tool that fails either one should leave the shortlist early. This guide to RAG security controls covers how to test permission-aware retrieval before launch.
Checklist
Generative AI Checklist: Plan Your RAG Rollout
Turn the evaluation criteria above into a working plan with Kanerika’s Generative AI Checklist before you commit to a RAG stack.
Download the checklist →The 7 Best RAG Tools for Enterprise AI Applications at a Glance
The seven tools below cover three of the four layers: three frameworks, three vector databases and one evaluator. Versions and prices are as of November 3, 2026, taken from each project’s release page or pricing page.
| Tool | Layer | License | Latest release | Managed option and entry price | Best for |
|---|---|---|---|---|---|
| LangChain | Framework | MIT | 1.4.8 (November 2, 2026) | Free library, plus LangSmith for tracing | Agent-heavy workflows with many integrations |
| LlamaIndex | Framework | MIT | 0.14.25 (September 21, 2026) | Free library | Document-heavy ingestion, such as contracts and policies |
| Haystack | Framework | Apache 2.0 | haystack-ai 3.4.1 (October 21, 2026) | Free library | Production teams that want explicit pipelines |
| Pinecone | Vector database | Commercial service | Managed service | Starter free; Builder $20/month; Standard $50/month minimum | Retrieval as a service rather than a database to run |
| Weaviate | Vector database | Open source | v1.40.3 (October 28, 2026) | Weaviate Cloud free tier; Flex from $45/month | Starting managed, then self-hosting later |
| Qdrant | Vector database | Apache 2.0 | v1.20.0 (October 22, 2026) | Qdrant Cloud free tier; Standard usage-based; Hybrid Cloud | Data residency through self-hosting or Hybrid Cloud |
| Ragas | Evaluator | Apache 2.0 | 0.4.3 (January 13, 2026) | Free library | Scoring retrieval and answers before each release |
Read the table by layer, and avoid treating it as a ranking. A framework and a vector database solve different problems, so the right stack usually holds one of each plus an evaluator.
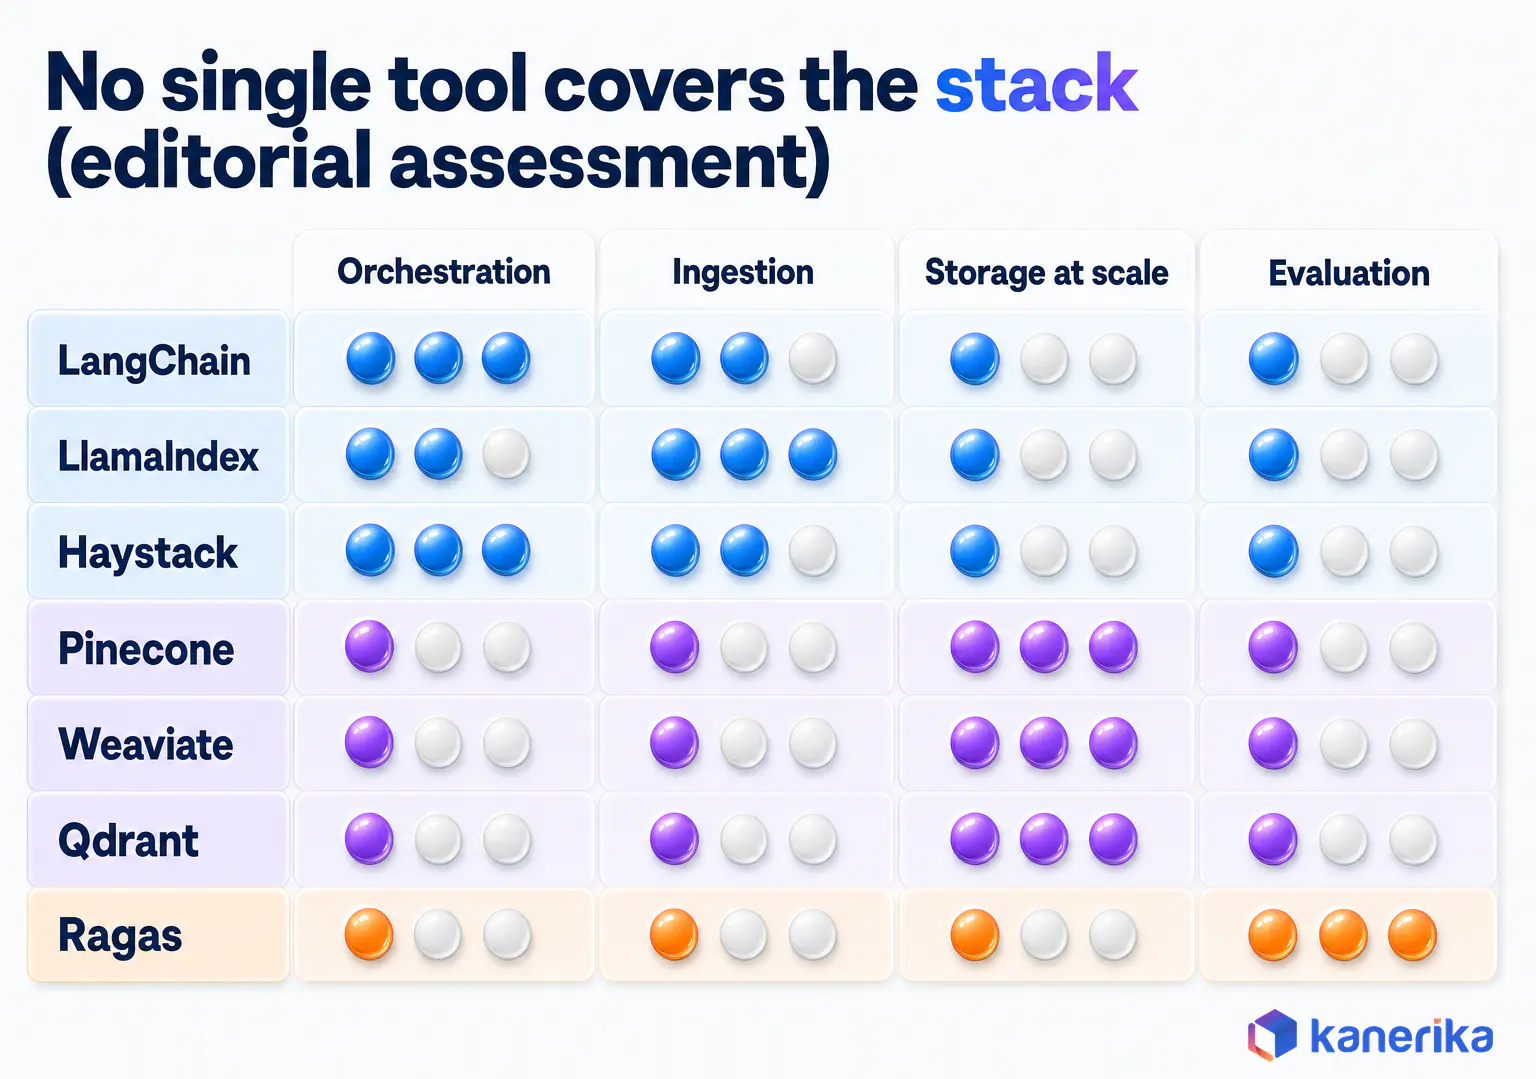
The matrix below is our editorial assessment of where each tool is strongest. Frameworks score highest on orchestration, vector databases on storage at scale, and Ragas only on evaluation, so no single tool covers the stack.
RAG Frameworks: LangChain, LlamaIndex and Haystack
A RAG framework is the code layer that wires loaders, retrievers, prompts and models together. All three below are open source and free to use, so the choice comes down to how your team likes to build. For a head-to-head on APIs and design, see LlamaIndex vs LangChain vs Haystack.
LangChain
LangChain is the most widely adopted of the three, with about 149K GitHub stars as of November 3, 2026. The latest release on PyPI is 1.4.8 from November 2, 2026, under the MIT license, and it needs Python 3.10 or later.
Its strength is breadth, since it connects to most model providers and vector databases. Two companion projects also cover the rest of the lifecycle: LangGraph for stateful agents and LangSmith for tracing and evaluation.
The watch-out is moving parts. Fast release cycles mean you should pin versions and test every upgrade, while a simple retrieval flow can carry more abstraction than it needs. Choose LangChain when RAG is one step inside a larger agent workflow.
LlamaIndex
LlamaIndex focuses on getting documents into a searchable shape. It has about 53K GitHub stars, and version 0.14.25 shipped on September 21, 2026, under MIT with Python 3.10 or later.
Its strength is ingestion and indexing, with loaders and index structures built for large, messy document sets. That makes it a strong fit when the hard part of the project is the documents themselves.
The watch-out is scope, because teams that need complex multi-step agents often pair it with a second orchestration tool. Choose LlamaIndex for document-heavy knowledge bases, research assistants and contract or policy search.
Haystack
Haystack builds RAG as explicit pipelines of components that you connect and test one by one. The haystack-ai package reached 3.4.1 on October 21, 2026, under Apache 2.0, and it has about 27K GitHub stars.
Its strength is clarity. Each pipeline is a defined graph of steps, so behavior is easier to review, test and hand over between teams.
The watch-out is the Python 3.11 floor, since it can block older runtime images. The pipeline style also asks for more design up front. Choose Haystack when you want production pipelines that an operations team can read and maintain.
All three can run the same retrieval flow. The real difference is whether your team thinks in agents, in documents or in pipelines.
Kanerika Service
Move a RAG Pilot into Production
Kanerika designs and builds enterprise RAG systems with permission-aware retrieval, citations on every answer and evaluation on every change.
Explore RAG developmentVector Databases: Pinecone, Weaviate and Qdrant
A vector database stores embeddings and returns the passages closest to a question, with filters on metadata such as owner or date. The three below differ most in how they are hosted and priced. Our vector database comparison also covers more options in depth.
Pinecone
Pinecone is a fully managed vector database, so there is no cluster for your team to run. Pricing as of November 3, 2026, starts with a free Starter plan, then Builder at $20 a month flat.
Production plans add minimums. Standard carries a $50 monthly minimum, while Enterprise carries a $500 monthly minimum. Storage then costs $0.33 per GB per month, and reranking costs $2 per 1,000 requests.
Choose Pinecone when your team wants retrieval as a service and is comfortable with data in a vendor cloud. The watch-out is dependence on its API and hosting model.
Weaviate
Weaviate is an open-source vector database with its own managed cloud. Version v1.40.3 shipped on October 28, 2026, and the project has about 17K GitHub stars.
The Weaviate Cloud free tier holds 100,000 objects with 1 GB of memory and 10 GB of disk. Paid plans then start with Flex from $45 a month and Premium from $400 a month.
Choose Weaviate when you want to start managed and keep the option to self-host the same engine later. The watch-out is that self-hosting moves backups, upgrades and scaling onto your team.
Qdrant
Qdrant is an open-source vector database under Apache 2.0, at version v1.20.0 from October 22, 2026. It has about 35K GitHub stars, and its cloud has a free-forever tier with 0.5 vCPU, 1 GB of RAM and 4 GB of disk.
Paid tiers split by control. On the Qdrant pricing page, Standard is usage-based with a 99.5% SLA, while Premium adds a minimum spend, SSO, private VPC links and a 99.9% SLA.
Hybrid Cloud runs Qdrant’s managed service on your own infrastructure. Choose Qdrant when data residency or self-hosting is a hard requirement, but plan for the fact that the underlying infrastructure stays your job.
What Vector Storage Actually Costs
Storage is rarely the cost driver. As a labeled assumption, take 10 million chunks at 1,536 dimensions and 4 bytes per value. That comes to about 61 GB, or roughly $20 a month at Pinecone’s $0.33 per GB.
That sits below the $50 Standard minimum, so the plan minimum sets the bill and the data size barely matters. For small corpora, Postgres or an existing search index can be enough.
Evaluation: Ragas and How to Score a RAG System
Evaluation tells you whether a change made answers better or worse before users find out. Without it, a team that swaps an embedding model or a chunk size is guessing.
Ragas is the open-source evaluator in this guide, under Apache 2.0, with about 16K GitHub stars. It scores retrieval and generation separately, which matters because the fixes are different.
Five Ragas metrics cover most enterprise needs:
- Context Precision. How much of the retrieved context is relevant to the question.
- Context Recall. Whether the retrieved context holds the information needed to answer.
- Faithfulness. Whether every claim in the answer is supported by the retrieved context.
- Response Relevancy. How directly the answer addresses the question asked.
- Noise Sensitivity. How often the system makes errors when irrelevant passages are mixed into the context.
Reading the Scores Before You Fix Anything
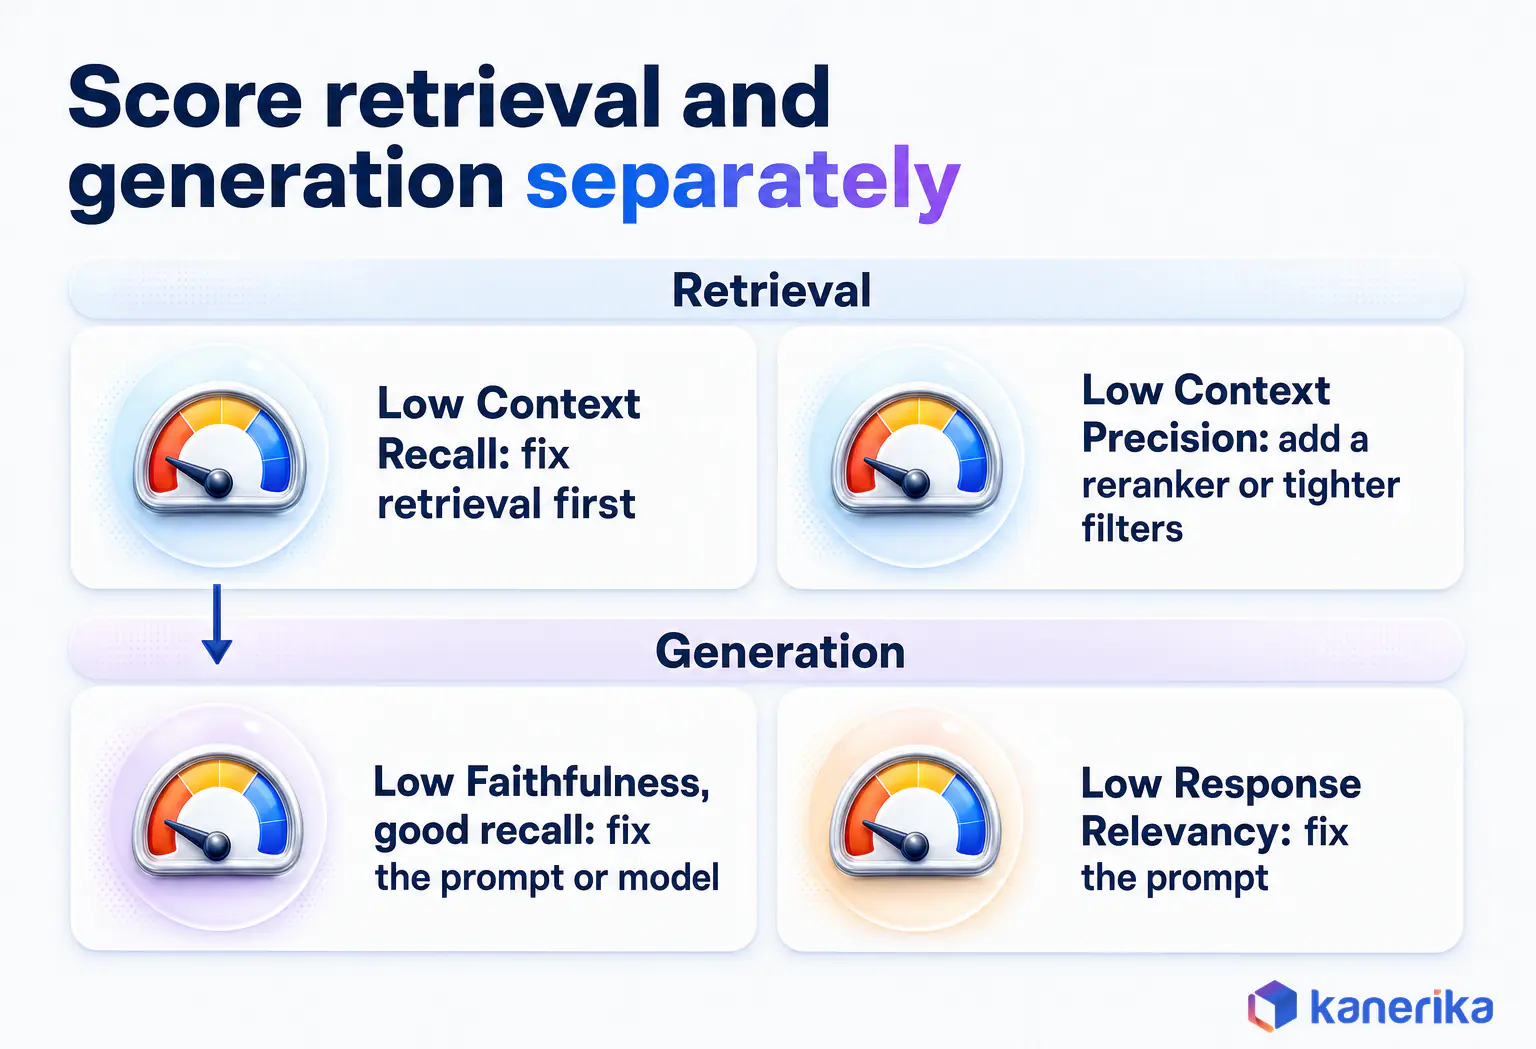
Read the scores as a diagnosis. If Context Recall is low, fix retrieval first; if Faithfulness is low while recall is good, fix the prompt or the model.
Low Context Precision usually calls for a reranker or tighter metadata filters. Low Response Relevancy, on the other hand, points to the prompt or to the way the question reaches the model.
Check project health before you depend on it. The latest Ragas release is 0.4.3 from January 13, 2026, and the repository moved to vibrantlabsai/ragas, with its last commit on February 24, 2026.
So pin the version in your requirements and keep a fallback, such as LangSmith evaluations or your own scoring scripts. Our LLM evaluation framework guide covers test-set design, while our guide to AI hallucinations explains the failure that Faithfulness is built to catch. For production tracing, pair evaluation with LLMOps observability.
Managed Cloud RAG Services: When to Buy Instead of Build
A managed RAG service bundles ingestion, indexing and retrieval inside one cloud, so the team configures instead of coding. These services are not counted in the seven tools above, because each one replaces several layers at once.
| Service | What it manages | Best fit |
|---|---|---|
| Azure AI Search | Indexing and hybrid retrieval, as well as agentic retrieval with parallel subqueries; it also underpins Foundry IQ | Microsoft and Azure estates, especially those building on Azure AI Foundry |
| Amazon Bedrock Knowledge Bases | Ingestion, storage and retrieval; AWS also recommends its Managed Knowledge Base, with multimodal ingestion, auto-scaling storage and agentic multi-hop retrieval | When data and models already run on AWS |
| RAG Engine on Gemini Enterprise Agent Platform | Connects private data to models for grounded answers, as one component of Google’s agent platform | When agents are built on Google Cloud |
| Databricks AI Search (formerly Databricks Vector Search) | Vector indexes built from Delta tables | Lakehouse teams with governed Delta data, as covered in our Databricks vector search guide |
Some teams run both, with a managed service for one estate and a framework for cross-cloud cases. Platform direction matters here as well, and this Kanerika podcast episode looks at the AI trends and predictions shaping 2026.
The rule of thumb is simple. Buy when your data already lives in that cloud and the team is small; build when you need cross-cloud sources or custom retrieval logic. Either route still has to pass the security checks in the next section.
Security, Permission-Aware Retrieval and Compliance
Permission-aware retrieval means the system only fetches passages the user could open in the source system. That check has to run at retrieval time, because once a restricted passage reaches the model, no output filter can reliably pull it back.
The OWASP Top 10 for LLM Applications 2025 names the risks directly. LLM08:2025 Vector and Embedding Weaknesses covers leaks through the vector store, while LLM01:2025 covers prompt injection and LLM02:2025 covers sensitive information disclosure.
Here is how those risks show up in a RAG system. A shared document carries hidden text telling the model to ignore its rules, and a retriever with no checks passes it straight into the prompt. The same retriever can also surface a salary file to a user who only searched for the pay policy.
For governance, the NIST AI Risk Management Framework 1.0, released on January 26, 2023, sets the structure. Its Generative AI Profile, NIST-AI-600-1, then followed on July 26, 2024.
Five Controls That Stop Leaks Before Generation
Five controls do most of the work, and each one maps to the risks above:
- Sync access control lists from each source into chunk metadata, then filter on them in every query.
- Use SSO so that retrieval runs as the real user, never as a shared service account.
- Treat retrieved text as untrusted input, since a poisoned document can carry injected instructions.
- Log every retrieval and answer, together with its citations, for audit.
- Pick a deployment that meets residency rules, such as Qdrant Hybrid Cloud on your own infrastructure. Amazon Bedrock regional endpoints also route data through set regions for Claude Opus 4.7, Haiku 4.5 and later models.
None of these controls depends on which framework or vector database you pick. Instead, they depend on whether the tool exposes metadata filters, user identity and logs, which is why those checks sit near the top of the scoring sheet.
For the wider threat model, see our LLM security guide. For fully isolated deployments, also read our guide to private LLMs.
Checklist
Check Your RAG Controls Against an AI Governance Checklist
Use Kanerika’s AI Governance Checklist to review access control, audit and risk steps before a RAG system reaches regulated data.
Download the checklist →Which LLM to Pair with Your RAG Tools, and What a Month Costs
The LLM is the part of a RAG system you pay for on every query, so model choice sets most of the monthly bill. The retrieval layer also decides how many tokens each query sends, which links the two decisions.
Prices below are per million tokens, from vendor pages read on November 2 and 3, 2026.
| Model | Input / output per 1M tokens | Context | Notes |
|---|---|---|---|
| Claude Haiku 5.5 | $0.10 / $0.50 | 1M | For prompts up to 100K tokens; above that, output is $2.50 |
| Claude Sonnet 5.5 | $2 / $10 | 1M | Mid tier for harder cited answers |
| Claude Opus 5.5 | $4 / $20 | 1M | Matches or beats Fable 5.1 on most listed benchmarks |
| GPT-6 Luna | $0.10 / $0.50 | 1.05M | Same list price as Claude Haiku 5.5; suits high volume |
| GPT-6.1 Sol | $2 / $10 | 1,050,000 | Input costs 2x once prompts pass 272K tokens |
| Gemini 3.8 Flash | $0.75 / $3.75 | See vendor page | Price through December 31, 2026, then $1.50 / $7.50 |
| Gemini 4 Argon | $2 / $10 | Up to 1M | Price through November 30, 2026, then $4 / $20 from December 1, 2026 |
| Mistral Large 4 | $0.70 / $2.10 | 1M | Open weights, but under a custom license |
| gpt-oss-120b | Self-hosted, no per-token fee | See model card | Apache 2.0; runs on a single 80GB GPU such as an H100 |
A Worked Monthly Cost Example
The numbers below are illustrative assumptions, not a quote. Take 20,000 queries a day for 30 days, which is 600,000 queries a month.
Each query sends 5 retrieved chunks of 600 tokens plus 1,000 tokens of prompt and instructions, so 4,000 input tokens in total. Each answer then returns 400 output tokens.
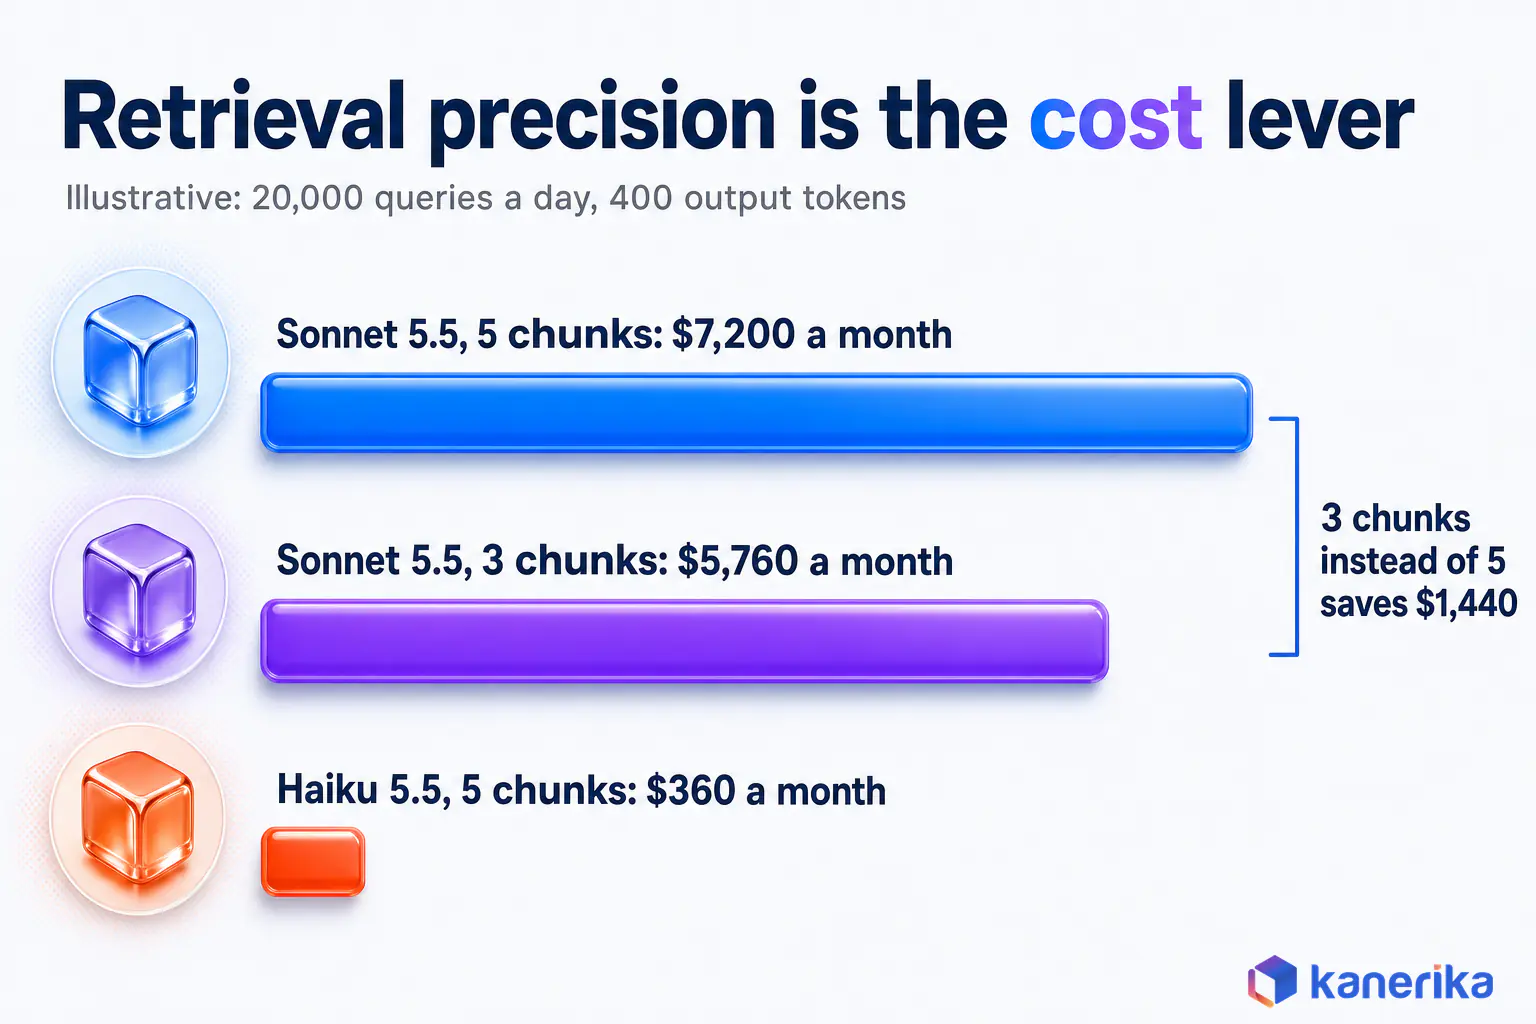
- Claude Sonnet 5.5 with 5 chunks. 2.4 billion input tokens cost $4,800 and 240 million output tokens cost $2,400, so the month costs $7,200.
- Claude Sonnet 5.5 with 3 chunks. Input falls to 2,800 tokens per query, so input costs $3,360 and the month costs $5,760.
- Claude Haiku 5.5 with 5 chunks. Input costs $240 and output costs $120, so the month costs $360.
Retrieval precision is the main cost lever here. If a reranker lets you send 3 strong chunks instead of 5 average ones, the bill drops by $1,440 a month on the same model.
A 1M-token context window does not replace retrieval either. Stuffing whole libraries into each prompt multiplies the cost per query, and it also skips the permission check that retrieval enforces.
Retrieval is not the only way to adapt a model, though. Our guides to RAG vs fine-tuning and parameter-efficient fine-tuning cover when training beats retrieval, while context engineering covers how to shape what each prompt carries. For model choice at scale, see our enterprise LLM guide.
How to Choose and Roll Out a RAG Tool in Five Steps
Choosing a RAG tool works best as a short, evidence-led project. The five steps below turn the criteria and costs above into a decision you can defend to security, finance and the business owner.
- Define one use case and its sources. Name the users, the questions they ask and the systems that hold the answers.
- Pick the layer you are missing. For example, a team that already runs a vector store may only need a framework and an evaluator.
- Run a bake-off on 50 to 100 of your own questions. Score each candidate stack with the same Ragas metrics, then compare cost per query.
- Harden permissions, citations and evaluation in CI. Every change to chunking, models or prompts should rerun the question set before release.
- Scale sources and monitor cost. Add one source at a time, and track token spend per query as usage grows.
RAG is also not the only way to connect a model to enterprise data. Tool-calling protocols can fetch live records on demand, and our MCP vs RAG guide explains when each one fits.
No-Code and Low-Code Builders: Dify and RAGFlow
Dify and RAGFlow let business teams assemble RAG apps through a visual interface. Both were active projects on GitHub as of November 3, 2026. RAGFlow is licensed under Apache 2.0, while Dify uses a modified Apache 2.0 license that requires a commercial license for multi-tenant use.
They fit internal prototypes and departmental tools, where speed matters more than custom retrieval. They fit less well when you need fine-grained permission filters, custom reranking or strict deployment controls.
Treat them as a fast way to test demand before a full build. Once a prototype proves its value, move it onto the framework, vector database and evaluator you chose above.
Need a second opinion on the shortlist? A short working session can map your sources and constraints to a stack.
Talk to Kanerika
Get a RAG Stack Recommendation for Your Data
Share your sources, users and constraints, and Kanerika’s RAG team will map them to the framework, vector database and evaluator that fit.
Talk to our RAG team →Common RAG Failure Points and How to Fix Them
RAG failures usually trace back to the data and the retrieval step, and the model is rarely the first suspect. Each item below pairs a common problem with the fix that usually works.
- Poor document quality. Scans, tables and duplicate files produce noisy text. Fix it with better parsing and deduplication before indexing.
- Bad chunking. Chunks that split a table or a clause lose meaning. Test two or three chunk sizes, then keep headings with their text.
- Heavy tuning load. Retrieval settings, prompts and models all interact. Change one variable at a time, then rerun the evaluation set.
- Latency. Reranking and long prompts add response time. Cap the candidate count, cache frequent queries and send fewer, better chunks.
- Prompt dependence. Small prompt changes can swing answer quality. Version prompts like code, and test them against the same questions before release.
- Stale indexes. Answers quote superseded documents. Schedule incremental re-indexing and store document dates so that filters can drop old versions.
Four of the six fixes are data or retrieval work. That is why the evaluation and permission layers deserve as much budget as the model itself.
How Kanerika Builds Enterprise RAG Systems
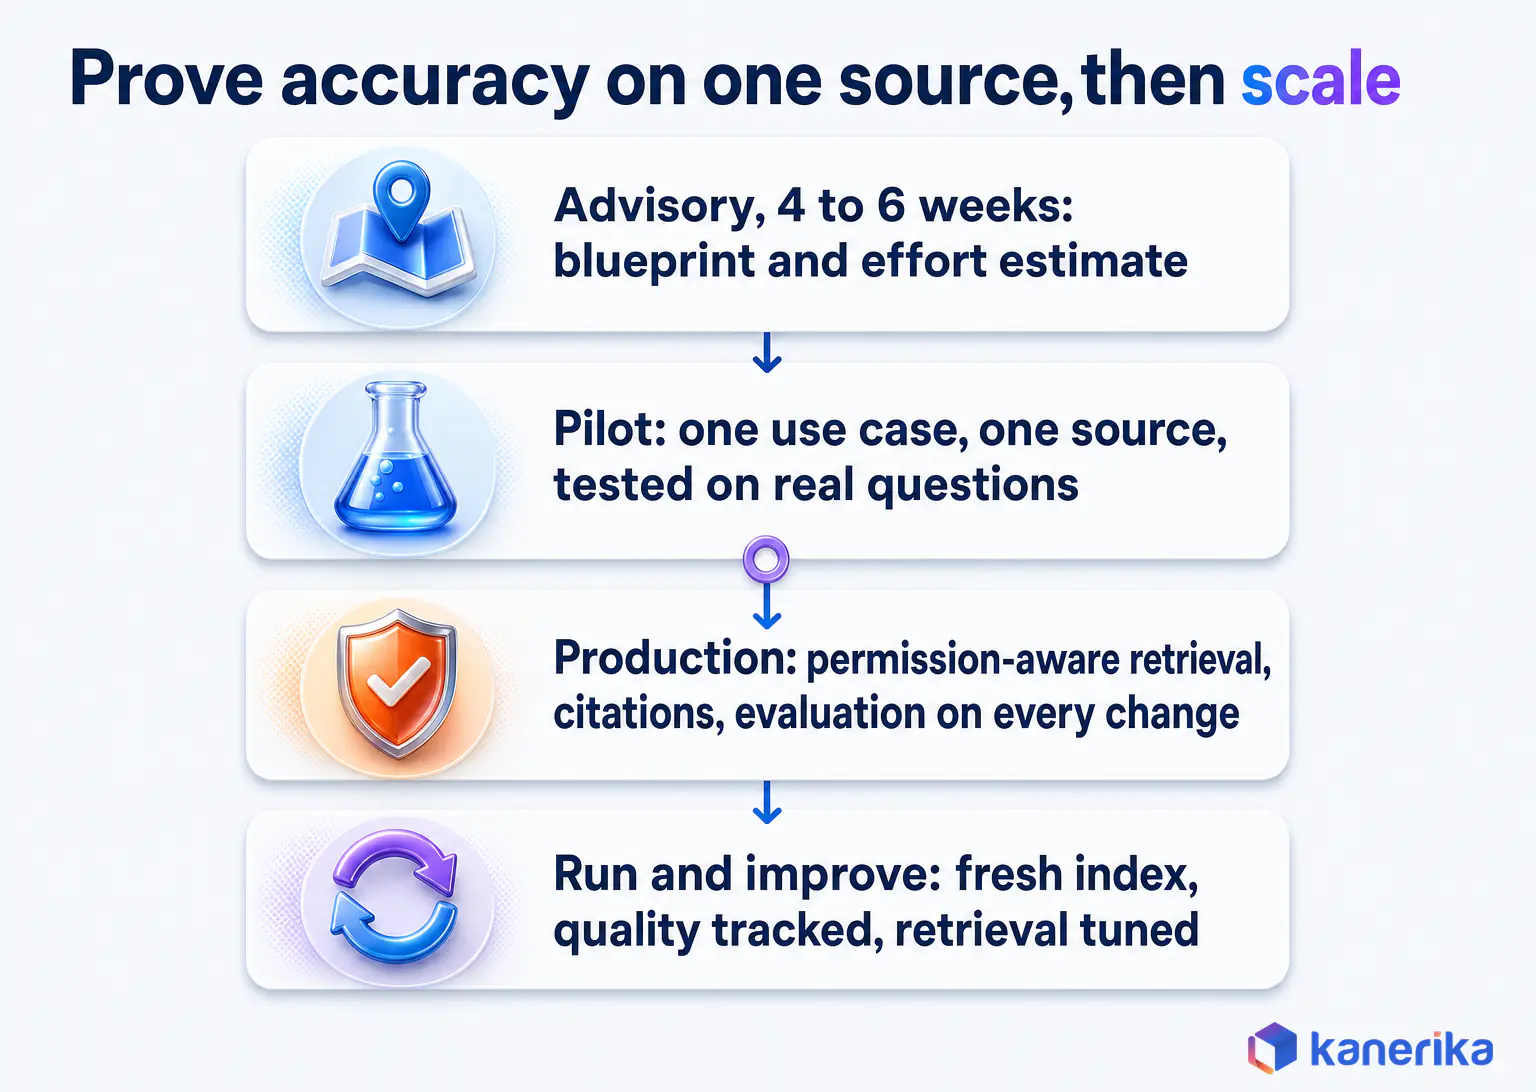
Kanerika builds RAG systems as a staged program, so accuracy is proven on a small scope before more sources are added. The engagement path is modeled on how we run our own agents, KlarityIQ for document intelligence and Karl for data insights.
- Advisory. A 4 to 6 week phase that produces a production blueprint and an effort estimate.
- Pilot. One use case and one priority data source, with accuracy tested on real questions.
- Production build. More sources with permission-aware retrieval, citations on every answer and evaluation checks on every change.
- Run and improve. Keep the index fresh, track answer quality over time and tune retrieval as usage grows.
Our RAG development services connect the systems where enterprise knowledge sits. That means SharePoint, file shares, PDFs and scanned documents, as well as Salesforce, ServiceNow and SAP through APIs. Each source keeps its own access rules in the index, so permission-aware retrieval holds as sources grow.
Data platforms such as Fabric, Synapse and SQL Server connect too, and answers can surface in Microsoft Teams. Retrieval runs on hybrid search plus reranking, tuned to each client’s real queries, while our LLM development team handles model choice and adaptation.
Each production build carries an evaluation set drawn from the client’s own questions. The set runs before every release, so a change to chunking, prompts or models cannot quietly lower answer quality.
Case Study: 65% Self-Service Resolution with an AI Support Agent
One example is a member support agent Kanerika delivered for a client’s service team. The agent was built to “instantly resolve 65% of member queries”, drawing answers from the client’s knowledge bases and Zendesk.
It auto-generated ticket summaries with suggested next steps, and it worked across chat and voice channels. When its confidence was low, it routed complex cases to live executives.
That routing rule is the production form of the evaluation thresholds in the Ragas section above. In any RAG system, the same idea means passing a question to a person when its confidence score falls below a set level. Read the full AI member support agent case study for the details.
Three habits carry across our RAG projects, whichever tools the stack uses:
- Test retrieval before generation. Check that the right passage reaches the model for each test question. If it never does, no prompt or model upgrade will fix the answer.
- Enforce permissions at retrieval. Access filters run inside the query, so restricted text never enters the prompt.
- Set a confidence threshold. Below it, the system hands off to a person instead of guessing, which is how the support agent above handled complex cases.
Those three checks decide whether a pilot survives contact with the full file estate. That is the same SharePoint moment this guide began with.
Talk to Kanerika
Book a RAG Pilot Scoping Call
Start with one use case and one data source. Kanerika scopes the pilot, the evaluation set and the path to production.
Talk to our RAG team →So which are the best RAG tools for enterprise AI applications? Pick one tool per missing layer, test it on your own questions, and then let security, retrieval quality and cost decide, in that order.
Frequently Asked Questions
What are RAG tools?
RAG tools are the software layers that let a language model answer from your own documents. They include orchestration frameworks such as LangChain, vector databases such as Qdrant, evaluators such as Ragas, and managed cloud services. Together they find relevant passages, pass them to the model and cite each source, so answers stay grounded and checkable.
What are the best RAG tools?
The strongest picks in 2026 are LangChain, LlamaIndex and Haystack for orchestration, Pinecone, Weaviate and Qdrant for vector storage, and Ragas for evaluation. Managed services such as Azure AI Search and Amazon Bedrock Knowledge Bases suit teams that want one bundle. Pick one tool per missing layer and test it on your own questions first.
What is the difference between RAG and LLM?
An LLM is the model that generates text. RAG is an architecture that feeds that model relevant passages from your own data before it answers. So RAG uses an LLM and adds a retrieval layer around it. The result is answers grounded in current, approved sources, with citations that users and auditors can check for themselves.
What are the types of RAG?
Common types include traditional RAG, hybrid RAG that mixes keyword and vector search, advanced RAG with reranking and query rewriting, knowledge graph RAG that retrieves linked entities, and agentic RAG that plans multi-step retrieval. Many production systems combine several types. Choose by question complexity, from simple lookups to multi-part research questions.
What is RAG used for?
Enterprises use RAG for internal knowledge search, domain expert assistants, research tools, learning platforms and compliance support. In each case, people ask questions in plain language and get answers drawn from approved documents, with citations. It suits any task where answers must reflect current, private information that a general model has never seen.
Is RAG still relevant?
Yes. Models such as Claude Sonnet 5.5 and Gemini 4 Argon accept up to 1M tokens, yet sending whole libraries in every prompt multiplies the cost per query. Long contexts also skip the permission checks that retrieval enforces. RAG keeps prompts small, current and access-controlled, so it remains the default for enterprise knowledge work.
What is a RAG example?
Picture an HR assistant that answers leave policy questions. An employee asks how many leave days carry over to next year. The system retrieves the current policy section for that employee’s region, passes it to the model and returns a short answer with a link to the policy page. Outdated policy versions stay filtered out.
Are RAG tools scalable for enterprise use?
Yes, with the right layer choices. Managed vector databases such as Pinecone and Qdrant Cloud scale storage and queries, and frameworks such as Haystack run as production pipelines. Scaling well also needs permission-aware retrieval, incremental re-indexing, evaluation on every change and cost tracking per query. Data quality causes most scaling problems.
Do I need a vector database for RAG?
Not always. Small corpora can run on Postgres or an existing search index. A dedicated vector database helps once you hold millions of chunks, need metadata filters at scale or want managed hybrid search. Storage is rarely the cost driver either, since 10 million chunks at 1,536 dimensions take only about 61 GB.
What does a reranker do in a RAG pipeline?
A reranker takes the top candidates from the first retrieval pass and reorders them by how well each one answers the question. It reads the question and passage together, so it judges relevance more precisely than vector similarity alone. Sending fewer, better chunks to the model improves answers and cuts token cost per query.
How much does it cost to run a RAG system?
Most of the bill is LLM tokens. In an illustrative model of 20,000 queries a day with 4,000 input and 400 output tokens each, Claude Sonnet 5.5 costs about $7,200 a month and Claude Haiku 5.5 about $360. Vector storage adds little, and the Pinecone Standard plan starts at a $50 monthly minimum.
How do you evaluate a RAG system?
Build a fixed set of real questions with expected answers, then score each run with Ragas metrics such as Context Precision, Context Recall, Faithfulness, Response Relevancy and Noise Sensitivity. Score retrieval and generation separately, since the fixes differ. Rerun the full set on every change to chunking, models or prompts before release.
Is RAG cheaper than fine-tuning?
For most knowledge tasks, yes. RAG needs no training run, and updating answers only means re-indexing documents. Fine-tuning adds training cost and repeats it whenever knowledge changes. It can still pay off for a fixed style or output format. Many teams combine both, using RAG for facts and a light fine-tune for tone and structure.
Which LLM is best for RAG?
It depends on volume and difficulty. Claude Haiku 5.5 and GPT-6 Luna cost $0.10 per million input tokens and suit high-volume lookups. Claude Sonnet 5.5 and GPT-6.1 Sol cost $2 per million input tokens and handle harder reasoning. Teams that must self-host can run gpt-oss-120b under Apache 2.0. Test two candidates on your own questions.
What is the difference between RAG and agent tools?
RAG tools retrieve passages and ground one answer in them. Agent tools plan multi-step tasks, call APIs and act on the results. The two often work together, since an agent can call a RAG retriever as one of its tools. LangChain with LangGraph covers both patterns, and agentic RAG adds query planning to the retrieval step.
What is the full form of RAG?
RAG stands for retrieval-augmented generation. The term describes a system that first retrieves relevant passages from a knowledge source and then generates an answer using them as context. The retrieval step grounds the model in your own data, and the generation step turns those passages into a readable, cited response for the user.
Is ChatGPT a RAG?
ChatGPT is a chat product built on large language models. It acts like a RAG system when it searches the web or reads files you upload and then answers from them. An enterprise RAG system goes further. It adds your own approved sources, permission checks at retrieval time and citations, all under your control and audit.
Can an LLM work without RAG?
Yes. An LLM can answer from its training data alone, which works for general questions. It cannot see your private documents, may be out of date and cannot cite sources. RAG adds those missing pieces by retrieving current, approved passages first. Use an LLM alone for drafting, and use RAG when answers must be accurate and traceable.
What is a traditional RAG?
Traditional RAG is the basic retrieve-then-generate loop. A question is embedded, the nearest chunks come back from a vector database, and the model answers from them in one pass. It has no query planning, no reranking and no multi-step retrieval. Advanced and agentic RAG add those steps to handle harder, multi-part questions well.
How do you use RAG with an LLM?
Index your documents first by parsing, chunking and embedding them into a vector database. At query time, retrieve the most relevant chunks, rerank them and place them in the prompt with an instruction to answer only from them. The LLM then writes a cited answer. A framework such as LangChain or LlamaIndex wires these steps together.