TL;DR
In generative AI vs predictive AI, pick predictive AI when a decision needs a score or forecast, and generative AI when the job is new content. Predictive AI learns from your labeled history and is checked against real outcomes with measures such as AUC or MAPE. Generative AI starts from a pretrained model, such as Claude Opus 5.5 or GPT-6.1 Sol, and is judged on groundedness and review. Model choice moves the bill more than the label does, since OpenAI list prices on November 2, 2026 ran from $0.10 to $10 per million input tokens. Time-series foundation models such as TimesFM 3.0 and Chronos-2 are pretrained like LLMs but return forecasts, so treat them as predictive AI. When one process needs both, let the predictive model decide and the generative model draft, with a person approving what reaches customers.
Key Takeaways
- Predictive AI estimates, so it returns a score, a class or a forecast learned from labeled history.
- Generative AI creates, so it returns new text, images or code from a pretrained foundation model.
- ChatGPT is generative AI, even though its models are trained to predict the next token.
- Predictive models are judged on error against real outcomes, while generative output is judged on groundedness and human review.
- Time-series foundation models blur the line in training, yet their output is a forecast, so they belong on the predictive side.
- Strong systems pair the two, so a predictive score triggers a generative draft that a person approves before it goes out.
One Insurance Claim, Two Kinds of AI
Picture a water-damage claim arriving at an insurer on a Monday morning. Before anyone opens the file, a fraud model scores it at 0.91, well above the line the team reviews by hand.
That score helps, but it is not enough for the adjuster. She still needs a plain summary of the photos, the policy terms and the repair estimate. She also needs a letter asking the customer for more evidence, written in a tone that will not start a complaint.
Both outputs then land on her screen within seconds of each other. They come from different models, though, built by different teams, trained on different data and checked in different ways. So treating them as one thing called “AI” is how projects end up with the wrong tool for half the job.
The score is predictive AI at work, and the summary and the letter are generative AI. The scene is illustrative, but the same split shows up in banking, retail and manufacturing. Our guide to AI in fraud detection covers the scoring half in depth.
Stanford’s 2026 AI Index reports that organizational AI adoption reached 88%. So for most teams the open question is no longer whether to use AI. It is which kind fits each task.
This guide compares generative AI vs predictive AI on the jobs they do, the data they need and how each is measured. It also covers what each costs to run. It then gives a decision framework, with six common scenarios and one pick for each.
What Is the Difference Between Generative AI and Predictive AI?
The difference is the job each one does. Predictive AI estimates something unknown, such as a probability, a category or a future value, from patterns in labeled history. Generative AI creates something new, such as text, an image or code, from patterns learned across very large amounts of content.
Both are branches of machine learning, so the line is not about smart versus simple. It is about the shape of the answer you need, and that shape decides almost everything that follows.
When the answer is a number you act on, the job is predictive. When the answer is content a person reads, the job is generative. For the wider family tree of these terms, see our explainer on machine learning vs AI.
A quick test helps when a project brief is vague. Ask what the system hands to the next person in the process. Then ask whether that person checks it against a later fact or reads it and acts.
What Is Generative AI?
Generative AI is a class of models that produce new content, such as text, images or code, in response to a prompt. For example, large language models write and summarize text, image models create pictures and code models draft software. Our comparison of diffusion models vs LLMs explains how the image and text families differ inside.
Many models now accept more than one input type. As of November 2026, Anthropic lists Claude Opus 5.5 as taking text and image input and returning text. So it can read a photo of a damaged roof and write the claim note. Our guide to multimodal AI applications explores where that helps.
Most of these language models build on the Transformer architecture, introduced in the 2017 paper Attention Is All You Need. In practice, a business rarely trains such a model itself. It starts from a pretrained foundation model and then shapes it with prompts, retrieved documents or fine-tuning.
The output is open-ended by design. Ask the same question twice and you may get two different but reasonable answers. That is useful for drafting and risky for anything that must be exact.
What Is Predictive AI?
Predictive AI uses historical data to estimate an outcome that is not yet known. Regression models predict a quantity, such as demand next week, while classification models assign a category, such as fraud or not fraud. Time-series models also forecast a value over a run of future dates.
Its output is narrow on purpose. A churn model returns a probability between 0 and 1 for each customer, and the same inputs give the same score every time.
That consistency is also what makes predictive AI easy to test, audit and run at scale. Our guide to AI predictive analytics covers the methods and tooling for this side in detail.
Is ChatGPT Generative or Predictive?
ChatGPT is generative AI. The confusion comes from the way its models are trained, because training is a prediction task. OpenAI’s 2023 GPT-4 Technical Report described GPT-4 as “a Transformer-based model pre-trained to predict the next token in a document.”
The product has moved on since that report. As of November 2026, the $20 ChatGPT Plus plan includes GPT-6.1 Sol and GPT-6 Luna, yet the principle is the same. Each word is a guess about what comes next, and the job the system does for you is still generation.
Next-token prediction is not business forecasting, even though both get called prediction. A language model predicts the next word of a sentence. A forecasting model predicts next month’s sales, and it can be scored when the month closes.
So the useful test is the output. A next-token predictor that writes a contract summary is doing generative work. A gradient-boosted model that scores the same contract for renewal risk is doing predictive work.
Kanerika Service
Predictive Analytics Services
Kanerika builds, validates and monitors predictive models for forecasting, risk scoring and churn, measured against a baseline and watched for drift after launch.
Explore Predictive AnalyticsWhat the Two Have in Common
The two families share more than the debate suggests. Each learns patterns from data, so each inherits that data’s gaps and biases. Accuracy also drifts as the world changes, which is why monitoring after launch applies to both.
The split itself also has roots in classic machine learning. Our guide to generative vs discriminative models explains that older distinction. Some models learn how data is produced, while others learn to separate classes.
Governance covers them together as well. For example, the NIST AI Risk Management Framework, released on January 26, 2023, applies to AI systems of either kind. On July 26, 2024, NIST added a Generative AI Profile, NIST AI 600-1, for risks specific to generative systems.
A bank that already validates credit models therefore has a head start on generative AI, since its testing and documenting habits carry over. People are the last shared dependency, because a model of either kind changes nothing until someone owns the decision it feeds.
Generative AI vs Predictive AI: Side-by-Side Comparison
A side-by-side view makes the split concrete. The rows below cover what each one is for, how it is built, what it costs per call and how it fails.
The goal row explains most of the others, because a model built to estimate is judged, owned and run differently from one built to create. Read the failure row twice, since it shapes the controls you need.
| Dimension | Predictive AI | Generative AI |
|---|---|---|
| Objective | Estimate an unknown value or class | Create new content |
| Output | Score, class or forecast | Text, images, audio or code |
| Training data | Your labeled, mostly structured history | Large unstructured corpora, plus your documents at run time |
| Typical models | Regression, gradient-boosted trees, time-series models | Large language models, diffusion models |
| Metrics | Error against real outcomes (AUC, MAPE) | Groundedness, task success, rubric scores, human review |
| Explainability | Feature importance per prediction (SHAP) | Source citations and logs; internal reasoning is hard to inspect |
| Cost per call | Very low; cheap batch or real-time scoring | Higher, and it grows with the number of tokens |
| Latency | Milliseconds per score | Seconds, longer for long outputs |
| Typical failure | A wrong score that looks plausible, often from drift | Confident false text, or leaked content |
| Governance focus | Model validation, bias in labels, drift monitoring | Grounding, access control, content review |
Two rows explain most project trouble. Predictive projects tend to fail quietly, because drift wears down accuracy month by month and nobody sees a single dramatic error.
Generative projects instead tend to fail loudly, with one confident wrong answer in front of a customer. Neither failure is a reason to avoid the technology, but each calls for a different control, and the next sections cover those controls in turn.
How Generative AI and Predictive AI Work
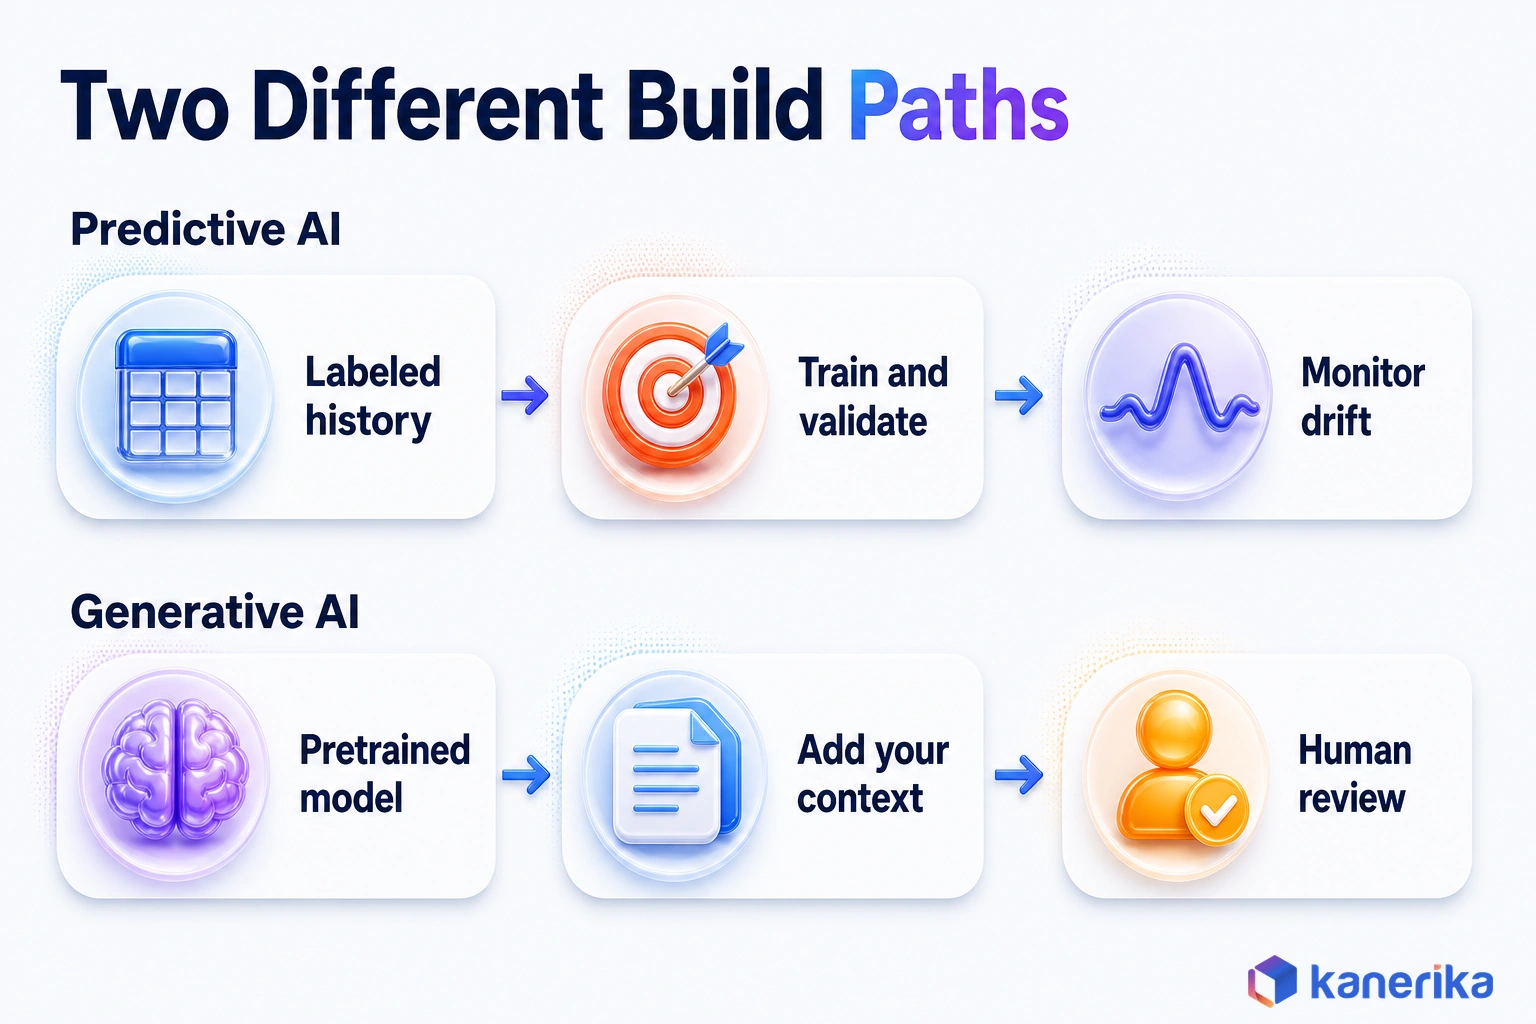
Under the hood, the two follow different build paths. A predictive model is trained on your own data from the start. A generative system usually starts with someone else’s model and then adds your data around it.
That difference shapes the project plan. A predictive project spends most of its effort on data and features. A generative project instead spends most of its effort on context, guardrails and review.
Inside a Predictive Model
A typical predictive build moves through six steps. Each one depends on the step before it, so a weak label set in step one shows up as poor accuracy in step four.
- Collect labeled history: for example, past claims marked fraud or not fraud, or past weeks of sales by store.
- Engineer features: turn raw records into signals such as claim amount, policy age or a promotion flag.
- Train and validate: fit candidate models, then test them on data they have not seen.
- Compare to a baseline: beat a simple rule or the prior year’s average before going further.
- Deploy and score: run the model in batch overnight, or in real time when an application needs an answer.
- Watch for drift and retrain: track accuracy as behavior changes, then retrain on fresh labels.
Monitoring and retraining are where many teams underinvest, because the work starts after the launch. Our roundup of MLOps tools covers the platforms that automate that loop, such as drift alerts and scheduled retraining.
Inside a Generative AI System
A generative system is assembled more than trained. The steps below describe a common enterprise pattern, using a document assistant that answers staff questions as the example.
- Pick a foundation model: choose by quality, cost and latency, and by where the data may be processed.
- Write the prompt: set the role and the task, then the output format and the rules.
- Add your context: retrieve approved documents when a request arrives (RAG), or fine-tune on worked examples.
- Add guardrails: filter inputs and outputs for sensitive data, policy breaches and prompt injection.
- Keep a person in the loop: route drafts for approval when they touch customers, money or records.
- Log and evaluate: score outputs against a fixed test set, then track failure patterns.
Step three has its own trade-offs, which our comparison of RAG vs fine-tuning sets out. For most business documents, retrieval comes first because it keeps answers tied to sources you can cite.
The wording of the prompt matters less than the material placed around it. A well-phrased prompt over stale documents still gives stale answers, so the content pipeline deserves as much care as the model.
Checklist
Generative AI Checklist
Work through model choice, grounding, guardrails, review and evaluation before a generative AI system goes live.
Get the Checklist →Time-Series Foundation Models Blur the Line
A newer family sits between the two camps. Time-series foundation models are pretrained on very large collections of time series, much as LLMs are pretrained on text. They then forecast series they have never seen.
Two open examples lead the field. Google released TimesFM 3.0 in August 2026 with native multivariate forecasting and support for past and future covariates. Amazon released Chronos-2 on October 20, 2025, with zero-shot univariate, multivariate and covariate-informed forecasting.
The training looks generative, but the output is a forecast with an error you can measure. So in the decision framework below, treat these models as predictive AI. Our guide to AI forecasting covers how they fit beside classic methods.
| Model | Released | What it forecasts | License and commercial route |
|---|---|---|---|
| TimesFM 3.0 (Google) | August 2026 | Univariate and multivariate series, with past and future covariates | Downloadable weights under a non-commercial license; commercial use through Google Cloud services such as BigQuery ML (rollout completed September 2026) |
| Chronos-2 (Amazon) | October 20, 2025 | Univariate, multivariate and covariate-informed series, zero-shot | Apache-2.0 repository; deploys through SageMaker JumpStart |
Read the license column before a pilot. The TimesFM 3.0 model card lists a non-commercial license for the weights. So a team that downloads them for a production forecast is on the wrong side of it. For commercial use, the route is Google Cloud services such as BigQuery ML.
What Data Each One Needs
Data is where most of the practical difference shows up. Predictive AI needs your own labeled history, while generative AI needs well-organized content and strict rules about who may see it.
A churn model, for example, needs enough past customers whose outcome is known. If nobody recorded which customers left and when, there is nothing to learn from, and no algorithm can invent the missing labels.
A policy assistant, on the other hand, needs current documents that are tagged and permissioned. That way it never quotes a retired version, and it never shows an HR file to the wrong person.
Readiness matters on both sides, and it starts with data governance. Gartner predicted in February 2025 that through 2026, organizations will abandon 60% of AI projects unsupported by AI-ready data. The same research also found that 63% of organizations lack, or are unsure they have, the right data management practices for AI.
| Data need | Predictive AI | Generative AI |
|---|---|---|
| Main source | Structured records with known outcomes | Documents, emails, tickets and images |
| Labels | Required for supervised models | Not required to start; examples help testing and fine-tuning |
| Volume | Enough history to cover seasons and rare events | A curated set of your own content on top of the pretrained model |
| Freshness | Retrain as patterns shift | Re-index documents when they change |
| Access control | Mostly at the data warehouse layer | Per document, enforced at retrieval time |
| Biggest risk | Missing or biased labels | Stale, duplicated or over-shared content |
Time-series foundation models do change one row of this table, the volume row. Because they forecast zero-shot, a team with only a short sales history can get a first forecast sooner. It still needs actual outcomes to judge that forecast.
A Five-Point Data Readiness Check
Before either kind of project starts, five checks tell you whether the data can carry it. Run them in a single working session while the business owner is in the room.
- An owner can name the decision or task the model will change.
- The outcome or content sits in one place, with a known history.
- Sensitive fields are classified, and access rules are written down before any build.
- Someone has measured the baseline, such as error rate or handling time.
- A review step exists for when outputs touch customers, money or records.
When any of the five checks fails, fix the data first. No model choice makes up for weak data, and a failed check found in week one costs far less than one found after launch.
AI Assessment
Is Your Data Ready for Predictive or Generative AI?
The AI Maturity Assessment scores your data, governance and skills, so you can see which kind of AI project your organization can carry first.
Start Your AI Assessment →How to Measure Accuracy and Explainability
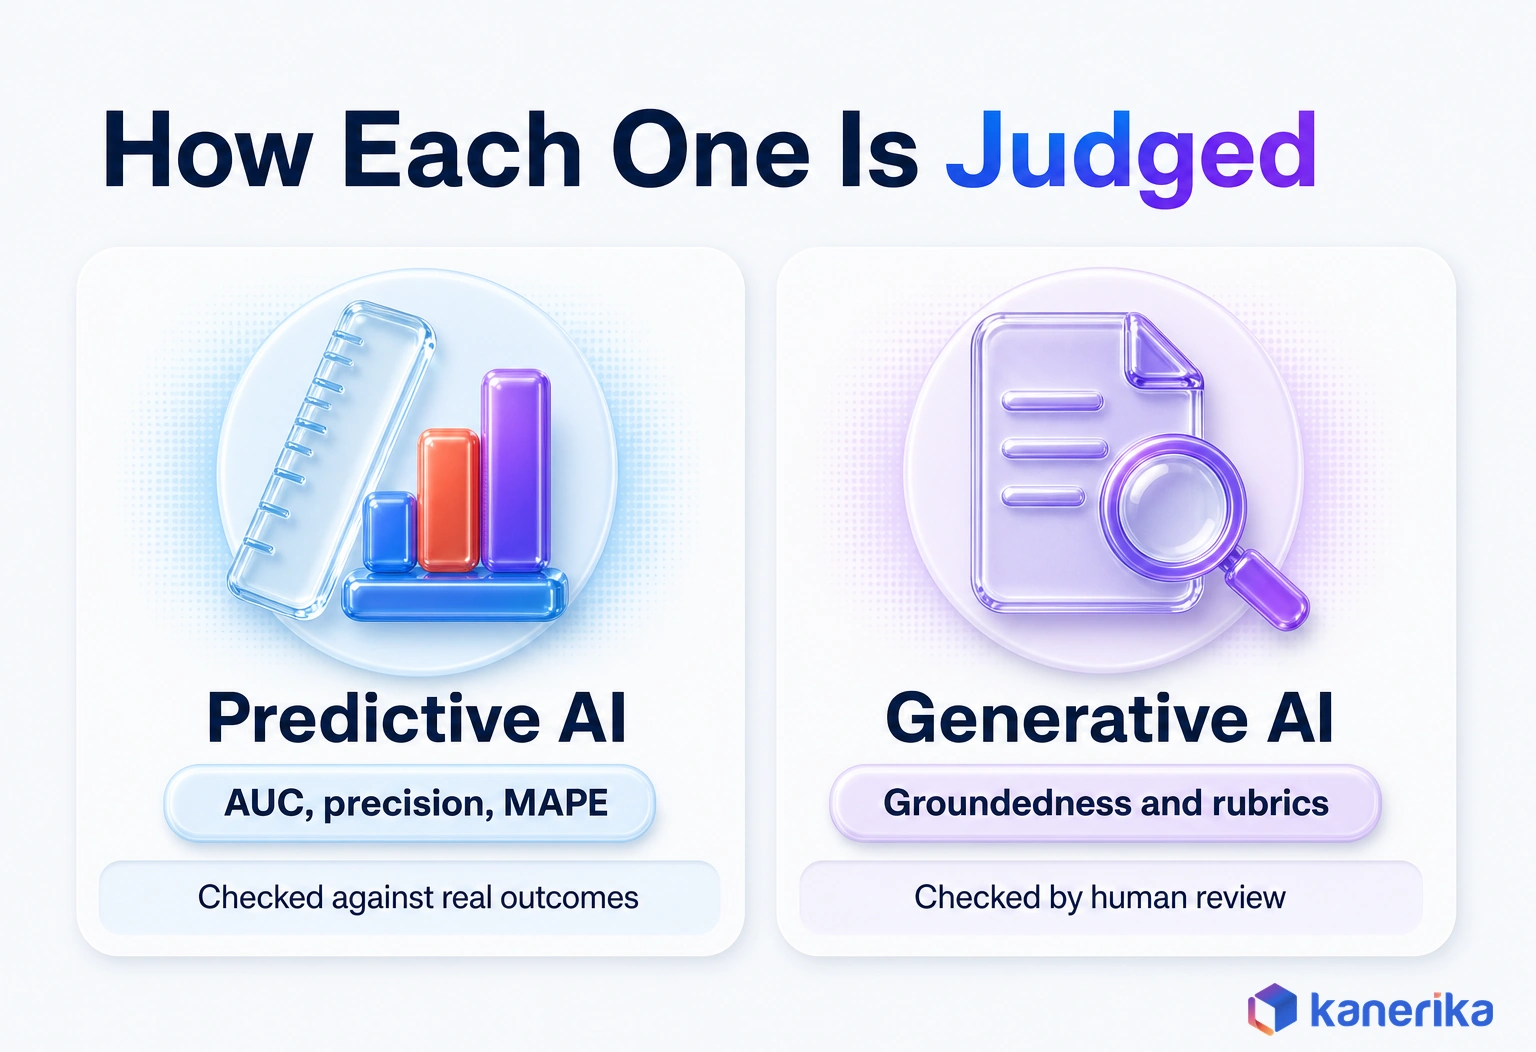
Measurement is where the two diverge most sharply. A predictive model has a right answer to compare against. A generative answer usually has many acceptable versions, so it needs a different kind of test, such as an LLM evaluation framework.
Take a demand forecast. After the month closes you know actual sales, so you can compute the error and compare it with the previous model.
A drafted claim letter, however, has no single correct version. You judge it on whether its facts match the file, whether it follows policy and whether an adjuster would send it as written.
Forecasts need one more check that teams often skip. A point forecast without a prediction interval hides risk, because a buyer cannot tell a confident 1,000 units from a shaky one. Calibration tests whether the stated ranges hold, so an 80% interval should contain the actual value about 80% of the time.
Explaining a Score vs Explaining a Draft
Explainability splits the same way. For predictive models, SHAP assigns each feature an importance value for a particular prediction. A reviewer can then see that claim age and repair cost drove a high fraud score.
Generative systems, though, are harder to explain from the inside. So the practical substitute is to make them cite their sources and to log every prompt and response. Our guide to explainable AI covers both approaches in more depth.
| Check | Predictive AI | Generative AI |
|---|---|---|
| Core accuracy measure | AUC, precision and recall for classes; MAPE for forecasts | Groundedness and factual accuracy against sources |
| Uncertainty | Prediction intervals and calibration | Abstain or flag when sources do not support an answer |
| How it is tested | Backtests on held-out history | Rubric scoring on a fixed set of test prompts |
| Explainability | SHAP or similar feature attributions | Citations to retrieved sources, plus prompt logs |
| Who reviews | Model validators and analysts | Subject experts and end users |
| When to recheck | On a schedule and when drift alerts fire | Whenever the model, prompt or source content changes |
For a predictive classifier, AUC takes a few lines to compute. This example from the scikit-learn documentation fits a model to a built-in dataset and scores it.
>>> from sklearn.datasets import load_breast_cancer
>>> from sklearn.linear_model import LogisticRegression
>>> from sklearn.metrics import roc_auc_score
>>> X, y = load_breast_cancer(return_X_y=True)
>>> clf = LogisticRegression(solver="newton-cholesky", random_state=0).fit(X, y)
>>> roc_auc_score(y, clf.predict_proba(X)[:, 1])
0.99
A generative draft has no single number like this, which is why its tests rest on rubrics and reviewers. One rule holds for both, so set the bar before launch.
For instance, a fraud model that must beat the current rules engine gives the project a finish line. So does an assistant that must match an expert’s answers on a fixed list of test questions.
Generative AI vs Predictive AI Use Cases by Industry
Most industries use both kinds of AI, often on the same process. For six sectors, the table maps one predictive job, one generative job and one combined workflow.
| Industry | Predictive job | Generative job | Combined workflow |
|---|---|---|---|
| Banking | Credit default and fraud scores | Credit memos and customer letters | A fraud alert arrives with a plain summary for the investigator |
| Insurance | Claim fraud and severity scores | Claim summaries and correspondence | A high-risk score routes the claim with a drafted evidence request |
| Retail | Demand and markdown forecasts | Product descriptions and campaign copy | A demand spike triggers drafted reorder notes and promotion copy |
| Manufacturing | Failure prediction from sensor data | Maintenance answers from manuals | A failure alert comes with a drafted work order and the manual page |
| Healthcare | Readmission and no-show risk | Draft visit notes and discharge instructions | A high-risk patient gets a drafted follow-up plan for clinician sign-off |
| Logistics | Arrival time and delay prediction | Customer delay notices | A predicted delay triggers a drafted notice before the customer asks |
The pattern repeats across rows. The predictive model finds where attention is needed, and the generative model turns that finding into something a person can read or send.
Banking and insurance lean hardest on the predictive column, as our guide to AI in risk management explains. For a longer catalog of the content side, see our list of generative AI use cases.
Where the Two Meet in Retail
Retail shows how tightly the two can be linked. A demand forecast tells a buyer how many units to order before the season starts. Generative AI can then read the reviews and social posts that hint at why demand is moving.
The buyer gets both in one view, so the order size and the reason behind it arrive together. Our guide to AI in demand forecasting walks through the predictive half of that setup.
The split also keeps each model honest. The forecast is scored against actual sales, and the text analysis is checked by a merchandiser who knows whether the trend it found is real.
Case Study
37% Lower Inventory Holding Costs With AI Demand Forecasting
A luxury fashion house paired ML demand models with FLIP analysis of reviews and media coverage, cutting inventory holding costs by 37% and launch stockouts by 22%.
Read the Case Study →Benefits, Limitations and Risks of Each
Each technology is strong where the other is weak, so the comparison is rarely a contest. The two lists below set strengths and limits side by side, and after them come the frameworks that govern both.
Generative AI: Strengths and Limits
Generative AI shines on unstructured work. It can read a 40-page contract, draft a reply in a customer’s language or turn a spreadsheet into a short narrative. A task that once took an analyst an afternoon becomes a review of a draft.
The gain is speed on the first draft rather than judgment. A person still decides whether the draft is right, so the time saved depends on how often drafts need heavy edits. Track that edit rate from the first week, because it is the most honest measure of value.
Its limits come from the same open-endedness:
- Hallucination: fluent answers that no source supports, a failure our guide to AI hallucinations explains.
- Intellectual property: open questions about training data and about generated output.
- Data leakage: prompts or retrieved documents that expose confidential content when access rules are loose.
- Variable output: answers that change between runs, so regression testing gets harder.
Even so, most of these risks can be managed with grounding, access controls and review. None of them is solved by picking a bigger model, because each one is a property of how the system is wired.
Kanerika Service
Generative AI Consulting
Kanerika designs generative AI systems grounded in governed content, with guardrails, evaluation on a fixed question set and human approval where output reaches customers.
Explore Generative AI ServicesPredictive AI: Strengths and Limits
Predictive AI is measurable and repeatable. A card issuer can score every transaction in milliseconds and report each month exactly how many fraud cases the model caught and missed.
It also runs cheaply on millions of records, its accuracy can be stated as a number and validation teams already know how to test it. Its limits sit mostly in the data:
- Label hunger: it needs labeled history, so new products and rare events are hard to model.
- Drift: accuracy decays when customer behavior, prices or supply chains change.
- Bias at scale: biased labels produce biased scores on every record, since the model repeats what it learned.
- No next step: a score alone does not tell a person what to do, so someone still has to decide.
That last limit is where generative AI often comes in, as the section on using both together shows.
Governance Frameworks That Apply to Both
The same frameworks cover both kinds of AI, although some rules aim squarely at generative systems. The table lists four that most programs reference.
| Framework | What it covers | Date |
|---|---|---|
| NIST AI Risk Management Framework | Voluntary framework for managing AI risk across the lifecycle | Released January 26, 2023 |
| NIST AI 600-1 (Generative AI Profile) | Risks unique to, or made worse by, generative AI | Released July 26, 2024 |
| EU AI Act | Risk-based rules, plus transparency duties for generative AI | In force August 1, 2024; generally applicable August 2, 2026 |
| ISO/IEC 42001 | Standard for an AI management system | Published in 2023 |
The EU dates deserve care. Prohibitions and AI literacy duties have applied since February 2, 2025, and duties for general-purpose AI models since August 2, 2025.
The high-risk rules moved later. Under the AI Omnibus agreement, the EU page lists the Annex III high-risk rules as extended to December 2, 2027. The Annex I rules then move to August 2, 2028. To turn these rules into an internal program, see our AI governance framework guide.
In practice, a credit score and a customer chatbot can both fall under these rules. So the inventory should list every model by the decision it touches, not by whether it is predictive or generative.
Checklist
AI Governance Checklist
Map your models to NIST AI RMF and EU AI Act duties, assign owners and set review points for predictive and generative systems alike.
Get the Checklist →Cost, Compute and Latency Trade-offs
Cost follows the shape of the model. A predictive model is small and cheap to run, so scoring millions of rows overnight costs little. A large language model does far more work per request.
Latency shapes the design too. A fraud score must return before a card payment completes, which rules out slow calls in that path. A claim summary can take several seconds, because the adjuster opens it minutes later.
What Moves the Bill
Inside generative AI, the spread between models is wider than most budgets assume. The table shows list prices per million tokens as published on November 2, 2026.
| Model | Input per 1M tokens | Output per 1M tokens | Note |
|---|---|---|---|
| GPT-6 Luna (OpenAI) | $0.10 | $0.50 | Low-cost tier for high-volume tasks |
| Claude Haiku 5.5 (Anthropic) | $0.10 | $0.50 | Price applies up to a 100k-token prompt |
| GPT-6.1 Sol (OpenAI) | $2 | $10 | General-purpose model in ChatGPT Plus |
| Gemini 4 Argon (Google) | $2 | $10 | Through November 30, 2026; $4 and $20 from December 1, 2026 |
| Claude Opus 5.5 (Anthropic) | $4 | $20 | Text and image in, text out |
| GPT-6 Astra (OpenAI) | $10 | $50 | Top of OpenAI’s list |
Look at one vendor’s list alone. GPT-6 Astra costs 100 times as much as GPT-6 Luna per input token. So the model you pick moves the bill more than the generative or predictive label does.
Beyond the Token Price
A list price is not the total cost, though. Retrieval, human review, logging and monitoring all add to it, and on a busy assistant they can outweigh the token bill.
| Factor | Predictive AI | Generative AI |
|---|---|---|
| Cost per prediction or call | Very low | Higher, and it grows with text length (tokens) |
| Latency | Milliseconds to seconds | Seconds, longer for long outputs |
| Hardware | CPUs are often enough | GPUs or hosted model APIs |
| Scaling pattern | Batch scoring of whole tables | Per-request calls, often user-facing |
| Main cost lever | Feature and retraining efficiency | Model choice, prompt length and caching |
Design choices move the bill as well. A smaller model for routine requests, cached answers for repeated questions and batch runs for overnight jobs all lower it. Small language models are one option for narrow, high-volume tasks.
Volume still matters at any price. A support assistant that handles every ticket will cost more than a model that scores the same tickets for urgency. For the full business case, our guide to the ROI of generative AI shows how to weigh these costs against the time saved.
Using Generative AI and Predictive AI Together
The most useful systems do not pick one side for a whole process. They give each step to the kind of AI that fits it, and four patterns cover most designs.
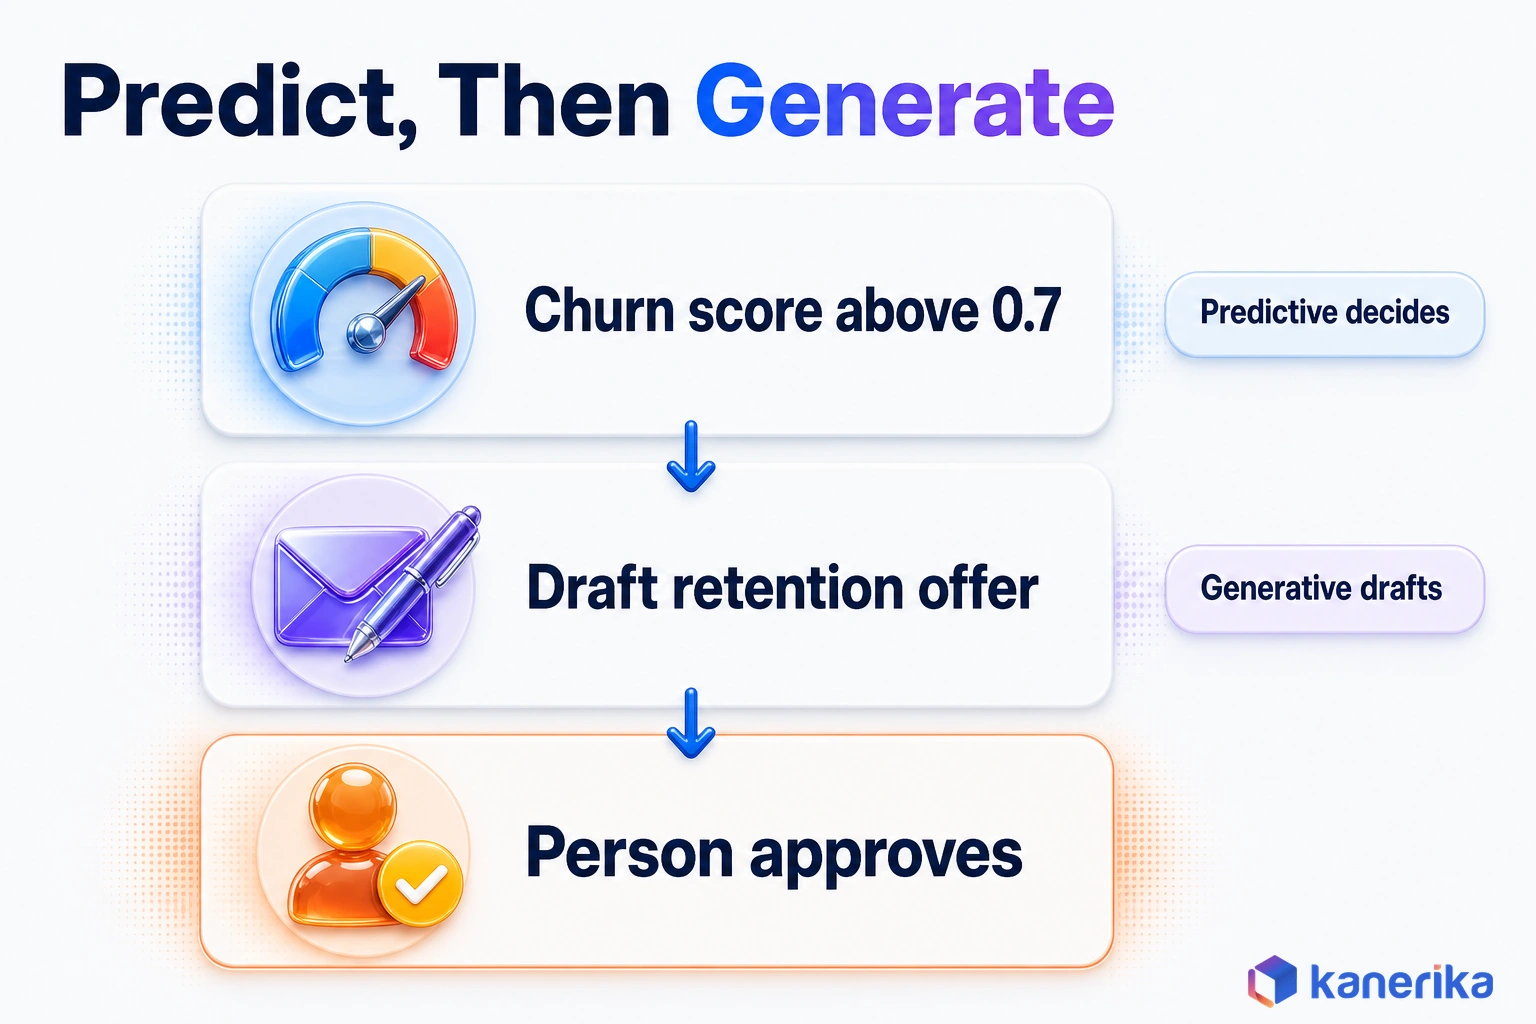
- Predict, then generate: a predictive score decides which cases need action, and a generative model drafts the action.
- Generate, then predict: a language model extracts fields from emails or notes, and those fields feed a predictive model.
- Explain the forecast: a generative assistant answers questions about model outputs, such as why a forecast changed.
- Let an agent route: an AI agent calls a forecasting model as one tool and a drafting model as another, within set limits.
The second pattern is easy to overlook. In insurance and customer support, many telling signals sit in free text, such as an adjuster’s notes or a complaint email. A language model can turn that text into fields a fraud or churn model can use.
Agents now chain the two in one flow. A score crosses a threshold, an agent drafts the follow-up and routes it to the right owner, and a person approves it. The agent is a language model choosing which tool to call. Our comparison of agentic AI vs generative AI explains how its limits are set.
A Worked Example: Churn Score to Retention Offer
This example is illustrative, with numbers chosen to show the pattern. Take a subscription business with a churn model that scores every customer each night, and say the team sets an alert threshold at 0.7.
- Score: the churn model rates every customer overnight, and those above 0.7 go to the retention desk.
- Draft: a generative model reads the account history and recent tickets, then drafts an offer that names the real issue, such as repeated billing errors.
- Approve: a retention specialist edits or approves the draft before it is sent.
- Learn: whether the customer stayed becomes a new label, and the specialist’s edits become test cases for the drafting prompt.
Each side improves the other over time. The churn model gets fresher labels, and the drafting prompt gets a growing set of real corrections to test against.
Teams that run predictive maintenance use the same loop on equipment. A model predicts that a pump is likely to fail, then an agent drafts the work order with the right manual pages attached.
The video below walks through that shift from predictive to agentic maintenance on a digital twin. It shows the same score-then-act loop running on plant equipment instead of customer accounts.
How to Choose: A Decision Framework
Choosing well starts with the task the AI must do. Five questions, asked in order, settle most cases.
The order matters because the early questions rule options out. When you need a forecast but have no outcome history, no tuning will close that gap. When you need a customer letter, even a very accurate forecasting model cannot write it.
- What output do you need? A number or a category points to predictive AI, while text, images or code point to generative AI.
- Do you have labeled history? Predictive AI needs past outcomes. Until you have them, collect labels, test a time-series foundation model for forecasts, or use generative AI for tasks that need none.
- How much error can the decision absorb? Lending and pricing need measured, stable accuracy, while a first-draft email can tolerate a human edit.
- Must you explain each result? Regulators and customers may ask why. Feature attributions explain scores, while citations explain drafts.
- What volume and speed do you need? Millions of nightly scores favor predictive models, whereas fewer, longer interactions suit generative ones.
Once you answer all five, a clear pick usually emerges for each step of a process. A claims workflow ends up with a predictive score at intake and a generative summary at review.
Six Scenarios, One Pick Each
The table applies the same five questions to six common scenarios. Each row names one winner, or the order in which the two run when both are needed.
| Scenario | Pick | Why |
|---|---|---|
| Forecast next quarter’s demand by store | Predictive AI | Numeric output, years of labeled sales; a time-series foundation model is still predictive here |
| Flag likely fraud on card transactions | Predictive AI | High volume, fast scoring, measurable error |
| Summarize long contracts for a legal team | Generative AI | Unstructured input, readable output |
| Answer staff questions from policy documents | Generative AI | Language task grounded in approved sources |
| Contact customers likely to churn | Predictive AI for the score, then generative AI for the message | The score picks who; the draft says what |
| Explain why a forecast moved | Predictive AI for the forecast, then generative AI for the explanation | Feature drivers become a plain summary |
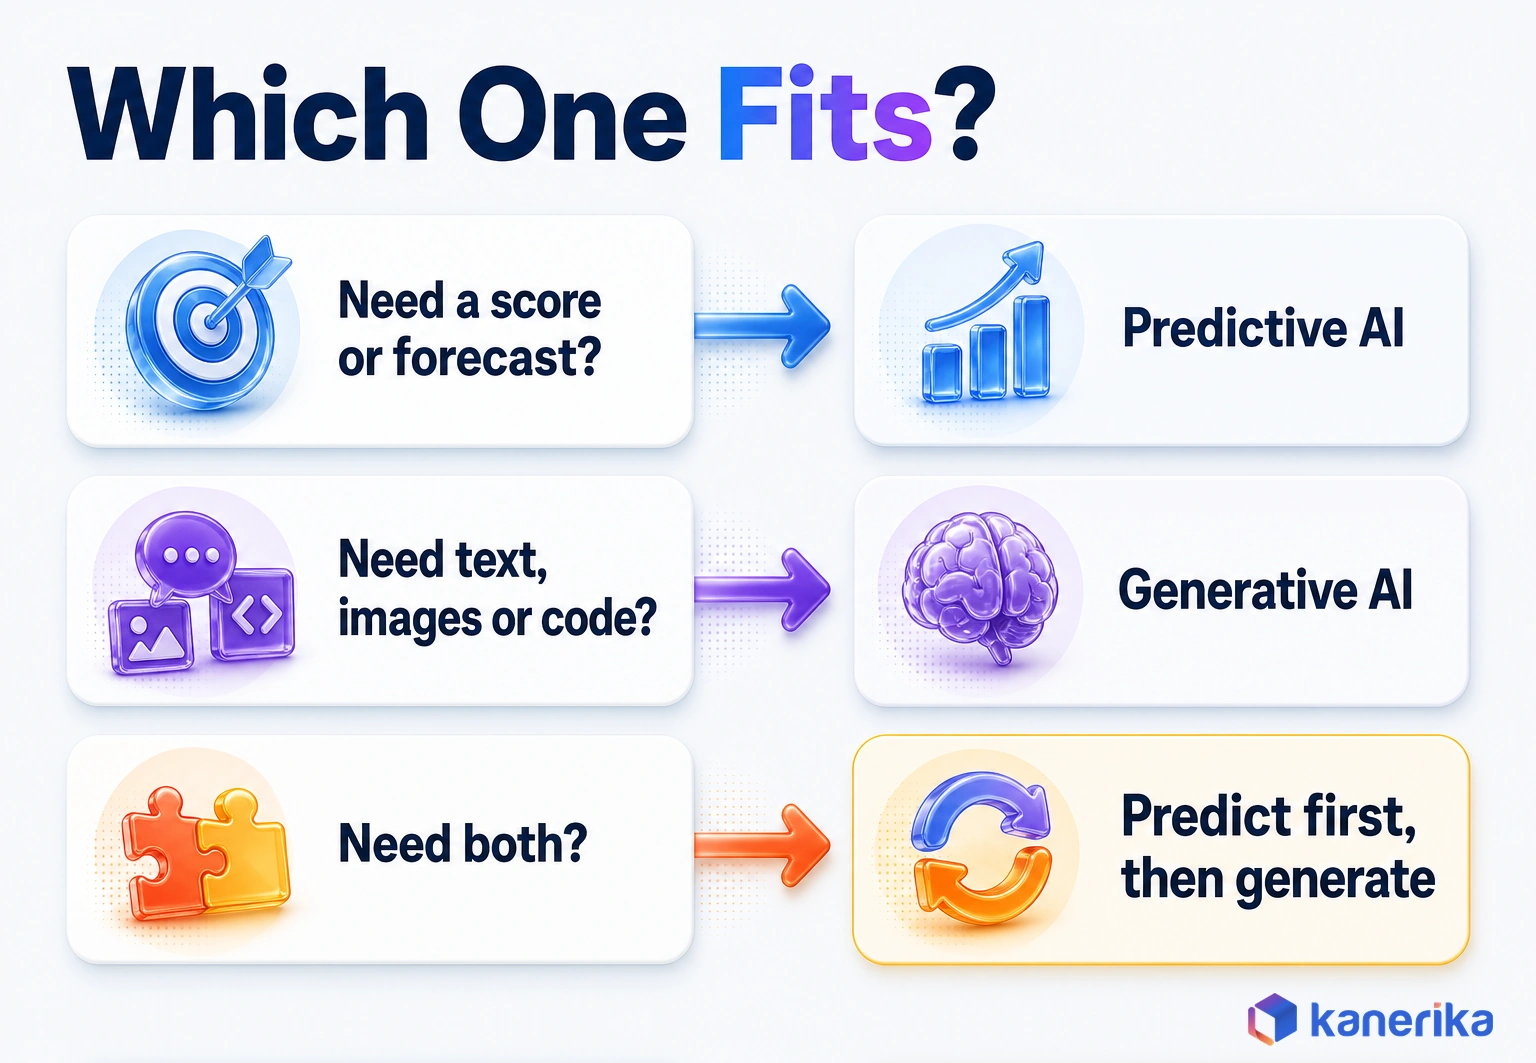
When a row names both, the order matters. The predictive model makes the call, then the generative model communicates or acts on it.
Common Mistakes When Choosing
The same five mistakes come up again and again in early AI programs. Each one is cheap to avoid at the planning stage and expensive after launch.
- Using generative AI for a forecasting job. A language model can write about demand, but a trained forecasting model predicts it with measurable error.
- Skipping the baseline. Without the existing error rate or handling time, nobody can show that the model helped.
- Ignoring data readiness. Missing labels or unpermissioned documents stall a project, whatever model it uses.
- Launching without an evaluation plan. Decide the measure, the test set and the pass mark before the first demo.
- Leaving drift without an owner. Someone must watch accuracy and answer quality after launch, with budget to retrain or re-index.
Most of these are planning gaps rather than technical ones. They cost little to fix before a build starts and a great deal to fix after it.
Tools and Platforms for Each
The tool market is crowded, so it helps to think in categories first. Each category serves one side of the split, although a few serve both.
| Category | Serves | What it does |
|---|---|---|
| AutoML and ML platforms | Predictive | Train, compare and deploy models on tabular data |
| Forecasting libraries and time-series foundation models | Predictive | Forecast series with seasonality, holidays and covariates |
| MLOps and model monitoring | Predictive, and more and more both | Versioning, drift alerts and retraining |
| LLM APIs and model hubs | Generative | Hosted foundation models for text, images and code |
| RAG and orchestration frameworks | Generative | Retrieval, prompt chains and tool calls |
| AI governance tools | Both | Model inventories, risk reviews and audit trails |
Named examples make the categories concrete. The list below reflects what was available as of November 2026, and the prices sit in the cost section above.
| Side | Named examples (November 2026) | Typical use |
|---|---|---|
| Predictive, tabular | XGBoost | Gradient-boosted scores for fraud, churn and credit |
| Predictive, forecasting | TimesFM 3.0 through BigQuery ML; Chronos-2 through SageMaker JumpStart | Zero-shot or covariate-informed demand forecasts |
| Generative, general | GPT-6.1 Sol, Claude Opus 5.5, Gemini 4 Argon | Drafting, summarizing, reasoning over documents |
| Generative, high volume | Claude Haiku 5.5, GPT-6 Luna | Narrow tasks such as tagging, extraction and routing |
For more named products on the generative side, see our list of generative AI tools. On the predictive side, the deciding factor is usually the data platform you already run, since models are best trained where the data lives.
Most enterprises already own part of this stack. Cloud data platforms often bundle model training, model serving and access to hosted language models, so the first question is what your platform already covers. A separate tool makes sense when the gap is clear, such as drift monitoring or prompt evaluation.
How Kanerika Builds Predictive and Generative AI Together
Kanerika runs predictive analytics services and generative AI consulting side by side, and many engagements end up using both on one process. Our working rule is to start with the decision the output feeds, not with the model type.
Delivery follows four stages, so that each model has a job, a measure and an owner before it goes live:
- Data foundation: build the data layer and run a readiness check, because neither a forecast nor an assistant is better than the data under it.
- Model type per step: give each workflow step the type that fits it, with scores and forecasts on the predictive side and reading and drafting on the generative side.
- Measure and control: test predictive models against a baseline and monitor them for drift, while generative parts are grounded in governed content, tested on a fixed question set and routed for approval.
- Wire and own: connect the two so a score triggers the generative step, and name an owner for each.
A project for an iconic luxury fashion house shows the pattern. The brand needed sharper demand forecasts for its seasonal and capsule collections, so Kanerika built machine learning demand models over sales, influencer-trend and macroeconomic data.
On the unstructured side, FLIP processed customer reviews, media coverage and fashion blogs. The Karl insights agent ran what-if forecasts for planners. The demand forecasting case study reports these results:
- 37% reduction in inventory holding costs
- 22% lower stockouts during launches
- 87% improvement in forecast accuracy
The predictive models produced the forecast, and the text analysis added the consumer context around it. The same approach carries over to claims volume, equipment failure or customer churn. In each case a forecast is worth most when the people acting on it also get a plain explanation and a drafted next step.
Talk to Kanerika
Planning a Predictive and Generative AI Roadmap?
Talk to Kanerika about which steps of your process need a score, which need a draft, and how to wire the two with an owner for each.
Talk to an Expert →Generative AI vs Predictive AI: The Bottom Line
Pick predictive AI when the job is to estimate a number or a category and you have labeled history to learn from. Pick generative AI when the job is to read, write or summarize content for a person.
Time-series foundation models stay on the predictive side, because their output is a forecast you can score. Agents sit on the generative side, because they are language models choosing which tool to call.
When a process needs both, let the predictive model decide and the generative model draft, with a person approving anything that reaches a customer. Model choice inside each side moves cost more than the label, so price the model you will run, not the category. In the end, generative AI vs predictive AI comes down to one question: do you need a number, or new content?
Frequently Asked Questions
What is the difference between generative AI and predictive AI?
Generative AI creates new content such as text, images or code from patterns learned across large datasets. Predictive AI estimates an unknown value, such as a fraud score, a churn probability or next month’s demand, from labeled history. Choose by the output you need. A number points to predictive AI, and new content points to generative AI.
Is ChatGPT generative AI or predictive AI?
ChatGPT is generative AI. Its models are trained to predict the next token, and OpenAI’s GPT-4 Technical Report describes GPT-4 in exactly those terms. Each predicted word builds new text, code or a summary that did not exist before. So the training method looks predictive, while the job the system does for its users is generative.
What is predictive AI, and is it a type of machine learning?
Predictive AI is a use of machine learning that estimates unknown outcomes from historical data. Regression predicts quantities, classification assigns categories and time-series models forecast values over time. It needs labeled examples where the outcome is known, such as past claims marked fraudulent. Its results are scores or forecasts that teams can test against what really happened.
What is an example of predictive AI?
A common example is a churn model that gives every customer a nightly probability of canceling. Banks use credit default scores, and insurers flag likely fraud on claims. Retailers forecast demand by store, factories predict failures from sensor data and carriers predict delays. Each one returns a number that triggers a decision or an action.
What are examples of generative AI?
Common examples include chat assistants that answer staff questions from policy documents and tools that summarize long contracts. Coding assistants draft functions and tests, and image models create product visuals. In insurance, a model can draft a claim summary and a customer letter. Each one produces new content that a person can read, edit and approve.
Which is better for business, generative AI or predictive AI?
Neither is better in general, because the right choice depends on the task. Predictive AI fits decisions that need a measurable number, such as fraud scoring or demand planning. Generative AI fits work built on language, such as summaries, drafts and answers. Many businesses get the most value by using predictive AI to decide and generative AI to communicate.
Which is more accurate, generative AI or predictive AI?
Predictive AI is easier to measure, because each forecast or score can be checked against what really happened using measures such as AUC or MAPE. Generative output has many acceptable versions, so accuracy means staying grounded in sources and passing rubric or expert review. For tasks that need an exact number, a trained predictive model is the safer choice.
What is the difference between generative AI and AI?
AI is the broad field of building systems that perform tasks that normally need human judgment. Machine learning is a large part of it, and both predictive AI and generative AI sit inside machine learning. Generative AI is the branch that creates new content. Other branches include predictive models, computer vision classifiers and older rule-based systems.
What are the three main types of predictive models?
The three main types are regression, classification and time-series models. Regression predicts a quantity, such as the cost of a claim. Classification assigns a category, such as fraud or not fraud, or churn or stay. Time-series models forecast values across future dates, such as weekly demand by store. Many projects combine all three within one pipeline.
What are the main types of generative AI models?
The main types are large language models for text and code, diffusion models for images, and multimodal models that handle several input types at once. Older families include generative adversarial networks and variational autoencoders. Most enterprise generative AI runs on Transformer-based language models, often grounded in company documents through retrieval so answers can cite their sources.
How do descriptive, predictive and generative AI differ?
Descriptive analytics explains what already happened, using reports, dashboards and summaries of past data. Predictive AI estimates what is likely to happen next, such as demand or churn. Generative AI creates new content, such as a written explanation of a dashboard or a draft customer email. Mature data teams often run all three on the same data.
Can generative AI and predictive AI work together?
Yes, and many strong systems do. A predictive model scores churn risk, then a generative model drafts a retention offer that a person approves. In the reverse pattern, a language model extracts fields from emails that then feed a predictive model. An AI agent can also call each one as a separate tool within set limits.
Will generative AI replace predictive analytics?
Generative AI is unlikely to replace predictive analytics. The two do different jobs. Forecasts and risk scores need trained models with measurable error and stable behavior. Generative AI is more likely to sit on top of predictive models, explaining forecasts in plain language and drafting the actions that follow. Analysts then spend less time writing reports.
Is generative AI more expensive or compute-hungry than predictive AI?
Per request, yes. Generative models do far more work per call and need GPUs or hosted APIs. Predictive models often run on CPUs in cheap batch jobs. Model choice matters even more. On November 2, 2026, OpenAI listed GPT-6 Astra at 100 times the input price of GPT-6 Luna. So price the model you will run, not the category.
What data do generative AI and predictive AI need?
Predictive AI needs labeled, mostly structured history, such as past transactions marked fraudulent or past sales by week. Generative AI starts from a pretrained model, so it needs your well-organized documents, plus access rules that decide who may see each one. Both need a measured baseline and a clear owner before any project starts.
Can ChatGPT or generative AI build predictive models?
Generative AI can help build predictive models by writing feature code, drafting SQL, suggesting algorithms and explaining results. The forecast itself should come from a trained model, such as gradient-boosted trees or a time-series model, tested on your labeled history. Asking a chatbot to guess future numbers directly gives answers you cannot measure or audit.
Are time-series foundation models generative AI?
They are pretrained like large language models, on huge collections of time series, but their output is a forecast. So treat them as predictive AI in practice. Examples include Google’s TimesFM 3.0 and Amazon’s Chronos-2. Check the license first, because TimesFM 3.0’s downloadable weights carry a non-commercial license, and commercial use runs through Google Cloud services such as BigQuery ML.