TL;DR
Data governance best practices that work in 2026 give data an owner, a rule that runs in a system and a number someone checks. Start small, with the data behind one business problem such as revenue reporting. Give each data area one business owner and one day-to-day caretaker, and keep a few shared rules central.
Put quality checks and access rules inside your data pipelines and platforms, so they run on their own. Judge success by fewer data errors, faster fixes and quicker audit answers. Gartner expects 80% of data and analytics governance programs to fail by 2027 because no real or manufactured crisis drives them.
Key Takeaways
- Start with the critical data elements behind one business problem, then widen scope domain by domain.
- Give every data domain one accountable owner and a named steward, with IT running the platform rather than owning the data.
- Enforce controls inside systems, as quality rules in pipelines and access policies in the platform, instead of in policy documents.
- Large enterprises do best with federated ownership under a few central rules, such as shared definitions, classification and access.
- Measure outcomes such as quality pass rates, issue resolution time and audit evidence speed, not activity counts.
- Extend the same controls to the data that AI copilots, models and agents read, before those tools reach production.
The Board Report Nobody Could Agree On
Picture a quarterly business review, when every leader brings their own numbers. The CFO opens with a Q3 revenue figure; the sales leader answers with one several million dollars higher.
Both teams pulled their totals from the same warehouse, so nobody in the room is lying. Finance counts revenue when an invoice is recognized, while sales counts it when a contract is signed. The dashboards also read different copies of the customer table, and one carries duplicate accounts.
Three things went wrong at once. Nobody owned the definition of revenue. Nobody was accountable for the customer table, so no one watched its quality. And no check in the pipeline caught the duplicates before they reached a board slide.
Data governance exists so that meeting never happens again. This guide covers the practices that work, the order to adopt them in, who owns each one and how to tell whether they work.
What Are Data Governance Best Practices?
Data governance best practices are repeatable habits that decide who owns data, which rules it must meet and how those rules are enforced. They sit on top of data governance as a discipline and then turn its policies into daily work.
A data governance framework describes the structure, meaning the roles, policies and processes a program needs. Practices, by comparison, are narrower. They are the specific moves that make the framework run on real data, in real systems, with real people accountable.
What Separates a Practice That Works From a Policy Document
A policy says what should happen, whereas a working practice makes it happen and proves it did. A quick test helps: a practice works when it has an owner, an enforcement point inside a system and a metric someone reviews.
Take a rule such as “customer email addresses must be valid.” Written in a policy binder, that sentence changes nothing. Once a steward owns it, a pipeline check rejects bad values and a weekly report shows the pass rate, it becomes governance.
| Test | What it looks like | Failure sign |
|---|---|---|
| Named owner | One person accountable for the data domain and its rules | “The data team” or “IT” owns it |
| Enforcement point | A rule running in a pipeline, catalog or access policy | The rule lives only in a document or a wiki |
| Reviewed metric | A number tracked on a schedule, with action when it slips | Nobody can say whether the rule is being met |
These three tests apply to every practice below. If you want the values that sit underneath them, such as accountability and transparency, the guide to core data governance principles covers them in depth.
Why Governance Matters More in 2026
The case for governance once rested on compliance and reporting accuracy. Both still matter, but two shifts have raised the stakes.
The first is AI. Copilots, retrieval assistants and agents read enterprise data directly, so a stale definition or a loose permission no longer stays inside a dashboard. Instead, it shows up in an answer that an employee or a customer acts on. Under Article 10 of the EU AI Act, data used to train, validate and test high-risk AI systems must follow governance and management practices.
The second shift is the spread of platforms, especially in large enterprises. Many enterprises run Microsoft Fabric, the Databricks Data Intelligence Platform and Snowflake side by side, while each keeps its own catalog and permission model. Without shared rules, the same customer can carry three definitions and three access policies.
Gartner puts the risk plainly. In a February 2024 prediction, it said 80% of data and analytics governance initiatives will fail by 2027. The reason it gave was the lack of a real or manufactured crisis. In other words, programs without a burning business reason stall.
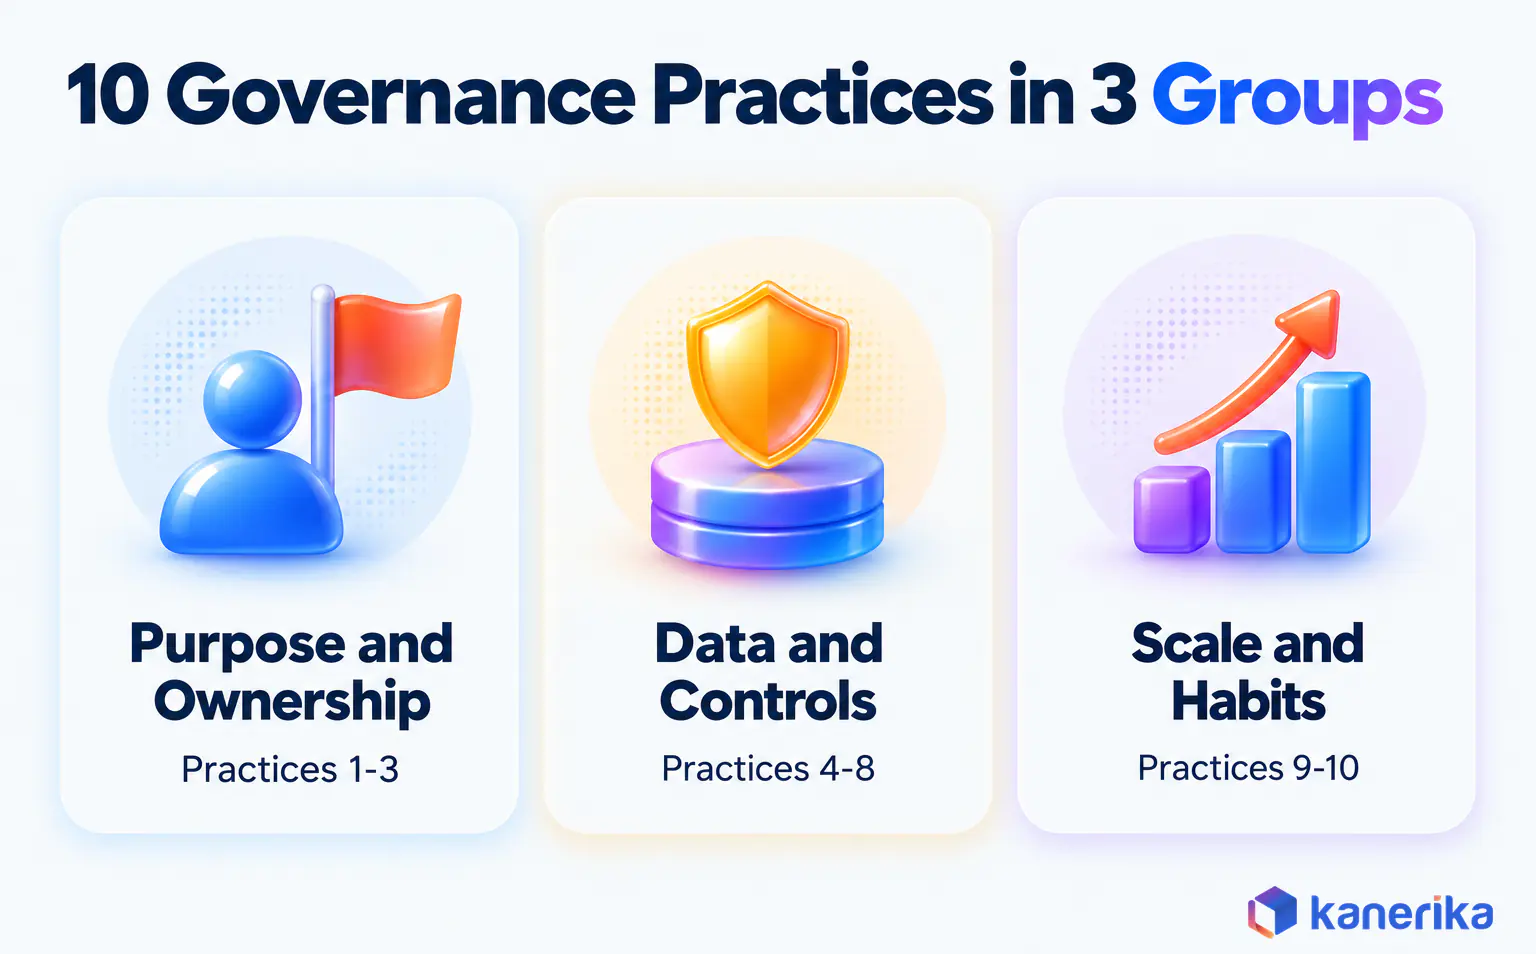
10 Data Governance Best Practices That Work
The ten practices below follow the order most programs should adopt them in, starting with purpose and ownership and ending with skills and habits. Each one names what it is and why it works, then gives a first action you can take within a week.
1. Tie Governance to a Business Problem and an Executive Sponsor
Governance earns support when it fixes a pain leaders already feel. Think of a disputed revenue number, a failed audit or an AI pilot blocked by data access. Gartner’s Saul Judah put it directly: “A D&A governance program that does not enable prioritized business outcomes fails.”
A sponsor matters because governance asks teams to change how they work. Someone with budget authority has to settle disputes between domains and protect time for stewards.
First action: write a one-page charter that names the business problem, the sponsor, the first data domain and two outcome measures. For example, “cut month-end revenue reconciliation from five days to two” gives the program a target that finance cares about.
2. Name Owners and Stewards for Each Data Domain
Ownership comes first because everything else depends on it. Without a named owner, every quality issue becomes a ticket that bounces between teams until someone gives up.
The model that works splits accountability from hands-on work, so each role stays clear. A business leader owns the domain and its decisions. A steward does the day-to-day data stewardship work on definitions and quality, and the platform team runs the technology.
| Role | Accountable for | Typical holder |
|---|---|---|
| Governance council | Shared policies, priorities and cross-domain disputes | Sponsor, CDO and domain owners |
| Data owner | Decisions about a domain’s data, access approvals and risk | Business leader, such as VP of Finance |
| Data steward | Definitions, quality rules and issue triage for the domain | Analyst or operations lead inside the business |
| Data custodian | Storage, security, pipelines and platform controls | Data engineering or platform team |
First action: list your top five data domains and write one owner and one steward next to each, with their agreement. Any empty cell in that list then becomes your first governance gap.
3. Govern Critical Data Elements First
Critical data elements are the fields that drive important decisions, reports or regulatory filings. Typical examples include fields such as customer ID, revenue amount, product code and consent status.
Starting there works because it shrinks the problem. Instead of thousands of tables, a team governs a few dozen fields the business already argues about. Every fix then shows up in a report people read.
First action: pick the report your sponsor cares about most and trace it to its source fields. Then mark the ones that would change a decision if they were wrong.
Kanerika Service
Data Governance Consulting Services
Kanerika names owners, sets up glossaries, quality rules, lineage and access policies in Microsoft Purview or Databricks Unity Catalog, and measures the results one domain at a time.
Explore Data Governance Services4. Agree on Business Definitions, a Glossary and Metadata
A business glossary records what each important term means, who approved the meaning and which data assets carry it. Metadata then links those terms to real tables and columns, so a reader can see where “active customer” comes from. Most teams keep it current with metadata management tools.
The revenue dispute in our opening scene was, in effect, a glossary problem. Once finance and sales agree on a written definition, with an owner who signs it off, both dashboards can calculate it the same way. Shared metadata is also the base for broader data intelligence, where teams can search and trust data without asking around.
First action: hold a 60-minute session with finance and sales to define the five most disputed terms. Then publish each one in your data catalog with an owner.
5. Build Data Quality Checks Into Pipelines
Quality checks belong where data moves rather than in a cleanup project after the damage of bad data quality is done. A rule that runs inside the pipeline can stop bad records, quarantine them or raise an alert before a dashboard refreshes.
This works because it turns quality from an opinion into a test result. Common rules also cover completeness, validity, uniqueness, timeliness and consistency between systems. Monitoring pipeline health over time is the job of data observability tools, since they flag volume drops and schema changes that rule checks miss.
First action: write three rules for one critical data element and run them on every data ingestion load. A good first rule is “customer ID is never null and never duplicated.”
6. Maintain End-to-End Lineage
Data lineage shows where data came from, how it was transformed and where it ends up. When a number looks wrong, lineage lets a steward trace it back to the source in minutes instead of days.
Lineage also makes change safer. Before renaming a column, an engineer can see every report and model that depends on it. So a quiet schema change no longer breaks the board pack.
Partial lineage is a common trap, though. A map that stops at the warehouse, for example, misses the BI layer and the AI application, so it gives false confidence.
First action: map full lineage for one critical report, from source system to dashboard, and record any manual spreadsheet step you find along the way.
7. Classify Data and Enforce Access by Approved Use
Data classification labels data by sensitivity, such as public, internal, confidential or restricted, and flags categories like personal or health data. Access policies then grant use based on those labels and on the purpose a person has been approved for.
The practice works when labels drive enforcement automatically. A column tagged as personal data, for instance, should be masked for analysts who do not need it, without a separate request for every table.
In Databricks Unity Catalog, that mask is a SQL function attached to the column itself. The sample below follows the pattern in the Databricks guide to row filters and column masks. Its group names are illustrative, so swap in your own.
-- Show real email addresses only to the approved outreach group
CREATE FUNCTION email_mask(email STRING)
RETURN CASE WHEN is_account_group_member('sales_outreach') THEN email ELSE '***@***' END;

ALTER TABLE customers ALTER COLUMN email SET MASK email_mask;

-- Row filter: members of the admin group see every row, others see US rows only
CREATE FUNCTION us_filter(region STRING)
RETURN IF(is_account_group_member('admin'), true, region = 'US');

ALTER TABLE customers SET ROW FILTER us_filter ON (region);
First action: run automated classification on one domain and review the results with the steward. Then connect the top sensitivity label to a masking or row-level policy.
Talk to Kanerika
Find the Gaps in Your Governance Controls
Kanerika reviews one data domain for missing owners, quality rules, labels and access policies, then turns the gaps into a 90-day plan.
Talk to a Governance Expert →8. Govern the Full Data Lifecycle
Data still has a life after it stops being useful, and that tail carries cost and risk. Lifecycle governance sets how long each data class is kept, when it is archived and how it is deleted.
Retention rules come from regulation, contracts and business need, so the owner and legal team should agree on them together. Deletion must also reach copies, extracts and backups, or the rule only exists on paper.
First action: pick one data class with a known legal retention period and check whether any copy is held longer than that period.
9. Automate Repeatable Controls While Keeping People Accountable
Manual governance works only until the estate grows. Spreadsheets of owners, emailed access approvals and quarterly quality reviews fall behind once new sources and users arrive.
Automation should handle the repeatable work, such as scanning for new assets, applying labels, running quality rules and routing access requests. People still keep the decisions, including approving definitions, granting exceptions and accepting risk. In the same 2024 forecast, Gartner expects GenAI to speed up the time to value of governance and master data programs by 40% by 2027. That gain only lands where owners still sign off on what the tools propose.
First action: list every governance task your team still repeats by hand. Then mark the ones a catalog, a policy engine or one of your data orchestration tools could run on a schedule.
10. Train People and Build Adoption Habits
Governance fails quietly when people do not know the rules exist. Analysts keep their own definitions, and engineers bypass the catalog because it feels slower than asking a colleague.
Role-based training works better than one company-wide course. Stewards need hands-on skills in the catalog and quality tools, whereas analysts mostly need the data literacy basics of where trusted data lives and how to request access.
First action: add a governance step to routines you already run. A glossary check in sprint reviews works, for example, as does a data quality item at the monthly business review.
All Ten Practices at a Glance
The table below sums up all ten practices with the problem each fixes, the first action and the usual owner.
| Practice | Problem it fixes | First action | Owner |
|---|---|---|---|
| Business problem and sponsor | Program stalls with no reason to exist | One-page charter with two outcome measures | Executive sponsor |
| Owners and stewards | Issues bounce between teams | Owner and steward for top five domains | Governance council |
| Critical data first | Effort spread too thin | Trace one key report to its source fields | Data owner |
| Glossary and metadata | Same term, different numbers | Define the five most disputed terms | Data steward |
| Quality checks in pipelines | Bad data reaches reports | Three rules on one critical element | Steward and data engineering |
| End-to-end lineage | Slow root-cause analysis, risky changes | Full lineage for one critical report | Data custodian |
| Classification and access | Over-shared sensitive data | Label one domain, link labels to policy | Owner and security |
| Lifecycle | Data kept longer than allowed | Check one data class against retention | Owner and legal |
| Automation | Manual controls fall behind | List recurring tasks that can be scheduled | Platform team |
| Training and habits | Rules exist but nobody follows them | Add a governance step to an existing routine | Governance lead |
From Policy to Enforcement: How Governance Works Day to Day
Day to day, governance is a chain that runs from a written intent to proof that the intent was met. If one link is missing, the program looks busy but does not change outcomes.
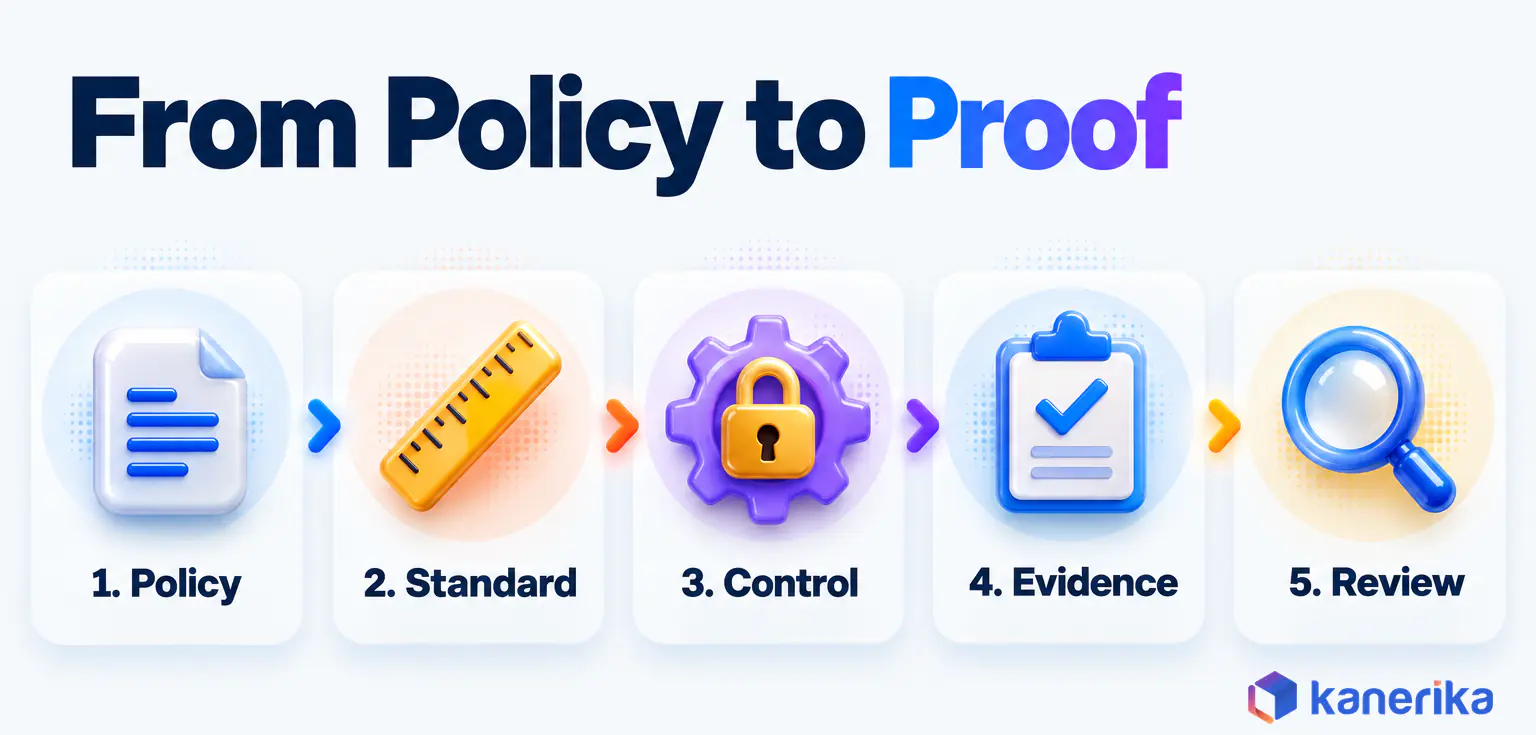
The chain has five links, and each one depends on the one before. A policy states the intent, such as “customer personal data is only used for approved purposes”. Then a standard makes it specific, for example which fields count as personal and which purposes are approved. A control enforces the standard inside a system, such as a masking policy in the warehouse. Evidence records that the control ran, and a review checks that evidence on a schedule and fixes what failed.
Most stalled programs have the first two links and skip the last three. They often have well-written policies, but no system enforces them and nobody can show an auditor that they worked.
Worked Example: One Customer Dataset Shared by CRM, BI and an AI Assistant
Consider a customer table that feeds the CRM, a revenue dashboard and a new internal AI assistant that answers account questions. Here is how the chain applies to it.
- Owner: the VP of Sales Operations owns the customer domain, while a sales operations analyst acts as steward.
- Quality rule: customer ID must be unique and non-null, so the pipeline quarantines any load that breaks the rule.
- Access rule: email and phone columns are labelled personal data, so analysts see them masked unless their role is approved for outreach.
- Lineage: the catalog shows the table flowing from the CRM into the warehouse, then into the dashboard and the assistant’s retrieval index.
- AI retrieval approval: the owner approves the table for the assistant, and the assistant respects the same masking rules a human analyst would face.
When the assistant later gives a wrong account count, the steward follows lineage back to a quarantined load and fixes the source within an hour. The control worked, the evidence existed, and the review caught the gap before it spread.
A 90-Day Plan to Put These Practices in Place
Ninety days is enough to prove governance on one domain, so it makes a good length for a first phase. The aim is a working example that others can copy, rather than a finished enterprise program.
Before you start, take a quick baseline of where you stand. A data governance maturity model gives you a simple scale to score ownership, quality, metadata and access today and again at day 90.
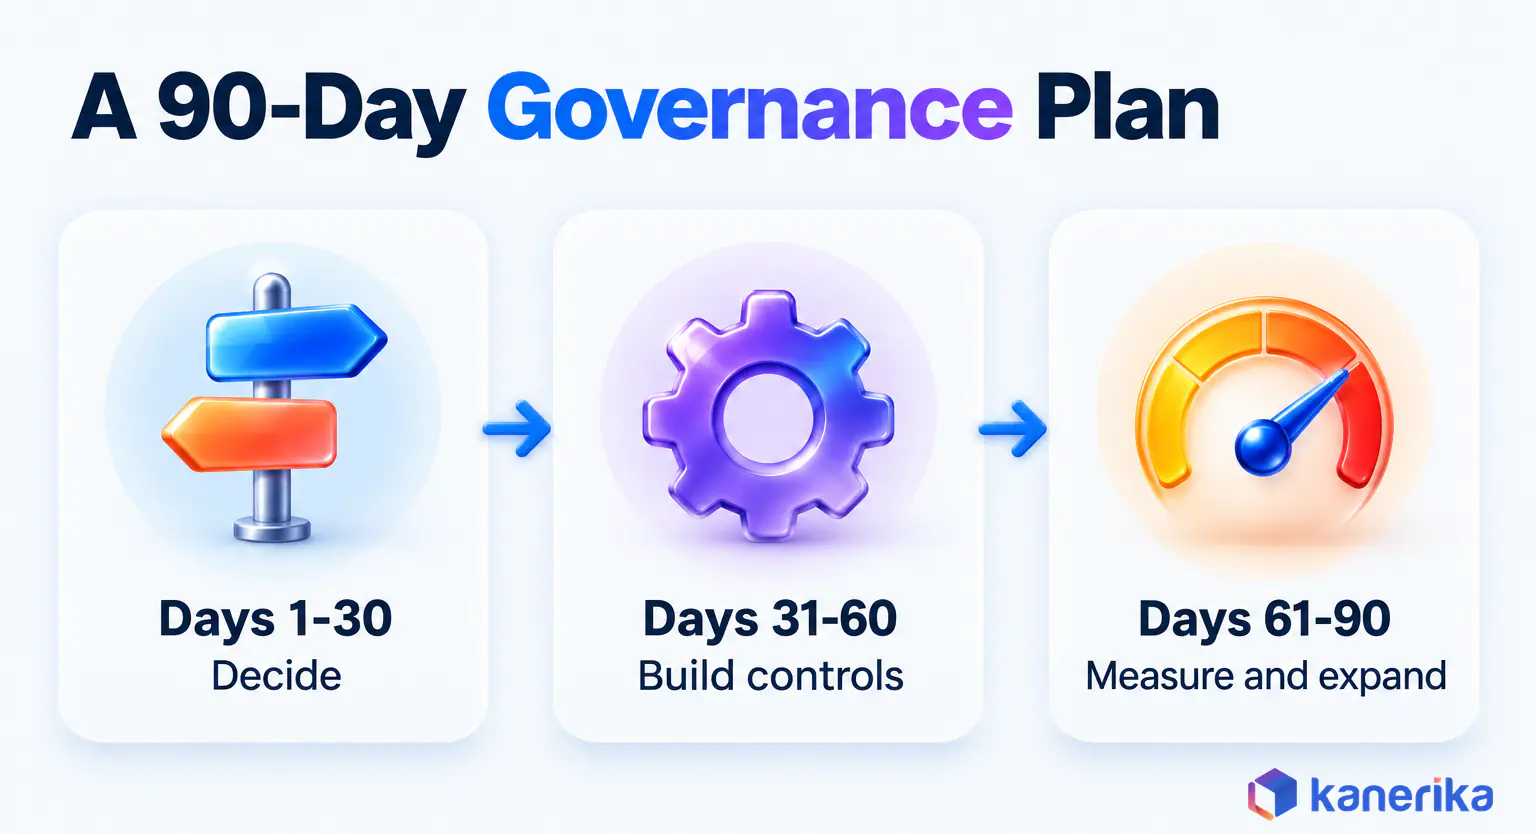
Days 1 to 30: Choose the Problem, the Domain and the Operating Model
The first month is for decisions, so tools can wait until the owners and the domain are clear. Before anything else, agree on the business problem and pick one domain. Then name its owner and steward, and choose how ownership will work across the company.
| Operating model | Best fit | Main risk | Example |
|---|---|---|---|
| Centralized | Smaller firms or one dominant data platform | The central team becomes a bottleneck once demand grows | One data office approves every definition |
| Federated | Large enterprises with several business units | Domains drift apart unless shared rules exist | Domains own data, a council sets classification and glossary rules |
| Decentralized | Independent units with little shared data | Conflicting definitions and duplicate effort | Each unit runs its own catalog and policies |
For most large enterprises, federated ownership with central rules is the default worth choosing. It matches the domain thinking behind data mesh’s federated governance, while keeping one set of definitions, labels and access rules across domains.
Days 31 to 90: Build Controls, Then Measure
After that, the second and third months turn decisions into running controls. Take the customer dataset from the worked example above. In days 31 to 60, the steward ships glossary terms, the customer-ID rule and lineage for the revenue dashboard.
In days 61 to 90, the owner sends the first scorecard to the sponsor, showing the rule’s pass rate and how fast issues closed. That tells the sponsor whether the domain is ready to copy. The table lists the outputs and owners for all three phases.
| Phase | Outputs | Owner |
|---|---|---|
| Days 1 to 30 | Charter, sponsor, first domain, owner and steward, operating model, list of critical data elements, baseline maturity score | Sponsor and governance lead |
| Days 31 to 60 | Glossary terms for the domain, quality rules in pipelines, lineage for one key report, sensitivity labels and access policies | Steward and platform team |
| Days 61 to 90 | KPI scorecard, first quarterly review, issue log with resolution times, plan for the next two domains | Data owner and council |
By day 90 you should be able to show the sponsor a before-and-after view of the business problem you started with. That result, more than any policy count, decides whether the program gets funding for the next domain.
How Do You Measure Data Governance Success?
Success shows up as fewer data problems reaching the business and faster answers when they do. So the best measures track outcomes and speed, while activity counts such as policies written or assets scanned only show effort.
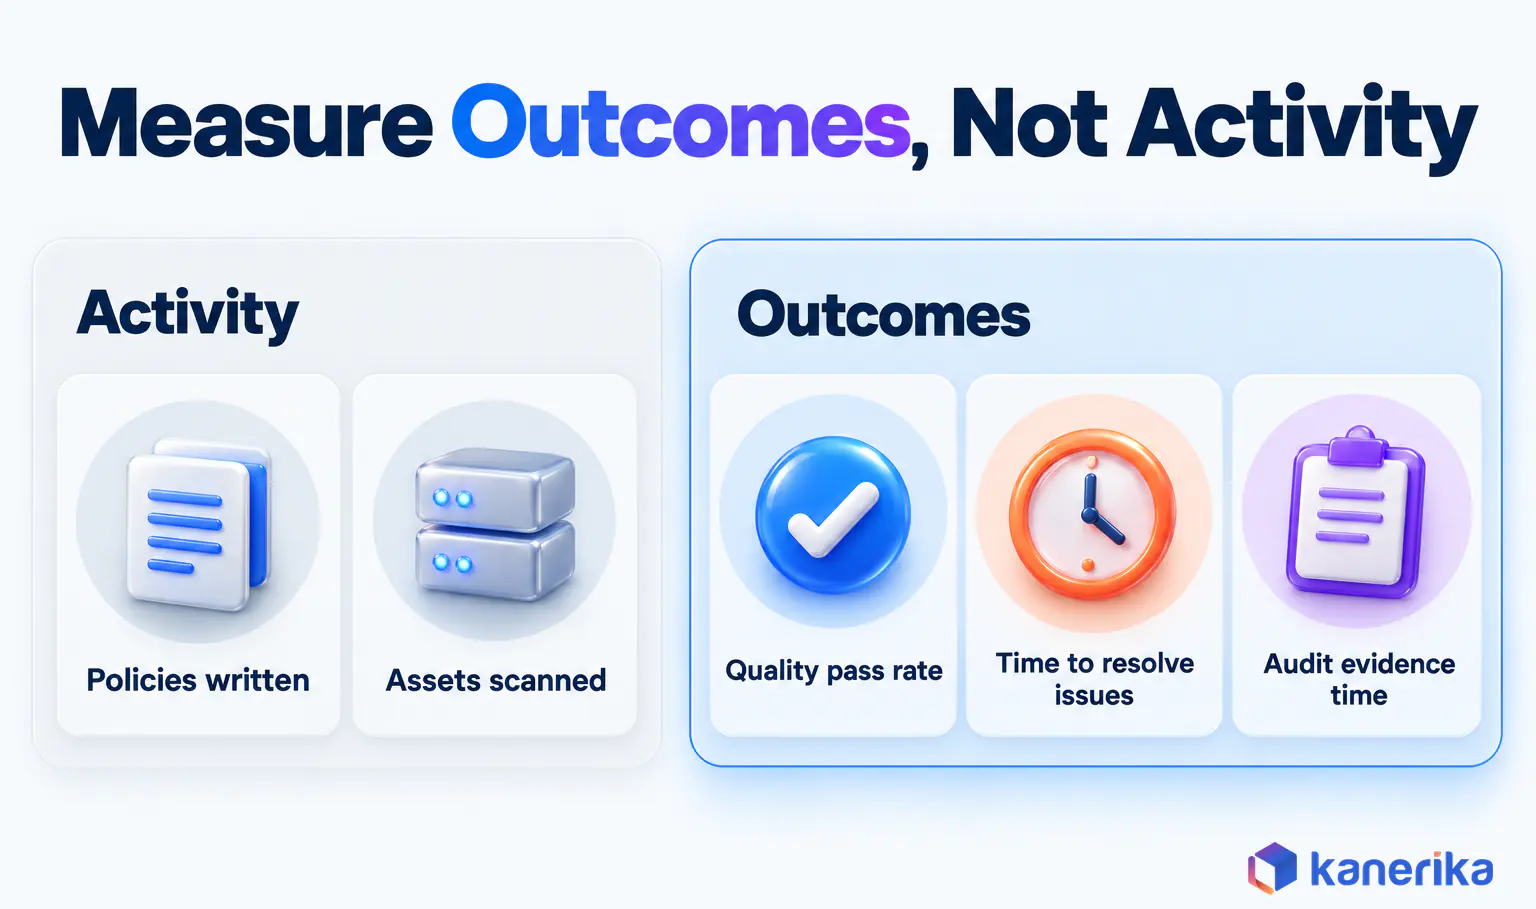
The KPIs below work across most programs, since each one has a simple formula. Two teams calculating a KPI should then get the same answer.
| KPI | Formula | Good direction |
|---|---|---|
| Critical data ownership coverage | Critical data elements with a named owner, divided by all critical data elements | Up |
| Quality rule pass rate | Rule checks passed, divided by rule checks run | Up |
| Mean time to resolve data issues | Total hours from issue logged to issue closed, divided by issues closed | Down |
| Access policy violations | Count of access events that broke a policy in the period | Down |
| Lineage coverage | Critical assets with end-to-end lineage, divided by all critical assets | Up |
| Time to produce audit evidence | Hours from an audit request to complete evidence | Down |
| Glossary adoption | Reports that use approved glossary terms, divided by all governed reports | Up |
A Sample Quarterly Scorecard
A scorecard keeps the sponsor’s attention on a few numbers rather than a long report. The illustrative example below shows the structure only, since the right targets depend on your own baseline.
| KPI | Reported by | Target set by | Action if off track |
|---|---|---|---|
| Ownership coverage | Governance lead | Council | Escalate unowned elements to the sponsor |
| Quality rule pass rate | Data steward | Data owner | Root-cause review of the top three failing rules |
| Mean time to resolve issues | Data steward | Data owner | Add triage capacity or automate alerts |
| Access policy violations | Security team | Council | Tighten the policy or retrain the role |
| Audit evidence time | Compliance lead | Sponsor | Automate evidence capture for slow controls |
Review the scorecard every quarter with the council, then agree on fixes for any KPI that slips. A KPI that never changes is either measuring the wrong thing or tracking a control nobody owns.
Common Data Governance Mistakes and How to Fix Them
Most governance mistakes come from doing the visible work first, such as buying a catalog or writing policies, and leaving ownership and enforcement for later.
Take a catalog bought before anyone owns the data. The tool scans every asset, but nobody curates them, so descriptions stay blank and search returns duplicates. Business users soon stop opening it, and the purchase becomes proof that governance does not work.
The table pairs each common mistake with what fails and the fix.
| Mistake | What fails | Fix |
|---|---|---|
| Buying a catalog before naming owners | Assets get scanned but nobody curates them | Name owners and stewards first, then configure the tool |
| Governing everything at once | Effort spreads thin, so no result is visible | Start with one domain and its critical data elements |
| Making IT the sole owner | Business definitions stay disputed | Business leaders own data, IT runs the platform |
| Treating the catalog as governance | Metadata exists but no rule is enforced | Link each policy to a control in a system |
| Running governance in spreadsheets | Records go stale soon after setup | Move owners, terms and rules into the catalog |
| No exception process | Teams bypass rules when deadlines loom | Time-boxed exceptions approved by the owner |
| Partial lineage | Root-cause analysis stops at the warehouse | Trace critical reports from source to dashboard |
| Copying access rights into AI tools | Assistants show users data they could not open before | Enforce source permissions at retrieval time |
| Reporting activity metrics | Leaders see effort but no outcome | Report quality, speed and audit KPIs instead |
Overall, the pattern across these mistakes is simple. Each one treats governance as a project to finish, when it works better as a routine that runs inside the systems people already use.
Which Regulations and Standards Should Shape Your Program?
Fixing those mistakes is easier once you know which outside rules your controls have to satisfy. Regulations set the minimum your controls must prove, while standards give you a tested structure to build on. Not every framework applies to every business, so map them against where you operate and what data you hold.
| Reference | What it informs | Who it applies to |
|---|---|---|
| DAMA-DMBOK | Knowledge areas and roles for data management | Any organization, voluntary |
| ISO/IEC 38505-1 | Board-level governance of data | Any organization, voluntary |
| NIST AI RMF | Risk management for AI systems, including data | Any organization, voluntary |
| GDPR | Lawful basis, purpose limits and retention for personal data | EU-based organizations, and any organization offering services to or monitoring people in the EU |
| CCPA/CPRA | Consumer rights over personal information | Qualifying businesses handling California residents’ data |
| HIPAA | Privacy and security of health information | US covered entities and their business associates |
| BCBS 239 | Risk data aggregation and reporting | Banks, especially systemically important ones |
| EU AI Act, Article 10 | Governance of training, validation and testing data | Providers of high-risk AI systems in the EU market |
The penalties also explain why these references deserve a place in your controls. Under GDPR Article 83, serious breaches can draw fines of up to EUR 20 million or 4% of worldwide annual turnover, whichever is higher. The NIST AI RMF, released in January 2023, is voluntary, yet many US firms use it to structure AI data controls.
The EU AI Act runs on its own timetable. As amended, it applies generally from 2 August 2026, according to the AI Act Service Desk. Its high-risk rules start later, on 2 December 2027 for Annex III systems and 2 August 2028 for Annex I systems.
Extending Governance to AI Applications and Agents
AI governance starts with data governance, because a model or agent can only be as trustworthy as the data it reads. This section covers the data side of AI, meaning what AI tools may use and how, rather than the full model risk process.
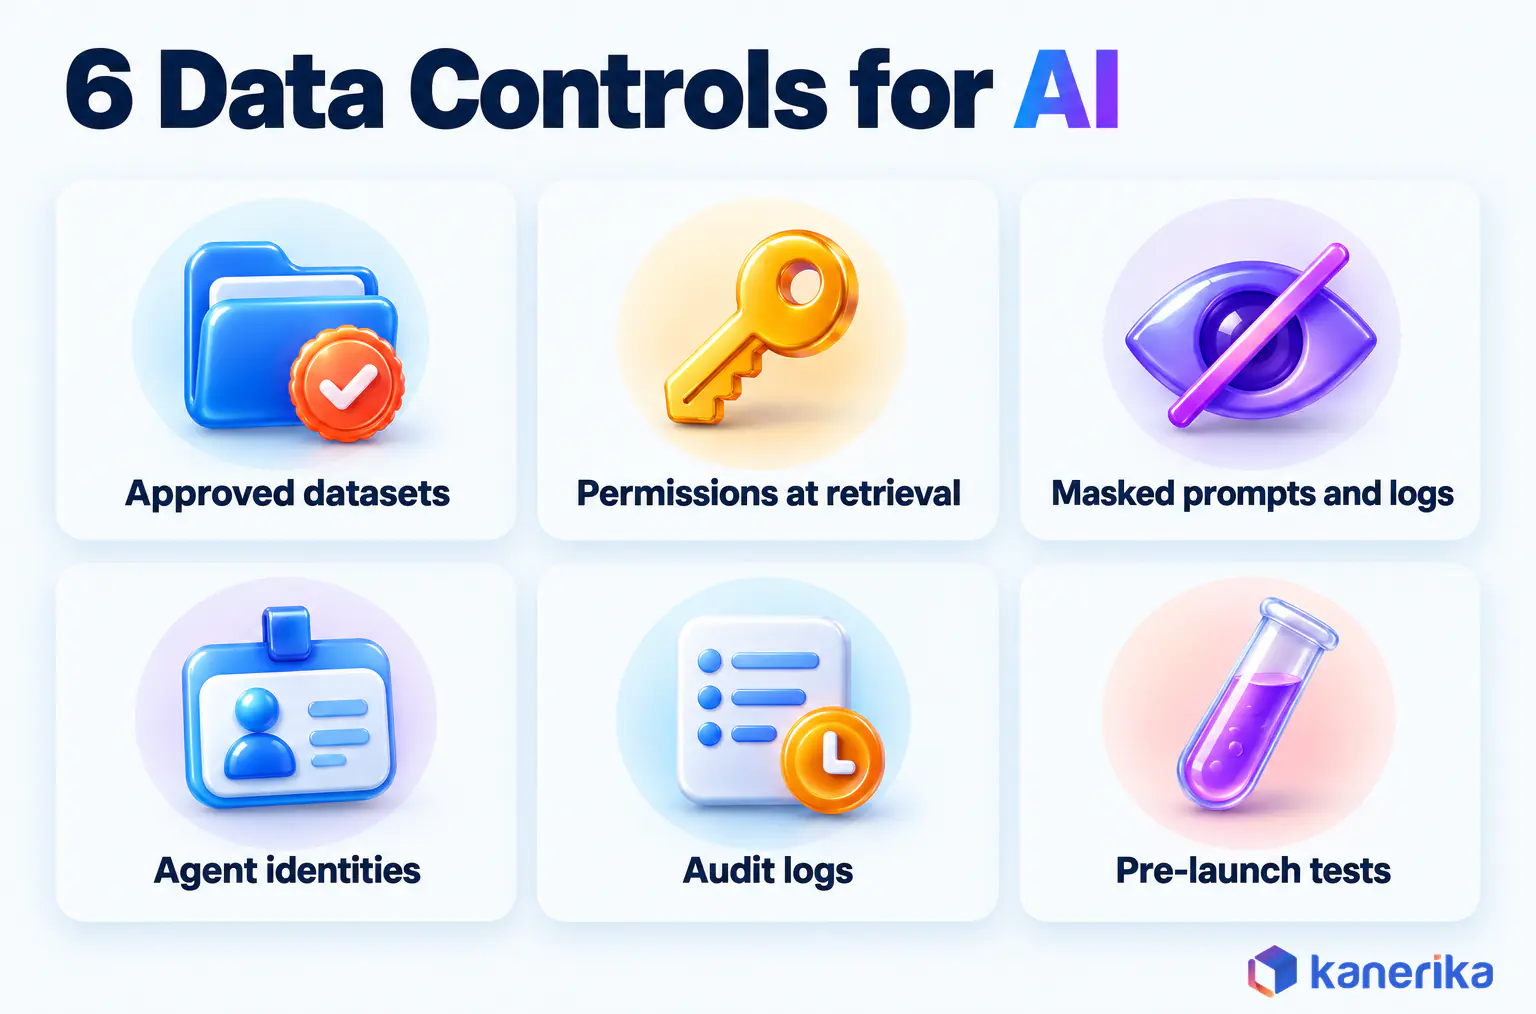
The core idea is that existing rules must follow data into AI tools, so permissions do not reset at the AI layer. When an assistant indexes a document library, it should honor the same permissions a person faces. Otherwise one well-phrased question can surface a salary file or a contract that the person asking was never cleared to read.
Six controls cover most of the risk:
- Approved datasets: only data an owner has approved for training or retrieval enters an AI pipeline, so nothing slips in unreviewed.
- Source permissions at retrieval: the assistant checks the user’s access rights whenever it fetches content.
- Sensitive data in prompts and logs: personal and confidential data is masked or blocked before it reaches prompts, outputs and logs.
- Agent identities and connectors: each agent has its own identity, scoped permissions and an owner for every connector, a core rule of agentic AI governance.
- Provenance and audit logs: you can trace which data informed an answer and who asked for it.
- Pre-production testing: data quality, bias and leakage tests run before an AI tool goes live.
Why AI-Ready Data Starts With Governance
Gartner predicted in February 2025 that through 2026, organizations will abandon 60% of AI projects unsupported by AI-ready data. The same release cites a July 2024 Gartner survey of 1,203 data management leaders. In it, 63% of organizations either lacked the right data management practices for AI or were unsure they had them. So governed, owned and labelled data is a large part of what makes data AI-ready. For the policy and risk side, see the guides on AI governance, risk and compliance and unified AI governance architecture.
Read More: AI Governance: What It Is and How It Works in Enterprises
Tools That Help the Practices Stick
Tools make governance practices repeatable, but they do not create ownership or decisions. Pick tools after the owners and first domain are clear, and judge them by how well they enforce the practices above.
Four categories matter most. Microsoft’s Purview Unified Catalog covers several of them in one place. Its features include governance domains, data products, glossary terms, critical data elements, data quality rules, health controls and reports, OKRs and self-service access requests. Databricks Unity Catalog plays a similar role for lakehouse data, with catalog, lineage and access controls inside the platform.
| Category | Practices it supports | What to look for |
|---|---|---|
| Catalog and glossary | Ownership, definitions, critical data elements | Owner fields, approval workflow and search business users can use |
| Quality and observability | Quality checks, issue resolution | Rules that run in pipelines, alerts, pass-rate history |
| Lineage | Root-cause analysis, change impact | Column-level lineage from source to BI and AI tools |
| Classification and access | Sensitivity labels, access by approved use | Automated labelling linked to masking and access policies |
For side-by-side comparisons, see the reviews of data governance tools and data access governance tools. For a step-by-step setup on the Microsoft stack, read our guide to governing data with Microsoft Purview.
Data Governance Best Practices Checklist
Use this checklist before each quarterly review to check whether your program covers the basics. Each line maps to one of the practices above, grouped by the part of the program it belongs to.
Ownership
- ☐ A business problem, an executive sponsor and two outcome measures are written down.
- ☐ Every priority data domain has a named owner and steward who have agreed to the role.
- ☐ A governance council meets on a fixed schedule and settles cross-domain disputes.
Data
- ☐ Critical data elements are listed for the first domain before any tool rollout.
- ☐ Disputed business terms have approved definitions in the catalog.
- ☐ Lineage runs from source to dashboard for at least one critical report.
Controls
- ☐ Quality rules run in pipelines for every critical data element.
- ☐ Sensitive data is labelled and labels drive masking or access policies.
- ☐ Retention and deletion rules are set for each data class.
Measurement
- ☐ A quarterly scorecard tracks outcome KPIs, not activity counts.
- ☐ AI tools use only approved data and honor source permissions.
- ☐ Audit evidence can be produced from systems rather than assembled by hand.
Then score each line as done, partial or missing. Three or more missing lines in one group shows where the next 90 days should go.
Checklist
AI Governance Checklist
A downloadable checklist to confirm that the data your AI tools read is approved, permissioned, masked and logged before launch.
Get the Checklist →How Kanerika Puts Data Governance Best Practices into Production
Kanerika runs data governance best practices the same way this guide describes, one domain at a time, with owners named before any tool is configured. A typical engagement assesses one domain, sets owners and stewards, enforces rules in Microsoft Purview or Databricks Unity Catalog and then measures the results. Where a client already runs Purview, the work starts with an audit and gap analysis of the existing configuration rather than a rip-and-replace.
Our data governance consulting services run on Microsoft Purview, Databricks Unity Catalog and Concentric AI. Kanerika packages the work in three accelerators, KANGovern, KANGuard and KANComply. On its service page, Kanerika reports 57% faster data discovery and 75% fewer data access violations. It also reports 82% fewer manual governance tasks and 90% accuracy in data classification.
Kanerika is a Microsoft Solutions Partner for Data and AI, and each accelerator covers a different layer of the practices above. KANGovern handles discovery, cataloging and business glossary management on Purview and Unity Catalog, which maps to practices 2 and 4. KANGuard applies data loss prevention and AI-powered classification to sensitive content in Teams, SharePoint, OneDrive and email. KANComply maps compliance against more than 360 regulations, standards and frameworks, including GDPR, CCPA and HIPAA.
Healthcare Example: One Catalog and Classification Framework in Purview
One example is a top North American healthcare organization with data spread across Azure Blob Storage, SQL databases and SaaS apps. It had no consistent classification or metadata framework, while stakeholder engagement was weak. Kanerika used Microsoft Purview to build a centralized catalog with metadata and classifications, and designed a classification framework for the organization.
The work touched practices 2, 4 and 7. The client reported a 57% reduction in data discovery time and a 90% increase in compliance adherence. Data accessibility improved by 70%, while data accuracy rose 35%.
Case Study
90% Compliance Adherence for Healthcare with Purview
Kanerika used Microsoft Purview and a new classification framework to help a North American healthcare organization cut data discovery time by 57% and raise compliance adherence by 90%.
Read the Case Study →Read More: AI Governance Consulting Services for Enterprises
What Data Governance Best Practices Actually Deliver Results?
The data governance best practices that deliver results change what happens inside systems, where data is created, moved and used. Programs that work start from a real business problem and a sponsor who cares about it.
These programs give every domain one owner, so every issue has a home. They govern critical data first, since that keeps effort visible and small enough to finish. They enforce quality, lineage and access rules in pipelines and platforms, and they extend those rules to AI tools. Finally, they measure outcomes every quarter.
Picture the opening board meeting again. A finance owner signs off one revenue definition, a pipeline rule blocks duplicate customer records, and both dashboards show the same number.
Of the ten practices that work in 2026, four carry the most weight: one owner per domain, critical data first, controls in systems and measured outcomes.
Frequently Asked Questions
What are the best practices for data governance?
The practices that work are tying governance to a business problem, naming an owner and steward per data domain, governing critical data elements first, agreeing on a glossary, building quality checks into pipelines, keeping end-to-end lineage, enforcing access by approved use, managing the data lifecycle, automating repeatable controls and training people in their roles.
What are the 4 or 5 pillars of data governance?
Lists vary by source, but most cover the same ground. The common pillars are ownership and stewardship, data quality, metadata and lineage, security and access, and compliance with lifecycle management. Four-pillar versions usually fold compliance into security. What matters more than the count is that each pillar has an owner and a control that runs in a system.
How do you implement data governance step by step?
Start with one business problem and an executive sponsor. Pick one data domain, name its owner and steward, and list its critical data elements. Then agree on definitions, build quality rules and lineage, and set access policies. Measure results with a scorecard after 90 days, and use that proof to expand to the next domains.
What is the difference between data governance and data management?
Data governance decides who owns data, which rules it must meet and how compliance is checked. Data management is the hands-on work of storing, moving, integrating and maintaining data under those rules. Governance sets direction and accountability, while management carries out the work. Our guide on data governance vs data management explains the split in detail.
How do you measure data governance effectiveness?
Measure outcomes rather than activity. Useful KPIs include the share of critical data elements with a named owner, quality rule pass rate, mean time to resolve data issues, access policy violations, lineage coverage, time to produce audit evidence and glossary adoption. Review them quarterly with the governance council and act on any metric that stays flat.
How long does it take to implement data governance?
There is no universal timeline, because scope, data estate size and regulation differ widely. A focused first phase on one domain can show working results in about 90 days. An enterprise-wide program then grows domain by domain over the following quarters. Governance never fully ends, since new data, tools and rules keep arriving.
How does Microsoft Purview support data governance?
Microsoft Purview supports governance through its Unified Catalog, which offers governance domains, data products, glossary terms, critical data elements, data quality rules, health controls and reports, OKRs and self-service access requests. It also handles classification and sensitivity labels across Microsoft and other sources. Our guide to governing data with Microsoft Purview covers setup step by step.
What are data governance best practices for AI?
For AI, approve which datasets may be used for training or retrieval, and enforce source permissions each time an assistant fetches content. Mask sensitive data in prompts, outputs and logs. Give each agent its own identity and scoped access, keep provenance logs, and test data quality, bias and leakage before an AI tool reaches production.
How much does enterprise data governance cost?
Cost depends on the number of domains in scope, the size and spread of the data estate, existing platform licenses, regulatory needs and how much work is automated. The largest cost is usually people time for owners and stewards, not software. Starting with one domain keeps the first phase small and gives a real basis for budgeting.
Why do data governance programs fail?
Programs fail when they lack a clear business reason, when nobody owns the data, or when policies never reach the systems people use. Gartner predicts that 80% of data and analytics governance initiatives will fail by 2027 for lack of a real or manufactured crisis. Tying governance to a pressing business problem is the best defense.
How can you automate data governance?
Automate the repeatable tasks, such as scanning for new data assets, applying sensitivity labels, running quality rules in pipelines, capturing lineage and routing access requests to owners. Catalogs, observability tools and policy engines handle most of this work. Keep people in charge of decisions, including approving definitions, granting exceptions and accepting risk on behalf of the business.
Why is executive buy-in important for data governance?
Governance asks teams to change how they define, share and fix data, and that change needs authority behind it. An executive sponsor funds stewards, settles disputes between domains and keeps governance tied to business goals. Without one, programs tend to stall once the first conflict appears or budgets tighten, and the work quietly stops.
What is a data governance framework, and which is most common?
A data governance framework is the structure of roles, policies, standards and processes that a program follows. DAMA-DMBOK is the most widely referenced model for data management, and many firms adapt it rather than build from scratch. Our guide to the data governance framework explains the components, while practices describe how to run them day to day.
What are the core principles of data governance?
Core principles include clear accountability, data treated as a shared business asset, transparency about definitions and lineage, quality fit for purpose, security and privacy by design, and compliance with the rules that apply. Principles state the values, while practices put them to work. Our guide to core data governance principles covers each one with examples.
What are the four main roles in data governance?
The four main roles are the governance council, the data owner, the data steward and the data custodian. The council sets shared rules and settles disputes. The owner is a business leader accountable for a domain. The steward handles definitions and quality day to day, and the custodian runs storage, security and pipelines.
What is an example of a data governance best practice?
A clear example is building a quality rule into a pipeline for a critical field. Suppose customer ID must be unique and never empty. A steward owns the rule, the pipeline quarantines any load that breaks it, and a weekly report shows the pass rate. The rule is owned, enforced and measured, so it works.
What are data governance tools?
Data governance tools are software that put governance into systems. They fall into four groups, namely catalog and glossary, data quality and observability, lineage, and classification with access control. Microsoft Purview and Databricks Unity Catalog cover several groups each. Tools make practices repeatable, but owners and decisions still have to come from people in the business.
What are the two types of data governance?
The two main types are centralized and federated governance. In a centralized model one data office sets and enforces all rules, which suits smaller firms. In a federated model business domains own their data while a central council sets shared rules for definitions, classification and access. Large enterprises usually do best with the federated approach.
What is data governance in ETL?
Data governance in ETL means applying governance rules while data is extracted, transformed and loaded. Pipelines check quality rules, apply sensitivity labels, mask restricted fields and record lineage as data moves. Bad records are rejected or quarantined before they reach reports. This turns policies into tests that run on every load rather than occasional manual reviews.
What are the main goals of data governance?
The main goals are trusted data for decisions, clear accountability for each data domain, protection of sensitive and regulated data, and evidence that rules are met. Good programs also aim to cut the time people spend finding and fixing data. In 2026, a growing goal is making data safe and fit for AI tools.