TL;DR
Explainable AI shows why a model made a decision, and a method called SHAP is the best default for most business models. Use counterfactual explanations when a customer needs to know what would change the outcome. If a simple model is about as accurate as a complex one, pick the simple model. For chatbots and AI agents, trust cited sources and human review over the model’s own story. Free open-source libraries do most of the work, and Azure Machine Learning wraps them in a managed dashboard. Grand View Research puts the market at USD 10.9 billion in 2026, while US credit rules and GDPR already demand reasons and EU high-risk rules follow in December 2027.
Key Takeaways
- Explainable AI answers why a model made a decision, in terms the affected person, the model owner and an auditor can each check.
- SHAP is the default for tabular models: TreeSHAP is fast and exact for tree ensembles, while KernelSHAP works on any model but runs slower.
- Counterfactual explanations tell a customer what would need to change, so they fit recourse and adverse-action letters best.
- When an interpretable model such as an Explainable Boosting Machine is nearly as accurate, ship it instead of explaining a black box.
- Published 2025 market sizes range from USD 7.5 billion to USD 9.2 billion, so demand is real but the forecasts are not directly comparable.
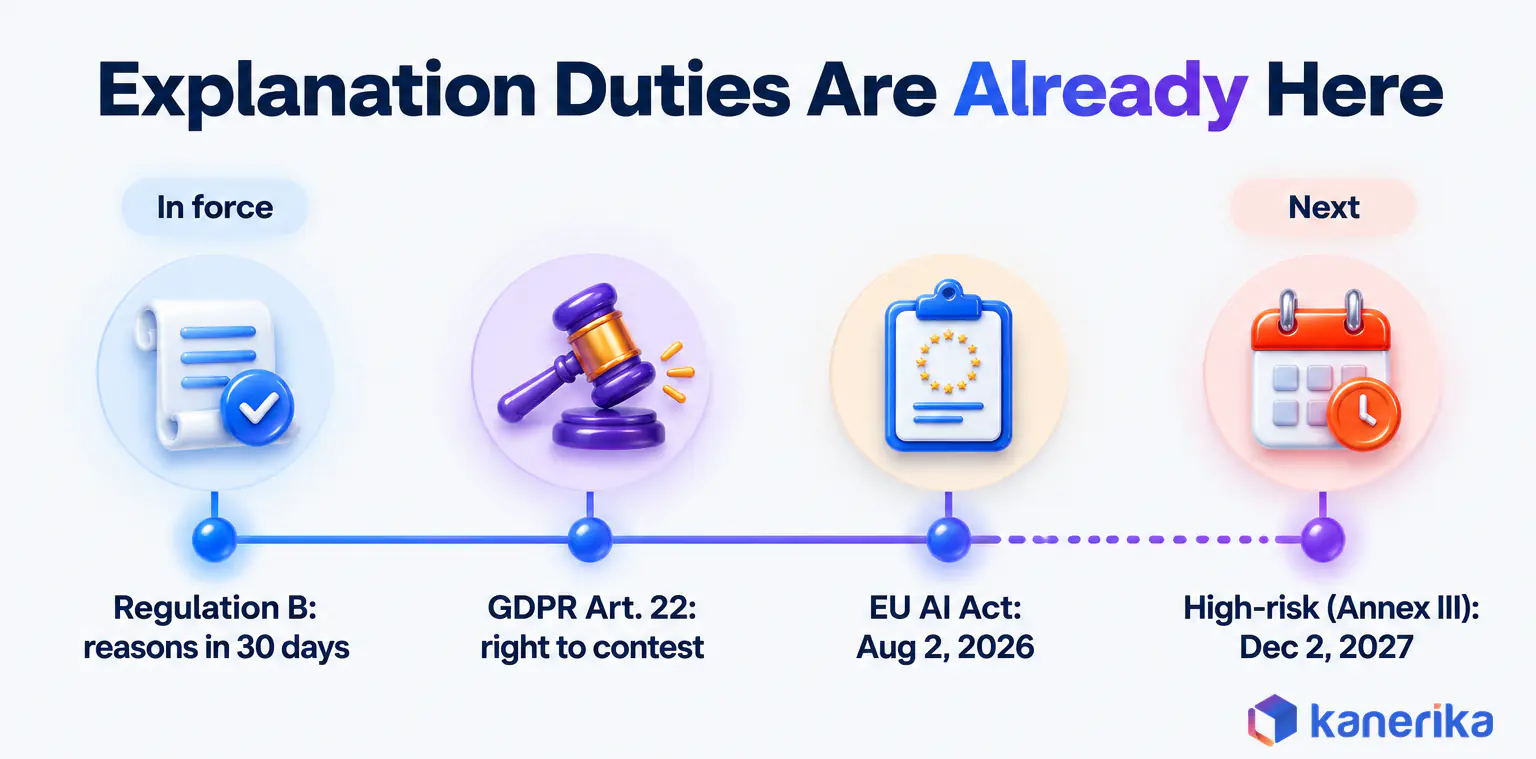
- GDPR Article 22 and US Regulation B already require reasons, while EU AI Act duties for Annex III high-risk systems start December 2, 2027.
From a Correct Prediction to a Defensible One
The Letter That Has to Say Why
Picture a small-business owner who applies for an equipment loan on a Monday. An automated model scores the file overnight, and by Wednesday the application is declined. So she calls the bank and asks the obvious question: why?
In the United States, that question comes with a deadline. Regulation B, 12 CFR 1002.9, gives the lender 30 days after a completed application to send its notice. That notice must also state the specific reasons, or else tell the applicant how to request them. “Our model said no” does not qualify.
Still, the model may well be accurate. It might be a gradient-boosted ensemble that beats the old scorecard on every validation test, yet nobody in the branch can read it. So the compliance team cannot sign a letter it cannot defend.
That gap between a correct prediction and a defensible one is the problem explainable AI solves. This guide covers what XAI means and which techniques work for which models. It also shows how to choose a method, which tools implement it, and what the market size figures really say.
Watch on YouTube
AI Audit Framework: EU AI Act, NIST, ISO 42001 & the 6-Step Blueprint
A walkthrough of the EU AI Act, the NIST AI RMF and six steps to audit an AI system. Watch it for how auditors test the evidence your explanations leave behind.
What Is Explainable AI?
Explainable AI (XAI) is the set of methods that show why a model produced a given output, in terms a person can check. In other words, it turns “the model scored this file 0.71” into “these three inputs pushed the score up, and this one pulled it down.”
The NIST AI Risk Management Framework, released on January 26, 2023, lists “explainable and interpretable” among the traits of trustworthy AI. Its section 3.5 draws a useful line between the two words. Explainability describes the mechanisms behind a system’s operation, while interpretability describes what an output means in the context of its purpose.
Transparency is the third term people mix in, and it is broader still. It covers what anyone can learn about the system at all, from its training data to who built it and when it last changed. The table below puts the three side by side, again using the loan from the opening.
| Term | Question it answers | Who usually asks | Example in the loan case |
|---|
| Explainability | How did the system reach this output? | Data scientists, model validators | Each input’s contribution to the declined applicant’s score |
| Interpretability | What does this output mean for the decision? | Loan officers, the applicant | “A high debt-to-income ratio was the main reason” |
| Transparency | What can anyone know about the system? | Regulators, auditors | Model documentation, data sources and version history |
NIST also published four principles of explainable AI in NISTIR 8312 on September 29, 2021. First, a system should give an explanation, and that explanation should be meaningful to its audience. It should also reflect how the system really works, and finally the system should know its limits. If these terms are new, our guide to machine learning vs AI also explains where predictive models sit within AI.
The Black-Box Problem in One Example
Go back to the loan model. Suppose it is a gradient-boosted ensemble with several hundred trees and well over a hundred input features. Every prediction passes through all of those trees, while each tree splits on different thresholds.
No person can trace that path for one applicant, let alone summarize it in a letter. That is what people mean by a black box. The model is not secret, but its logic is too tangled to read directly. So any explanation has to come from a method built for the job, or else from choosing a simpler model in the first place.
Why Explainable AI Matters in 2026
Explanations matter for four reasons that reinforce each other. People trust what they can check, and teams fix what they can see. Bias also shows up in the reasons, and laws such as GDPR Article 22 and Regulation B ask for them. Taken in that order, the business case builds itself.
Trust comes first because a model nobody trusts gets overridden or ignored. For instance, a claims adjuster who sees why a file was flagged can agree, disagree or escalate. One who sees only a score tends to fall back on gut feel, and then the model adds cost without changing decisions.
Debugging is the quieter benefit. For example, a fraud model can score well in testing while leaning on a field that only appears after review. An attribution chart exposes that dependency in minutes, so the team fixes it long before it fails in production. The same check also applies to any model in AI fraud detection, where a leaked field can make a weak model look strong.
Bias detection follows from the same view, too. When a postal code tops a credit model’s explanation, for instance, it may be acting as a proxy for a protected characteristic. The explanation does not prove bias on its own, but it tells the team exactly where to test. Our guide to responsible AI then covers the fairness checks that follow.
Checklist
AI Governance Checklist
Check explainability, bias testing, audit trails and human oversight for each high-stakes model before it reaches customers or regulators.
Get the Checklist →
The Legal Duty to Explain
The legal duty is what turned XAI from a research topic into a budget line. As of October 2026, several rules require reasons for automated or model-assisted decisions, and more take effect in 2027. Each one therefore belongs in an AI compliance register with its own trigger and deadline.
| Rule | What it requires | Applies when |
|---|
| EU AI Act, Article 13 | High-risk systems must be “sufficiently transparent to enable deployers to interpret a system’s output” | A provider places a high-risk AI system on the EU market |
| EU AI Act, Article 86 | Affected persons can obtain “clear and meaningful explanations” from the deployer | A decision rests on the output of an Annex III high-risk system |
| GDPR, Article 22 (reprint) | A right not to face decisions based solely on automated processing, plus human intervention and a right to contest | A fully automated decision has legal or similarly significant effects |
| US Regulation B, 12 CFR 1002.9 | Specific reasons for adverse action, or notice of the right to request them, within 30 days of a completed application | US consumer and small-business credit decisions, automated or not |
| NIST AI RMF 1.0 | A voluntary framework that names “explainable and interpretable” as a trustworthy-AI characteristic | US organizations that adopt it as a governance baseline |
EU AI Act Dates to Plan Around
The EU dates matter for planning. According to the implementation timeline on the Commission’s AI Act Service Desk, the Act entered into force on August 1, 2024. Prohibitions applied from February 2, 2025, general-purpose AI rules from August 2, 2025, and most remaining rules from August 2, 2026.
After the Digital Omnibus changes, the Annex III high-risk obligations, which carry the Article 13 transparency duty, apply from December 2, 2027. High-risk AI embedded in Annex I products follows on August 2, 2028. That leaves a short runway for credit, hiring and insurance models, so start testing explanations before an auditor does. Our overview of AI regulation tracks the wider rulebook.
How Big Is the Explainable AI Market?
Market estimates for explainable AI agree on direction but disagree on size. So read them as a signal of demand, and build plans on your own data. Three publishers whose pages we checked on October 29, 2026 show the spread.
| Publisher | Base value | Forecast | CAGR | Note |
|---|
| Grand View Research | USD 9.2B (2025), USD 10.9B (2026) | USD 32.9B by 2033 | 17.1% (2026 to 2033) | North America holds a 37.4% share |
| DataM Intelligence | USD 7.50B (2025) | USD 31.89B by 2033 | 20.2% (2026 to 2033) | Highest growth rate of the three |
| Global Market Insights | USD 6.55B (2023) | Not restated here | Over 15% (2024 to 2032) | Page published July 2024; its own FAQ quotes a 7.2% CAGR, so the headline rate is inconsistent |
The gap is wide even for a single year. Grand View’s 2025 figure of USD 9.2 billion sits about 23% above DataM’s USD 7.50 billion. Gaps like this usually come from definitions. One publisher may count consulting and integration services while another counts software only, and base years and regional coverage differ too.
A buyer should take two things from this. Demand for explanation tooling and skills grows on every estimate. Still, none of these numbers belongs in a business case until you read the methodology.
- Check the base year, since a 2023 base and a 2025 base describe different markets.
- Check the scope, because software-only and software-plus-services figures differ by design.
- Compare growth rates, not totals, when you want a sense of momentum across sources.
AI Assessment
How Ready Are Your Models to Explain Themselves?
Score your data, governance and AI maturity in a few minutes, and see which models need explanations before a regulator or a customer asks.
Start Your AI Assessment →
Explainable AI Techniques That Actually Work
XAI techniques split along two lines. Some explain one prediction (local), others describe the whole model (global), and some work on any model while others need a specific model family. So knowing where a method sits on both lines tells you most of what it can and cannot do.
| Technique | Scope | Model types | Strength | Known weakness |
|---|
| TreeSHAP | Local and global | Tree ensembles | Fast, exact attributions that add up to the prediction | Splits credit between correlated features in ways readers misread |
| KernelSHAP | Local and global | Any model | Model-agnostic, same additive output | Slow on large data, and the values are approximate |
| LIME | Local | Any model | Simple, readable local surrogate | Results can shift between runs |
| Counterfactuals (DiCE) | Local | Any model | Actionable “what would need to change” | Can suggest unrealistic changes without constraints |
| Explainable Boosting Machine | Global and local | The model itself | Exact, readable effect per feature | Can trail a black box on some problems |
| Integrated Gradients | Local | Differentiable neural networks | Attribution for images, text and embeddings | Results depend on the baseline input you choose |
SHAP
SHAP comes from “A Unified Approach to Interpreting Model Predictions” by Lundberg and Lee, published in 2017. It borrows Shapley values from cooperative game theory, where each input feature is a player and the prediction is the payout to share.
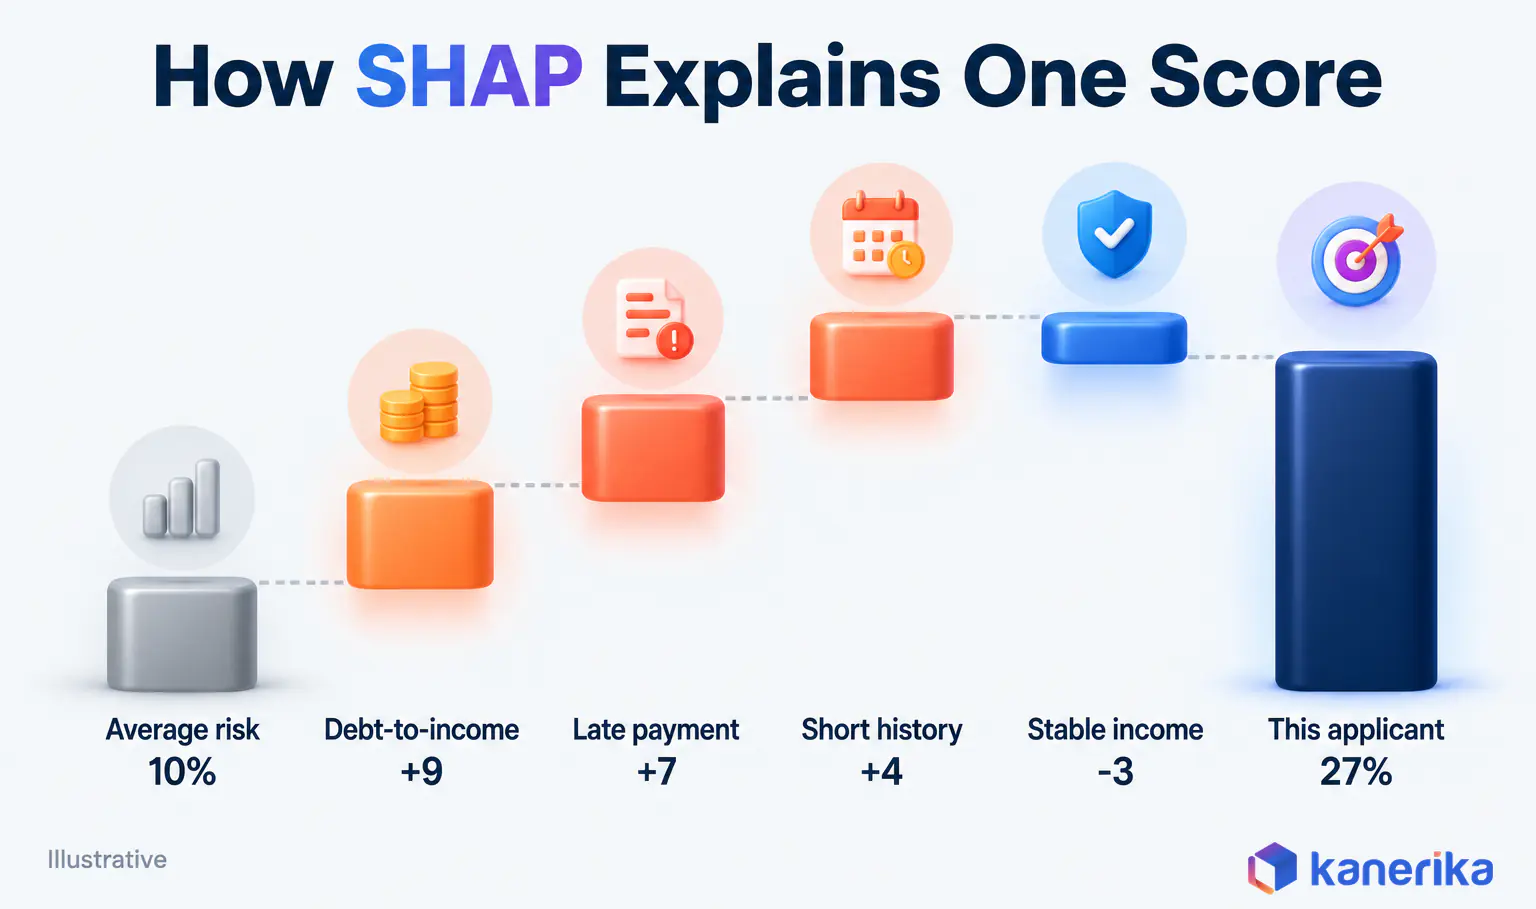
A feature’s SHAP value is its average marginal contribution across all the orders in which features could join. Because the values are additive, they sum to the gap between this prediction and the model’s average prediction. That property is what makes SHAP easy to turn into reason codes, since every point of the score is accounted for.
The variant matters in practice. TreeSHAP uses the structure of tree ensembles such as XGBoost or LightGBM to compute exact values quickly, so it suits production scoring. KernelSHAP, by contrast, treats the model as a black box and estimates the values by sampling, which works on anything but runs much slower. The shap library (version 0.54.1, released October 16, 2026, MIT license) ships both.
import shap

# model: a trained tree ensemble, e.g. an XGBoost classifier
explainer = shap.TreeExplainer(model)
shap_values = explainer(X_applicants)

# one applicant: how each feature moved the score from the average
shap.plots.waterfall(shap_values[0])

# whole portfolio: which features matter most, and in which direction
shap.plots.beeswarm(shap_values)
The waterfall plot is the one most teams show to business readers. It starts at the average score, then adds each feature’s push up or down, and ends at the applicant’s score, as the illustration below shows.
LIME
Ribeiro, Singh and Guestrin introduced LIME in “Why Should I Trust You?” in 2016. It explains one prediction by building a small, simple model around it.
First, the method perturbs the input many times and asks the black box for a prediction on each variant. Then it weights each variant by how close it is to the original. It then fits a sparse linear model to that neighborhood and reads off the weights. With a text classifier, for example, the result is a set of highlighted words that pushed the label one way or the other.
The catch is stability. Because the samples are random, two runs on the same input can rank features differently. The result also shifts with how widely you define the neighborhood. LIME suits a quick sanity check, but fix the random seed and repeat the run before a regulator sees it.
Counterfactual Explanations
A counterfactual explanation answers a different question: what would need to change for the outcome to change? Wachter, Mittelstadt and Russell argued in 2017 that this form suits GDPR, since it explains a decision without opening up the model’s internals.
The output reads naturally to a customer: you would have been approved with a debt-to-income ratio below 38%. That makes counterfactuals the strongest tool for actionable recourse. The constraint is realism, because an unconstrained search may suggest changing age or moving cities. So restrict it to inputs a person can actually change.
Microsoft’s DiCE library generates several diverse counterfactuals at once, so the customer sees more than one path. Its dice-ml package reached version 0.12 on July 13, 2025, under an MIT license.
The features_to_vary argument is where the realism constraint lives. In this sketch, the search may change only debt-to-income and the age of the late payment.
import dice_ml

# train_df: past applications with a binary "default" column
data = dice_ml.Data(dataframe=train_df,
                    continuous_features=["income", "debt_to_income", "months_since_late_payment"],
                    outcome_name="default")
model_if = dice_ml.Model(model=model, backend="sklearn")
explainer = dice_ml.Dice(data, model_if, method="random")

# search only inputs the applicant can change
cf = explainer.generate_counterfactuals(applicant_df, total_CFs=2,
                                        desired_class="opposite",
                                        features_to_vary=["debt_to_income", "months_since_late_payment"])
cf.visualize_as_dataframe(show_only_changes=True)
Everything else, including age and location, stays fixed, so every path DiCE returns is one the applicant could actually take.
Inherently Interpretable Models
The cleanest explanation is a model you can read directly. Credit scorecards, logistic regression and generalized additive models (GAMs) all qualify, since each feature’s effect on the output is visible and separate.
The Explainable Boosting Machine, or EBM, brings boosting into that family. It learns one shape function per feature, plus optional pairwise interactions, so you can plot each function to see how income, say, moves risk. EBMs ship in InterpretML, whose interpret package reached version 0.7.8 on March 17, 2026.
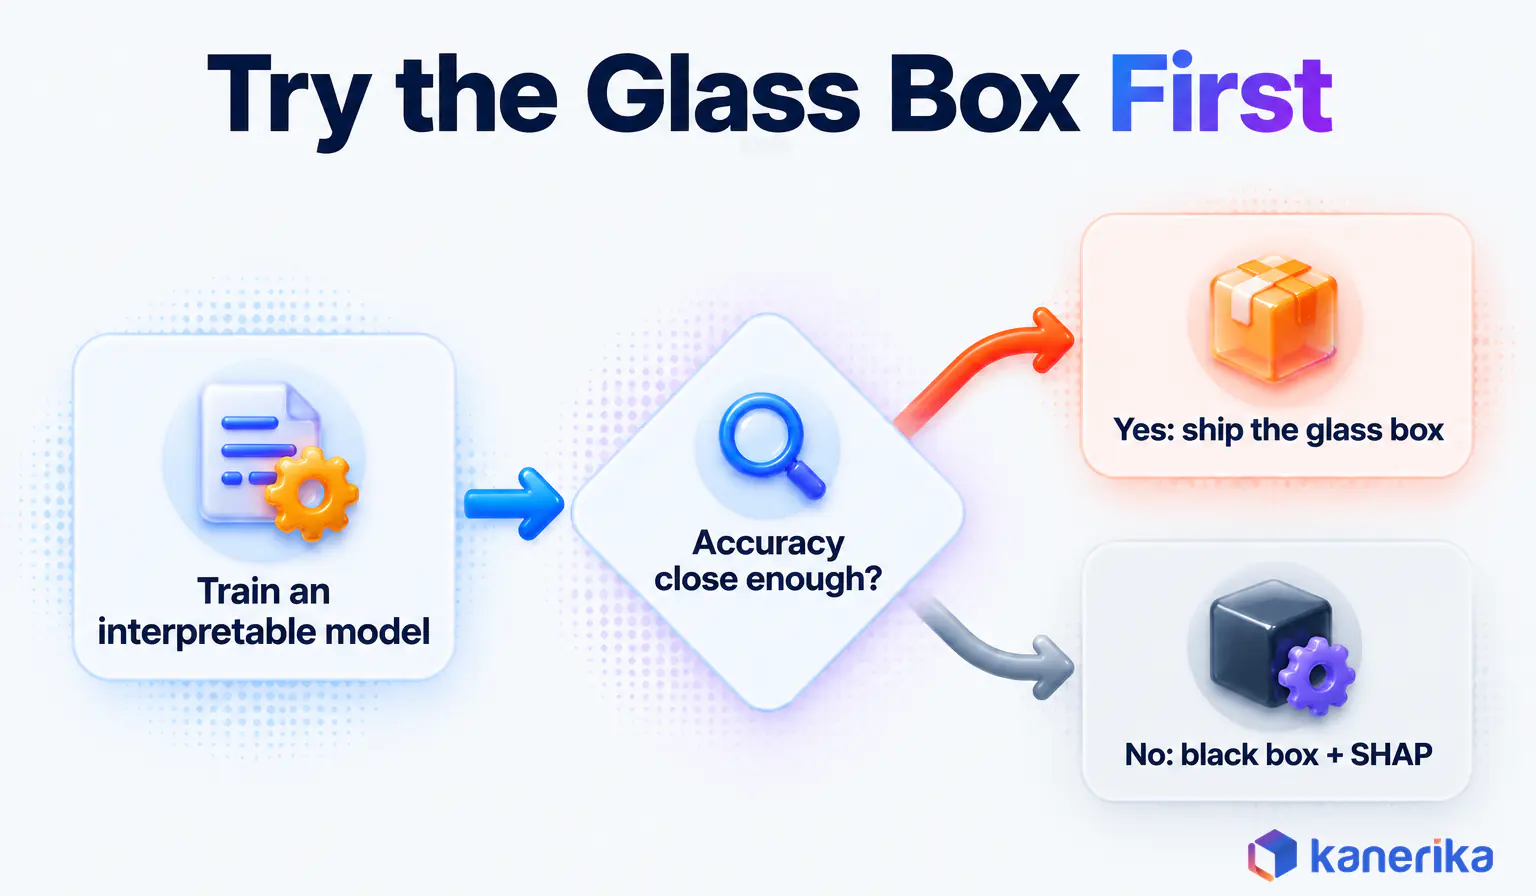
So the order of work matters. Train an interpretable model first, then compare it with the black box on the same holdout data. Choose the glass box whenever the accuracy cost is small enough for the business to accept.
Explaining Deep Learning Models
Neural networks for images, audio and text call for a different family of methods, ones that work with gradients. Integrated Gradients accumulates the gradient along a path from a neutral baseline, such as a black image, to the real input. The result is an attribution score per pixel or per token.
PyTorch teams usually reach for Captum, version 0.9.0 since April 17, 2026, which implements Integrated Gradients alongside saliency maps and other attribution methods. Saliency maps give a quicker, rougher heat map of the pixels that most affect an image classifier’s output.
One warning applies to transformer models. Attention weights show where the model looked, but they are not explanations by themselves. High attention does not prove that a token changed the output. Pair them with an attribution method before you draw conclusions.
Worked Example: Explaining a Declined Credit Decision
Here is how the techniques combine on the loan from the opening, step by step. The numbers are illustrative, chosen to show the mechanics rather than taken from a real lender. For readability, the SHAP values appear in percentage points.
- Score. The model estimates a 27% probability of default, above the bank’s 20% cut-off, so the application is declined.
- Compute SHAP contributions. Against a 10% portfolio average, debt-to-income adds 9 points and a recent late payment adds 7. A short credit history adds 4, while stable income subtracts 3. Together, that gives 10 + 9 + 7 + 4 – 3 = 27.
- Map factors to reason codes. Then the three largest positive contributors become the adverse-action reasons: debt-to-income ratio too high, recent delinquency, and limited length of credit history.
- Generate a counterfactual. Next, DiCE searches only inputs the applicant can change. It finds two paths to approval: a debt-to-income ratio below 38%, or the late payment aging past twelve months.
- Human review. A credit officer checks that the reasons make sense for this file before the letter goes out.
- Log the evidence. Finally, the record stores the inputs, model version, SHAP values, reason codes, counterfactual, reviewer and date.
Step 5 is where augmented intelligence shows up in practice: the model ranks and explains, and a person owns the decision. As a result, the bank can answer the applicant within the 30-day window, with reasons it can defend and a path she can act on.
The same pattern also scales beyond lending. In decision intelligence, explanations are what let the people acting on a recommendation trust it, override it when they should, and record why. Our guide to AI decision-making covers which decisions to hand to a model at all.
Talk to Kanerika
Need Reasons a Regulator Will Accept?
Kanerika reviews one high-stakes model with your team, picks the explanation method that fits it and shows what the audit evidence should contain.
Schedule a Demo →
Where Explainable AI Is Used Across Industries
Explainable AI matters most where a model’s output changes someone’s money, health or job. Four industries carry most of the demand, and each one needs a different kind of explanation.
Banking, Lending and Insurance
Banking and lending come first, because Regulation B makes adverse-action reasons a legal duty. The EU AI Act’s Annex III also treats credit scoring of individuals as high-risk, with an exception for fraud detection. For the wider picture, see our guides to AI in finance and AI in risk management.
Similarly, insurers face pressure on pricing. Annex III covers risk assessment and pricing for individuals in life and health insurance, so those models need reasons an underwriter can sign. Claims triage is a softer case, where the reason behind a flag mainly helps an adjuster decide faster. Our post on generative AI in insurance covers the newer, text-based side of the industry.
Healthcare and Hiring
Healthcare models mostly read images, signals and clinical notes, so gradient methods such as Integrated Gradients do much of the work. The FDA, Health Canada and the UK’s MHRA identified transparency principles for machine learning-enabled medical devices (page dated June 13, 2024). They ask that a device’s intended use, performance and, when available, its logic reach the people who rely on it. In the EU, medical devices sit in Annex I, so high-risk AI in those products follows the August 2, 2028 date.
Finally, hiring is the fourth area. Annex III also lists AI used to recruit or select people. In New York City, Local Law 144 bars an automated hiring tool unless it had a bias audit within the past year. Enforcement began on July 5, 2023, and employers must also post a summary of the audit results.
| Industry | Typical model | Explanation that fits | Who reads it |
|---|
| Lending | Tree ensemble credit score | TreeSHAP reason codes plus constrained counterfactuals | Applicant, credit officer, regulator |
| Insurance pricing | Pricing or risk model on tabular data | EBM where accuracy allows, otherwise TreeSHAP | Underwriter, regulator |
| Medical imaging | Deep neural network | Integrated Gradients plus clinician review | Clinician |
| Hiring | Screening or ranking model | Interpretable model plus a bias audit | Candidate, auditor |
In short, a simple rule ties the rows together. If a person can contest the decision, give them a counterfactual, and if a specialist reviews it, give them attributions.
How to Choose an Explainable AI Method
The right method depends on three things: the model you have, the person who needs the explanation, and the risk the decision carries. A data scientist debugging a churn model needs something different from a customer reading a declined-loan letter.
First, start from the audience and work backwards. A regulator wants consistent, logged reasons, while a customer wants an action they can take, and an engineer wants to see where the model breaks. Then check which methods your model type supports, since gradient methods need a differentiable network and TreeSHAP needs trees.
| Situation | Pick | Why |
|---|
| Tree ensemble scoring credit or claims, with a regulator reviewing | TreeSHAP plus reason codes | Exact, fast and consistent attributions that map to adverse-action reasons |
| Any model, quick local check | LIME or KernelSHAP | Model-agnostic and good for spot checks, but not audit evidence on its own |
| Customer-facing decision that needs recourse | Counterfactuals (DiCE) with constraints | Tells the person what they can change |
| Image, text or other deep model | Integrated Gradients (Captum) | Gradient attribution works on differentiable networks |
| New build where an interpretable model is nearly as accurate | EBM or scorecard | The model is its own explanation, so nothing is approximated |
| LLM or agent output | Cited sources, traces and human review | Feature attribution does not transfer well to generated text |
So most mature teams end up with two methods per high-stakes model. One is a global view for validation, such as SHAP summaries or EBM shape functions, and the other is a local explanation for each decision. The glass-box question comes before both, because a model that explains itself removes a whole layer of approximation.
Kanerika Service
AI Governance Services
Kanerika sets up explainability reporting, bias testing before deployment and a model registry with an audit trail, so explanations hold up when an auditor asks.
Explore AI Governance Services
Explainable AI Tools Compared
The tooling splits into open-source libraries that do the math and cloud services that run it at scale. Most cloud offerings wrap the same libraries, so the choice is often about where your models already live. Governance platforms that track models, policies and approvals, by contrast, form a separate category, covered in our review of AI governance tools.
| Tool | Type | What it explains | Latest version or status | Note |
|---|
| SHAP | Open source, MIT | Feature attributions, local and global | 0.54.1, October 16, 2026 | TreeSHAP, KernelSHAP and plots |
| LIME | Open source, BSD | Local surrogate explanations | 0.2.0.1, June 26, 2020 | No release since 2020, so check maintenance before adopting |
| InterpretML | Open source | Explainable Boosting Machines | 0.7.8, March 17, 2026 | Glass-box models with plots per feature |
| DiCE | Open source, MIT | Diverse counterfactuals | 0.12, July 13, 2025 | Powers the what-if view in Azure Machine Learning |
| Captum | Open source, PyTorch | Gradient and perturbation attributions | 0.9.0, April 17, 2026 | Integrated Gradients and saliency |
| Azure ML Responsible AI dashboard | Cloud, Microsoft | Interpretability, what-if counterfactuals, error analysis, fairness, causal inference | CLI v2 and SDK v2 | Bundles InterpretML, DiCE and Fairlearn in one view |
| Amazon SageMaker Clarify | Cloud, AWS | Scalable SHAP, per-instance explanations at inference, partial dependence plots | Closed to new customers; no new features planned | As of October 2026, AWS points users to the open-source SHAP library it is built on |
| Vertex Explainable AI | Cloud, Google | Feature-based and example-based explanations | Deprecated March 16, 2026 | Unavailable from March 16, 2027, so plan a move |
The Vertex row deserves attention if you run on Google Cloud, because the service stops on March 16, 2027. Teams that rely on it should move to an open-source library they control well before that date.
Five Tests Before You Pick a Tool
Whichever tool you shortlist, test it against the same five questions before it reaches production.
- Model coverage: does it support every model type you run, including the deep models?
- Local and global: can it explain one decision and also summarize the whole model?
- Stability: does the same input give the same explanation on every run?
- Audit export: can you store explanations with the model version and inputs?
- Latency: can it explain at inference time, or only in batch afterwards?
Explaining Generative AI and LLM Agents
Large language models break most of the techniques above. Their inputs run to thousands of tokens and their outputs are open-ended text. As a result, a per-token attribution score is noisy and hard for a business reader to use.
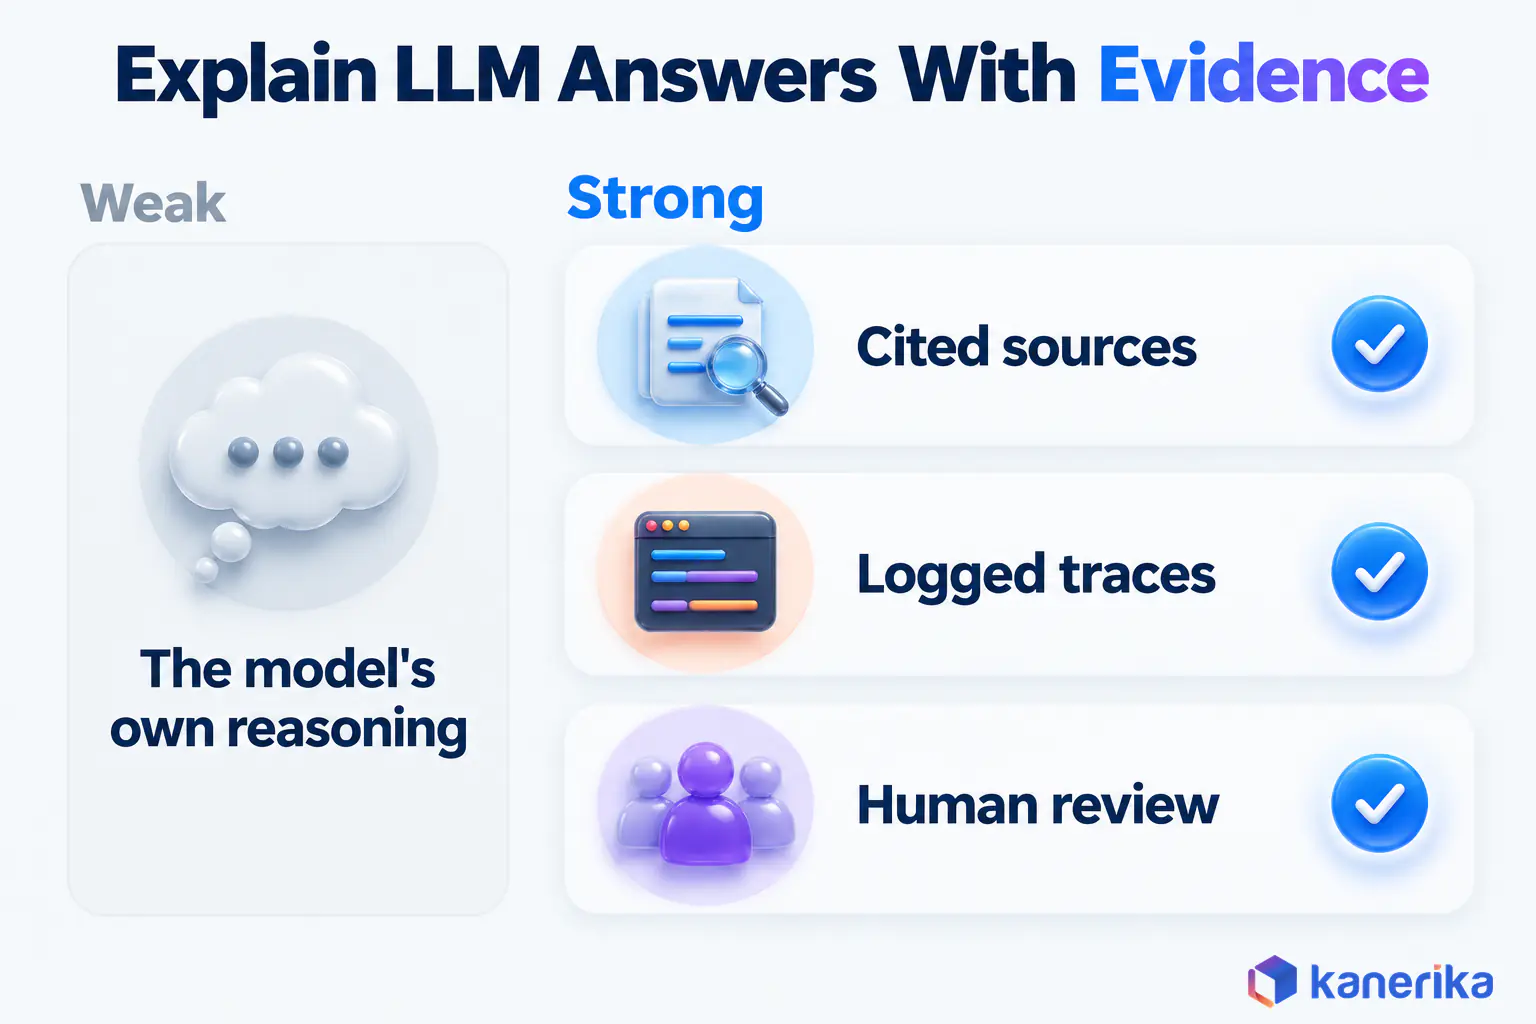
A model’s own written reasoning is tempting to treat as the explanation, but it is generated text like any other output. It can read convincingly and still not reflect what actually drove the answer. Treat it as a claim that still needs checking against the evidence. The same gap explains why AI hallucinations often arrive with confident, well-argued reasoning attached.
What works in practice is evidence. Ground answers in retrieved documents through retrieval-augmented generation, show the citations, and require each output to point at the records it relied on.
For agentic AI that calls tools, log the trace of prompts, retrieved passages and tool calls. Then route high-stakes outputs to a person who checks the evidence rather than the prose. Our guide to LLM observability covers the tracing side in depth.
A risk-detection system, for example, shows the pattern well. A rules engine flags an anomaly in transaction data, and a language model then writes a business-readable finding. Every finding cites the transactions behind it, so the reviewer judges the evidence, not the model’s wording.
The same evidence-first design also underpins process intelligence, where each finding about a workflow points back to event-log records. In both cases the explanation is the evidence trail, and the language model is only the narrator.
Challenges and Limits of Explainable AI
Explanations are models of models, so they can be wrong in their own ways. Knowing the failure modes keeps a team from treating a chart as proof.
Fidelity is the first problem. A LIME surrogate may fit the black box poorly around a given input, and the explanation then describes the surrogate rather than the model. NIST’s principle of explanation accuracy targets exactly this gap. Its principle of knowledge limits also asks a system to flag cases outside its competence.
Correlated features cause quieter trouble. When income and salary band move together, SHAP divides the credit between them in a way that depends on the method’s assumptions. A reader may conclude that neither matters much when together they drive the score.
The audience is the most common mismatch. A beeswarm plot means a lot to a data scientist and nothing to a customer, so the same model needs different explanations for different readers.
The accuracy cost of explainability is the other common misjudgment. On tabular data, an interpretable model often costs less accuracy than teams assume. Measure that gap on the same holdout set before anyone commits to a black box.
Explanations can also be gamed. A model can be tuned so its explanations look clean while its behavior stays the same. Similarly, applicants who learn which inputs move a score may adjust them. Independent review is therefore the defense in both cases.
| Challenge | Mitigation |
|---|
| Low fidelity of surrogate explanations | Measure how well the surrogate fits locally; prefer exact methods for audit evidence |
| Unstable results between runs | Fix random seeds, repeat runs and report the spread |
| Correlated features | Group related features and explain the group |
| Wrong audience | Test explanations with the people who receive them |
| Explanations that can be gamed | Independent validation and periodic re-checks of the model itself |
How to Roll Out Explainable AI: A Five-Step Plan
Rolling out XAI comes down to three decisions: which models need explaining, to whom, and with what evidence. The five steps below work the same way for a bank with three credit models and an insurer with forty pricing models.
- Inventory high-stakes models. List every model that affects customers, money or legal rights, then rank them by impact.
- Pick a method per model. Use the selection table above, and then record why you chose it in the model inventory your machine learning governance process keeps.
- Test explanations with the people who receive them. Loan officers, customers and auditors each need a different view, so check that each one understands theirs.
- Record audit evidence. Store inputs, model version, the explanation and the reviewer for every high-stakes decision.
- Monitor explanation drift. When the top drivers of a model’s decisions shift, investigate before the accuracy metrics move. Add the check to your existing machine learning operations (MLOps) monitoring.
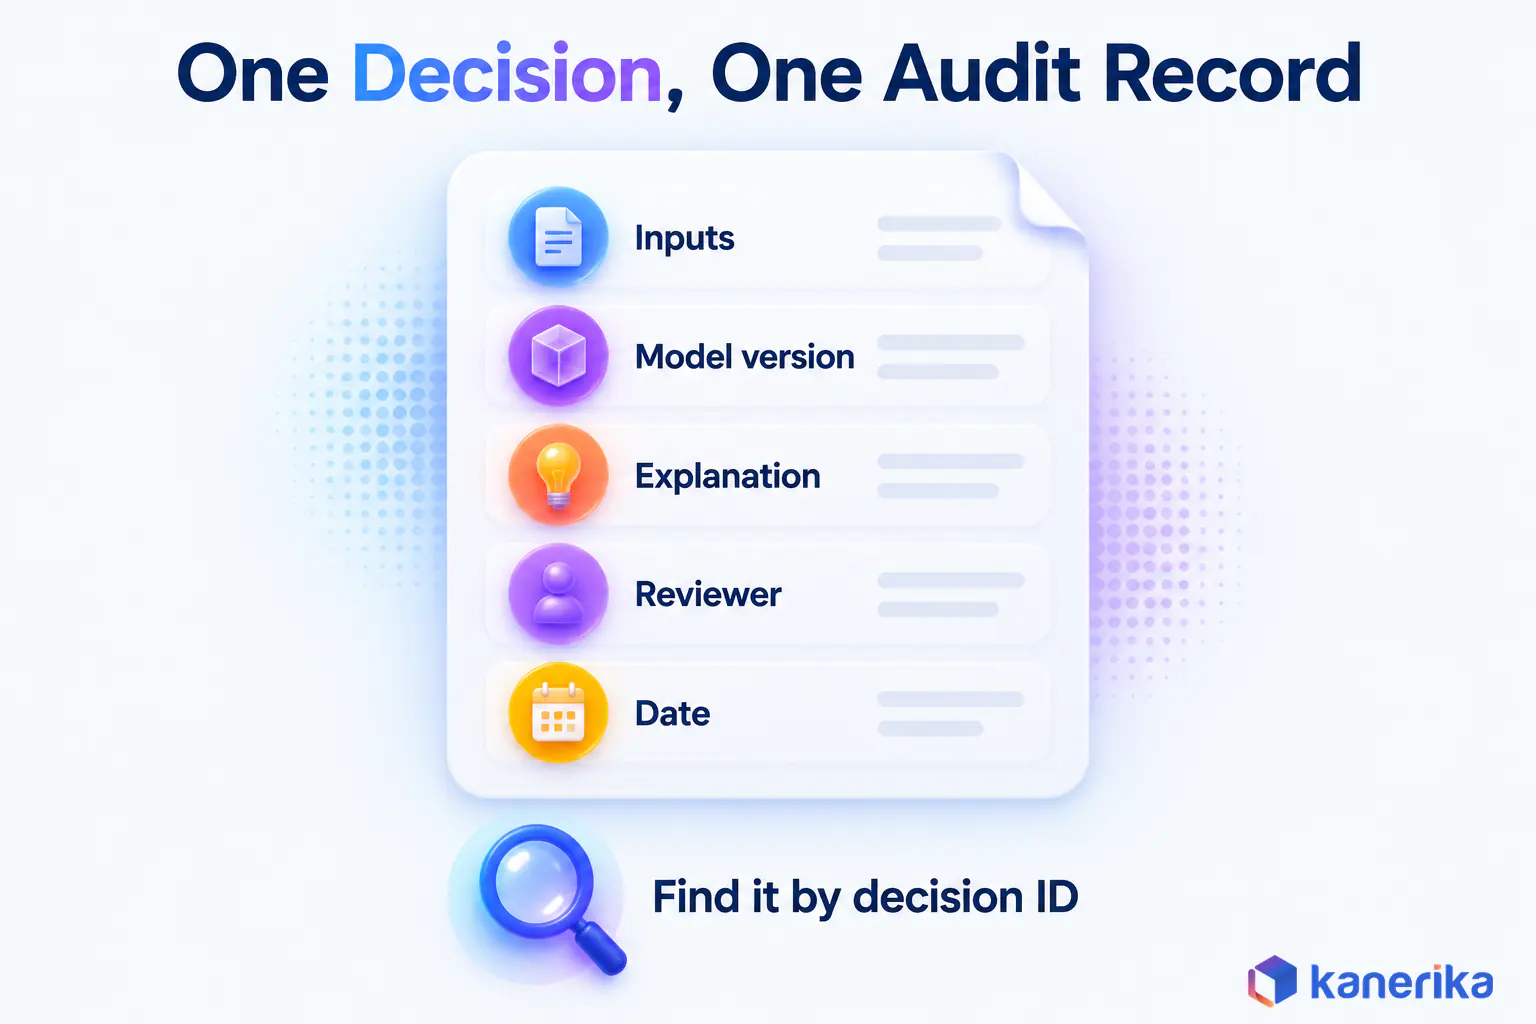
Here is what one record could look like for the declined loan in the worked example. The field names are illustrative, and the contributions are in probability units, so 0.10 + 0.09 + 0.07 + 0.04 – 0.03 = 0.27.
{
  "decision_id": "LN-2026-104233",
  "decided_at": "2026-10-27T14:05:00Z",
  "model": {"name": "small-business-credit-gbm", "version": "3.2.0"},
  "inputs_ref": "evidence/LN-2026-104233/inputs.json",
  "outcome": {"probability_of_default": 0.27, "cutoff": 0.20, "decision": "decline"},
  "explanation": {
    "method": "TreeSHAP",
    "base_value": 0.10,
    "contributions": {
      "debt_to_income": 0.09,
      "recent_late_payment": 0.07,
      "credit_history_length": 0.04,
      "stable_income": -0.03
    }
  },
  "reason_codes": ["Debt-to-income ratio too high", "Recent delinquency", "Limited length of credit history"],
  "counterfactuals": ["debt_to_income below 0.38", "late payment older than 12 months"],
  "reviewer": {"role": "credit_officer", "approved": true},
  "notice_sent": "2026-10-28"
}
Step 4 is the one auditors ask about first. A decision without a stored explanation is hard to defend months later, because the model may have been retrained since. Keep each record small and consistent, so it can be retrieved by decision ID within minutes.
What Drives the Effort
The effort depends on a few drivers you can assess before you start. Model count matters most, since each high-stakes model needs its own method, tests and evidence. Latency comes next, because explaining at inference time costs more than explaining in nightly batches.
Regulated decisions add review and documentation steps, while weak data lineage makes every explanation harder to trust. Programs that already run AI governance with a model registry move fastest, and an AI TRiSM framework gives the controls a home. Our AI auditing framework guide shows how auditors test that evidence.
How Kanerika Builds Explainable, Auditable AI
Kanerika treats explainability as a delivery requirement rather than a report written at the end. In our AI governance consulting work, the explanation method is chosen per model, then tested with the business users who act on it. Audit evidence is stored with the model version, and bias testing runs before deployment.
The same discipline runs through our wider AI and machine learning services, from predictive models to agents. Our AI governance service page states the goal plainly: “explainability reports that consistently hold up in audit.”
An engagement for a multifamily property manager shows this evidence-first pattern in practice. A rules engine on Microsoft Fabric flags anomalies in rental transactions. Then an Azure OpenAI reasoning layer turns each one into a structured finding backed by transaction-level evidence. In this guide’s terms, the rules engine decides, the language model narrates, and the transaction records are the explanation.
Business users review every finding, and their decisions refine the governed rules over time. The system surfaced about 500 risk findings across 6 risk categories and identified about 1.2M in financial exposure. Each finding could be traced back to the transactions behind it, which is what made it usable.
Case Study
Detecting Rental Transaction Risk Early with AI-Powered Risk Intelligence
A rules engine on Microsoft Fabric and an Azure OpenAI reasoning layer surfaced about 500 evidence-backed risk findings across 6 risk categories for a multifamily property manager.
Read the Case Study →
The Bottom Line on Explainable AI Techniques, Tools and Market Size
In 2026, explainable AI is an operational requirement for any model that touches credit, claims, hiring or health. On techniques, the picture is settled: SHAP for tabular models, counterfactuals for recourse and Integrated Gradients for deep learning. Glass-box models still win wherever they are accurate enough.
On tools, the open-source libraries are mature and free, while the managed cloud options are shrinking. Vertex Explainable AI shuts down on March 16, 2027, and Amazon SageMaker Clarify no longer takes new customers. On market size, the forecasts disagree on totals but agree that demand is rising. Treat them as a signal, and size your own program from your own models and duties. The practical rule for 2026 is to choose each technique by the decision and the person who reads the explanation, then keep the evidence.
Frequently Asked Questions
What is an example of explainable AI?
A common example is a bank’s credit model that declines a loan and then lists the reasons. SHAP values show that a high debt-to-income ratio and a recent late payment raised the risk score most. A counterfactual adds what would change the outcome, such as a lower debt ratio. The applicant gets reasons she can act on.
What are the four principles of explainable AI?
NIST set out four principles in NISTIR 8312, published in September 2021. A system should give an explanation for its outputs, and that explanation should be meaningful to its audience. The explanation should also reflect accurately how the system reached the output. Finally, the system should recognize its knowledge limits and flag cases it was not designed for.
How big is the explainable AI market in 2026?
Estimates differ by publisher. Grand View Research puts the explainable AI market at USD 10.9 billion in 2026, growing to USD 32.9 billion by 2033. DataM Intelligence starts from USD 7.50 billion in 2025 and projects USD 31.89 billion by 2033. The figures differ because each publisher defines the market and its scope in its own way.
Is explainable AI required by law in the United States?
No single US law requires explainable AI across the board. Regulation B does require lenders to give specific reasons for adverse credit decisions, whether or not a model made them. The NIST AI Risk Management Framework is voluntary, but it names explainability as a trait of trustworthy AI. Other sector rules may apply, so check each use case.
Does the EU AI Act require explainable AI?
Yes, for high-risk systems. Article 13 requires them to be transparent enough for deployers to interpret their outputs. Article 86 gives affected people a right to clear and meaningful explanations of decisions based on Annex III high-risk systems. Under the timeline the European Commission publishes, Annex III obligations apply from December 2, 2027.
Can explainable AI detect bias in machine learning models?
It can reveal where bias may come from, though it cannot prove fairness on its own. If a postal code or device type ranks high in a credit model’s explanations, it may be a proxy for a protected group. Teams then test that feature with fairness metrics and decide whether to remove it or constrain the model.
How do you measure the quality of an AI explanation?
Check four things. Fidelity measures how closely the explanation matches the model’s real behavior. Stability checks that the same input gives the same explanation on repeated runs. Usefulness is tested with the people who receive it, who should understand it and act on it. Finally, the explanation should state its limits when an input falls outside the training data.
What is the difference between explainability and interpretability?
The NIST AI Risk Management Framework draws the line clearly. Explainability describes the mechanisms behind how a system produced an output, such as which features pushed a score up. Interpretability describes what that output means for the decision at hand. A data scientist usually needs the first, while a loan officer or a customer needs the second.
What is the difference between explainable AI and AI?
AI is the broad field of systems that learn from data and make predictions or decisions. Explainable AI is a set of methods applied to those systems so people can see why a given output was produced. It is not a separate kind of AI. Any model, from a scorecard to a deep network, can be paired with explanation methods.
What is the difference between responsible AI and explainable AI?
Responsible AI is the wider program of making AI fair, safe, private, accountable and transparent. Explainable AI is one part of it, focused on showing why a model produced each output. Explanations support the other goals, because they reveal biased drivers and give auditors evidence. A responsible AI program without explainability struggles to prove its other claims.
Is ChatGPT an explainable AI?
Not in the strict sense. ChatGPT is a large language model whose internal reasoning cannot be traced to specific inputs the way SHAP traces a credit score. Its written reasoning is generated text, not a faithful record of the computation. Enterprises make LLM outputs explainable through cited sources, logged traces and human review of high-stakes answers.
What is the difference between SHAP and LIME?
SHAP assigns each feature a Shapley value from game theory. The values add up exactly to the gap between a prediction and the average prediction. LIME fits a simple local model around one prediction by sampling nearby inputs. SHAP is more consistent and suits audit evidence. LIME is quick and model-agnostic, but its results can shift between runs.
Which explainable AI technique works best for deep learning?
Integrated Gradients is the usual starting point for neural networks on images, text or audio. It accumulates gradients from a neutral baseline to the real input and scores each pixel or token. The Captum library implements it for PyTorch. Saliency maps give a faster first look, and attention weights should never be treated as explanations on their own.
What are the best explainable AI tools for enterprises?
Most enterprises combine open-source libraries with a cloud service. SHAP, InterpretML, DiCE and Captum cover attributions, glass-box models, counterfactuals and deep learning. The Responsible AI dashboard in Azure Machine Learning and Amazon SageMaker Clarify run these methods at scale. Google’s Vertex Explainable AI is deprecated and becomes unavailable on March 16, 2027.
Where is explainable AI used?
Explainable AI is used wherever a model’s decision affects people, money or safety. Banks use it for credit decisions and adverse-action reasons, and insurers use it for pricing and claims. Hospitals use it to show clinicians why a model flagged a patient. Fraud, hiring and public-sector teams use it to support audits, appeals and internal reviews.














